
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
fastapi-users/fastapi-users | fastapi | 44 | Make easy to override Responses and HTTPException | Hello! At the moment, i can't override values which returns fastapi-users. For example:
When user have bad credentials fastapi-user simple raise the FastAPI `HTTPException`, but in some cases it isn't well :( My idea is to make a classvars (or global vars?) of responses (errors) classes, which user easy can override. | closed | 2019-11-10T01:50:11Z | 2019-11-12T11:25:16Z | https://github.com/fastapi-users/fastapi-users/issues/44 | [
"feedback"
] | prostomarkeloff | 4 |
ivy-llc/ivy | numpy | 28,146 | Fix Frontend Failing Test: paddle - mathematical_functions.jax.numpy.fmin | closed | 2024-01-31T21:44:34Z | 2024-02-01T21:20:38Z | https://github.com/ivy-llc/ivy/issues/28146 | [
"Sub Task"
] | samthakur587 | 0 | |
ultralytics/ultralytics | computer-vision | 18,946 | model.predict takes significantly more time for batch input | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
**Description**
When running `model.predict` on a batch of 6 input frames (f... | open | 2025-01-30T12:05:12Z | 2025-02-03T12:08:56Z | https://github.com/ultralytics/ultralytics/issues/18946 | [
"question",
"detect"
] | afismoossa | 14 |
MycroftAI/mycroft-core | nlp | 2,848 | Discussion MycroftSkill parameter use_settings to be or not to be | The [use_settings parameter](https://github.com/MycroftAI/mycroft-core/blob/dev/mycroft/skills/mycroft_skill/mycroft_skill.py#L119) for the MycroftSkill was a bit of a hack when we added it. Basically it was because Padatious ran as a Skill and we didn't want it to show up on the skill page.
Padatious is now a prope... | closed | 2021-03-06T10:45:20Z | 2024-09-08T08:30:24Z | https://github.com/MycroftAI/mycroft-core/issues/2848 | [
"Status: For discussion"
] | forslund | 5 |
axnsan12/drf-yasg | django | 833 | Use PyYAML instead of ruamel.yaml | ## Description
PyYAML is the [default YAML serializer used in Django](https://github.com/django/django/blob/main/django/core/serializers/pyyaml.py) and also the suggested DRF [YAML renderer uses it](https://jpadilla.github.io/django-rest-framework-yaml/).
If someone uses these library with drf-yasg he is going to h... | closed | 2023-01-27T08:06:52Z | 2023-07-20T14:29:48Z | https://github.com/axnsan12/drf-yasg/issues/833 | [
"1.21.x"
] | sevdog | 5 |
ARM-DOE/pyart | data-visualization | 1,367 | DeprecationWarning: 'xdrlib' is deprecated and slated for removal in Python 3.13 |
I'm running python-3.11, and getting a warning :
```
pyart/io/nexrad_level3.py:72: DeprecationWarning: 'xdrlib' is deprecated and slated for removal in Python 3.13
from xdrlib import Unpacker
``` | closed | 2023-01-05T08:32:27Z | 2023-01-06T03:17:58Z | https://github.com/ARM-DOE/pyart/issues/1367 | [] | captcha1 | 3 |
BeanieODM/beanie | pydantic | 653 | merge_models does not merge list even if it does not include Link | ### Discussed in https://github.com/roman-right/beanie/discussions/652
<div type='discussions-op-text'>
<sup>Originally posted by **tomohirohiratsuka** August 10, 2023</sup>
Hi, I'm wondering this is expected behavior or not.
When I update document with `update` method, it returns updated document only when the... | open | 2023-08-10T16:55:43Z | 2024-09-16T14:48:49Z | https://github.com/BeanieODM/beanie/issues/653 | [
"bug",
"not reproduced"
] | roman-right | 7 |
piccolo-orm/piccolo | fastapi | 406 | Expose an API for running `QueryString` | Piccolo uses a class called `QueryString` internally for composing queries. It's very powerful, and allows you to compose complex nested queries, and compiles to a parameterised SQL statement and values.
At the moment, if someone wants to compose their own query, they have to use `raw`. For example `await Band.raw('... | open | 2022-01-25T20:50:42Z | 2022-02-09T16:46:44Z | https://github.com/piccolo-orm/piccolo/issues/406 | [
"enhancement"
] | dantownsend | 1 |
TheKevJames/coveralls-python | pytest | 324 | 3.2.0: pytest is failing with `pytest-randomly` plugin | I'm trying to package your module as an rpm package. So I'm using the typical build, install and test cycle used on building packages from non-root account.
- "setup.py build"
- "setup.py install --root </install/prefix>"
- "pytest with PYTHONPATH pointing to sitearch and sitelib inside </install/prefix>
```conso... | closed | 2021-09-03T21:17:29Z | 2023-01-01T15:41:53Z | https://github.com/TheKevJames/coveralls-python/issues/324 | [] | kloczek | 5 |
robusta-dev/robusta | automation | 1,173 | Rate limit feature for on_kubernetes_warning_event | We sometimes have GCP acting up and causing false positives in our alerts.Currently this is our configuration, but sometimes we still get false positives.
```
- triggers:
- on_kubernetes_warning_event_create:
include: [ "FailedGetPodsMetric", "FailedGetExternalMetric" ]
exclude: [ "googleapi: Error... | open | 2023-11-17T10:58:56Z | 2024-02-09T10:18:03Z | https://github.com/robusta-dev/robusta/issues/1173 | [
"needs-triage"
] | otherguy | 5 |
LAION-AI/Open-Assistant | python | 3,380 | Issue with chat accessibility | Everytime i open the bot chat i have to swipe down all the way through our msgs just to reach our last msg so that i can chat with the bot which is a really annoying thing i have to do everytime i open the bot, and the longer the chat the worse it becomes, thanks for the amazing bot btw and keep up the good work. | open | 2023-06-11T08:56:40Z | 2023-06-11T09:38:37Z | https://github.com/LAION-AI/Open-Assistant/issues/3380 | [
"bug",
"website"
] | 7fadi7 | 0 |
iperov/DeepFaceLab | deep-learning | 5,554 | Fail to start training with numpy import error | So, the same "ImportError: numpy.core.multiarray failed to import" message appears everytime when training with SAEHD. Tried updating pip, numpy and tensorflow but the issue still exists. AMP shares the same issue, but Quick96 works perfectly.
My rig is: AMD 5950X, 128G RAM, dual RTX3090. Win10 19044.1889. No WSL no... | open | 2022-09-02T15:53:18Z | 2023-06-08T23:19:08Z | https://github.com/iperov/DeepFaceLab/issues/5554 | [] | okingjo | 4 |
lux-org/lux | jupyter | 340 | [Question] Large dataframe warnings | Hello. Thank you so much for creating and maintaining lux. I got below warning
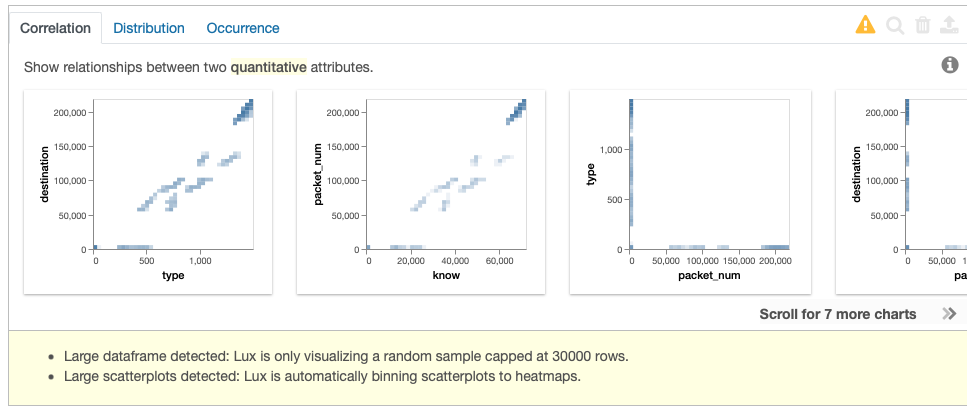
Is it a serious thing? because I have a large data set and I need each item | closed | 2021-04-03T19:40:19Z | 2021-04-11T04:31:04Z | https://github.com/lux-org/lux/issues/340 | [
"question"
] | beneslami | 2 |
tqdm/tqdm | jupyter | 1,466 | .write not working in Spyder 5.4.2 | Hi,
I'm experiencing a bug with the simple .write() method. Even with the snippet from the docs, a new line and progress bar are created for every print command.
Code:
```
from tqdm.auto import tqdm, trange
from time import sleep
bar = trange(10)
for i in bar:
# Print using tqdm class method .write()... | open | 2023-04-13T14:04:59Z | 2023-04-13T14:04:59Z | https://github.com/tqdm/tqdm/issues/1466 | [] | albb20 | 0 |
huggingface/transformers | pytorch | 36,723 | trainer.train() | ### System Info
hello
I still have error as below on distilbert-base-uncased on jupyter!!!!!!
please help me
--------------------------------------------------------------------------
ValueError Traceback (most recent call last)
Cell In[90], line 9
2 trainer = Trainer(
3 ... | open | 2025-03-14T14:10:36Z | 2025-03-14T14:10:36Z | https://github.com/huggingface/transformers/issues/36723 | [
"bug"
] | ARS1979ie | 0 |
jmcnamara/XlsxWriter | pandas | 227 | Legend Key Text issues in chart | Hi John,
Thanks for the quick response last time.
With the same code I provided last time, I noticed that under LibreOffice Calc, the legend key
in the chart did have text that said: "Column C".
BUT when I open the same file in Office-2007 this text in the legend Key Text portion in the charts does not appear at all, ... | closed | 2015-03-07T18:57:23Z | 2015-03-08T00:43:52Z | https://github.com/jmcnamara/XlsxWriter/issues/227 | [
"question",
"ready to close"
] | pablo3p | 4 |
gevent/gevent | asyncio | 1,899 | Build error since Cython update | * gevent version: 20.9.0 from pip+build
* Python version: 2.9.13
* Operating System: Docker on ARM (Apple Silicon)
### Description:
Probably this is not really an issue we can "solve", but we're experiencing problems since some days and maybe we're not alone, so I'm writing some notes here just in case somebody... | closed | 2022-08-05T14:59:37Z | 2024-11-18T10:53:03Z | https://github.com/gevent/gevent/issues/1899 | [] | serl | 11 |
dynaconf/dynaconf | flask | 1,082 | [RFC] Provide workaround for auto-complete w/ Schema | ## Problem
I want to be able to use a schema object to provide type hints for my `settings` object:
```python
class MySchema(DynaconfBase):
name: str
age: int
settings = Dynaconf()
settings.na # IDE autocomplete "name" and recognizes as string
```
## Proposal
Fake the type of the Dynaconf ob... | closed | 2024-03-22T18:22:11Z | 2024-08-06T17:56:31Z | https://github.com/dynaconf/dynaconf/issues/1082 | [
"Not a Bug",
"RFC",
"typed_dynaconf"
] | pedro-psb | 4 |
Lightning-AI/pytorch-lightning | machine-learning | 20,652 | ModelCheckpoint need monitor average loss | ### Description & Motivation
I know ModelCheckpoint can monitor like "train_loss" , "val_loss" , when the value is min and "every_n_train_steps" is true. but I want to cache "train_loss" or "val_loss" from "every_n_train_steps" to next "every_n_train_steps" ,when cache loss is lower than before, then save model.
... | open | 2025-03-18T08:39:48Z | 2025-03-18T08:40:10Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20652 | [
"feature",
"needs triage"
] | Johnson-yue | 0 |
microsoft/Bringing-Old-Photos-Back-to-Life | pytorch | 267 | i am not able to run code for installation | git : The term 'git' is not recognized as the name of a cmdlet, function, script file, or operable program. Check the spelling of the name, or if a path was included, verify that the path is correct and try again.
At line:2 char:1
+ git clone https://github.com/vacancy/Synchronized-BatchNorm-PyTorch
+ ~~~
+ Cat... | open | 2023-03-23T09:08:39Z | 2024-01-26T10:51:38Z | https://github.com/microsoft/Bringing-Old-Photos-Back-to-Life/issues/267 | [] | rakshitsharma574 | 3 |
aleju/imgaug | machine-learning | 751 | imgaug.random conflict with numpy.random | Hello, I tried to use imgaug with python 3.6.7 on Ubuntu 16.04. After I use pip to install imgaug and try to import it in ipython. It raised an error called module 'numpy' has no attribute 'random' as follows.

```python
run1 = wandb.init(
id="id1"
name="name1",
reinit=True,
)
# log stuff ...
# next c... | closed | 2024-12-19T15:29:44Z | 2024-12-20T03:38:22Z | https://github.com/wandb/wandb/issues/9120 | [
"ty:bug",
"a:sdk",
"c:sdk:init"
] | MathisTLD | 1 |
ipython/ipython | jupyter | 13,873 | %%timeit documentation is formatted wrong | The [`%%timeit` documentation](https://ipython.readthedocs.io/en/stable/interactive/magics.html#magic-timeit) looks like this:
> Usage, in line mode:
> %timeit [-n\<N> -r\<R> [-t|-c] -q -p\<P> -o] statement
>
> or in cell mode:
> %%timeit [-n\<N> -r\<R> [-t|-c] -q -p\<P> -o] setup_code code code…
But it shoul... | closed | 2022-12-22T23:36:28Z | 2024-10-25T07:55:14Z | https://github.com/ipython/ipython/issues/13873 | [
"documentation"
] | wjandrea | 1 |
Significant-Gravitas/AutoGPT | python | 9,000 | Marketplace - creator page - add 24px to the padding at the bottom of the page |
### Describe your issue.
Please add 24px at the bottom of the page's padding, so that it totals to 90px padding.
<img width="1318" alt="Screenshot 2024-12-16 at 21 28 21" src="https://github.com/user-attachments/assets/6773fd48-e7e2-482b-a0c5-774230b99ff6" />
| open | 2024-12-16T13:29:20Z | 2025-01-06T05:41:44Z | https://github.com/Significant-Gravitas/AutoGPT/issues/9000 | [
"good first issue",
"UI",
"platform/frontend"
] | ograce1421 | 0 |
BeanieODM/beanie | asyncio | 1,130 | [BUG] Optional Link Field Not Fetching Data in fetch_links |
### Description
When using `fetch_links` with an `Optional[Link[Answer]]` field in a `Document`, the related document is not fetched properly. Instead, only the required `Link` fields (`template` and `candidate`) are correctly populated.
### Code to Reproduce
```python
from typing import Optional
from beanie import D... | closed | 2025-02-19T17:11:37Z | 2025-02-24T16:53:55Z | https://github.com/BeanieODM/beanie/issues/1130 | [
"action requested"
] | SwAt1563 | 2 |
jupyter/nbgrader | jupyter | 1,056 | Non-Deterministic Behavior of Validate when Exceptions are Thrown | <!--
Thanks for helping to improve nbgrader!
If you are submitting a bug report or looking for support, please use the below
template so we can efficiently solve the problem.
If you are requesting a new feature, feel free to remove irrelevant pieces of
the issue template.
-->
### Operating system
```
... | closed | 2018-12-17T15:59:56Z | 2019-06-06T08:20:07Z | https://github.com/jupyter/nbgrader/issues/1056 | [
"bug"
] | samuelmanzer | 7 |
axnsan12/drf-yasg | django | 709 | AttributeError: 'PosixPath' object has no attribute 'rstrip' | ### Environment:
- Python3.7.8
- Django2.0
### pip list
```
asgiref==3.3.1
certifi==2020.12.5
chardet==4.0.0
Django==2.0
django-filter==1.1.0
djangorestframework==3.8.2
icalendar==4.0.7
idna==2.10
mysql-connector==2.2.9
mysqlclient==2.0.3
pymongo==3.10.1
python-dateutil==2.8.1
pytz==2020.5
pyvmomi... | closed | 2021-03-11T10:14:53Z | 2021-03-12T06:38:03Z | https://github.com/axnsan12/drf-yasg/issues/709 | [] | thinkinghere | 0 |
robinhood/faust | asyncio | 87 | Deployment docs | ## Checklist
- [ ] Supervisord for deployment (See https://github.com/celery/celery/tree/master/extra/supervisord) Docs should link to a similar file in `faust/extra`
- [ ] Sentry logging (show example with log handler)
- [ ] Statsd monitoring to applications
| closed | 2018-03-12T23:14:24Z | 2018-07-31T14:39:15Z | https://github.com/robinhood/faust/issues/87 | [
"Issue Type: Documentation"
] | vineetgoel | 0 |
kynan/nbstripout | jupyter | 196 | Any examples for --keep-id option? | Hi, I just started using nbstripout and it worked well in my case except the "--keep-id" option.
I would like to keep all the cell ids in my notebook. However, I failed to configure anything and the ids were reassigned everytime I push the .ipynb files.
I've tried running "nbstripout --keep-id" alone but there wa... | closed | 2024-05-12T17:02:18Z | 2024-07-26T16:12:18Z | https://github.com/kynan/nbstripout/issues/196 | [
"type:question",
"state:waiting"
] | zy-cai | 8 |
deezer/spleeter | tensorflow | 335 | [Discussion] What should I put in CSV file when training? | <!-- Please respect the title [Discussion] tag. -->
In this CSV file: https://github.com/deezer/spleeter/blob/master/configs/musdb_train.csv
The first column states that it has the mixture.wav files. I would like to confirm, are these files the full song with all the instruments/vocals in it? Also the other columns... | open | 2020-04-20T09:05:53Z | 2021-02-19T07:37:41Z | https://github.com/deezer/spleeter/issues/335 | [
"question"
] | gg2001 | 1 |
nl8590687/ASRT_SpeechRecognition | tensorflow | 338 | 训练自己的数据报错 | RuntimeError: The expanded size of the tensor (64) must match the existing size (73) at non-singleton dimension 0. Target sizes: [64]. Tensor sizes: [73] | open | 2025-03-13T05:40:48Z | 2025-03-13T05:40:48Z | https://github.com/nl8590687/ASRT_SpeechRecognition/issues/338 | [] | huangboyua | 0 |
CorentinJ/Real-Time-Voice-Cloning | tensorflow | 682 | Issues with pretrained model | I downloaded and installed the pretrained models, but when I try to run the toolbox it says that there are no models. | closed | 2021-02-26T22:02:15Z | 2021-02-28T06:43:52Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/682 | [] | Horus50 | 3 |
graphql-python/graphene | graphql | 1,321 | cannot have Enum member named "description" | if the enum contains member called "descrpition" or "deprecation_reason", graphql schema-bullding validations die with error like :
TypeError: The description of the enum value must be a string
Happens on latest beta version, and depends on grapql's version.
This seems because in create_enum() (former construct_... | closed | 2021-04-09T20:50:10Z | 2022-12-01T10:06:28Z | https://github.com/graphql-python/graphene/issues/1321 | [
"🐛 bug"
] | svilendobrev | 0 |
pennersr/django-allauth | django | 3,518 | How does `_get_apple_public_key` of `AppleOAuth2Adapter` returns None? | I came across issues, where the `_get_apple_public_key` private method returns `None` even though it receives `kid` value from the caller. I believe the code from `_get_apple_public_key` didn't find the `d` from `data` for the given `kid` (So this means, we don't have a public key for the given kid).
```python
... | closed | 2023-11-10T07:28:22Z | 2024-05-05T13:16:38Z | https://github.com/pennersr/django-allauth/issues/3518 | [] | ramchandra-st | 1 |
numba/numba | numpy | 9,199 | Return `Tuple` type containing `Record` type has an error | ```python
import os
import numpy as np
from numba import njit, types
os.environ["NUMBA_DEBUG_TYPEINFER"] = "1"
os.environ["NUMBA_CAPTURED_ERRORS"] = "new_style"
arr = np.array(object=[(1, 2)], dtype=[('a1', 'f8'), ('a2', 'f8')])
@njit
def _goo(arr, i):
rec = arr[i]
return rec, i
@njit
def ... | open | 2023-09-16T14:02:25Z | 2025-03-20T08:20:15Z | https://github.com/numba/numba/issues/9199 | [
"bug - failure to compile"
] | dlee992 | 13 |
flairNLP/flair | nlp | 3,191 | Flair and Pickle | ### Question
Is it just me or is it not possible anymore to load tagged Sentence objects that have been stored in pickle files? If I do so, there's an `TypeError: Span.__new__() missing 1 required positional argument: 'tokens'` thrown. This hasn't been an issue in older flair versions.
Any workarounds? Thank you ... | open | 2023-04-12T13:58:04Z | 2023-09-17T01:27:02Z | https://github.com/flairNLP/flair/issues/3191 | [
"question",
"wontfix"
] | michaelgoeggelmann | 2 |
hbldh/bleak | asyncio | 1,454 | Could not start notify on 0011: Unreachable | * bleak version: v0.21.1
* Python version: v3.11.5
* Operating System: Windows 11
### Description
I run main.py from using Nordic UART service (NUS) to read/write data. But I encountered "Could not start notify on 0011: Unreachable" with the following code.
await client.start_notify(UART_RX_UUID, notification_... | closed | 2023-11-15T03:42:54Z | 2023-11-15T05:32:31Z | https://github.com/hbldh/bleak/issues/1454 | [
"3rd party issue",
"Backend: WinRT"
] | snowuyl | 2 |
aio-libs-abandoned/aioredis-py | asyncio | 1,360 | Aws redis 'Connection closed by server' exception occurs in my program running in aws ecs fargate | ### Describe the bug
aioredis is used in my fastapi web program connected with aws redis. Running for one day or a moment, this exception
'2022-05-04 21:13:47 raise ConnectionError(SERVER_CLOSED_CONNECTION_ERROR)
2022-05-04 21:13:47aioredis.exceptions.ConnectionError: Connection closed by server.' occurs.
I have... | open | 2022-05-11T09:39:23Z | 2022-05-11T09:39:23Z | https://github.com/aio-libs-abandoned/aioredis-py/issues/1360 | [
"bug"
] | bjjoy | 0 |
keras-team/autokeras | tensorflow | 1,049 | Can I change the vocabulary size? Getting this error in AutoKeras (TextClassifier): | ### Bug Description
Getting the following error using multi label classification:
Is there a way to increase the vocabulary?
`Epoch 1/1000
2020-03-17 17:56:31.128359: I tensorflow/stream_executor/platform/default/dso_loader.cc:44] Successfully opened dynamic library cublas64_10.dll
2020-03-17 17:56:31.665519: I ... | closed | 2020-03-17T22:06:41Z | 2020-05-30T18:03:06Z | https://github.com/keras-team/autokeras/issues/1049 | [
"wontfix"
] | nectario | 5 |
gradio-app/gradio | deep-learning | 10,142 | Gradio 5.8.0 - Can't load Hugging Face model repos | ### Describe the bug
After the 5.8.0 update I can no longer load a Hugging Face model within a function that is passed to the Gradio interface function.
The model loads fine in the same script at the top level, outside the Gradio interface
### Have you searched existing issues? 🔎
- [X] I have searched and found... | closed | 2024-12-06T03:53:29Z | 2024-12-06T05:44:18Z | https://github.com/gradio-app/gradio/issues/10142 | [
"bug"
] | shorecodeorg | 4 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 678 | [BUG]: Bot attaches files to direct messages by mistake. | ### Describe the bug
but attaches file to direct message instead of resume option on job application
### Steps to reproduce
Precise steps are unknown, but this presumably happens when the bot receives a new direct message pop-up while it is applying to a job.
### Expected behavior
File should have been attached t... | closed | 2024-10-30T05:40:56Z | 2025-01-22T22:55:54Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/678 | [
"bug",
"stale"
] | sloganking | 3 |
pydantic/pydantic-settings | pydantic | 435 | Error validating Literal types from .env | Validation fails for non-string Literal types when reading values from the environment:
```python
import os
from typing import Literal
from pydantic_settings import BaseSettings, SettingsConfigDict
class LiteralFromEnv(BaseSettings):
A: bool
B: Literal[False]
C: int
D: Literal[1]
m... | closed | 2024-10-05T00:29:47Z | 2024-10-08T10:18:55Z | https://github.com/pydantic/pydantic-settings/issues/435 | [
"unconfirmed"
] | slingshotvfx | 3 |
matplotlib/matplotlib | data-science | 28,944 | [Bug]: calling title before making polar plot | ### Bug summary
Hi, sorry to bother if it is not an issue at all.
Setting title first and then making polar plot messes up the plot and it makes the plot in usual cartesian plane
### Code for reproduction
```Python
import matplotlib.pyplot as plt
theta = [0, 1, 2, 3, 4, 5, 6]
r = [0, 1, 0.5, 1, 0.5, 1, 0]
pl... | closed | 2024-10-07T10:59:43Z | 2024-10-29T21:13:41Z | https://github.com/matplotlib/matplotlib/issues/28944 | [
"Documentation",
"Community support"
] | exekerey | 1 |
streamlit/streamlit | streamlit | 10,758 | Unable to see tracebacks in console for app exceptions | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
Hello, I have encountered a very frustrating ... | closed | 2025-03-12T21:52:06Z | 2025-03-13T16:10:11Z | https://github.com/streamlit/streamlit/issues/10758 | [
"type:bug",
"status:needs-triage"
] | cc-c4 | 2 |
Evil0ctal/Douyin_TikTok_Download_API | fastapi | 577 | 没法获取用户主页的全部视频 | 抖音我想获取100条用户主页视频数据,但是只返回了38条视频数据,我以为max_cursor可以调整,我调了几次都请求不到数据,如何才能连续地获取100条视频数据呢? | closed | 2025-03-09T06:55:30Z | 2025-03-09T07:28:20Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/577 | [
"BUG"
] | ChinaCs7 | 4 |
DistrictDataLabs/yellowbrick | scikit-learn | 1,302 | No figure output of the show method and produce a lot of findfont: Generic family 'sans-serif' not found warnings | **Describe the bug**
I was just following the offical docs (https://www.scikit-yb.org/en/latest/quickstart.html#walkthrough) in jupyter lab environment.
**To Reproduce**
In the first example, data loading was fine,
```python
import pandas as pd
from yellowbrick.datasets import load_bikeshare
from yellowbri... | closed | 2023-04-06T12:18:20Z | 2023-04-06T19:49:56Z | https://github.com/DistrictDataLabs/yellowbrick/issues/1302 | [] | bingyao | 2 |
cvat-ai/cvat | tensorflow | 9,127 | New annotation format guide : "Label is not registered for this task" | Hi all!
When following the instructions for [adding a new annotation format](https://docs.cvat.ai/docs/contributing/new-annotation-format/), at the bottom there is a snippet to import labeled shapes, however when trying to run this
```
shape = task_data.LabeledShape(
type="rectangle",
points=[0, 0, 100, 100],
o... | closed | 2025-02-20T09:02:58Z | 2025-02-21T13:08:14Z | https://github.com/cvat-ai/cvat/issues/9127 | [
"question"
] | vilhub | 1 |
paperless-ngx/paperless-ngx | machine-learning | 9,436 | [BUG] Duplicate email document processing due import filter | ### Description
**[BUG] Duplicate document processing due to mail fetch interval timing**
**Description**
This issue is identical to [[Issue #3419](https://github.com/paperless-ngx/paperless-ngx/issues/3419)](https://github.com/paperless-ngx/paperless-ngx/issues/3419), which was closed because it couldn't be reprodu... | closed | 2025-03-18T18:33:18Z | 2025-03-19T13:58:50Z | https://github.com/paperless-ngx/paperless-ngx/issues/9436 | [
"not a bug"
] | dgehriger | 6 |
deepspeedai/DeepSpeed | pytorch | 5,795 | Will deepspeed be slower than pytorch when training small model with single GPU? [BUG] | **Describe the bug**
I'm new to deepspeed and I'm training a tiny LLM with single gpu. But I fount that seems deepspeed is more slower than casual pytorch with below config:
**To Reproduce**
Here's my ds config:
```
{
"gradient_accumulation_steps": "auto",
"gradient_clipping": "auto",
"steps_per_p... | closed | 2024-07-23T11:20:10Z | 2025-01-21T11:12:22Z | https://github.com/deepspeedai/DeepSpeed/issues/5795 | [
"bug",
"training"
] | Mactarvish | 6 |
AUTOMATIC1111/stable-diffusion-webui | deep-learning | 15,431 | [Bug]: Keep randomly getting "connection errored out" | ### Checklist
- [X] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [X] The issue has not been reported ... | closed | 2024-04-02T08:21:56Z | 2024-06-03T14:40:21Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15431 | [
"bug-report"
] | k52252467 | 1 |
howie6879/owllook | asyncio | 7 | 功能:实现各大站点排行榜推荐 | - [x] owllook数据排行
- [x] 起点
- [x] 纵横百度月票榜:已经失效 故去除
- [x] 纵横 | closed | 2017-07-29T06:24:44Z | 2018-12-21T01:30:49Z | https://github.com/howie6879/owllook/issues/7 | [
"新功能"
] | howie6879 | 2 |
LAION-AI/Open-Assistant | python | 2,851 | Display name spill-over | In isolated cases users misuse their freedom to use unicode display names to set bad names which spill over to other parts of the UI. Specifically affected are the leaderboard and trollboard pages which list users.
Use css styles to clip display names at the border of the surrounding cell's box.
| closed | 2023-04-23T08:41:28Z | 2023-04-25T10:49:32Z | https://github.com/LAION-AI/Open-Assistant/issues/2851 | [
"bug",
"website",
"good first issue"
] | andreaskoepf | 2 |
mljar/mercury | jupyter | 430 | Progress bars for long-running notebooks? | It would be great to add tqdm support for long-running notebooks so that you can display the progress of the notebook load while it is still loading. Otherwise, there is no way to tell how much longer the load will take. | open | 2024-03-09T07:55:04Z | 2024-03-09T07:55:04Z | https://github.com/mljar/mercury/issues/430 | [] | kapily | 0 |
RomelTorres/alpha_vantage | pandas | 313 | Daily data for crypto currencies | 2. Questions
it seems that there are duplicated columns that are the same 1a 1b etc.
` 1a. open (USD) 1b. open (USD) 2a. high (USD) 2b. high (USD) 3a. low (USD) 3b. low (USD) 4a. close (USD) 4b. close (USD) 5. volume 6. market cap (USD)
2021-05-30 2278.74000000 2278.74000000 2282.59000000 2282... | closed | 2021-05-30T19:17:02Z | 2021-05-31T14:38:45Z | https://github.com/RomelTorres/alpha_vantage/issues/313 | [] | MichaelWS | 1 |
rthalley/dnspython | asyncio | 518 | Adding a type hierarchy for dns.message.Message | Support for DNS updates in dnspython is problematic because it's all tightly wrapped up in the message code.
While this is potentially fine for basic cases, more significant usages of it are harder because of lack of correct message section names, no ability to do specialised parsing/error handling (e.g. update me... | closed | 2020-06-24T23:12:29Z | 2020-06-26T21:19:37Z | https://github.com/rthalley/dnspython/issues/518 | [] | nrhall | 3 |
plotly/dash-bio | dash | 79 | Dash Bio Sample Apps | 1) Ideogram
https://github.com/igvteam/igv.js/tree/master
https://igv.org/web/test/examples/bam.html
2) Clustegram
http://qb.cshl.edu/ginkgo/?q=results/_t10breast_navin
https://github.com/robertaboukhalil/ginkgo
3) Sequence viewer
https://hemoglobin-comparison.herokuapp.com/
https://github.com/lmalet/hemogl... | closed | 2018-12-10T01:03:39Z | 2021-05-04T20:25:32Z | https://github.com/plotly/dash-bio/issues/79 | [
"nice-to-have"
] | VeraZab | 0 |
JoeanAmier/TikTokDownloader | api | 222 | 视频下载不完整,好像是还在缓存_internal\cache\temp 临时目录没有移动到目标目录 | 是不是下载太慢 移动文件超时 导致文件没有被移动到目标目录,使得视频下载不完全,还是下载时间间隔太短,导致移动文件超时。
发现部分视频下载不完整,好像是还在缓存_internal\cache\temp 临时目录,没有移动到目标目录。 | open | 2024-05-21T08:36:39Z | 2024-05-30T06:47:06Z | https://github.com/JoeanAmier/TikTokDownloader/issues/222 | [] | areyouoka | 2 |
axnsan12/drf-yasg | django | 48 | Provide consumes and produces at the root of the schema | Hey,
I would like to provide a list of types that the API consumes and produces at the root of the schema but I didn't find the way to achieve it...
The only way I found is to modify the `get_schema` method of `OpenAPISchemaGenerator` se it looks like this:
```python
consumes = ['application/vnd.api+json']
p... | closed | 2018-01-17T13:36:23Z | 2018-01-24T12:44:00Z | https://github.com/axnsan12/drf-yasg/issues/48 | [] | Darkheir | 3 |
fastapi/fastapi | python | 13,400 | Header parameter and model handling does not work as expected |
### Discussed in https://github.com/fastapi/fastapi/discussions/13160
<div type='discussions-op-text'>
<sup>Originally posted by **freud14-tm** January 6, 2025</sup>
### First Check
- [X] I added a very descriptive title here.
- [X] I used the GitHub search to find a similar question and didn't find it.
- [X] I se... | closed | 2025-02-20T16:17:31Z | 2025-03-24T11:33:03Z | https://github.com/fastapi/fastapi/issues/13400 | [
"bug"
] | DuplosFidibuss | 15 |
mwaskom/seaborn | data-science | 3,504 | No module named 'numpay what is this? | closed | 2023-09-27T14:59:50Z | 2023-09-27T22:01:21Z | https://github.com/mwaskom/seaborn/issues/3504 | [] | muhammadmursaleen-nicaas | 1 | |
gradio-app/gradio | machine-learning | 10,458 | Lite: Plotly doesn't work when installed along with altair | ### Describe the bug
In the `outbreak_forecast` demo running on Lite,
Plotly throws the following error.
`plotly==6.0.0` was released and it depends on `narwhals>=1.15.0` (https://github.com/plotly/plotly.py/blob/v6.0.0/packages/python/plotly/recipe/meta.yaml#L28).
However, installing `altair` leads to install `narwh... | closed | 2025-01-29T07:53:43Z | 2025-01-30T07:20:21Z | https://github.com/gradio-app/gradio/issues/10458 | [
"bug",
"gradio-lite"
] | whitphx | 2 |
pyjanitor-devs/pyjanitor | pandas | 891 | [DOC] `get_features_targets` should be removed from general_functions.rst | # Brief Description of Fix
<!-- Please describe the fix in terms of a "before" and "after". In other words, what's not so good about the current docs
page, and what you would like to see it become.
Example starter wording is provided. -->
When I see docs I found [`get_features_targets` page](https://pyjanitor... | closed | 2021-08-23T09:19:24Z | 2021-10-26T03:44:30Z | https://github.com/pyjanitor-devs/pyjanitor/issues/891 | [
"good first issue",
"docfix",
"available for hacking"
] | Zeroto521 | 4 |
mwaskom/seaborn | data-science | 3,703 | Seaborn objects interface: Log transformed bar plot does not plot correctly | I have a quick question regarding the seaborn objects interface. I am trying to simply generate a dodged bar plot with a log scaled y-axis. The bar plot renders without any problem, but as soon as I pass `.scale(y="log")` to the Plot object I get the error `Ill-defined clip_path detected` and instead of a bar, only a l... | closed | 2024-05-31T09:33:43Z | 2024-06-03T20:01:57Z | https://github.com/mwaskom/seaborn/issues/3703 | [] | Kartoffelecke | 1 |
flavors/django-graphql-jwt | graphql | 34 | Can't get token wihen using custom Model. | Thank you for this project.
~~I am using a custom model with different params. (email and password, no username). However, I can't get it to work and I always get "Please, enter valid credentials" when providing email and password in my mutation.~~
My apologies, it was a bug on my side. Thank you for this project... | closed | 2018-09-03T22:45:55Z | 2020-12-14T04:34:16Z | https://github.com/flavors/django-graphql-jwt/issues/34 | [] | kiloreux | 1 |
recommenders-team/recommenders | deep-learning | 1,679 | [BUG] Badge icon does not show in SARplus | ### Description
<!--- Describe your issue/bug/request in detail -->
- https://github.com/microsoft/recommenders/tree/main/contrib/sarplus
The icon that shows the test status does not show properly.
- https://github.com/microsoft/recommenders/tree/main/contrib/sarplus#azure-synapse
JAR location is missing.
###... | closed | 2022-03-22T11:01:14Z | 2022-03-23T13:18:36Z | https://github.com/recommenders-team/recommenders/issues/1679 | [
"bug"
] | anargyri | 1 |
kornia/kornia | computer-vision | 3,077 | lam is computed incorrectly in RandomCutMixV2 | ### Describe the bug
The computation of lambda in this line:
https://github.com/kornia/kornia/blob/52cee42a15f4828adf729e28931479ec5375ed20/kornia/augmentation/_2d/mix/cutmix.py#L90
should be:
```python
lam = 1 - w.to(input.dtype) * h.to(input.dtype) / (width * height) # width_beta * height_beta
```
If a... | open | 2024-11-28T09:18:48Z | 2024-12-18T11:47:53Z | https://github.com/kornia/kornia/issues/3077 | [
"help wanted"
] | m1pro | 4 |
scrapy/scrapy | web-scraping | 6,641 | Unexpected Contract Fail | very strange behaviour, when running ```scrapy crawl``` everything works fine but somehow ```scrapy check``` fails. it says non-200 response but i verify many times and there is no non-200 by website when running ```scrapy crawl```. even more strange is that sometime contracts get passed randomly but most of the time g... | closed | 2025-01-31T05:22:49Z | 2025-01-31T09:29:02Z | https://github.com/scrapy/scrapy/issues/6641 | [] | Ehsan-U | 0 |
babysor/MockingBird | pytorch | 435 | 【长期】如何改参数,搞出更逼真的克隆效果 | 待补充描述
欢迎留言讨论
> 作者却苦于近期精力限制只能势单力薄处理一些小的bug,也看到issue区有不少爱好与开发者想要学习或二次改造更好满足自己需求,不过比较零碎难以展开。为了让项目和AI持续可以给大家提供更多价值,共同学习,我在issue区根据不同主题创建长期交流频道,若留言人数超过20也将建立对应交流群。
> - 如何改参数,搞出更逼真的克隆效果 435
> - 如何改模型,搞出更好效果 436
> - 训练克隆特定人声音&finetune 437
> - 学术/论文讨论/训练分析 438
> - 跨语言支持 440
> - 工程化/新场景讨论(绝不做恶 & 合法合规) 439
| open | 2022-03-07T15:10:55Z | 2023-01-27T05:46:32Z | https://github.com/babysor/MockingBird/issues/435 | [
"documentation",
"discussion"
] | babysor | 2 |
tiangolo/uvicorn-gunicorn-fastapi-docker | pydantic | 45 | GET Query Parameters is not forwarded to docker container | I deployed my apps to my production server in AWS EC2 (Standard Ubuntu VPS)
When I tried to access it with the public IP, the query params seems not forwarded. The log is `180.252.8.xxx:58693 - "GET /get_total_order HTTP/1.1" 200 OK`. The port part is always different every time I accessed it through public IP
but ... | closed | 2020-05-20T00:05:58Z | 2020-06-06T15:49:37Z | https://github.com/tiangolo/uvicorn-gunicorn-fastapi-docker/issues/45 | [] | rizkyarlin | 2 |
brightmart/text_classification | nlp | 128 | git clone error | i git clone the project failing, how can i clone it
------------------------------------------------
error: RPC failed; curl 18 transfer closed with outstanding read data remaining
fatal: The remote end hung up unexpectedly
fatal: early EOF
fatal: index-pack failed
| open | 2019-07-23T01:52:21Z | 2019-07-23T06:15:04Z | https://github.com/brightmart/text_classification/issues/128 | [] | zxyscz | 0 |
deepfakes/faceswap | deep-learning | 836 | Exception in Tkinter callback | When I try to extract, it keeps showing"Loading"
then i press to terminate and it shows excetas follows
> Exception in Tkinter callback
> Traceback (most recent call last):
> File "/home/ist/miniconda3/envs/env/lib/python3.6/tkinter/__init__.py", line 1699, in __call__
> return self.func(*args)
> File "... | closed | 2019-08-13T11:38:41Z | 2019-08-13T11:54:49Z | https://github.com/deepfakes/faceswap/issues/836 | [] | F1sh-Yu | 0 |
stanford-oval/storm | nlp | 110 | How many iterations of questions will it ask? | I am wondering where the setting which simulates a conversation between a Wikipedia writer with a specific persona and an expert ? How many iterations of questions will it ask ? Where is that setting in the code?
_In practice, we limit the conversation to at most M rounds_
Is this the one?
max_conv_turn: int = f... | closed | 2024-07-29T10:28:23Z | 2024-07-31T22:07:18Z | https://github.com/stanford-oval/storm/issues/110 | [] | ferrygun | 5 |
FujiwaraChoki/MoneyPrinter | automation | 24 | GPT keeps including a lot of instructions | GPT keeps givign me stuff like this when requesting; example "tokyo food culture"
> Tokyo Food Culture Script:
>
> Segment 1: Introduction to Tokyo Food Culture
> Tokyo, the bustling capital city of Japan, is not only known for its vibrant culture and advanced technology but also for its rich and divers... | closed | 2024-02-07T09:47:56Z | 2024-02-07T09:56:21Z | https://github.com/FujiwaraChoki/MoneyPrinter/issues/24 | [] | evolite | 0 |
hankcs/HanLP | nlp | 1,005 | 能否基于Word2VecTrainer做word2vec的增量训练? | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2018-10-23T16:41:36Z | 2018-10-28T00:40:32Z | https://github.com/hankcs/HanLP/issues/1005 | [
"question"
] | Wangyq9527 | 2 |
deeppavlov/DeepPavlov | nlp | 1,377 | NER model hangs | Hello, I run model like this:
`python3 -m deeppavlov riseapi ner_ontonotes_bert_mult -p 5000`
Server has 64gb ram and cpu `i7-8700 CPU @ 3.20GHz`. We send requests to api every 2-3 seconds, it works and responds for 50-200 requests and after this server hangs and only reboot can restore it. The same problem with ... | closed | 2021-01-18T08:54:32Z | 2023-07-06T12:09:14Z | https://github.com/deeppavlov/DeepPavlov/issues/1377 | [
"bug"
] | max-frai | 1 |
neuml/txtai | nlp | 316 | Is Embeddings.search() support GPU? | Is Embeddings.search() support GPU? If it is supported, how to use the GPU support?
If it is not supported, do I need to revise codes from
https://github.com/neuml/txtai/blob/3ced24d7e3ee926e4ef58ed510a1edc3ade2bca8/src/python/txtai/ann/faiss.py#L26
to
```python
self.model = faiss.index_cpu_to_all_gpus(index_facto... | closed | 2022-07-29T20:23:14Z | 2022-08-30T13:12:45Z | https://github.com/neuml/txtai/issues/316 | [] | muazhari | 2 |
SYSTRAN/faster-whisper | deep-learning | 512 | Over lapping audio/Cross talk | When two people speak together (like in an interview), the model does very well to capture the words spoken individually by both speakers but the timestamps assigned to those words are aligned so that there is no overlap of timestamps. Model decides to assign one person a set of start and end times which are bunched to... | open | 2023-10-14T04:47:14Z | 2023-10-14T20:24:42Z | https://github.com/SYSTRAN/faster-whisper/issues/512 | [] | ksbedi | 1 |
jupyter-book/jupyter-book | jupyter | 1,428 | How to disable binder button for all pages | ### Describe the enhancement you'd like
I want to disable the binder button but I did not find a way to do it.
In your documentation the binder launch button is sometimes available (e.g., https://jupyterbook.org/interactive/launchbuttons.html) and for some pages it is not (e.g., https://jupyterbook.org/structure/con... | closed | 2021-08-19T13:42:14Z | 2023-01-09T07:02:21Z | https://github.com/jupyter-book/jupyter-book/issues/1428 | [
"enhancement"
] | eotp | 5 |
mwaskom/seaborn | matplotlib | 3,702 | Incorrect errobar for drawstyle='steps-post' | Plotting an errorbar for several step functions draws the error bars ignoring the steps:
```python
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt
data = pd.DataFrame({
"iteration" : [ 1, 3, 8, 1, 3, 8, 1, 3, 8],
"value" : [10, 9, 8, 11, 6, 5, 20, 5, 4],
"run" ... | open | 2024-05-31T08:41:37Z | 2024-05-31T18:05:42Z | https://github.com/mwaskom/seaborn/issues/3702 | [] | MLopez-Ibanez | 2 |
yt-dlp/yt-dlp | python | 11,922 | How to manually process `.part` and `.ytdl` files | ### DO NOT REMOVE OR SKIP THE ISSUE TEMPLATE
- [X] I understand that I will be **blocked** if I *intentionally* remove or skip any mandatory\* field
### Checklist
- [X] I'm asking a question and **not** reporting a bug or requesting a feature
- [X] I've looked through the [README](https://github.com/yt-dlp/yt-dlp#re... | closed | 2024-12-27T14:08:06Z | 2024-12-30T19:15:54Z | https://github.com/yt-dlp/yt-dlp/issues/11922 | [
"question"
] | lantua | 5 |
Anjok07/ultimatevocalremovergui | pytorch | 979 | all the input array dimensions for the concatenation axis must match exactly, but along dimension 0, the array at index 0 has size 2 and the array at index 1 has size 6 | Last Error Received:
Process: Ensemble Mode
If this error persists, please contact the developers with the error details.
Raw Error Details:
ValueError: "all the input array dimensions for the concatenation axis must match exactly, but along dimension 0, the array at index 0 has size 2 and the array at inde... | closed | 2023-11-15T03:26:30Z | 2023-11-15T22:53:09Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/979 | [] | AminElhag | 3 |
mwaskom/seaborn | pandas | 3,049 | Seaborn0.12 stripplot() Newly added parameters 'formatter' | Mr Waskom :
The "stripplot()" Newly added parameters 'formatter'
What does this parameters do ?
Can you give me an example ? | closed | 2022-09-27T11:59:44Z | 2022-09-27T12:38:26Z | https://github.com/mwaskom/seaborn/issues/3049 | [] | jianghui1229 | 2 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 1,300 | Hi I am cumar pro | closed | 2024-06-01T05:56:35Z | 2024-06-01T05:57:06Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1300 | [] | Cumarpro252 | 1 | |
pandas-dev/pandas | pandas | 61,099 | BUG: Can only compare identically-labeled Series objects (string vs. object) | ### Pandas version checks
- [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [x] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/dev/ge... | open | 2025-03-10T20:18:17Z | 2025-03-17T11:05:35Z | https://github.com/pandas-dev/pandas/issues/61099 | [
"Bug",
"Strings",
"Needs Discussion"
] | wahsmail | 2 |
modin-project/modin | pandas | 7,287 | Update Modin on Dask documentation. | closed | 2024-05-24T16:41:21Z | 2024-05-27T11:32:46Z | https://github.com/modin-project/modin/issues/7287 | [] | Retribution98 | 0 | |
jessevig/bertviz | nlp | 68 | Visualizing Encoder Decoder Attention | I am wondering if there is a method visualize the attention between an encoder input and a decoder input (for seq2seq)? Current methods seems to only work for self attention. | closed | 2021-03-04T04:19:39Z | 2021-04-18T19:05:42Z | https://github.com/jessevig/bertviz/issues/68 | [] | kevin3567 | 1 |
MaartenGr/BERTopic | nlp | 1,969 | Switch from setup.py to pyproject.toml | The `pyproject.toml` file is decribed in [PEP 621](https://peps.python.org/pep-0621/). It is the recommended way to package Python projects these days.
Please have a look at my fork's version of this file: <https://github.com/afuetterer/BERTopic/blob/1969-toml/pyproject.toml>
You are still able to do a local `pip... | closed | 2024-05-04T06:14:50Z | 2024-06-06T09:23:30Z | https://github.com/MaartenGr/BERTopic/issues/1969 | [] | afuetterer | 5 |
vimalloc/flask-jwt-extended | flask | 561 | PyJWT 2.10.0 Enforces `sub` | Recently the version of the PyJWT dependency was upgraded to 2.10.0, which adds new token verification behavior. In this version PyJWT enforces that the `sub` claim in the JWT be a string, and deems the token invalid if that verification fails (by default). This issue in PyJWT has a discussion about the change, and way... | closed | 2024-11-19T23:03:45Z | 2024-11-20T23:46:17Z | https://github.com/vimalloc/flask-jwt-extended/issues/561 | [] | jlucier | 5 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 3,815 | traceback when adding a duplicated user | ### What version of GlobaLeaks are you using?
4.13.18
### What browser(s) are you seeing the problem on?
All
### What operating system(s) are you seeing the problem on?
Linux
### Describe the issue
An administrator tried to create a user, accidentally using the same username of another user already present in th... | closed | 2023-11-24T17:40:54Z | 2023-12-13T18:40:11Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/3815 | [
"T: Bug",
"Triage"
] | mapreri | 3 |
biolab/orange3 | scikit-learn | 6,770 | Could not Fetch Dataset when using Orange | When trying to utilise the dataset widget on Orange, i get error "could not fetch dataset list".
I have also tried to allow the Orange application through my firewall, but still get the same error.
Can you please assist.
<!--
If something's not right with Orange, fill out the bug report template at:
https://gi... | closed | 2024-03-22T06:57:21Z | 2024-11-23T09:22:49Z | https://github.com/biolab/orange3/issues/6770 | [] | kerwindevries | 4 |
modelscope/modelscope | nlp | 1,202 | modelscope push_to_hub displays a progress bar (or logs print in the command line) | **Describe the feature**
Features description
**Motivation**
A clear and concise description of the motivation of the feature. Ex1. It is inconvenient when [....]. Ex2. There is a recent paper [....], which is very helpful for [....].
**Related resources**
If there is an official code release or third-party implemen... | open | 2025-01-24T09:30:44Z | 2025-02-24T02:04:41Z | https://github.com/modelscope/modelscope/issues/1202 | [] | Jintao-Huang | 1 |
scikit-optimize/scikit-optimize | scikit-learn | 1,095 | Parallelize scikit-optimize using Dask | This issue is only to make it easy to find this information. If there's interest I can make a PR to add this to the documentation samples.
Originally published here and might be updated over time: <https://rigtorp.se/notes/skopt/>
First initialize a `Optimizer` instance:
```python
from skopt import Optimizer
... | closed | 2021-12-05T17:51:10Z | 2024-01-12T17:19:16Z | https://github.com/scikit-optimize/scikit-optimize/issues/1095 | [
"Question"
] | rigtorp | 2 |
AntonOsika/gpt-engineer | python | 455 | You should explicitly warn user you are collecting data | This should be put in README, instead of hidden inside Term of Use.
Also defining `COLLECT_LEARNINGS_OPT_OUT=true` has no effect since what the code actually check is `COLLECT_LEARNINGS_OPT_IN`.
| closed | 2023-06-30T14:07:20Z | 2023-07-02T17:19:14Z | https://github.com/AntonOsika/gpt-engineer/issues/455 | [] | bhy | 1 |
streamlit/streamlit | data-visualization | 10,744 | Add an optimized search input widget | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
Add a specialized text input widget optimized for search usecases. Potential features:
- Search icon on the l... | open | 2025-03-12T15:14:57Z | 2025-03-14T15:55:04Z | https://github.com/streamlit/streamlit/issues/10744 | [
"type:enhancement",
"area:widgets",
"feature:st.text_input"
] | lukasmasuch | 1 |
zappa/Zappa | django | 717 | [Migrated] AuthorizationScopes not supported | Originally from: https://github.com/Miserlou/Zappa/issues/1816 by [urluba](https://github.com/urluba)
## Context
When using Cognito, API Gateway provides the authorizationScopes property on the API Gateway Method to match against scopes in the access token.
https://docs.aws.amazon.com/AWSCloudFormation/latest/User... | closed | 2021-02-20T12:41:02Z | 2024-04-13T18:14:30Z | https://github.com/zappa/Zappa/issues/717 | [
"no-activity",
"auto-closed"
] | jneves | 2 |
ExpDev07/coronavirus-tracker-api | fastapi | 262 | Population Numbers Inaccurate | country_population data is using old data. From what I can tell, It may be using data from the last Census nearly 10 years ago. I may have missed documentation noting that, but just making sure it wasn't missed.
Thanks for the API! it's great! | closed | 2020-04-05T14:15:21Z | 2020-04-11T18:05:28Z | https://github.com/ExpDev07/coronavirus-tracker-api/issues/262 | [
"enhancement",
"question"
] | ccedacero | 8 |
mlflow/mlflow | machine-learning | 14,573 | [DOC-FIX] 403 on README.md "running mflow anywhere" link | ### Willingness to contribute
Yes. I can contribute a documentation fix independently.
### URL(s) with the issue
https://[mlflow.org/docs/index.html#running-mlflow-anywhere](https://mlflow.org/docs/index.html#running-mlflow-anywhere)
### Description of proposal (what needs changing)
https://github.com/mlflow/mlflo... | closed | 2025-02-13T01:42:10Z | 2025-02-13T07:39:01Z | https://github.com/mlflow/mlflow/issues/14573 | [
"area/docs",
"has-closing-pr"
] | ImMamey | 1 |
fastapi/sqlmodel | pydantic | 259 | How to convert sub-query SQLModel objects to Strawberry Objects | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | closed | 2022-03-01T11:29:40Z | 2022-03-01T11:45:48Z | https://github.com/fastapi/sqlmodel/issues/259 | [
"question"
] | martarho | 0 |
unit8co/darts | data-science | 2,446 | fix: PerformanceWarning - DataFrame is highly fragmented | I'll make a PR and remove the warning:
```
darts/tests/utils/test_timeseries_generation.py: 635 warnings
darts/darts/utils/timeseries_generation.py:681: PerformanceWarning: DataFrame is highly fragmented. This is usually the result of calling `frame.insert` many times, which has poor performance. Consider joi... | closed | 2024-07-03T16:34:12Z | 2024-07-08T09:13:20Z | https://github.com/unit8co/darts/issues/2446 | [] | quant12345 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.