

The dataset viewer is not available for this split.
Error code:   StreamingRowsError
Exception:    TypeError
Message:      Couldn't cast array of type list<item: binary> to string
Traceback:    Traceback (most recent call last):
                File "/src/services/worker/src/worker/utils.py", line 147, in get_rows_or_raise
                  return get_rows(
                      dataset=dataset,
                  ...<4 lines>...
                      column_names=column_names,
                  )
                File "/src/libs/libcommon/src/libcommon/utils.py", line 272, in decorator
                  return func(*args, **kwargs)
                File "/src/services/worker/src/worker/utils.py", line 127, in get_rows
                  rows_plus_one = list(itertools.islice(safe_iter(ds, dataset=dataset), rows_max_number + 1))
                File "/src/services/worker/src/worker/utils.py", line 483, in safe_iter
                  yield from ds.decode(False) if ds.features else ds
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2951, in __iter__
                  for key, example in ex_iterable:
                                      ^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2461, in __iter__
                  for key, pa_table in self._iter_arrow():
                                       ~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2486, in _iter_arrow
                  for key, pa_table in self.ex_iterable._iter_arrow():
                                       ~~~~~~~~~~~~~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 547, in _iter_arrow
                  for key, pa_table in iterator:
                                       ^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 430, in _iter_arrow
                  for key, pa_table in self.generate_tables_fn(**gen_kwags):
                                       ~~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/hdf5/hdf5.py", line 87, in _generate_tables
                  yield Key(file_idx, batch_idx), cast_table_to_features(pa_table, self.info.features)
                                                  ~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2285, in cast_table_to_features
                  arrays = [cast_array_to_feature(table[name], feature) for name, feature in features.items()]
                            ~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 1861, in wrapper
                  return pa.chunked_array([func(chunk, *args, **kwargs) for chunk in array.chunks])
                                           ~~~~^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2068, in cast_array_to_feature
                  _c(array.field(name) if name in array_fields else null_array, subfeature)
                  ~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 1863, in wrapper
                  return func(array, *args, **kwargs)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2152, in cast_array_to_feature
                  return array_cast(
                      array,
                  ...<2 lines>...
                      allow_decimal_to_str=allow_decimal_to_str,
                  )
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 1863, in wrapper
                  return func(array, *args, **kwargs)
                File "/usr/local/lib/python3.14/site-packages/datasets/table.py", line 2016, in array_cast
                  raise TypeError(f"Couldn't cast array of type {_short_str(array.type)} to {_short_str(pa_type)}")
              TypeError: Couldn't cast array of type list<item: binary> to string
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
MOV-AAD: Multimodal Auditory Attention Dataset



Official dataset repository for MOV-AAD, a large-scale multimodal dataset designed for investigating selective auditory attention decoding (AAD), spatial audio localization, and cross-modal peripheral physiological tracking during dynamic, naturalistic conversations with moving sound sources.
🎬 10-Minute Walkthrough & Overview
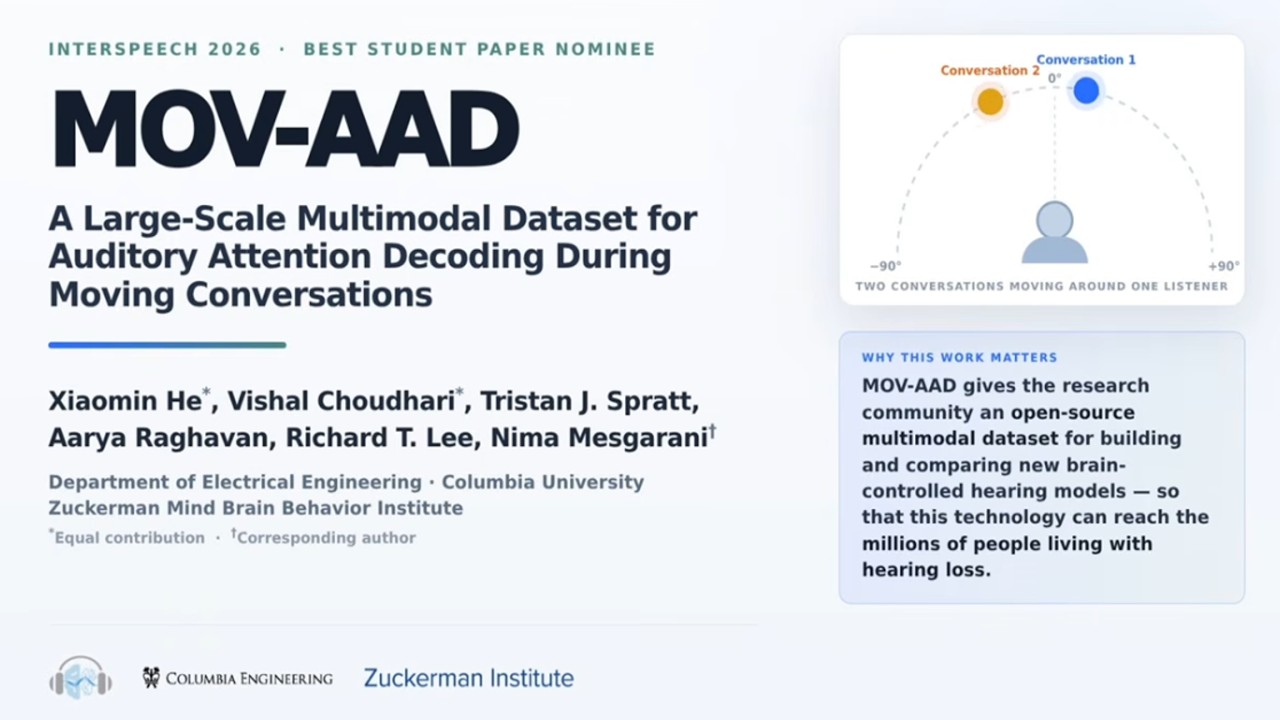
(Experimental paradigm, sensor alignment, & demos)
|

(Click image or link to open high-res figure)
|
📜 Citation
If you use MOV-AAD in your research, please cite our Interspeech 2026 paper:
@inproceedings{he26g_interspeech,
  title     = {{MOV-AAD: A Large-Scale Multimodal Dataset for Auditory Attention Decoding During Moving Conversations}},
  author    = {Xiaomin He and Vishal Choudhari and Tristan J. Spratt and Aarya Raghavan and Richard T. Lee and Nima Mesgarani},
  year      = {2026},
  booktitle = {{Interspeech 2026 [Long Track]}},
  pages     = {3237--3246},
  doi       = {10.21437/Interspeech.2026-3556},
  issn      = {2958-1796}
}
📊 Dataset At A Glance
| 10 Synchronized Modalities | 1200 Hz Unified Sampling Rate | 50 Healthy Subjects |
|---|---|---|
| 64-ch EEG, Gaze, Pupil, Respiration Airflow, Respiration Effort, GSR, PPG, SpO₂, Temperature, Motion | Fully aligned across all neural & physiological data streams | Age 24 ± 4.5 years, verified normal hearing status |
| ~75 Min Total Duration | 4 Distinct Tasks | Rich Behavioral Tracking |
|---|---|---|
| Massive continuous recording per participant for AAD modeling | From structured validation to naturalistic conversations | Active repeated-word detection & precise localization reports |
🛠️ Experimental Paradigms & Data Composition
The dataset encompasses four sequential experimental tasks per participant, transition from structured sensory validation to ecologically valid, naturalistic listening scenarios:
- Repeated Sentence Task (120 trials): A baseline neural reliability check featuring shuffled short sentences repeated without background noise to evaluate within-subject response consistency.
- Localization Task (54 trials): A spatial perception task conducted prior to the main experiment to familiarize participants with spatial cues and assess their localization accuracy.
- Single-Conversation Task (40 trials): An active listening task where participants track naturalistic, continuous conversational narratives from a single dynamically moving sound source.
- Multi-Conversation Task (56 trials): A selective attention task requiring participants to attend to one target conversational stream while ignoring a competing co-spatial distractor.
Parameters Summary Matrix
| Task / Condition | Experimental Purpose | Stimuli & Speakers | Spatial Configuration | Background Noise | Total Stimuli / Duration | Available Modalities |
|---|---|---|---|---|---|---|
| Repeated Sentence Task | Split-half & odd-even reliability check | 6 short sentences (shuffled); 3M/3F talkers | Diotic presentation (None) | None | 120 trials(~12 min) |
✓ EEG & Physio ✓ Behavioral |
| Localization Task | Familiarize spatial cues & assess perception accuracy | Independent short sentences; Single talker/trial | Static; 9 coordinates (-90° to +90° in 22.5° steps) | None | 54 sentences(Short segments) |
- No Neural ✓ Behavior Metrics |
| Single-Conversation Task | Track neural tracking of speech with spatial change | Continuous dialogue context; Multi-turn talkers | HRTF-based dynamic moving (-90° to +90°); RMS-matched | Diotic pedestrian/babble noise (-9, -12 dB) | 40 trials(~30 min) |
✓ EEG & Physio ✓ Behavior & Audio |
| Multi-Conversation Task | Evaluate selective Auditory Attention Decoding (AAD) | Two parallel stories; Continuous context & turn-taking | Two independent HRTF sources moving dynamically within ±90° | Diotic pedestrian/babble noise (-9, -12 dB) | 56 trials(~45 min) |
✓ EEG & Physio ✓ Behavior & Audio |
🔬 Recording Modalities Specification
All signals were synchronously recorded and streamed through g.tec HIamp and a Simulink GUI at 1200 Hz, with a hardware 60 Hz notch filter applied during acquisition.
- EEG: 64 channels, 1200 Hz high-density neural recordings via
g.tec g.HIamp. - Pupil Dilation: Binocular measurements captured at 60 Hz via
Tobii Pro Nanoand upsampled with aligned temporal interpolation to 1200 Hz. - Gaze Location: Screen-coordinate gaze tracking (X and Y axes) mapped to screen size (display dimensions: 52 × 32 cm, viewing distance: roughly 60 cm to account for natural posture variation), recorded at 60 Hz and unified to 1200 Hz.
- Respiration Flow: Nasal airflow monitoring.
- Respiration Effort: Thoracic expansion belt (chest) tracking.
- GSR: Galvanic skin response.
- PPG: Raw optical photoplethysmography waveform.
- Heart Rate: Derived beat-by-beat heart rate extracted from raw PPG streams.
- SpO₂: Peripheral oxygen saturation monitoring.
- Temperature: Skin temperature monitoring, recorded from the dorsal surface of the non-dominant hand.
- Accelerometer: Triaxial motion tracking sampled at 1200 Hz, mounted on the chair back to capture gross body and seat vibrations.
📂 Dataset Directory Structure
The released dataset is organized by experimental task. The four task folders are arranged in parallel, with task-specific recordings and stimuli stored together. For the conversation tasks, each subject recording file contains all trials from that task for the participant, including the synchronized neural, physiological, and behavioral modalities.
MOV-AAD/
├── SC/                              # Single-Conversation Task
│   ├── recordings/                  # One subject file per participant; all SC trials and synchronized modalities
│   │   ├── sub-001.*
│   │   ├── sub-002.*
│   │   └── ...
│   └── stimulus/
│       ├── audio/                   # Trial-level audio presented during SC
│       └── trajectory/              # Trial-level source-motion trajectories
│
├── MC/                              # Multi-Conversation Task
│   ├── recordings/                  # One subject file per participant; all MC trials and synchronized modalities
│   │   ├── sub-001.*
│   │   ├── sub-002.*
│   │   └── ...
│   └── stimulus/
│       ├── audio/                   # Trial-level target/distractor audio used during MC
│       └── trajectory/              # Trial-level source-motion trajectories
│
├── localization/                    # Localization Task
│   ├── recordings/                  # Subject-level behavioral response recordings
│   │   ├── sub-001.*                # Localization choice responses
│   │   └── ...
│   └── stimulus/                    # Stimuli used in the localization task
│
├── repeated_sentence/               # Repeated Sentence Task
│   ├── recordings/                  # Subject-level recordings for the repeated-sentence task
│   │   ├── sub-001.*
│   │   └── ...
│   └── stimulus/                    # Repeated-sentence stimuli
│
├── preprocessing_scripts/           # Preprocessing and alignment scripts
├── README.md
└── dataset_info.json
Organization Notes
- Task-first organization: Data are grouped by experimental task rather than by participant.
- SC and MC recordings: Each subject file contains that participant's complete set of trials for the corresponding conversation task, with all available synchronized modalities stored together.
- Conversation stimuli: Audio and source trajectories are stored under each conversation task's
stimulus/directory so that each trial can be paired with the exact presented stimulus and motion path. - Localization task: The released subject recordings contain the behavioral localization responses, corresponding to the participant's multiple-choice spatial reports, together with the task stimuli.
- Repeated Sentence task: Subject recordings and the corresponding repeated-sentence stimuli are stored within the same task-level structure.
🛠️ Preprocessing & Data Alignment Notes
To ensure high data reproducibility, the released dataset provides clean, aligned pipelines processed as follows:
EEG Artifact Handling & Channel Interpolation
- EEG channels exhibiting abnormal cross-trial variance or high-frequency impedance spikes were automatically flagged.
- Bad channels were reconstructed using Spherical Spline Interpolation (following standard
EEGLABprocedures [Delorme & Makeig, 2004]). - Note: Peripheral modalities are released in a minimally processed form (hardware notch filtering only) to retain raw autonomic dynamics.
Trial Epoching & Windowing
- Conversation Tasks (SC & MC): Each continuous trial includes a 3-second pre-onset baseline segment prior to speech onset.
- Baseline Period: Vital for calculating trial-level neural entrainment, baseline normalization, or calculating time-frequency relative power.
Cross-Modal Temporal Realignment
- Primary sync was established via hardware trigger pulses routed simultaneously into the
g.tecdigital input channel. - Fine-grained temporal jitter was eliminated post-hoc via cross-correlation analysis between the recorded acoustic playback loop and the original master stimulus waveforms, ensuring sub-millisecond precision.
- Primary sync was established via hardware trigger pulses routed simultaneously into the
💻 Download & Access
Because of the massive scale of the multi-channel recordings, the full dataset archive is hosted externally across dedicated data repositories.
📦 Access Channels
Google Drive (Primary Archive — Controlled Access)
- Link: Google Drive Master Archive
- Access Note: Click Request Access on Google Drive. Access requests are approved manually in accordance with our institutional governance protocol. You can download the complete archive or select specific task folders (
SC/,MC/,localization/,repeated_sentence/) as needed.
Hugging Face Hub (In Preparation)
- Link:
naplabdataset/mov-aad - Access Note: Dataset upload is currently in progress. Direct CLI and programmatic loading via Hugging Face will be supported upon completion.
- Link:
- Downloads last month
- 202