
owner stringclasses 14
values | repo stringclasses 14
values | id int64 116k 4.61B | issue_number int32 1 181k | author stringlengths 1 39 | body stringlengths 1 262k | created_at timestamp[us]date 2000-06-06 02:40:44 2026-06-02 20:16:18 | updated_at timestamp[us]date 2000-06-06 02:40:44 2026-06-02 20:22:56 | reactions unknown | author_association stringclasses 5
values |
|---|---|---|---|---|---|---|---|---|---|
ClickHouse | ClickHouse | 628,907,414 | 6,464 | azat | >Here's another example without group by:
without `GROUP BY` but with aggregation (since `sum()`/`count()` requires final aggregate)
But does not looks like this is how it should work anyway.
Can you provide `select name, value from system.settings where changed` ? (and full output with `send_logs_level='trace'`... | 2020-05-14T21:56:43 | 2020-05-14T21:58:58 | {} | MEMBER |
ClickHouse | ClickHouse | 629,153,853 | 10,839 | cailin-lai | Hi @chengbinghan , are there any workarounds to fix this issue?
Thanks! | 2020-05-15T10:14:45 | 2020-05-15T10:14:45 | {} | NONE |
ClickHouse | ClickHouse | 629,569,996 | 10,957 | volfco | Stack Trace
```
2020.05.16 00:50:28.194142 [ 31215 ] {5a7c6390-5c1b-4305-8636-48bea3205f89} <Error> executeQuery: Code: 493, e.displayText() = DB::Exception: Row policy `plc_dyn_testing ON default.pdnsQueryMetrics_shard`: cannot insert because Row policy `plc_dyn_testing ON default.pdnsQueryMetrics_shard` already exi... | 2020-05-16T01:38:00 | 2020-05-16T01:38:00 | {} | NONE |
ClickHouse | ClickHouse | 628,652,826 | 10,911 | den-crane | ERROR: type should be string, got "\r\nhttps://github.com/ClickHouse/ClickHouse/issues/10212#issuecomment-612676750" | 2020-05-14T13:55:11 | 2020-05-14T13:55:11 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,681,129 | 10,907 | 4ertus2 | Could you add trace in server log related to to the error, please? | 2020-05-14T14:42:16 | 2020-05-14T16:34:04 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,870,033 | 10,055 | filimonov | > @filimonov I get the same error if ClickHouse is compiled with OpenSSL 1.1.1.
In the meanwhile i've also checked the connection with openssl 3 cli and it also worked. :\ | 2020-05-14T20:28:53 | 2020-05-14T20:28:53 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,995,782 | 10,905 | gubinjie | @den-crane
Thank you! | 2020-05-15T02:50:10 | 2020-05-15T02:50:10 | {} | NONE |
ClickHouse | ClickHouse | 629,303,786 | 10,941 | alesapin | According to trace, you have some incorrect log entry (empty) in your replication queue. How is it related to synchronization? | 2020-05-15T15:22:48 | 2020-05-15T15:22:48 | {} | MEMBER |
ClickHouse | ClickHouse | 629,368,862 | 10,948 | den-crane | duplicate https://github.com/ClickHouse/ClickHouse/issues/10907 | 2020-05-15T16:54:00 | 2020-05-15T16:54:00 | {} | CONTRIBUTOR |
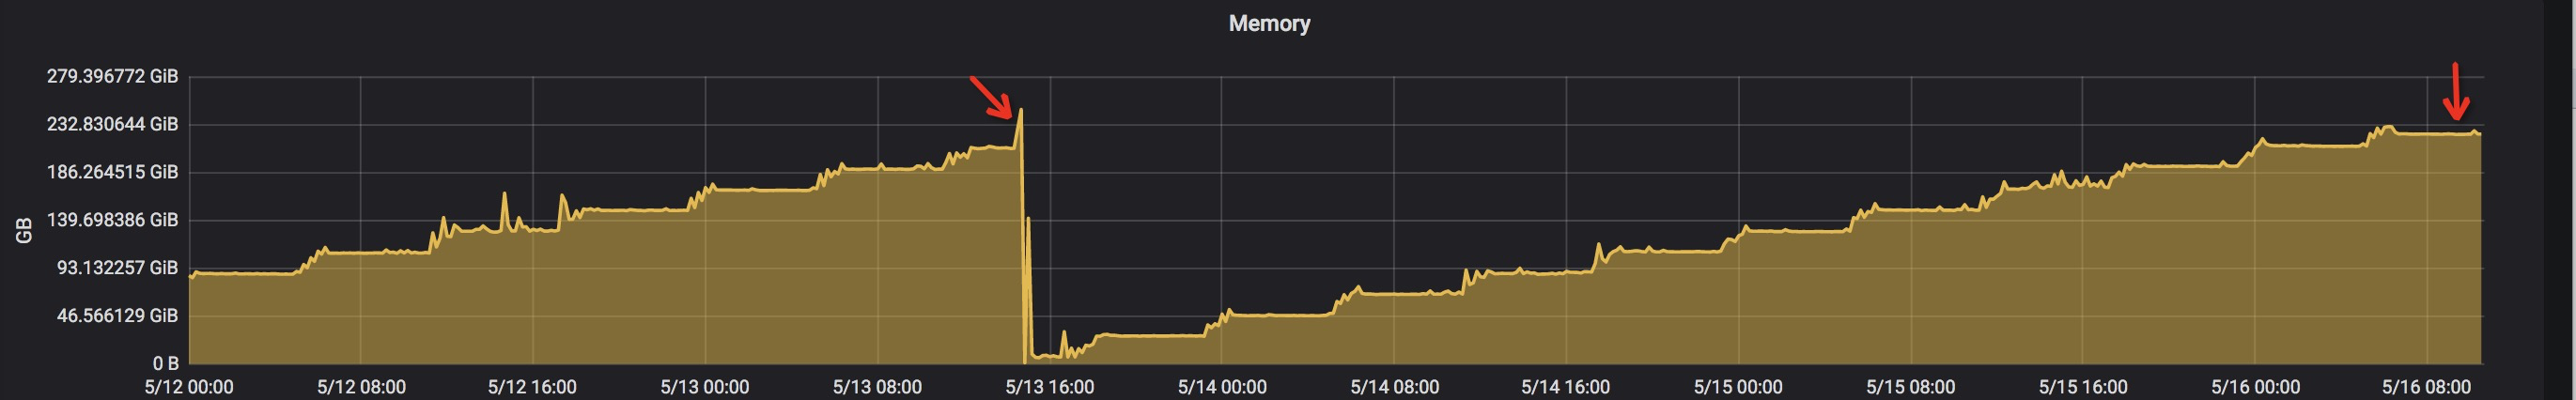
ClickHouse | ClickHouse | 629,576,986 | 10,917 | huang--yijian | Now is 2020-5-16 10:41:35. The current memory footprint is high, as below graph shows.
The related trace-level log of around 1 minute is attached. Let us know if you need more log.
[long_text_2020-05-16-10-3... | 2020-05-16T02:43:12 | 2020-05-16T02:43:35 | {} | NONE |
ClickHouse | ClickHouse | 628,776,369 | 10,913 | 4ertus2 | The reason is right table is not rewritten to subquery:
```
ANALYZE SELECT count(*)
FROM hits AS l
INNER JOIN hits AS r USING (EventDate)
WHERE (l.EventDate < today()) AND (r.EventDate < today())
┌─explain───────────────────────────────────────────────────────────────────────────────────────────────────────────... | 2020-05-14T17:21:46 | 2020-05-14T17:26:01 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,081,099 | 10,926 | alexey-milovidov | 33 successful checks - what a nice day! | 2020-05-15T07:35:16 | 2020-05-15T07:35:16 | {
"laugh": 1
} | MEMBER |
ClickHouse | ClickHouse | 629,153,644 | 10,797 | weiyongyuan | wow,:thumbsup:Thank you very much!That;s waht i want!:smiley:But in the past time,i don't understand distributed_group_by_no_merge.haha,I've troubled you so much!Thanks you who works to make clickhouse better,faster!You really do a very meaningful job! | 2020-05-15T10:14:12 | 2020-05-15T10:16:46 | {} | NONE |
ClickHouse | ClickHouse | 629,344,223 | 10,906 | kaijianding | Another simper solution comes to my mind.
A skipping index like `INDEX a (concat(year, month, day)) TYPE minmax GRANULARITY 3` should be helpful to reduce disk read for a sql who has where condition like `concat(year, month, day) between '20191210' and '20200515'`.
```sql
alter table test14 add INDEX a (concat(... | 2020-05-15T16:07:03 | 2020-05-15T16:27:43 | {} | NONE |
ClickHouse | ClickHouse | 628,604,775 | 10,897 | silviucpp | @alexey-milovidov I can replicate this problem on OSX no matter what build I'm using. The offcial build or building myself...
Anything that can generate this ? | 2020-05-14T12:35:56 | 2020-05-14T12:35:56 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,821,136 | 8,096 | inakivb | Hello,
I'm having the same problem. Is there any workarround to make two joins and also a IN ?
Thank you! | 2020-05-14T18:46:43 | 2020-05-14T18:46:43 | {} | NONE |
ClickHouse | ClickHouse | 628,880,189 | 7,714 | SaltTan | https://github.com/ClickHouse/ClickHouse/issues/9132 was fixed in 20.1.7 | 2020-05-14T20:51:32 | 2020-05-14T20:51:32 | {
"heart": 1
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,074,365 | 10,918 | alexey-milovidov | Awesome! | 2020-05-15T07:19:56 | 2020-05-15T07:19:56 | {} | MEMBER |
ClickHouse | ClickHouse | 629,186,833 | 8,096 | maqroll | Seems to be fixed in version 20.3.8.53. | 2020-05-15T11:37:45 | 2020-05-15T11:37:45 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,201,365 | 10,884 | brefre | I also increased retries from 2 to 3, to see if it helps. I don't have many errors during the day, so it takes some time before I can see how it behaves | 2020-05-15T12:14:32 | 2020-05-15T12:14:32 | {} | NONE |
ClickHouse | ClickHouse | 629,242,747 | 10,887 | alesapin | I don't know why, but zookeeper dies about 350 times during these test run:
```
$ cat docker.log | grep 'Exception causing close of session 0x0: ZooKeeperServer not running' | wc -l
347
```
On my machine, I rarely have single such failure... | 2020-05-15T13:41:52 | 2020-05-15T13:42:09 | {} | MEMBER |
ClickHouse | ClickHouse | 629,431,057 | 10,605 | georgantasp | Seeing the same from mysql source. | 2020-05-15T19:11:37 | 2020-05-15T19:11:37 | {} | NONE |
ClickHouse | ClickHouse | 628,602,606 | 10,862 | hhell | > date formatting
Related: should this option affect `toString(toDateTime(…))`? | 2020-05-14T12:31:51 | 2020-05-14T12:31:51 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,644,599 | 10,897 | alexey-milovidov | @qoega Please validate. | 2020-05-14T13:42:28 | 2020-05-14T13:42:28 | {} | MEMBER |
ClickHouse | ClickHouse | 628,743,120 | 10,897 | silviucpp | OK so I found the real problem. background_pool_size If is less than 11 mutations are freezing forever. If is 11 or more works like charm.
I have a feeling that's because of :
M(SettingUInt64, number_of_free_entries_in_pool_to_execute_mutation, 10, "When there is less than specified number of free entries in po... | 2020-05-14T16:23:35 | 2020-05-14T16:23:35 | {
"+1": 2
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,785,824 | 10,914 | 4ertus2 | Workaround: `set optimize_move_to_prewhere = 0` | 2020-05-14T17:40:39 | 2020-05-14T17:40:39 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,994,811 | 10,797 | weiyongyuan | > > In my tests,when group_by_overflow_mode='break',the local node still return all the distinct keys on it.
>
> I guess you checked on very small number of rows, and in case of `group_by_overflow_mode='break'` it will "break"/stop the aggregation from the next block
>
> > the local node still return all the dist... | 2020-05-15T02:46:55 | 2020-05-15T02:46:55 | {} | NONE |
ClickHouse | ClickHouse | 629,275,042 | 8,976 | sundarv85 | @blinkov how safe is it to upgrade to the latest version.. this is production db.. so we are not really sure if we could just upgrade.. Btw, does clickhouse offer any LTS releases.. | 2020-05-15T14:45:19 | 2020-05-15T14:45:19 | {} | NONE |
ClickHouse | ClickHouse | 629,284,504 | 8,559 | alesapin | Actually your idea (give mutations higher priority) is already implemented. First of all, you can tune `max_replicated_mutations_in_queue` and `max_replicated_merges_in_queue`. It allows you to have as many mutations in the queue as you want. Another setting is `number_of_free_entries_in_pool_to_execute_mutation`. It h... | 2020-05-15T15:03:49 | 2020-05-15T15:03:49 | {
"+1": 1
} | MEMBER |
ClickHouse | ClickHouse | 629,367,771 | 10,949 | Fanduzi | > Not yet. Probably it will be the next stable release 20.4 or 20.5 #10387
Where is the user information now stored? | 2020-05-15T16:52:02 | 2020-05-15T16:52:02 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,369,855 | 10,949 | den-crane | /var/lib/clickhouse/access/
quotas.list
roles.list
row_policies.list
settings_profiles.list
users.list
| 2020-05-15T16:56:04 | 2020-05-15T16:56:04 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,579,382 | 3,561 | nikitamikhaylov | Maybe the problem is in your sharding key? Try to use pure `rand()` to check. | 2020-05-14T11:44:58 | 2020-05-14T11:44:58 | {} | MEMBER |
ClickHouse | ClickHouse | 628,671,580 | 10,906 | den-crane | I highly doubt that it could be implemented or will be implemented in next 5 years.
You should design your tables accordingly to CH.
for example
```
CREATE TABLE test14 (
...
xxxx String materialized concat(year, month, day)
) PARTITION BY xxxx
```
or write SQL queries like `where year = '2020' and... | 2020-05-14T14:26:13 | 2020-05-14T14:33:00 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,056,764 | 10,797 | azat | >Can we add a new group_by_mode that local node will aggregate all keys in the query condition ,but return a topK or bottomk(determined by order ) to distribute node?
But this will not reduce memory usage, while `group_by_overflow_mode` created for this
Not sure that I understand you correctly but maybe you can a... | 2020-05-15T06:34:45 | 2020-05-15T06:34:45 | {} | MEMBER |
ClickHouse | ClickHouse | 629,461,868 | 7,900 | vdimir | > Hello, this looks cool. Just few comments/questions : so we have a basic /metrics endpoints which answer so hardcoded queries and we can add some predefined_queries in http_handler conf.
>
> Great but it would be better if we can add predefined_queries at the end of the same path /metrics endpoints (unless I miss so... | 2020-05-15T20:18:31 | 2020-05-15T20:18:31 | {} | MEMBER |
ClickHouse | ClickHouse | 628,676,928 | 10,884 | filimonov | Check that: https://github.com/edenhill/librdkafka/issues/1470#issuecomment-355544200
So your broker rejected commit because during `offsets.commit.timeout.ms` (5000 by default),
there were not enough replicas available for the `__consumer_offsets` topic.
You can try to increase `offsets.commit.timeout.ms` (on b... | 2020-05-14T14:35:11 | 2020-05-14T14:36:23 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,694,759 | 10,881 | byx313 | > Hello! Your `schema.xml` is not informative. You don't provide us any information, especially table schema. However I noticed that you have an error near the tag '**engine**'. I think the problem is that you didn't specify the engine of your table. That's why copier сan't parse this (empty string). Please read this a... | 2020-05-14T15:03:27 | 2020-05-14T15:03:27 | {} | NONE |
ClickHouse | ClickHouse | 628,718,370 | 10,881 | byx313 | > Hello! Your `schema.xml` is not informative. You don't provide us any information, especially table schema. However I noticed that you have an error near the tag '**engine**'. I think the problem is that you didn't specify the engine of your table. That's why copier сan't parse this (empty string). Please read this a... | 2020-05-14T15:41:25 | 2020-05-14T15:41:25 | {} | NONE |
ClickHouse | ClickHouse | 628,900,300 | 9,641 | azat | >So i see duplicated row from not local shard.
FWIW you can see from which node the rows came using `_shard_num` "virtual" column:
```sql
select host_name, date, x from adv.distr_replicas join system.clusters as c on _shard_num = c.shard_num and c.cluster = 'all'
```
But, it will not work in your version (19... | 2020-05-14T21:38:41 | 2020-05-14T21:38:41 | {} | MEMBER |
ClickHouse | ClickHouse | 629,249,660 | 10,009 | qoega | Already fixed in #10410 | 2020-05-15T13:55:20 | 2020-05-15T13:55:20 | {} | MEMBER |
ClickHouse | ClickHouse | 629,366,191 | 10,949 | den-crane | Not yet. Probably it will be the next stable release 20.4 or 20.5 https://github.com/ClickHouse/ClickHouse/pull/10387 | 2020-05-15T16:50:22 | 2020-05-15T16:50:22 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,663,967 | 10,957 | volfco | It seems that either the docs are slightly incorrect or this is implemented slightly incorrect.
```
CREATE ROW POLICY OR REPLACE dyn_testing ON default.queryMetrics_shard ON CLUSTER metrics AS RESTRICTIVE FOR SELECT USING DomainID = 1 TO dyn_testing;
```
The ON CLUSTER statement works when put after the DB nam... | 2020-05-16T15:33:00 | 2020-05-16T15:33:00 | {} | NONE |
ClickHouse | ClickHouse | 629,701,314 | 10,964 | ObjatieGroba | I found 0 usages of getRawData().size | 2020-05-16T20:24:03 | 2020-05-16T20:24:03 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,710,349 | 10,963 | filimonov | Makes sense. | 2020-05-16T21:49:42 | 2020-05-16T21:49:42 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,577,014 | 9,177 | nikitamikhaylov | But if you explicitly create target tables by yourself, everything will work pretty well. Copier removes materialized and aliased columns only for internal service tables. It is needed to not to send useless data over the network. | 2020-05-14T11:40:04 | 2020-05-14T11:40:04 | {} | MEMBER |
ClickHouse | ClickHouse | 628,651,342 | 10,917 | den-crane | I you sure that CH does not restart? Can you show `select uptime()`
Try the latest 20.1.11.73. | 2020-05-14T13:52:59 | 2020-05-14T13:52:59 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,705,570 | 10,897 | silviucpp | If helps in my canse the code freeze in the `mutation_wait_event.wait(lock, check);` (see image)
<img width="1133" alt="Screen Shot 2020-05-14 at 6 18 07 PM" src="https://user-images.githubusercontent.com/4814731/81952635-66b47600-960f-11ea-872a-62a1528c2a10.png">
In the file system I see a new file created mutatio... | 2020-05-14T15:20:34 | 2020-05-14T15:20:34 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,784,111 | 10,904 | azat | Closed in favor of #10910 | 2020-05-14T17:37:09 | 2020-05-14T17:37:09 | {} | MEMBER |
ClickHouse | ClickHouse | 628,854,186 | 8,976 | sundarv85 | @blinkov we still were not able to figure out what is causing this issue? We are currently just deleting the snapshots using the cron. Any pointers on how to fix this would be really helpful | 2020-05-14T19:54:22 | 2020-05-14T19:54:22 | {} | NONE |
ClickHouse | ClickHouse | 628,854,979 | 10,921 | abyss7 | The sysincl part is already fixed on Arcadia side. | 2020-05-14T19:56:02 | 2020-05-14T19:56:02 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,212,381 | 10,889 | CurtizJ | Performance of parsing of big sets was decreased, but it's impossible to leave backward compatibility without it.
Though, it's still faster, than e.g. 19.17.
Test `set_index` with query ```SELECT count() FROM numbers(10000) WHERE (number, number) IN ((17258, 93148), (4508, 52749)...```
This PR:
```
localhost:9... | 2020-05-15T12:38:51 | 2020-05-15T12:38:51 | {} | MEMBER |
ClickHouse | ClickHouse | 629,602,955 | 8,976 | blinkov | @sundarv85 you need to see for yourself on your testing/preproduction environments. And don't forget to check the changelog for warnings and incompatible changes.
The latest LTS release is 20.3, they are supported for a year. | 2020-05-16T07:34:25 | 2020-05-16T07:34:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,631,339 | 10,960 | frank-zsy | Sorry for two commits, may need to squash merge. | 2020-05-16T11:30:31 | 2020-05-16T11:30:31 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,707,914 | 10,822 | alexey-milovidov | There is example data for this library:
https://github.com/highpower/uatraits/tree/master/data
It is from 7 years ago. We can use it for tests*.
(But we don't have permission to publish the recent version of this data from Yandex).
\* I found that this data contains comments with profanity and hate speech - nee... | 2020-05-16T21:27:17 | 2020-05-16T21:29:01 | {} | MEMBER |
ClickHouse | ClickHouse | 628,725,065 | 10,881 | byx313 | > Hello! Your `schema.xml` is not informative. You don't provide us any information, especially table schema. However I noticed that you have an error near the tag '**engine**'. I think the problem is that you didn't specify the engine of your table. That's why copier сan't parse this (empty string). Please read this a... | 2020-05-14T15:52:22 | 2020-05-14T15:52:22 | {} | NONE |
ClickHouse | ClickHouse | 629,218,804 | 10,935 | filimonov | Some health check maybe? | 2020-05-15T12:52:45 | 2020-05-15T12:52:45 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,607,773 | 10,058 | alexey-milovidov | @lth08091998 Yes, it's a good topic and this implementation of dynamic dispatch will help.
Sent you email... | 2020-05-16T08:15:20 | 2020-05-16T08:15:20 | {} | MEMBER |
ClickHouse | ClickHouse | 628,707,884 | 6,203 | filimonov | #10922 | 2020-05-14T15:24:11 | 2020-05-14T15:24:11 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,159,250 | 7,900 | ut0mt8 | Hello, this looks cool. Just few comments/questions : so we have a basic /metrics endpoints which answer so hardcoded queries and we can add some predefined_queries in http_handler conf.
Great but it would be better if we can add predefined_queries at the end of the same path /metrics endpoints (unless I miss somethin... | 2020-05-15T10:26:57 | 2020-05-15T10:26:57 | {} | NONE |
ClickHouse | ClickHouse | 629,324,430 | 10,932 | KochetovNicolai | I need to fix `00600_replace_running_query` | 2020-05-15T15:43:13 | 2020-05-15T15:43:13 | {} | MEMBER |
ClickHouse | ClickHouse | 629,381,360 | 10,910 | filimonov | Integration test failure is relevant (will fix that) | 2020-05-15T17:22:06 | 2020-05-15T17:22:06 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,453,570 | 10,952 | alexey-milovidov | > Do I get it right that it broke when we introduced StringHashMap in 19.17 because we didn't increment the version?
Yes.
> What about this one #9829 ? It can also lead to different algorithms being selected on replicas.
It was lucky because the hash values that used to split data into buckets did not change.
... | 2020-05-15T19:58:03 | 2020-05-15T19:58:03 | {} | MEMBER |
ClickHouse | ClickHouse | 628,612,087 | 10,882 | qoega | I think the main application will be for test purposes.
Also interested if it would easier/faster to parse array in `IN` clause and convert it to Tuple rather than write Tuple explicitly in query. Something like
```sql
... IN toTuple(range(1000))
... IN toTuple(['aa', 'ab', ..., 'az'])
... IN toTuple(arrayZip(ran... | 2020-05-14T12:50:00 | 2020-05-14T12:50:00 | {
"+1": 3
} | MEMBER |
ClickHouse | ClickHouse | 628,785,520 | 10,907 | 4ertus2 | As temporary workaround `set optimize_move_to_prewhere = 0` should help. | 2020-05-14T17:40:01 | 2020-05-14T17:40:18 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,027,613 | 10,883 | thyn | It's great, thank you | 2020-05-15T05:00:59 | 2020-05-15T05:00:59 | {} | NONE |
ClickHouse | ClickHouse | 629,126,660 | 10,917 | huang--yijian | Is there any related issue fixed in 20.1.11.73 ?
Upgrading to 20.1.11.73 is a serious decision for our production environment.
We would like to see some evidence showing better memory footprint of 20.1.11.73. | 2020-05-15T09:13:26 | 2020-05-15T09:13:26 | {} | NONE |
ClickHouse | ClickHouse | 629,168,496 | 8,096 | maqroll | @inakivb which version are you using? | 2020-05-15T10:50:17 | 2020-05-15T10:50:17 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,199,524 | 10,884 | brefre | Hi,
Thank you for your response.
It's weird that this is a broker problem, when none of the other servers has the same issue. I grepped my logs, and can see these messages on many of my brokers:
```
[2020-01-15 17:12:53,359] INFO [Partition __consumer_offsets-31 broker=10] Expanding ISR from 10,11,15 to 10,11... | 2020-05-15T12:10:22 | 2020-05-15T12:10:22 | {} | NONE |
ClickHouse | ClickHouse | 629,271,652 | 10,777 | alesapin | Also, fix changelog entry, please. It's not improvement, just refactoring (so non-significant). | 2020-05-15T14:38:29 | 2020-05-15T14:38:29 | {} | MEMBER |
ClickHouse | ClickHouse | 629,561,219 | 10,954 | azat | >Is 20.3.5.53 - the latest LTS - recent enough?
If it works - then it is recent enough!
Glad it works! | 2020-05-16T00:34:50 | 2020-05-16T00:34:50 | {} | MEMBER |
ClickHouse | ClickHouse | 629,568,270 | 10,954 | yfinkelstein | Yes it does work. We see the query expanded exactly like you said. So, the logic here is:
the subquery in WITH has a priority over the main SELECT hence DT must handle it first?
Does the same logic apply to all uncorrelated subqueries or WITH is a special case?
It would be cool to document it for the benefit of o... | 2020-05-16T01:23:34 | 2020-05-16T01:42:44 | {} | NONE |
ClickHouse | ClickHouse | 629,080,572 | 10,903 | alexey-milovidov | Notes:
- some whitespaces are invisible and the query that use only these whitespaces will look strange;
- some characters have different use case (like zero-width joiner, zero-width non-joiner), maybe better to remove them. | 2020-05-15T07:34:09 | 2020-05-15T07:34:09 | {} | MEMBER |
ClickHouse | ClickHouse | 629,513,911 | 10,884 | filimonov | >What should I do if I wanted to commit less often?
Increase kafka_max_block_size or flush interval | 2020-05-15T21:54:45 | 2020-05-15T21:54:45 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,559,476 | 10,954 | yfinkelstein | Wrapping dictGet with a select is a beautiful idea. Thanks so much for the tip @azat! 🥇 💯
Is 20.3.5.53 - the latest LTS - recent enough? | 2020-05-16T00:25:20 | 2020-05-16T00:25:20 | {} | NONE |
ClickHouse | ClickHouse | 629,710,965 | 10,759 | cw9 | > Set log_queries=1 and check the counters in system.query_log and system.query_thread_log
So I've enabled log_queries for all queries and found some more examples of this case.
This distributed query took 11s to run:
```
┌──────────event_time─┬────query_start_time─┬─initial_query_id─────────────────────┬─que... | 2020-05-16T21:55:17 | 2020-05-16T21:55:17 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,587,732 | 10,572 | akuzm | Stack trace:
https://pastebin.com/raw/2kv0AhiE
Table definition (can be reproduced w/o data):
```
CREATE TABLE default.hits1 ( `WatchID` UInt64, `JavaEnable` UInt8, `Title` String, `GoodEvent` Int16, `EventTime` DateTime, `EventDate` Date, `CounterID` UInt32, `ClientIP` UInt32, ... | 2020-05-14T12:01:40 | 2020-05-14T12:01:40 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,655,584 | 10,905 | den-crane | >If we configure socket_timeout, do we not need to configure these two parameters
IF YOU USE OFFICIAL JDBC https://github.com/ClickHouse/clickhouse-jdbc:
Yes. You should configure only `socket_timeout` using JDBC parameters. | 2020-05-14T13:59:35 | 2020-05-14T13:59:35 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,137,895 | 8,976 | blinkov | @sundarv85 I think nobody has actually tried to reproduce it, at least because you are using an obsolete version, have you managed to upgrade to some recent one that's still supported? | 2020-05-15T09:37:44 | 2020-05-15T09:37:44 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,441,623 | 10,952 | akuzm | Good that we have this version number.
Do I get it right that it broke when we introduced StringHashMap in 19.17 because we didn't increment the version?
What about this one https://github.com/ClickHouse/ClickHouse/pull/9829 ? It can also lead to different algorithms being selected on replicas. | 2020-05-15T19:35:23 | 2020-05-15T19:35:23 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,479,227 | 10,621 | azat | Friendly ping | 2020-05-15T20:56:51 | 2020-05-15T20:56:51 | {} | MEMBER |
ClickHouse | ClickHouse | 629,552,276 | 10,954 | azat | >Will dictGet(..) be performed by DT and query sent to the data nodes be re-written as WITH 10 as _ver SELECT ... ?
This depends, without any extra settings it won't be executed on the initiator node (DT) (you can verify this by using something like this `with sleep(1) as v select * from remote('127.{2,3}', system.o... | 2020-05-15T23:51:45 | 2020-05-15T23:52:33 | {} | MEMBER |
ClickHouse | ClickHouse | 629,618,416 | 10,954 | azat | >We see the query expanded exactly like you said
Actually you can verify this with `ANALYZE` instead of looking into logs:
```sql
set enable_debug_queries=1;
analyze with (select crc64('')) as v select * from remote('127.{2,3}', system.one) where dummy=v;
Row 1:
──────
explain: WITH CAST(0, 'UInt64') AS v
S... | 2020-05-16T09:43:56 | 2020-05-16T09:43:56 | {} | MEMBER |
ClickHouse | ClickHouse | 629,619,617 | 10,887 | alesapin | Will enable skipped tests in separate PR. | 2020-05-16T09:54:24 | 2020-05-16T09:54:24 | {} | MEMBER |
ClickHouse | ClickHouse | 628,583,453 | 10,473 | pgeek | > Maybe you can use `clickhouse-local`?
The clickhouse-local is more likely to use clickhouse engine to query local data without deployment. It is not used to bulk load data into clickhouse server.
[https://clickhouse.tech/docs/en/operations/utilities/clickhouse-local/](https://clickhouse.tech/docs/en/operations/... | 2020-05-14T11:53:11 | 2020-05-14T11:53:11 | {} | NONE |
ClickHouse | ClickHouse | 628,785,770 | 943 | alexey-milovidov | Fixed some time ago.
I've added a test in #10926. | 2020-05-14T17:40:32 | 2020-05-14T17:40:32 | {} | MEMBER |
ClickHouse | ClickHouse | 628,970,570 | 10,907 | leoones | > As temporary workaround `set optimize_move_to_prewhere = 0` should help.
ok, I try . | 2020-05-15T01:23:26 | 2020-05-15T01:23:26 | {} | NONE |
ClickHouse | ClickHouse | 629,081,647 | 10,829 | alexey-milovidov | > PS. We can move test scenarios to run over system.numbers(_mt) in stateless tests.
We have both stateless and stateful tests for this function, this is Ok. | 2020-05-15T07:36:24 | 2020-05-15T07:36:24 | {} | MEMBER |
ClickHouse | ClickHouse | 629,408,422 | 10,917 | den-crane | >Our operations confirm that since May 5,
CH has an autorestart ability. Check /etc/cron.d/clickhouse-server
Do you have graph with CH uptime?
Need /var/log/clickhouse-server/clickhouse-server.log with loglevel=trace to investigate the cause | 2020-05-15T18:20:00 | 2020-05-15T20:04:49 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 629,480,555 | 10,927 | azat | >Conflicting files
>src/Access/AccessFlags.h
The same fix was in #10387, will rebase | 2020-05-15T20:59:58 | 2020-05-15T20:59:58 | {} | MEMBER |
ClickHouse | ClickHouse | 629,593,793 | 8,559 | silviucpp | @alesapin I think https://github.com/ClickHouse/ClickHouse/issues/10897 is related to this problem as well. In case number_of_free_entries_in_pool_to_execute_mutationis > than background_pool_size the mutations will block forever. So at least some alerts should be added in logs. | 2020-05-16T05:57:03 | 2020-05-16T05:57:03 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,974,728 | 10,907 | leoones | > Could you add trace in server log related to to the error, please?
error.log
(version 20.4.2.9 (official build))
2020.05.14 15:05:19.859835 [ 22692 ] {0e5e5c31-0d77-46c3-becc-49f0a6a2c5ef} <Error> executeQuery: Code: 10, e.displayText() = DB::Exception: No such name in Block::erase(): 'exchange_date' (version 20... | 2020-05-15T01:37:33 | 2020-05-15T01:37:33 | {} | NONE |
ClickHouse | ClickHouse | 629,042,702 | 10,906 | kaijianding | @den-crane these 2 solutions are with consequences.
for the `materialized ` solution,
the schema is different to the upstream table like a hive table, people need to know there is an extra `xxxx` column, people have to use `xxxx` > '20200510' and `xxxx` < '20200515' to achieve better performance, but the 'xxxx' col... | 2020-05-15T05:53:32 | 2020-05-15T05:53:32 | {} | NONE |
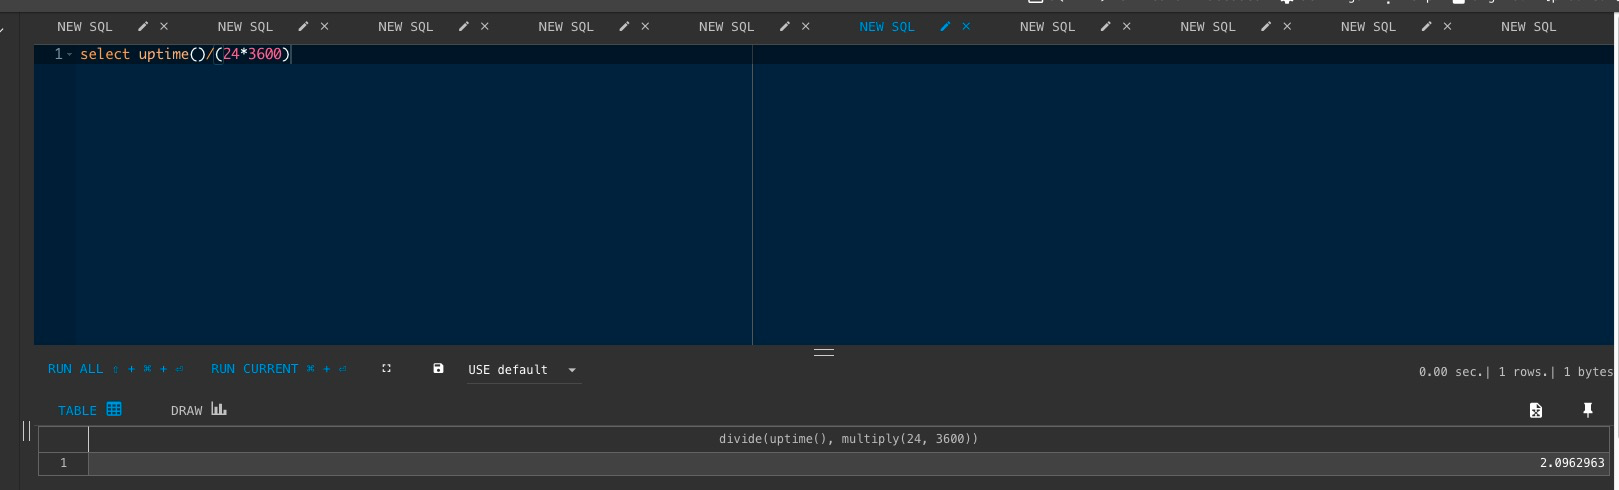
ClickHouse | ClickHouse | 629,141,405 | 10,917 | huang--yijian | > I you sure that CH does not restart? Can you show `select uptime()`
> Try the latest 20.1.11.73.
Our operations confirm that since May 5, the server was manually started only once on May 13:
| 2020-05-15T09:46:08 | 2020-05-15T09:46:08 | {} | NONE |
ClickHouse | ClickHouse | 629,287,012 | 10,895 | alesapin | DatabaseAtomic tests set failure is expected. | 2020-05-15T15:06:25 | 2020-05-15T15:06:55 | {} | MEMBER |
ClickHouse | ClickHouse | 628,576,376 | 10,915 | akuzm | As usual, integration tests fail locally with incomprehensible errors, so this is a blind commit. | 2020-05-14T11:38:43 | 2020-05-14T11:38:43 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 628,769,406 | 10,866 | alexey-milovidov | > But I try to find a real use case where we need random function.
You can use it in more contexts - e.g. for default values.
It's more easy to use plain function than a table function.
Especially when you are already selecting from one table but provide random value for one column (instead of IPv6, UUID*, hash va... | 2020-05-14T17:10:56 | 2020-05-14T17:11:57 | {} | MEMBER |
ClickHouse | ClickHouse | 629,498,376 | 7,900 | ut0mt8 | In prometheus label can be anything.
In our queries we wants labels for fields in the group by clause.
For example :
`select sum(somefield) as super_stat , pid from stats_table group by pid; `
would result in :
`super_stat{pid="somepid"} XX`
So yep add more custom queries possible for the same htttp ... | 2020-05-15T21:28:02 | 2020-05-15T21:28:02 | {} | NONE |
ClickHouse | ClickHouse | 629,676,737 | 10,962 | ObjatieGroba | TODO:
1) Придумать способ определения или создания numpy::dtype по типу UDF
2) Скрестить CREATE FUNCTION с фабрикой
Вощможно стоит перейти на версию сравнимую с Monet DB, а именно не scalar функции использовать, а применимые к одной строке. Только в этом случае можно гарантировать верную запись в нужное место. Тем... | 2020-05-16T17:02:58 | 2020-05-16T17:02:58 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 646,946,356 | 11,484 | alexey-milovidov | https://github.com/ClickHouse/ClickHouse/issues/11815 | 2020-06-20T05:47:00 | 2020-06-20T05:47:00 | {} | MEMBER |
ClickHouse | ClickHouse | 646,955,417 | 6,549 | alexey-milovidov | If it's not fixed, why close? | 2020-06-20T07:07:19 | 2020-06-20T07:07:19 | {} | MEMBER |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.