
owner stringclasses 14
values | repo stringclasses 14
values | id int64 116k 4.61B | issue_number int32 1 181k | author stringlengths 1 39 | body stringlengths 1 262k | created_at timestamp[us]date 2000-06-06 02:40:44 2026-06-02 20:16:18 | updated_at timestamp[us]date 2000-06-06 02:40:44 2026-06-02 20:22:56 | reactions unknown | author_association stringclasses 5
values |
|---|---|---|---|---|---|---|---|---|---|
ClickHouse | ClickHouse | 790,840,745 | 21,376 | pumelo | @Jokser, glad I am not the only one observing this behavior
@excitoon are the backtraces @jokser provided enough or do you need something more? Honestly I don't know how to provide backtraces as the ones jokser provided, not sure I can be of any help... | 2021-03-04T18:41:30 | 2021-03-04T18:41:30 | {} | NONE |
ClickHouse | ClickHouse | 790,957,975 | 21,451 | den-crane | >getting following exception
What exception?
`<Warning>` -- it's not an exception. | 2021-03-04T21:30:56 | 2021-03-04T21:31:06 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,433,308 | 21,360 | alesapin | Yes, MergeTree has WAL, but it's optional and it's very different from the common understanding of WAL. I think this change doesn't improve the understandability of the MergeTree architecture. | 2021-03-05T13:54:14 | 2021-03-05T13:54:14 | {} | MEMBER |
ClickHouse | ClickHouse | 790,411,017 | 21,364 | yiguolei | @filimonov
If there is explicit engine, then the number of shard will not be related with number of machines. User could create a table with 10 shards on a 3 node cluster. The "shard" is different from current shard. Maybe it should be called "tablet". If new node is added to the cluster, just move some tablet to t... | 2021-03-04T08:04:03 | 2021-03-04T08:04:03 | {
"+1": 1
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,469,796 | 14,995 | vitlibar | Yandex third-party checks say
```
$(SOURCE_ROOT)/contrib/libs/cxxsupp/libcxx/include/memory:2364:19: error: invalid application of 'sizeof' to an incomplete type 'DB::Credentials'
static_assert(sizeof(_Tp) > 0,
^~~~~~~~~~~
$(SOURCE_ROOT)/contrib/libs/cxxsupp/libcxx/include/memory:2623:7: no... | 2021-03-04T09:29:20 | 2021-03-04T09:29:37 | {} | MEMBER |
ClickHouse | ClickHouse | 790,490,582 | 9,900 | filimonov | @Avogar did you add that test? | 2021-03-04T09:59:26 | 2021-03-04T09:59:26 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,390,003 | 21,425 | alesapin | Shutdown bug :( | 2021-03-05T12:30:10 | 2021-03-05T12:30:10 | {} | MEMBER |
ClickHouse | ClickHouse | 790,546,965 | 21,425 | alesapin | Works:
```
2021.03.04 13:24:21.053645 [ 217641 ] {} <Debug> NuKeeperDispatcher: Initializing storage dispatcher
2021.03.04 13:24:21.054106 [ 217641 ] {} <Debug> NuKeeperDispatcher: Waiting server to initialize
2021.03.04 13:24:21.054129 [ 217641 ] {} <Debug> NuKeeperStateMachine: Totally have 3 snapshots
2021.03.0... | 2021-03-04T11:30:29 | 2021-03-04T11:30:29 | {} | MEMBER |
ClickHouse | ClickHouse | 790,626,817 | 21,376 | Jokser | It's related to S3 connection pools. It seems there's a concurrency bug in acquiring pooled HTTP sessions, but it's unclear how it has happened because I don't see any thread that holds mutex in HTTPSessionPool | 2021-03-04T13:43:02 | 2021-03-04T13:43:02 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,634,190 | 21,431 | azat | >@azat Need to check it - maybe it started to work.
@alexey-milovidov yep, I've re-checked before writing, it still does not work. | 2021-03-04T13:54:34 | 2021-03-04T13:54:34 | {
"+1": 1
} | MEMBER |
ClickHouse | ClickHouse | 791,064,040 | 20,477 | akuzm | I am completely confused now :)
Do I get it right that the basic idea is to make queries that go to local replica look like remote queries in the query log? E.g. have their own query id and process list entry. This is basically what `executeQueryImpl` would do if we passed `internal = false` to it, right? | 2021-03-05T00:57:42 | 2021-03-05T00:57:42 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,190,528 | 21,452 | filimonov | Yes, I have same doubts. But those known failures prevent running further Kafka tests, and disrupt attention... | 2021-03-05T06:30:08 | 2021-03-05T06:30:08 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,209,472 | 21,103 | pg-yang | > Q: How to remove TTL in ClickHouse version 20.8?
> A: It takes two steps. Step 1: Upgrade to ClickHouse version 21.2 or newer. Step 2: Remove TTL with ALTER TABLE ... REMOVE TTL query.
Thanks , and sorry for my bad English | 2021-03-05T07:13:20 | 2021-03-05T07:13:20 | {} | NONE |
ClickHouse | ClickHouse | 791,227,403 | 20,961 | havardk | Hi,
It took some time to get this PR in shape, but I think it is OK now. The test failures look unrelated, though I don't know about the Yandex internal ones. Should I try to run the tests again? | 2021-03-05T07:45:47 | 2021-03-05T07:45:47 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,409,154 | 21,468 | den-crane | I see that it happened with your own build. Does it reproduce with official binary? | 2021-03-05T13:08:38 | 2021-03-05T13:08:38 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,423,912 | 21,136 | traceon | @alexey-milovidov So what's the final decision on this? Adding a separate mode/format/switch that will make ClickHouse to respond in HTTP with Server-sent events? Does anyone work on adding this currently?
I would make use of this to properly implement #18689 (and/or #20490).
For the sake of completeness, there i... | 2021-03-05T13:37:36 | 2021-03-05T13:37:36 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,428,522 | 21,463 | den-crane | It because this one replica is closer to ZK / faster / more lucky. It does not matter who was the first | 2021-03-05T13:45:59 | 2021-03-05T13:45:59 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,618,761 | 21,431 | alexey-milovidov | @azat Need to check it - maybe it started to work. | 2021-03-04T13:30:09 | 2021-03-04T13:30:09 | {} | MEMBER |
ClickHouse | ClickHouse | 791,049,924 | 21,452 | alexey-milovidov | Thank you!
Actually I'm not even sure should we merge it... Only as some temporary solution. | 2021-03-05T00:22:32 | 2021-03-05T00:22:32 | {} | MEMBER |
ClickHouse | ClickHouse | 791,099,897 | 21,443 | ywxkz |
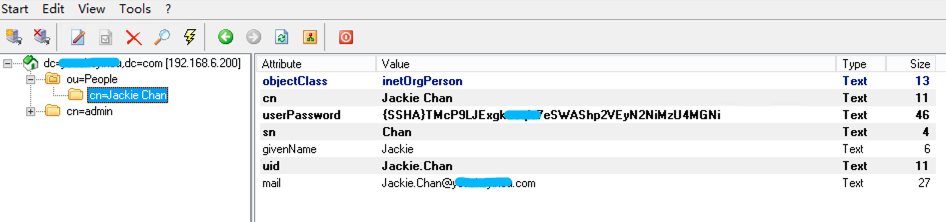
Thank you for your reply!I think uid and cn are different。 | 2021-03-05T02:28:41 | 2021-03-05T02:30:15 | {} | NONE |
ClickHouse | ClickHouse | 791,246,059 | 16,240 | ianton-ru | > How to solve the cache consistency problem of different replicas?
In Clickhouse data is "append only". Sometimes entry part can be deleted. So could you please describe where you see a problem?
| 2021-03-05T08:16:40 | 2021-03-05T08:24:04 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,282,789 | 21,437 | filimonov | > I appreciate suggestions why we have issues with certain formats via kafka, e.g. Parquet and ArrowStream if kafka is in use.
Discussed in telegram.
Long story short - we don't recreate parser and underlying buffer readers on every Kafka message due to performance reason, see https://github.com/ClickHouse/Clic... | 2021-03-05T09:14:06 | 2021-03-05T09:14:59 | {
"+1": 1
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,415,143 | 21,443 | traceon | If the ClickHouse user name matches `uid` in the LDAP database, you should put it (`uid=...`) in the `bind_dn` string. Otherwise, you can put `cn=...`. Is that the problem? | 2021-03-05T13:20:32 | 2021-03-05T13:20:57 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,553,601 | 21,363 | amosbird | AST fuzzer (TSan): OOM killed
AST fuzzer (debug) — segfaults in fuzzBits https://github.com/ClickHouse/ClickHouse/blob/master/src/Functions/fuzzBits.cpp#L38
Intergration tests : `E Code: 159. DB::Exception: Received from 172.18.0.7:9000. DB::Exception: Watching task /clickhouse/task_queue/ddl/query-... | 2021-03-04T11:42:14 | 2021-03-04T11:42:14 | {} | COLLABORATOR |
ClickHouse | ClickHouse | 790,728,415 | 20,182 | filimonov | PVS-Studio check was not working for some time, it seems it report few real issues now, for ex.: https://github.com/ClickHouse/ClickHouse/pull/21458
Worth checking probably. | 2021-03-04T16:05:38 | 2021-03-04T16:34:16 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,076,059 | 21,337 | akuzm | Please look at the fuzzer failure, looks like it is related to your changes:
```
2021.03.03 13:57:22.609393 [ 90 ] {37b80ae1-8cbf-4084-bfb8-8871a2430ea3} <Debug> executeQuery: (from [::1]:43126, using production parser) SELECT count(*) FROM test_insert_t3
2021.03.03 13:57:23.480634 [ 90 ] {37b80ae1-8cbf-4084... | 2021-03-05T01:30:21 | 2021-03-05T01:30:21 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,112,924 | 20,350 | amosbird | There are still places where expression parser is used directly, for instance, `select * from remote('127.0.0.1:9000', system.numbers, view(select 1))`. https://clickhouse-test-reports.s3.yandex.net/21401/909cb3c24324e923a371255e01cbba6f0730b854/fuzzer_debug/fuzzer.log
We still need a guard in ASTFunction. | 2021-03-05T02:54:39 | 2021-03-05T02:54:39 | {} | COLLABORATOR |
ClickHouse | ClickHouse | 791,342,323 | 21,456 | nikitamikhaylov | #21452 | 2021-03-05T10:52:01 | 2021-03-05T10:52:01 | {} | MEMBER |
ClickHouse | ClickHouse | 791,381,937 | 21,476 | wuzedewuze | 2021.03.05 20:09:56.139329 [ 201557 ] {} <Warning> Application: Calculated checksum of the binary: 34B52F8F7BC6DB128D516E9B3985B1CB. There is no information about the reference checksum.
2021.03.05 20:09:56.208425 [ 201590 ] {} <Fatal> BaseDaemon: ########################################
2021.03.05 20:09:56.208451 [ ... | 2021-03-05T12:14:11 | 2021-03-05T12:14:11 | {} | NONE |
ClickHouse | ClickHouse | 791,392,148 | 21,447 | traceon | Maybe it is worth reducing the amount of data? | 2021-03-05T12:34:40 | 2021-03-05T12:36:41 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,400,485 | 21,476 | filimonov | checked latest (21.3.1.6179) - just works. | 2021-03-05T12:52:37 | 2021-03-05T12:52:37 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,419,209 | 21,464 | den-crane | Please provide table DDL.
Insert performance depends on many factors.
| 2021-03-05T13:28:15 | 2021-03-05T13:28:15 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,427,187 | 20,961 | tavplubix | Hi, you can just ignore Yandex synchronization check failure, because it's only for Yandex employees.
Integration tests (asan) - test_distributed_ddl - broken in master
Performance - flaky | 2021-03-05T13:43:32 | 2021-03-05T13:43:32 | {} | MEMBER |
ClickHouse | ClickHouse | 790,407,019 | 21,425 | alesapin | Ahh, snapshots were disabled in configs. | 2021-03-04T07:57:14 | 2021-03-04T07:57:14 | {} | MEMBER |
ClickHouse | ClickHouse | 790,695,138 | 21,456 | qoega | Can we write a test? | 2021-03-04T15:20:43 | 2021-03-04T15:20:43 | {} | MEMBER |
ClickHouse | ClickHouse | 790,713,680 | 21,447 | KochetovNicolai | Let's wait for perftests. | 2021-03-04T15:46:40 | 2021-03-04T15:46:40 | {} | MEMBER |
ClickHouse | ClickHouse | 791,089,088 | 21,460 | den-crane | >ClickHouse client version 18.16.1.
Client parses SQL. 18.16 does not support skip indexes.
You should upgrade ClickHouse client to 21.2.5 | 2021-03-05T02:01:19 | 2021-03-05T02:01:19 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,309,224 | 19,644 | CurtizJ | Yes, there is conflict with syntax of parametrized queries.
Example: `$CLICKHOUSE_CLIENT --param_test 'Hello, world' --query 'SELECT {test:String}'` | 2021-03-05T09:54:43 | 2021-03-05T09:54:53 | {} | MEMBER |
ClickHouse | ClickHouse | 791,399,929 | 19,766 | ghost | @vdimir
I fixed some codes for more deterministic sorting
1. Remove EMPTY_EVENTS_BITSET
2. Remove event_bitsets from comparison criterion in order to more deterministic sorting.
3. Replace the type of bitset with std::bitset
4. Remove in-determinisms in testcases
Thank you. | 2021-03-05T12:51:25 | 2021-03-05T12:51:25 | {
"+1": 1
} | NONE |
ClickHouse | ClickHouse | 791,403,546 | 21,447 | traceon | > Maybe it is worth reducing the amount of data?
Pushed in #21442. | 2021-03-05T12:59:13 | 2021-03-05T12:59:13 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,422,615 | 21,437 | ilejn | Looking into this issue. Will try to fix.
I appreciate suggestions why we have issues with certain formats via kafka, e.g. Parquet and ArrowStream if kafka is in use.
| 2021-03-04T08:23:32 | 2021-03-04T08:23:32 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,915,438 | 20,477 | azat | Can someone take a look at this? | 2021-03-04T20:24:31 | 2021-03-04T20:24:31 | {} | MEMBER |
ClickHouse | ClickHouse | 790,988,608 | 18,583 | alexey-milovidov | @jart First try either did not show performance improvement or we cannot observe it.
Maybe it because I have disabled AVX.
We can try better by the following way:
- make jump table not readonly;
- allow to rewrite it in runtime by simple function call (to avoid dealing with init mechanics);
- maybe add AVX non-t... | 2021-03-04T22:26:25 | 2021-03-04T22:26:25 | {} | MEMBER |
ClickHouse | ClickHouse | 791,207,468 | 21,425 | alesapin | Ok, the synchronous version works well. | 2021-03-05T07:09:09 | 2021-03-05T07:09:09 | {} | MEMBER |
ClickHouse | ClickHouse | 791,396,167 | 21,461 | tavplubix | > BTW is there a chance to cover this with an integration test?
I'm not sure, integration tests are complicated, too hard to write and not reliable enough. All tests passed in #16193 and #21079, but then we noticed random failures of `test_distributed_ddl` in master. | 2021-03-05T12:43:31 | 2021-03-05T12:43:31 | {} | MEMBER |
ClickHouse | ClickHouse | 791,434,982 | 21,311 | ucasfl | > @ucasFL can you add a test?
> If you don't know how you can see these examples:
> tests/queries/0_stateless/01548_create_table_compound_column_format.sh
> tests/queries/0_stateless/00754_distributed_optimize_skip_select_on_unused_shards_with_prewhere.sh (good way how to check exceptions)
Ok, I will add a test ... | 2021-03-05T13:57:03 | 2021-03-05T13:57:03 | {} | COLLABORATOR |
ClickHouse | ClickHouse | 790,524,998 | 21,413 | citrin | The error was discovered first on a distributed table, but then reproduced by a direct query to a table with `ENGINE=MergeTree`. Changing condition manually to `PREWHERE` doesn't change anything too (as well as `set optimize_move_to_prewhere=0`). | 2021-03-04T10:54:10 | 2021-03-04T10:57:58 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,667,067 | 21,447 | traceon | Just noticed this PR. Thanks. | 2021-03-04T14:42:25 | 2021-03-04T14:42:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,673,454 | 21,304 | amosbird | Integration tests (thread) — fail: 1, passed: 1040, error: 24
```
E Code: 159. DB::Exception: Received from 172.19.0.6:9000. DB::Exception: Watching task /clickhouse/task_queue/ddl/query-0000000017 is executing longer than distributed_ddl_task_timeout (=180) seconds. There are 1 unfinished hosts (0 of them ... | 2021-03-04T14:51:18 | 2021-03-04T14:51:18 | {} | COLLABORATOR |
ClickHouse | ClickHouse | 791,416,520 | 21,467 | den-crane | * You can implement deduplication in ETL (before loading into Clickhouse).
* You can query data with selects witch deduplicate data on the fly. And then run optimize once a day. | 2021-03-05T13:23:17 | 2021-03-05T13:23:17 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,428,369 | 21,468 | ghost | @den-crane
My own build just contains new aggregate function, the others are the same with official 21.1.2.15-stable.
And the old version is also my own build using the same build environment.
From now on, ClickHouse servers are hard to test because that's on service.
We had better to find some other test ... | 2021-03-05T13:45:44 | 2021-03-05T13:45:44 | {} | NONE |
ClickHouse | ClickHouse | 791,440,526 | 21,468 | filimonov | Can you try to look for a corresponding log fragment in zookeeper logs? | 2021-03-05T14:06:30 | 2021-03-05T14:06:30 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,664,554 | 21,413 | den-crane | I cannot reproduce it with 21.3 , I tried all tricks.
index_granularity=333, more rows, different partition by, optimize_read_in_order, prewhere,
clickhouse-benchmark --max_threads=32 <<<"SELECT arraySort(x -> x.2, [tuple('a', 10)]) AS X FROM ttt PREWHERE d >= toDate('2021-03-03') - 2 ORDER BY n desc LIMIT 1"
... | 2021-03-04T14:38:58 | 2021-03-04T14:39:34 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,078,402 | 20,392 | akuzm | By the way, why do we even have cross/comma join as separate concepts? They are fully equivalent to a clauseless `INNER` join. There is some difference in operator precedence with comma, but it shouldn't survive past the parsing stage.
Probably the reason is that we don't have a suitable structure for representing t... | 2021-03-05T01:36:58 | 2021-03-05T01:36:58 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,496,287 | 21,302 | keen-wolf | After test and code analysis, I found the “Native” format will read all columns from the raw data file, as this patch only fix the column filter path from the upper layer of StorageFile, so it will do no favor to the “Native” format. If we want to improve it, some internal code changes may be required.
And below is an... | 2021-03-04T10:07:59 | 2021-03-05T08:08:59 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,428,291 | 21,462 | den-crane | It because this one replica is closer to ZK / faster / more lucky. It does not matter who was the first | 2021-03-05T13:45:35 | 2021-03-05T13:45:35 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,371,024 | 21,402 | mjh568412187 | > > The set of parts restored in place of ... looks incomplete. There might or might not be a data loss. Suspicious parts
> > This is data loss because of power outage (linux cache was not written to disk).
>
> If you have replicas unaffected by power outage, the missing data parts will be restored from them.
He... | 2021-03-04T06:58:25 | 2021-03-04T06:58:25 | {} | NONE |
ClickHouse | ClickHouse | 790,613,253 | 21,440 | nflorentin | I just tested it and the following query now runs in **50ms** ! I can't believe how fast it is!
```SQL
SELECT * FROM results
INNER JOIN words ON results.word_id = words.id
WHERE results.domain = crc32('www.abc.fr')
LIMIT 50000;
```
@vdimir thank you for your reactivity and for the pertinence of your answer. | 2021-03-04T13:21:01 | 2021-03-04T13:21:01 | {} | NONE |
ClickHouse | ClickHouse | 790,620,207 | 21,431 | alexey-milovidov | > Integration tests (thread) — fail: 1, passed: 1040, error: 24
Broken in master. | 2021-03-04T13:32:26 | 2021-03-04T13:32:26 | {} | MEMBER |
ClickHouse | ClickHouse | 791,086,769 | 19,644 | akuzm | @CurtizJ do you remember what we decided about this syntax? I vaguely recall there was some conflict with the query parameters, and we decided to postpone it... | 2021-03-05T01:54:58 | 2021-03-05T01:54:58 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,129,552 | 16,240 | Sallery-X | How to solve the cache consistency problem of different replicas? | 2021-03-05T03:42:35 | 2021-03-05T03:42:35 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,209,240 | 21,368 | pg-yang | > @ypg521 FYI Copier uses Distributed tables to copy from source to destination cluster, that's why there are some limitations
Thanks , and sorry for my bad English | 2021-03-05T07:12:54 | 2021-03-05T07:12:54 | {} | NONE |
ClickHouse | ClickHouse | 791,280,940 | 21,361 | cyberhuman | We decided to start the table from scratch, but with an important difference.
Previously the temporary tables had only one replica to make it simpler. Now we create both replicas.
The process is ongoing and I noticed a suspicious thing on a few occasions: there were hundreds of REPLACE_RANGE elements waiting in the r... | 2021-03-05T09:11:25 | 2021-03-05T09:11:25 | {} | NONE |
ClickHouse | ClickHouse | 791,314,582 | 21,376 | Jokser | Here is the problematic thread that caused deadlock:
```
Thread 55 (Thread 0x7f7d8ebf5700 (LWP 4162103)):
#0 0x00007f7e4625bf85 in pthread_cond_timedwait@@GLIBC_2.3.2 () from /lib/x86_64-linux-gnu/libpthread.so.0
#1 0x000000000cdf61d5 in PoolBase<Poco::Net::HTTPClientSession>::get(long) ()
#2 0x000000000cdf49f1... | 2021-03-05T10:03:39 | 2021-03-05T10:03:55 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,771,106 | 21,413 | citrin | Tried to bisect using available docker images:
* 20.5.5.74 - can reproduce the problem using queries above (1500000 rows)
* 20.6.3.28 - cannot reproduce | 2021-03-04T17:03:42 | 2021-03-04T17:03:42 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,068,730 | 21,320 | akuzm | @vdimir Maybe you would be interested in this. | 2021-03-05T01:09:40 | 2021-03-05T01:09:40 | {
"eyes": 1
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,284,938 | 19,401 | CurtizJ | But in the test `read_in_order_many_parts` query ```SELECT sum(val2) FROM mt_100_parts GROUP BY val1 FORMAT Null``` has speeded up. For `aggregation_in_order` it's expected, that there is almost no improvement, because `hits` table contains only one or few parts and merge stage takes non-significant amount of time. | 2021-03-05T09:17:05 | 2021-03-05T09:17:05 | {} | MEMBER |
ClickHouse | ClickHouse | 791,406,435 | 21,473 | den-crane | in 20.12.7.3 You can move all tables to ordinary database by rename.
```
create database atomic_db Engine=Atomic;
create database ordinary_db Engine=Ordinary;
create table atomic_db.x(A Int64) Engine=MergeTree order by A;
insert into atomic_db.x select number from numbers(100000);
rename table atomic_db.x to o... | 2021-03-05T13:03:47 | 2021-03-05T13:04:20 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,545,405 | 21,413 | citrin | Found a way to reproduce this on a test table (though not sure this way is reliable - it looks like number of rows is important here):
```
DROP TABLE IF EXISTS ttt;
CREATE TABLE ttt (d Date, n UInt64) ENGINE = MergeTree() PARTITION BY toMonday(d) ORDER BY n;
INSERT INTO ttt SELECT toDate('2021-02-14') + (number % 3... | 2021-03-04T11:27:52 | 2021-03-04T11:49:13 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,570,854 | 21,412 | amosbird | I also need similar features. Perhaps we can provide `WITH FILL` with a lambda function with arguments: begin_value, previous_value, next_value, end_value, index. | 2021-03-04T12:06:30 | 2021-03-04T12:07:05 | {
"+1": 1
} | COLLABORATOR |
ClickHouse | ClickHouse | 790,620,588 | 21,431 | alexey-milovidov | > ClickHouse special build check — 5/6 builds are OK
Need to disable the flag for Darwin build.
| 2021-03-04T13:33:04 | 2021-03-04T13:33:04 | {} | MEMBER |
ClickHouse | ClickHouse | 791,186,263 | 21,464 | filimonov | Maybe your bottleneck is not a cpu? And we need exact insert scenario (there are hundreds of options) | 2021-03-05T06:20:03 | 2021-03-05T06:20:03 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,429,690 | 21,311 | Avogar | @ucasFL can you add a test?
If you don't know how you can see these examples:
tests/queries/0_stateless/01548_create_table_compound_column_format.sh
tests/queries/0_stateless/00754_distributed_optimize_skip_select_on_unused_shards_with_prewhere.sh (good way how to check exceptions) | 2021-03-05T13:48:02 | 2021-03-05T13:48:59 | {} | MEMBER |
ClickHouse | ClickHouse | 790,405,617 | 21,425 | alesapin | Tests very far from perfect, but passed from the first try... The current implementation is synchronous, I'll try async version. | 2021-03-04T07:54:38 | 2021-03-04T07:54:47 | {} | MEMBER |
ClickHouse | ClickHouse | 790,424,440 | 21,438 | ilejn | Currently this is only a test to demonstrate #21437 issue. | 2021-03-04T08:26:31 | 2021-03-04T08:26:31 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,572,733 | 14,995 | traceon | > It seems the destructor of HTTPHandler should be added to .cpp file.
Pushed that change. | 2021-03-04T12:09:53 | 2021-03-04T12:09:53 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,573,946 | 21,443 | traceon | Not sure I understand what's the problem, and what are you trying to achieve. | 2021-03-04T12:12:15 | 2021-03-04T12:13:27 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,577,319 | 21,413 | citrin | Tried to reproduce this with official docker images.
For `yandex/clickhouse-server:20.3.21.2` I had to rise number of rows to 1500000, may be because of different MergeTree settings (which caused different number of parts to be created/used? or may be this has to do something with the amount of data sorted in `ORDER B... | 2021-03-04T12:18:39 | 2021-03-04T12:34:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,619,929 | 21,431 | alexey-milovidov | For function alignment - the changes in performance are unclear, maybe it is faster for 0.3% in average. Good to merge.
For changes in stability of perf tests, we should compare two new versions with this change (after merge). | 2021-03-04T13:32:00 | 2021-03-04T13:32:00 | {} | MEMBER |
ClickHouse | ClickHouse | 790,624,408 | 21,376 | Jokser | I've observed the same problem on one of 21.2 production CH over S3 clusters.
Here are backtraces:
https://gist.github.com/Jokser/2a159d7566f9079d07d5fc612ecc567a | 2021-03-04T13:39:10 | 2021-03-04T13:39:10 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,712,919 | 21,456 | nikitamikhaylov | > Can we write a test?
I've added a concurrent selecting from system.zookeeper in integration test. It catched a race before fixes. | 2021-03-04T15:45:41 | 2021-03-04T15:45:41 | {} | MEMBER |
ClickHouse | ClickHouse | 790,913,950 | 21,325 | azat | >Integration tests (asan) — fail: 2, passed: 1161, error: 0
>Integration tests (release) — fail: 2, passed: 1161, error: 0
>Integration tests (thread) — fail: 4, passed: 1042, error: 24
Test failures looks related | 2021-03-04T20:22:12 | 2021-03-04T20:22:12 | {} | MEMBER |
ClickHouse | ClickHouse | 790,958,696 | 21,413 | den-crane | 21.3. not 20.3 | 2021-03-04T21:32:07 | 2021-03-04T21:32:07 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,009,870 | 21,433 | nikitamikhaylov | Failures are not related | 2021-03-04T22:59:01 | 2021-03-04T22:59:01 | {} | MEMBER |
ClickHouse | ClickHouse | 791,403,833 | 21,476 | filimonov | If it still happens on your side - try to run it in gdb | 2021-03-05T12:59:53 | 2021-03-05T12:59:53 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,502,319 | 21,431 | azat | Note that this will break path/line numbers in stacktrace (as pointed by @alexey-milovidov in https://github.com/ClickHouse/ClickHouse/pull/18952#issuecomment-758112335) | 2021-03-04T10:17:24 | 2021-03-04T10:17:24 | {} | MEMBER |
ClickHouse | ClickHouse | 791,183,141 | 21,101 | filimonov | /cc @vitlibar | 2021-03-05T06:12:31 | 2021-03-05T06:12:31 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,208,642 | 21,439 | alesapin | Tests ok | 2021-03-05T07:11:39 | 2021-03-05T07:11:39 | {} | MEMBER |
ClickHouse | ClickHouse | 791,400,830 | 21,467 | sanjaypocket52 | Please suggest any solutions | 2021-03-05T12:53:22 | 2021-03-05T12:53:22 | {} | NONE |
ClickHouse | ClickHouse | 790,420,262 | 21,437 | ilejn | Stacktrace
```
0. /home/ilejn/projects/ClickHouse/contrib/libcxx/include/exception:133: std::runtime_error::runtime_error(std::__1::basic_string<char, std::__1::char_traits<char>, std::__1::allocator<char> > const&) @ 0xd16af9d in /usr/bin/clickhouse
1. /home/ilejn/projects/ClickHouse/contrib/avro/lang/c++/api/Excep... | 2021-03-04T08:19:41 | 2021-03-04T08:19:41 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 790,891,618 | 21,411 | alexey-milovidov | Some logic remains to support running different ClickHouse versions on the same cluster for a short time during upgrade. | 2021-03-04T19:58:40 | 2021-03-04T19:58:50 | {} | MEMBER |
ClickHouse | ClickHouse | 791,091,616 | 19,401 | akuzm | The performance improvement in `read_in_order_many_parts` is nice. For `aggregation_in_order`, the improvement is only noticeable for the query with `GROUP BY CounterID, EventDate, intHash32(UserID)`, and not for other queries. Is this expected?
https://clickhouse-test-reports.s3.yandex.net/19401/2e8b45afc17d4bce41f... | 2021-03-05T02:07:11 | 2021-03-05T02:07:11 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,119,141 | 21,401 | amosbird | AST fuzzer (debug) — Logical error: 'Trying to get name of not a column: SelectWithUnionQuery'.
https://github.com/ClickHouse/ClickHouse/pull/21465 | 2021-03-05T03:11:30 | 2021-03-05T03:11:30 | {} | COLLABORATOR |
ClickHouse | ClickHouse | 791,148,759 | 21,101 | keerthana-kannan-ch | I am facing the same issue in `21.1.2.15 with revision 54445` | 2021-03-05T04:41:45 | 2021-03-05T04:41:45 | {} | NONE |
ClickHouse | ClickHouse | 791,397,105 | 21,476 | filimonov | will check it...
| 2021-03-05T12:45:27 | 2021-03-05T12:45:27 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 791,403,466 | 21,476 | filimonov | Where did you get the build?
Try that:
```
curl -O 'https://builds.clickhouse.tech/master/aarch64/clickhouse' && chmod a+x ./clickhouse
sudo ./clickhouse install
sudo clickhouse start
clickhouse-client
``` | 2021-03-05T12:59:01 | 2021-03-05T12:59:01 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 803,396,824 | 21,907 | den-crane | Can you show `create table topconversationdetails` | 2021-03-20T16:12:54 | 2021-03-20T16:12:54 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 803,453,422 | 9,945 | arslanhashmi | @den-crane how do we add swap? I don't seem to find it in CH documentation.. | 2021-03-20T19:44:15 | 2021-03-20T19:44:15 | {} | NONE |
ClickHouse | ClickHouse | 803,501,929 | 13,832 | filimonov | #21844 | 2021-03-21T02:36:22 | 2021-03-21T02:36:22 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 803,583,470 | 21,947 | den-crane | duplicate https://github.com/ClickHouse/ClickHouse/issues/8340 | 2021-03-21T13:48:23 | 2021-03-21T13:48:23 | {} | CONTRIBUTOR |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.