

RealityBench v1
🌐 Website | 📄 Paper: arXiv link to come
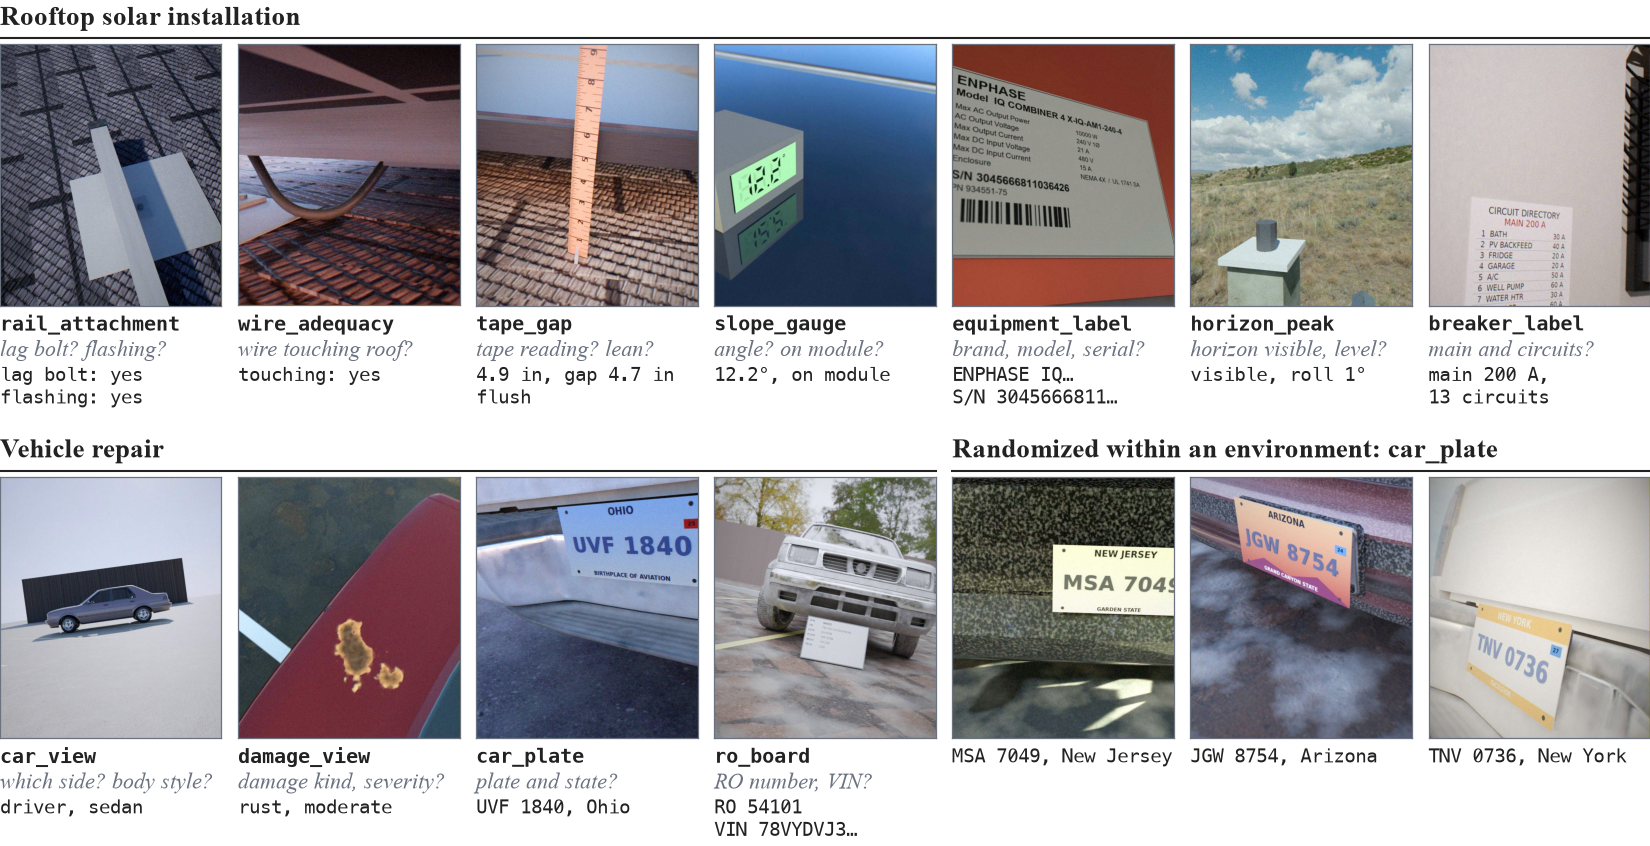
RealityBench tests whether a vision-language model can review a photo taken to document physical work. Each of the 1,378 items is one photo from one of eleven environments (seven from rooftop solar installation, four from vehicle repair intake) and one prompt. The model answers in a single JSON object:
- Acceptability: does the photo meet the stated requirement (
"adequate": true/false)? - Documentation: what does the photo show (a tape reading, a serial number, whether a lag bolt is present, ...)?
The photos are rendered in Blender from procedurally generated scenes, through a model of a phone camera (depth of field, sensor noise, missed focus and hand shake), so the ground truth for every documentation answer is read from the scene. The acceptability verdict comes from a rule per environment, tuned against human raters (below).
🏆 Leaderboard
26 models, one query per item, each at its provider's or model card's default settings, 13-23 September 2026. Sorted by acceptability F1; best model score in each column in bold.
| Model | F1 | precision | recall | documentation | in grammar (%) |
|---|---|---|---|---|---|
| GPT-6 Astra | 0.61 | 0.55 | 0.68 | 0.83 | 100 |
| Claude Opus 5.5 | 0.58 | 0.51 | 0.67 | 0.83 | 100 |
| GPT-5.6 Sol | 0.57 | 0.49 | 0.69 | 0.77 | 100 |
| GLM-5.3 Flash | 0.57 | 0.49 | 0.68 | 0.75 | 99 |
| Gemini 3.5 Flash | 0.56 | 0.49 | 0.66 | 0.80 | 97 |
| Claude Fable 5.1 | 0.56 | 0.51 | 0.63 | 0.83 | 100 |
| Claude Opus 5 | 0.56 | 0.54 | 0.57 | 0.75 | 100 |
| Qwen 3.8 Max | 0.55 | 0.43 | 0.78 | 0.82 | 100 |
| GPT-6 Sol | 0.55 | 0.50 | 0.61 | 0.78 | 100 |
| Muse Spark 1.3 | 0.55 | 0.49 | 0.62 | 0.79 | 100 |
| Qwen 3.5 397B-A17B | 0.55 | 0.49 | 0.61 | 0.76 | 99 |
| GPT-5.6 Terra | 0.55 | 0.45 | 0.70 | 0.76 | 100 |
| Qwen 3.8 27B | 0.54 | 0.45 | 0.68 | 0.74 | 99 |
| Grok 4.6 | 0.54 | 0.43 | 0.72 | 0.78 | 100 |
| Gemini 3.8 Flash | 0.54 | 0.48 | 0.62 | 0.84 | 100 |
| Kimi K3 | 0.53 | 0.42 | 0.70 | 0.77 | 99 |
| GPT-5.6 Luna | 0.53 | 0.46 | 0.62 | 0.71 | 100 |
| Gemma 4 31B | 0.52 | 0.44 | 0.63 | 0.79 | 100 |
| DeepSeek V4.1 Flash | 0.50 | 0.39 | 0.68 | 0.68 | 95 |
| Gemma 4 26B-A4B | 0.48 | 0.39 | 0.64 | 0.77 | 99 |
| Claude Sonnet 5 | 0.48 | 0.45 | 0.51 | 0.73 | 100 |
| Gemini 3.1 Flash Lite | 0.47 | 0.39 | 0.58 | 0.73 | 98 |
| LFM2.5-VL-3B | 0.43 | 0.30 | 0.79 | 0.68 | 99 |
| GPT-6 Luna | 0.43 | 0.46 | 0.41 | 0.62 | 100 |
| Gemma 4 E4B | 0.42 | 0.30 | 0.70 | 0.69 | 98 |
| Qwen3.5-4B | 0.39 | 0.31 | 0.50 | 0.66 | 95 |
| Human rater* | 0.59 | ||||
| Always "adequate" | 0.33 | 0.19 | 1.00 |
* A single non-author rater against the scorer, on 274 rated frames rather than this set (95 % CI 0.50-0.67). Intervals, per-environment scores and every model's answers are in results/.
Example
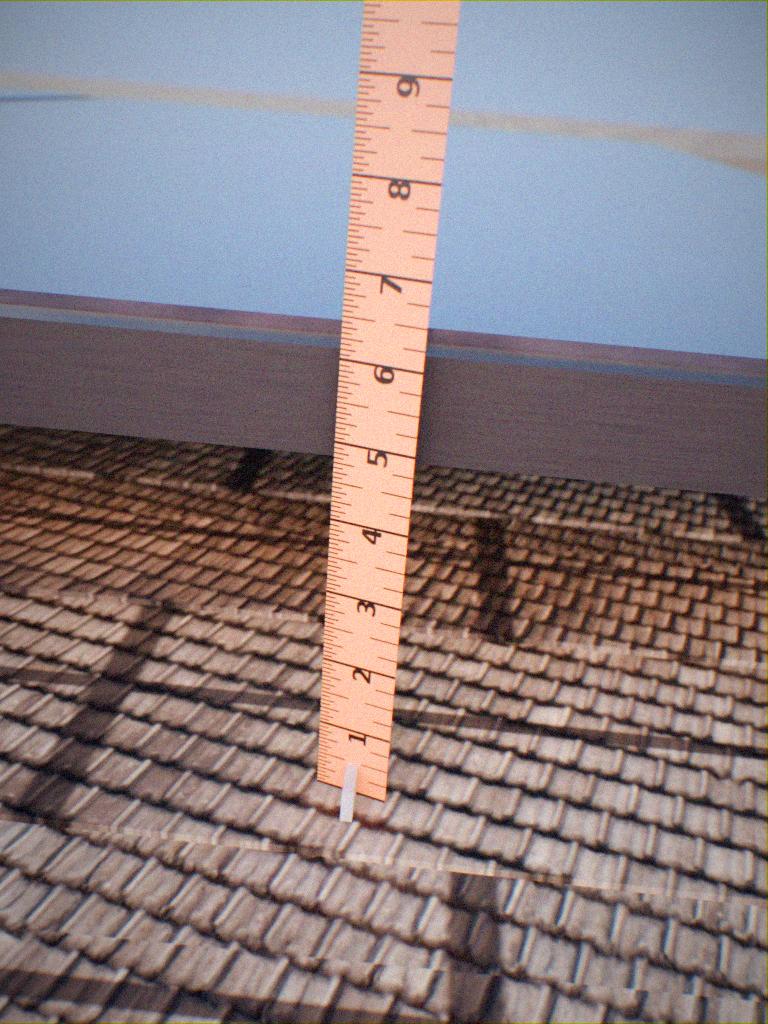
tape_gap/img_005117. The scorer accepts this frame. Ground truth: tape reads 4.88 in where the module frame crosses it (1/8 in tolerance), true gap 4.72 in (1/4 in tolerance), tape not tilted.
Prompt
You are reviewing a photo taken by a solar installer to document their work; the photo criteria will be used to prove the work was carried out correctly. The photo we need: Tape measure hooked at the roof surface and standing up to the module frame; the number where the frame crosses the tape must be legible, and the tape should be seated flush (perpendicular to the roof). First: is this photo adequate -- does it satisfy the requirement as a reviewer would judge it? Then answer the documentation question. What number (inches) is on the tape where the module frame crosses it, what is your estimate of the true perpendicular module-to-roof gap in inches, and is the tape leaning rather than standing flush? Answer with exactly one JSON object and nothing else -- no prose, no code fence -- with exactly these keys: "adequate": true or false (a JSON boolean): whether the photo is adequate; "reading_in": a number (JSON number, no units, no quotes); "gap_in": a number (JSON number, no units, no quotes); "tilted": true or false (a JSON boolean). Use these values exactly as written; a value in any other form is scored as wrong. Answer every key even if you judge the photo inadequate: give your best reading of what is visible.
| Model | adequate | reading_in | gap_in | tilted |
|---|---|---|---|---|
| GPT-6 Astra | false ✗ | 5 ✓ | 4 ✗ | true ✗ |
| Claude Opus 5.5 | false ✗ | 5.1 ✗ | 4.8 ✓ | true ✗ |
| Gemini 3.8 Flash | true ✓ | 5.5 ✗ | 5.5 ✗ | false ✓ |
Usage
from datasets import load_dataset
ds = load_dataset("relantic/realitybench", split="test")   # send prompt + image as one user message
python run_model.py --base-url http://localhost:8000/v1 --model <your model> --out predictions.jsonl   # any OpenAI-compatible endpoint
python score.py predictions.jsonl            # standard library only; lines are {"id": ..., "response": "<reply text>"}
python score.py results/lfm2.5-vl-3b.jsonl   # check your setup: prints that model's leaderboard row
Acceptability
Each prompt states a short natural-language requirement for the photo. The scorer turns it into checks (in frame, unoccluded, distance, view angle, resolution, sharpness, contrast), and a frame is acceptable when it passes all of them. Acceptability judges only the photo, so a photo of faulty work can still be acceptable. Raters disagree on these requirements, so the scorer encodes one interpretation of each: on held-out frames it agrees with the majority of six raters on 82 % of frames, while a single rater agrees with the others' majority on 76-92 %.
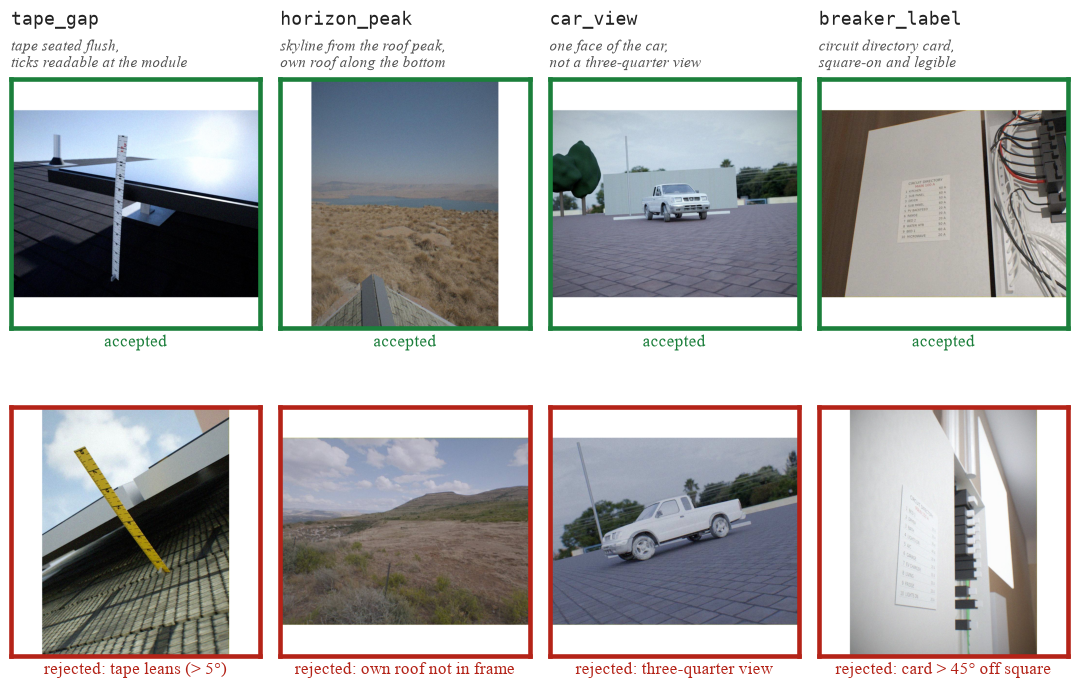
Scoring rules, items and fields
Metrics. F1: positives are the frames the scorer accepts; precision on the 934 random frames with an acceptability
score, recall on those plus the positive strata. A reply with no JSON boolean under adequate gives no verdict and is left
out. Documentation: mean per-field score on scorer-acceptable frames (exact match after normalisation for text; tape 1/8 in,
gap 1/4 in, slope 0.2 degrees), except tape leaning, which is scored on every tape_gap frame. In grammar: answers with
exactly the requested keys and types; reported, not scored.
Items. Random frames come from each environment's camera-pose distribution; the positive stratum adds acceptable frames
where they are rare and counts for recall only. Counts below 100 are frames left out because their verdict depended only on
an ambiguous term (43) or withdrawn for a texture defect (ro_board).
| environment | documentation question | random frames | of which acceptable | positive stratum |
|---|---|---|---|---|
breaker_label |
main breaker amps; every circuit's name and amps | 100 | 5 | 50 |
car_plate |
plate text and state | 100 | 21 | -- |
car_view |
which face (front, rear, driver, passenger); body style | 87 | 23 | -- |
damage_view |
damage kind (dent, scratch, rust); severity | 86 | 24 | -- |
equipment_label |
brand, model, serial; on a module, microinverter or inverter | 100 | 6 | 50 |
horizon_peak |
horizon visible? level? | 100 | 19 | 50 |
rail_attachment |
lag bolt present? flashing present? | 100 | 12 | 50 |
ro_board |
RO number, VIN | 79 | 14 | 42 |
slope_gauge |
gauge reading (degrees); on the module? | 91 | 25 | 50 |
tape_gap |
tape reading at the module frame; true gap (in); tape leaning? | 93 | 17 | 50 |
wire_adequacy |
wire touching the roof? | 100 | 39 | -- |
Fields. id, image, environment, stratum (random / positive), prompt (send as is), acceptable (the scorer's
verdict), acceptability_scored, documentation_asked, ground_truth (JSON string; also in items.jsonl).
Caveats. car_plate and 13 rail_attachment frames have no acceptability score, and 22 damage_view frames that do not
show the damage have no documentation score. body_style in ro_board and own_roof_blocks in horizon_peak are asked
but not scored. Our runs allowed 8,192 output tokens, thinking included.
Real tape-measure photos (tape_real)
To check that tape reading, one of the hardest rendered tasks, transfers to real photos: 133 readings on 84 photos of a tape measure held against everyday objects, with the truth from a caliper or a careful human tape read. A reading counts when it is within 1/8 in.
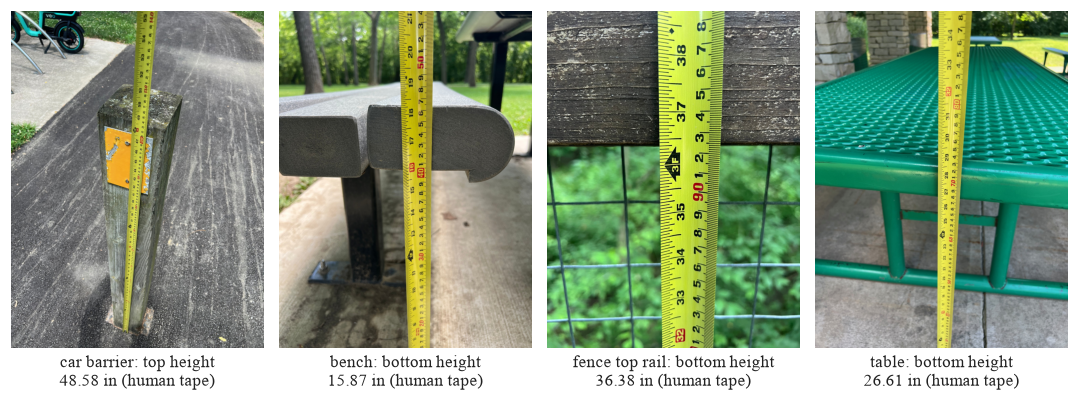
tape = load_dataset("relantic/realitybench", "tape_real", split="test") # then: python score.py --tape predictions.jsonl
Scores on the real photos (22 models)
A reply cut by the output-token cap is left out of that model's rate, so the number of scored readings varies.
| Model | within 1/8 in | readings scored |
|---|---|---|
| GPT-6 Astra | 0.44 | 133 |
| Claude Opus 5.5 | 0.35 | 133 |
| GPT-6 Sol | 0.33 | 133 |
| GPT-5.6 Sol | 0.33 | 133 |
| Claude Fable 5.1 | 0.29 | 133 |
| GLM-5.3 Flash | 0.27 | 79 |
| Claude Opus 5 | 0.23 | 133 |
| Gemini 3.8 Flash | 0.21 | 133 |
| GPT-5.6 Luna | 0.19 | 133 |
| Gemini 3.5 Flash | 0.17 | 133 |
| Qwen 3.5 397B-A17B | 0.13 | 125 |
| Grok 4.6 | 0.13 | 133 |
| Qwen 3.8 27B | 0.13 | 118 |
| Gemma 4 31B | 0.11 | 133 |
| Gemma 4 26B-A4B | 0.11 | 133 |
| Gemini 3.1 Flash Lite | 0.11 | 133 |
| GPT-6 Luna | 0.11 | 133 |
| GPT-5.6 Terra | 0.10 | 133 |
| Claude Sonnet 5 | 0.08 | 133 |
| Gemma 4 E4B | 0.05 | 133 |
| LFM2.5-VL-3B | 0.03 | 133 |
| Qwen3.5-4B | 0.02 | 133 |
Limitations
Single frames rather than video; the scorer is one reading of each requirement; two kinds of work; general-purpose models zero-shot at provider defaults. See the paper.
Contact
support@relantic.com, including for access to the environments (this repository holds the rendered benchmark only).
Citation
@misc{perrault2026realitybench,
  title  = {RealityBench: Simulated Environments to Evaluate a Vision Language Model's Ability to Document Human Physical Work},
  author = {Perrault, Andrew and Takiar, Anmol and Wienecki, Dominik and Nandi, Arnab},
  year   = {2026},
}
License
Frames, tape-measure photos, ground truth and model results: CC BY 4.0 (LICENSE-DATA). Code: MIT (LICENSE). The frames
were rendered from third-party CC0 and CC BY 4.0 assets, credited in ATTRIBUTION.md. © 2026 Relantic, Inc.
- Downloads last month
- 29