
url stringlengths 58 61 | repository_url stringclasses 1
value | labels_url stringlengths 72 75 | comments_url stringlengths 67 70 | events_url stringlengths 65 68 | html_url stringlengths 48 51 | id int64 600M 5.54B | node_id stringlengths 18 24 | number int64 2 8.66k | title stringlengths 1 290 | user dict | labels listlengths 0 4 | state stringclasses 2
values | locked bool 1
class | assignees listlengths 0 4 | milestone dict | comments listlengths 0 30 | created_at stringdate 2020-04-14 18:18:51 2026-09-22 08:39:29 | updated_at stringdate 2020-04-29 09:23:05 2026-09-22 08:41:52 | closed_at stringlengths 19 19 ⌀ | assignee dict | author_association stringclasses 4
values | issue_field_values listlengths 0 0 | type stringclasses 0
values | active_lock_reason stringclasses 0
values | draft bool 0
classes | pull_request dict | body stringlengths 0 228k ⌀ | closed_by dict | reactions dict | timeline_url stringlengths 67 70 | performed_via_github_app dict | state_reason stringclasses 4
values | sub_issues_summary stringclasses 1
value | issue_dependencies_summary stringclasses 1
value | pinned_comment stringclasses 0
values | is_pull_request bool 1
class |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
https://api.github.com/repos/huggingface/datasets/issues/5666 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5666/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5666/comments | https://api.github.com/repos/huggingface/datasets/issues/5666/events | https://github.com/huggingface/datasets/issues/5666 | 1,637,675,062 | I_kwDODunzps5hnPA2 | 5,666 | Support tensorflow 2.12.0 in CI | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [] | 2023-03-23 14:37:51 | 2023-03-23 16:14:54 | 2023-03-23 16:14:54 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | Once we find out the root cause of:
- #5663
we should revert the temporary pin on tensorflow introduced by:
- #5664 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5666/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5666/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5665 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5665/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5665/comments | https://api.github.com/repos/huggingface/datasets/issues/5665/events | https://github.com/huggingface/datasets/issues/5665 | 1,637,193,648 | I_kwDODunzps5hlZew | 5,665 | Feature request: IterableDataset.push_to_hub | {
"login": "NielsRogge",
"id": 48327001,
"node_id": "MDQ6VXNlcjQ4MzI3MDAx",
"avatar_url": "https://avatars.githubusercontent.com/u/48327001?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NielsRogge",
"html_url": "https://github.com/NielsRogge",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"+1",
"+1",
"+1, should be possible now? :) https://huggingface.co/blog/xethub-joins-hf",
"Haha we're working hard to integrate Xet in the HF back-end, it will enable cool use cases :)\n\nAnyway about `IterableDataset.push_to_hub`, I'd be happy to to provide guidance and answer questions if anyone wants to st... | 2023-03-23 09:53:04 | 2025-06-06 16:13:22 | 2025-06-06 16:12:36 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
It'd be great to have a lazy push to hub, similar to the lazy loading we have with `IterableDataset`.
Suppose you'd like to filter [LAION](https://huggingface.co/datasets/laion/laion400m) based on certain conditions, but as LAION doesn't fit into your disk, you'd like to leverage streaming:
`... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5665/reactions",
"total_count": 32,
"+1": 32,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5665/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5663 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5663/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5663/comments | https://api.github.com/repos/huggingface/datasets/issues/5663/events | https://github.com/huggingface/datasets/issues/5663 | 1,637,173,248 | I_kwDODunzps5hlUgA | 5,663 | CI is broken: ModuleNotFoundError: jax requires jaxlib to be installed | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [] | 2023-03-23 09:39:43 | 2023-03-23 10:09:55 | 2023-03-23 10:09:55 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | CI test_py310 is broken: see https://github.com/huggingface/datasets/actions/runs/4498945505/jobs/7916194236?pr=5662
```
FAILED tests/test_arrow_dataset.py::BaseDatasetTest::test_map_jax_in_memory - ModuleNotFoundError: jax requires jaxlib to be installed. See https://github.com/google/jax#installation for installati... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5663/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5663/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5661 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5661/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5661/comments | https://api.github.com/repos/huggingface/datasets/issues/5661/events | https://github.com/huggingface/datasets/issues/5661 | 1,637,129,445 | I_kwDODunzps5hlJzl | 5,661 | CI is broken: Unnecessary `dict` comprehension | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [] | 2023-03-23 09:13:01 | 2023-03-23 09:37:51 | 2023-03-23 09:37:51 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | CI check_code_quality is broken:
```
src/datasets/arrow_dataset.py:3267:35: C416 [*] Unnecessary `dict` comprehension (rewrite using `dict()`)
Found 1 error.
``` | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5661/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5661/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5660 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5660/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5660/comments | https://api.github.com/repos/huggingface/datasets/issues/5660/events | https://github.com/huggingface/datasets/issues/5660 | 1,635,543,646 | I_kwDODunzps5hfGpe | 5,660 | integration with imbalanced-learn | {
"login": "tansaku",
"id": 30216,
"node_id": "MDQ6VXNlcjMwMjE2",
"avatar_url": "https://avatars.githubusercontent.com/u/30216?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/tansaku",
"html_url": "https://github.com/tansaku",
"followers_url": "https://api.github.com/users/tansaku/follower... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"You can convert any dataset to pandas to be used with imbalanced-learn using `.to_pandas()`\r\n\r\nOtherwise if you want to keep a `Dataset` object and still use e.g. [make_imbalance](https://imbalanced-learn.org/stable/references/generated/imblearn.datasets.make_imbalance.html#imblearn.datasets.make_imbalance), y... | 2023-03-22 11:05:17 | 2023-07-06 18:10:15 | 2023-07-06 18:10:15 | null | NONE | [] | null | null | null | null | ### Feature request
Wouldn't it be great if the various class balancing operations from imbalanced-learn were available as part of datasets?
### Motivation
I'm trying to use imbalanced-learn to balance a dataset, but it's not clear how to get the two to interoperate - what would be great would be some examples. I'v... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5660/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5660/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5659 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5659/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5659/comments | https://api.github.com/repos/huggingface/datasets/issues/5659/events | https://github.com/huggingface/datasets/issues/5659 | 1,635,447,540 | I_kwDODunzps5hevL0 | 5,659 | [Audio] Soundfile/libsndfile requirements too stringent for decoding mp3 files | {
"login": "sanchit-gandhi",
"id": 93869735,
"node_id": "U_kgDOBZhWpw",
"avatar_url": "https://avatars.githubusercontent.com/u/93869735?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sanchit-gandhi",
"html_url": "https://github.com/sanchit-gandhi",
"followers_url": "https://api.github.com... | [] | closed | false | [] | null | [
"cc @polinaeterna @lhoestq ",
"@sanchit-gandhi can you please also post the logs of `pip install soundfile==0.12.1`? To check what wheel is being installed or if it's being built from source (I think it's the latter case). \r\nRequired `libsndfile` binary **should** be bundeled with `soundfile` wheel but I assume... | 2023-03-22 10:07:33 | 2024-07-12 01:35:01 | 2023-04-07 08:51:28 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I'm encountering several issues trying to load mp3 audio files using `datasets` on a TPU v4.
The PR https://github.com/huggingface/datasets/pull/5573 updated the audio loading logic to rely solely on the `soundfile`/`libsndfile` libraries for loading audio samples, regardless of their file t... | {
"login": "sanchit-gandhi",
"id": 93869735,
"node_id": "U_kgDOBZhWpw",
"avatar_url": "https://avatars.githubusercontent.com/u/93869735?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sanchit-gandhi",
"html_url": "https://github.com/sanchit-gandhi",
"followers_url": "https://api.github.com... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5659/reactions",
"total_count": 3,
"+1": 3,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5659/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5654 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5654/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5654/comments | https://api.github.com/repos/huggingface/datasets/issues/5654/events | https://github.com/huggingface/datasets/issues/5654 | 1,633,523,705 | I_kwDODunzps5hXZf5 | 5,654 | Offset overflow when executing Dataset.map | {
"login": "jan-pair",
"id": 118280608,
"node_id": "U_kgDOBwzRoA",
"avatar_url": "https://avatars.githubusercontent.com/u/118280608?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jan-pair",
"html_url": "https://github.com/jan-pair",
"followers_url": "https://api.github.com/users/jan-pair/... | [] | open | false | [] | null | [
"Upd. the above code works if we replace `25` with `1`, but the result value at key \"hr\" is not a tensor but a list of lists of lists of uint8.\r\n\r\nAdding `train_data.set_format(\"torch\")` after map fixes this, but the original issue remains\r\n\r\n",
"As a workaround, one can replace\r\n`return {\"hr\": to... | 2023-03-21 09:33:27 | 2023-03-21 10:32:07 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi, I'm trying to use `.map` method to cache multiple random crops from the image to speed up data processing during training, as the image size is too big.
The map function executes all iterations, and then returns the following error:
```bash
Traceback (most recent call last): ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5654/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5654/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5653 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5653/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5653/comments | https://api.github.com/repos/huggingface/datasets/issues/5653/events | https://github.com/huggingface/datasets/issues/5653 | 1,633,254,159 | I_kwDODunzps5hWXsP | 5,653 | Doc: save_to_disk, `num_proc` will affect `num_shards`, but it's not documented | {
"login": "RmZeta2718",
"id": 42400165,
"node_id": "MDQ6VXNlcjQyNDAwMTY1",
"avatar_url": "https://avatars.githubusercontent.com/u/42400165?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/RmZeta2718",
"html_url": "https://github.com/RmZeta2718",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892861,
"node_id": "MDU6TGFiZWwxOTM1ODkyODYx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/documentation",
"name": "documentation",
"color": "0075ca",
"default": true,
"description": "Improvements or additions to documentation",
"archived_at": null,
... | closed | false | [] | null | [
"I agree this should be documented"
] | 2023-03-21 05:25:35 | 2023-03-24 16:36:23 | 2023-03-24 16:36:23 | null | NONE | [] | null | null | null | null | ### Describe the bug
[`num_proc`](https://huggingface.co/docs/datasets/main/en/package_reference/main_classes#datasets.DatasetDict.save_to_disk.num_proc) will affect `num_shards`, but it's not documented
### Steps to reproduce the bug
Nothing to reproduce
### Expected behavior
[document of `num_shards`](https://... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5653/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5653/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5651 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5651/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5651/comments | https://api.github.com/repos/huggingface/datasets/issues/5651/events | https://github.com/huggingface/datasets/issues/5651 | 1,631,967,509 | I_kwDODunzps5hRdkV | 5,651 | expanduser in save_to_disk | {
"login": "RmZeta2718",
"id": 42400165,
"node_id": "MDQ6VXNlcjQyNDAwMTY1",
"avatar_url": "https://avatars.githubusercontent.com/u/42400165?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/RmZeta2718",
"html_url": "https://github.com/RmZeta2718",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892877,
"node_id": "MDU6TGFiZWwxOTM1ODkyODc3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/good%20first%20issue",
"name": "good first issue",
"color": "7057ff",
"default": true,
"description": "Good for newcomers",
"archived_at": null,
"archived_b... | closed | false | [
{
"login": "benjaminbrown038",
"id": 35114142,
"node_id": "MDQ6VXNlcjM1MTE0MTQy",
"avatar_url": "https://avatars.githubusercontent.com/u/35114142?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/benjaminbrown038",
"html_url": "https://github.com/benjaminbrown038",
"follo... | null | [
"`save_to_disk` should indeed expand `~`. Marking it as a \"good first issue\".",
"#self-assign\r\n\r\nFile path to code: \r\n\r\nhttps://github.com/huggingface/datasets/blob/2.13.0/src/datasets/arrow_dataset.py#L1364\r\n\r\n@RmZeta2718 I created a pull request for this issue. ",
"Hello, \r\nIt says `save_to_di... | 2023-03-20 12:02:18 | 2023-10-27 14:04:37 | 2023-10-27 14:04:37 | {
"login": "benjaminbrown038",
"id": 35114142,
"node_id": "MDQ6VXNlcjM1MTE0MTQy",
"avatar_url": "https://avatars.githubusercontent.com/u/35114142?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/benjaminbrown038",
"html_url": "https://github.com/benjaminbrown038",
"followers_url": "https://... | NONE | [] | null | null | null | null | ### Describe the bug
save_to_disk() does not expand `~`
1. `dataset = load_datasets("any dataset")`
2. `dataset.save_to_disk("~/data")`
3. a folder named "~" created in current folder
4. FileNotFoundError is raised, because the expanded path does not exist (`/home/<user>/data`)
related issue https://github.... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5651/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5651/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5650 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5650/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5650/comments | https://api.github.com/repos/huggingface/datasets/issues/5650/events | https://github.com/huggingface/datasets/issues/5650 | 1,630,336,919 | I_kwDODunzps5hLPeX | 5,650 | load_dataset can't work correct with my image data | {
"login": "WiNE-iNEFF",
"id": 41611046,
"node_id": "MDQ6VXNlcjQxNjExMDQ2",
"avatar_url": "https://avatars.githubusercontent.com/u/41611046?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/WiNE-iNEFF",
"html_url": "https://github.com/WiNE-iNEFF",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [
"Can you post a reproducible code snippet of what you tried to do?\r\n\r\n",
"> Can you post a reproducible code snippet of what you tried to do?\n> \n> \n\n```python\nfrom datasets import load_dataset\n\ndataset = load_dataset(\"my_folder_name\", split=\"train\")\n```",
"hi @WiNE-iNEFF ! can you please also te... | 2023-03-18 13:59:13 | 2026-02-27 06:58:26 | 2023-07-24 14:13:01 | null | NONE | [] | null | null | null | null | I have about 20000 images in my folder which divided into 4 folders with class names.
When i use load_dataset("my_folder_name", split="train") this function create dataset in which there are only 4 images, the remaining 19000 images were not added there. What is the problem and did not understand. Tried converting imag... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5650/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5650/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5649 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5649/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5649/comments | https://api.github.com/repos/huggingface/datasets/issues/5649/events | https://github.com/huggingface/datasets/issues/5649 | 1,630,173,460 | I_kwDODunzps5hKnkU | 5,649 | The index column created with .to_sql() is dependent on the batch_size when writing | {
"login": "lsb",
"id": 45281,
"node_id": "MDQ6VXNlcjQ1Mjgx",
"avatar_url": "https://avatars.githubusercontent.com/u/45281?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lsb",
"html_url": "https://github.com/lsb",
"followers_url": "https://api.github.com/users/lsb/followers",
"following... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [
"Thanks for reporting, @lsb. \r\n\r\nWe are investigating it.\r\n\r\nOn the other hand, please note that in the next `datasets` release, the index will not be created by default (see #5583). If you would like to have it, you will need to explicitly pass `index=True`. ",
"I think this is low enough priority for me... | 2023-03-18 05:25:17 | 2023-06-17 07:01:57 | 2023-06-17 07:01:57 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | NONE | [] | null | null | null | null | ### Describe the bug
It seems like the "index" column is designed to be unique? The values are only unique per batch. The SQL index is not a unique index.
This can be a problem, for instance, when building a faiss index on a dataset and then trying to match up ids with a sql export.
### Steps to reproduce the ... | {
"login": "lsb",
"id": 45281,
"node_id": "MDQ6VXNlcjQ1Mjgx",
"avatar_url": "https://avatars.githubusercontent.com/u/45281?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lsb",
"html_url": "https://github.com/lsb",
"followers_url": "https://api.github.com/users/lsb/followers",
"following... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5649/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5649/timeline | null | not_planned | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5648 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5648/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5648/comments | https://api.github.com/repos/huggingface/datasets/issues/5648/events | https://github.com/huggingface/datasets/issues/5648 | 1,629,253,719 | I_kwDODunzps5hHHBX | 5,648 | flatten_indices doesn't work with pandas format | {
"login": "alialamiidrissi",
"id": 14365168,
"node_id": "MDQ6VXNlcjE0MzY1MTY4",
"avatar_url": "https://avatars.githubusercontent.com/u/14365168?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alialamiidrissi",
"html_url": "https://github.com/alialamiidrissi",
"followers_url": "https://api... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | open | false | [
{
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https:... | null | [
"Thanks for reporting! This can be fixed by setting the format to `arrow` in `flatten_indices` and restoring the original format after the flattening. I'm working on a PR that reduces the number of the `flatten_indices` calls in our codebase and makes `flatten_indices` a no-op when a dataset does not have an indice... | 2023-03-17 12:44:25 | 2023-03-21 13:12:03 | null | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
I noticed that `flatten_indices` throws an error when the batch format is `pandas`. This is probably due to the fact that flatten_indices uses map internally which doesn't accept dataframes as the transformation function output
### Steps to reproduce the bug
tabular_data = pd.DataFrame(np.r... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5648/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5648/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5647 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5647/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5647/comments | https://api.github.com/repos/huggingface/datasets/issues/5647/events | https://github.com/huggingface/datasets/issues/5647 | 1,628,225,544 | I_kwDODunzps5hDMAI | 5,647 | Make all print statements optional | {
"login": "gagan3012",
"id": 49101362,
"node_id": "MDQ6VXNlcjQ5MTAxMzYy",
"avatar_url": "https://avatars.githubusercontent.com/u/49101362?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/gagan3012",
"html_url": "https://github.com/gagan3012",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"related to #5444 ",
"We now log these messages instead of printing them (addressed in #6019), so I'm closing this issue."
] | 2023-03-16 20:30:07 | 2023-07-21 14:20:25 | 2023-07-21 14:20:24 | null | NONE | [] | null | null | null | null | ### Feature request
Make all print statements optional to speed up the development
### Motivation
Im loading multiple tiny datasets and all the print statements make the loading slower
### Your contribution
I can help contribute | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5647/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5647/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5645 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5645/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5645/comments | https://api.github.com/repos/huggingface/datasets/issues/5645/events | https://github.com/huggingface/datasets/issues/5645 | 1,627,108,278 | I_kwDODunzps5g-7O2 | 5,645 | Datasets map and select(range()) is giving dill error | {
"login": "Tanya-11",
"id": 90728105,
"node_id": "MDQ6VXNlcjkwNzI4MTA1",
"avatar_url": "https://avatars.githubusercontent.com/u/90728105?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Tanya-11",
"html_url": "https://github.com/Tanya-11",
"followers_url": "https://api.github.com/users/Tan... | [] | closed | false | [] | null | [
"It looks like an error that we observed once in https://github.com/huggingface/datasets/pull/5166\r\n\r\nCan you try to update `datasets` ?\r\n\r\n```\r\npip install -U datasets\r\n```\r\n\r\nif it doesn't work, can you make sure you don't have packages installed that may modify `dill`'s behavior, such as `apache-... | 2023-03-16 10:01:28 | 2023-03-17 04:24:51 | 2023-03-17 04:24:51 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm using Huggingface Datasets library to load the dataset in google colab
When I do,
> data = train_dataset.select(range(10))
or
> train_datasets = train_dataset.map(
> process_data_to_model_inputs,
> batched=True,
> batch_size=batch_size,
> remove_columns... | {
"login": "Tanya-11",
"id": 90728105,
"node_id": "MDQ6VXNlcjkwNzI4MTA1",
"avatar_url": "https://avatars.githubusercontent.com/u/90728105?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Tanya-11",
"html_url": "https://github.com/Tanya-11",
"followers_url": "https://api.github.com/users/Tan... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5645/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5645/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5641 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5641/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5641/comments | https://api.github.com/repos/huggingface/datasets/issues/5641/events | https://github.com/huggingface/datasets/issues/5641 | 1,625,942,730 | I_kwDODunzps5g6erK | 5,641 | Features cannot be named "self" | {
"login": "alialamiidrissi",
"id": 14365168,
"node_id": "MDQ6VXNlcjE0MzY1MTY4",
"avatar_url": "https://avatars.githubusercontent.com/u/14365168?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alialamiidrissi",
"html_url": "https://github.com/alialamiidrissi",
"followers_url": "https://api... | [] | closed | false | [] | null | [] | 2023-03-15 17:16:40 | 2023-03-16 17:14:51 | 2023-03-16 17:14:51 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
I noticed that we cannot create a HuggingFace dataset from Pandas DataFrame with a column named `self`.
The error seems to be coming from arguments validation in the `Features.from_dict` function.
### Steps to reproduce the bug
```python
import datasets
dummy_pandas = pd.DataFrame([0... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5641/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5641/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5639 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5639/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5639/comments | https://api.github.com/repos/huggingface/datasets/issues/5639/events | https://github.com/huggingface/datasets/issues/5639 | 1,625,737,098 | I_kwDODunzps5g5seK | 5,639 | Parquet file wrongly recognized as zip prevents loading a dataset | {
"login": "clefourrier",
"id": 22726840,
"node_id": "MDQ6VXNlcjIyNzI2ODQw",
"avatar_url": "https://avatars.githubusercontent.com/u/22726840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/clefourrier",
"html_url": "https://github.com/clefourrier",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [] | 2023-03-15 15:20:45 | 2023-03-16 13:40:14 | 2023-03-16 13:40:14 | null | MEMBER | [] | null | null | null | null | ### Describe the bug
When trying to `load_dataset_builder` for `HuggingFaceGECLM/StackExchange_Mar2023`, extraction fails, because parquet file [devops-00000-of-00001-22fe902fd8702892.parquet](https://huggingface.co/datasets/HuggingFaceGECLM/StackExchange_Mar2023/resolve/1f8c9a2ab6f7d0f9ae904b8b922e4384592ae1a5/data... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5639/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5639/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5638 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5638/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5638/comments | https://api.github.com/repos/huggingface/datasets/issues/5638/events | https://github.com/huggingface/datasets/issues/5638 | 1,625,564,471 | I_kwDODunzps5g5CU3 | 5,638 | xPath to implement all operations for Path | {
"login": "thomasw21",
"id": 24695242,
"node_id": "MDQ6VXNlcjI0Njk1MjQy",
"avatar_url": "https://avatars.githubusercontent.com/u/24695242?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/thomasw21",
"html_url": "https://github.com/thomasw21",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
" I think https://github.com/fsspec/universal_pathlib is the project you are looking for.\r\n\r\n`xPath` has the methods often used in dataset scripts, and `mkdir` is not one of them (`dl_manager`'s role is to \"interact\" with the file system, so using `mkdir` is discouraged).",
"Right is there a difference betw... | 2023-03-15 13:47:11 | 2023-03-17 13:21:12 | 2023-03-17 13:21:12 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Current xPath implementation is a great extension of Path in order to work with remote objects. However some methods such as `mkdir` are not implemented correctly. It should instead rely on `fsspec` methods, instead of defaulting do `Path` methods which only work locally.
### Motivation
I'm using... | {
"login": "thomasw21",
"id": 24695242,
"node_id": "MDQ6VXNlcjI0Njk1MjQy",
"avatar_url": "https://avatars.githubusercontent.com/u/24695242?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/thomasw21",
"html_url": "https://github.com/thomasw21",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5638/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5638/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5637 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5637/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5637/comments | https://api.github.com/repos/huggingface/datasets/issues/5637/events | https://github.com/huggingface/datasets/issues/5637 | 1,625,295,691 | I_kwDODunzps5g4AtL | 5,637 | IterableDataset with_format does not support 'device' keyword for jax | {
"login": "Lime-Cakes",
"id": 91322985,
"node_id": "MDQ6VXNlcjkxMzIyOTg1",
"avatar_url": "https://avatars.githubusercontent.com/u/91322985?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Lime-Cakes",
"html_url": "https://github.com/Lime-Cakes",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"Hi! Yes, only `torch` is currently supported. Unlike `Dataset`, `IterableDataset` is not PyArrow-backed, so we cannot simply call `to_numpy` on the underlying subtables to format them numerically. Instead, we must manually convert examples to (numeric) arrays while preserving consistency with `Dataset`, which is n... | 2023-03-15 11:04:12 | 2025-01-07 06:59:33 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
As seen here: https://huggingface.co/docs/datasets/use_with_jax dataset.with_format() supports the keyword 'device', to put data on a specific device when loaded as jax. However, when called on an IterableDataset, I got the error `TypeError: with_format() got an unexpected keyword argument 'devi... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5637/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5637/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5634 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5634/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5634/comments | https://api.github.com/repos/huggingface/datasets/issues/5634/events | https://github.com/huggingface/datasets/issues/5634 | 1,622,424,174 | I_kwDODunzps5gtDpu | 5,634 | Not all progress bars are showing up when they should for downloading dataset | {
"login": "garlandz-db",
"id": 110427462,
"node_id": "U_kgDOBpT9Rg",
"avatar_url": "https://avatars.githubusercontent.com/u/110427462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/garlandz-db",
"html_url": "https://github.com/garlandz-db",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Hi! \r\n\r\nBy default, tqdm has `leave=True` to \"keep all traces of the progress bar upon the termination of iteration\". However, we use `leave=False` in some places (as of recently), which removes the bar once the iteration is over.\r\n\r\nI feel like our TQDM bars are noisy, so I think we should always set `l... | 2023-03-13 23:04:18 | 2023-10-11 16:30:16 | 2023-10-11 16:30:16 | null | NONE | [] | null | null | null | null | ### Describe the bug
During downloading the rotten tomatoes dataset, not all progress bars are displayed properly. This might be related to [this ticket](https://github.com/huggingface/datasets/issues/5117) as it raised the same concern but its not clear if the fix solves this issue too.
ipywidgets
<img width=... | {
"login": "garlandz-db",
"id": 110427462,
"node_id": "U_kgDOBpT9Rg",
"avatar_url": "https://avatars.githubusercontent.com/u/110427462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/garlandz-db",
"html_url": "https://github.com/garlandz-db",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5634/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5634/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5633 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5633/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5633/comments | https://api.github.com/repos/huggingface/datasets/issues/5633/events | https://github.com/huggingface/datasets/issues/5633 | 1,621,469,970 | I_kwDODunzps5gpasS | 5,633 | Cannot import datasets | {
"login": "ruplet",
"id": 11250555,
"node_id": "MDQ6VXNlcjExMjUwNTU1",
"avatar_url": "https://avatars.githubusercontent.com/u/11250555?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ruplet",
"html_url": "https://github.com/ruplet",
"followers_url": "https://api.github.com/users/ruplet/fo... | [] | closed | false | [] | null | [
"Okay, the issue was likely caused by mixing `conda` and `pip` usage - I forgot that I have already used `pip` in this environment previously and that it was 'spoiled' because of it. Creating another environment and installing `datasets` by pip with other packages from the `requirements.txt` file solved the problem... | 2023-03-13 13:14:44 | 2023-03-13 17:54:19 | 2023-03-13 17:54:19 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
I cannot even import the library :( I installed it by running:
```
$ conda install datasets
```
Then I realized I should maybe use the huggingface channel, because I encountered the error below, so I ran:
```
$ conda remove datasets
$ conda install -c huggingface datasets
```
Pl... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5633/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5633/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5632 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5632/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5632/comments | https://api.github.com/repos/huggingface/datasets/issues/5632/events | https://github.com/huggingface/datasets/issues/5632 | 1,621,177,391 | I_kwDODunzps5goTQv | 5,632 | Dataset cannot convert too large dictionnary | {
"login": "MaraLac",
"id": 108518627,
"node_id": "U_kgDOBnfc4w",
"avatar_url": "https://avatars.githubusercontent.com/u/108518627?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MaraLac",
"html_url": "https://github.com/MaraLac",
"followers_url": "https://api.github.com/users/MaraLac/foll... | [] | open | false | [] | null | [
"Answered on the forum:\r\n\r\n> To fix the overflow error, we need to merge [support LargeListArray in pyarrow by xwwwwww · Pull Request #4800 · huggingface/datasets · GitHub](https://github.com/huggingface/datasets/pull/4800), which adds support for the large lists. However, before merging it, we need to come up ... | 2023-03-13 10:14:40 | 2023-03-16 15:28:57 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hello everyone!
I tried to build a new dataset with the command "dict_valid = datasets.Dataset.from_dict({'input_values': values_array})".
However, I have a very large dataset (~400Go) and it seems that dataset cannot handle this.
Indeed, I can create the dataset until a certain size of m... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5632/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5632/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5631 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5631/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5631/comments | https://api.github.com/repos/huggingface/datasets/issues/5631/events | https://github.com/huggingface/datasets/issues/5631 | 1,620,442,854 | I_kwDODunzps5glf7m | 5,631 | Custom split names | {
"login": "ErfanMoosaviMonazzah",
"id": 79091831,
"node_id": "MDQ6VXNlcjc5MDkxODMx",
"avatar_url": "https://avatars.githubusercontent.com/u/79091831?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ErfanMoosaviMonazzah",
"html_url": "https://github.com/ErfanMoosaviMonazzah",
"followers_url... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi!\r\n\r\nYou can also use names other than \"train\", \"validation\" and \"test\". As an example, check the [script](https://huggingface.co/datasets/mozilla-foundation/common_voice_11_0/blob/e095840f23f3dffc1056c078c2f9320dad9ca74d/common_voice_11_0.py#L139) of the Common Voice 11 dataset. "
] | 2023-03-12 17:21:43 | 2023-03-24 14:13:00 | 2023-03-24 14:13:00 | null | NONE | [] | null | null | null | null | ### Feature request
Hi,
I participated in multiple NLP tasks where there are more than just train, test, validation splits, there could be multiple validation sets or test sets. But it seems currently only those mentioned three splits supported. It would be nice to have the support for more splits on the hub. (curren... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5631/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5631/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5629 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5629/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5629/comments | https://api.github.com/repos/huggingface/datasets/issues/5629/events | https://github.com/huggingface/datasets/issues/5629 | 1,619,921,247 | I_kwDODunzps5gjglf | 5,629 | load_dataset gives "403" error when using Financial phrasebank | {
"login": "Jimchoo91",
"id": 67709789,
"node_id": "MDQ6VXNlcjY3NzA5Nzg5",
"avatar_url": "https://avatars.githubusercontent.com/u/67709789?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Jimchoo91",
"html_url": "https://github.com/Jimchoo91",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"Hi! You seem to be using an outdated version of `datasets` that downloads the older script version. To avoid the error, you can either pass `revision=\"main\"` to `load_dataset` (this can fail if a script uses newer features of the lib) or update your installation with `pip install -U datasets` (better solution)."... | 2023-03-11 07:46:39 | 2023-03-13 18:27:26 | null | null | NONE | [] | null | null | null | null | When I try to load this dataset, I receive the following error:
ConnectionError: Couldn't reach https://www.researchgate.net/profile/Pekka_Malo/publication/251231364_FinancialPhraseBank-v10/data/0c96051eee4fb1d56e000000/FinancialPhraseBank-v10.zip (error 403)
Has this been seen before? Thanks. The website loads ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5629/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5629/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5627 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5627/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5627/comments | https://api.github.com/repos/huggingface/datasets/issues/5627/events | https://github.com/huggingface/datasets/issues/5627 | 1,619,336,609 | I_kwDODunzps5ghR2h | 5,627 | Unable to load AutoTrain-generated dataset from the hub | {
"login": "ijmiller2",
"id": 8560151,
"node_id": "MDQ6VXNlcjg1NjAxNTE=",
"avatar_url": "https://avatars.githubusercontent.com/u/8560151?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ijmiller2",
"html_url": "https://github.com/ijmiller2",
"followers_url": "https://api.github.com/users/ij... | [] | open | false | [] | null | [
"The AutoTrain format is not supported right now. I think it would require a dedicated dataset builder",
"Okay, good to know. Thanks for the reply. For now I will just have to\nmanage the split manually before training, because I can’t find any way of\npulling out file indices or file names from the autogenerated... | 2023-03-10 17:25:58 | 2023-03-11 15:44:42 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
DatasetGenerationError: An error occurred while generating the dataset -> ValueError: Couldn't cast ... because column names don't match
```
ValueError: Couldn't cast
_data_files: list<item: struct<filename: string>>
child 0, item: struct<filename: string>
child 0, filename: string
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5627/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5627/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5625 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5625/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5625/comments | https://api.github.com/repos/huggingface/datasets/issues/5625/events | https://github.com/huggingface/datasets/issues/5625 | 1,618,971,855 | I_kwDODunzps5gf4zP | 5,625 | Allow "jsonl" data type signifier | {
"login": "BramVanroy",
"id": 2779410,
"node_id": "MDQ6VXNlcjI3Nzk0MTA=",
"avatar_url": "https://avatars.githubusercontent.com/u/2779410?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/BramVanroy",
"html_url": "https://github.com/BramVanroy",
"followers_url": "https://api.github.com/users... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"You can use \"json\" instead. It doesn't work by extension names, but rather by dataset builder names, e.g. \"text\", \"imagefolder\", etc. I don't think the example in `transformers` is correct because of that",
"Yes, I understand the reasoning but this issue is to propose that the example in transformers (whil... | 2023-03-10 13:21:48 | 2023-03-11 10:35:39 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
`load_dataset` currently does not accept `jsonl` as type but only `json`.
### Motivation
I was working with one of the `run_translation` scripts and used my own datasets (`.jsonl`) as train_dataset. But the default code did not work because
```
FileNotFoundError: Couldn't find a dataset scri... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5625/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5625/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5624 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5624/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5624/comments | https://api.github.com/repos/huggingface/datasets/issues/5624/events | https://github.com/huggingface/datasets/issues/5624 | 1,617,400,192 | I_kwDODunzps5gZ5GA | 5,624 | glue datasets returning -1 for test split | {
"login": "lithafnium",
"id": 8939967,
"node_id": "MDQ6VXNlcjg5Mzk5Njc=",
"avatar_url": "https://avatars.githubusercontent.com/u/8939967?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lithafnium",
"html_url": "https://github.com/lithafnium",
"followers_url": "https://api.github.com/users... | [] | closed | false | [] | null | [
"Hi @lithafnium, thanks for reporting.\r\n\r\nPlease note that you can use the \"Community\" tab in the corresponding dataset page to start any discussion: https://huggingface.co/datasets/glue/discussions\r\n\r\nIndeed this issue was already raised there (https://huggingface.co/datasets/glue/discussions/5) and answ... | 2023-03-09 14:47:18 | 2023-03-09 16:49:29 | 2023-03-09 16:49:29 | null | NONE | [] | null | null | null | null | ### Describe the bug
Downloading any dataset from GLUE has -1 as class labels for test split. Train and validation have regular 0/1 class labels. This is also present in the dataset card online.
### Steps to reproduce the bug
```
dataset = load_dataset("glue", "sst2")
for d in dataset:
# prints out -1
... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5624/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5624/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5618 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5618/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5618/comments | https://api.github.com/repos/huggingface/datasets/issues/5618/events | https://github.com/huggingface/datasets/issues/5618 | 1,612,977,934 | I_kwDODunzps5gJBcO | 5,618 | Unpin fsspec < 2023.3.0 once issue fixed | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | [] | 2023-03-07 08:41:51 | 2023-03-07 13:39:03 | 2023-03-07 13:39:03 | null | MEMBER | [] | null | null | null | null | Unpin `fsspec` upper version once root cause of our CI break is fixed.
See:
- #5614 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5618/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5618/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5616 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5616/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5616/comments | https://api.github.com/repos/huggingface/datasets/issues/5616/events | https://github.com/huggingface/datasets/issues/5616 | 1,612,932,508 | I_kwDODunzps5gI2Wc | 5,616 | CI is broken after fsspec-2023.3.0 release | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [] | null | [] | 2023-03-07 08:06:39 | 2023-03-07 08:37:29 | 2023-03-07 08:37:29 | null | MEMBER | [] | null | null | null | null | As reported by @lhoestq, our CI is broken after `fsspec` 2023.3.0 release:
```
FAILED tests/test_filesystem.py::test_compression_filesystems[Bz2FileSystem] - AssertionError: assert [{'created': ...: False, ...}] == ['file.txt']
At index 0 diff: {'name': 'file.txt', 'size': 70, 'type': 'file', 'created': 1678175677... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5616/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5616/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5615 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5615/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5615/comments | https://api.github.com/repos/huggingface/datasets/issues/5615/events | https://github.com/huggingface/datasets/issues/5615 | 1,612,552,653 | I_kwDODunzps5gHZnN | 5,615 | IterableDataset.add_column is unable to accept another IterableDataset as a parameter. | {
"login": "zsaladin",
"id": 6466389,
"node_id": "MDQ6VXNlcjY0NjYzODk=",
"avatar_url": "https://avatars.githubusercontent.com/u/6466389?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/zsaladin",
"html_url": "https://github.com/zsaladin",
"followers_url": "https://api.github.com/users/zsala... | [
{
"id": 1935892913,
"node_id": "MDU6TGFiZWwxOTM1ODkyOTEz",
"url": "https://api.github.com/repos/huggingface/datasets/labels/wontfix",
"name": "wontfix",
"color": "ffffff",
"default": true,
"description": "This will not be worked on",
"archived_at": null,
"archived_by": null
}
] | closed | false | [] | null | [
"Hi! You can use `concatenate_datasets([ids1, ids2], axis=1)` to do this."
] | 2023-03-07 01:52:00 | 2023-03-09 15:24:05 | 2023-03-09 15:23:54 | null | NONE | [] | null | null | null | null | ### Describe the bug
`IterableDataset.add_column` occurs an exception when passing another `IterableDataset` as a parameter.
The method seems to accept only eager evaluated values.
https://github.com/huggingface/datasets/blob/35b789e8f6826b6b5a6b48fcc2416c890a1f326a/src/datasets/iterable_dataset.py#L1388-L1391
... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5615/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5615/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5613 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5613/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5613/comments | https://api.github.com/repos/huggingface/datasets/issues/5613/events | https://github.com/huggingface/datasets/issues/5613 | 1,611,875,473 | I_kwDODunzps5gE0SR | 5,613 | Version mismatch with multiprocess and dill on Python 3.10 | {
"login": "adampauls",
"id": 1243668,
"node_id": "MDQ6VXNlcjEyNDM2Njg=",
"avatar_url": "https://avatars.githubusercontent.com/u/1243668?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/adampauls",
"html_url": "https://github.com/adampauls",
"followers_url": "https://api.github.com/users/ad... | [] | open | false | [] | null | [
"Sorry, I just found https://github.com/apache/beam/issues/24458. It seems this issue is being worked on. ",
"Reopening, since I think the docs should inform the user of this problem. For example, [this page](https://huggingface.co/docs/datasets/installation) says \r\n> Datasets is tested on Python 3.7+.\r\n\r\nb... | 2023-03-06 17:14:41 | 2024-04-05 20:13:52 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Grabbing the latest version of `datasets` and `apache-beam` with `poetry` using Python 3.10 gives a crash at runtime. The crash is
```
File "/Users/adpauls/sc/git/DSI-transformers/data/NQ/create_NQ_train_vali.py", line 1, in <module>
import datasets
File "/Users/adpauls/Library/Caches/... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5613/reactions",
"total_count": 10,
"+1": 10,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5613/timeline | null | reopened | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5612 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5612/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5612/comments | https://api.github.com/repos/huggingface/datasets/issues/5612/events | https://github.com/huggingface/datasets/issues/5612 | 1,611,262,510 | I_kwDODunzps5gCeou | 5,612 | Arrow map type in parquet files unsupported | {
"login": "TevenLeScao",
"id": 26709476,
"node_id": "MDQ6VXNlcjI2NzA5NDc2",
"avatar_url": "https://avatars.githubusercontent.com/u/26709476?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TevenLeScao",
"html_url": "https://github.com/TevenLeScao",
"followers_url": "https://api.github.com/... | [] | open | false | [] | null | [
"I'm attaching a minimal reproducible example:\r\n```python\r\nfrom datasets import load_dataset\r\nimport pyarrow as pa\r\nimport pyarrow.parquet as pq\r\n\r\ntable_with_map = pa.Table.from_pydict(\r\n {\"a\": [1, 2], \"b\": [[(\"a\", 2)], [(\"b\", 4)]]},\r\n schema=pa.schema({\"a\": pa.int32(), \"b\": pa.ma... | 2023-03-06 12:03:24 | 2024-03-15 18:56:12 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True` solves the issue.
### Steps to reproduce ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5612/reactions",
"total_count": 5,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 5
} | https://api.github.com/repos/huggingface/datasets/issues/5612/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5610 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5610/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5610/comments | https://api.github.com/repos/huggingface/datasets/issues/5610/events | https://github.com/huggingface/datasets/issues/5610 | 1,610,698,006 | I_kwDODunzps5gAU0W | 5,610 | use datasets streaming mode in trainer ddp mode cause memory leak | {
"login": "gromzhu",
"id": 15223544,
"node_id": "MDQ6VXNlcjE1MjIzNTQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/15223544?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/gromzhu",
"html_url": "https://github.com/gromzhu",
"followers_url": "https://api.github.com/users/gromzh... | [] | open | false | [] | null | [
"Same problem, \r\ntransformers 4.28.1\r\ndatasets 2.12.0\r\n\r\nleak around 100Mb per 10 seconds when use dataloader_num_werker > 0 in training argumennts for transformer train, possile bug in transformers repo, but still not found solution :(\r\n",
"found an article described a problem, may be helpful for someb... | 2023-03-06 05:26:49 | 2024-03-07 01:11:32 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
use datasets streaming mode in trainer ddp mode cause memory leak
### Steps to reproduce the bug
import os
import time
import datetime
import sys
import numpy as np
import random
import torch
from torch.utils.data import Dataset, DataLoader, random_split, RandomSampler, Sequenti... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5610/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5610/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5609 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5609/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5609/comments | https://api.github.com/repos/huggingface/datasets/issues/5609/events | https://github.com/huggingface/datasets/issues/5609 | 1,610,062,862 | I_kwDODunzps5f95wO | 5,609 | `load_from_disk` vs `load_dataset` performance. | {
"login": "davidgilbertson",
"id": 4443482,
"node_id": "MDQ6VXNlcjQ0NDM0ODI=",
"avatar_url": "https://avatars.githubusercontent.com/u/4443482?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/davidgilbertson",
"html_url": "https://github.com/davidgilbertson",
"followers_url": "https://api.g... | [] | open | false | [] | null | [
"Hi! We've recently made some improvements to `save_to_disk`/`list_to_disk` (100x faster in some scenarios), so it would help if you could install `datasets` directly from `main` (`pip install git+https://github.com/huggingface/datasets.git`) and re-run the \"benchmark\".",
"Great to hear! I'll give it a try when... | 2023-03-05 05:27:15 | 2023-07-13 18:48:05 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I have downloaded `openwebtext` (~12GB) and filtered out a small amount of junk (it's still huge). Now, I would like to use this filtered version for future work. It seems I have two choices:
1. Use `load_dataset` each time, relying on the cache mechanism, and re-run my filtering.
2. `save_to_di... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5609/reactions",
"total_count": 4,
"+1": 4,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5609/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5608 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5608/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5608/comments | https://api.github.com/repos/huggingface/datasets/issues/5608/events | https://github.com/huggingface/datasets/issues/5608 | 1,609,996,563 | I_kwDODunzps5f9pkT | 5,608 | audiofolder only creates dataset of 13 rows (files) when the data folder it's reading from has 20,000 mp3 files. | {
"login": "joseph-y-cho",
"id": 107211437,
"node_id": "U_kgDOBmPqrQ",
"avatar_url": "https://avatars.githubusercontent.com/u/107211437?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joseph-y-cho",
"html_url": "https://github.com/joseph-y-cho",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [
"Hi!\r\n\r\n> naming convention of mp3 files\r\n\r\nYes, this could be the problem. MP3 files should end with `.mp3`/`.MP3` to be recognized as audio files.\r\n\r\nIf the file names are not the culprit, can you paste the audio folder's directory structure to help us reproduce the error (e.g., by running the `tree ... | 2023-03-05 00:14:45 | 2023-03-12 00:02:57 | 2023-03-12 00:02:57 | null | NONE | [] | null | null | null | null | ### Describe the bug
x = load_dataset("audiofolder", data_dir="x")
When running this, x is a dataset of 13 rows (files) when it should be 20,000 rows (files) as the data_dir "x" has 20,000 mp3 files. Does anyone know what could possibly cause this (naming convention of mp3 files, etc.)
### Steps to reproduce the b... | {
"login": "joseph-y-cho",
"id": 107211437,
"node_id": "U_kgDOBmPqrQ",
"avatar_url": "https://avatars.githubusercontent.com/u/107211437?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joseph-y-cho",
"html_url": "https://github.com/joseph-y-cho",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5608/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5608/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5606 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5606/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5606/comments | https://api.github.com/repos/huggingface/datasets/issues/5606/events | https://github.com/huggingface/datasets/issues/5606 | 1,608,911,632 | I_kwDODunzps5f5gsQ | 5,606 | Add `Dataset.to_list` to the API | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "kyoto7250",
"id": 50972773,
"node_id": "MDQ6VXNlcjUwOTcyNzcz",
"avatar_url": "https://avatars.githubusercontent.com/u/50972773?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/kyoto7250",
"html_url": "https://github.com/kyoto7250",
"followers_url": "https://a... | null | [
"Hello, I have an interest in this issue.\r\nIs the `Dataset.to_dict` you are describing correct in the code here?\r\n\r\nhttps://github.com/huggingface/datasets/blob/35b789e8f6826b6b5a6b48fcc2416c890a1f326a/src/datasets/arrow_dataset.py#L4633-L4667",
"Yes, this is where `Dataset.to_dict` is defined.",
"#self-a... | 2023-03-03 16:17:10 | 2023-03-27 13:26:40 | 2023-03-27 13:26:40 | {
"login": "kyoto7250",
"id": 50972773,
"node_id": "MDQ6VXNlcjUwOTcyNzcz",
"avatar_url": "https://avatars.githubusercontent.com/u/50972773?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/kyoto7250",
"html_url": "https://github.com/kyoto7250",
"followers_url": "https://api.github.com/users/... | COLLABORATOR | [] | null | null | null | null | Since there is `Dataset.from_list` in the API, we should also add `Dataset.to_list` to be consistent.
Regarding the implementation, we can re-use `Dataset.to_dict`'s code and replace the `to_pydict` calls with `to_pylist`. | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5606/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5606/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5604 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5604/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5604/comments | https://api.github.com/repos/huggingface/datasets/issues/5604/events | https://github.com/huggingface/datasets/issues/5604 | 1,608,304,775 | I_kwDODunzps5f3MiH | 5,604 | Problems with downloading The Pile | {
"login": "sentialx",
"id": 11065386,
"node_id": "MDQ6VXNlcjExMDY1Mzg2",
"avatar_url": "https://avatars.githubusercontent.com/u/11065386?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sentialx",
"html_url": "https://github.com/sentialx",
"followers_url": "https://api.github.com/users/sen... | [] | closed | false | [] | null | [
"Hi! \r\n\r\n\r\nYou can specify `download_config=DownloadConfig(resume_download=True))` in `load_dataset` to resume the download when re-running the code after the timeout error:\r\n```python\r\nfrom datasets import load_dataset, DownloadConfig\r\ndataset = load_dataset('the_pile', split='train', cache_dir='F:\\da... | 2023-03-03 09:52:08 | 2023-10-14 02:15:52 | 2023-03-24 12:44:25 | null | NONE | [] | null | null | null | null | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.
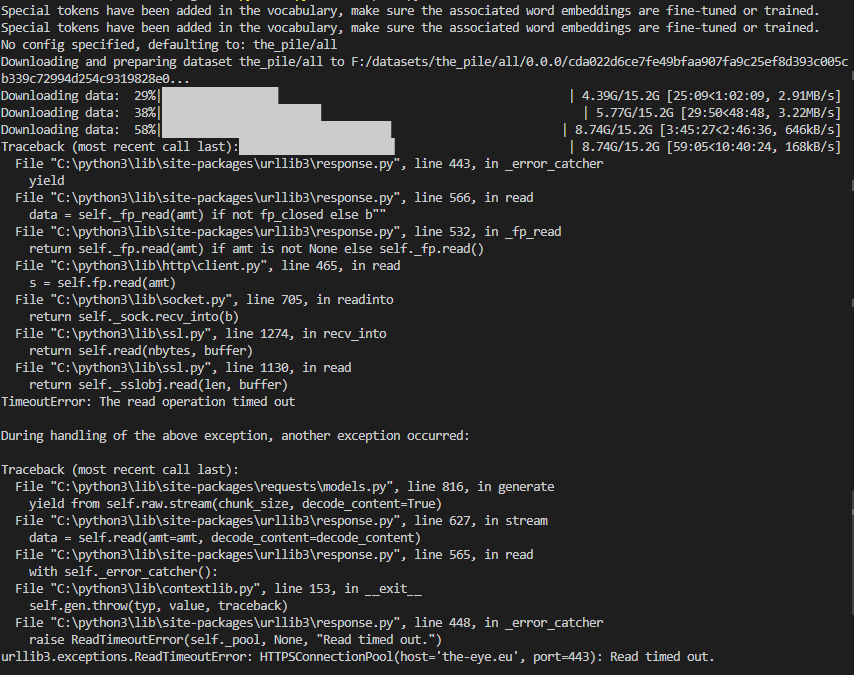
Here are the downloaded files:
`hg_user` but my repo cont... | 2023-03-02 12:08:39 | 2023-03-14 16:55:35 | 2023-03-14 16:55:34 | null | NONE | [] | null | null | null | null | ### Describe the bug
Get `Authorization error` when try to push data into hugginface datasets hub.
### Steps to reproduce the bug
I did all steps in the [tutorial](https://huggingface.co/docs/datasets/share),
1. `huggingface-cli login` with WRITE token
2. `git lfs install`
3. `git clone https://huggingfa... | {
"login": "OleksandrKorovii",
"id": 107404835,
"node_id": "U_kgDOBmbeIw",
"avatar_url": "https://avatars.githubusercontent.com/u/107404835?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/OleksandrKorovii",
"html_url": "https://github.com/OleksandrKorovii",
"followers_url": "https://api.gi... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5601/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5601/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5600 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5600/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5600/comments | https://api.github.com/repos/huggingface/datasets/issues/5600/events | https://github.com/huggingface/datasets/issues/5600 | 1,606,585,596 | I_kwDODunzps5fwoz8 | 5,600 | Dataloader getitem not working for DreamboothDatasets | {
"login": "salahiguiliz",
"id": 76955987,
"node_id": "MDQ6VXNlcjc2OTU1OTg3",
"avatar_url": "https://avatars.githubusercontent.com/u/76955987?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/salahiguiliz",
"html_url": "https://github.com/salahiguiliz",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"Hi! \r\n\r\n> (see example of DreamboothDatasets)\r\n\r\n\r\nCould you please provide a link to it? If you are referring to the example in the `diffusers` repo, your issue is unrelated to `datasets` as that example uses `Dataset` from PyTorch to load data."
] | 2023-03-02 11:00:27 | 2023-03-13 17:59:35 | 2023-03-13 17:59:35 | null | NONE | [] | null | null | null | null | ### Describe the bug
Dataloader getitem is not working as before (see example of [DreamboothDatasets](https://github.com/huggingface/peft/blob/main/examples/lora_dreambooth/train_dreambooth.py#L451C14-L529))
moving Datasets to 2.8.0 solved the issue.
### Steps to reproduce the bug
1- using DreamBoothDataset ... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5600/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5600/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5597 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5597/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5597/comments | https://api.github.com/repos/huggingface/datasets/issues/5597/events | https://github.com/huggingface/datasets/issues/5597 | 1,604,928,721 | I_kwDODunzps5fqUTR | 5,597 | in-place dataset update | {
"login": "speedcell4",
"id": 3585459,
"node_id": "MDQ6VXNlcjM1ODU0NTk=",
"avatar_url": "https://avatars.githubusercontent.com/u/3585459?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/speedcell4",
"html_url": "https://github.com/speedcell4",
"followers_url": "https://api.github.com/users... | [
{
"id": 1935892913,
"node_id": "MDU6TGFiZWwxOTM1ODkyOTEz",
"url": "https://api.github.com/repos/huggingface/datasets/labels/wontfix",
"name": "wontfix",
"color": "ffffff",
"default": true,
"description": "This will not be worked on",
"archived_at": null,
"archived_by": null
}
] | closed | false | [] | null | [
"We won't support in-place modifications since `datasets` is based on the Apache Arrow format which doesn't support in-place modifications.\r\n\r\nIn your case the old dataset is garbage collected pretty quickly so you won't have memory issues.\r\n\r\nNote that datasets loaded from disk (memory mapped) are not load... | 2023-03-01 12:58:18 | 2023-03-02 13:30:41 | 2023-03-02 03:47:00 | null | NONE | [] | null | null | null | null | ### Motivation
For the circumstance that I creat an empty `Dataset` and keep appending new rows into it, I found that it leads to creating a new dataset at each call. It looks quite memory-consuming. I just wonder if there is any more efficient way to do this.
```python
from datasets import Dataset
ds = Datas... | {
"login": "speedcell4",
"id": 3585459,
"node_id": "MDQ6VXNlcjM1ODU0NTk=",
"avatar_url": "https://avatars.githubusercontent.com/u/3585459?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/speedcell4",
"html_url": "https://github.com/speedcell4",
"followers_url": "https://api.github.com/users... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5597/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5597/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5596 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5596/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5596/comments | https://api.github.com/repos/huggingface/datasets/issues/5596/events | https://github.com/huggingface/datasets/issues/5596 | 1,604,919,993 | I_kwDODunzps5fqSK5 | 5,596 | [TypeError: Couldn't cast array of type] Can only load a subset of the dataset | {
"login": "loubnabnl",
"id": 44069155,
"node_id": "MDQ6VXNlcjQ0MDY5MTU1",
"avatar_url": "https://avatars.githubusercontent.com/u/44069155?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/loubnabnl",
"html_url": "https://github.com/loubnabnl",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Apparently some JSON objects have a `\"labels\"` field. Since this field is not present in every object, you must specify all the fields types in the README.md\r\n\r\nEDIT: actually specifying the feature types doesn’t solve the issue, it raises an error because “labels” is missing in the data",
"We've updated t... | 2023-03-01 12:53:08 | 2023-12-05 03:22:00 | 2023-03-02 11:12:11 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm trying to load this [dataset](https://huggingface.co/datasets/bigcode-data/the-stack-gh-issues) which consists of jsonl files and I get the following error:
```
casted_values = _c(array.values, feature[0])
File "/opt/conda/lib/python3.7/site-packages/datasets/table.py", line 1839, in wr... | {
"login": "loubnabnl",
"id": 44069155,
"node_id": "MDQ6VXNlcjQ0MDY5MTU1",
"avatar_url": "https://avatars.githubusercontent.com/u/44069155?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/loubnabnl",
"html_url": "https://github.com/loubnabnl",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5596/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5596/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5594 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5594/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5594/comments | https://api.github.com/repos/huggingface/datasets/issues/5594/events | https://github.com/huggingface/datasets/issues/5594 | 1,603,980,995 | I_kwDODunzps5fms7D | 5,594 | Error while downloading the xtreme udpos dataset | {
"login": "simran-khanuja",
"id": 24687672,
"node_id": "MDQ6VXNlcjI0Njg3Njcy",
"avatar_url": "https://avatars.githubusercontent.com/u/24687672?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/simran-khanuja",
"html_url": "https://github.com/simran-khanuja",
"followers_url": "https://api.gi... | [] | closed | false | [] | null | [
"Hi! I cannot reproduce this error on my machine.\r\n\r\nThe raised error could mean that one of the downloaded files is corrupted. To verify this is not the case, you can run `load_dataset` as follows:\r\n```python\r\ntrain_dataset = load_dataset('xtreme', 'udpos.English', split=\"train\", cache_dir=args.cache_dir... | 2023-02-28 23:40:53 | 2023-11-04 20:45:56 | 2023-07-24 14:22:18 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
I am facing an error while downloading the xtreme udpos dataset using load_dataset. I have datasets 2.10.1 installed
```Downloading and preparing dataset xtreme/udpos.Arabic to /compute/tir-1-18/skhanuja/multilingual_ft/cache/data/xtreme/udpos.Arabic/1.0.0/29f5d57a48779f37ccb75cb8708d1... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5594/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5594/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5586 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5586/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5586/comments | https://api.github.com/repos/huggingface/datasets/issues/5586/events | https://github.com/huggingface/datasets/issues/5586 | 1,602,961,544 | I_kwDODunzps5fi0CI | 5,586 | .sort() is broken when used after .filter(), only in 2.10.0 | {
"login": "MattYoon",
"id": 57797966,
"node_id": "MDQ6VXNlcjU3Nzk3OTY2",
"avatar_url": "https://avatars.githubusercontent.com/u/57797966?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MattYoon",
"html_url": "https://github.com/MattYoon",
"followers_url": "https://api.github.com/users/Mat... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [] | null | [
"Thanks for reporting and thanks @mariosasko for fixing ! We just did a patch release `2.10.1` with the fix"
] | 2023-02-28 12:18:09 | 2023-02-28 18:17:26 | 2023-02-28 17:21:59 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi, thank you for your support!
It seems like the addition of multiple key sort (#5502) in 2.10.0 broke the `.sort()` method.
After filtering a dataset with `.filter()`, the `.sort()` seems to refer to the query_table index of the previous unfiltered dataset, resulting in an IndexError.
... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5586/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5586/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5585 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5585/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5585/comments | https://api.github.com/repos/huggingface/datasets/issues/5585/events | https://github.com/huggingface/datasets/issues/5585 | 1,602,190,030 | I_kwDODunzps5ff3rO | 5,585 | Cache is not transportable | {
"login": "davidgilbertson",
"id": 4443482,
"node_id": "MDQ6VXNlcjQ0NDM0ODI=",
"avatar_url": "https://avatars.githubusercontent.com/u/4443482?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/davidgilbertson",
"html_url": "https://github.com/davidgilbertson",
"followers_url": "https://api.g... | [] | closed | false | [] | null | [
"Hi ! No the cache is not transportable in general. It will work on a shared filesystem if you use the same python environment, but not across machines/os/environments.\r\n\r\nIn particular, reloading cached datasets does work, but reloading cached processed datasets (e.g. from `map`) may not work. This is because ... | 2023-02-28 00:53:06 | 2023-02-28 21:26:52 | 2023-02-28 21:26:52 | null | NONE | [] | null | null | null | null | ### Describe the bug
I would like to share cache between two machines (a Windows host machine and a WSL instance).
I run most my code in WSL. I have just run out of space in the virtual drive. Rather than expand the drive size, I plan to move to cache to the host Windows machine, thereby sharing the downloads.
I... | {
"login": "davidgilbertson",
"id": 4443482,
"node_id": "MDQ6VXNlcjQ0NDM0ODI=",
"avatar_url": "https://avatars.githubusercontent.com/u/4443482?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/davidgilbertson",
"html_url": "https://github.com/davidgilbertson",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5585/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5585/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5584 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5584/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5584/comments | https://api.github.com/repos/huggingface/datasets/issues/5584/events | https://github.com/huggingface/datasets/issues/5584 | 1,601,821,808 | I_kwDODunzps5fedxw | 5,584 | Unable to load coyo700M dataset | {
"login": "manuaero",
"id": 3059998,
"node_id": "MDQ6VXNlcjMwNTk5OTg=",
"avatar_url": "https://avatars.githubusercontent.com/u/3059998?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/manuaero",
"html_url": "https://github.com/manuaero",
"followers_url": "https://api.github.com/users/manua... | [] | closed | false | [] | null | [
"Hi @manuaero \r\n\r\nThank you for your interest in the COYO dataset.\r\n\r\nOur dataset provides the img-url and alt-text in the form of a parquet, so to utilize the coyo dataset you will need to download it directly.\r\n\r\nWe provide a [guide](https://github.com/kakaobrain/coyo-dataset/blob/main/download/README... | 2023-02-27 19:35:03 | 2023-02-28 07:27:59 | 2023-02-28 07:27:58 | null | NONE | [] | null | null | null | null | ### Describe the bug
Seeing this error when downloading https://huggingface.co/datasets/kakaobrain/coyo-700m:
```ArrowInvalid: Parquet magic bytes not found in footer. Either the file is corrupted or this is not a parquet file.```
Full stack trace
```Downloading and preparing dataset parquet/kakaobrain--coy... | {
"login": "manuaero",
"id": 3059998,
"node_id": "MDQ6VXNlcjMwNTk5OTg=",
"avatar_url": "https://avatars.githubusercontent.com/u/3059998?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/manuaero",
"html_url": "https://github.com/manuaero",
"followers_url": "https://api.github.com/users/manua... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5584/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5584/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5581 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5581/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5581/comments | https://api.github.com/repos/huggingface/datasets/issues/5581/events | https://github.com/huggingface/datasets/issues/5581 | 1,600,675,489 | I_kwDODunzps5faF6h | 5,581 | [DOC] Mistaken docs on set_format | {
"login": "NightMachinery",
"id": 36224762,
"node_id": "MDQ6VXNlcjM2MjI0NzYy",
"avatar_url": "https://avatars.githubusercontent.com/u/36224762?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NightMachinery",
"html_url": "https://github.com/NightMachinery",
"followers_url": "https://api.gi... | [
{
"id": 1935892877,
"node_id": "MDU6TGFiZWwxOTM1ODkyODc3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/good%20first%20issue",
"name": "good first issue",
"color": "7057ff",
"default": true,
"description": "Good for newcomers",
"archived_at": null,
"archived_b... | closed | false | [] | null | [
"Thanks for reporting!"
] | 2023-02-27 08:03:09 | 2023-02-28 19:19:17 | 2023-02-28 19:19:17 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
https://huggingface.co/docs/datasets/v2.10.0/en/package_reference/main_classes#datasets.Dataset.set_format
<img width="700" alt="image" src="https://user-images.githubusercontent.com/36224762/221506973-ae2e3991-60a7-4d4e-99f8-965c6eb61e59.png">
While actually running it will result in:
<img w... | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5581/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5581/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5577 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5577/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5577/comments | https://api.github.com/repos/huggingface/datasets/issues/5577/events | https://github.com/huggingface/datasets/issues/5577 | 1,598,587,665 | I_kwDODunzps5fSIMR | 5,577 | Cannot load `the_pile_openwebtext2` | {
"login": "wjfwzzc",
"id": 5126316,
"node_id": "MDQ6VXNlcjUxMjYzMTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/5126316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/wjfwzzc",
"html_url": "https://github.com/wjfwzzc",
"followers_url": "https://api.github.com/users/wjfwzzc/... | [] | closed | false | [] | null | [
"Hi! I've merged a PR to use `int32` instead of `int8` for `reddit_scores`, so it should work now.\r\n\r\n"
] | 2023-02-24 13:01:48 | 2023-02-24 14:01:09 | 2023-02-24 14:01:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
I met the same bug mentioned in #3053 which is never fixed. Because several `reddit_scores` are larger than `int8` even `int16`. https://huggingface.co/datasets/the_pile_openwebtext2/blob/main/the_pile_openwebtext2.py#L62
### Steps to reproduce the bug
```python3
from datasets import load... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5577/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5577/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5576 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5576/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5576/comments | https://api.github.com/repos/huggingface/datasets/issues/5576/events | https://github.com/huggingface/datasets/issues/5576 | 1,598,582,744 | I_kwDODunzps5fSG_Y | 5,576 | I was getting a similar error `pyarrow.lib.ArrowInvalid: Integer value 528 not in range: -128 to 127` - AFAICT, this is because the type specified for `reddit_scores` is `datasets.Sequence(datasets.Value("int8"))`, but the actual values can be well outside the max range for 8-bit integers. | {
"login": "wjfwzzc",
"id": 5126316,
"node_id": "MDQ6VXNlcjUxMjYzMTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/5126316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/wjfwzzc",
"html_url": "https://github.com/wjfwzzc",
"followers_url": "https://api.github.com/users/wjfwzzc/... | [] | closed | false | [] | null | [
"Duplicated issue."
] | 2023-02-24 12:57:49 | 2023-02-24 12:58:31 | 2023-02-24 12:58:18 | null | NONE | [] | null | null | null | null | I was getting a similar error `pyarrow.lib.ArrowInvalid: Integer value 528 not in range: -128 to 127` - AFAICT, this is because the type specified for `reddit_scores` is `datasets.Sequence(datasets.Value("int8"))`, but the actual values can be well outside the max range for 8-bit integers.
I worked aro... | {
"login": "wjfwzzc",
"id": 5126316,
"node_id": "MDQ6VXNlcjUxMjYzMTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/5126316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/wjfwzzc",
"html_url": "https://github.com/wjfwzzc",
"followers_url": "https://api.github.com/users/wjfwzzc/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5576/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5576/timeline | null | not_planned | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5575 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5575/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5575/comments | https://api.github.com/repos/huggingface/datasets/issues/5575/events | https://github.com/huggingface/datasets/issues/5575 | 1,598,396,552 | I_kwDODunzps5fRZiI | 5,575 | Metadata for each column | {
"login": "parsa-ra",
"id": 11356471,
"node_id": "MDQ6VXNlcjExMzU2NDcx",
"avatar_url": "https://avatars.githubusercontent.com/u/11356471?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/parsa-ra",
"html_url": "https://github.com/parsa-ra",
"followers_url": "https://api.github.com/users/par... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | {
"url": "https://api.github.com/repos/huggingface/datasets/milestones/10",
"html_url": "https://github.com/huggingface/datasets/milestone/10",
"labels_url": "https://api.github.com/repos/huggingface/datasets/milestones/10/labels",
"id": 9038583,
"node_id": "MI_kwDODunzps4Aier3",
"number": 10,
"title": "3... | [
"Hi! Indeed it would be useful to support this. PyArrow natively supports schema-level and column-level metadata, so implementing this should be straightforward. The API I have in mind would work as follows:\r\n```python\r\ncol_feature = Value(\"string\", metadata=\"Some column-level metadata\")\r\n\r\nfeatures = F... | 2023-02-24 10:53:44 | 2024-01-05 21:48:35 | null | null | NONE | [] | null | null | null | null | ### Feature request
Being able to put some metadata for each column as a string or any other type.
### Motivation
I will bring the motivation by an example, lets say we are experimenting with embedding produced by some image encoder network, and we want to iterate through a couple of preprocessing and see which on... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5575/reactions",
"total_count": 11,
"+1": 11,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5575/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5574 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5574/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5574/comments | https://api.github.com/repos/huggingface/datasets/issues/5574/events | https://github.com/huggingface/datasets/issues/5574 | 1,598,104,691 | I_kwDODunzps5fQSRz | 5,574 | c4 dataset streaming fails with `FileNotFoundError` | {
"login": "krasserm",
"id": 202907,
"node_id": "MDQ6VXNlcjIwMjkwNw==",
"avatar_url": "https://avatars.githubusercontent.com/u/202907?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/krasserm",
"html_url": "https://github.com/krasserm",
"followers_url": "https://api.github.com/users/krasser... | [] | closed | false | [] | null | [
"Also encountering this issue for every dataset I try to stream! Installed datasets from main:\r\n```\r\n- `datasets` version: 2.10.1.dev0\r\n- Platform: macOS-13.1-arm64-arm-64bit\r\n- Python version: 3.9.13\r\n- PyArrow version: 10.0.1\r\n- Pandas version: 1.5.2\r\n```\r\n\r\nRepro:\r\n```python\r\nfrom datasets ... | 2023-02-24 07:57:32 | 2023-12-18 07:32:32 | 2023-02-27 04:03:38 | null | NONE | [] | null | null | null | null | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | {
"login": "krasserm",
"id": 202907,
"node_id": "MDQ6VXNlcjIwMjkwNw==",
"avatar_url": "https://avatars.githubusercontent.com/u/202907?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/krasserm",
"html_url": "https://github.com/krasserm",
"followers_url": "https://api.github.com/users/krasser... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5574/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5574/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5572 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5572/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5572/comments | https://api.github.com/repos/huggingface/datasets/issues/5572/events | https://github.com/huggingface/datasets/issues/5572 | 1,597,257,624 | I_kwDODunzps5fNDeY | 5,572 | Datasets 2.10.0 does not reuse the dataset cache | {
"login": "lsb",
"id": 45281,
"node_id": "MDQ6VXNlcjQ1Mjgx",
"avatar_url": "https://avatars.githubusercontent.com/u/45281?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lsb",
"html_url": "https://github.com/lsb",
"followers_url": "https://api.github.com/users/lsb/followers",
"following... | [] | closed | false | [] | null | [] | 2023-02-23 17:28:11 | 2023-02-23 18:03:55 | 2023-02-23 18:03:55 | null | NONE | [] | null | null | null | null | ### Describe the bug
download_mode="reuse_dataset_if_exists" will always consider that a dataset doesn't exist.
Specifically, upon losing an internet connection trying to load a dataset for a second time in ten seconds, a connection error results, showing a breakpoint of:
```
File ~/jupyterlab/.direnv/python-... | {
"login": "lsb",
"id": 45281,
"node_id": "MDQ6VXNlcjQ1Mjgx",
"avatar_url": "https://avatars.githubusercontent.com/u/45281?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lsb",
"html_url": "https://github.com/lsb",
"followers_url": "https://api.github.com/users/lsb/followers",
"following... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5572/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5572/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5571 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5571/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5571/comments | https://api.github.com/repos/huggingface/datasets/issues/5571/events | https://github.com/huggingface/datasets/issues/5571 | 1,597,198,953 | I_kwDODunzps5fM1Jp | 5,571 | load_dataset fails for JSON in windows | {
"login": "abinashsahu",
"id": 11876897,
"node_id": "MDQ6VXNlcjExODc2ODk3",
"avatar_url": "https://avatars.githubusercontent.com/u/11876897?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/abinashsahu",
"html_url": "https://github.com/abinashsahu",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"Hi! \r\n\r\nYou need to pass an input json file explicitly as `data_files` to `load_dataset` to avoid this error:\r\n```python\r\n ds = load_dataset(\"json\", data_files=args.input_json)\r\n```\r\n\r\n",
"Thanks it worked!"
] | 2023-02-23 16:50:11 | 2023-02-24 13:21:47 | 2023-02-24 13:21:47 | null | NONE | [] | null | null | null | null | ### Describe the bug
Steps:
1. Created a dataset in a Linux VM and created a small sample using dataset.to_json() method.
2. Downloaded the JSON file to my local Windows machine for working and saved in say - r"C:\Users\name\file.json"
3. I am reading the file in my local PyCharm - the location of python file is di... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5571/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5571/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5570 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5570/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5570/comments | https://api.github.com/repos/huggingface/datasets/issues/5570/events | https://github.com/huggingface/datasets/issues/5570 | 1,597,190,926 | I_kwDODunzps5fMzMO | 5,570 | load_dataset gives FileNotFoundError on imagenet-1k if license is not accepted on the hub | {
"login": "buoi",
"id": 38630200,
"node_id": "MDQ6VXNlcjM4NjMwMjAw",
"avatar_url": "https://avatars.githubusercontent.com/u/38630200?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/buoi",
"html_url": "https://github.com/buoi",
"followers_url": "https://api.github.com/users/buoi/followers"... | [] | closed | false | [] | null | [
"Hi, thanks for the feedback! Would it help to add a tip or note saying the dataset is gated and you need to accept the license before downloading it?",
"The error is now more informative:\r\n```\r\nFileNotFoundError: Couldn't find a dataset script at /content/imagenet-1k/imagenet-1k.py or any data file in the sa... | 2023-02-23 16:44:32 | 2023-07-24 15:18:50 | 2023-07-24 15:18:50 | null | NONE | [] | null | null | null | null | ### Describe the bug
When calling ```load_dataset('imagenet-1k')``` FileNotFoundError is raised, if not logged in and if logged in with huggingface-cli but not having accepted the licence on the hub. There is no error once accepting.
### Steps to reproduce the bug
```
from datasets import load_dataset
imagenet =... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5570/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5570/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5568 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5568/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5568/comments | https://api.github.com/repos/huggingface/datasets/issues/5568/events | https://github.com/huggingface/datasets/issues/5568 | 1,596,900,532 | I_kwDODunzps5fLsS0 | 5,568 | dataset.to_iterable_dataset() loses useful info like dataset features | {
"login": "bruno-hays",
"id": 48770768,
"node_id": "MDQ6VXNlcjQ4NzcwNzY4",
"avatar_url": "https://avatars.githubusercontent.com/u/48770768?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bruno-hays",
"html_url": "https://github.com/bruno-hays",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "bruno-hays",
"id": 48770768,
"node_id": "MDQ6VXNlcjQ4NzcwNzY4",
"avatar_url": "https://avatars.githubusercontent.com/u/48770768?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bruno-hays",
"html_url": "https://github.com/bruno-hays",
"followers_url": "https:... | null | [
"Hi ! Oh good catch. I think the features should be passed to `IterableDataset.from_generator()` in `to_iterable_dataset()` indeed.\r\n\r\nSetting this as a good first issue if someone would like to contribute, otherwise we can take care of it :)",
"#self-assign",
"seems like the feature parameter is missing fr... | 2023-02-23 13:45:33 | 2023-02-24 13:22:36 | 2023-02-24 13:22:36 | {
"login": "bruno-hays",
"id": 48770768,
"node_id": "MDQ6VXNlcjQ4NzcwNzY4",
"avatar_url": "https://avatars.githubusercontent.com/u/48770768?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bruno-hays",
"html_url": "https://github.com/bruno-hays",
"followers_url": "https://api.github.com/use... | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
Hello,
I like the new `to_iterable_dataset` feature but I noticed something that seems to be missing.
When using `to_iterable_dataset` to transform your map style dataset into iterable dataset, you lose valuable metadata like the features.
These metadata are useful if you want to interleav... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5568/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5568/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5566 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5566/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5566/comments | https://api.github.com/repos/huggingface/datasets/issues/5566/events | https://github.com/huggingface/datasets/issues/5566 | 1,595,916,674 | I_kwDODunzps5fH8GC | 5,566 | Directly reading parquet files in a s3 bucket from the load_dataset method | {
"login": "shamanez",
"id": 16892570,
"node_id": "MDQ6VXNlcjE2ODkyNTcw",
"avatar_url": "https://avatars.githubusercontent.com/u/16892570?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shamanez",
"html_url": "https://github.com/shamanez",
"followers_url": "https://api.github.com/users/sha... | [
{
"id": 1935892865,
"node_id": "MDU6TGFiZWwxOTM1ODkyODY1",
"url": "https://api.github.com/repos/huggingface/datasets/labels/duplicate",
"name": "duplicate",
"color": "cfd3d7",
"default": true,
"description": "This issue or pull request already exists",
"archived_at": null,
"archi... | open | false | [] | null | [
"Hi ! I think is in the scope of this other issue: to https://github.com/huggingface/datasets/issues/5281 "
] | 2023-02-22 22:13:40 | 2023-02-23 11:03:29 | null | null | NONE | [] | null | null | null | null | ### Feature request
Right now, we have to read the get the parquet file to the local storage. So having ability to read given the bucket directly address would be benificial
### Motivation
In a production set up, this feature can help us a lot. So we do not need move training datafiles in between storage.
### Yo... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5566/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5566/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5555 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5555/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5555/comments | https://api.github.com/repos/huggingface/datasets/issues/5555/events | https://github.com/huggingface/datasets/issues/5555 | 1,592,469,938 | I_kwDODunzps5e6ymy | 5,555 | `.shuffle` throwing error `ValueError: Protocol not known: parent` | {
"login": "prabhakar267",
"id": 10768588,
"node_id": "MDQ6VXNlcjEwNzY4NTg4",
"avatar_url": "https://avatars.githubusercontent.com/u/10768588?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/prabhakar267",
"html_url": "https://github.com/prabhakar267",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [
"Hi ! The indices mapping is written in the same cachedirectory as your dataset.\r\n\r\nCan you run this to show your current cache directory ?\r\n```python\r\nprint(train_dataset.cache_files)\r\n```",
"```\r\n[{'filename': '.../train/dataset.arrow'}, {'filename': '.../train/dataset.arrow'}]\r\n```\r\n\r\nThese a... | 2023-02-20 21:33:45 | 2023-02-27 09:23:34 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
```
---------------------------------------------------------------------------
ValueError Traceback (most recent call last)
Cell In [16], line 1
----> 1 train_dataset = train_dataset.shuffle()
File /opt/conda/envs/pytorch/lib/python3.9/site-packages/dataset... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5555/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5555/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5548 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5548/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5548/comments | https://api.github.com/repos/huggingface/datasets/issues/5548/events | https://github.com/huggingface/datasets/issues/5548 | 1,590,835,479 | I_kwDODunzps5e0jkX | 5,548 | Apply flake8-comprehensions to codebase | {
"login": "Skylion007",
"id": 2053727,
"node_id": "MDQ6VXNlcjIwNTM3Mjc=",
"avatar_url": "https://avatars.githubusercontent.com/u/2053727?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Skylion007",
"html_url": "https://github.com/Skylion007",
"followers_url": "https://api.github.com/users... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [] | 2023-02-19 20:05:38 | 2023-02-23 13:59:41 | 2023-02-23 13:59:41 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Apply ruff flake8 comprehension checks to codebase.
### Motivation
This should strictly improve the performance / readability of the codebase by removing unnecessary iteration, function calls, etc. This should generate better Python bytecode which should strictly improve performance.
I alread... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5548/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5548/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5546 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5546/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5546/comments | https://api.github.com/repos/huggingface/datasets/issues/5546/events | https://github.com/huggingface/datasets/issues/5546 | 1,590,346,349 | I_kwDODunzps5eysJt | 5,546 | Downloaded datasets do not cache at $HF_HOME | {
"login": "ErfanMoosaviMonazzah",
"id": 79091831,
"node_id": "MDQ6VXNlcjc5MDkxODMx",
"avatar_url": "https://avatars.githubusercontent.com/u/79091831?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ErfanMoosaviMonazzah",
"html_url": "https://github.com/ErfanMoosaviMonazzah",
"followers_url... | [] | closed | false | [] | null | [
"Hi ! Can you make sure you set `HF_HOME` before importing `datasets` ?\r\n\r\nThen you can print\r\n```python\r\nprint(datasets.config.HF_CACHE_HOME)\r\nprint(datasets.config.HF_DATASETS_CACHE)\r\n```"
] | 2023-02-18 13:30:35 | 2023-07-24 14:22:43 | 2023-07-24 14:22:43 | null | NONE | [] | null | null | null | null | ### Describe the bug
In the huggingface course (https://huggingface.co/course/chapter3/2?fw=pt) it said that if we set HF_HOME, downloaded datasets would be cached at specified address but it does not. downloaded models from checkpoint names are downloaded and cached at HF_HOME but this is not the case for datasets, t... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5546/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5546/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5543 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5543/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5543/comments | https://api.github.com/repos/huggingface/datasets/issues/5543/events | https://github.com/huggingface/datasets/issues/5543 | 1,588,951,379 | I_kwDODunzps5etXlT | 5,543 | the pile datasets url seems to change back | {
"login": "wjfwzzc",
"id": 5126316,
"node_id": "MDQ6VXNlcjUxMjYzMTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/5126316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/wjfwzzc",
"html_url": "https://github.com/wjfwzzc",
"followers_url": "https://api.github.com/users/wjfwzzc/... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [
"Thanks for reporting, @wjfwzzc.\r\n\r\nI am transferring this issue to the corresponding dataset on the Hub: https://huggingface.co/datasets/bookcorpusopen/discussions/1",
"Thank you. All fixes are done:\r\n- [x] https://huggingface.co/datasets/bookcorpusopen/discussions/2\r\n- [x] https://huggingface.co/dataset... | 2023-02-17 08:40:11 | 2023-02-21 06:37:00 | 2023-02-20 08:41:33 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | NONE | [] | null | null | null | null | ### Describe the bug
in #3627, the host url of the pile dataset became `https://mystic.the-eye.eu`. Now the new url is broken, but `https://the-eye.eu` seems to work again.
### Steps to reproduce the bug
```python3
from datasets import load_dataset
dataset = load_dataset("bookcorpusopen")
```
shows
```python3
... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5543/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5543/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5541 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5541/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5541/comments | https://api.github.com/repos/huggingface/datasets/issues/5541/events | https://github.com/huggingface/datasets/issues/5541 | 1,588,633,555 | I_kwDODunzps5esJ_T | 5,541 | Flattening indices in selected datasets is extremely inefficient | {
"login": "marioga",
"id": 6591505,
"node_id": "MDQ6VXNlcjY1OTE1MDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/6591505?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/marioga",
"html_url": "https://github.com/marioga",
"followers_url": "https://api.github.com/users/marioga/... | [] | closed | false | [] | null | [
"Running the script above on the branch https://github.com/huggingface/datasets/pull/5542 results in the expected behaviour:\r\n```\r\nNum chunks for original ds: 1\r\nOriginal ds save/load\r\nsave_to_disk -- RAM memory used: 0.671875 MB -- Total time: 0.255265 s\r\nload_from_disk -- RAM memory used: 42.796875 MB -... | 2023-02-17 01:52:24 | 2023-02-22 13:15:20 | 2023-02-17 11:12:33 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
If we perform a `select` (or `shuffle`, `train_test_split`, etc.) operation on a dataset , we end up with a dataset with an `indices_table`. Currently, flattening such dataset consumes a lot of memory and the resulting flat dataset contains ChunkedArrays with as many chunks as there are rows. Thi... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5541/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5541/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5539 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5539/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5539/comments | https://api.github.com/repos/huggingface/datasets/issues/5539/events | https://github.com/huggingface/datasets/issues/5539 | 1,587,970,083 | I_kwDODunzps5epoAj | 5,539 | IndexError: invalid index of a 0-dim tensor. Use `tensor.item()` in Python or `tensor.item<T>()` in C++ to convert a 0-dim tensor to a number | {
"login": "aalbersk",
"id": 41912135,
"node_id": "MDQ6VXNlcjQxOTEyMTM1",
"avatar_url": "https://avatars.githubusercontent.com/u/41912135?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/aalbersk",
"html_url": "https://github.com/aalbersk",
"followers_url": "https://api.github.com/users/aal... | [
{
"id": 1935892877,
"node_id": "MDU6TGFiZWwxOTM1ODkyODc3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/good%20first%20issue",
"name": "good first issue",
"color": "7057ff",
"default": true,
"description": "Good for newcomers",
"archived_at": null,
"archived_b... | closed | false | [] | null | [
"Hi! The `set_transform` does not apply a custom formatting transform on a single example but the entire batch, so the fixed version of your transform would look as follows:\r\n```python\r\nfrom datasets import load_dataset\r\nimport torch\r\n\r\ndataset = load_dataset(\"lambdalabs/pokemon-blip-captions\", split='t... | 2023-02-16 16:08:51 | 2023-02-22 10:30:30 | 2023-02-21 13:03:57 | null | NONE | [] | null | null | null | null | ### Describe the bug
When dataset contains a 0-dim tensor, formatting.py raises a following error and fails.
```bash
Traceback (most recent call last):
File "<path>/lib/python3.8/site-packages/datasets/formatting/formatting.py", line 501, in format_row
return _unnest(formatted_batch)
File "<path>/lib/py... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5539/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5539/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5538 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5538/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5538/comments | https://api.github.com/repos/huggingface/datasets/issues/5538/events | https://github.com/huggingface/datasets/issues/5538 | 1,587,732,596 | I_kwDODunzps5eouB0 | 5,538 | load_dataset in seaborn is not working for me. getting this error. | {
"login": "reemaranibarik",
"id": 125575109,
"node_id": "U_kgDOB3wfxQ",
"avatar_url": "https://avatars.githubusercontent.com/u/125575109?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/reemaranibarik",
"html_url": "https://github.com/reemaranibarik",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"Hi! `seaborn`'s `load_dataset` pulls datasets from [here](https://github.com/mwaskom/seaborn-data) and not from our Hub, so this issue is not related to our library in any way and should be reported in their repo instead."
] | 2023-02-16 14:01:58 | 2023-02-16 14:44:36 | 2023-02-16 14:44:36 | null | NONE | [] | null | null | null | null | TimeoutError Traceback (most recent call last)
~\anaconda3\lib\urllib\request.py in do_open(self, http_class, req, **http_conn_args)
1345 try:
-> 1346 h.request(req.get_method(), req.selector, req.data, headers,
1347 encode_chu... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5538/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5538/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5537 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5537/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5537/comments | https://api.github.com/repos/huggingface/datasets/issues/5537/events | https://github.com/huggingface/datasets/issues/5537 | 1,587,567,464 | I_kwDODunzps5eoFto | 5,537 | Increase speed of data files resolution | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "semajyllek",
"id": 35013374,
"node_id": "MDQ6VXNlcjM1MDEzMzc0",
"avatar_url": "https://avatars.githubusercontent.com/u/35013374?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/semajyllek",
"html_url": "https://github.com/semajyllek",
"followers_url": "https:... | null | [
"#self-assign",
"You were right, if `self.dir_cache` is not None in glob, it is exactly the same as what is returned by find, at least for all the tests we have, and some extended evaluation I did across a random sample of about 1000 datasets. \r\n\r\nThanks for the nice hints, and let me know if this is not exac... | 2023-02-16 12:11:45 | 2023-12-15 13:12:31 | 2023-12-15 13:12:31 | {
"login": "semajyllek",
"id": 35013374,
"node_id": "MDQ6VXNlcjM1MDEzMzc0",
"avatar_url": "https://avatars.githubusercontent.com/u/35013374?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/semajyllek",
"html_url": "https://github.com/semajyllek",
"followers_url": "https://api.github.com/use... | MEMBER | [] | null | null | null | null | Certain datasets like `bigcode/the-stack-dedup` have so many files that loading them takes forever right from the data files resolution step.
`datasets` uses file patterns to check the structure of the repository but it takes too much time to iterate over and over again on all the data files.
This comes from `res... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5537/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5537/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5536 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5536/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5536/comments | https://api.github.com/repos/huggingface/datasets/issues/5536/events | https://github.com/huggingface/datasets/issues/5536 | 1,586,930,643 | I_kwDODunzps5elqPT | 5,536 | Failure to hash function when using .map() | {
"login": "venzen",
"id": 6916056,
"node_id": "MDQ6VXNlcjY5MTYwNTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/6916056?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/venzen",
"html_url": "https://github.com/venzen",
"followers_url": "https://api.github.com/users/venzen/foll... | [] | closed | false | [] | null | [
"Hi ! `enc` is not hashable:\r\n```python\r\nimport tiktoken\r\nfrom datasets.fingerprint import Hasher\r\n\r\nenc = tiktoken.get_encoding(\"gpt2\")\r\nHasher.hash(enc)\r\n# raises TypeError: cannot pickle 'builtins.CoreBPE' object\r\n```\r\nIt happens because it's not picklable, and because of that it's not possib... | 2023-02-16 03:12:07 | 2023-09-08 21:06:01 | 2023-02-16 14:56:41 | null | NONE | [] | null | null | null | null | ### Describe the bug
_Parameter 'function'=<function process at 0x7f1ec4388af0> of the transform datasets.arrow_dataset.Dataset.\_map_single couldn't be hashed properly, a random hash was used instead. Make sure your transforms and parameters are serializable with pickle or dill for the dataset fingerprinting and ca... | {
"login": "venzen",
"id": 6916056,
"node_id": "MDQ6VXNlcjY5MTYwNTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/6916056?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/venzen",
"html_url": "https://github.com/venzen",
"followers_url": "https://api.github.com/users/venzen/foll... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5536/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5536/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5534 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5534/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5534/comments | https://api.github.com/repos/huggingface/datasets/issues/5534/events | https://github.com/huggingface/datasets/issues/5534 | 1,586,177,862 | I_kwDODunzps5eiydG | 5,534 | map() breaks at certain dataset size when using Array3D | {
"login": "ArneBinder",
"id": 3375489,
"node_id": "MDQ6VXNlcjMzNzU0ODk=",
"avatar_url": "https://avatars.githubusercontent.com/u/3375489?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ArneBinder",
"html_url": "https://github.com/ArneBinder",
"followers_url": "https://api.github.com/users... | [] | open | false | [] | null | [
"Hi! This code works for me locally or in Colab. What's the output of `python -c \"import pyarrow as pa; print(pa.__version__)\"` when you run it inside your environment?",
"Thanks for looking into this!\r\nThe output of `python -c \"import pyarrow as pa; print(pa.__version__)\"` is:\r\n```\r\n11.0.0\r\n```\r\n\... | 2023-02-15 16:34:25 | 2023-03-03 16:31:33 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
`map()` magically breaks when using a `Array3D` feature and mapping it. I created a very simple dummy dataset (see below). When filtering it down to 95 elements I can apply map, but it breaks when filtering it down to just 96 entries with the following exception:
```
Traceback (most recent cal... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5534/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5534/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5532 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5532/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5532/comments | https://api.github.com/repos/huggingface/datasets/issues/5532/events | https://github.com/huggingface/datasets/issues/5532 | 1,584,505,128 | I_kwDODunzps5ecaEo | 5,532 | train_test_split in arrow_dataset does not ensure to keep single classes in test set | {
"login": "Ulipenitz",
"id": 37191008,
"node_id": "MDQ6VXNlcjM3MTkxMDA4",
"avatar_url": "https://avatars.githubusercontent.com/u/37191008?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Ulipenitz",
"html_url": "https://github.com/Ulipenitz",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Hi! You can get this behavior by specifying `stratify_by_column=\"label\"` in `train_test_split`.\r\n\r\nThis is the full example:\r\n```python\r\nimport numpy as np\r\nfrom datasets import Dataset, ClassLabel\r\n\r\ndata = [\r\n {'label': 0, 'text': \"example1\"},\r\n {'label': 1, 'text': \"example2\"},\r\n... | 2023-02-14 16:52:29 | 2023-02-15 16:09:19 | 2023-02-15 16:09:19 | null | NONE | [] | null | null | null | null | ### Describe the bug
When I have a dataset with very few (e.g. 1) examples per class and I call the train_test_split function on it, sometimes the single class will be in the test set. thus will never be considered for training.
### Steps to reproduce the bug
```
import numpy as np
from datasets import Dataset
... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5532/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5532/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5531 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5531/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5531/comments | https://api.github.com/repos/huggingface/datasets/issues/5531/events | https://github.com/huggingface/datasets/issues/5531 | 1,584,387,276 | I_kwDODunzps5eb9TM | 5,531 | Invalid Arrow data from JSONL | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | open | false | [] | null | [
"Can I bump this? I am still running into the same crash, or a similar crash, a few years later:\n\n```\n>>> from datasets import load_dataset\n>>> ds = load_dataset('oscar-corpus/community-oscar', data_files='data/2024-38/sd_meta/*.jsonl.zst', split='train', streaming=False)\ndata/2024-38/sd_meta/sd_meta.jsonl.zs... | 2023-02-14 15:39:49 | 2026-09-11 12:05:08 | null | null | MEMBER | [] | null | null | null | null | This code fails:
```python
from datasets import Dataset
ds = Dataset.from_json(path_to_file)
ds.data.validate()
```
raises
```python
ArrowInvalid: Column 2: In chunk 1: Invalid: Struct child array #3 invalid: Invalid: Length spanned by list offsets (4064) larger than values array (length 4063)
```
This ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5531/reactions",
"total_count": 2,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 2,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5531/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5525 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5525/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5525/comments | https://api.github.com/repos/huggingface/datasets/issues/5525/events | https://github.com/huggingface/datasets/issues/5525 | 1,580,342,729 | I_kwDODunzps5eMh3J | 5,525 | TypeError: Couldn't cast array of type string to null | {
"login": "TJ-Solergibert",
"id": 74564958,
"node_id": "MDQ6VXNlcjc0NTY0OTU4",
"avatar_url": "https://avatars.githubusercontent.com/u/74564958?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TJ-Solergibert",
"html_url": "https://github.com/TJ-Solergibert",
"followers_url": "https://api.gi... | [] | closed | false | [] | null | [
"Thanks for reporting, @TJ-Solergibert.\r\n\r\nWe cannot access your Colab notebook: `There was an error loading this notebook. Ensure that the file is accessible and try again.`\r\nCould you please make it publicly accessible?\r\n",
"I swear it's public, I've checked the settings and I've been able to open it in... | 2023-02-10 21:12:36 | 2023-02-14 17:41:08 | 2023-02-14 09:35:49 | null | NONE | [] | null | null | null | null | ### Describe the bug
Processing a dataset I alredy uploaded to the Hub (https://huggingface.co/datasets/tj-solergibert/Europarl-ST) I found that for some splits and some languages (test split, source_lang = "nl") after applying a map function I get the mentioned error.
I alredy tried reseting the shorter strings... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5525/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5525/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5523 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5523/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5523/comments | https://api.github.com/repos/huggingface/datasets/issues/5523/events | https://github.com/huggingface/datasets/issues/5523 | 1,580,193,015 | I_kwDODunzps5eL9T3 | 5,523 | Checking that split name is correct happens only after the data is downloaded | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | open | false | [
{
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "... | null | [
"#self-assign"
] | 2023-02-10 19:13:03 | 2026-05-27 01:52:40 | null | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
Verification of split names (=indexing data by split) happens after downloading the data. So when the split name is incorrect, users learn about that only after the data is fully downloaded, for large datasets it might take a lot of time.
### Steps to reproduce the bug
Load any dataset with rand... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5523/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5523/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5520 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5520/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5520/comments | https://api.github.com/repos/huggingface/datasets/issues/5520/events | https://github.com/huggingface/datasets/issues/5520 | 1,578,417,074 | I_kwDODunzps5eFLuy | 5,520 | ClassLabel.cast_storage raises TypeError when called on an empty IntegerArray | {
"login": "marioga",
"id": 6591505,
"node_id": "MDQ6VXNlcjY1OTE1MDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/6591505?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/marioga",
"html_url": "https://github.com/marioga",
"followers_url": "https://api.github.com/users/marioga/... | [] | closed | false | [] | null | [] | 2023-02-09 18:46:52 | 2023-02-12 11:17:18 | 2023-02-12 11:17:18 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
`ClassLabel.cast_storage` raises `TypeError` when called on an empty `IntegerArray`.
### Steps to reproduce the bug
Minimal steps:
```python
import pyarrow as pa
from datasets import ClassLabel
ClassLabel(names=['foo', 'bar']).cast_storage(pa.array([], pa.int64()))
```
In practice, thi... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5520/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5520/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5517 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5517/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5517/comments | https://api.github.com/repos/huggingface/datasets/issues/5517/events | https://github.com/huggingface/datasets/issues/5517 | 1,577,976,608 | I_kwDODunzps5eDgMg | 5,517 | `with_format("numpy")` silently downcasts float64 to float32 features | {
"login": "ernestum",
"id": 1250234,
"node_id": "MDQ6VXNlcjEyNTAyMzQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/1250234?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ernestum",
"html_url": "https://github.com/ernestum",
"followers_url": "https://api.github.com/users/ernes... | [] | open | false | [] | {
"url": "https://api.github.com/repos/huggingface/datasets/milestones/10",
"html_url": "https://github.com/huggingface/datasets/milestone/10",
"labels_url": "https://api.github.com/repos/huggingface/datasets/milestones/10/labels",
"id": 9038583,
"node_id": "MI_kwDODunzps4Aier3",
"number": 10,
"title": "3... | [
"Hi! This behavior stems from these lines:\r\n\r\nhttps://github.com/huggingface/datasets/blob/b065547654efa0ec633cf373ac1512884c68b2e1/src/datasets/formatting/np_formatter.py#L45-L46\r\n\r\nI agree we should preserve the original type whenever possible and downcast explicitly with a warning.\r\n\r\n@lhoestq Do you... | 2023-02-09 14:18:00 | 2024-01-18 08:42:17 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When I create a dataset with a `float64` feature, then apply numpy formatting the returned numpy arrays are silently downcasted to `float32`.
### Steps to reproduce the bug
```python
import datasets
dataset = datasets.Dataset.from_dict({'a': [1.0, 2.0, 3.0]}).with_format("numpy")
print(... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5517/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5517/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5514 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5514/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5514/comments | https://api.github.com/repos/huggingface/datasets/issues/5514/events | https://github.com/huggingface/datasets/issues/5514 | 1,576,453,837 | I_kwDODunzps5d9sbN | 5,514 | Improve inconsistency of `Dataset.map` interface for `load_from_cache_file` | {
"login": "HallerPatrick",
"id": 22773355,
"node_id": "MDQ6VXNlcjIyNzczMzU1",
"avatar_url": "https://avatars.githubusercontent.com/u/22773355?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/HallerPatrick",
"html_url": "https://github.com/HallerPatrick",
"followers_url": "https://api.githu... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi, thanks for noticing this! We can't just remove the cache control as this allows us to control where the arrow files generated by the ops are written (cached on disk if enabled or a temporary directory if disabled). The right way to address this inconsistency would be by having `load_from_cache_file=None` by de... | 2023-02-08 16:40:44 | 2023-02-14 14:26:44 | 2023-02-14 14:26:44 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
1. Replace the `load_from_cache_file` default value to `True`.
2. Remove or alter checks from `is_caching_enabled` logic.
### Motivation
I stumbled over an inconsistency in the `Dataset.map` interface. The documentation (and source) states for the parameter `load_from_cache_file`:
```
load_... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5514/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5514/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5513 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5513/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5513/comments | https://api.github.com/repos/huggingface/datasets/issues/5513/events | https://github.com/huggingface/datasets/issues/5513 | 1,576,300,803 | I_kwDODunzps5d9HED | 5,513 | Some functions use a param named `type` shouldn't that be avoided since it's a Python reserved name? | {
"login": "alvarobartt",
"id": 36760800,
"node_id": "MDQ6VXNlcjM2NzYwODAw",
"avatar_url": "https://avatars.githubusercontent.com/u/36760800?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alvarobartt",
"html_url": "https://github.com/alvarobartt",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"Hi! Let's not do this - renaming it would be a breaking change, and going through the deprecation cycle is only worth it if it improves user experience.",
"Hi @mariosasko, ok it makes sense. Anyway, don't you think it's worth it at some point to start a deprecation cycle e.g. `fs` in `load_from_disk`? It doesn't... | 2023-02-08 15:13:46 | 2023-07-24 16:02:18 | 2023-07-24 14:27:59 | null | MEMBER | [] | null | null | null | null | Hi @mariosasko, @lhoestq, or whoever reads this! :)
After going through `ArrowDataset.set_format` I found out that the `type` param is actually named `type` which is a Python reserved name as you may already know, shouldn't that be renamed to `format_type` before the 3.0.0 is released?
Just wanted to get your inp... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5513/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5513/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5511 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5511/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5511/comments | https://api.github.com/repos/huggingface/datasets/issues/5511/events | https://github.com/huggingface/datasets/issues/5511 | 1,575,851,768 | I_kwDODunzps5d7Zb4 | 5,511 | Creating a dummy dataset from a bigger one | {
"login": "patrickvonplaten",
"id": 23423619,
"node_id": "MDQ6VXNlcjIzNDIzNjE5",
"avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/patrickvonplaten",
"html_url": "https://github.com/patrickvonplaten",
"followers_url": "https://... | [] | closed | false | [] | null | [
"Update `datasets` or downgrade `huggingface-hub` ;)\r\n\r\nThe `huggingface-hub` lib did a breaking change a few months ago, and you're using an old version of `datasets` that does't support it",
"Awesome thanks a lot! Everything works just fine with `datasets==2.9.0` :-) ",
"Getting same error with latest ver... | 2023-02-08 10:18:41 | 2023-12-28 18:21:01 | 2023-02-08 10:35:48 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I often want to create a dummy dataset from a bigger dataset for fast iteration when training. However, I'm having a hard time doing this especially when trying to upload the dataset to the Hub.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset... | {
"login": "patrickvonplaten",
"id": 23423619,
"node_id": "MDQ6VXNlcjIzNDIzNjE5",
"avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/patrickvonplaten",
"html_url": "https://github.com/patrickvonplaten",
"followers_url": "https://... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5511/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5511/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5508 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5508/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5508/comments | https://api.github.com/repos/huggingface/datasets/issues/5508/events | https://github.com/huggingface/datasets/issues/5508 | 1,573,290,359 | I_kwDODunzps5dxoF3 | 5,508 | Saving a dataset after setting format to torch doesn't work, but only if filtering | {
"login": "joebhakim",
"id": 13984157,
"node_id": "MDQ6VXNlcjEzOTg0MTU3",
"avatar_url": "https://avatars.githubusercontent.com/u/13984157?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joebhakim",
"html_url": "https://github.com/joebhakim",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Hey, I'm a research engineer working on language modelling wanting to contribute to open source. I was wondering if I could give it a shot?",
"Hi! This issue was fixed in https://github.com/huggingface/datasets/pull/4972, so please install `datasets>=2.5.0` to avoid it."
] | 2023-02-06 21:08:58 | 2023-02-09 14:55:26 | 2023-02-09 14:55:26 | null | NONE | [] | null | null | null | null | ### Describe the bug
Saving a dataset after setting format to torch doesn't work, but only if filtering
### Steps to reproduce the bug
```
a = Dataset.from_dict({"b": [1, 2]})
a.set_format('torch')
a.save_to_disk("test_save") # saves successfully
a.filter(None).save_to_disk("test_save_filter") # does not
>> [..... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5508/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5508/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5507 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5507/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5507/comments | https://api.github.com/repos/huggingface/datasets/issues/5507/events | https://github.com/huggingface/datasets/issues/5507 | 1,572,667,036 | I_kwDODunzps5dvP6c | 5,507 | Optimise behaviour in respect to indices mapping | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [
{
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https:... | null | [] | 2023-02-06 14:25:55 | 2023-02-28 18:19:18 | null | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | COLLABORATOR | [] | null | null | null | null | _Originally [posted](https://huggingface.slack.com/archives/C02V51Q3800/p1675443873878489?thread_ts=1675418893.373479&cid=C02V51Q3800) on Slack_
Considering all this, perhaps for Datasets 3.0, we can do the following:
* [ ] have `continuous=True` by default in `.shard` (requested in the survey and makes more sense... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5507/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5507/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5506 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5506/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5506/comments | https://api.github.com/repos/huggingface/datasets/issues/5506/events | https://github.com/huggingface/datasets/issues/5506 | 1,571,838,641 | I_kwDODunzps5dsFqx | 5,506 | IterableDataset and Dataset return different batch sizes when using Trainer with multiple GPUs | {
"login": "kheyer",
"id": 38166299,
"node_id": "MDQ6VXNlcjM4MTY2Mjk5",
"avatar_url": "https://avatars.githubusercontent.com/u/38166299?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/kheyer",
"html_url": "https://github.com/kheyer",
"followers_url": "https://api.github.com/users/kheyer/fo... | [] | closed | false | [] | null | [
"Hi ! `datasets` doesn't do batching - the PyTorch DataLoader does and is created by the `Trainer`. Do you pass other arguments to training_args with respect to data loading ?\r\n\r\nAlso we recently released `.to_iterable_dataset` that does pretty much what you implemented, but using contiguous shards to get a bet... | 2023-02-06 03:26:03 | 2023-02-08 18:30:08 | 2023-02-08 18:30:07 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am training a Roberta model using 2 GPUs and the `Trainer` API with a batch size of 256.
Initially I used a standard `Dataset`, but had issues with slow data loading. After reading [this issue](https://github.com/huggingface/datasets/issues/2252), I swapped to loading my dataset as contiguous... | {
"login": "kheyer",
"id": 38166299,
"node_id": "MDQ6VXNlcjM4MTY2Mjk5",
"avatar_url": "https://avatars.githubusercontent.com/u/38166299?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/kheyer",
"html_url": "https://github.com/kheyer",
"followers_url": "https://api.github.com/users/kheyer/fo... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5506/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5506/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5505 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5505/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5505/comments | https://api.github.com/repos/huggingface/datasets/issues/5505/events | https://github.com/huggingface/datasets/issues/5505 | 1,571,720,814 | I_kwDODunzps5dro5u | 5,505 | PyTorch BatchSampler still loads from Dataset one-by-one | {
"login": "davidgilbertson",
"id": 4443482,
"node_id": "MDQ6VXNlcjQ0NDM0ODI=",
"avatar_url": "https://avatars.githubusercontent.com/u/4443482?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/davidgilbertson",
"html_url": "https://github.com/davidgilbertson",
"followers_url": "https://api.g... | [] | closed | false | [] | null | [
"This change seems to come from a few months ago in the PyTorch side. That's good news and it means we may not need to pass a batch_sampler as soon as we add `Dataset.__getitems__` to get the optimal speed :)\r\n\r\nThanks for reporting ! Would you like to open a PR to add `__getitems__` and remove this outdated do... | 2023-02-06 01:14:55 | 2023-02-19 18:27:30 | 2023-02-19 18:27:30 | null | NONE | [] | null | null | null | null | ### Describe the bug
In [the docs here](https://huggingface.co/docs/datasets/use_with_pytorch#use-a-batchsampler), it mentions the issue of the Dataset being read one-by-one, then states that using a BatchSampler resolves the issue.
I'm not sure if this is a mistake in the docs or the code, but it seems that the on... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5505/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5505/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5500 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5500/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5500/comments | https://api.github.com/repos/huggingface/datasets/issues/5500/events | https://github.com/huggingface/datasets/issues/5500 | 1,569,257,240 | I_kwDODunzps5diPcY | 5,500 | WMT19 custom download checksum error | {
"login": "Hannibal046",
"id": 38466901,
"node_id": "MDQ6VXNlcjM4NDY2OTAx",
"avatar_url": "https://avatars.githubusercontent.com/u/38466901?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Hannibal046",
"html_url": "https://github.com/Hannibal046",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"I update the `datatsets` version and it works."
] | 2023-02-03 05:45:37 | 2023-02-03 05:52:56 | 2023-02-03 05:52:56 | null | NONE | [] | null | null | null | null | ### Describe the bug
I use the following scripts to download data from WMT19:
```python
import datasets
from datasets import inspect_dataset, load_dataset_builder
from wmt19.wmt_utils import _TRAIN_SUBSETS,_DEV_SUBSETS
## this is a must due to: https://discuss.huggingface.co/t/load-dataset-hangs-with-local-fi... | {
"login": "Hannibal046",
"id": 38466901,
"node_id": "MDQ6VXNlcjM4NDY2OTAx",
"avatar_url": "https://avatars.githubusercontent.com/u/38466901?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Hannibal046",
"html_url": "https://github.com/Hannibal046",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5500/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5500/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5499 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5499/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5499/comments | https://api.github.com/repos/huggingface/datasets/issues/5499/events | https://github.com/huggingface/datasets/issues/5499 | 1,568,937,026 | I_kwDODunzps5dhBRC | 5,499 | `load_dataset` has ~4 seconds of overhead for cached data | {
"login": "davidgilbertson",
"id": 4443482,
"node_id": "MDQ6VXNlcjQ0NDM0ODI=",
"avatar_url": "https://avatars.githubusercontent.com/u/4443482?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/davidgilbertson",
"html_url": "https://github.com/davidgilbertson",
"followers_url": "https://api.g... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! To skip the verification step that checks if newer data exist, you can enable offline mode with `HF_DATASETS_OFFLINE=1`.\r\n\r\nAlthough I agree this step should be much faster for datasets hosted on the HF Hub - we could just compare the commit hash from the local data and the remote git repository. We're no... | 2023-02-02 23:34:50 | 2023-02-07 19:35:11 | null | null | NONE | [] | null | null | null | null | ### Feature request
When loading a dataset that has been cached locally, the `load_dataset` function takes a lot longer than it should take to fetch the dataset from disk (or memory).
This is particularly noticeable for smaller datasets. For example, wikitext-2, comparing `load_data` (once cached) and `load_from_disk... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5499/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5499/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5498 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5498/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5498/comments | https://api.github.com/repos/huggingface/datasets/issues/5498/events | https://github.com/huggingface/datasets/issues/5498 | 1,568,190,529 | I_kwDODunzps5deLBB | 5,498 | TypeError: 'bool' object is not iterable when filtering a datasets.arrow_dataset.Dataset | {
"login": "vmuel",
"id": 91255010,
"node_id": "MDQ6VXNlcjkxMjU1MDEw",
"avatar_url": "https://avatars.githubusercontent.com/u/91255010?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vmuel",
"html_url": "https://github.com/vmuel",
"followers_url": "https://api.github.com/users/vmuel/follow... | [] | closed | false | [] | null | [
"Hi! Instead of a single boolean, your filter function should return an iterable (of booleans) in the batched mode like so:\r\n```python\r\ntrain_dataset = train_dataset.filter(\r\n function=lambda batch: [image is not None for image in batch[\"image\"]], \r\n batched=True,\r\n batc... | 2023-02-02 14:46:49 | 2023-10-08 06:12:47 | 2023-02-04 17:19:36 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
Thanks for the amazing work on the library!
**Describe the bug**
I think I might have noticed a small bug in the filter method.
Having loaded a dataset using `load_dataset`, when I try to filter out empty entries with `batched=True`, I get a TypeError.
### Steps to reproduce the ... | {
"login": "vmuel",
"id": 91255010,
"node_id": "MDQ6VXNlcjkxMjU1MDEw",
"avatar_url": "https://avatars.githubusercontent.com/u/91255010?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vmuel",
"html_url": "https://github.com/vmuel",
"followers_url": "https://api.github.com/users/vmuel/follow... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5498/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5498/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5496 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5496/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5496/comments | https://api.github.com/repos/huggingface/datasets/issues/5496/events | https://github.com/huggingface/datasets/issues/5496 | 1,567,301,765 | I_kwDODunzps5dayCF | 5,496 | Add a `reduce` method | {
"login": "zhangir-azerbayev",
"id": 59542043,
"node_id": "MDQ6VXNlcjU5NTQyMDQz",
"avatar_url": "https://avatars.githubusercontent.com/u/59542043?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/zhangir-azerbayev",
"html_url": "https://github.com/zhangir-azerbayev",
"followers_url": "https... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi! Sure, feel free to open a PR, so we can see the API you have in mind.",
"I would like to give it a go! #self-assign",
"Closing as `Dataset.map` can be used instead (see https://github.com/huggingface/datasets/pull/5533#issuecomment-1440571658 and https://github.com/huggingface/datasets/pull/5533#issuecomme... | 2023-02-02 04:30:22 | 2024-11-12 05:58:14 | 2023-07-21 14:24:32 | null | NONE | [] | null | null | null | null | ### Feature request
Right now the `Dataset` class implements `map()` and `filter()`, but leaves out the third functional idiom popular among Python users: `reduce`.
### Motivation
A `reduce` method is often useful when calculating dataset statistics, for example, the occurrence of a particular n-gram or the average... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5496/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5496/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5495 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5495/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5495/comments | https://api.github.com/repos/huggingface/datasets/issues/5495/events | https://github.com/huggingface/datasets/issues/5495 | 1,566,803,452 | I_kwDODunzps5dY4X8 | 5,495 | to_tf_dataset fails with datetime UTC columns even if not included in columns argument | {
"login": "dwyatte",
"id": 2512762,
"node_id": "MDQ6VXNlcjI1MTI3NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/2512762?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dwyatte",
"html_url": "https://github.com/dwyatte",
"followers_url": "https://api.github.com/users/dwyatte/... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
},
{
"id... | closed | false | [] | null | [
"Hi! This is indeed a bug in our zero-copy logic.\r\n\r\nTo fix it, instead of the line:\r\nhttps://github.com/huggingface/datasets/blob/7cfac43b980ab9e4a69c2328f085770996323005/src/datasets/features/features.py#L702\r\n\r\nwe should have:\r\n```python\r\nreturn pa.types.is_primitive(pa_type) and not (pa.types.is_b... | 2023-02-01 20:47:33 | 2023-02-08 14:33:19 | 2023-02-08 14:33:19 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
There appears to be some eager behavior in `to_tf_dataset` that runs against every column in a dataset even if they aren't included in the columns argument. This is problematic with datetime UTC columns due to them not working with zero copy. If I don't have UTC information in my datetime column... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5495/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5495/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5494 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5494/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5494/comments | https://api.github.com/repos/huggingface/datasets/issues/5494/events | https://github.com/huggingface/datasets/issues/5494 | 1,566,655,348 | I_kwDODunzps5dYUN0 | 5,494 | Update audio installation doc page | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [
{
"id": 1935892861,
"node_id": "MDU6TGFiZWwxOTM1ODkyODYx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/documentation",
"name": "documentation",
"color": "0075ca",
"default": true,
"description": "Improvements or additions to documentation",
"archived_at": null,
... | closed | false | [] | null | [
"Totally agree, the docs should be in sync with our code.\r\n\r\nIndeed to avoid confusing users, I think we should have updated the docs at the same time as this PR:\r\n- #5167",
"@albertvillanova yeah sure I should have, but I forgot back then, sorry for that 😶",
"No, @polinaeterna, nothing to be sorry about... | 2023-02-01 19:07:50 | 2023-03-02 16:08:17 | 2023-03-02 16:08:17 | null | CONTRIBUTOR | [] | null | null | null | null | Our [installation documentation page](https://huggingface.co/docs/datasets/installation#audio) says that one can use Datasets for mp3 only with `torchaudio<0.12`. `torchaudio>0.12` is actually supported too but requires a specific version of ffmpeg which is not easily installed on all linux versions but there is a cust... | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5494/reactions",
"total_count": 3,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 1
} | https://api.github.com/repos/huggingface/datasets/issues/5494/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5492 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5492/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5492/comments | https://api.github.com/repos/huggingface/datasets/issues/5492/events | https://github.com/huggingface/datasets/issues/5492 | 1,566,604,216 | I_kwDODunzps5dYHu4 | 5,492 | Push_to_hub in a pull request | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "nateraw",
"id": 32437151,
"node_id": "MDQ6VXNlcjMyNDM3MTUx",
"avatar_url": "https://avatars.githubusercontent.com/u/32437151?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nateraw",
"html_url": "https://github.com/nateraw",
"followers_url": "https://api.git... | null | [
"Assigned to myself and will get to it in the next week, but if someone finds this issue annoying and wants to submit a PR before I do, just ping me here and I'll reassign :). ",
"I would like to be assigned to this issue, @nateraw . #self-assign"
] | 2023-02-01 18:32:14 | 2023-10-16 13:30:48 | 2023-10-16 13:30:48 | {
"login": "nateraw",
"id": 32437151,
"node_id": "MDQ6VXNlcjMyNDM3MTUx",
"avatar_url": "https://avatars.githubusercontent.com/u/32437151?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nateraw",
"html_url": "https://github.com/nateraw",
"followers_url": "https://api.github.com/users/natera... | MEMBER | [] | null | null | null | null | Right now `ds.push_to_hub()` can push a dataset on `main` or on a new branch with `branch=`, but there is no way to open a pull request. Even passing `branch=refs/pr/x` doesn't seem to work: it tries to create a branch with that name
cc @nateraw
It should be possible to tweak the use of `huggingface_hub` in `pus... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5492/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5492/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5488 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5488/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5488/comments | https://api.github.com/repos/huggingface/datasets/issues/5488/events | https://github.com/huggingface/datasets/issues/5488 | 1,565,025,262 | I_kwDODunzps5dSGPu | 5,488 | Error loading MP3 files from CommonVoice | {
"login": "kradonneoh",
"id": 110259722,
"node_id": "U_kgDOBpJuCg",
"avatar_url": "https://avatars.githubusercontent.com/u/110259722?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/kradonneoh",
"html_url": "https://github.com/kradonneoh",
"followers_url": "https://api.github.com/users/kra... | [] | closed | false | [] | null | [
"Hi @kradonneoh, thanks for reporting.\r\n\r\nPlease note that to work with audio datasets (and specifically with MP3 files) we have detailed installation instructions in our docs: https://huggingface.co/docs/datasets/installation#audio\r\n- one of the requirements is torchaudio<0.12.0\r\n\r\nLet us know if the pro... | 2023-01-31 21:25:33 | 2023-03-02 16:25:14 | 2023-03-02 16:25:13 | null | NONE | [] | null | null | null | null | ### Describe the bug
When loading a CommonVoice dataset with `datasets==2.9.0` and `torchaudio>=0.12.0`, I get an error reading the audio arrays:
```python
---------------------------------------------------------------------------
LibsndfileError Traceback (most recent call last)
~/.l... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5488/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5488/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5487 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5487/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5487/comments | https://api.github.com/repos/huggingface/datasets/issues/5487/events | https://github.com/huggingface/datasets/issues/5487 | 1,564,480,121 | I_kwDODunzps5dQBJ5 | 5,487 | Incorrect filepath for dill module | {
"login": "avivbrokman",
"id": 35349273,
"node_id": "MDQ6VXNlcjM1MzQ5Mjcz",
"avatar_url": "https://avatars.githubusercontent.com/u/35349273?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/avivbrokman",
"html_url": "https://github.com/avivbrokman",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"Hi! The correct path is still `dill._dill.XXXX` in the latest release. What do you get when you run `python -c \"import dill; print(dill.__version__)\"` in your environment?",
"`0.3.6` I feel like that's bad news, because it's probably not the issue.\r\n\r\nMy mistake, about the wrong path guess. I think I did... | 2023-01-31 15:01:08 | 2023-02-24 16:18:36 | 2023-02-24 16:18:36 | null | NONE | [] | null | null | null | null | ### Describe the bug
I installed the `datasets` package and when I try to `import` it, I get the following error:
```
Traceback (most recent call last):
File "/var/folders/jt/zw5g74ln6tqfdzsl8tx378j00000gn/T/ipykernel_3805/3458380017.py", line 1, in <module>
import datasets
File "/Users/avivbrokman/... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5487/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5487/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5486 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5486/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5486/comments | https://api.github.com/repos/huggingface/datasets/issues/5486/events | https://github.com/huggingface/datasets/issues/5486 | 1,564,059,749 | I_kwDODunzps5dOahl | 5,486 | Adding `sep` to TextConfig | {
"login": "omar-araboghli",
"id": 29576434,
"node_id": "MDQ6VXNlcjI5NTc2NDM0",
"avatar_url": "https://avatars.githubusercontent.com/u/29576434?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/omar-araboghli",
"html_url": "https://github.com/omar-araboghli",
"followers_url": "https://api.gi... | [] | open | false | [] | null | [
"Hi @omar-araboghli, thanks for your proposal.\r\n\r\nHave you tried to use \"csv\" loader instead of \"text\"? That already has a `sep` argument.",
"Hi @albertvillanova, thanks for the quick response!\r\n\r\nIndeed, I have been trying to use `csv` instead of `text`. However I am still not able to define range of... | 2023-01-31 10:39:53 | 2023-01-31 14:50:18 | null | null | NONE | [] | null | null | null | null | I have a local a `.txt` file that follows the `CONLL2003` format which I need to load using `load_script`. However, by using `sample_by='line'`, one can only split the dataset into lines without splitting each line into columns. Would it be reasonable to add a `sep` argument in combination with `sample_by='paragraph'` ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5486/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5486/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5483 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5483/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5483/comments | https://api.github.com/repos/huggingface/datasets/issues/5483/events | https://github.com/huggingface/datasets/issues/5483 | 1,560,894,690 | I_kwDODunzps5dCVzi | 5,483 | Unable to upload dataset | {
"login": "yuvalkirstain",
"id": 57996478,
"node_id": "MDQ6VXNlcjU3OTk2NDc4",
"avatar_url": "https://avatars.githubusercontent.com/u/57996478?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yuvalkirstain",
"html_url": "https://github.com/yuvalkirstain",
"followers_url": "https://api.githu... | [] | closed | false | [] | null | [
"Seems to work now, perhaps it was something internal with our university's network."
] | 2023-01-28 15:18:26 | 2023-01-29 08:09:49 | 2023-01-29 08:09:49 | null | NONE | [] | null | null | null | null | ### Describe the bug
Uploading a simple dataset ends with an exception
### Steps to reproduce the bug
I created a new conda env with python 3.10, pip installed datasets and:
```python
>>> from datasets import load_dataset, load_from_disk, Dataset
>>> d = Dataset.from_dict({"text": ["hello"] * 2})
>>> d.pus... | {
"login": "yuvalkirstain",
"id": 57996478,
"node_id": "MDQ6VXNlcjU3OTk2NDc4",
"avatar_url": "https://avatars.githubusercontent.com/u/57996478?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yuvalkirstain",
"html_url": "https://github.com/yuvalkirstain",
"followers_url": "https://api.githu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5483/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5483/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5482 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5482/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5482/comments | https://api.github.com/repos/huggingface/datasets/issues/5482/events | https://github.com/huggingface/datasets/issues/5482 | 1,560,853,137 | I_kwDODunzps5dCLqR | 5,482 | Reload features from Parquet metadata | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "MFreidank",
"id": 6368040,
"node_id": "MDQ6VXNlcjYzNjgwNDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6368040?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MFreidank",
"html_url": "https://github.com/MFreidank",
"followers_url": "https://api... | null | [
"I'd be happy to have a look, if nobody else has started working on this yet @lhoestq. \r\n\r\nIt seems to me that for the `arrow` format features are currently attached as metadata [in `datasets.arrow_writer`](https://github.com/huggingface/datasets/blob/5f810b7011a8a4ab077a1847c024d2d9e267b065/src/datasets/arrow_... | 2023-01-28 13:12:31 | 2023-02-12 15:57:02 | 2023-02-12 15:57:02 | {
"login": "MFreidank",
"id": 6368040,
"node_id": "MDQ6VXNlcjYzNjgwNDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6368040?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MFreidank",
"html_url": "https://github.com/MFreidank",
"followers_url": "https://api.github.com/users/MF... | MEMBER | [] | null | null | null | null | The idea would be to allow this :
```python
ds.to_parquet("my_dataset/ds.parquet")
reloaded = load_dataset("my_dataset")
assert ds.features == reloaded.features
```
And it should also work with Image and Audio types (right now they're reloaded as a dict type)
This can be implemented by storing and reading th... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5482/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5482/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5481 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5481/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5481/comments | https://api.github.com/repos/huggingface/datasets/issues/5481/events | https://github.com/huggingface/datasets/issues/5481 | 1,560,468,195 | I_kwDODunzps5dAtrj | 5,481 | Load a cached dataset as iterable | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Can I work on this issue? I am pretty new to this.",
"Hi ! Sure :) you can comment `#self-assign` to assign yourself to this issue.\r\n\r\nI can give you some pointers to get started:\r\n\r\n`load_dataset` works roughly this way:\r\n1. it instantiate a dataset builder using `load_dataset_builder()`\r\n2. the bui... | 2023-01-27 21:43:51 | 2026-09-17 20:01:48 | null | null | MEMBER | [] | null | null | null | null | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5481/reactions",
"total_count": 5,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 5,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5481/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5479 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5479/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5479/comments | https://api.github.com/repos/huggingface/datasets/issues/5479/events | https://github.com/huggingface/datasets/issues/5479 | 1,560,357,590 | I_kwDODunzps5dASrW | 5,479 | audiofolder works on local env, but creates empty dataset in a remote one, what dependencies could I be missing/outdated | {
"login": "joseph-y-cho",
"id": 107211437,
"node_id": "U_kgDOBmPqrQ",
"avatar_url": "https://avatars.githubusercontent.com/u/107211437?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joseph-y-cho",
"html_url": "https://github.com/joseph-y-cho",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [] | 2023-01-27 20:01:22 | 2023-01-29 05:23:14 | 2023-01-29 05:23:14 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm using a custom audio dataset (400+ audio files) in the correct format for audiofolder. Although loading the dataset with audiofolder works in one local setup, it doesn't in a remote one (it just creates an empty dataset). I have both ffmpeg and libndfile installed on both computers, what cou... | {
"login": "joseph-y-cho",
"id": 107211437,
"node_id": "U_kgDOBmPqrQ",
"avatar_url": "https://avatars.githubusercontent.com/u/107211437?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joseph-y-cho",
"html_url": "https://github.com/joseph-y-cho",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5479/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5479/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5477 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5477/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5477/comments | https://api.github.com/repos/huggingface/datasets/issues/5477/events | https://github.com/huggingface/datasets/issues/5477 | 1,559,909,892 | I_kwDODunzps5c-lYE | 5,477 | Unpin sqlalchemy once issue is fixed | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | [
"@albertvillanova It looks like that issue has been fixed so I made a PR to unpin sqlalchemy! ",
"The source issue:\r\n- https://github.com/pandas-dev/pandas/issues/40686\r\n\r\nhas been fixed:\r\n- https://github.com/pandas-dev/pandas/pull/48576\r\n\r\nThe fix was released yesterday (2023-04-03) only in `pandas-... | 2023-01-27 15:01:55 | 2024-01-26 14:50:45 | 2024-01-26 14:50:45 | null | MEMBER | [] | null | null | null | null | Once the source issue is fixed:
- pandas-dev/pandas#51015
we should revert the pin introduced in:
- #5476 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5477/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5477/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5475 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5475/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5475/comments | https://api.github.com/repos/huggingface/datasets/issues/5475/events | https://github.com/huggingface/datasets/issues/5475 | 1,559,030,149 | I_kwDODunzps5c7OmF | 5,475 | Dataset scan time is much slower than using native arrow | {
"login": "jonny-cyberhaven",
"id": 121845112,
"node_id": "U_kgDOB0M1eA",
"avatar_url": "https://avatars.githubusercontent.com/u/121845112?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonny-cyberhaven",
"html_url": "https://github.com/jonny-cyberhaven",
"followers_url": "https://api.gi... | [] | closed | false | [] | null | [
"Hi ! In your code you only iterate on the Arrow buffers - you don't actually load the data as python objects. For a fair comparison, you can modify your code using:\r\n```diff\r\n- for _ in range(0, len(table), bsz):\r\n- _ = {k:table[k][_ : _ + bsz] for k in cols}\r\n+ for _ in range(0, len(table)... | 2023-01-27 01:32:25 | 2023-01-30 16:17:11 | 2023-01-30 16:17:11 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I'm basically running the same scanning experiment from the tutorials https://huggingface.co/course/chapter5/4?fw=pt except now I'm comparing to a native pyarrow version.
I'm finding that the native pyarrow approach is much faster (2 orders of magnitude). Is there something I'm missing that exp... | {
"login": "jonny-cyberhaven",
"id": 121845112,
"node_id": "U_kgDOB0M1eA",
"avatar_url": "https://avatars.githubusercontent.com/u/121845112?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonny-cyberhaven",
"html_url": "https://github.com/jonny-cyberhaven",
"followers_url": "https://api.gi... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5475/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5475/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5474 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5474/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5474/comments | https://api.github.com/repos/huggingface/datasets/issues/5474/events | https://github.com/huggingface/datasets/issues/5474 | 1,558,827,155 | I_kwDODunzps5c6dCT | 5,474 | Column project operation on `datasets.Dataset` | {
"login": "daskol",
"id": 9336514,
"node_id": "MDQ6VXNlcjkzMzY1MTQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/9336514?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/daskol",
"html_url": "https://github.com/daskol",
"followers_url": "https://api.github.com/users/daskol/foll... | [
{
"id": 1935892865,
"node_id": "MDU6TGFiZWwxOTM1ODkyODY1",
"url": "https://api.github.com/repos/huggingface/datasets/labels/duplicate",
"name": "duplicate",
"color": "cfd3d7",
"default": true,
"description": "This issue or pull request already exists",
"archived_at": null,
"archi... | closed | false | [] | null | [
"Hi ! This would be a nice addition indeed :) This sounds like a duplicate of https://github.com/huggingface/datasets/issues/5468\r\n\r\n> Not sure. Some of my PRs are still open and some do not have any discussions.\r\n\r\nSorry to hear that, feel free to ping me on those PRs"
] | 2023-01-26 21:47:53 | 2023-02-13 09:59:37 | 2023-02-13 09:59:37 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
There is no operation to select a subset of columns of original dataset. Expected API follows.
```python
a = Dataset.from_dict({
'int': [0, 1, 2]
'char': ['a', 'b', 'c'],
'none': [None] * 3,
})
b = a.project('int', 'char') # usually, .select()
print(a.column_names) # std... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5474/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5474/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5468 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5468/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5468/comments | https://api.github.com/repos/huggingface/datasets/issues/5468/events | https://github.com/huggingface/datasets/issues/5468 | 1,558,066,625 | I_kwDODunzps5c3jXB | 5,468 | Allow opposite of remove_columns on Dataset and DatasetDict | {
"login": "hollance",
"id": 346853,
"node_id": "MDQ6VXNlcjM0Njg1Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/346853?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/hollance",
"html_url": "https://github.com/hollance",
"followers_url": "https://api.github.com/users/hollanc... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi! I agree it would be nice to have a method like that. Instead of `keep_columns`, we can name it `select_columns` to be more aligned with PyArrow's naming convention (`pa.Table.select`).",
"Hi, I am a newbie to open source and would like to contribute. @mariosasko can I take up this issue ?",
"Hey, I also wa... | 2023-01-26 12:28:09 | 2023-02-13 09:59:38 | 2023-02-13 09:59:38 | null | NONE | [] | null | null | null | null | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5468/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5468/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5465 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5465/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5465/comments | https://api.github.com/repos/huggingface/datasets/issues/5465/events | https://github.com/huggingface/datasets/issues/5465 | 1,557,510,618 | I_kwDODunzps5c1bna | 5,465 | audiofolder creates empty dataset even though the dataset passed in follows the correct structure | {
"login": "joseph-y-cho",
"id": 107211437,
"node_id": "U_kgDOBmPqrQ",
"avatar_url": "https://avatars.githubusercontent.com/u/107211437?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joseph-y-cho",
"html_url": "https://github.com/joseph-y-cho",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [] | 2023-01-26 01:45:45 | 2023-01-26 08:48:45 | 2023-01-26 08:48:45 | null | NONE | [] | null | null | null | null | ### Describe the bug
The structure of my dataset folder called "my_dataset" is : data metadata.csv
The data folder consists of all mp3 files and metadata.csv consist of file locations like 'data/...mp3 and transcriptions. There's 400+ mp3 files and corresponding transcriptions for my dataset.
When I run the follo... | {
"login": "joseph-y-cho",
"id": 107211437,
"node_id": "U_kgDOBmPqrQ",
"avatar_url": "https://avatars.githubusercontent.com/u/107211437?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/joseph-y-cho",
"html_url": "https://github.com/joseph-y-cho",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5465/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5465/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5464 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5464/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5464/comments | https://api.github.com/repos/huggingface/datasets/issues/5464/events | https://github.com/huggingface/datasets/issues/5464 | 1,557,462,104 | I_kwDODunzps5c1PxY | 5,464 | NonMatchingChecksumError for hendrycks_test | {
"login": "sarahwie",
"id": 8027676,
"node_id": "MDQ6VXNlcjgwMjc2NzY=",
"avatar_url": "https://avatars.githubusercontent.com/u/8027676?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sarahwie",
"html_url": "https://github.com/sarahwie",
"followers_url": "https://api.github.com/users/sarah... | [] | closed | false | [] | null | [
"Thanks for reporting, @sarahwie.\r\n\r\nPlease note this issue was already fixed in `datasets` 2.6.0 version:\r\n- #5040\r\n\r\nIf you update your `datasets` version, you will be able to load the dataset:\r\n```\r\npip install -U datasets\r\n```",
"Oops, missed that I needed to upgrade. Thanks!"
] | 2023-01-26 00:43:23 | 2023-01-27 05:44:31 | 2023-01-26 07:41:58 | null | NONE | [] | null | null | null | null | ### Describe the bug
The checksum of the file has likely changed on the remote host.
### Steps to reproduce the bug
`dataset = nlp.load_dataset("hendrycks_test", "anatomy")`
### Expected behavior
no error thrown
### Environment info
- `datasets` version: 2.2.1
- Platform: macOS-13.1-arm64-arm-64bit
- Pyt... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5464/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5464/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5461 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5461/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5461/comments | https://api.github.com/repos/huggingface/datasets/issues/5461/events | https://github.com/huggingface/datasets/issues/5461 | 1,555,532,719 | I_kwDODunzps5ct4uv | 5,461 | Discrepancy in `nyu_depth_v2` dataset | {
"login": "awsaf49",
"id": 36858976,
"node_id": "MDQ6VXNlcjM2ODU4OTc2",
"avatar_url": "https://avatars.githubusercontent.com/u/36858976?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/awsaf49",
"html_url": "https://github.com/awsaf49",
"followers_url": "https://api.github.com/users/awsaf4... | [] | open | false | [] | null | [
"Ccing @dwofk (the author of `fast-depth`). \r\n\r\nThanks, @awsaf49 for reporting this. I believe this is because the NYU Depth V2 shipped from `fast-depth` is already preprocessed. \r\n\r\nIf you think it might be better to have the NYU Depth V2 dataset from BTS [here](https://huggingface.co/datasets/sayakpaul/ny... | 2023-01-24 19:15:46 | 2023-02-06 20:52:00 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5461/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5461/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5458 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5458/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5458/comments | https://api.github.com/repos/huggingface/datasets/issues/5458/events | https://github.com/huggingface/datasets/issues/5458 | 1,555,054,737 | I_kwDODunzps5csECR | 5,458 | slice split while streaming | {
"login": "SvenDS9",
"id": 122370631,
"node_id": "U_kgDOB0s6Rw",
"avatar_url": "https://avatars.githubusercontent.com/u/122370631?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SvenDS9",
"html_url": "https://github.com/SvenDS9",
"followers_url": "https://api.github.com/users/SvenDS9/foll... | [] | closed | false | [] | null | [
"Hi! Yes, that's correct. When `streaming` is `True`, only split names can be specified as `split`, and for slicing, you have to use `.skip`/`.take` instead.\r\n\r\nE.g. \r\n`load_dataset(\"lhoestq/demo1\",revision=None, streaming=True, split=\"train[:3]\")`\r\n\r\nrewritten with `.skip`/`.take`:\r\n`load_dataset(\... | 2023-01-24 14:08:17 | 2023-01-24 15:11:47 | 2023-01-24 15:11:47 | null | NONE | [] | null | null | null | null | ### Describe the bug
When using the `load_dataset` function with streaming set to True, slicing splits is apparently not supported.
Did I miss this in the documentation?
### Steps to reproduce the bug
`load_dataset("lhoestq/demo1",revision=None, streaming=True, split="train[:3]")`
causes ValueError: Bad split:... | {
"login": "SvenDS9",
"id": 122370631,
"node_id": "U_kgDOB0s6Rw",
"avatar_url": "https://avatars.githubusercontent.com/u/122370631?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SvenDS9",
"html_url": "https://github.com/SvenDS9",
"followers_url": "https://api.github.com/users/SvenDS9/foll... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5458/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5458/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5457 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5457/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5457/comments | https://api.github.com/repos/huggingface/datasets/issues/5457/events | https://github.com/huggingface/datasets/issues/5457 | 1,554,171,264 | I_kwDODunzps5cosWA | 5,457 | prebuilt dataset relies on `downloads/extracted` | {
"login": "stas00",
"id": 10676103,
"node_id": "MDQ6VXNlcjEwNjc2MTAz",
"avatar_url": "https://avatars.githubusercontent.com/u/10676103?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stas00",
"html_url": "https://github.com/stas00",
"followers_url": "https://api.github.com/users/stas00/fo... | [] | open | false | [] | null | [
"Hi! \r\n\r\nThis issue is due to our audio/image datasets not being self-contained. This allows us to save disk space (files are written only once) but also leads to the issues like this one. We plan to make all our datasets self-contained in Datasets 3.0.\r\n\r\nIn the meantime, you can run the following map to e... | 2023-01-24 02:09:32 | 2024-11-18 07:43:51 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I pre-built the dataset:
```
python -c 'import sys; from datasets import load_dataset; ds=load_dataset(sys.argv[1])' HuggingFaceM4/general-pmd-synthetic-testing
```
and it can be used just fine.
now I wipe out `downloads/extracted` and it no longer works.
```
rm -r ~/.cache/huggingface... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5457/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5457/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.