
url stringlengths 58 61 | repository_url stringclasses 1
value | labels_url stringlengths 72 75 | comments_url stringlengths 67 70 | events_url stringlengths 65 68 | html_url stringlengths 48 51 | id int64 600M 5.54B | node_id stringlengths 18 24 | number int64 2 8.66k | title stringlengths 1 290 | user dict | labels listlengths 0 4 | state stringclasses 2
values | locked bool 1
class | assignees listlengths 0 4 | milestone dict | comments listlengths 0 30 | created_at stringdate 2020-04-14 18:18:51 2026-09-22 08:39:29 | updated_at stringdate 2020-04-29 09:23:05 2026-09-22 08:41:52 | closed_at stringlengths 19 19 ⌀ | assignee dict | author_association stringclasses 4
values | issue_field_values listlengths 0 0 | type stringclasses 0
values | active_lock_reason stringclasses 0
values | draft bool 0
classes | pull_request dict | body stringlengths 0 228k ⌀ | closed_by dict | reactions dict | timeline_url stringlengths 67 70 | performed_via_github_app dict | state_reason stringclasses 4
values | sub_issues_summary stringclasses 1
value | issue_dependencies_summary stringclasses 1
value | pinned_comment stringclasses 0
values | is_pull_request bool 1
class |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
https://api.github.com/repos/huggingface/datasets/issues/7545 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7545/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7545/comments | https://api.github.com/repos/huggingface/datasets/issues/7545/events | https://github.com/huggingface/datasets/issues/7545 | 3,031,617,547 | I_kwDODunzps60stAL | 7,545 | Networked Pull Through Cache | {
"login": "wrmedford",
"id": 8764173,
"node_id": "MDQ6VXNlcjg3NjQxNzM=",
"avatar_url": "https://avatars.githubusercontent.com/u/8764173?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/wrmedford",
"html_url": "https://github.com/wrmedford",
"followers_url": "https://api.github.com/users/wr... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [] | 2025-04-30 15:16:33 | 2025-04-30 15:16:33 | null | null | NONE | [] | null | null | null | null | ### Feature request
Introduce a HF_DATASET_CACHE_NETWORK_LOCATION configuration (e.g. an environment variable) together with a companion network cache service.
Enable a three-tier cache lookup for datasets:
1. Local on-disk cache
2. Configurable network cache proxy
3. Official Hugging Face Hub
### Motivation
- Dis... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7545/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7545/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7543 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7543/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7543/comments | https://api.github.com/repos/huggingface/datasets/issues/7543/events | https://github.com/huggingface/datasets/issues/7543 | 3,026,867,706 | I_kwDODunzps60alX6 | 7,543 | The memory-disk mapping failure issue of the map function(resolved, but there are some suggestions.) | {
"login": "jxma20",
"id": 76415358,
"node_id": "MDQ6VXNlcjc2NDE1MzU4",
"avatar_url": "https://avatars.githubusercontent.com/u/76415358?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jxma20",
"html_url": "https://github.com/jxma20",
"followers_url": "https://api.github.com/users/jxma20/fo... | [] | closed | false | [] | null | [] | 2025-04-29 03:04:59 | 2025-04-30 02:22:17 | 2025-04-30 02:22:17 | null | NONE | [] | null | null | null | null | ### Describe the bug
## bug
When the map function processes a large dataset, it temporarily stores the data in a cache file on the disk. After the data is stored, the memory occupied by it is released. Therefore, when using the map function to process a large-scale dataset, only a dataset space of the size of `writer_... | {
"login": "jxma20",
"id": 76415358,
"node_id": "MDQ6VXNlcjc2NDE1MzU4",
"avatar_url": "https://avatars.githubusercontent.com/u/76415358?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jxma20",
"html_url": "https://github.com/jxma20",
"followers_url": "https://api.github.com/users/jxma20/fo... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7543/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7543/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7538 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7538/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7538/comments | https://api.github.com/repos/huggingface/datasets/issues/7538/events | https://github.com/huggingface/datasets/issues/7538 | 3,023,280,056 | I_kwDODunzps60M5e4 | 7,538 | `IterableDataset` drops samples when resuming from a checkpoint | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [] | null | [
"Thanks for reporting ! I fixed the issue using RebatchedArrowExamplesIterable before the formatted iterable"
] | 2025-04-27 19:34:49 | 2025-05-06 14:04:05 | 2025-05-06 14:03:42 | null | COLLABORATOR | [] | null | null | null | null | When resuming from a checkpoint, `IterableDataset` will drop samples if `num_shards % world_size == 0` and the underlying example supports `iter_arrow` and needs to be formatted.
In that case, the `FormattedExamplesIterable` fetches a batch of samples from the child iterable's `iter_arrow` and yields them one by one ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7538/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7538/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7537 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7537/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7537/comments | https://api.github.com/repos/huggingface/datasets/issues/7537/events | https://github.com/huggingface/datasets/issues/7537 | 3,018,792,966 | I_kwDODunzps6z7yAG | 7,537 | `datasets.map(..., num_proc=4)` multi-processing fails | {
"login": "faaany",
"id": 24477841,
"node_id": "MDQ6VXNlcjI0NDc3ODQx",
"avatar_url": "https://avatars.githubusercontent.com/u/24477841?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/faaany",
"html_url": "https://github.com/faaany",
"followers_url": "https://api.github.com/users/faaany/fo... | [] | open | false | [] | null | [
"related: https://github.com/huggingface/datasets/issues/7510\n\nwe need to do more tests to see if latest `dill` is deterministic"
] | 2025-04-25 01:53:47 | 2025-05-06 13:12:08 | null | null | NONE | [] | null | null | null | null | The following code fails in python 3.11+
```python
tokenized_datasets = datasets.map(tokenize_function, batched=True, num_proc=4, remove_columns=["text"])
```
Error log:
```bash
Traceback (most recent call last):
File "/usr/local/lib/python3.12/dist-packages/multiprocess/process.py", line 315, in _bootstrap
self.ru... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7537/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7537/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7536 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7536/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7536/comments | https://api.github.com/repos/huggingface/datasets/issues/7536/events | https://github.com/huggingface/datasets/issues/7536 | 3,018,425,549 | I_kwDODunzps6z6YTN | 7,536 | [Errno 13] Permission denied: on `.incomplete` file | {
"login": "ryan-clancy",
"id": 1282383,
"node_id": "MDQ6VXNlcjEyODIzODM=",
"avatar_url": "https://avatars.githubusercontent.com/u/1282383?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ryan-clancy",
"html_url": "https://github.com/ryan-clancy",
"followers_url": "https://api.github.com/us... | [] | closed | false | [] | null | [
"It must be an issue with umask being used by multiple threads indeed. Maybe we can try to make a thread safe function to apply the umask (using filelock for example)",
"> It must be an issue with umask being used by multiple threads indeed. Maybe we can try to make a thread safe function to apply the umask (usin... | 2025-04-24 20:52:45 | 2025-05-06 13:05:01 | 2025-05-06 13:05:01 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When downloading a dataset, we frequently hit the below Permission Denied error. This looks to happen (at least) across datasets in HF, S3, and GCS.
It looks like the `temp_file` being passed [here](https://github.com/huggingface/datasets/blob/main/src/datasets/utils/file_utils.py#L412) can somet... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7536/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7536/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7534 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7534/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7534/comments | https://api.github.com/repos/huggingface/datasets/issues/7534/events | https://github.com/huggingface/datasets/issues/7534 | 3,017,259,407 | I_kwDODunzps6z17mP | 7,534 | TensorFlow RaggedTensor Support (batch-level) | {
"login": "Lundez",
"id": 7490199,
"node_id": "MDQ6VXNlcjc0OTAxOTk=",
"avatar_url": "https://avatars.githubusercontent.com/u/7490199?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Lundez",
"html_url": "https://github.com/Lundez",
"followers_url": "https://api.github.com/users/Lundez/foll... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Keras doesn't support other inputs other than tf.data.Dataset objects ? it's a bit painful to have to support and maintain this kind of integration\n\nIs there a way to use a `datasets.Dataset` with outputs formatted as tensors / ragged tensors instead ? like in https://huggingface.co/docs/datasets/use_with_tensor... | 2025-04-24 13:14:52 | 2025-06-30 17:03:39 | null | null | NONE | [] | null | null | null | null | ### Feature request
Hi,
Currently datasets does not support RaggedTensor output on batch-level.
When building a Object Detection Dataset (with TensorFlow) I need to enable RaggedTensors as that's how BBoxes & classes are expected from the Keras Model POV.
Currently there's a error thrown saying that "Nested Data is ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7534/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7534/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7531 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7531/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7531/comments | https://api.github.com/repos/huggingface/datasets/issues/7531/events | https://github.com/huggingface/datasets/issues/7531 | 3,008,914,887 | I_kwDODunzps6zWGXH | 7,531 | Deepspeed reward training hangs at end of training with Dataset.from_list | {
"login": "Matt00n",
"id": 60710414,
"node_id": "MDQ6VXNlcjYwNzEwNDE0",
"avatar_url": "https://avatars.githubusercontent.com/u/60710414?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Matt00n",
"html_url": "https://github.com/Matt00n",
"followers_url": "https://api.github.com/users/Matt00... | [] | open | false | [] | null | [
"Hi ! How big is the dataset ? if you load it using `from_list`, the dataset lives in memory and has to be copied to every gpu process, which can be slow.\n\nIt's fasted if you load it from JSON files from disk, because in that case the dataset in converted to Arrow and loaded from disk using memory mapping. Memory... | 2025-04-21 17:29:20 | 2026-05-02 13:03:01 | null | null | NONE | [] | null | null | null | null | There seems to be a weird interaction between Deepspeed, the Dataset.from_list method and trl's RewardTrainer. On a multi-GPU setup (10 A100s), training always hangs at the very end of training until it times out. The training itself works fine until the end of training and running the same script with Deepspeed on a s... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7531/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7531/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7530 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7530/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7530/comments | https://api.github.com/repos/huggingface/datasets/issues/7530/events | https://github.com/huggingface/datasets/issues/7530 | 3,007,452,499 | I_kwDODunzps6zQhVT | 7,530 | How to solve "Spaces stuck in Building" problems | {
"login": "ghost",
"id": 10137,
"node_id": "MDQ6VXNlcjEwMTM3",
"avatar_url": "https://avatars.githubusercontent.com/u/10137?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ghost",
"html_url": "https://github.com/ghost",
"followers_url": "https://api.github.com/users/ghost/followers",
"f... | [] | closed | false | [] | null | [
"I'm facing the same issue—Space stuck in \"Building\" even after restart and Factory rebuild. Any fix?\n",
"> I'm facing the same issue—Space stuck in \"Building\" even after restart and Factory rebuild. Any fix?\n\nAlso see https://github.com/huggingface/huggingface_hub/issues/3019",
"I'm facing the same issu... | 2025-04-21 03:08:38 | 2025-11-11 00:57:14 | 2025-04-22 07:49:52 | null | NONE | [] | null | null | null | null | ### Describe the bug
Public spaces may stuck in Building after restarting, error log as follows:
build error
Unexpected job error
ERROR: failed to push spaces-registry.huggingface.tech/spaces/*:cpu-*-*: unexpected status from HEAD request to https://spaces-registry.huggingface.tech/v2/spaces/*/manifests/cpu-*-*: 401... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7530/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7530/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7529 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7529/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7529/comments | https://api.github.com/repos/huggingface/datasets/issues/7529/events | https://github.com/huggingface/datasets/issues/7529 | 3,007,118,969 | I_kwDODunzps6zPP55 | 7,529 | audio folder builder cannot detect custom split name | {
"login": "phineas-pta",
"id": 37548991,
"node_id": "MDQ6VXNlcjM3NTQ4OTkx",
"avatar_url": "https://avatars.githubusercontent.com/u/37548991?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/phineas-pta",
"html_url": "https://github.com/phineas-pta",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"Hi! Triaging older issues — reproduced your behavior, but I think this is by design rather than a bug.\n\nThe folder-based builders (`audiofolder`/`imagefolder`/`videofolder`) auto-detect splits using a fixed keyword list (`train`, `validation`/`valid`/`val`/`dev`, `test`/`testing`/`eval`/`evaluation`) — see `SPLI... | 2025-04-20 16:53:21 | 2026-05-16 17:16:35 | 2026-05-16 17:16:35 | null | NONE | [] | null | null | null | null | ### Describe the bug
when using audio folder builder (`load_dataset("audiofolder", data_dir="/path/to/folder")`), it cannot detect custom split name other than train/validation/test
### Steps to reproduce the bug
i have the following folder structure
```
my_dataset/
├── train/
│ ├── lorem.wav
│ ├── …
│ └── met... | {
"login": "phineas-pta",
"id": 37548991,
"node_id": "MDQ6VXNlcjM3NTQ4OTkx",
"avatar_url": "https://avatars.githubusercontent.com/u/37548991?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/phineas-pta",
"html_url": "https://github.com/phineas-pta",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7529/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7529/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7528 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7528/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7528/comments | https://api.github.com/repos/huggingface/datasets/issues/7528/events | https://github.com/huggingface/datasets/issues/7528 | 3,006,433,485 | I_kwDODunzps6zMojN | 7,528 | Data Studio Error: Convert JSONL incorrectly | {
"login": "zxccade",
"id": 144962041,
"node_id": "U_kgDOCKPx-Q",
"avatar_url": "https://avatars.githubusercontent.com/u/144962041?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/zxccade",
"html_url": "https://github.com/zxccade",
"followers_url": "https://api.github.com/users/zxccade/foll... | [] | open | false | [] | null | [
"Hi ! Your JSONL file is incompatible with Arrow / Parquet. Indeed in Arrow / Parquet every dict should have the same keys, while in your dataset the bboxes have varying keys.\n\nThis causes the Data Studio to treat the bboxes as if each row was missing the keys from other rows.\n\nFeel free to take a look at the d... | 2025-04-19 13:21:44 | 2025-05-06 13:18:38 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi there,
I uploaded a dataset here https://huggingface.co/datasets/V-STaR-Bench/V-STaR, but I found that Data Studio incorrectly convert the "bboxes" value for the whole dataset. Therefore, anyone who downloaded the dataset via the API would get the wrong "bboxes" value in the data file.
Could ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7528/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7528/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7527 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7527/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7527/comments | https://api.github.com/repos/huggingface/datasets/issues/7527/events | https://github.com/huggingface/datasets/issues/7527 | 3,005,242,422 | I_kwDODunzps6zIFw2 | 7,527 | Auto-merge option for `convert-to-parquet` | {
"login": "klamike",
"id": 17013474,
"node_id": "MDQ6VXNlcjE3MDEzNDc0",
"avatar_url": "https://avatars.githubusercontent.com/u/17013474?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/klamike",
"html_url": "https://github.com/klamike",
"followers_url": "https://api.github.com/users/klamik... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "klamike",
"id": 17013474,
"node_id": "MDQ6VXNlcjE3MDEzNDc0",
"avatar_url": "https://avatars.githubusercontent.com/u/17013474?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/klamike",
"html_url": "https://github.com/klamike",
"followers_url": "https://api.git... | null | [
"Alternatively, there could be an option to switch from submitting PRs to just committing changes directly to `main`.",
"Why not, I'd be in favor of `--merge-pull-request` to call `HfApi().merge_pull_request()` at the end of the conversion :) feel free to open a PR if you'd like",
"#self-assign",
"Closing sin... | 2025-04-18 16:03:22 | 2025-07-18 19:09:03 | 2025-07-18 19:09:03 | {
"login": "klamike",
"id": 17013474,
"node_id": "MDQ6VXNlcjE3MDEzNDc0",
"avatar_url": "https://avatars.githubusercontent.com/u/17013474?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/klamike",
"html_url": "https://github.com/klamike",
"followers_url": "https://api.github.com/users/klamik... | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Add a command-line option, e.g. `--auto-merge-pull-request` that enables automatic merging of the commits created by the `convert-to-parquet` tool.
### Motivation
Large datasets may result in dozens of PRs due to the splitting mechanism. Each of these has to be manually accepted via the website.
... | {
"login": "klamike",
"id": 17013474,
"node_id": "MDQ6VXNlcjE3MDEzNDc0",
"avatar_url": "https://avatars.githubusercontent.com/u/17013474?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/klamike",
"html_url": "https://github.com/klamike",
"followers_url": "https://api.github.com/users/klamik... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7527/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7527/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7526 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7526/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7526/comments | https://api.github.com/repos/huggingface/datasets/issues/7526/events | https://github.com/huggingface/datasets/issues/7526 | 3,005,107,536 | I_kwDODunzps6zHk1Q | 7,526 | Faster downloads/uploads with Xet storage | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | open | false | [] | null | [] | 2025-04-18 14:46:42 | 2025-05-12 12:09:09 | null | null | MEMBER | [] | null | null | null | null | 
## Xet is out !
Over the past few weeks, Hugging Face’s [Xet Team](https://huggingface.co/xet-team) took a major step forward by [migrating the first Model and Dataset repositories off LFS and to Xet storage](https://huggingface... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7526/reactions",
"total_count": 7,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 7,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7526/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7520 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7520/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7520/comments | https://api.github.com/repos/huggingface/datasets/issues/7520/events | https://github.com/huggingface/datasets/issues/7520 | 2,997,422,044 | I_kwDODunzps6yqQfc | 7,520 | Update items in the dataset without `map` | {
"login": "mashdragon",
"id": 122402293,
"node_id": "U_kgDOB0u19Q",
"avatar_url": "https://avatars.githubusercontent.com/u/122402293?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mashdragon",
"html_url": "https://github.com/mashdragon",
"followers_url": "https://api.github.com/users/mas... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hello!\n\nHave you looked at `Dataset.shard`? [Docs](https://huggingface.co/docs/datasets/en/process#shard)\n\nUsing this method you could break your dataset in N shards. Apply `map` on each shard and concatenate them back."
] | 2025-04-15 19:39:01 | 2025-04-19 18:47:46 | null | null | NONE | [] | null | null | null | null | ### Feature request
I would like to be able to update items in my dataset without affecting all rows. At least if there was a range option, I would be able to process those items, save the dataset, and then continue.
If I am supposed to split the dataset first, that is not clear, since the docs suggest that any of th... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7520/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7520/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7518 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7518/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7518/comments | https://api.github.com/repos/huggingface/datasets/issues/7518/events | https://github.com/huggingface/datasets/issues/7518 | 2,996,141,825 | I_kwDODunzps6ylX8B | 7,518 | num_proc parallelization works only for first ~10s. | {
"login": "pshishodiaa",
"id": 33901783,
"node_id": "MDQ6VXNlcjMzOTAxNzgz",
"avatar_url": "https://avatars.githubusercontent.com/u/33901783?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/pshishodiaa",
"html_url": "https://github.com/pshishodiaa",
"followers_url": "https://api.github.com/... | [] | open | false | [] | null | [
"Hi, can you check if the processes are still alive ? It's a bit weird because `datasets` does check if processes crash and return an error in that case",
"Thank you for reverting quickly. I digged a bit, and realized my disk's IOPS is also limited - which is causing this. will check further and report if it's an... | 2025-04-15 11:44:03 | 2025-04-15 13:12:13 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When I try to load an already downloaded dataset with num_proc=64, the speed is very high for the first 10-20 seconds acheiving 30-40K samples / s, and 100% utilization for all cores but it soon drops to <= 1000 with almost 0% utilization for most cores.
### Steps to reproduce the bug
```
// do... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7518/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7518/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7517 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7517/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7517/comments | https://api.github.com/repos/huggingface/datasets/issues/7517/events | https://github.com/huggingface/datasets/issues/7517 | 2,996,106,077 | I_kwDODunzps6ylPNd | 7,517 | Image Feature in Datasets Library Fails to Handle bytearray Objects from Spark DataFrames | {
"login": "giraffacarp",
"id": 73196164,
"node_id": "MDQ6VXNlcjczMTk2MTY0",
"avatar_url": "https://avatars.githubusercontent.com/u/73196164?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/giraffacarp",
"html_url": "https://github.com/giraffacarp",
"followers_url": "https://api.github.com/... | [] | closed | false | [
{
"login": "giraffacarp",
"id": 73196164,
"node_id": "MDQ6VXNlcjczMTk2MTY0",
"avatar_url": "https://avatars.githubusercontent.com/u/73196164?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/giraffacarp",
"html_url": "https://github.com/giraffacarp",
"followers_url": "htt... | null | [
"Hi ! The `Image()` type accepts either\n- a `bytes` object containing the image bytes\n- a `str` object containing the image path\n- a `PIL.Image` object\n\nbut it doesn't support `bytearray`, maybe you can convert to `bytes` beforehand ?",
"Hi @lhoestq, \nconverting to bytes is certainly possible and would work... | 2025-04-15 11:29:17 | 2025-05-07 14:17:30 | 2025-05-07 14:17:30 | {
"login": "giraffacarp",
"id": 73196164,
"node_id": "MDQ6VXNlcjczMTk2MTY0",
"avatar_url": "https://avatars.githubusercontent.com/u/73196164?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/giraffacarp",
"html_url": "https://github.com/giraffacarp",
"followers_url": "https://api.github.com/... | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When using `IterableDataset.from_spark()` with a Spark DataFrame containing image data, the `Image` feature class fails to properly process this data type, causing an `AttributeError: 'bytearray' object has no attribute 'get'`
### Steps to reproduce the bug
1. Create a Spark DataFrame with a col... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7517/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7517/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7516 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7516/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7516/comments | https://api.github.com/repos/huggingface/datasets/issues/7516/events | https://github.com/huggingface/datasets/issues/7516 | 2,995,780,283 | I_kwDODunzps6yj_q7 | 7,516 | unsloth/DeepSeek-R1-Distill-Qwen-32B server error | {
"login": "Editor-1",
"id": 164353862,
"node_id": "U_kgDOCcvXRg",
"avatar_url": "https://avatars.githubusercontent.com/u/164353862?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Editor-1",
"html_url": "https://github.com/Editor-1",
"followers_url": "https://api.github.com/users/Editor-1/... | [] | closed | false | [] | null | [] | 2025-04-15 09:26:53 | 2025-04-15 09:57:26 | 2025-04-15 09:57:26 | null | NONE | [] | null | null | null | null | ### Describe the bug
hfhubhttperror: 500 server error: internal server error for url: https://huggingface.co/api/models/unsloth/deepseek-r1-distill-qwen-32b-bnb-4bit/commits/main (request id: root=1-67fe23fa-3a2150eb444c2a823c388579;de3aed68-c397-4da5-94d4-6565efd3b919) internal error - we're working hard to fix this ... | {
"login": "Editor-1",
"id": 164353862,
"node_id": "U_kgDOCcvXRg",
"avatar_url": "https://avatars.githubusercontent.com/u/164353862?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Editor-1",
"html_url": "https://github.com/Editor-1",
"followers_url": "https://api.github.com/users/Editor-1/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7516/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7516/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7515 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7515/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7515/comments | https://api.github.com/repos/huggingface/datasets/issues/7515/events | https://github.com/huggingface/datasets/issues/7515 | 2,995,082,418 | I_kwDODunzps6yhVSy | 7,515 | `concatenate_datasets` does not preserve Pytorch format for IterableDataset | {
"login": "francescorubbo",
"id": 5140987,
"node_id": "MDQ6VXNlcjUxNDA5ODc=",
"avatar_url": "https://avatars.githubusercontent.com/u/5140987?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/francescorubbo",
"html_url": "https://github.com/francescorubbo",
"followers_url": "https://api.gith... | [] | closed | false | [] | null | [
"Hi ! Oh indeed it would be cool to return the same format in that case. Would you like to submit a PR ? The function that does the concatenation is here:\n\nhttps://github.com/huggingface/datasets/blob/90e5bf8a8599b625d6103ee5ac83b98269991141/src/datasets/iterable_dataset.py#L3375-L3380",
"Thank you for the poin... | 2025-04-15 04:36:34 | 2025-05-19 15:07:38 | 2025-05-19 15:07:38 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When concatenating datasets with `concatenate_datasets`, I would expect the resulting combined dataset to be in the same format as the inputs (assuming it's consistent). This is indeed the behavior when combining `Dataset`, but not when combining `IterableDataset`. Specifically, when applying `con... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7515/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7515/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7513 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7513/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7513/comments | https://api.github.com/repos/huggingface/datasets/issues/7513/events | https://github.com/huggingface/datasets/issues/7513 | 2,994,678,437 | I_kwDODunzps6yfyql | 7,513 | MemoryError while creating dataset from generator | {
"login": "simonreise",
"id": 43753582,
"node_id": "MDQ6VXNlcjQzNzUzNTgy",
"avatar_url": "https://avatars.githubusercontent.com/u/43753582?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/simonreise",
"html_url": "https://github.com/simonreise",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [
"Upd: created a PR that can probably solve the problem: #7514",
"Hi ! We need to take the generator into account for the cache. The generator is hashed to make the dataset fingerprint used by the cache. This way you can reload the Dataset from the cache without regenerating in subsequent `from_generator` calls.\n... | 2025-04-15 01:02:02 | 2025-10-23 22:55:10 | 2025-10-23 22:55:10 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
# TL:DR
`Dataset.from_generator` function passes all of its arguments to `BuilderConfig.create_config_id`, including `generator` function itself. `BuilderConfig.create_config_id` function tries to hash all the args, which can take a large amount of time or even cause MemoryError if the dataset pr... | {
"login": "simonreise",
"id": 43753582,
"node_id": "MDQ6VXNlcjQzNzUzNTgy",
"avatar_url": "https://avatars.githubusercontent.com/u/43753582?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/simonreise",
"html_url": "https://github.com/simonreise",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7513/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7513/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7512 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7512/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7512/comments | https://api.github.com/repos/huggingface/datasets/issues/7512/events | https://github.com/huggingface/datasets/issues/7512 | 2,994,043,544 | I_kwDODunzps6ydXqY | 7,512 | .map() fails if function uses pyvista | {
"login": "el-hult",
"id": 11832922,
"node_id": "MDQ6VXNlcjExODMyOTIy",
"avatar_url": "https://avatars.githubusercontent.com/u/11832922?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/el-hult",
"html_url": "https://github.com/el-hult",
"followers_url": "https://api.github.com/users/el-hul... | [] | open | false | [] | null | [
"I found a similar (?) issue in https://github.com/huggingface/datasets/issues/6435, where someone had issues with forks and CUDA. According to https://huggingface.co/docs/datasets/main/en/process#multiprocessing we should do \n\n```\nfrom multiprocess import set_start_method\nset_start_method(\"spawn\")\n```\n\nto... | 2025-04-14 19:43:02 | 2025-04-14 20:01:53 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Using PyVista inside a .map() produces a crash with `objc[78796]: +[NSResponder initialize] may have been in progress in another thread when fork() was called. We cannot safely call it or ignore it in the fork() child process. Crashing instead. Set a breakpoint on objc_initializeAfterForkError to ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7512/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7512/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7510 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7510/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7510/comments | https://api.github.com/repos/huggingface/datasets/issues/7510/events | https://github.com/huggingface/datasets/issues/7510 | 2,992,131,117 | I_kwDODunzps6yWEwt | 7,510 | Incompatibile dill version (0.3.9) in datasets 2.18.0 - 3.5.0 | {
"login": "JGrel",
"id": 98061329,
"node_id": "U_kgDOBdhMEQ",
"avatar_url": "https://avatars.githubusercontent.com/u/98061329?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JGrel",
"html_url": "https://github.com/JGrel",
"followers_url": "https://api.github.com/users/JGrel/followers",
... | [] | closed | false | [] | null | [
"Hi ! We can bump `dill` to 0.3.9 if we make sure it's deterministic and doesn't break the caching mechanism in `datasets`.\n\nWould you be interested in opening a PR ? Then we can run the CI to see if it works",
"Hi!. Yeah I can do it. Should I make any changes besides dill versions?",
"There are probably some... | 2025-04-14 07:22:44 | 2025-09-15 08:37:49 | 2025-09-15 08:37:49 | null | NONE | [] | null | null | null | null | ### Describe the bug
Datasets 2.18.0 - 3.5.0 has a dependency on dill < 0.3.9. This causes errors with dill >= 0.3.9.
Could you please take a look into it and make it compatible?
### Steps to reproduce the bug
1. Install setuptools >= 2.18.0
2. Install dill >=0.3.9
3. Run pip check
4. Output:
ERROR: pip's dependenc... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7510/reactions",
"total_count": 3,
"+1": 3,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7510/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7509 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7509/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7509/comments | https://api.github.com/repos/huggingface/datasets/issues/7509/events | https://github.com/huggingface/datasets/issues/7509 | 2,991,484,542 | I_kwDODunzps6yTm5- | 7,509 | Dataset uses excessive memory when loading files | {
"login": "avishaiElmakies",
"id": 36810152,
"node_id": "MDQ6VXNlcjM2ODEwMTUy",
"avatar_url": "https://avatars.githubusercontent.com/u/36810152?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/avishaiElmakies",
"html_url": "https://github.com/avishaiElmakies",
"followers_url": "https://api... | [] | open | false | [] | null | [
"small update: I converted the jsons to parquet and it now works well with 32 proc and the same node. \nI still think this needs to be understood, since json is a very popular and easy-to-use format. ",
"Hi ! The JSON loader loads full files in memory, unless they are JSON Lines. In this case it iterates on the J... | 2025-04-13 21:09:49 | 2025-04-28 15:18:55 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi
I am having an issue when loading a dataset.
I have about 200 json files each about 1GB (total about 215GB). each row has a few features which are a list of ints.
I am trying to load the dataset using `load_dataset`.
The dataset is about 1.5M samples
I use `num_proc=32` and a node with 378GB of... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7509/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7509/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7508 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7508/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7508/comments | https://api.github.com/repos/huggingface/datasets/issues/7508/events | https://github.com/huggingface/datasets/issues/7508 | 2,986,612,934 | I_kwDODunzps6yBBjG | 7,508 | Iterating over Image feature columns is extremely slow | {
"login": "sohamparikh",
"id": 11831521,
"node_id": "MDQ6VXNlcjExODMxNTIx",
"avatar_url": "https://avatars.githubusercontent.com/u/11831521?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sohamparikh",
"html_url": "https://github.com/sohamparikh",
"followers_url": "https://api.github.com/... | [] | open | false | [] | null | [
"Hi ! Could it be because the `Image()` type in dataset does `image = Image.open(image_path)` and also `image.load()` which actually loads the image data in memory ? This is needed to avoid too many open files issues, see https://github.com/huggingface/datasets/issues/3985",
"Yes, that seems to be it. For my pur... | 2025-04-10 19:00:54 | 2025-04-15 17:57:08 | null | null | NONE | [] | null | null | null | null | We are trying to load datasets where the image column stores `PIL.PngImagePlugin.PngImageFile` images. However, iterating over these datasets is extremely slow.
What I have found:
1. It is the presence of the image column that causes the slowdown. Removing the column from the dataset results in blazingly fast (as expe... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7508/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7508/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7507 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7507/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7507/comments | https://api.github.com/repos/huggingface/datasets/issues/7507/events | https://github.com/huggingface/datasets/issues/7507 | 2,984,309,806 | I_kwDODunzps6x4PQu | 7,507 | Front-end statistical data quantity deviation | {
"login": "rangehow",
"id": 88258534,
"node_id": "MDQ6VXNlcjg4MjU4NTM0",
"avatar_url": "https://avatars.githubusercontent.com/u/88258534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/rangehow",
"html_url": "https://github.com/rangehow",
"followers_url": "https://api.github.com/users/ran... | [] | open | false | [] | null | [
"Hi ! the format of this dataset is not supported by the Dataset Viewer. It looks like this dataset was saved using `save_to_disk()` which is meant for local storage / easy reload without compression, not for sharing online."
] | 2025-04-10 02:51:38 | 2025-04-15 12:54:51 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
While browsing the dataset at https://huggingface.co/datasets/NeuML/wikipedia-20250123, I noticed that a dataset with nearly 7M entries was estimated to be only 4M in size—almost half the actual amount. According to the post-download loading and the dataset_info (https://huggingface.co/datasets/Ne... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7507/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7507/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7506 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7506/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7506/comments | https://api.github.com/repos/huggingface/datasets/issues/7506/events | https://github.com/huggingface/datasets/issues/7506 | 2,981,687,450 | I_kwDODunzps6xuPCa | 7,506 | HfHubHTTPError: 429 Client Error: Too Many Requests for URL when trying to access Fineweb-10BT on 4A100 GPUs using SLURM | {
"login": "calvintanama",
"id": 66202555,
"node_id": "MDQ6VXNlcjY2MjAyNTU1",
"avatar_url": "https://avatars.githubusercontent.com/u/66202555?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/calvintanama",
"html_url": "https://github.com/calvintanama",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [
"Hi ! make sure to be logged in with your HF account (e.g. using `huggingface-cli login` or passing `token=` to `load_dataset()`), otherwise you'll get rate limited at one point",
"Hey @calvintanama! Just building on what @lhoestq mentioned above — I ran into similar issues in multi-GPU SLURM setups and here’s wh... | 2025-04-09 06:32:04 | 2025-06-29 06:04:59 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to run some finetunings on 4 A100 GPUs using SLURM using axolotl training framework which in turn uses Huggingface's Trainer and Accelerate on [Fineweb-10BT](https://huggingface.co/datasets/HuggingFaceFW/fineweb), but I end up running into 429 Client Error: Too Many Requests for URL er... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7506/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7506/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7505 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7505/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7505/comments | https://api.github.com/repos/huggingface/datasets/issues/7505/events | https://github.com/huggingface/datasets/issues/7505 | 2,979,926,156 | I_kwDODunzps6xnhCM | 7,505 | HfHubHTTPError: 403 Forbidden: None. Cannot access content at: https://hf.co/api/s3proxy | {
"login": "hissain",
"id": 1412262,
"node_id": "MDQ6VXNlcjE0MTIyNjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/1412262?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/hissain",
"html_url": "https://github.com/hissain",
"followers_url": "https://api.github.com/users/hissain/... | [] | open | false | [] | null | [] | 2025-04-08 14:08:40 | 2025-04-08 14:08:40 | null | null | NONE | [] | null | null | null | null | I have already logged in Huggingface using CLI with my valid token. Now trying to download the datasets using following code:
from transformers import WhisperProcessor, WhisperForConditionalGeneration, WhisperTokenizer, Trainer, TrainingArguments, DataCollatorForSeq2Seq
from datasets import load_dataset, Data... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7505/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7505/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7504 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7504/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7504/comments | https://api.github.com/repos/huggingface/datasets/issues/7504/events | https://github.com/huggingface/datasets/issues/7504 | 2,979,410,641 | I_kwDODunzps6xljLR | 7,504 | BuilderConfig ParquetConfig(...) doesn't have a 'use_auth_token' key. | {
"login": "tteguayco",
"id": 20015750,
"node_id": "MDQ6VXNlcjIwMDE1NzUw",
"avatar_url": "https://avatars.githubusercontent.com/u/20015750?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/tteguayco",
"html_url": "https://github.com/tteguayco",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"I encountered the same error, have you resolved it?",
"Hi ! `use_auth_token` has been deprecated and removed some time ago. You should use `token` instead in `load_dataset()`",
"Hi @lhoestq, I'd like to take this up.\n\nAs discussed in #7504, the issue arises when `use_auth_token` is passed to `load_dataset`, ... | 2025-04-08 10:55:03 | 2025-06-28 09:18:09 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Trying to run the following fine-tuning script (based on this page [here](https://github.com/huggingface/instruction-tuned-sd)):
```
! accelerate launch /content/instruction-tuned-sd/finetune_instruct_pix2pix.py \
--pretrained_model_name_or_path=${MODEL_ID} \
--dataset_name=${DATASET_NAME... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7504/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7504/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7503 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7503/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7503/comments | https://api.github.com/repos/huggingface/datasets/issues/7503/events | https://github.com/huggingface/datasets/issues/7503 | 2,978,512,625 | I_kwDODunzps6xiH7x | 7,503 | Inconsistency between load_dataset and load_from_disk functionality | {
"login": "zzzzzec",
"id": 60975422,
"node_id": "MDQ6VXNlcjYwOTc1NDIy",
"avatar_url": "https://avatars.githubusercontent.com/u/60975422?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/zzzzzec",
"html_url": "https://github.com/zzzzzec",
"followers_url": "https://api.github.com/users/zzzzze... | [] | open | false | [] | null | [
"Hi ! you can find more info here: https://github.com/huggingface/datasets/issues/5044#issuecomment-1263714347\n\n> What's the recommended approach for this use case? Should I manually process my gsm8k-new dataset to make it compatible with load_dataset? Is there a standard way to convert between these formats?\n\n... | 2025-04-08 03:46:22 | 2025-06-28 08:51:16 | null | null | NONE | [] | null | null | null | null | ## Issue Description
I've encountered confusion when using `load_dataset` and `load_from_disk` in the datasets library. Specifically, when working offline with the gsm8k dataset, I can load it using a local path:
```python
import datasets
ds = datasets.load_dataset('/root/xxx/datasets/gsm8k', 'main')
```
output:
```t... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7503/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7503/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7502 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7502/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7502/comments | https://api.github.com/repos/huggingface/datasets/issues/7502/events | https://github.com/huggingface/datasets/issues/7502 | 2,977,453,814 | I_kwDODunzps6xeFb2 | 7,502 | `load_dataset` of size 40GB creates a cache of >720GB | {
"login": "pietrolesci",
"id": 61748653,
"node_id": "MDQ6VXNlcjYxNzQ4NjUz",
"avatar_url": "https://avatars.githubusercontent.com/u/61748653?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/pietrolesci",
"html_url": "https://github.com/pietrolesci",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"Hi ! Parquet is a compressed format. When you load a dataset, it uncompresses the Parquet data into Arrow data on your disk. That's why you can indeed end up with 720GB of uncompressed data on disk. The uncompression is needed to enable performant dataset objects (especially for random access).\n\nTo save some sto... | 2025-04-07 16:52:34 | 2025-04-15 15:22:12 | 2025-04-15 15:22:11 | null | NONE | [] | null | null | null | null | Hi there,
I am trying to load a dataset from the Hugging Face Hub and split it into train and validation splits. Somehow, when I try to do it with `load_dataset`, it exhausts my disk quota. So, I tried manually downloading the parquet files from the hub and loading them as follows:
```python
ds = DatasetDict(
... | {
"login": "pietrolesci",
"id": 61748653,
"node_id": "MDQ6VXNlcjYxNzQ4NjUz",
"avatar_url": "https://avatars.githubusercontent.com/u/61748653?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/pietrolesci",
"html_url": "https://github.com/pietrolesci",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7502/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7502/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7501 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7501/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7501/comments | https://api.github.com/repos/huggingface/datasets/issues/7501/events | https://github.com/huggingface/datasets/issues/7501 | 2,976,721,014 | I_kwDODunzps6xbSh2 | 7,501 | Nested Feature raises ArrowNotImplementedError: Unsupported cast using function cast_struct | {
"login": "yaner-here",
"id": 26623948,
"node_id": "MDQ6VXNlcjI2NjIzOTQ4",
"avatar_url": "https://avatars.githubusercontent.com/u/26623948?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yaner-here",
"html_url": "https://github.com/yaner-here",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [
"Solved by the default `load_dataset(features)` parameters. Do not use `Sequence` for the `list` in `list[any]` json schema, just simply use `[]`. For example, `\"b\": Sequence({...})` fails but `\"b\": [{...}]` works fine."
] | 2025-04-07 12:35:39 | 2025-04-07 12:43:04 | 2025-04-07 12:43:03 | null | NONE | [] | null | null | null | null | ### Describe the bug
`datasets.Features` seems to be unable to handle json file that contains fields of `list[dict]`.
### Steps to reproduce the bug
```json
// test.json
{"a": 1, "b": [{"c": 2, "d": 3}, {"c": 4, "d": 5}]}
{"a": 5, "b": [{"c": 7, "d": 8}, {"c": 9, "d": 10}]}
```
```python
import json
from datasets i... | {
"login": "yaner-here",
"id": 26623948,
"node_id": "MDQ6VXNlcjI2NjIzOTQ4",
"avatar_url": "https://avatars.githubusercontent.com/u/26623948?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yaner-here",
"html_url": "https://github.com/yaner-here",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7501/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7501/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7500 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7500/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7500/comments | https://api.github.com/repos/huggingface/datasets/issues/7500/events | https://github.com/huggingface/datasets/issues/7500 | 2,974,841,921 | I_kwDODunzps6xUHxB | 7,500 | Make `with_format` correctly indicate that a `Dataset` is compatible with PyTorch's `Dataset` class | {
"login": "benglewis",
"id": 3817460,
"node_id": "MDQ6VXNlcjM4MTc0NjA=",
"avatar_url": "https://avatars.githubusercontent.com/u/3817460?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/benglewis",
"html_url": "https://github.com/benglewis",
"followers_url": "https://api.github.com/users/be... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Does the torch `DataLoader` really require the dataset to be a subclass of `torch.utils.data.Dataset` ? Or is there a simpler type we could use ?\n\nPS: also note that a dataset without `with_format()` can also be used in a torch `DataLoader` . Calling `with_format(\"torch\")` simply makes the output of the datase... | 2025-04-06 09:56:09 | 2026-08-09 23:15:15 | null | null | NONE | [] | null | null | null | null | ### Feature request
Currently `datasets` does not correctly indicate to the Python type-checker (e.g. `pyright` / `Pylance`) that the output of `with_format` is compatible with PyTorch's `Dataloader` since it does not indicate that the HuggingFace `Dataset` is compatible with the PyTorch `Dataset` class. It would be g... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7500/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7500/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7498 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7498/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7498/comments | https://api.github.com/repos/huggingface/datasets/issues/7498/events | https://github.com/huggingface/datasets/issues/7498 | 2,969,218,273 | I_kwDODunzps6w-qzh | 7,498 | Extreme memory bandwidth. | {
"login": "J0SZ",
"id": 185079645,
"node_id": "U_kgDOCwgXXQ",
"avatar_url": "https://avatars.githubusercontent.com/u/185079645?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/J0SZ",
"html_url": "https://github.com/J0SZ",
"followers_url": "https://api.github.com/users/J0SZ/followers",
"f... | [] | open | false | [] | null | [] | 2025-04-03 11:09:08 | 2025-04-03 11:11:22 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When I use hf datasets on 4 GPU with 40 workers I get some extreme memory bandwidth of constant ~3GB/s.
However, if I wrap the dataset in `IterableDataset`, this issue is gone and the data also loads way faster (4x faster training on 1 worker).
It seems like the workers don't share memory and b... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7498/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7498/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7497 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7497/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7497/comments | https://api.github.com/repos/huggingface/datasets/issues/7497/events | https://github.com/huggingface/datasets/issues/7497 | 2,968,553,693 | I_kwDODunzps6w8Ijd | 7,497 | How to convert videos to images? | {
"login": "Loki-Lu",
"id": 171649931,
"node_id": "U_kgDOCjsriw",
"avatar_url": "https://avatars.githubusercontent.com/u/171649931?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Loki-Lu",
"html_url": "https://github.com/Loki-Lu",
"followers_url": "https://api.github.com/users/Loki-Lu/foll... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! there is some documentation here on how to read video frames: https://huggingface.co/docs/datasets/video_load"
] | 2025-04-03 07:08:39 | 2025-04-15 12:35:15 | null | null | NONE | [] | null | null | null | null | ### Feature request
Does someone know how to return the images from videos?
### Motivation
I am trying to use openpi(https://github.com/Physical-Intelligence/openpi) to finetune my Lerobot dataset(V2.0 and V2.1). I find that although the codedaset is v2.0, they are different. It seems like Lerobot V2.0 has two versi... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7497/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7497/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7496 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7496/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7496/comments | https://api.github.com/repos/huggingface/datasets/issues/7496/events | https://github.com/huggingface/datasets/issues/7496 | 2,967,345,522 | I_kwDODunzps6w3hly | 7,496 | Json builder: Allow features to override problematic Arrow types | {
"login": "edmcman",
"id": 1017189,
"node_id": "MDQ6VXNlcjEwMTcxODk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1017189?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/edmcman",
"html_url": "https://github.com/edmcman",
"followers_url": "https://api.github.com/users/edmcman/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! It would be cool indeed, currently the JSON data are generally loaded here: \n\nhttps://github.com/huggingface/datasets/blob/90e5bf8a8599b625d6103ee5ac83b98269991141/src/datasets/packaged_modules/json/json.py#L137-L140\n\nMaybe we can pass a Arrow `schema` to avoid errors ?"
] | 2025-04-02 19:27:16 | 2025-04-15 13:06:09 | null | null | NONE | [] | null | null | null | null | ### Feature request
In the JSON builder, use explicitly requested feature types before or while converting to Arrow.
### Motivation
Working with JSON datasets is really hard because of Arrow. At the very least, it seems like it should be possible to work-around these problems by explicitly setting problematic colum... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7496/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7496/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7495 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7495/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7495/comments | https://api.github.com/repos/huggingface/datasets/issues/7495/events | https://github.com/huggingface/datasets/issues/7495 | 2,967,034,060 | I_kwDODunzps6w2VjM | 7,495 | Columns in the dataset obtained though load_dataset do not correspond to the one in the dataset viewer since 3.4.0 | {
"login": "bruno-hays",
"id": 48770768,
"node_id": "MDQ6VXNlcjQ4NzcwNzY4",
"avatar_url": "https://avatars.githubusercontent.com/u/48770768?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bruno-hays",
"html_url": "https://github.com/bruno-hays",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [
"Hi, the dataset viewer shows all the possible columns and their types, but `load_dataset()` iterates through all the columns that you defined. It seems that you only have one column (‘audio’) defined in your dataset because when I ran `print(ds.column_names)`, the only name I got was “audio”. You need to clearly d... | 2025-04-02 17:01:11 | 2025-07-02 23:24:57 | 2025-07-02 23:24:57 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I have noticed that on my dataset named [BrunoHays/Accueil_UBS](https://huggingface.co/datasets/BrunoHays/Accueil_UBS), since the version 3.4.0, every column except audio is missing when I load the dataset.
Interestingly, the dataset viewer still shows the correct columns
### Steps to reproduce ... | {
"login": "bruno-hays",
"id": 48770768,
"node_id": "MDQ6VXNlcjQ4NzcwNzY4",
"avatar_url": "https://avatars.githubusercontent.com/u/48770768?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bruno-hays",
"html_url": "https://github.com/bruno-hays",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7495/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7495/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7494 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7494/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7494/comments | https://api.github.com/repos/huggingface/datasets/issues/7494/events | https://github.com/huggingface/datasets/issues/7494 | 2,965,347,685 | I_kwDODunzps6wv51l | 7,494 | Broken links in pdf loading documentation | {
"login": "VyoJ",
"id": 75789232,
"node_id": "MDQ6VXNlcjc1Nzg5MjMy",
"avatar_url": "https://avatars.githubusercontent.com/u/75789232?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/VyoJ",
"html_url": "https://github.com/VyoJ",
"followers_url": "https://api.github.com/users/VyoJ/followers"... | [] | closed | false | [] | null | [
"thanks for reporting ! I fixed the links, the docs will be updated in the next release"
] | 2025-04-02 06:45:22 | 2025-04-15 13:36:25 | 2025-04-15 13:36:04 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi, just a couple of small issues I ran into while reading the docs for [loading pdf data](https://huggingface.co/docs/datasets/main/en/document_load):
1. The link for the [`Create a pdf dataset`](https://huggingface.co/docs/datasets/main/en/document_load#pdffolder) points to https://huggingface.... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7494/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7494/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7493 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7493/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7493/comments | https://api.github.com/repos/huggingface/datasets/issues/7493/events | https://github.com/huggingface/datasets/issues/7493 | 2,964,025,179 | I_kwDODunzps6wq29b | 7,493 | push_to_hub does not upload videos | {
"login": "DominikVincent",
"id": 9339403,
"node_id": "MDQ6VXNlcjkzMzk0MDM=",
"avatar_url": "https://avatars.githubusercontent.com/u/9339403?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DominikVincent",
"html_url": "https://github.com/DominikVincent",
"followers_url": "https://api.gith... | [] | closed | false | [] | null | [
"Hi ! the `Video` type is still experimental, and in particular `push_to_hub` doesn't upload videos at the moment (only the paths).\n\nThere is an open question to either upload the videos inside the Parquet files, or rather have them as separate files (which is great to enable remote seeking/streaming)",
"im hav... | 2025-04-01 17:00:20 | 2026-01-29 18:59:38 | 2026-01-29 18:56:05 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hello,
I would like to upload a video dataset (some .mp4 files and some segments within them), i.e. rows correspond to subsequences from videos. Videos might be referenced by several rows.
I created a dataset locally and it references the videos and the video readers can read them correctly. I u... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7493/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7493/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7486 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7486/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7486/comments | https://api.github.com/repos/huggingface/datasets/issues/7486/events | https://github.com/huggingface/datasets/issues/7486 | 2,954,042,179 | I_kwDODunzps6wExtD | 7,486 | `shared_datadir` fixture is missing | {
"login": "lahwaacz",
"id": 1289205,
"node_id": "MDQ6VXNlcjEyODkyMDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/1289205?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lahwaacz",
"html_url": "https://github.com/lahwaacz",
"followers_url": "https://api.github.com/users/lahwa... | [] | closed | false | [] | null | [
"OK I was missing the `pytest-datadir` package. Sorry for the noise!"
] | 2025-03-27 18:17:12 | 2025-03-27 19:49:11 | 2025-03-27 19:49:10 | null | NONE | [] | null | null | null | null | ### Describe the bug
Running the tests for the latest release fails due to missing `shared_datadir` fixture.
### Steps to reproduce the bug
Running `pytest` while building a package for Arch Linux leads to these errors:
```
==================================== ERRORS ====================================
_________ E... | {
"login": "lahwaacz",
"id": 1289205,
"node_id": "MDQ6VXNlcjEyODkyMDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/1289205?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lahwaacz",
"html_url": "https://github.com/lahwaacz",
"followers_url": "https://api.github.com/users/lahwa... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7486/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7486/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7481 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7481/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7481/comments | https://api.github.com/repos/huggingface/datasets/issues/7481/events | https://github.com/huggingface/datasets/issues/7481 | 2,950,692,971 | I_kwDODunzps6v4ABr | 7,481 | deal with python `10_000` legal number in slice syntax | {
"login": "sfc-gh-sbekman",
"id": 196988264,
"node_id": "U_kgDOC73NaA",
"avatar_url": "https://avatars.githubusercontent.com/u/196988264?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sfc-gh-sbekman",
"html_url": "https://github.com/sfc-gh-sbekman",
"followers_url": "https://api.github.c... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"should be an easy fix, I opened a PR"
] | 2025-03-26 20:10:54 | 2025-03-28 16:20:44 | 2025-03-28 16:20:44 | null | NONE | [] | null | null | null | null | ### Feature request
```
In [6]: ds = datasets.load_dataset("HuggingFaceH4/ultrachat_200k", split="train_sft[:1000]")
In [7]: ds = datasets.load_dataset("HuggingFaceH4/ultrachat_200k", split="train_sft[:1_000]")
[dozens of frames skipped]
File /usr/local/lib/python3.10/dist-packages/datasets/arrow_reader.py:444, in _s... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7481/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7481/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7480 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7480/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7480/comments | https://api.github.com/repos/huggingface/datasets/issues/7480/events | https://github.com/huggingface/datasets/issues/7480 | 2,950,315,214 | I_kwDODunzps6v2jzO | 7,480 | HF_DATASETS_CACHE ignored? | {
"login": "stephenroller",
"id": 31896,
"node_id": "MDQ6VXNlcjMxODk2",
"avatar_url": "https://avatars.githubusercontent.com/u/31896?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stephenroller",
"html_url": "https://github.com/stephenroller",
"followers_url": "https://api.github.com/user... | [] | open | false | [] | null | [
"FWIW, it does eventually write to /tmp/roller/datasets when generating the final version.",
"Hey, I’d love to work on this issue but I am a beginner, can I work it with you?",
"Hi @lhoestq,\nI'd like to look into this issue but I'm still learning. Could you share any quick pointers on the HF_DATASETS_CACHE beh... | 2025-03-26 17:19:34 | 2026-05-10 12:02:42 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm struggling to get things to respect HF_DATASETS_CACHE.
Rationale: I'm on a system that uses NFS for homedir, so downloading to NFS is expensive, slow, and wastes valuable quota compared to local disk. Instead, it seems to rely mostly on HF_HUB_CACHE.
Current version: 3.2.1dev. In the process... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7480/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7480/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7479 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7479/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7479/comments | https://api.github.com/repos/huggingface/datasets/issues/7479/events | https://github.com/huggingface/datasets/issues/7479 | 2,950,235,396 | I_kwDODunzps6v2QUE | 7,479 | Features.from_arrow_schema is destructive | {
"login": "BramVanroy",
"id": 2779410,
"node_id": "MDQ6VXNlcjI3Nzk0MTA=",
"avatar_url": "https://avatars.githubusercontent.com/u/2779410?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/BramVanroy",
"html_url": "https://github.com/BramVanroy",
"followers_url": "https://api.github.com/users... | [] | open | false | [] | null | [
"The `schema=` passthrough discussed above is undone by the `Dataset` constructor, which I think is the piece that was missing from the earlier analysis.\n\n`src/datasets/arrow_dataset.py` (currently lines 766-767):\n\n```python\nif self.data.schema != self.info.features.arrow_schema:\n self._data = self.data.ca... | 2025-03-26 16:46:43 | 2026-08-18 09:45:29 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I came across this, perhaps niche, bug where `Features` does not/cannot account for pyarrow's `nullable=False` option in Fields. Interestingly, I found that in regular "flat" fields this does not necessarily lead to conflicts, but when a non-nullable field is in a struct, an incompatibility arises... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7479/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7479/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7477 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7477/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7477/comments | https://api.github.com/repos/huggingface/datasets/issues/7477/events | https://github.com/huggingface/datasets/issues/7477 | 2,947,169,460 | I_kwDODunzps6vqjy0 | 7,477 | What is the canonical way to compress a Dataset? | {
"login": "eric-czech",
"id": 6130352,
"node_id": "MDQ6VXNlcjYxMzAzNTI=",
"avatar_url": "https://avatars.githubusercontent.com/u/6130352?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/eric-czech",
"html_url": "https://github.com/eric-czech",
"followers_url": "https://api.github.com/users... | [] | open | false | [] | null | [
"I saw this post by @lhoestq: https://discuss.huggingface.co/t/increased-arrow-table-size-by-factor-of-2/26561/4 suggesting that there is at least some internal code for writing sharded parquet datasets non-concurrently. This appears to be that code: https://github.com/huggingface/datasets/blob/94ccd1b4fada8a92cea... | 2025-03-25 16:47:51 | 2025-04-03 09:13:11 | null | null | NONE | [] | null | null | null | null | Given that Arrow is the preferred backend for a Dataset, what is a user supposed to do if they want concurrent reads, concurrent writes AND on-disk compression for a larger dataset?
Parquet would be the obvious answer except that there is no native support for writing sharded, parquet datasets concurrently [[1](https:... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7477/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7477/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7475 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7475/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7475/comments | https://api.github.com/repos/huggingface/datasets/issues/7475/events | https://github.com/huggingface/datasets/issues/7475 | 2,946,640,570 | I_kwDODunzps6voiq6 | 7,475 | IterableDataset's state_dict shard_example_idx is always equal to the number of samples in a shard | {
"login": "bruno-hays",
"id": 48770768,
"node_id": "MDQ6VXNlcjQ4NzcwNzY4",
"avatar_url": "https://avatars.githubusercontent.com/u/48770768?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bruno-hays",
"html_url": "https://github.com/bruno-hays",
"followers_url": "https://api.github.com/use... | [] | closed | false | [
{
"login": "Harry-Yang0518",
"id": 129883215,
"node_id": "U_kgDOB73cTw",
"avatar_url": "https://avatars.githubusercontent.com/u/129883215?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Harry-Yang0518",
"html_url": "https://github.com/Harry-Yang0518",
"followers_url": "... | null | [
"Hey, I’d love to work on this issue but I am a beginner, can I work it with you?",
"Hello. I'm sorry but I don't have much time to get in the details for now.\nHave you managed to reproduce the issue with the code provided ?\nIf you want to work on it, you can self-assign and ask @lhoestq for directions",
"Hi ... | 2025-03-25 13:58:07 | 2025-12-12 16:15:37 | 2025-05-06 14:05:07 | {
"login": "Harry-Yang0518",
"id": 129883215,
"node_id": "U_kgDOB73cTw",
"avatar_url": "https://avatars.githubusercontent.com/u/129883215?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Harry-Yang0518",
"html_url": "https://github.com/Harry-Yang0518",
"followers_url": "https://api.github.c... | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
I've noticed a strange behaviour with Iterable state_dict: the value of shard_example_idx is always equal to the amount of samples in a shard.
### Steps to reproduce the bug
I am reusing the example from the doc
```python
from datasets import Dataset
ds = Dataset.from_dict({"a": range(6)}).to_... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7475/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7475/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7473 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7473/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7473/comments | https://api.github.com/repos/huggingface/datasets/issues/7473/events | https://github.com/huggingface/datasets/issues/7473 | 2,939,034,643 | I_kwDODunzps6vLhwT | 7,473 | Webdataset data format problem | {
"login": "edmcman",
"id": 1017189,
"node_id": "MDQ6VXNlcjEwMTcxODk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1017189?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/edmcman",
"html_url": "https://github.com/edmcman",
"followers_url": "https://api.github.com/users/edmcman/... | [] | closed | false | [] | null | [
"I was able to work around it"
] | 2025-03-21 17:23:52 | 2025-03-21 19:19:58 | 2025-03-21 19:19:58 | null | NONE | [] | null | null | null | null | ### Describe the bug
Please see https://huggingface.co/datasets/ejschwartz/idioms/discussions/1
Error code: FileFormatMismatchBetweenSplitsError
All three splits, train, test, and validation, use webdataset. But only the train split has more than one file. How can I force the other two splits to also be interpreted ... | {
"login": "edmcman",
"id": 1017189,
"node_id": "MDQ6VXNlcjEwMTcxODk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1017189?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/edmcman",
"html_url": "https://github.com/edmcman",
"followers_url": "https://api.github.com/users/edmcman/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7473/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7473/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7472 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7472/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7472/comments | https://api.github.com/repos/huggingface/datasets/issues/7472/events | https://github.com/huggingface/datasets/issues/7472 | 2,937,607,272 | I_kwDODunzps6vGFRo | 7,472 | Label casting during `map` process is canceled after the `map` process | {
"login": "yoshitomo-matsubara",
"id": 11156001,
"node_id": "MDQ6VXNlcjExMTU2MDAx",
"avatar_url": "https://avatars.githubusercontent.com/u/11156001?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yoshitomo-matsubara",
"html_url": "https://github.com/yoshitomo-matsubara",
"followers_url": ... | [] | closed | false | [] | null | [
"Hi ! By default `map()` tries to keep the types of each column of the dataset, so here it reuses the int type since all your float values can be converted to integers. But I agree it would be nice to store float values as float values and don't try to reuse the same type in this case.\n\nIn the meantime, you can e... | 2025-03-21 07:56:22 | 2025-04-10 05:11:15 | 2025-04-10 05:11:14 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When preprocessing a multi-label dataset, I introduced a step to convert int labels to float labels as [BCEWithLogitsLoss](https://pytorch.org/docs/stable/generated/torch.nn.BCEWithLogitsLoss.html) expects float labels and forward function of models in transformers package internally use `BCEWithL... | {
"login": "yoshitomo-matsubara",
"id": 11156001,
"node_id": "MDQ6VXNlcjExMTU2MDAx",
"avatar_url": "https://avatars.githubusercontent.com/u/11156001?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yoshitomo-matsubara",
"html_url": "https://github.com/yoshitomo-matsubara",
"followers_url": ... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7472/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7472/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7471 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7471/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7471/comments | https://api.github.com/repos/huggingface/datasets/issues/7471/events | https://github.com/huggingface/datasets/issues/7471 | 2,937,530,069 | I_kwDODunzps6vFybV | 7,471 | Adding argument to `_get_data_files_patterns` | {
"login": "SangbumChoi",
"id": 34004152,
"node_id": "MDQ6VXNlcjM0MDA0MTUy",
"avatar_url": "https://avatars.githubusercontent.com/u/34004152?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SangbumChoi",
"html_url": "https://github.com/SangbumChoi",
"followers_url": "https://api.github.com/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi ! The pattern can be specified in advance in YAML in the README.md of the dataset :)\n\nFor example\n\n```\n---\nconfigs:\n- config_name: default\n data_files:\n - split: train\n path: \"train/*\"\n - split: test\n path: \"test/*\"\n---\n```\n\nSee the docs at https://huggingface.co/docs/hub/en/dataset... | 2025-03-21 07:17:53 | 2025-03-27 12:30:52 | 2025-03-26 07:26:27 | null | NONE | [] | null | null | null | null | ### Feature request
How about adding if the user already know about the pattern?
https://github.com/huggingface/datasets/blob/a256b85cbc67aa3f0e75d32d6586afc507cf535b/src/datasets/data_files.py#L252
### Motivation
While using this load_dataset people might use 10M of images for the local files.
However, due to sear... | {
"login": "SangbumChoi",
"id": 34004152,
"node_id": "MDQ6VXNlcjM0MDA0MTUy",
"avatar_url": "https://avatars.githubusercontent.com/u/34004152?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SangbumChoi",
"html_url": "https://github.com/SangbumChoi",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7471/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7471/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7470 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7470/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7470/comments | https://api.github.com/repos/huggingface/datasets/issues/7470/events | https://github.com/huggingface/datasets/issues/7470 | 2,937,236,323 | I_kwDODunzps6vEqtj | 7,470 | Is it possible to shard a single-sharded IterableDataset? | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | [] | closed | false | [] | null | [
"Hi ! Maybe you can look for an option in your dataset to partition your data based on a deterministic filter ? For example each worker could stream the data based on `row.id % num_shards` or something like that ?",
"So the recommendation is to start out with multiple shards initially and re-sharding after is not... | 2025-03-21 04:33:37 | 2025-11-22 07:55:43 | 2025-03-26 06:49:28 | null | NONE | [] | null | null | null | null | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7470/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7470/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7469 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7469/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7469/comments | https://api.github.com/repos/huggingface/datasets/issues/7469/events | https://github.com/huggingface/datasets/issues/7469 | 2,936,606,080 | I_kwDODunzps6vCQ2A | 7,469 | Custom split name with the web interface | {
"login": "vince62s",
"id": 15141326,
"node_id": "MDQ6VXNlcjE1MTQxMzI2",
"avatar_url": "https://avatars.githubusercontent.com/u/15141326?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vince62s",
"html_url": "https://github.com/vince62s",
"followers_url": "https://api.github.com/users/vin... | [] | closed | false | [] | null | [] | 2025-03-20 20:45:59 | 2025-03-21 07:20:37 | 2025-03-21 07:20:37 | null | NONE | [] | null | null | null | null | ### Describe the bug
According the doc here: https://huggingface.co/docs/hub/datasets-file-names-and-splits#custom-split-name
it should infer the split name from the subdir of data or the beg of the name of the files in data.
When doing this manually through web upload it does not work. it uses "train" as a unique spl... | {
"login": "vince62s",
"id": 15141326,
"node_id": "MDQ6VXNlcjE1MTQxMzI2",
"avatar_url": "https://avatars.githubusercontent.com/u/15141326?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vince62s",
"html_url": "https://github.com/vince62s",
"followers_url": "https://api.github.com/users/vin... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7469/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7469/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7468 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7468/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7468/comments | https://api.github.com/repos/huggingface/datasets/issues/7468/events | https://github.com/huggingface/datasets/issues/7468 | 2,934,094,103 | I_kwDODunzps6u4rkX | 7,468 | function `load_dataset` can't solve folder path with regex characters like "[]" | {
"login": "Hpeox",
"id": 89294013,
"node_id": "MDQ6VXNlcjg5Mjk0MDEz",
"avatar_url": "https://avatars.githubusercontent.com/u/89294013?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Hpeox",
"html_url": "https://github.com/Hpeox",
"followers_url": "https://api.github.com/users/Hpeox/follow... | [] | open | false | [] | null | [
"Hi ! Have you tried escaping the glob special characters `[` and `]` ?\n\nbtw note that`AbstractFileSystem.glob` doesn't support regex, instead it supports glob patterns as in the python library [glob](https://docs.python.org/3/library/glob.html)\n"
] | 2025-03-20 05:21:59 | 2025-03-25 10:18:12 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When using the `load_dataset` function with a folder path containing regex special characters (such as "[]"), the issue occurs due to how the path is handled in the `resolve_pattern` function. This function passes the unprocessed path directly to `AbstractFileSystem.glob`, which supports regular e... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7468/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7468/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7467 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7467/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7467/comments | https://api.github.com/repos/huggingface/datasets/issues/7467/events | https://github.com/huggingface/datasets/issues/7467 | 2,930,067,107 | I_kwDODunzps6upUaj | 7,467 | load_dataset with streaming hangs on parquet datasets | {
"login": "The0nix",
"id": 10550252,
"node_id": "MDQ6VXNlcjEwNTUwMjUy",
"avatar_url": "https://avatars.githubusercontent.com/u/10550252?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/The0nix",
"html_url": "https://github.com/The0nix",
"followers_url": "https://api.github.com/users/The0ni... | [] | closed | false | [] | null | [
"Hi ! The issue comes from `pyarrow`, I reported it here: https://github.com/apache/arrow/issues/45214 (feel free to comment / thumb up).\n\nAlternatively we can try to find something else than `ParquetFileFragment.to_batches()` to iterate on Parquet data and keep the option the pass `filters=`...",
"I pushed a w... | 2025-03-18 23:33:54 | 2026-05-06 16:07:14 | 2026-05-06 16:06:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
When I try to load a dataset with parquet files (e.g. "bigcode/the-stack") the dataset loads, but python interpreter can't exit and hangs
### Steps to reproduce the bug
```python3
import datasets
print('Start')
dataset = datasets.load_dataset("bigcode/the-stack", data_dir="data/yaml", streaming... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7467/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7467/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7461 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7461/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7461/comments | https://api.github.com/repos/huggingface/datasets/issues/7461/events | https://github.com/huggingface/datasets/issues/7461 | 2,925,608,123 | I_kwDODunzps6uYTy7 | 7,461 | List of images behave differently on IterableDataset and Dataset | {
"login": "FredrikNoren",
"id": 1288009,
"node_id": "MDQ6VXNlcjEyODgwMDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1288009?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/FredrikNoren",
"html_url": "https://github.com/FredrikNoren",
"followers_url": "https://api.github.com... | [] | closed | false | [] | null | [
"Hi ! Can you try with `datasets` ^3.4 released recently ? on my side it works with IterableDataset on the recent version :)\n\n```python\nIn [20]: def train_iterable_gen():\n ...: images = np.array(load_image(\"https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg\")... | 2025-03-17 15:59:23 | 2025-03-18 08:57:17 | 2025-03-18 08:57:16 | null | NONE | [] | null | null | null | null | ### Describe the bug
This code:
```python
def train_iterable_gen():
images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((128, 128)))
yield {
"images": np.expand_dims(images, axis=0),
"messages": [
... | {
"login": "FredrikNoren",
"id": 1288009,
"node_id": "MDQ6VXNlcjEyODgwMDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1288009?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/FredrikNoren",
"html_url": "https://github.com/FredrikNoren",
"followers_url": "https://api.github.com... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7461/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7461/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7458 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7458/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7458/comments | https://api.github.com/repos/huggingface/datasets/issues/7458/events | https://github.com/huggingface/datasets/issues/7458 | 2,925,403,528 | I_kwDODunzps6uXh2I | 7,458 | Loading the `laion/filtered-wit` dataset in streaming mode fails on v3.4.0 | {
"login": "nikita-savelyevv",
"id": 23343961,
"node_id": "MDQ6VXNlcjIzMzQzOTYx",
"avatar_url": "https://avatars.githubusercontent.com/u/23343961?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikita-savelyevv",
"html_url": "https://github.com/nikita-savelyevv",
"followers_url": "https://... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | [
"thanks for reporting, I released 3.4.1 with a fix"
] | 2025-03-17 14:54:02 | 2025-03-17 16:02:04 | 2025-03-17 15:25:55 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | NONE | [] | null | null | null | null | ### Describe the bug
Loading https://huggingface.co/datasets/laion/filtered-wit in streaming mode fails after update to `datasets==3.4.0`. The dataset loads fine on v3.3.2.
### Steps to reproduce the bug
Steps to reproduce:
```
pip install datastes==3.4.0
python -c "from datasets import load_dataset; load_dataset('l... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7458/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7458/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7457 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7457/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7457/comments | https://api.github.com/repos/huggingface/datasets/issues/7457/events | https://github.com/huggingface/datasets/issues/7457 | 2,924,886,467 | I_kwDODunzps6uVjnD | 7,457 | Document the HF_DATASETS_CACHE env variable | {
"login": "LSerranoPEReN",
"id": 92166725,
"node_id": "U_kgDOBX5aRQ",
"avatar_url": "https://avatars.githubusercontent.com/u/92166725?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LSerranoPEReN",
"html_url": "https://github.com/LSerranoPEReN",
"followers_url": "https://api.github.com/us... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "Harry-Yang0518",
"id": 129883215,
"node_id": "U_kgDOB73cTw",
"avatar_url": "https://avatars.githubusercontent.com/u/129883215?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Harry-Yang0518",
"html_url": "https://github.com/Harry-Yang0518",
"followers_url": "... | null | [
"Strongly agree to this, in addition, I am also suffering to change the cache location similar to other issues (since I changed the environmental variables).\nhttps://github.com/huggingface/datasets/issues/6886",
"`HF_DATASETS_CACHE` should be documented there indeed, feel free to open a PR :) ",
"Hey, I’d love... | 2025-03-17 12:24:50 | 2025-05-06 15:54:39 | 2025-05-06 15:54:39 | {
"login": "Harry-Yang0518",
"id": 129883215,
"node_id": "U_kgDOB73cTw",
"avatar_url": "https://avatars.githubusercontent.com/u/129883215?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Harry-Yang0518",
"html_url": "https://github.com/Harry-Yang0518",
"followers_url": "https://api.github.c... | NONE | [] | null | null | null | null | ### Feature request
Hello,
I have a use case where my team is sharing models and dataset in shared directory to avoid duplication.
I noticed that the [cache documentation for datasets](https://huggingface.co/docs/datasets/main/en/cache) only mention the `HF_HOME` environment variable but never the `HF_DATASETS_CACHE`... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7457/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7457/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7456 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7456/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7456/comments | https://api.github.com/repos/huggingface/datasets/issues/7456/events | https://github.com/huggingface/datasets/issues/7456 | 2,922,676,278 | I_kwDODunzps6uNIA2 | 7,456 | .add_faiss_index and .add_elasticsearch_index returns ImportError at Google Colab | {
"login": "MapleBloom",
"id": 109490785,
"node_id": "U_kgDOBoayYQ",
"avatar_url": "https://avatars.githubusercontent.com/u/109490785?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MapleBloom",
"html_url": "https://github.com/MapleBloom",
"followers_url": "https://api.github.com/users/Map... | [] | open | false | [] | null | [
"I can fix this.\nIt's mainly because faiss-gpu requires python<=3.10 but the default python version in colab is 3.11. We just have to downgrade the CPython version down to 3.10 and it should work fine.\n",
"I think I just had no chance to meet with faiss-cpu.\nIt could be import problem? \n_has_faiss gets its va... | 2025-03-16 00:51:49 | 2025-03-17 15:57:19 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
At Google Colab
```!pip install faiss-cpu``` works
```import faiss``` no error
but
```embeddings_dataset.add_faiss_index(column='embeddings')```
returns
```
[/usr/local/lib/python3.11/dist-packages/datasets/search.py](https://localhost:8080/#) in init(self, device, string_factory, metric_type, cus... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7456/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7456/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7455 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7455/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7455/comments | https://api.github.com/repos/huggingface/datasets/issues/7455/events | https://github.com/huggingface/datasets/issues/7455 | 2,921,933,250 | I_kwDODunzps6uKSnC | 7,455 | Problems with local dataset after upgrade from 3.3.2 to 3.4.0 | {
"login": "andjoer",
"id": 60151338,
"node_id": "MDQ6VXNlcjYwMTUxMzM4",
"avatar_url": "https://avatars.githubusercontent.com/u/60151338?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/andjoer",
"html_url": "https://github.com/andjoer",
"followers_url": "https://api.github.com/users/andjoe... | [] | open | false | [] | null | [
"Hi ! I just released 3.4.1 with a fix, let me know if it's working now !"
] | 2025-03-15 09:22:50 | 2025-03-17 16:20:43 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I was not able to open a local saved dataset anymore that was created using an older datasets version after the upgrade yesterday from datasets 3.3.2 to 3.4.0
The traceback is
```
Traceback (most recent call last):
File "/usr/local/lib/python3.10/dist-packages/datasets/packaged_modules/arrow/... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7455/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7455/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7449 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7449/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7449/comments | https://api.github.com/repos/huggingface/datasets/issues/7449/events | https://github.com/huggingface/datasets/issues/7449 | 2,916,235,092 | I_kwDODunzps6t0jdU | 7,449 | Cannot load data with different schemas from different parquet files | {
"login": "li-plus",
"id": 39846316,
"node_id": "MDQ6VXNlcjM5ODQ2MzE2",
"avatar_url": "https://avatars.githubusercontent.com/u/39846316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/li-plus",
"html_url": "https://github.com/li-plus",
"followers_url": "https://api.github.com/users/li-plu... | [] | closed | false | [] | null | [
"Hi ! `load_dataset` expects all the data_files to have the same schema.\n\nMaybe you can try enforcing certain `features` using:\n\n```python\nfeatures = Features({\"conversations\": {'content': Value('string'), 'role': Value('string',)}})\nds = load_dataset(..., features=features)\n```",
"Thanks! It works if I ... | 2025-03-13 08:14:49 | 2025-03-17 07:27:48 | 2025-03-17 07:27:46 | null | NONE | [] | null | null | null | null | ### Describe the bug
Cannot load samples with optional fields from different files. The schema cannot be correctly derived.
### Steps to reproduce the bug
When I place two samples with an optional field `some_extra_field` within a single parquet file, it can be loaded via `load_dataset`.
```python
import pandas as ... | {
"login": "li-plus",
"id": 39846316,
"node_id": "MDQ6VXNlcjM5ODQ2MzE2",
"avatar_url": "https://avatars.githubusercontent.com/u/39846316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/li-plus",
"html_url": "https://github.com/li-plus",
"followers_url": "https://api.github.com/users/li-plu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7449/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7449/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7448 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7448/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7448/comments | https://api.github.com/repos/huggingface/datasets/issues/7448/events | https://github.com/huggingface/datasets/issues/7448 | 2,916,025,762 | I_kwDODunzps6tzwWi | 7,448 | `datasets.disable_caching` doesn't work | {
"login": "UCC-team",
"id": 35629974,
"node_id": "MDQ6VXNlcjM1NjI5OTc0",
"avatar_url": "https://avatars.githubusercontent.com/u/35629974?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/UCC-team",
"html_url": "https://github.com/UCC-team",
"followers_url": "https://api.github.com/users/UCC... | [] | open | false | [] | null | [
"cc",
"Yes I have the same issue. It's a confusingly named function. See [here](https://github.com/huggingface/datasets/blob/main/src/datasets/fingerprint.py#L115-L130)\n\n```\n...\nIf disabled, the library will no longer reload cached datasets files when applying transforms to the datasets.\n More precisely... | 2025-03-13 06:40:12 | 2026-05-10 12:02:44 | null | null | NONE | [] | null | null | null | null | When I use `Dataset.from_generator(my_gen)` to load my dataset, it simply skips my changes to the generator function.
I tried `datasets.disable_caching`, but it doesn't work! | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7448/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7448/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7447 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7447/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7447/comments | https://api.github.com/repos/huggingface/datasets/issues/7447/events | https://github.com/huggingface/datasets/issues/7447 | 2,915,233,248 | I_kwDODunzps6twu3g | 7,447 | Epochs shortened after resuming mid-epoch with Iterable dataset+StatefulDataloader(persistent_workers=True) | {
"login": "dhruvdcoder",
"id": 4356534,
"node_id": "MDQ6VXNlcjQzNTY1MzQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/4356534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dhruvdcoder",
"html_url": "https://github.com/dhruvdcoder",
"followers_url": "https://api.github.com/us... | [] | closed | false | [] | null | [
"Thanks for reporting ! Maybe we should store the epoch in the state_dict, and then when the dataset is iterated on again after setting a new epoch it should restart from scratch instead of resuming ? wdyt ?",
"But why does this only happen when `persistent_workers=True`? I would expect it to work correctly even ... | 2025-03-12 21:41:05 | 2025-07-09 23:04:57 | 2025-03-14 10:50:10 | null | NONE | [] | null | null | null | null | ### Describe the bug
When `torchdata.stateful_dataloader.StatefulDataloader(persistent_workers=True)` the epochs after resuming only iterate through the examples that were left in the epoch when the training was interrupted. For example, in the script below training is interrupted on step 124 (epoch 1) when 3 batches ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7447/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7447/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7446 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7446/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7446/comments | https://api.github.com/repos/huggingface/datasets/issues/7446/events | https://github.com/huggingface/datasets/issues/7446 | 2,913,050,552 | I_kwDODunzps6toZ-4 | 7,446 | pyarrow.lib.ArrowTypeError: Expected dict key of type str or bytes, got 'int' | {
"login": "rangehow",
"id": 88258534,
"node_id": "MDQ6VXNlcjg4MjU4NTM0",
"avatar_url": "https://avatars.githubusercontent.com/u/88258534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/rangehow",
"html_url": "https://github.com/rangehow",
"followers_url": "https://api.github.com/users/ran... | [] | closed | false | [] | null | [
"I think the Counter object you used in 'labels' may be the issue, since the {2:1} inside is the dict and 2 is the int",
"> I think the Counter object you used in 'labels' may be the issue, since the {2:1} inside is the dict and 2 is the int我认为您在 'labels' 中使用的 Counter 对象可能是问题所在,因为里面的 {2:1} 是 dict,而 2 是 int\n\nYes... | 2025-03-12 07:48:37 | 2025-07-04 05:14:45 | 2025-07-04 05:14:45 | null | NONE | [] | null | null | null | null | ### Describe the bug
A dict with its keys are all str but get following error
```python
test_data=[{'input_ids':[1,2,3],'labels':[[Counter({2:1})]]}]
dataset = datasets.Dataset.from_list(test_data)
```
```bash
pyarrow.lib.ArrowTypeError: Expected dict key of type str or bytes, got 'int'
```
### Steps to reproduce the... | {
"login": "rangehow",
"id": 88258534,
"node_id": "MDQ6VXNlcjg4MjU4NTM0",
"avatar_url": "https://avatars.githubusercontent.com/u/88258534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/rangehow",
"html_url": "https://github.com/rangehow",
"followers_url": "https://api.github.com/users/ran... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7446/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7446/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7444 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7444/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7444/comments | https://api.github.com/repos/huggingface/datasets/issues/7444/events | https://github.com/huggingface/datasets/issues/7444 | 2,911,202,445 | I_kwDODunzps6thWyN | 7,444 | Excessive warnings when resuming an IterableDataset+buffered shuffle+DDP. | {
"login": "dhruvdcoder",
"id": 4356534,
"node_id": "MDQ6VXNlcjQzNTY1MzQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/4356534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dhruvdcoder",
"html_url": "https://github.com/dhruvdcoder",
"followers_url": "https://api.github.com/us... | [] | open | false | [] | null | [
"I had a similar issue when loading the saved iterable dataset state to fast-forward to the mid-train location before resuming. This happened when I shuffled a concatenated dataset. A `iterable_data_state_dict.json` file was saved during checkpointing in the Trainer with:\n```\ndef _save_rng_state(self, output_dir)... | 2025-03-11 16:34:39 | 2025-11-22 06:45:25 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I have a large dataset that I shared into 1024 shards and save on the disk during pre-processing. During training, I load the dataset using load_from_disk() and convert it into an iterable dataset, shuffle it and split the shards to different DDP nodes using the recommended method.
However, when ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7444/reactions",
"total_count": 2,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7444/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7443 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7443/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7443/comments | https://api.github.com/repos/huggingface/datasets/issues/7443/events | https://github.com/huggingface/datasets/issues/7443 | 2,908,585,656 | I_kwDODunzps6tXX64 | 7,443 | index error when num_shards > len(dataset) | {
"login": "eminorhan",
"id": 17934496,
"node_id": "MDQ6VXNlcjE3OTM0NDk2",
"avatar_url": "https://avatars.githubusercontent.com/u/17934496?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/eminorhan",
"html_url": "https://github.com/eminorhan",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"Actually, looking at the code a bit more carefully, maybe an even better solution is to explicitly set `num_shards=len(self)` somewhere inside both `push_to_hub()` and `save_to_disk()` when these functions are invoked with `num_shards > len(dataset)`."
] | 2025-03-10 22:40:59 | 2025-03-10 23:43:08 | null | null | NONE | [] | null | null | null | null | In `ds.push_to_hub()` and `ds.save_to_disk()`, `num_shards` must be smaller than or equal to the number of rows in the dataset, but currently this is not checked anywhere inside these functions. Attempting to invoke these functions with `num_shards > len(dataset)` should raise an informative `ValueError`.
I frequently... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7443/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7443/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7442 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7442/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7442/comments | https://api.github.com/repos/huggingface/datasets/issues/7442/events | https://github.com/huggingface/datasets/issues/7442 | 2,905,543,017 | I_kwDODunzps6tLxFp | 7,442 | Flexible Loader | {
"login": "dipta007",
"id": 13894030,
"node_id": "MDQ6VXNlcjEzODk0MDMw",
"avatar_url": "https://avatars.githubusercontent.com/u/13894030?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dipta007",
"html_url": "https://github.com/dipta007",
"followers_url": "https://api.github.com/users/dip... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Ideally `save_to_disk` should save in a format compatible with load_dataset, wdyt ?",
"> Ideally `save_to_disk` should save in a format compatible with load_dataset, wdyt ?\n\nThat would be perfect if not at least a flexible loader.",
"@lhoestq For now, you can use this small utility library: [nanoml](https://... | 2025-03-09 16:55:03 | 2026-02-21 19:58:58 | 2026-02-21 19:58:58 | null | NONE | [] | null | null | null | null | ### Feature request
Can we have a utility function that will use `load_from_disk` when given the local path and `load_dataset` if given an HF dataset?
It can be something as simple as this one:
```
def load_hf_dataset(path_or_name):
if os.path.exists(path_or_name):
return load_from_disk(path_or_name)
... | {
"login": "dipta007",
"id": 13894030,
"node_id": "MDQ6VXNlcjEzODk0MDMw",
"avatar_url": "https://avatars.githubusercontent.com/u/13894030?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dipta007",
"html_url": "https://github.com/dipta007",
"followers_url": "https://api.github.com/users/dip... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7442/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7442/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7441 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7441/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7441/comments | https://api.github.com/repos/huggingface/datasets/issues/7441/events | https://github.com/huggingface/datasets/issues/7441 | 2,904,702,329 | I_kwDODunzps6tIj15 | 7,441 | `drop_last_batch` does not drop the last batch using IterableDataset + interleave_datasets + multi_worker | {
"login": "memray",
"id": 4197249,
"node_id": "MDQ6VXNlcjQxOTcyNDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/4197249?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/memray",
"html_url": "https://github.com/memray",
"followers_url": "https://api.github.com/users/memray/foll... | [] | open | false | [] | null | [
"Hi @memray, I’d like to help fix the issue with `drop_last_batch` not working when `num_workers > 1`. I’ll investigate and propose a solution. Thanks!\n",
"Thank you very much for offering to help! I also noticed a problem related to a previous issue and left a comment [here](https://github.com/huggingface/datas... | 2025-03-08 10:28:44 | 2025-10-09 10:14:24 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
See the script below
`drop_last_batch=True` is defined using map() for each dataset.
The last batch for each dataset is expected to be dropped, id 21-25.
The code behaves as expected when num_workers=0 or 1.
When using num_workers>1, 'a-11', 'b-11', 'a-12', 'b-12' are gone and instead 21 and 22 a... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7441/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7441/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7440 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7440/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7440/comments | https://api.github.com/repos/huggingface/datasets/issues/7440/events | https://github.com/huggingface/datasets/issues/7440 | 2,903,740,662 | I_kwDODunzps6tE5D2 | 7,440 | IterableDataset raises FileNotFoundError instead of retrying | {
"login": "bauwenst",
"id": 145220868,
"node_id": "U_kgDOCKflBA",
"avatar_url": "https://avatars.githubusercontent.com/u/145220868?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bauwenst",
"html_url": "https://github.com/bauwenst",
"followers_url": "https://api.github.com/users/bauwenst/... | [] | open | false | [] | null | [
"I have since been training more models with identical architectures over the same dataset, and it is completely unstable. One has now failed at chunk9/1215, whilst others have gotten past that.\n```python\nFileNotFoundError: zstd://example_train_1215.jsonl::hf://datasets/cerebras/SlimPajama-627B@2d0accdd58c5d55119... | 2025-03-07 19:14:18 | 2026-04-24 11:15:36 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
In https://github.com/huggingface/datasets/issues/6843 it was noted that the streaming feature of `datasets` is highly susceptible to outages and doesn't back off for long (or even *at all*).
I was training a model while streaming SlimPajama and training crashed with a `FileNotFoundError`. I can ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7440/reactions",
"total_count": 2,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 1
} | https://api.github.com/repos/huggingface/datasets/issues/7440/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7433 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7433/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7433/comments | https://api.github.com/repos/huggingface/datasets/issues/7433/events | https://github.com/huggingface/datasets/issues/7433 | 2,890,240,400 | I_kwDODunzps6sRZGQ | 7,433 | `Dataset.map` ignores existing caches and remaps when ran with different `num_proc` | {
"login": "ringohoffman",
"id": 27844407,
"node_id": "MDQ6VXNlcjI3ODQ0NDA3",
"avatar_url": "https://avatars.githubusercontent.com/u/27844407?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ringohoffman",
"html_url": "https://github.com/ringohoffman",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"This feels related: https://github.com/huggingface/datasets/issues/3044",
"@lhoestq This comment specifically, I agree:\n\n* https://github.com/huggingface/datasets/issues/3044#issuecomment-1239877570\n\n> Almost a year later and I'm in a similar boat. Using custom fingerprints and when using multiprocessing the... | 2025-03-03 05:51:26 | 2025-05-12 15:14:09 | 2025-05-12 15:14:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
If you `map` a dataset and save it to a specific `cache_file_name` with a specific `num_proc`, and then call map again with that same existing `cache_file_name` but a different `num_proc`, the dataset will be re-mapped.
### Steps to reproduce the bug
1. Download a dataset
```python
import datase... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7433/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7433/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7431 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7431/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7431/comments | https://api.github.com/repos/huggingface/datasets/issues/7431/events | https://github.com/huggingface/datasets/issues/7431 | 2,887,244,074 | I_kwDODunzps6sF9kq | 7,431 | Issues with large Datasets | {
"login": "nikitabelooussovbtis",
"id": 106806889,
"node_id": "U_kgDOBl2-aQ",
"avatar_url": "https://avatars.githubusercontent.com/u/106806889?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikitabelooussovbtis",
"html_url": "https://github.com/nikitabelooussovbtis",
"followers_url": "ht... | [] | open | false | [] | null | [
"what's the error message ?",
"This was the final error message that it was giving pyarrow.lib.ArrowInvalid: JSON parse error: Column() changed from object to string in row 0",
"Here is the list of errors:\n\nTraceback (most recent call last):\n File \".venv/lib/python3.12/site-packages/datasets/packaged_modul... | 2025-02-28 14:05:22 | 2025-03-04 15:02:26 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
If the coco annotation file is too large the dataset will not be able to load it, not entirely sure were the issue is but I am guessing it is due to the code trying to load it all as one line into a dataframe. This was for object detections.
My current work around is the following code but would ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7431/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7431/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7430 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7430/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7430/comments | https://api.github.com/repos/huggingface/datasets/issues/7430/events | https://github.com/huggingface/datasets/issues/7430 | 2,886,922,573 | I_kwDODunzps6sEvFN | 7,430 | Error in code "Time to slice and dice" from course "NLP Course" | {
"login": "Yurkmez",
"id": 122965300,
"node_id": "U_kgDOB1RNNA",
"avatar_url": "https://avatars.githubusercontent.com/u/122965300?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Yurkmez",
"html_url": "https://github.com/Yurkmez",
"followers_url": "https://api.github.com/users/Yurkmez/foll... | [] | closed | false | [] | null | [
"You should open an issue in the NLP course website / github page. I'm closing this issue if you don't mind",
"ok, i don't mind, i'll mark the error there"
] | 2025-02-28 11:36:10 | 2025-03-05 11:32:47 | 2025-03-03 17:52:15 | null | NONE | [] | null | null | null | null | ### Describe the bug
When we execute code
```
frequencies = (
train_df["condition"]
.value_counts()
.to_frame()
.reset_index()
.rename(columns={"index": "condition", "condition": "frequency"})
)
frequencies.head()
```
answer should be like this
condition | frequency
birth control | 27655
dep... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7430/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7430/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7427 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7427/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7427/comments | https://api.github.com/repos/huggingface/datasets/issues/7427/events | https://github.com/huggingface/datasets/issues/7427 | 2,886,032,571 | I_kwDODunzps6sBVy7 | 7,427 | Error splitting the input into NAL units. | {
"login": "MengHao666",
"id": 47114466,
"node_id": "MDQ6VXNlcjQ3MTE0NDY2",
"avatar_url": "https://avatars.githubusercontent.com/u/47114466?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MengHao666",
"html_url": "https://github.com/MengHao666",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"First time I see this error :/ maybe it's an issue with your version of `multiprocess` and `dill` ? Make sure they are compatible with `datasets`",
"> First time I see this error :/ maybe it's an issue with your version of `multiprocess` and `dill` ? Make sure they are compatible with `datasets`\n\nany recommend... | 2025-02-28 02:30:15 | 2025-03-04 01:40:28 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to finetune qwen2.5-vl on 16 * 80G GPUS, and I use `LLaMA-Factory` and set `preprocessing_num_workers=16`. However, I met the following error and the program seem to got crush. It seems that the error come from `datasets` library
The error logging is like following:
```text
Convertin... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7427/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7427/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7425 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7425/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7425/comments | https://api.github.com/repos/huggingface/datasets/issues/7425/events | https://github.com/huggingface/datasets/issues/7425 | 2,883,684,686 | I_kwDODunzps6r4YlO | 7,425 | load_dataset("livecodebench/code_generation_lite", version_tag="release_v2") TypeError: 'NoneType' object is not callable | {
"login": "dshwei",
"id": 42167236,
"node_id": "MDQ6VXNlcjQyMTY3MjM2",
"avatar_url": "https://avatars.githubusercontent.com/u/42167236?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dshwei",
"html_url": "https://github.com/dshwei",
"followers_url": "https://api.github.com/users/dshwei/fo... | [] | open | false | [] | null | [
"> datasets\n\nHi, have you solved this bug? Today I also met the same problem about `livecodebench/code_generation_lite` when evaluating the `Open-R1` repo. I am looking forward to your reply!\n\n",
"Hey guys,\nI tried to re... | 2025-02-27 07:36:02 | 2025-03-27 05:05:33 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
from datasets import load_dataset
lcb_codegen = load_dataset("livecodebench/code_generation_lite", version_tag="release_v2")
or
configs = get_dataset_config_names("livecodebench/code_generation_lite", trust_remote_code=True)
both error:
Traceback (most recent call last):
File "", line 1, in
File... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7425/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 1
} | https://api.github.com/repos/huggingface/datasets/issues/7425/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7423 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7423/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7423/comments | https://api.github.com/repos/huggingface/datasets/issues/7423/events | https://github.com/huggingface/datasets/issues/7423 | 2,879,271,409 | I_kwDODunzps6rnjHx | 7,423 | Row indexing a dataset with numpy integers | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Would be cool to be consistent when it comes to indexing with numpy objects, if we do accept numpy arrays we should indeed accept numpy integers. Your idea sounds reasonable, I'd also be in favor of adding a simple test as well"
] | 2025-02-25 18:44:45 | 2025-07-28 02:23:17 | 2025-07-28 02:23:17 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Allow indexing datasets with a scalar numpy integer type.
### Motivation
Indexing a dataset with a scalar numpy.int* object raises a TypeError. This is due to the test in `datasets/formatting/formatting.py:key_to_query_type`
``` python
def key_to_query_type(key: Union[int, slice, range, str, Ite... | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7423/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7423/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7421 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7421/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7421/comments | https://api.github.com/repos/huggingface/datasets/issues/7421/events | https://github.com/huggingface/datasets/issues/7421 | 2,878,369,052 | I_kwDODunzps6rkG0c | 7,421 | DVC integration broken | {
"login": "maxstrobel",
"id": 34747372,
"node_id": "MDQ6VXNlcjM0NzQ3Mzcy",
"avatar_url": "https://avatars.githubusercontent.com/u/34747372?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/maxstrobel",
"html_url": "https://github.com/maxstrobel",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"Unfortunately `url` is a reserved argument in `fsspec.url_to_fs`, so ideally file system implementations like DVC should use another argument name to avoid this kind of errors"
] | 2025-02-25 13:14:31 | 2025-03-03 17:42:02 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
The DVC integration seems to be broken.
Followed this guide: https://dvc.org/doc/user-guide/integrations/huggingface
### Steps to reproduce the bug
#### Script to reproduce
~~~python
from datasets import load_dataset
dataset = load_dataset(
"csv",
data_files="dvc://workshop/satellite-d... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7421/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7421/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7420 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7420/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7420/comments | https://api.github.com/repos/huggingface/datasets/issues/7420/events | https://github.com/huggingface/datasets/issues/7420 | 2,876,281,928 | I_kwDODunzps6rcJRI | 7,420 | better correspondence between cached and saved datasets created using from_generator | {
"login": "vttrifonov",
"id": 12157034,
"node_id": "MDQ6VXNlcjEyMTU3MDM0",
"avatar_url": "https://avatars.githubusercontent.com/u/12157034?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vttrifonov",
"html_url": "https://github.com/vttrifonov",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Until this lands, in case anyone needs this, I made this helper (based on HF sources) that merely serializes the metadata from a dataset, thus allowing to bypass the completely redundant additional save.\n\n```python\nimport json\nimport posixpath\nimport os\nfrom typing import Optional\nfrom fsspec.core import ur... | 2025-02-24 22:14:37 | 2026-01-05 15:16:35 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
At the moment `.from_generator` can only create a dataset that lives in the cache. The cached dataset cannot be loaded with `load_from_disk` because the cache folder is missing `state.json`. So the only way to convert this cached dataset to a regular is to use `save_to_disk` which needs to create a... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7420/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7420/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7419 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7419/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7419/comments | https://api.github.com/repos/huggingface/datasets/issues/7419/events | https://github.com/huggingface/datasets/issues/7419 | 2,875,635,320 | I_kwDODunzps6rZrZ4 | 7,419 | Import order crashes script execution | {
"login": "DamienMatias",
"id": 23298479,
"node_id": "MDQ6VXNlcjIzMjk4NDc5",
"avatar_url": "https://avatars.githubusercontent.com/u/23298479?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DamienMatias",
"html_url": "https://github.com/DamienMatias",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [] | 2025-02-24 17:03:43 | 2025-02-24 17:03:43 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hello,
I'm trying to convert an HF dataset into a TFRecord so I'm importing `tensorflow` and `datasets` to do so.
Depending in what order I'm importing those librairies, my code hangs forever and is unkillable (CTRL+C doesn't work, I need to kill my shell entirely).
Thank you for your help
🙏
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7419/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7419/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7418 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7418/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7418/comments | https://api.github.com/repos/huggingface/datasets/issues/7418/events | https://github.com/huggingface/datasets/issues/7418 | 2,868,701,471 | I_kwDODunzps6q_Okf | 7,418 | pyarrow.lib.arrowinvalid: cannot mix list and non-list, non-null values with map function | {
"login": "alexxchen",
"id": 15705569,
"node_id": "MDQ6VXNlcjE1NzA1NTY5",
"avatar_url": "https://avatars.githubusercontent.com/u/15705569?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alexxchen",
"html_url": "https://github.com/alexxchen",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"@lhoestq ",
"Can you try passing text: None for the image object ? Pyarrow expects all the objects to have the exact same type, in particular the dicttionaries in \"content\" should all have the keys \"type\" and \"text\"",
"The following modification on system prompt works, but it is different from the usual ... | 2025-02-21 10:58:06 | 2026-03-09 15:58:00 | 2026-03-09 15:58:00 | null | NONE | [] | null | null | null | null | ### Describe the bug
Encounter pyarrow.lib.arrowinvalid error with map function in some example when loading the dataset
### Steps to reproduce the bug
```
from datasets import load_dataset
from PIL import Image, PngImagePlugin
dataset = load_dataset("leonardPKU/GEOQA_R1V_Train_8K")
system_prompt="You are a helpful... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7418/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7418/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7415 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7415/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7415/comments | https://api.github.com/repos/huggingface/datasets/issues/7415/events | https://github.com/huggingface/datasets/issues/7415 | 2,865,774,546 | I_kwDODunzps6q0D_S | 7,415 | Shard Dataset at specific indices | {
"login": "nikonikolov",
"id": 11044035,
"node_id": "MDQ6VXNlcjExMDQ0MDM1",
"avatar_url": "https://avatars.githubusercontent.com/u/11044035?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikonikolov",
"html_url": "https://github.com/nikonikolov",
"followers_url": "https://api.github.com/... | [] | open | false | [] | null | [
"Hi ! if it's an option I'd suggest to have one sequence per row instead.\n\nOtherwise you'd have to make your own save/load mechanism",
"Saving one sequence per row is very difficult and heavy and makes all the optimizations pointless. How would a custom save/load mechanism look like?",
"You can use `pyarrow` ... | 2025-02-20 10:43:10 | 2025-02-24 11:06:45 | null | null | NONE | [] | null | null | null | null | I have a dataset of sequences, where each example in the sequence is a separate row in the dataset (similar to LeRobotDataset). When running `Dataset.save_to_disk` how can I provide indices where it's possible to shard the dataset such that no episode spans more than 1 shard. Consequently, when I run `Dataset.load_from... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7415/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7415/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7413 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7413/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7413/comments | https://api.github.com/repos/huggingface/datasets/issues/7413/events | https://github.com/huggingface/datasets/issues/7413 | 2,860,947,582 | I_kwDODunzps6qhph- | 7,413 | Documentation on multiple media files of the same type with WebDataset | {
"login": "DCNemesis",
"id": 3616964,
"node_id": "MDQ6VXNlcjM2MTY5NjQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/3616964?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DCNemesis",
"html_url": "https://github.com/DCNemesis",
"followers_url": "https://api.github.com/users/DC... | [] | open | false | [] | null | [
"Yes this is correct and it works with huggingface datasets as well ! Feel free to include an example here: https://github.com/huggingface/datasets/blob/main/docs/source/video_dataset.mdx"
] | 2025-02-18 16:13:20 | 2025-02-20 14:17:54 | null | null | NONE | [] | null | null | null | null | The [current documentation](https://huggingface.co/docs/datasets/en/video_dataset) on a creating a video dataset includes only examples with one media file and one json. It would be useful to have examples where multiple files of the same type are included. For example, in a sign language dataset, you may have a base v... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7413/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7413/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7412 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7412/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7412/comments | https://api.github.com/repos/huggingface/datasets/issues/7412/events | https://github.com/huggingface/datasets/issues/7412 | 2,859,433,710 | I_kwDODunzps6qb37u | 7,412 | Index Error Invalid Ket is out of bounds for size 0 for code-search-net/code_search_net dataset | {
"login": "harshakhmk",
"id": 56113657,
"node_id": "MDQ6VXNlcjU2MTEzNjU3",
"avatar_url": "https://avatars.githubusercontent.com/u/56113657?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/harshakhmk",
"html_url": "https://github.com/harshakhmk",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [] | 2025-02-18 05:58:33 | 2025-02-18 06:42:07 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to do model pruning on sentence-transformers/all-mini-L6-v2 for the code-search-net/code_search_net dataset using INCTrainer class
However I am getting below error
```
raise IndexError(f"Invalid Key: {key is our of bounds for size {size}")
IndexError: Invalid key: 1840208 is out of b... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7412/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7412/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7406 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7406/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7406/comments | https://api.github.com/repos/huggingface/datasets/issues/7406/events | https://github.com/huggingface/datasets/issues/7406 | 2,856,441,206 | I_kwDODunzps6qQdV2 | 7,406 | Adding Core Maintainer List to CONTRIBUTING.md | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"@lhoestq",
"there is no per-module maintainer and the list is me alone nowadays ^^'",
"@lhoestq \nOh... I feel for you. \nWhat are your criteria for choosing a core maintainer? \nIt seems like it's too much work for you to manage all this code by yourself.\n\nAlso, if you don't mind, can you check this PR for ... | 2025-02-17 00:32:40 | 2025-03-24 10:57:54 | 2025-03-24 10:57:54 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
I propose adding a core maintainer list to the `CONTRIBUTING.md` file.
### Motivation
The Transformers and Liger-Kernel projects maintain lists of core maintainers for each module.
However, the Datasets project doesn't have such a list.
### Your contribution
I have nothing to add here. | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7406/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7406/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7405 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7405/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7405/comments | https://api.github.com/repos/huggingface/datasets/issues/7405/events | https://github.com/huggingface/datasets/issues/7405 | 2,856,372,814 | I_kwDODunzps6qQMpO | 7,405 | Lazy loading of environment variables | {
"login": "nikvaessen",
"id": 7225987,
"node_id": "MDQ6VXNlcjcyMjU5ODc=",
"avatar_url": "https://avatars.githubusercontent.com/u/7225987?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikvaessen",
"html_url": "https://github.com/nikvaessen",
"followers_url": "https://api.github.com/users... | [] | open | false | [] | null | [
"Many python packages out there, including `huggingface_hub`, do load the environment variables on import.\nYou should `load_dotenv()` before importing the libraries.\n\nFor example you can move all you imports inside your `main()` function"
] | 2025-02-16 22:31:41 | 2025-02-17 15:17:18 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Loading a `.env` file after an `import datasets` call does not correctly use the environment variables.
This is due the fact that environment variables are read at import time:
https://github.com/huggingface/datasets/blob/de062f0552a810c52077543c1169c38c1f0c53fc/src/datasets/config.py#L155C1-L15... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7405/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7405/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7404 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7404/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7404/comments | https://api.github.com/repos/huggingface/datasets/issues/7404/events | https://github.com/huggingface/datasets/issues/7404 | 2,856,366,207 | I_kwDODunzps6qQLB_ | 7,404 | Performance regression in `dataset.filter` | {
"login": "ttim",
"id": 82200,
"node_id": "MDQ6VXNlcjgyMjAw",
"avatar_url": "https://avatars.githubusercontent.com/u/82200?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ttim",
"html_url": "https://github.com/ttim",
"followers_url": "https://api.github.com/users/ttim/followers",
"follo... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | [
"Thanks for reporting, I'll fix the regression today",
"I just released `datasets` 3.3.1 with a fix, let me know if it's good now :)",
"@lhoestq it fixed the issue.\n\nThis was (very) fast, thank you very much!"
] | 2025-02-16 22:19:14 | 2025-02-17 17:46:06 | 2025-02-17 14:28:48 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | NONE | [] | null | null | null | null | ### Describe the bug
We're filtering dataset of ~1M (small-ish) records. At some point in the code we do `dataset.filter`, before (including 3.2.0) it was taking couple of seconds, and now it takes 4 hours.
We use 16 threads/workers, and stack trace at them look as follows:
```
Traceback (most recent call last):
Fi... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7404/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7404/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7399 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7399/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7399/comments | https://api.github.com/repos/huggingface/datasets/issues/7399/events | https://github.com/huggingface/datasets/issues/7399 | 2,853,098,442 | I_kwDODunzps6qDtPK | 7,399 | Synchronize parameters for various datasets | {
"login": "grofte",
"id": 7976840,
"node_id": "MDQ6VXNlcjc5NzY4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/7976840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/grofte",
"html_url": "https://github.com/grofte",
"followers_url": "https://api.github.com/users/grofte/foll... | [] | open | false | [] | null | [
"Hi ! the `desc` parameter is only available for Dataset / DatasetDict for the progress bar of `map()``\n\nSince IterableDataset only runs the map functions when you iterate over the dataset, there is no progress bar and `desc` is useless. We could still add the argument for parity but it wouldn't be used for anyth... | 2025-02-14 09:15:11 | 2025-02-19 11:50:29 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
[IterableDatasetDict](https://huggingface.co/docs/datasets/v3.2.0/en/package_reference/main_classes#datasets.IterableDatasetDict.map) map function is missing the `desc` parameter. You can see the equivalent map function for [Dataset here](https://huggingface.co/docs/datasets/v3.2.0/en/package_refe... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7399/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7399/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7400 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7400/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7400/comments | https://api.github.com/repos/huggingface/datasets/issues/7400/events | https://github.com/huggingface/datasets/issues/7400 | 2,853,201,277 | I_kwDODunzps6qEGV9 | 7,400 | 504 Gateway Timeout when uploading large dataset to Hugging Face Hub | {
"login": "hotchpotch",
"id": 3500,
"node_id": "MDQ6VXNlcjM1MDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/3500?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/hotchpotch",
"html_url": "https://github.com/hotchpotch",
"followers_url": "https://api.github.com/users/hotchpotc... | [] | open | false | [] | null | [
"I transferred to the `datasets` repository. Is there any retry mechanism in `datasets` @lhoestq ?\n\nAnother solution @hotchpotch if you want to get your dataset pushed to the Hub in a robust way is to save it to a local folder first and then use `huggingface-cli upload-large-folder` (see https://huggingface.co/do... | 2025-02-14 02:18:35 | 2025-02-14 23:48:36 | null | null | NONE | [] | null | null | null | null | ### Description
I encountered consistent 504 Gateway Timeout errors while attempting to upload a large dataset (approximately 500GB) to the Hugging Face Hub. The upload fails during the process with a Gateway Timeout error.
I will continue trying to upload. While it might succeed in future attempts, I wanted to report... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7400/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7400/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7394 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7394/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7394/comments | https://api.github.com/repos/huggingface/datasets/issues/7394/events | https://github.com/huggingface/datasets/issues/7394 | 2,847,172,115 | I_kwDODunzps6ptGYT | 7,394 | Using load_dataset with data_files and split arguments yields an error | {
"login": "devon-research",
"id": 61103399,
"node_id": "MDQ6VXNlcjYxMTAzMzk5",
"avatar_url": "https://avatars.githubusercontent.com/u/61103399?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/devon-research",
"html_url": "https://github.com/devon-research",
"followers_url": "https://api.gi... | [] | open | false | [] | null | [
"Hi, \nI want to work on this issue involving adding a verification test for the **`HuggingFaceM4/InterleavedWebDocuments`** dataset. \nThis will be my first contribution to `datasets`, \nI plan to add a simple loading and basic structure verification test like other recent dataset tests. \nYou can expect a PR ... | 2025-02-12 04:50:11 | 2025-11-21 14:05:23 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
It seems the list of valid splits recorded by the package becomes incorrectly overwritten when using the `data_files` argument.
If I run
```python
from datasets import load_dataset
load_dataset("allenai/super", split="all_examples", data_files="tasks/expert.jsonl")
```
then I get the error
```
Va... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7394/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7394/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7392 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7392/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7392/comments | https://api.github.com/repos/huggingface/datasets/issues/7392/events | https://github.com/huggingface/datasets/issues/7392 | 2,846,095,043 | I_kwDODunzps6po_bD | 7,392 | push_to_hub payload too large error when using large ClassLabel feature | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | [] | open | false | [] | null | [
"See also <https://discuss.huggingface.co/t/datasetdict-push-to-hub-failing-with-payload-to-large/140083/8>\n"
] | 2025-02-11 17:51:34 | 2025-02-11 18:01:31 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When using `datasets.DatasetDict.push_to_hub` an `HfHubHTTPError: 413 Client Error: Payload Too Large for url` is raised if the dataset contains a large `ClassLabel` feature. Even if the total size of the dataset is small.
### Steps to reproduce the bug
``` python
import random
import sys
impor... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7392/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7392/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7391 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7391/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7391/comments | https://api.github.com/repos/huggingface/datasets/issues/7391/events | https://github.com/huggingface/datasets/issues/7391 | 2,845,184,764 | I_kwDODunzps6plhL8 | 7,391 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType' | {
"login": "LinXin04",
"id": 25193686,
"node_id": "MDQ6VXNlcjI1MTkzNjg2",
"avatar_url": "https://avatars.githubusercontent.com/u/25193686?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LinXin04",
"html_url": "https://github.com/LinXin04",
"followers_url": "https://api.github.com/users/Lin... | [] | open | false | [] | null | [] | 2025-02-11 12:02:26 | 2025-02-11 12:02:26 | null | null | NONE | [] | null | null | null | null | pyarrow 尝试了若干个版本都不可以 | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7391/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7391/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7390 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7390/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7390/comments | https://api.github.com/repos/huggingface/datasets/issues/7390/events | https://github.com/huggingface/datasets/issues/7390 | 2,843,813,365 | I_kwDODunzps6pgSX1 | 7,390 | Re-add py.typed | {
"login": "NeilGirdhar",
"id": 730137,
"node_id": "MDQ6VXNlcjczMDEzNw==",
"avatar_url": "https://avatars.githubusercontent.com/u/730137?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NeilGirdhar",
"html_url": "https://github.com/NeilGirdhar",
"followers_url": "https://api.github.com/user... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"A similar issue was fixed for the `transformers` package, too: https://github.com/huggingface/transformers/pull/37022"
] | 2025-02-10 22:12:52 | 2025-08-10 00:51:17 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
The motivation for removing py.typed no longer seems to apply. Would a solution like [this one](https://github.com/huggingface/huggingface_hub/pull/2752) work here?
### Motivation
MyPy support is broken. As more type checkers come out, such as RedKnot, these may also be broken. It would be goo... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7390/reactions",
"total_count": 13,
"+1": 13,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7390/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7389 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7389/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7389/comments | https://api.github.com/repos/huggingface/datasets/issues/7389/events | https://github.com/huggingface/datasets/issues/7389 | 2,843,592,606 | I_kwDODunzps6pfcee | 7,389 | Getting statistics about filtered examples | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | [] | closed | false | [] | null | [
"You can actually track a running sum in map() or filter() :)\n\n```python\nnum_filtered = 0\n\ndef f(x):\n global num_filtered\n condition = len(x[\"text\"]) < 1000\n if not condition:\n num_filtered += 1\n return condition\n\nds = ds.filter(f)\nprint(num_filtered)\n```\n\nand if you want to use... | 2025-02-10 20:48:29 | 2025-02-11 20:44:15 | 2025-02-11 20:44:13 | null | NONE | [] | null | null | null | null | @lhoestq wondering if the team has thought about this and if there are any recommendations?
Currently when processing datasets some examples are bound to get filtered out, whether it's due to bad format, or length is too long, or any other custom filters that might be getting applied. Let's just focus on the filter by... | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7389/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7389/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7388 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7388/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7388/comments | https://api.github.com/repos/huggingface/datasets/issues/7388/events | https://github.com/huggingface/datasets/issues/7388 | 2,843,188,499 | I_kwDODunzps6pd50T | 7,388 | OSError: [Errno 22] Invalid argument forbidden character | {
"login": "langflogit",
"id": 124634542,
"node_id": "U_kgDOB23Frg",
"avatar_url": "https://avatars.githubusercontent.com/u/124634542?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/langflogit",
"html_url": "https://github.com/langflogit",
"followers_url": "https://api.github.com/users/lan... | [] | closed | false | [] | null | [
"You can probably copy the dataset in your HF account and rename the files (without having to download them to your disk). Or alternatively feel free to open a Pull Request to this dataset with the renamed file",
"Thank you, that will help me work around this problem"
] | 2025-02-10 17:46:31 | 2025-02-11 13:42:32 | 2025-02-11 13:42:30 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm on Windows and i'm trying to load a datasets but i'm having title error because files in the repository are named with charactere like < >which can't be in a name file. Could it be possible to load this datasets but removing those charactere ?
### Steps to reproduce the bug
load_dataset("CAT... | {
"login": "langflogit",
"id": 124634542,
"node_id": "U_kgDOB23Frg",
"avatar_url": "https://avatars.githubusercontent.com/u/124634542?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/langflogit",
"html_url": "https://github.com/langflogit",
"followers_url": "https://api.github.com/users/lan... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7388/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7388/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7387 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7387/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7387/comments | https://api.github.com/repos/huggingface/datasets/issues/7387/events | https://github.com/huggingface/datasets/issues/7387 | 2,841,228,048 | I_kwDODunzps6pWbMQ | 7,387 | Dynamic adjusting dataloader sampling weight | {
"login": "whc688",
"id": 72799643,
"node_id": "MDQ6VXNlcjcyNzk5NjQz",
"avatar_url": "https://avatars.githubusercontent.com/u/72799643?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/whc688",
"html_url": "https://github.com/whc688",
"followers_url": "https://api.github.com/users/whc688/fo... | [] | open | false | [] | null | [
"You mean based on a condition that has to be checked on-the-fly during training ? Otherwise if you know in advance after how many samples you need to change the sampling you can simply concatenate the two mixes",
"Yes, like during training, if one data sample's prediction is consistently wrong, its sampling weig... | 2025-02-10 03:18:47 | 2025-03-07 14:06:54 | null | null | NONE | [] | null | null | null | null | Hi,
Thanks for your wonderful work! I'm wondering is there a way to dynamically adjust the sampling weight of each data in the dataset during training? Looking forward to your reply, thanks again. | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7387/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7387/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7386 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7386/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7386/comments | https://api.github.com/repos/huggingface/datasets/issues/7386/events | https://github.com/huggingface/datasets/issues/7386 | 2,840,032,524 | I_kwDODunzps6pR3UM | 7,386 | Add bookfolder Dataset Builder for Digital Book Formats | {
"login": "shikanime",
"id": 22115108,
"node_id": "MDQ6VXNlcjIyMTE1MTA4",
"avatar_url": "https://avatars.githubusercontent.com/u/22115108?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shikanime",
"html_url": "https://github.com/shikanime",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"On second thought, probably not a good idea."
] | 2025-02-08 14:27:55 | 2025-02-08 14:30:10 | 2025-02-08 14:30:09 | null | NONE | [] | null | null | null | null | ### Feature request
This feature proposes adding a new dataset builder called bookfolder to the datasets library. This builder would allow users to easily load datasets consisting of various digital book formats, including: AZW, AZW3, CB7, CBR, CBT, CBZ, EPUB, MOBI, and PDF.
### Motivation
Currently, loading dataset... | {
"login": "shikanime",
"id": 22115108,
"node_id": "MDQ6VXNlcjIyMTE1MTA4",
"avatar_url": "https://avatars.githubusercontent.com/u/22115108?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shikanime",
"html_url": "https://github.com/shikanime",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7386/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7386/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7381 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7381/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7381/comments | https://api.github.com/repos/huggingface/datasets/issues/7381/events | https://github.com/huggingface/datasets/issues/7381 | 2,815,649,092 | I_kwDODunzps6n02VE | 7,381 | Iterating over values of a column in the IterableDataset | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https:... | null | [
"I'd be in favor of that ! I saw many people implementing their own iterables that wrap a dataset just to iterate on a single column, that would make things more practical.\n\nKinda related: https://github.com/huggingface/datasets/issues/5847",
"(For anyone's information, I'm going on vacation for the next 3 week... | 2025-01-28 13:17:36 | 2025-05-22 18:00:04 | 2025-05-22 18:00:04 | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
I would like to be able to iterate (and re-iterate if needed) over a column of an `IterableDataset` instance. The following example shows the supposed API:
```python
def gen():
yield {"text": "Good", "label": 0}
yield {"text": "Bad", "label": 1}
ds = IterableDataset.from_generator(gen)
tex... | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7381/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7381/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7378 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7378/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7378/comments | https://api.github.com/repos/huggingface/datasets/issues/7378/events | https://github.com/huggingface/datasets/issues/7378 | 2,802,957,388 | I_kwDODunzps6nEbxM | 7,378 | Allow pushing config version to hub | {
"login": "momeara",
"id": 129072,
"node_id": "MDQ6VXNlcjEyOTA3Mg==",
"avatar_url": "https://avatars.githubusercontent.com/u/129072?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/momeara",
"html_url": "https://github.com/momeara",
"followers_url": "https://api.github.com/users/momeara/fo... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! This sounds reasonable to me, feel free to open a PR :)"
] | 2025-01-21 22:35:07 | 2025-01-30 13:56:56 | null | null | NONE | [] | null | null | null | null | ### Feature request
Currently, when datasets are created, they can be versioned by passing the `version` argument to `load_dataset(...)`. For example creating `outcomes.csv` on the command line
```
echo "id,value\n1,0\n2,0\n3,1\n4,1\n" > outcomes.csv
```
and creating it
```
import datasets
dataset = datasets.load_dat... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7378/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7378/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7377 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7377/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7377/comments | https://api.github.com/repos/huggingface/datasets/issues/7377/events | https://github.com/huggingface/datasets/issues/7377 | 2,802,723,285 | I_kwDODunzps6nDinV | 7,377 | Support for sparse arrays with the Arrow Sparse Tensor format? | {
"login": "JulesGM",
"id": 3231217,
"node_id": "MDQ6VXNlcjMyMzEyMTc=",
"avatar_url": "https://avatars.githubusercontent.com/u/3231217?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JulesGM",
"html_url": "https://github.com/JulesGM",
"followers_url": "https://api.github.com/users/JulesGM/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! Unfortunately the Sparse Tensor structure in Arrow is not part of the Arrow format (yes it's confusing...), so it's not possible to use it in `datasets`. It's a separate structure that doesn't correspond to any type or extension type in Arrow.\n\nThe Arrow community recently added an extension type for fixed ... | 2025-01-21 20:14:35 | 2026-02-03 23:05:02 | null | null | NONE | [] | null | null | null | null | ### Feature request
AI in biology is becoming a big thing. One thing that would be a huge benefit to the field that Huggingface Datasets doesn't currently have is native support for **sparse arrays**.
Arrow has support for sparse tensors.
https://arrow.apache.org/docs/format/Other.html#sparse-tensor
It would be ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7377/reactions",
"total_count": 4,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 2
} | https://api.github.com/repos/huggingface/datasets/issues/7377/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7375 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7375/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7375/comments | https://api.github.com/repos/huggingface/datasets/issues/7375/events | https://github.com/huggingface/datasets/issues/7375 | 2,800,609,218 | I_kwDODunzps6m7efC | 7,375 | vllm批量推理报错 | {
"login": "YuShengzuishuai",
"id": 51228154,
"node_id": "MDQ6VXNlcjUxMjI4MTU0",
"avatar_url": "https://avatars.githubusercontent.com/u/51228154?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/YuShengzuishuai",
"html_url": "https://github.com/YuShengzuishuai",
"followers_url": "https://api... | [] | open | false | [] | null | [
"Make sure you have installed a recent version of `soundfile`"
] | 2025-01-21 03:22:23 | 2025-01-30 14:02:40 | null | null | NONE | [] | null | null | null | null | ### Describe the bug

### Steps to reproduce the bug
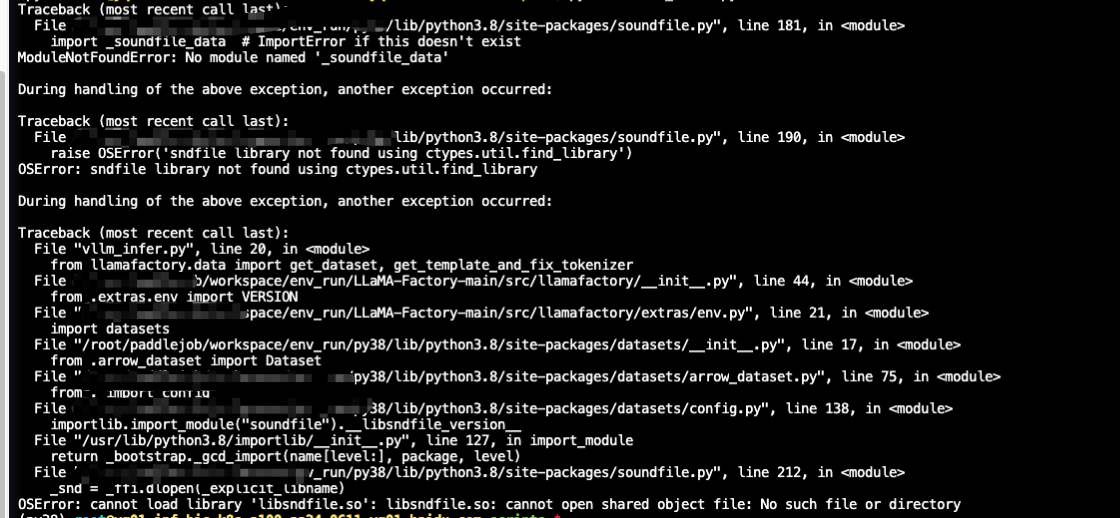
### Expected behavior
\n\n\n\nAdding a img from memray\nhttps://gist.github.com/sam-hey/00c958f13fb0f7b54d17197fe353002f",
"I'm having the same issue where c... | 2025-01-16 16:33:10 | 2025-03-27 17:40:59 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When loading a dataset from disk, concatenating it, and starting the training process, the RAM usage progressively increases until the kernel terminates the process due to excessive memory consumption.
https://github.com/huggingface/datasets/issues/2276
### Steps to reproduce the bug
```python
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7373/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7373/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7372 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7372/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7372/comments | https://api.github.com/repos/huggingface/datasets/issues/7372/events | https://github.com/huggingface/datasets/issues/7372 | 2,791,760,968 | I_kwDODunzps6mZuRI | 7,372 | Inconsistent Behavior Between `load_dataset` and `load_from_disk` When Loading Sharded Datasets | {
"login": "gaohongkui",
"id": 38203359,
"node_id": "MDQ6VXNlcjM4MjAzMzU5",
"avatar_url": "https://avatars.githubusercontent.com/u/38203359?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/gaohongkui",
"html_url": "https://github.com/gaohongkui",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [] | 2025-01-16 05:47:20 | 2025-01-16 05:47:20 | null | null | NONE | [] | null | null | null | null | ### Description
I encountered an inconsistency in behavior between `load_dataset` and `load_from_disk` when loading sharded datasets. Here is a minimal example to reproduce the issue:
#### Code 1: Using `load_dataset`
```python
from datasets import Dataset, load_dataset
# First save with max_shard_size=10
Dataset.fr... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7372/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7372/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7371 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7371/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7371/comments | https://api.github.com/repos/huggingface/datasets/issues/7371/events | https://github.com/huggingface/datasets/issues/7371 | 2,790,549,889 | I_kwDODunzps6mVGmB | 7,371 | 500 Server error with pushing a dataset | {
"login": "martinmatak",
"id": 7677814,
"node_id": "MDQ6VXNlcjc2Nzc4MTQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/7677814?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/martinmatak",
"html_url": "https://github.com/martinmatak",
"followers_url": "https://api.github.com/us... | [] | open | false | [] | null | [
"EDIT: seems to be all good now. I'll add a comment if the error happens again within the next 48 hours. If it doesn't, I'll just close the topic."
] | 2025-01-15 18:23:02 | 2025-01-15 20:06:05 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Suddenly, I started getting this error message saying it was an internal error.
`Error creating/pushing dataset: 500 Server Error: Internal Server Error for url: https://huggingface.co/api/datasets/ll4ma-lab/grasp-dataset/commit/main (Request ID: Root=1-6787f0b7-66d5bd45413e481c4c2fb22d;670d04ff-... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7371/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7371/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7369 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7369/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7369/comments | https://api.github.com/repos/huggingface/datasets/issues/7369/events | https://github.com/huggingface/datasets/issues/7369 | 2,787,193,238 | I_kwDODunzps6mITGW | 7,369 | Importing dataset gives unhelpful error message when filenames in metadata.csv are not found in the directory | {
"login": "svencornetsdegroot",
"id": 38278139,
"node_id": "MDQ6VXNlcjM4Mjc4MTM5",
"avatar_url": "https://avatars.githubusercontent.com/u/38278139?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/svencornetsdegroot",
"html_url": "https://github.com/svencornetsdegroot",
"followers_url": "ht... | [] | open | false | [] | null | [
"I'd prefer even more verbose errors; like `\"file123.mp3\" is referenced in metadata.csv, but not found in the data directory '/path/to/audiofolder' ! (and 100+ more missing files)` Or something along those lines."
] | 2025-01-14 13:53:21 | 2025-01-14 15:05:51 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
While importing an audiofolder dataset, where the names of the audiofiles don't correspond to the filenames in the metadata.csv, we get an unclear error message that is not helpful for the debugging, i.e.
```
ValueError: Instruction "train" corresponds to no data!
```
### Steps to reproduce the ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7369/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7369/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7366 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7366/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7366/comments | https://api.github.com/repos/huggingface/datasets/issues/7366/events | https://github.com/huggingface/datasets/issues/7366 | 2,781,522,894 | I_kwDODunzps6lyqvO | 7,366 | Dataset.from_dict() can't handle large dict | {
"login": "CSU-OSS",
"id": 164967134,
"node_id": "U_kgDOCdUy3g",
"avatar_url": "https://avatars.githubusercontent.com/u/164967134?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/CSU-OSS",
"html_url": "https://github.com/CSU-OSS",
"followers_url": "https://api.github.com/users/CSU-OSS/foll... | [] | open | false | [] | null | [] | 2025-01-11 02:05:21 | 2025-01-11 02:05:21 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I have 26,000,000 3-tuples. When I use Dataset.from_dict() to load, neither. py nor Jupiter notebook can run successfully. This is my code:
```
# len(example_data) is 26,000,000, 'diff' is a text
diff1_list = [example_data[i].texts[0] for i in range(len(example_data))]
diff2_list =... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7366/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7366/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7365 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7365/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7365/comments | https://api.github.com/repos/huggingface/datasets/issues/7365/events | https://github.com/huggingface/datasets/issues/7365 | 2,780,216,199 | I_kwDODunzps6ltruH | 7,365 | A parameter is specified but not used in datasets.arrow_dataset.Dataset.from_pandas() | {
"login": "NourOM02",
"id": 69003192,
"node_id": "MDQ6VXNlcjY5MDAzMTky",
"avatar_url": "https://avatars.githubusercontent.com/u/69003192?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NourOM02",
"html_url": "https://github.com/NourOM02",
"followers_url": "https://api.github.com/users/Nou... | [] | open | false | [] | null | [] | 2025-01-10 13:39:33 | 2025-01-10 13:39:33 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am interested in creating train, test and eval splits from a pandas Dataframe, therefore I was looking at the possibilities I can follow. I noticed the split parameter and was hopeful to use it in order to generate the 3 at once, however, while trying to understand the code, i noticed that it ha... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7365/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7365/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7364 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7364/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7364/comments | https://api.github.com/repos/huggingface/datasets/issues/7364/events | https://github.com/huggingface/datasets/issues/7364 | 2,776,929,268 | I_kwDODunzps6lhJP0 | 7,364 | API endpoints for gated dataset access requests | {
"login": "jerome-white",
"id": 6140840,
"node_id": "MDQ6VXNlcjYxNDA4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6140840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jerome-white",
"html_url": "https://github.com/jerome-white",
"followers_url": "https://api.github.com... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Looks like a [similar feature request](https://github.com/huggingface/huggingface_hub/issues/1198) was made to the HF Hub team. Is handling this at the Hub level more appropriate?\r\n\r\n(As an aside, I've gotten the [HTTP-based solution](https://github.com/huggingface/huggingface_hub/issues/1198#issuecomment-1905... | 2025-01-09 06:21:20 | 2025-01-09 11:17:40 | 2025-01-09 11:17:20 | null | NONE | [] | null | null | null | null | ### Feature request
I would like a programatic way of requesting access to gated datasets. The current solution to gain access forces me to visit a website and physically click an "agreement" button (as per the [documentation](https://huggingface.co/docs/hub/en/datasets-gated#access-gated-datasets-as-a-user)).
An i... | {
"login": "jerome-white",
"id": 6140840,
"node_id": "MDQ6VXNlcjYxNDA4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6140840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jerome-white",
"html_url": "https://github.com/jerome-white",
"followers_url": "https://api.github.com... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7364/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7364/timeline | null | not_planned | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.