
text stringlengths 5 409k | id stringlengths 14 178 | metadata dict | __index_level_0__ int64 0 572 |
|---|---|---|---|
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/examples/community/pipeline_sdxl_style_aligned.py/0 | {
"file_path": "diffusers/examples/community/pipeline_sdxl_style_aligned.py",
"repo_id": "diffusers",
"token_count": 42215
} | 87 |
#!/usr/bin/env python
# coding=utf-8
# Copyright 2024 The LCM team and the HuggingFace Inc. team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apach... | diffusers/examples/consistency_distillation/train_lcm_distill_lora_sdxl.py/0 | {
"file_path": "diffusers/examples/consistency_distillation/train_lcm_distill_lora_sdxl.py",
"repo_id": "diffusers",
"token_count": 27822
} | 88 |
#!/usr/bin/env python
# coding=utf-8
# Copyright 2025 The HuggingFace Inc. team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LI... | diffusers/examples/controlnet/train_controlnet_flux.py/0 | {
"file_path": "diffusers/examples/controlnet/train_controlnet_flux.py",
"repo_id": "diffusers",
"token_count": 26117
} | 89 |
# InstructPix2Pix SDXL training example
***This is based on the original InstructPix2Pix training example.***
[Stable Diffusion XL](https://huggingface.co/papers/2307.01952) (or SDXL) is the latest image generation model that is tailored towards more photorealistic outputs with more detailed imagery and composition c... | diffusers/examples/instruct_pix2pix/README_sdxl.md/0 | {
"file_path": "diffusers/examples/instruct_pix2pix/README_sdxl.md",
"repo_id": "diffusers",
"token_count": 3484
} | 90 |
import d4rl # noqa
import gym
import tqdm
from diffusers.experimental import ValueGuidedRLPipeline
config = {
"n_samples": 64,
"horizon": 32,
"num_inference_steps": 20,
"n_guide_steps": 2, # can set to 0 for faster sampling, does not use value network
"scale_grad_by_std": True,
"scale": 0.1,... | diffusers/examples/reinforcement_learning/run_diffuser_locomotion.py/0 | {
"file_path": "diffusers/examples/reinforcement_learning/run_diffuser_locomotion.py",
"repo_id": "diffusers",
"token_count": 724
} | 91 |
# GLIGEN: Open-Set Grounded Text-to-Image Generation
These scripts contain the code to prepare the grounding data and train the GLIGEN model on COCO dataset.
### Install the requirements
```bash
conda create -n diffusers python==3.10
conda activate diffusers
pip install -r requirements.txt
```
And initialize an [🤗... | diffusers/examples/research_projects/gligen/README.md/0 | {
"file_path": "diffusers/examples/research_projects/gligen/README.md",
"repo_id": "diffusers",
"token_count": 1748
} | 92 |
import argparse
import math
import os
import torch
from neural_compressor.utils.pytorch import load
from PIL import Image
from transformers import CLIPTextModel, CLIPTokenizer
from diffusers import AutoencoderKL, StableDiffusionPipeline, UNet2DConditionModel
def parse_args():
parser = argparse.ArgumentParser()
... | diffusers/examples/research_projects/intel_opts/textual_inversion_dfq/text2images.py/0 | {
"file_path": "diffusers/examples/research_projects/intel_opts/textual_inversion_dfq/text2images.py",
"repo_id": "diffusers",
"token_count": 1518
} | 93 |
import argparse
import copy
import itertools
import logging
import math
import os
import random
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
import torch.utils.checkpoint
from accelerate import Accelerator
from accelerate.logging import get_logger
from accelerate.utils impor... | diffusers/examples/research_projects/multi_subject_dreambooth_inpainting/train_multi_subject_dreambooth_inpainting.py/0 | {
"file_path": "diffusers/examples/research_projects/multi_subject_dreambooth_inpainting/train_multi_subject_dreambooth_inpainting.py",
"repo_id": "diffusers",
"token_count": 10829
} | 94 |
import argparse
import inspect
import logging
import math
import os
from pathlib import Path
import accelerate
import datasets
import torch
import torch.nn.functional as F
from accelerate import Accelerator
from accelerate.logging import get_logger
from accelerate.utils import ProjectConfiguration
from datasets import... | diffusers/examples/research_projects/onnxruntime/unconditional_image_generation/train_unconditional.py/0 | {
"file_path": "diffusers/examples/research_projects/onnxruntime/unconditional_image_generation/train_unconditional.py",
"repo_id": "diffusers",
"token_count": 12783
} | 95 |
import argparse
import os
import random
import time
from pathlib import Path
import datasets
import numpy as np
import torch
import torch.nn.functional as F
import torch.utils.checkpoint
import torch_xla.core.xla_model as xm
import torch_xla.debug.profiler as xp
import torch_xla.distributed.parallel_loader as pl
impor... | diffusers/examples/research_projects/pytorch_xla/training/text_to_image/train_text_to_image_xla.py/0 | {
"file_path": "diffusers/examples/research_projects/pytorch_xla/training/text_to_image/train_text_to_image_xla.py",
"repo_id": "diffusers",
"token_count": 10499
} | 96 |
# Running Stable Diffusion 3 DreamBooth LoRA training under 16GB
This is an **EDUCATIONAL** project that provides utilities for DreamBooth LoRA training for [Stable Diffusion 3 (SD3)](ttps://huggingface.co/papers/2403.03206) under 16GB GPU VRAM. This means you can successfully try out this project using a [free-tier C... | diffusers/examples/research_projects/sd3_lora_colab/README.md/0 | {
"file_path": "diffusers/examples/research_projects/sd3_lora_colab/README.md",
"repo_id": "diffusers",
"token_count": 706
} | 97 |
torch~=2.4.0
transformers==4.46.1
sentencepiece
aiohttp
py-consul
prometheus_client >= 0.18.0
prometheus-fastapi-instrumentator >= 7.0.0
fastapi
uvicorn | diffusers/examples/server/requirements.in/0 | {
"file_path": "diffusers/examples/server/requirements.in",
"repo_id": "diffusers",
"token_count": 65
} | 98 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/examples/unconditional_image_generation/test_unconditional.py/0 | {
"file_path": "diffusers/examples/unconditional_image_generation/test_unconditional.py",
"repo_id": "diffusers",
"token_count": 2492
} | 99 |
import argparse
import torch
from huggingface_hub import hf_hub_download
from diffusers.models.transformers.auraflow_transformer_2d import AuraFlowTransformer2DModel
def load_original_state_dict(args):
model_pt = hf_hub_download(repo_id=args.original_state_dict_repo_id, filename="aura_diffusion_pytorch_model.bi... | diffusers/scripts/convert_aura_flow_to_diffusers.py/0 | {
"file_path": "diffusers/scripts/convert_aura_flow_to_diffusers.py",
"repo_id": "diffusers",
"token_count": 2540
} | 100 |
import argparse
from contextlib import nullcontext
import safetensors.torch
from accelerate import init_empty_weights
from huggingface_hub import hf_hub_download
from diffusers.utils.import_utils import is_accelerate_available, is_transformers_available
if is_transformers_available():
from transformers import C... | diffusers/scripts/convert_flux_xlabs_ipadapter_to_diffusers.py/0 | {
"file_path": "diffusers/scripts/convert_flux_xlabs_ipadapter_to_diffusers.py",
"repo_id": "diffusers",
"token_count": 1463
} | 101 |
import json
import os
import torch
from diffusers import UNet1DModel
os.makedirs("hub/hopper-medium-v2/unet/hor32", exist_ok=True)
os.makedirs("hub/hopper-medium-v2/unet/hor128", exist_ok=True)
os.makedirs("hub/hopper-medium-v2/value_function", exist_ok=True)
def unet(hor):
if hor == 128:
down_block_... | diffusers/scripts/convert_models_diffuser_to_diffusers.py/0 | {
"file_path": "diffusers/scripts/convert_models_diffuser_to_diffusers.py",
"repo_id": "diffusers",
"token_count": 1700
} | 102 |
import argparse
import tempfile
import torch
from accelerate import load_checkpoint_and_dispatch
from diffusers.models.transformers.prior_transformer import PriorTransformer
from diffusers.pipelines.shap_e import ShapERenderer
"""
Example - From the diffusers root directory:
Download weights:
```sh
$ wget "https:... | diffusers/scripts/convert_shap_e_to_diffusers.py/0 | {
"file_path": "diffusers/scripts/convert_shap_e_to_diffusers.py",
"repo_id": "diffusers",
"token_count": 22932
} | 103 |
"""
This script modified from
https://github.com/huggingface/diffusers/blob/bc691231360a4cbc7d19a58742ebb8ed0f05e027/scripts/convert_original_stable_diffusion_to_diffusers.py
Convert original Zero1to3 checkpoint to diffusers checkpoint.
# run the convert script
$ python convert_zero123_to_diffusers.py \
--checkpoi... | diffusers/scripts/convert_zero123_to_diffusers.py/0 | {
"file_path": "diffusers/scripts/convert_zero123_to_diffusers.py",
"repo_id": "diffusers",
"token_count": 15250
} | 104 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/experimental/rl/value_guided_sampling.py/0 | {
"file_path": "diffusers/src/diffusers/experimental/rl/value_guided_sampling.py",
"repo_id": "diffusers",
"token_count": 2639
} | 105 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/loaders/textual_inversion.py/0 | {
"file_path": "diffusers/src/diffusers/loaders/textual_inversion.py",
"repo_id": "diffusers",
"token_count": 12077
} | 106 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/models/autoencoders/autoencoder_kl.py/0 | {
"file_path": "diffusers/src/diffusers/models/autoencoders/autoencoder_kl.py",
"repo_id": "diffusers",
"token_count": 10722
} | 107 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/models/controlnet_sparsectrl.py/0 | {
"file_path": "diffusers/src/diffusers/models/controlnet_sparsectrl.py",
"repo_id": "diffusers",
"token_count": 2376
} | 108 |
# coding=utf-8
# Copyright 2025 The HuggingFace Inc. team.
# Copyright (c) 2022, NVIDIA CORPORATION. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.a... | diffusers/src/diffusers/models/model_loading_utils.py/0 | {
"file_path": "diffusers/src/diffusers/models/model_loading_utils.py",
"repo_id": "diffusers",
"token_count": 9500
} | 109 |
# Copyright 2024 the Latte Team and The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless re... | diffusers/src/diffusers/models/transformers/latte_transformer_3d.py/0 | {
"file_path": "diffusers/src/diffusers/models/transformers/latte_transformer_3d.py",
"repo_id": "diffusers",
"token_count": 7047
} | 110 |
# Copyright 2024 OmniGen team and The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless requ... | diffusers/src/diffusers/models/transformers/transformer_omnigen.py/0 | {
"file_path": "diffusers/src/diffusers/models/transformers/transformer_omnigen.py",
"repo_id": "diffusers",
"token_count": 8866
} | 111 |
from dataclasses import dataclass
from typing import Dict, Optional, Tuple, Union
import torch
import torch.nn as nn
from ...configuration_utils import ConfigMixin, register_to_config
from ...loaders import UNet2DConditionLoadersMixin
from ...utils import BaseOutput, logging
from ..attention_processor import CROSS_AT... | diffusers/src/diffusers/models/unets/unet_spatio_temporal_condition.py/0 | {
"file_path": "diffusers/src/diffusers/models/unets/unet_spatio_temporal_condition.py",
"repo_id": "diffusers",
"token_count": 10332
} | 112 |
from typing import TYPE_CHECKING
from ...utils import (
DIFFUSERS_SLOW_IMPORT,
OptionalDependencyNotAvailable,
_LazyModule,
get_objects_from_module,
is_torch_available,
is_transformers_available,
)
_dummy_objects = {}
_import_structure = {"pipeline_output": ["AnimateDiffPipelineOutput"]}
try... | diffusers/src/diffusers/pipelines/animatediff/__init__.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/animatediff/__init__.py",
"repo_id": "diffusers",
"token_count": 880
} | 113 |
from dataclasses import dataclass
from typing import List, Optional, Union
import numpy as np
import PIL
from PIL import Image
from ...utils import OptionalDependencyNotAvailable, is_torch_available, is_transformers_available
try:
if not (is_transformers_available() and is_torch_available()):
raise Opti... | diffusers/src/diffusers/pipelines/blip_diffusion/__init__.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/blip_diffusion/__init__.py",
"repo_id": "diffusers",
"token_count": 219
} | 114 |
from typing import TYPE_CHECKING
from ...utils import (
DIFFUSERS_SLOW_IMPORT,
_LazyModule,
)
_import_structure = {"pipeline_ddpm": ["DDPMPipeline"]}
if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT:
from .pipeline_ddpm import DDPMPipeline
else:
import sys
sys.modules[__name__] = _LazyModule(
... | diffusers/src/diffusers/pipelines/ddpm/__init__.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/ddpm/__init__.py",
"repo_id": "diffusers",
"token_count": 193
} | 115 |
from dataclasses import dataclass
from typing import Optional, Tuple
import torch
from torch import nn
from transformers import RobertaPreTrainedModel, XLMRobertaConfig, XLMRobertaModel
from transformers.utils import ModelOutput
@dataclass
class TransformationModelOutput(ModelOutput):
"""
Base class for text... | diffusers/src/diffusers/pipelines/deprecated/alt_diffusion/modeling_roberta_series.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/deprecated/alt_diffusion/modeling_roberta_series.py",
"repo_id": "diffusers",
"token_count": 2322
} | 116 |
# Copyright 2022 The Music Spectrogram Diffusion Authors.
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache... | diffusers/src/diffusers/pipelines/deprecated/spectrogram_diffusion/continuous_encoder.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/deprecated/spectrogram_diffusion/continuous_encoder.py",
"repo_id": "diffusers",
"token_count": 1329
} | 117 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/pipelines/deprecated/versatile_diffusion/pipeline_versatile_diffusion_dual_guided.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/deprecated/versatile_diffusion/pipeline_versatile_diffusion_dual_guided.py",
"repo_id": "diffusers",
"token_count": 11632
} | 118 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/pipelines/kandinsky/pipeline_kandinsky.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/kandinsky/pipeline_kandinsky.py",
"repo_id": "diffusers",
"token_count": 8056
} | 119 |
# Copyright 2024 the Latte Team and The HuggingFace Team.
# All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless ... | diffusers/src/diffusers/pipelines/latte/pipeline_latte.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/latte/pipeline_latte.py",
"repo_id": "diffusers",
"token_count": 19152
} | 120 |
# Copyright 2024 Marigold authors, PRS ETH Zurich. All rights reserved.
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# htt... | diffusers/src/diffusers/pipelines/marigold/pipeline_marigold_normals.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/marigold/pipeline_marigold_normals.py",
"repo_id": "diffusers",
"token_count": 14563
} | 121 |
# Copyright 2024 Open AI and The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required ... | diffusers/src/diffusers/pipelines/shap_e/pipeline_shap_e.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/shap_e/pipeline_shap_e.py",
"repo_id": "diffusers",
"token_count": 5908
} | 122 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/src/diffusers/pipelines/stable_diffusion_k_diffusion/pipeline_stable_diffusion_k_diffusion.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/stable_diffusion_k_diffusion/pipeline_stable_diffusion_k_diffusion.py",
"repo_id": "diffusers",
"token_count": 14791
} | 123 |
from typing import TYPE_CHECKING
from ...utils import (
DIFFUSERS_SLOW_IMPORT,
OptionalDependencyNotAvailable,
_LazyModule,
is_torch_available,
is_transformers_available,
is_transformers_version,
)
_dummy_objects = {}
_import_structure = {}
try:
if not (is_transformers_available() and is... | diffusers/src/diffusers/pipelines/unclip/__init__.py/0 | {
"file_path": "diffusers/src/diffusers/pipelines/unclip/__init__.py",
"repo_id": "diffusers",
"token_count": 700
} | 124 |
# Copyright 2024 NVIDIA and The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required b... | diffusers/src/diffusers/schedulers/deprecated/scheduling_karras_ve.py/0 | {
"file_path": "diffusers/src/diffusers/schedulers/deprecated/scheduling_karras_ve.py",
"repo_id": "diffusers",
"token_count": 4063
} | 125 |
# Copyright 2024 Microsoft and The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless require... | diffusers/src/diffusers/schedulers/scheduling_vq_diffusion.py/0 | {
"file_path": "diffusers/src/diffusers/schedulers/scheduling_vq_diffusion.py",
"repo_id": "diffusers",
"token_count": 12476
} | 126 |
# This file is autogenerated by the command `make fix-copies`, do not edit.
from ..utils import DummyObject, requires_backends
class OnnxStableDiffusionImg2ImgPipeline(metaclass=DummyObject):
_backends = ["torch", "transformers", "onnx"]
def __init__(self, *args, **kwargs):
requires_backends(self, ["... | diffusers/src/diffusers/utils/dummy_torch_and_transformers_and_onnx_objects.py/0 | {
"file_path": "diffusers/src/diffusers/utils/dummy_torch_and_transformers_and_onnx_objects.py",
"repo_id": "diffusers",
"token_count": 1270
} | 127 |
import functools
import importlib
import importlib.metadata
import inspect
import io
import logging
import multiprocessing
import os
import random
import re
import struct
import sys
import tempfile
import time
import unittest
import urllib.parse
from contextlib import contextmanager
from io import BytesIO, StringIO
fro... | diffusers/src/diffusers/utils/testing_utils.py/0 | {
"file_path": "diffusers/src/diffusers/utils/testing_utils.py",
"repo_id": "diffusers",
"token_count": 17593
} | 128 |
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or agreed to in writ... | diffusers/tests/lora/test_lora_layers_lumina2.py/0 | {
"file_path": "diffusers/tests/lora/test_lora_layers_lumina2.py",
"repo_id": "diffusers",
"token_count": 1798
} | 129 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/models/autoencoders/test_models_autoencoder_oobleck.py/0 | {
"file_path": "diffusers/tests/models/autoencoders/test_models_autoencoder_oobleck.py",
"repo_id": "diffusers",
"token_count": 3864
} | 130 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/models/transformers/test_models_transformer_aura_flow.py/0 | {
"file_path": "diffusers/tests/models/transformers/test_models_transformer_aura_flow.py",
"repo_id": "diffusers",
"token_count": 1118
} | 131 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/models/transformers/test_models_transformer_temporal.py/0 | {
"file_path": "diffusers/tests/models/transformers/test_models_transformer_temporal.py",
"repo_id": "diffusers",
"token_count": 734
} | 132 |
# Copyright 2024 The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicabl... | diffusers/tests/others/test_dependencies.py/0 | {
"file_path": "diffusers/tests/others/test_dependencies.py",
"repo_id": "diffusers",
"token_count": 775
} | 133 |
# coding=utf-8
# Copyright 2024 Harutatsu Akiyama, Jinbin Bai, and HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unle... | diffusers/tests/pipelines/controlnet/test_controlnet_inpaint_sdxl.py/0 | {
"file_path": "diffusers/tests/pipelines/controlnet/test_controlnet_inpaint_sdxl.py",
"repo_id": "diffusers",
"token_count": 5966
} | 134 |
import gc
import unittest
import numpy as np
import pytest
import torch
from huggingface_hub import hf_hub_download
from transformers import AutoTokenizer, CLIPTextConfig, CLIPTextModel, CLIPTokenizer, T5EncoderModel
from diffusers import AutoencoderKL, FlowMatchEulerDiscreteScheduler, FluxPipeline, FluxTransformer2D... | diffusers/tests/pipelines/flux/test_pipeline_flux.py/0 | {
"file_path": "diffusers/tests/pipelines/flux/test_pipeline_flux.py",
"repo_id": "diffusers",
"token_count": 7551
} | 135 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/pipelines/kandinsky3/test_kandinsky3.py/0 | {
"file_path": "diffusers/tests/pipelines/kandinsky3/test_kandinsky3.py",
"repo_id": "diffusers",
"token_count": 3586
} | 136 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/pipelines/pag/test_pag_sdxl_img2img.py/0 | {
"file_path": "diffusers/tests/pipelines/pag/test_pag_sdxl_img2img.py",
"repo_id": "diffusers",
"token_count": 5805
} | 137 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/pipelines/semantic_stable_diffusion/test_semantic_diffusion.py/0 | {
"file_path": "diffusers/tests/pipelines/semantic_stable_diffusion/test_semantic_diffusion.py",
"repo_id": "diffusers",
"token_count": 9781
} | 138 |
# coding=utf-8
# Copyright 2024 HuggingFace Inc.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or ag... | diffusers/tests/pipelines/stable_diffusion/test_stable_diffusion_img2img.py/0 | {
"file_path": "diffusers/tests/pipelines/stable_diffusion/test_stable_diffusion_img2img.py",
"repo_id": "diffusers",
"token_count": 13595
} | 139 |
import gc
import random
import unittest
import numpy as np
import pytest
import torch
from transformers import AutoTokenizer, CLIPTextConfig, CLIPTextModelWithProjection, CLIPTokenizer, T5EncoderModel
from diffusers import (
AutoencoderKL,
FlowMatchEulerDiscreteScheduler,
SD3Transformer2DModel,
Stable... | diffusers/tests/pipelines/stable_diffusion_3/test_pipeline_stable_diffusion_3_img2img.py/0 | {
"file_path": "diffusers/tests/pipelines/stable_diffusion_3/test_pipeline_stable_diffusion_3_img2img.py",
"repo_id": "diffusers",
"token_count": 4126
} | 140 |
import contextlib
import io
import re
import unittest
import torch
from PIL import Image
from transformers import CLIPTextConfig, CLIPTextModel, CLIPTokenizer
from diffusers import (
AnimateDiffPipeline,
AnimateDiffVideoToVideoPipeline,
AutoencoderKL,
DDIMScheduler,
MotionAdapter,
StableDiffus... | diffusers/tests/pipelines/test_pipeline_utils.py/0 | {
"file_path": "diffusers/tests/pipelines/test_pipeline_utils.py",
"repo_id": "diffusers",
"token_count": 12422
} | 141 |
import gc
import random
import traceback
import unittest
import numpy as np
import torch
from PIL import Image
from transformers import (
CLIPImageProcessor,
CLIPTextModel,
CLIPTokenizer,
CLIPVisionModelWithProjection,
GPT2Tokenizer,
)
from diffusers import (
AutoencoderKL,
DPMSolverMultis... | diffusers/tests/pipelines/unidiffuser/test_unidiffuser.py/0 | {
"file_path": "diffusers/tests/pipelines/unidiffuser/test_unidiffuser.py",
"repo_id": "diffusers",
"token_count": 14717
} | 142 |
# Copyright 2024 ParaDiGMS authors and The HuggingFace Team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless... | diffusers/tests/schedulers/test_scheduler_ddim_parallel.py/0 | {
"file_path": "diffusers/tests/schedulers/test_scheduler_ddim_parallel.py",
"repo_id": "diffusers",
"token_count": 3801
} | 143 |
import torch
from diffusers import KDPM2DiscreteScheduler
from diffusers.utils.testing_utils import torch_device
from .test_schedulers import SchedulerCommonTest
class KDPM2DiscreteSchedulerTest(SchedulerCommonTest):
scheduler_classes = (KDPM2DiscreteScheduler,)
num_inference_steps = 10
def get_schedul... | diffusers/tests/schedulers/test_scheduler_kdpm2_discrete.py/0 | {
"file_path": "diffusers/tests/schedulers/test_scheduler_kdpm2_discrete.py",
"repo_id": "diffusers",
"token_count": 2878
} | 144 |
# coding=utf-8
# Copyright 2025 The HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable... | diffusers/utils/check_config_docstrings.py/0 | {
"file_path": "diffusers/utils/check_config_docstrings.py",
"repo_id": "diffusers",
"token_count": 1113
} | 145 |
# coding=utf-8
# Copyright 2025 The HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable... | diffusers/utils/overwrite_expected_slice.py/0 | {
"file_path": "diffusers/utils/overwrite_expected_slice.py",
"repo_id": "diffusers",
"token_count": 1259
} | 146 |
This tutorial will explain the training script, how to use it, and particularly how to configure everything needed for the training run.
> **Note:** The following assume you're running these commands on a machine equipped with a cuda GPU. If you don't have one (or if you're using a Mac), you can add `--device=cpu` (`--... | lerobot/examples/4_train_policy_with_script.md/0 | {
"file_path": "lerobot/examples/4_train_policy_with_script.md",
"repo_id": "lerobot",
"token_count": 4869
} | 147 |
## Using / Updating `CODEBASE_VERSION` (for maintainers)
Since our dataset pushed to the hub are decoupled with the evolution of this repo, we ensure compatibility of
the datasets with our code, we use a `CODEBASE_VERSION` (defined in
lerobot/common/datasets/lerobot_dataset.py) variable.
For instance, [`lerobot/pusht... | lerobot/lerobot/common/datasets/push_dataset_to_hub/CODEBASE_VERSION.md/0 | {
"file_path": "lerobot/lerobot/common/datasets/push_dataset_to_hub/CODEBASE_VERSION.md",
"repo_id": "lerobot",
"token_count": 1078
} | 148 |
#!/usr/bin/env python
# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# ... | lerobot/lerobot/common/datasets/push_dataset_to_hub/dora_parquet_format.py/0 | {
"file_path": "lerobot/lerobot/common/datasets/push_dataset_to_hub/dora_parquet_format.py",
"repo_id": "lerobot",
"token_count": 3622
} | 149 |
from .optimizers import OptimizerConfig as OptimizerConfig
| lerobot/lerobot/common/optim/__init__.py/0 | {
"file_path": "lerobot/lerobot/common/optim/__init__.py",
"repo_id": "lerobot",
"token_count": 13
} | 150 |
import torch
import torch.nn.functional as F # noqa: N812
from packaging.version import Version
if Version(torch.__version__) > Version("2.5.0"):
# Ffex attention is only available from torch 2.5 onwards
from torch.nn.attention.flex_attention import (
_mask_mod_signature,
_round_up_to_multiple... | lerobot/lerobot/common/policies/pi0/flex_attention.py/0 | {
"file_path": "lerobot/lerobot/common/policies/pi0/flex_attention.py",
"repo_id": "lerobot",
"token_count": 1891
} | 151 |
import abc
from dataclasses import dataclass
import draccus
@dataclass
class MotorsBusConfig(draccus.ChoiceRegistry, abc.ABC):
@property
def type(self) -> str:
return self.get_choice_name(self.__class__)
@MotorsBusConfig.register_subclass("dynamixel")
@dataclass
class DynamixelMotorsBusConfig(Motor... | lerobot/lerobot/common/robot_devices/motors/configs.py/0 | {
"file_path": "lerobot/lerobot/common/robot_devices/motors/configs.py",
"repo_id": "lerobot",
"token_count": 220
} | 152 |
#!/usr/bin/env python
# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# ... | lerobot/lerobot/common/utils/random_utils.py/0 | {
"file_path": "lerobot/lerobot/common/utils/random_utils.py",
"repo_id": "lerobot",
"token_count": 2878
} | 153 |
#!/usr/bin/env python
# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# ... | lerobot/lerobot/scripts/push_dataset_to_hub.py/0 | {
"file_path": "lerobot/lerobot/scripts/push_dataset_to_hub.py",
"repo_id": "lerobot",
"token_count": 5655
} | 154 |
version https://git-lfs.github.com/spec/v1
oid sha256:35723f2db499da3d9d121aa79d2ff4c748effd7c2ea92f277ec543a82fb843ca
size 3687117
| lerobot/tests/data/save_dataset_to_safetensors/lerobot/aloha_sim_insertion_human/frame_250.safetensors/0 | {
"file_path": "lerobot/tests/data/save_dataset_to_safetensors/lerobot/aloha_sim_insertion_human/frame_250.safetensors",
"repo_id": "lerobot",
"token_count": 66
} | 155 |
version https://git-lfs.github.com/spec/v1
oid sha256:0389a716d51c1c615fb2a3bfa386d89f00b0deca08c4fa21b23e020a939d0213
size 3686488
| lerobot/tests/data/save_image_transforms_to_safetensors/default_transforms.safetensors/0 | {
"file_path": "lerobot/tests/data/save_image_transforms_to_safetensors/default_transforms.safetensors",
"repo_id": "lerobot",
"token_count": 69
} | 156 |
version https://git-lfs.github.com/spec/v1
oid sha256:fcff4b736e95d685d56830b501f4542b081f4334f72d28a7415809f4d9d15d0f
size 68
| lerobot/tests/data/save_policy_to_safetensors/pusht_diffusion/output_dict.safetensors/0 | {
"file_path": "lerobot/tests/data/save_policy_to_safetensors/pusht_diffusion/output_dict.safetensors",
"repo_id": "lerobot",
"token_count": 66
} | 157 |
from functools import cache
import numpy as np
CAP_PROP_FPS = 5
CAP_PROP_FRAME_WIDTH = 3
CAP_PROP_FRAME_HEIGHT = 4
COLOR_RGB2BGR = 4
COLOR_BGR2RGB = 4
ROTATE_90_COUNTERCLOCKWISE = 2
ROTATE_90_CLOCKWISE = 0
ROTATE_180 = 1
@cache
def _generate_image(width: int, height: int):
return np.random.randint(0, 256, size... | lerobot/tests/mock_cv2.py/0 | {
"file_path": "lerobot/tests/mock_cv2.py",
"repo_id": "lerobot",
"token_count": 1099
} | 158 |
import json
from pathlib import Path
from typing import Any
import pytest
from lerobot.common.utils.io_utils import deserialize_json_into_object
@pytest.fixture
def tmp_json_file(tmp_path: Path):
"""Writes `data` to a temporary JSON file and returns the file's path."""
def _write(data: Any) -> Path:
... | lerobot/tests/test_io_utils.py/0 | {
"file_path": "lerobot/tests/test_io_utils.py",
"repo_id": "lerobot",
"token_count": 907
} | 159 |
## Serving DeepSeek-R1 on 2x8 H100 SLURM nodes with SGLang
1. Set up the environment (adjust for your cuda version):
```bash
conda create -n sglang124 python=3.11
conda activate sglang124
pip install torch=2.5.1 --index-url https://download.pytorch.org/whl/cu124
pip install sgl-kernel --force-reinstall --no-deps
pi... | open-r1/slurm/README.md/0 | {
"file_path": "open-r1/slurm/README.md",
"repo_id": "open-r1",
"token_count": 390
} | 160 |
import subprocess
from typing import TYPE_CHECKING, Dict, Union
from .hub import get_gpu_count_for_vllm, get_param_count_from_repo_id
if TYPE_CHECKING:
from trl import GRPOConfig, SFTConfig, ModelConfig
import os
# We need a special environment setup to launch vLLM from within Slurm training jobs.
# - Referen... | open-r1/src/open_r1/utils/evaluation.py/0 | {
"file_path": "open-r1/src/open_r1/utils/evaluation.py",
"repo_id": "open-r1",
"token_count": 1725
} | 161 |
- title: Get started
sections:
- local: index
title: 🤗 PEFT
- local: quicktour
title: Quicktour
- local: install
title: Installation
- title: Tutorial
sections:
- local: tutorial/peft_model_config
title: Configurations and models
- local: tutorial/peft_integrations
title: Integration... | peft/docs/source/_toctree.yml/0 | {
"file_path": "peft/docs/source/_toctree.yml",
"repo_id": "peft",
"token_count": 1373
} | 162 |
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | peft/docs/source/developer_guides/troubleshooting.md/0 | {
"file_path": "peft/docs/source/developer_guides/troubleshooting.md",
"repo_id": "peft",
"token_count": 5420
} | 163 |
from pathlib import Path
import torch
from PIL import Image
from torch.utils.data import Dataset
from torchvision import transforms
class DreamBoothDataset(Dataset):
"""
A dataset to prepare the instance and class images with the prompts for fine-tuning the model.
It pre-processes the images and the toke... | peft/examples/boft_dreambooth/utils/dataset.py/0 | {
"file_path": "peft/examples/boft_dreambooth/utils/dataset.py",
"repo_id": "peft",
"token_count": 1884
} | 164 |
# DoRA: Weight-Decomposed Low-Rank Adaptation
## Introduction
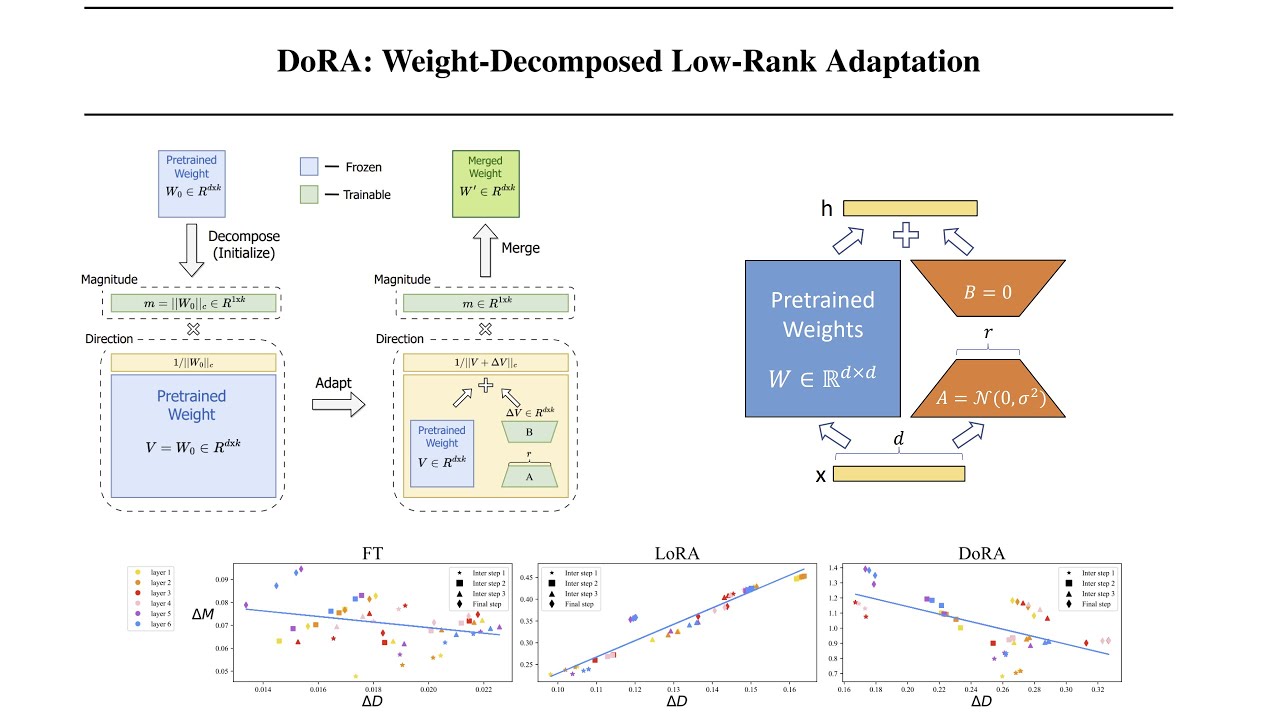
[DoRA](https://arxiv.org/abs/2402.09353) is a novel approach that leverages low rank adaptation through weight decomposition analysis to investigate the inherent differences between full fine-t... | peft/examples/dora_finetuning/README.md/0 | {
"file_path": "peft/examples/dora_finetuning/README.md",
"repo_id": "peft",
"token_count": 1500
} | 165 |
# LoftQ: LoRA-fine-tuning-aware Quantization
## Introduction
LoftQ finds quantized LoRA initialization: quantized backbone Q and LoRA adapters A and B, given a pre-trained weight W.
## Quick Start
Steps:
1. Apply LoftQ to a full-precision pre-trained weight and save.
2. Load LoftQ initialization and train.
For ste... | peft/examples/loftq_finetuning/README.md/0 | {
"file_path": "peft/examples/loftq_finetuning/README.md",
"repo_id": "peft",
"token_count": 1978
} | 166 |
# OLoRA: Orthonormal Low Rank Adaptation of Large Language Models
## Introduction
[OLoRA](https://arxiv.org/abs/2406.01775) is a novel approach that leverages orthonormal low rank adaptation through QR decomposition. Unlike the default LoRA implementation, OLoRA decomposes original weights into their $\mathbf{Q}$ and ... | peft/examples/olora_finetuning/README.md/0 | {
"file_path": "peft/examples/olora_finetuning/README.md",
"repo_id": "peft",
"token_count": 1443
} | 167 |
<jupyter_start><jupyter_text>Using VeRA for sequence classification In this example, we fine-tune Roberta on a sequence classification task using VeRA. Imports<jupyter_code>import torch
from torch.optim import AdamW
from torch.utils.data import DataLoader
from peft import (
get_peft_model,
VeraConfig,
Peft... | peft/examples/sequence_classification/VeRA.ipynb/0 | {
"file_path": "peft/examples/sequence_classification/VeRA.ipynb",
"repo_id": "peft",
"token_count": 2545
} | 168 |
# Copyright 2023 The HuggingFace Team, the AllenNLP library authors. All rights reserved.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
... | peft/scripts/stale.py/0 | {
"file_path": "peft/scripts/stale.py",
"repo_id": "peft",
"token_count": 890
} | 169 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/tuners/adalora/__init__.py/0 | {
"file_path": "peft/src/peft/tuners/adalora/__init__.py",
"repo_id": "peft",
"token_count": 498
} | 170 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/tuners/boft/layer.py/0 | {
"file_path": "peft/src/peft/tuners/boft/layer.py",
"repo_id": "peft",
"token_count": 19780
} | 171 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/tuners/lokr/layer.py/0 | {
"file_path": "peft/src/peft/tuners/lokr/layer.py",
"repo_id": "peft",
"token_count": 7994
} | 172 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/tuners/lora/tp_layer.py/0 | {
"file_path": "peft/src/peft/tuners/lora/tp_layer.py",
"repo_id": "peft",
"token_count": 8506
} | 173 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/tuners/poly/layer.py/0 | {
"file_path": "peft/src/peft/tuners/poly/layer.py",
"repo_id": "peft",
"token_count": 3184
} | 174 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/tuners/vera/config.py/0 | {
"file_path": "peft/src/peft/tuners/vera/config.py",
"repo_id": "peft",
"token_count": 3107
} | 175 |
# Copyright 2023-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/src/peft/utils/peft_types.py/0 | {
"file_path": "peft/src/peft/utils/peft_types.py",
"repo_id": "peft",
"token_count": 2234
} | 176 |
# Note: These tests were copied from test_common_gpu.py and test_gpu_examples.py as they can run on CPU too.
#
# Copyright 2025-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a cop... | peft/tests/test_gptqmodel.py/0 | {
"file_path": "peft/tests/test_gptqmodel.py",
"repo_id": "peft",
"token_count": 6031
} | 177 |
# Copyright 2024-present the HuggingFace Inc. team.
#
# Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# http://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or... | peft/tests/test_torch_compile.py/0 | {
"file_path": "peft/tests/test_torch_compile.py",
"repo_id": "peft",
"token_count": 11038
} | 178 |
# timm
<img class="float-left !m-0 !border-0 !dark:border-0 !shadow-none !max-w-lg w-[150px]" src="https://huggingface.co/front/thumbnails/docs/timm.png"/>
`timm` is a library containing SOTA computer vision models, layers, utilities, optimizers, schedulers, data-loaders, augmentations, and training/evaluation script... | pytorch-image-models/hfdocs/source/index.mdx/0 | {
"file_path": "pytorch-image-models/hfdocs/source/index.mdx",
"repo_id": "pytorch-image-models",
"token_count": 560
} | 179 |
# Wide ResNet
**Wide Residual Networks** are a variant on [ResNets](https://paperswithcode.com/method/resnet) where we decrease depth and increase the width of residual networks. This is achieved through the use of [wide residual blocks](https://paperswithcode.com/method/wide-residual-block).
## How do I use this mod... | pytorch-image-models/hfdocs/source/models/wide-resnet.mdx/0 | {
"file_path": "pytorch-image-models/hfdocs/source/models/wide-resnet.mdx",
"repo_id": "pytorch-image-models",
"token_count": 2037
} | 180 |
# Validation and Benchmark Results
This folder contains validation and benchmark results for the models in this collection. Validation scores are currently only run for models with pretrained weights and ImageNet-1k heads, benchmark numbers are run for all.
## Datasets
There are currently results for the ImageNet va... | pytorch-image-models/results/README.md/0 | {
"file_path": "pytorch-image-models/results/README.md",
"repo_id": "pytorch-image-models",
"token_count": 1173
} | 181 |
from .auto_augment import RandAugment, AutoAugment, rand_augment_ops, auto_augment_policy,\
rand_augment_transform, auto_augment_transform
from .config import resolve_data_config, resolve_model_data_config
from .constants import *
from .dataset import ImageDataset, IterableImageDataset, AugMixDataset
from .dataset_... | pytorch-image-models/timm/data/__init__.py/0 | {
"file_path": "pytorch-image-models/timm/data/__init__.py",
"repo_id": "pytorch-image-models",
"token_count": 256
} | 182 |
""" Random Erasing (Cutout)
Originally inspired by impl at https://github.com/zhunzhong07/Random-Erasing, Apache 2.0
Copyright Zhun Zhong & Liang Zheng
Hacked together by / Copyright 2019, Ross Wightman
"""
import random
import math
import torch
def _get_pixels(per_pixel, rand_color, patch_size, dtype=torch.float3... | pytorch-image-models/timm/data/random_erasing.py/0 | {
"file_path": "pytorch-image-models/timm/data/random_erasing.py",
"repo_id": "pytorch-image-models",
"token_count": 2258
} | 183 |
import math
import numbers
import random
import warnings
from typing import List, Sequence, Tuple, Union
import torch
import torchvision.transforms as transforms
import torchvision.transforms.functional as F
try:
from torchvision.transforms.functional import InterpolationMode
has_interpolation_mode = True
exce... | pytorch-image-models/timm/data/transforms.py/0 | {
"file_path": "pytorch-image-models/timm/data/transforms.py",
"repo_id": "pytorch-image-models",
"token_count": 9216
} | 184 |
""" Conv2d + BN + Act
Hacked together by / Copyright 2020 Ross Wightman
"""
from typing import Any, Dict, Optional, Type
from torch import nn as nn
from .typing import LayerType, PadType
from .blur_pool import create_aa
from .create_conv2d import create_conv2d
from .create_norm_act import get_norm_act_layer
class ... | pytorch-image-models/timm/layers/conv_bn_act.py/0 | {
"file_path": "pytorch-image-models/timm/layers/conv_bn_act.py",
"repo_id": "pytorch-image-models",
"token_count": 1446
} | 185 |
""" Halo Self Attention
Paper: `Scaling Local Self-Attention for Parameter Efficient Visual Backbones`
- https://arxiv.org/abs/2103.12731
@misc{2103.12731,
Author = {Ashish Vaswani and Prajit Ramachandran and Aravind Srinivas and Niki Parmar and Blake Hechtman and
Jonathon Shlens},
Title = {Scaling Local Self... | pytorch-image-models/timm/layers/halo_attn.py/0 | {
"file_path": "pytorch-image-models/timm/layers/halo_attn.py",
"repo_id": "pytorch-image-models",
"token_count": 4601
} | 186 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.