
text stringlengths 5 409k | id stringlengths 14 178 | metadata dict | __index_level_0__ int64 0 572 |
|---|---|---|---|
import pytest
@pytest.fixture(scope="module")
def flash_medusa_handle(launcher):
with launcher(
"FasterDecoding/medusa-vicuna-7b-v1.3", num_shard=2, revision="refs/pr/1"
) as handle:
yield handle
@pytest.fixture(scope="module")
async def flash_medusa(flash_medusa_handle):
await flash_med... | text-generation-inference/integration-tests/models/test_flash_medusa.py/0 | {
"file_path": "text-generation-inference/integration-tests/models/test_flash_medusa.py",
"repo_id": "text-generation-inference",
"token_count": 749
} | 228 |
import pytest
@pytest.fixture(scope="module")
def flash_starcoder2_handle(launcher):
with launcher("bigcode/starcoder2-3b", num_shard=2) as handle:
yield handle
@pytest.fixture(scope="module")
async def flash_starcoder2(flash_starcoder2_handle):
await flash_starcoder2_handle.health(300)
return f... | text-generation-inference/integration-tests/models/test_flash_starcoder2.py/0 | {
"file_path": "text-generation-inference/integration-tests/models/test_flash_starcoder2.py",
"repo_id": "text-generation-inference",
"token_count": 625
} | 229 |
import pytest
@pytest.fixture(scope="module")
def opt_sharded_handle(launcher):
with launcher("facebook/opt-6.7b", num_shard=2) as handle:
yield handle
@pytest.fixture(scope="module")
async def opt_sharded(opt_sharded_handle):
await opt_sharded_handle.health(300)
return opt_sharded_handle.client... | text-generation-inference/integration-tests/models/test_opt.py/0 | {
"file_path": "text-generation-inference/integration-tests/models/test_opt.py",
"repo_id": "text-generation-inference",
"token_count": 160
} | 230 |
import argparse
import datetime
import json
import os
import traceback
from typing import Dict, Tuple, List
import GPUtil
import docker
from docker.models.containers import Container
from loguru import logger
import pandas as pd
class InferenceEngineRunner:
def __init__(self, model: str):
self.model = mo... | text-generation-inference/load_tests/benchmarks.py/0 | {
"file_path": "text-generation-inference/load_tests/benchmarks.py",
"repo_id": "text-generation-inference",
"token_count": 4444
} | 231 |
syntax = "proto3";
package generate.v3;
service TextGenerationService {
/// Model Info
rpc Info(InfoRequest) returns (InfoResponse) {}
/// Service discovery
rpc ServiceDiscovery(ServiceDiscoveryRequest)
returns (ServiceDiscoveryResponse) {}
/// Empties batch cache
rpc ClearCache(ClearCacheRequest) r... | text-generation-inference/proto/v3/generate.proto/0 | {
"file_path": "text-generation-inference/proto/v3/generate.proto",
"repo_id": "text-generation-inference",
"token_count": 2270
} | 232 |
[toolchain]
# Released on: June 13, 2024
# https://releases.rs/docs/1.79.0/
channel = "1.84.0"
components = ["rustfmt", "clippy"]
| text-generation-inference/rust-toolchain.toml/0 | {
"file_path": "text-generation-inference/rust-toolchain.toml",
"repo_id": "text-generation-inference",
"token_count": 54
} | 233 |
#include <ATen/Dispatch.h>
#include <THC/THCAtomics.cuh>
#include <ATen/ATen.h>
#include <torch/torch.h>
#include <vector>
#include <optional>
/**
* Friendly reminder of how multithreading works in CUDA: https://developer.nvidia.com/blog/even-easier-introduction-cuda
* Check example at https://github.com/thomasw21/Li... | text-generation-inference/server/custom_kernels/custom_kernels/fused_bloom_attention_cuda.cu/0 | {
"file_path": "text-generation-inference/server/custom_kernels/custom_kernels/fused_bloom_attention_cuda.cu",
"repo_id": "text-generation-inference",
"token_count": 5345
} | 234 |
from setuptools import setup
from torch.utils.cpp_extension import BuildExtension, CUDAExtension
import torch
extra_cuda_cflags = []
extra_cflags = []
if torch.version.hip:
extra_cflags = ["-DLEGACY_HIPBLAS_DIRECT=ON"]
extra_cuda_cflags = ["-DLEGACY_HIPBLAS_DIRECT=ON"]
extra_compile_args = {
"cxx": extra_... | text-generation-inference/server/exllama_kernels/setup.py/0 | {
"file_path": "text-generation-inference/server/exllama_kernels/setup.py",
"repo_id": "text-generation-inference",
"token_count": 470
} | 235 |
#ifndef _qdq_8_cuh
#define _qdq_8_cuh
#include "qdq_util.cuh"
#include "../../config.h"
#if QMODE_8BIT == 1
// Not implemented
#else
__forceinline__ __device__ void shuffle_8bit_4
(
uint32_t* q,
int stride
)
{
}
__forceinline__ __device__ void dequant_8bit_8
(
const uint32_t q_0,
const uint32_t ... | text-generation-inference/server/exllamav2_kernels/exllamav2_kernels/cuda/quant/qdq_8.cuh/0 | {
"file_path": "text-generation-inference/server/exllamav2_kernels/exllamav2_kernels/cuda/quant/qdq_8.cuh",
"repo_id": "text-generation-inference",
"token_count": 337
} | 236 |
import pytest
from text_generation_server.pb import generate_pb2
from text_generation_server.models.causal_lm import CausalLMBatch, CausalLM
@pytest.fixture(scope="session")
def default_santacoder():
return CausalLM.fallback(model_id="bigcode/santacoder")
@pytest.fixture
def default_pb_request(default_pb_param... | text-generation-inference/server/tests/models/test_santacoder.py/0 | {
"file_path": "text-generation-inference/server/tests/models/test_santacoder.py",
"repo_id": "text-generation-inference",
"token_count": 1480
} | 237 |
import torch
import grpc
from google.rpc import status_pb2, code_pb2
from grpc_status import rpc_status
from grpc_interceptor.server import AsyncServerInterceptor
from loguru import logger
from typing import Callable, Any
class ExceptionInterceptor(AsyncServerInterceptor):
def __init__(self, shutdown_callback):
... | text-generation-inference/server/text_generation_server/interceptor.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/interceptor.py",
"repo_id": "text-generation-inference",
"token_count": 545
} | 238 |
from typing import Any, Dict, List, Union
from compressed_tensors import QuantizationConfig, QuantizationStatus
from compressed_tensors.config import CompressionFormat
from compressed_tensors.quantization import (
QuantizationScheme,
QuantizationType,
find_name_or_class_matches,
)
from loguru import logger... | text-generation-inference/server/text_generation_server/layers/compressed_tensors/loader.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/layers/compressed_tensors/loader.py",
"repo_id": "text-generation-inference",
"token_count": 3149
} | 239 |
import torch
# copied from https://github.com/openppl-public/ppq/blob/master/ppq/quantization/measure/norm.py
def torch_snr_error(
y_pred: torch.Tensor, y_real: torch.Tensor, reduction: str = "mean"
) -> torch.Tensor:
"""
Compute SNR between y_pred(tensor) and y_real(tensor)
SNR can be calcualted as ... | text-generation-inference/server/text_generation_server/layers/gptq/utils.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/layers/gptq/utils.py",
"repo_id": "text-generation-inference",
"token_count": 742
} | 240 |
import os
import math
import torch
from torch import nn
from text_generation_server.utils.import_utils import SYSTEM
if SYSTEM == "cuda":
from text_generation_server.utils.kernels import load_kernel
rotary = load_kernel(module="rotary", repo_id="kernels-community/rotary")
elif SYSTEM == "rocm":
import vll... | text-generation-inference/server/text_generation_server/layers/rotary.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/layers/rotary.py",
"repo_id": "text-generation-inference",
"token_count": 12430
} | 241 |
# coding=utf-8
# Copyright 2022 EleutherAI and the HuggingFace Inc. team. All rights reserved.
#
# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX
# and OPT implementations in this library. It has been modified from its
# original forms to accommodate minor architectural differences compared
# to G... | text-generation-inference/server/text_generation_server/models/custom_modeling/flash_gptj_modeling.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/models/custom_modeling/flash_gptj_modeling.py",
"repo_id": "text-generation-inference",
"token_count": 6420
} | 242 |
# coding=utf-8
# Copyright 2022 EleutherAI and the HuggingFace Inc. team. All rights reserved.
#
# This code is based on EleutherAI's GPT-NeoX library and the GPT-NeoX
# and OPT implementations in this library. It has been modified from its
# original forms to accommodate minor architectural differences compared
# to G... | text-generation-inference/server/text_generation_server/models/custom_modeling/idefics_modeling.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/models/custom_modeling/idefics_modeling.py",
"repo_id": "text-generation-inference",
"token_count": 28598
} | 243 |
from contextlib import nullcontext
import math
import os
import time
import torch
import torch.distributed
import numpy as np
from loguru import logger
from dataclasses import dataclass
from opentelemetry import trace
from transformers import (
PreTrainedTokenizerBase,
AutoConfig,
AutoTokenizer,
Gener... | text-generation-inference/server/text_generation_server/models/flash_causal_lm.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/models/flash_causal_lm.py",
"repo_id": "text-generation-inference",
"token_count": 51951
} | 244 |
from text_generation_server.utils.convert import convert_file, convert_files
from text_generation_server.utils.dist import initialize_torch_distributed
from text_generation_server.utils.weights import Weights
from text_generation_server.utils.peft import download_and_unload_peft
from text_generation_server.utils.hub im... | text-generation-inference/server/text_generation_server/utils/__init__.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/utils/__init__.py",
"repo_id": "text-generation-inference",
"token_count": 417
} | 245 |
# Origin: https://github.com/predibase/lorax
# Path: lorax/server/lorax_server/utils/sgmv.py
# License: Apache License Version 2.0, January 2004
import os
import warnings
from functools import lru_cache
from typing import List, Tuple
import torch
import torch.nn.functional as F
try:
import punica_kernels ... | text-generation-inference/server/text_generation_server/utils/sgmv.py/0 | {
"file_path": "text-generation-inference/server/text_generation_server/utils/sgmv.py",
"repo_id": "text-generation-inference",
"token_count": 3651
} | 246 |
target
.yarn | tokenizers/bindings/node/.prettierignore/0 | {
"file_path": "tokenizers/bindings/node/.prettierignore",
"repo_id": "tokenizers",
"token_count": 5
} | 247 |
{
"name": "tokenizers-darwin-x64",
"version": "0.13.4-rc1",
"os": [
"darwin"
],
"cpu": [
"x64"
],
"main": "tokenizers.darwin-x64.node",
"files": [
"tokenizers.darwin-x64.node"
],
"description": "Tokenizers platform specific bindings",
"keywords": [
"napi-rs",
"NAPI",
"N-API... | tokenizers/bindings/node/npm/darwin-x64/package.json/0 | {
"file_path": "tokenizers/bindings/node/npm/darwin-x64/package.json",
"repo_id": "tokenizers",
"token_count": 268
} | 248 |
{
"name": "tokenizers-win32-ia32-msvc",
"version": "0.13.4-rc1",
"os": [
"win32"
],
"cpu": [
"ia32"
],
"main": "tokenizers.win32-ia32-msvc.node",
"files": [
"tokenizers.win32-ia32-msvc.node"
],
"description": "Tokenizers platform specific bindings",
"keywords": [
"napi-rs",
"NA... | tokenizers/bindings/node/npm/win32-ia32-msvc/package.json/0 | {
"file_path": "tokenizers/bindings/node/npm/win32-ia32-msvc/package.json",
"repo_id": "tokenizers",
"token_count": 277
} | 249 |
use crate::decoders::Decoder;
use crate::encoding::{JsEncoding, JsTruncationDirection, JsTruncationStrategy};
use crate::models::Model;
use crate::normalizers::Normalizer;
use crate::pre_tokenizers::PreTokenizer;
use crate::processors::Processor;
use crate::tasks::tokenizer::{DecodeBatchTask, DecodeTask, EncodeBatchTas... | tokenizers/bindings/node/src/tokenizer.rs/0 | {
"file_path": "tokenizers/bindings/node/src/tokenizer.rs",
"repo_id": "tokenizers",
"token_count": 5713
} | 250 |
import argparse
import logging
import time
from tqdm import tqdm
from tokenizers import Tokenizer, decoders, pre_tokenizers
from tokenizers.models import BPE, WordPiece
from tokenizers.normalizers import BertNormalizer
from tokenizers.processors import BertProcessing
from transformers import BertTokenizer, GPT2Tokeni... | tokenizers/bindings/python/examples/example.py/0 | {
"file_path": "tokenizers/bindings/python/examples/example.py",
"repo_id": "tokenizers",
"token_count": 1770
} | 251 |
# Generated content DO NOT EDIT
from .. import models
Model = models.Model
BPE = models.BPE
Unigram = models.Unigram
WordLevel = models.WordLevel
WordPiece = models.WordPiece
| tokenizers/bindings/python/py_src/tokenizers/models/__init__.py/0 | {
"file_path": "tokenizers/bindings/python/py_src/tokenizers/models/__init__.py",
"repo_id": "tokenizers",
"token_count": 56
} | 252 |
from argparse import ArgumentParser
from json import dump
from logging import basicConfig, getLogger
from os import linesep, remove
from os.path import exists
from tempfile import NamedTemporaryFile
from typing import Dict, List, Tuple
from requests import get
from sentencepiece import SentencePieceProcessor
from tqdm... | tokenizers/bindings/python/scripts/sentencepiece_extractor.py/0 | {
"file_path": "tokenizers/bindings/python/scripts/sentencepiece_extractor.py",
"repo_id": "tokenizers",
"token_count": 2231
} | 253 |
use super::regex::PyRegex;
use super::{DestroyPtr, RefMutContainer, RefMutGuard};
use crate::error::ToPyResult;
use pyo3::exceptions;
use pyo3::prelude::*;
use pyo3::types::*;
use tk::normalizer::{char_to_bytes, NormalizedString, Range, SplitDelimiterBehavior};
use tk::pattern::Pattern;
/// Represents a Pattern as use... | tokenizers/bindings/python/src/utils/normalization.rs/0 | {
"file_path": "tokenizers/bindings/python/src/utils/normalization.rs",
"repo_id": "tokenizers",
"token_count": 8560
} | 254 |
# Decoders
<tokenizerslangcontent>
<python>
## BPEDecoder
[[autodoc]] tokenizers.decoders.BPEDecoder
## ByteLevel
[[autodoc]] tokenizers.decoders.ByteLevel
## CTC
[[autodoc]] tokenizers.decoders.CTC
## Metaspace
[[autodoc]] tokenizers.decoders.Metaspace
## WordPiece
[[autodoc]] tokenizers.decoders.WordPiece
<... | tokenizers/docs/source-doc-builder/api/decoders.mdx/0 | {
"file_path": "tokenizers/docs/source-doc-builder/api/decoders.mdx",
"repo_id": "tokenizers",
"token_count": 197
} | 255 |
# Training from memory
In the [Quicktour](quicktour), we saw how to build and train a
tokenizer using text files, but we can actually use any Python Iterator.
In this section we'll see a few different ways of training our
tokenizer.
For all the examples listed below, we'll use the same [`~tokenizers.Tokenizer`] and
[... | tokenizers/docs/source-doc-builder/training_from_memory.mdx/0 | {
"file_path": "tokenizers/docs/source-doc-builder/training_from_memory.mdx",
"repo_id": "tokenizers",
"token_count": 1199
} | 256 |
# Configuration file for the Sphinx documentation builder.
#
# This file only contains a selection of the most common options. For a full
# list see the documentation:
# https://www.sphinx-doc.org/en/master/usage/configuration.html
# -- Path setup --------------------------------------------------------------
# If ex... | tokenizers/docs/source/conf.py/0 | {
"file_path": "tokenizers/docs/source/conf.py",
"repo_id": "tokenizers",
"token_count": 781
} | 257 |
#[macro_use]
extern crate criterion;
mod common;
use std::fs::File;
use std::io::{BufRead, BufReader};
use std::path::Path;
use criterion::Criterion;
use tokenizers::models::wordpiece::{WordPiece, WordPieceTrainerBuilder};
use tokenizers::normalizers::{BertNormalizer, NormalizerWrapper};
use tokenizers::pre_tokenize... | tokenizers/tokenizers/benches/bert_benchmark.rs/0 | {
"file_path": "tokenizers/tokenizers/benches/bert_benchmark.rs",
"repo_id": "tokenizers",
"token_count": 1657
} | 258 |
language: node_js
node_js: "10"
script:
- ./node_modules/.bin/webpack
| tokenizers/tokenizers/examples/unstable_wasm/www/.travis.yml/0 | {
"file_path": "tokenizers/tokenizers/examples/unstable_wasm/www/.travis.yml",
"repo_id": "tokenizers",
"token_count": 30
} | 259 |
use crate::decoders::DecoderWrapper;
use crate::tokenizer::{Decoder, Result};
use crate::utils::macro_rules_attribute;
use serde::{Deserialize, Serialize};
#[derive(Clone, Debug)]
#[macro_rules_attribute(impl_serde_type!)]
pub struct Sequence {
decoders: Vec<DecoderWrapper>,
}
impl Sequence {
pub fn new(decod... | tokenizers/tokenizers/src/decoders/sequence.rs/0 | {
"file_path": "tokenizers/tokenizers/src/decoders/sequence.rs",
"repo_id": "tokenizers",
"token_count": 689
} | 260 |
use super::OrderedVocabIter;
use crate::tokenizer::{Model, Result, Token};
use serde_json::Value;
use std::collections::HashMap;
use std::fs::File;
use std::io::{BufReader, Read, Write};
use std::path::{Path, PathBuf};
mod serialization;
mod trainer;
// Re-export
pub use trainer::*;
type Vocab = HashMap<String, u32>... | tokenizers/tokenizers/src/models/wordlevel/mod.rs/0 | {
"file_path": "tokenizers/tokenizers/src/models/wordlevel/mod.rs",
"repo_id": "tokenizers",
"token_count": 3382
} | 261 |
use std::collections::{HashMap, HashSet};
use crate::utils::SysRegex;
use serde::{Deserialize, Serialize};
use crate::tokenizer::{
Decoder, Encoding, PostProcessor, PreTokenizedString, PreTokenizer, Result,
SplitDelimiterBehavior,
};
use crate::utils::macro_rules_attribute;
/// Converts bytes to unicode char... | tokenizers/tokenizers/src/pre_tokenizers/byte_level.rs/0 | {
"file_path": "tokenizers/tokenizers/src/pre_tokenizers/byte_level.rs",
"repo_id": "tokenizers",
"token_count": 11010
} | 262 |
//! # Template Processing
//!
//! Provides a way to specify templates in order to add the special tokens to each
//! input sequence as relevant.
//!
//! ## Example
//!
//! Let's take `BERT` tokenizer as an example. It uses two special tokens, used to
//! delimitate each sequence. `[CLS]` is always used at the beginning... | tokenizers/tokenizers/src/processors/template.rs/0 | {
"file_path": "tokenizers/tokenizers/src/processors/template.rs",
"repo_id": "tokenizers",
"token_count": 21738
} | 263 |
#[cfg(feature = "progressbar")]
pub(crate) use indicatif::{ProgressBar, ProgressStyle};
#[cfg(not(feature = "progressbar"))]
mod progressbar {
use std::borrow::Cow;
pub struct ProgressBar;
impl ProgressBar {
pub fn new(_length: u64) -> Self {
Self {}
}
pub fn set_length... | tokenizers/tokenizers/src/utils/progress.rs/0 | {
"file_path": "tokenizers/tokenizers/src/utils/progress.rs",
"repo_id": "tokenizers",
"token_count": 403
} | 264 |
# Building a React application
In this tutorial, we'll be building a simple React application that performs multilingual translation using Transformers.js! The final product will look something like this:
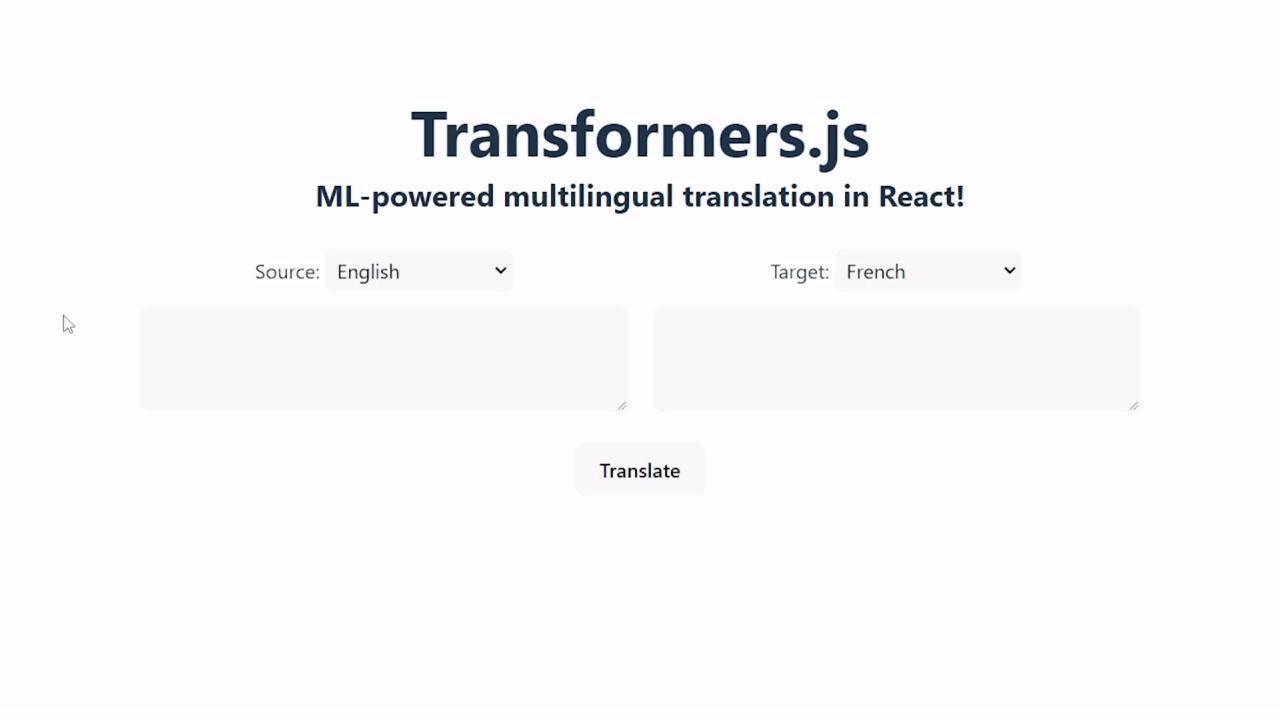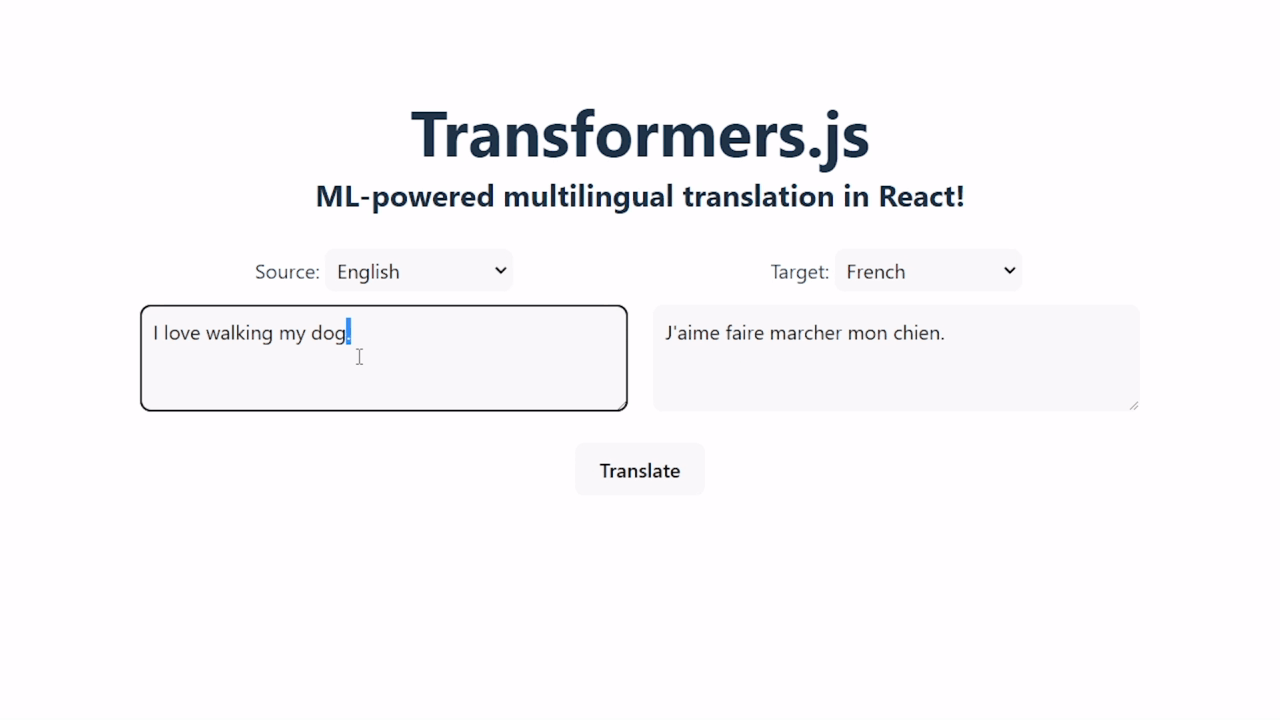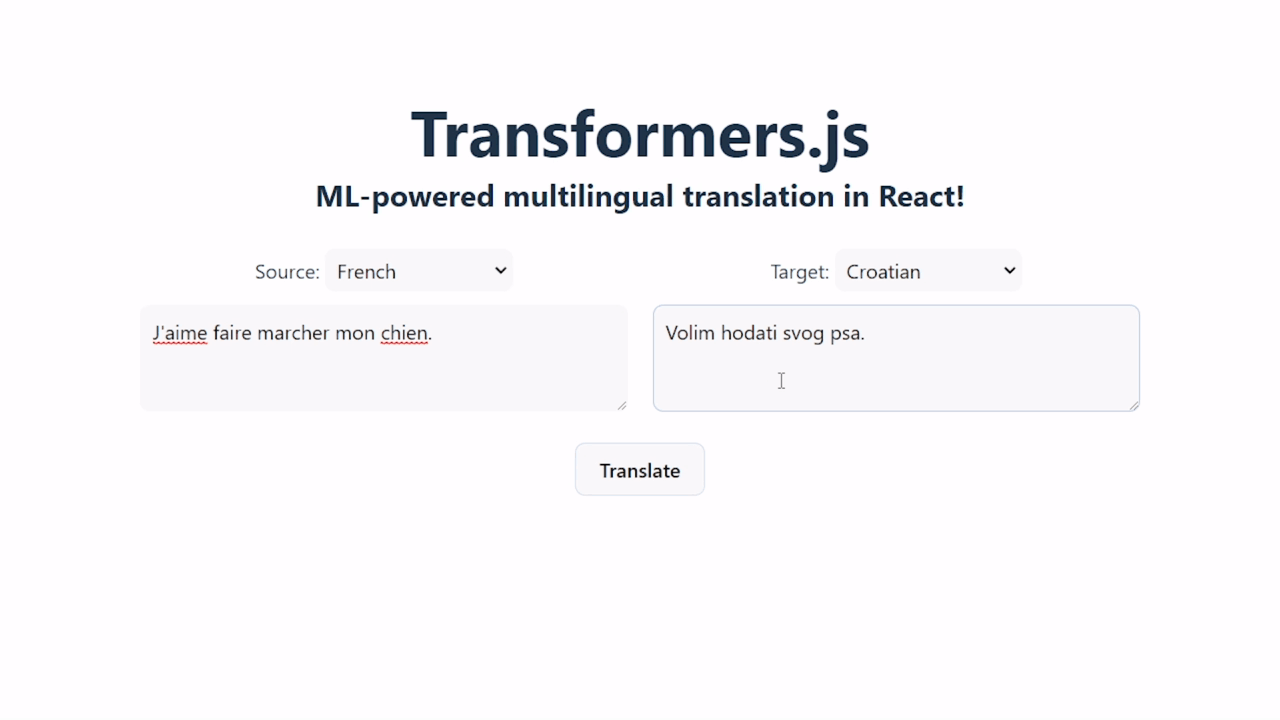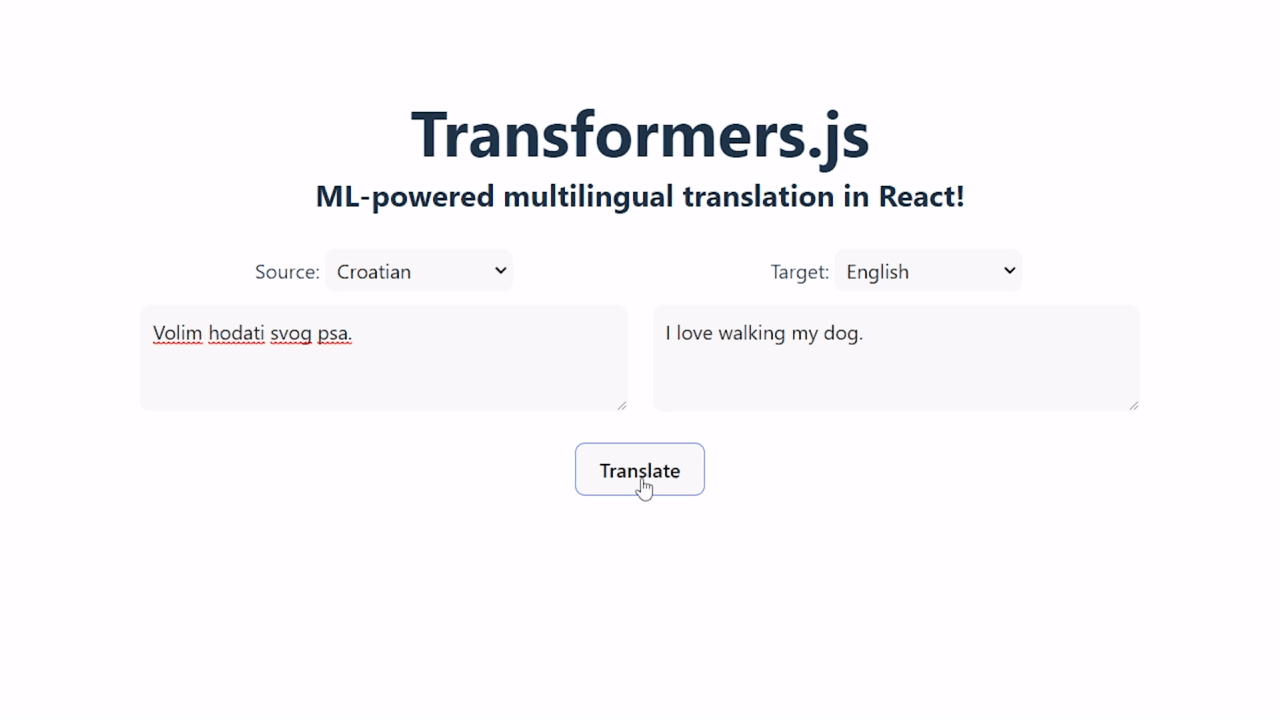
Use... | transformers.js/docs/source/tutorials/react.md/0 | {
"file_path": "transformers.js/docs/source/tutorials/react.md",
"repo_id": "transformers.js",
"token_count": 5891
} | 265 |
<!doctype html>
<html lang="en">
<head>
<meta charset="UTF-8" />
<link rel="icon" type="image/svg+xml" href="/vite.svg" />
<meta name="viewport" content="width=device-width, initial-scale=1.0" />
<title>Reranking w/ Transformers.js</title>
</head>
<body>
<div id="root"></div>
<script type=... | transformers.js/examples/cross-encoder/index.html/0 | {
"file_path": "transformers.js/examples/cross-encoder/index.html",
"repo_id": "transformers.js",
"token_count": 160
} | 266 |
@font-face {
font-family: "bootstrap-icons";
src: url("./bootstrap-icons.woff2") format("woff2"),
url("./bootstrap-icons.woff") format("woff");
}
.bi::before,
[class^="bi-"]::before,
[class*=" bi-"]::before {
display: inline-block;
font-family: bootstrap-icons !important;
font-style: normal;
font-we... | transformers.js/examples/demo-site/public/css/bootstrap-icons.css/0 | {
"file_path": "transformers.js/examples/demo-site/public/css/bootstrap-icons.css",
"repo_id": "transformers.js",
"token_count": 29385
} | 267 |
/////////////////////////////////////////////////////////////////
// Worker.js file for doing all transformer-based computations //
// Needed to ensure the UI thread is not blocked when running //
/////////////////////////////////////////////////////////////////
import { pipeline, env } from "@xenova/transformers";
... | transformers.js/examples/demo-site/src/worker.js/0 | {
"file_path": "transformers.js/examples/demo-site/src/worker.js",
"repo_id": "transformers.js",
"token_count": 6373
} | 268 |
<!DOCTYPE html>
<html>
<head>
<meta charset="UTF-8" />
<title>Transformers.js | Sample Electron application</title>
<!-- Load styles -->
<link rel="stylesheet" href="index.css" />
<!-- Load the client script -->
<script src="./client.js" defer></script>
</head>
<body>
<div class="contain... | transformers.js/examples/electron/src/index.html/0 | {
"file_path": "transformers.js/examples/electron/src/index.html",
"repo_id": "transformers.js",
"token_count": 220
} | 269 |
{
"name": "next",
"version": "0.1.0",
"lockfileVersion": 3,
"requires": true,
"packages": {
"": {
"name": "next",
"version": "0.1.0",
"dependencies": {
"@huggingface/transformers": "^3.0.0-alpha.5",
"autoprefixer": "10.4.14",
"eslint": "8.45.0",
"eslint-co... | transformers.js/examples/next-client/package-lock.json/0 | {
"file_path": "transformers.js/examples/next-client/package-lock.json",
"repo_id": "transformers.js",
"token_count": 116523
} | 270 |
/** @type {import('next').NextConfig} */
const nextConfig = {
// (Optional) Export as a standalone site
// See https://nextjs.org/docs/pages/api-reference/next-config-js/output#automatically-copying-traced-files
output: 'standalone', // Feel free to modify/remove this option
// Indicate that these ... | transformers.js/examples/next-server/next.config.js/0 | {
"file_path": "transformers.js/examples/next-server/next.config.js",
"repo_id": "transformers.js",
"token_count": 164
} | 271 |
{
"name": "commonjs",
"version": "1.0.0",
"description": "Server-side inference with Transformers.js (CommonJS)",
"main": "app.js",
"keywords": [],
"author": "Xenova",
"license": "ISC",
"dependencies": {
"@xenova/transformers": "^2.0.0"
}
}
| transformers.js/examples/node/commonjs/package.json/0 | {
"file_path": "transformers.js/examples/node/commonjs/package.json",
"repo_id": "transformers.js",
"token_count": 109
} | 272 |
<!DOCTYPE html>
<html lang="en">
<head>
<meta charset="UTF-8" />
<meta name="viewport" content="width=device-width, initial-scale=1.0" />
<title>Transformers.js - Background Removal</title>
</head>
<body>
<h1>Background Removal w/ <a href="https://github.com/huggingface/transformers.js" target="_blank">🤗 Tra... | transformers.js/examples/remove-background-client/index.html/0 | {
"file_path": "transformers.js/examples/remove-background-client/index.html",
"repo_id": "transformers.js",
"token_count": 719
} | 273 |
{
"name": "semantic-audio-search",
"version": "0.0.0",
"lockfileVersion": 3,
"requires": true,
"packages": {
"": {
"name": "semantic-audio-search",
"version": "0.0.0",
"dependencies": {
"@xenova/transformers": "^2.10.1",
"deepscatter": "github:nomic-ai/deepscatter"
... | transformers.js/examples/semantic-audio-search/package-lock.json/0 | {
"file_path": "transformers.js/examples/semantic-audio-search/package-lock.json",
"repo_id": "transformers.js",
"token_count": 46220
} | 274 |
'use client'
import Image from 'next/image'
import { downloadImage } from '../utils.js'
export function Modal({ currentImage, setCurrentImage }) {
const photo_url = currentImage ? `https://unsplash.com/photos/${currentImage.id}` : null;
const photo_image_url = currentImage ? `https://images.unsplash.com/${cur... | transformers.js/examples/semantic-image-search-client/src/app/components/Modal.jsx/0 | {
"file_path": "transformers.js/examples/semantic-image-search-client/src/app/components/Modal.jsx",
"repo_id": "transformers.js",
"token_count": 2014
} | 275 |
{
"name": "semantic-image-search",
"version": "0.1.0",
"lockfileVersion": 3,
"requires": true,
"packages": {
"": {
"name": "semantic-image-search",
"version": "0.1.0",
"dependencies": {
"@supabase/supabase-js": "^2.31.0",
"@xenova/transformers": "^2.5.0",
"autopre... | transformers.js/examples/semantic-image-search/package-lock.json/0 | {
"file_path": "transformers.js/examples/semantic-image-search/package-lock.json",
"repo_id": "transformers.js",
"token_count": 115594
} | 276 |
/** @type {import('tailwindcss').Config} */
module.exports = {
content: [
'./src/pages/**/*.{js,ts,jsx,tsx,mdx}',
'./src/components/**/*.{js,ts,jsx,tsx,mdx}',
'./src/app/**/*.{js,ts,jsx,tsx,mdx}',
],
theme: {
extend: {
boxShadow: {
highlight: 'inset 0 0 0 1px rgba(255, 255, 255, 0.1)... | transformers.js/examples/semantic-image-search/tailwind.config.js/0 | {
"file_path": "transformers.js/examples/semantic-image-search/tailwind.config.js",
"repo_id": "transformers.js",
"token_count": 188
} | 277 |
# Vanilla JS Application
This folder contains the source code for a simple web application that detects objects in images using Transformers.js! Check out the demo [here](https://huggingface.co/spaces/Scrimba/vanilla-js-object-detector).
If you'd like to build it yourself, you can follow the [written](https://hugging... | transformers.js/examples/vanilla-js/README.md/0 | {
"file_path": "transformers.js/examples/vanilla-js/README.md",
"repo_id": "transformers.js",
"token_count": 237
} | 278 |
export default {
plugins: {
tailwindcss: {},
autoprefixer: {},
},
}
| transformers.js/examples/webgpu-chat/postcss.config.js/0 | {
"file_path": "transformers.js/examples/webgpu-chat/postcss.config.js",
"repo_id": "transformers.js",
"token_count": 35
} | 279 |
<!DOCTYPE html>
<html lang="en">
<head>
<meta charset="UTF-8" />
<meta name="viewport" content="width=device-width, initial-scale=1.0" />
<title>Transformers.js | real-time CLIP</title>
</head>
<body>
<h1>
Real-time zero-shot image classification (WebGPU)
</h1>
<h3>
Runs locally in your browser w/... | transformers.js/examples/webgpu-clip/index.html/0 | {
"file_path": "transformers.js/examples/webgpu-clip/index.html",
"repo_id": "transformers.js",
"token_count": 417
} | 280 |
import { defineConfig } from 'vite';
export default defineConfig({
build: {
target: 'esnext'
}
});
| transformers.js/examples/webgpu-video-background-removal/vite.config.js/0 | {
"file_path": "transformers.js/examples/webgpu-video-background-removal/vite.config.js",
"repo_id": "transformers.js",
"token_count": 37
} | 281 |
import { marked } from 'marked';
import DOMPurify from 'dompurify';
import BotIcon from './icons/BotIcon';
import UserIcon from './icons/UserIcon';
import './Chat.css';
export default function Chat({ messages }) {
const empty = messages.length === 0;
return (<div className={`flex-1 p-6 max-w-[960px] w-full ... | transformers.js/examples/webgpu-vlm/src/components/Chat.jsx/0 | {
"file_path": "transformers.js/examples/webgpu-vlm/src/components/Chat.jsx",
"repo_id": "transformers.js",
"token_count": 1430
} | 282 |
# TODO: Enable once https://github.com/huggingface/optimum/pull/1552 is merged
# # Support exporting vision and text models separately:
# # Adapted from https://github.com/huggingface/optimum/issues/1186#issuecomment-1637641760
# from optimum.exporters.onnx.model_configs import CLAPTextWithProjectionOnnxConfig, Audio... | transformers.js/scripts/extra/clap.py/0 | {
"file_path": "transformers.js/scripts/extra/clap.py",
"repo_id": "transformers.js",
"token_count": 684
} | 283 |
/**
* @file Helper module for using model configs. For more information, see the corresponding
* [Python documentation](https://huggingface.co/docs/transformers/main/en/model_doc/auto#transformers.AutoConfig).
*
* **Example:** Load an `AutoConfig`.
*
* ```javascript
* import { AutoConfig } from '@huggingface/... | transformers.js/src/configs.js/0 | {
"file_path": "transformers.js/src/configs.js",
"repo_id": "transformers.js",
"token_count": 7215
} | 284 |
import { FeatureExtractor, validate_audio_inputs } from '../../base/feature_extraction_utils.js';
import { Tensor } from '../../utils/tensor.js';
import { mel_filter_bank, spectrogram, window_function } from '../../utils/audio.js';
export class ClapFeatureExtractor extends FeatureExtractor {
constructor(config) ... | transformers.js/src/models/clap/feature_extraction_clap.js/0 | {
"file_path": "transformers.js/src/models/clap/feature_extraction_clap.js",
"repo_id": "transformers.js",
"token_count": 3003
} | 285 |
import {
ImageProcessor,
} from "../../base/image_processors_utils.js";
export class VLMImageProcessor extends ImageProcessor {
constructor(config) {
super({
do_pad: true,
pad_size: {
width: config.image_size,
height: config.image_size,
... | transformers.js/src/models/janus/image_processing_janus.js/0 | {
"file_path": "transformers.js/src/models/janus/image_processing_janus.js",
"repo_id": "transformers.js",
"token_count": 359
} | 286 |
import { OwlViTImageProcessor } from "../owlvit/image_processing_owlvit.js";
// NOTE: extends OwlViTImageProcessor
export class Owlv2ImageProcessor extends OwlViTImageProcessor { }
| transformers.js/src/models/owlv2/image_processing_owlv2.js/0 | {
"file_path": "transformers.js/src/models/owlv2/image_processing_owlv2.js",
"repo_id": "transformers.js",
"token_count": 58
} | 287 |
import { FeatureExtractor, validate_audio_inputs } from '../../base/feature_extraction_utils.js';
import { Tensor } from '../../utils/tensor.js';
import { mel_filter_bank, spectrogram, window_function } from '../../utils/audio.js';
export class SeamlessM4TFeatureExtractor extends FeatureExtractor {
constructor(co... | transformers.js/src/models/seamless_m4t/feature_extraction_seamless_m4t.js/0 | {
"file_path": "transformers.js/src/models/seamless_m4t/feature_extraction_seamless_m4t.js",
"repo_id": "transformers.js",
"token_count": 3364
} | 288 |
/**
* @file Helper module for `Tensor` processing.
*
* These functions and classes are only used internally,
* meaning an end-user shouldn't need to access anything here.
*
* @module utils/tensor
*/
import {
interpolate_data,
max,
min,
permute_data
} from './maths.js';
import {
Tensor as ON... | transformers.js/src/utils/tensor.js/0 | {
"file_path": "transformers.js/src/utils/tensor.js",
"repo_id": "transformers.js",
"token_count": 21491
} | 289 |
import { FalconTokenizer } from "../../../src/tokenizers.js";
import { BASE_TEST_STRINGS, FALCON_TEST_STRINGS } from "../test_strings.js";
export const TOKENIZER_CLASS = FalconTokenizer;
export const TEST_CONFIG = {
"tiiuae/falcon-7b": {
SIMPLE: {
text: BASE_TEST_STRINGS.SIMPLE,
tokens: ["How", "\u01... | transformers.js/tests/models/falcon/test_tokenization_falcon.js/0 | {
"file_path": "transformers.js/tests/models/falcon/test_tokenization_falcon.js",
"repo_id": "transformers.js",
"token_count": 6152
} | 290 |
import { AutoProcessor, full, GroundingDinoProcessor } from "../../../src/transformers.js";
import { load_cached_image } from "../../asset_cache.js";
import { MAX_PROCESSOR_LOAD_TIME, MAX_TEST_EXECUTION_TIME } from "../../init.js";
export default () => {
const model_id = "hf-internal-testing/tiny-random-GroundingDi... | transformers.js/tests/models/grounding_dino/test_processor_grounding_dino.js/0 | {
"file_path": "transformers.js/tests/models/grounding_dino/test_processor_grounding_dino.js",
"repo_id": "transformers.js",
"token_count": 821
} | 291 |
import { AutoImageProcessor, Phi3VImageProcessor } from "../../../src/transformers.js";
import { load_cached_image } from "../../asset_cache.js";
import { MAX_PROCESSOR_LOAD_TIME, MAX_TEST_EXECUTION_TIME } from "../../init.js";
const TARGET_IMAGE_SIZE = [3, 336, 336];
export default () => {
// Phi3VImageProcessor
... | transformers.js/tests/models/phi3_v/test_image_processing_phi3_v.js/0 | {
"file_path": "transformers.js/tests/models/phi3_v/test_image_processing_phi3_v.js",
"repo_id": "transformers.js",
"token_count": 1634
} | 292 |
import { AutoImageProcessor, ViTFeatureExtractor } from "../../../src/transformers.js";
import { load_cached_image } from "../../asset_cache.js";
import { MAX_PROCESSOR_LOAD_TIME, MAX_TEST_EXECUTION_TIME } from "../../init.js";
export default () => {
describe("ViTFeatureExtractor", () => {
const model_id = "Xen... | transformers.js/tests/models/vit/test_image_processing_vit.js/0 | {
"file_path": "transformers.js/tests/models/vit/test_image_processing_vit.js",
"repo_id": "transformers.js",
"token_count": 435
} | 293 |
import { pipeline, FeatureExtractionPipeline } from "../../src/transformers.js";
import { MAX_MODEL_LOAD_TIME, MAX_TEST_EXECUTION_TIME, MAX_MODEL_DISPOSE_TIME, DEFAULT_MODEL_OPTIONS } from "../init.js";
const PIPELINE_ID = "feature-extraction";
export default () => {
describe("Feature Extraction", () => {
cons... | transformers.js/tests/pipelines/test_pipelines_feature_extraction.js/0 | {
"file_path": "transformers.js/tests/pipelines/test_pipelines_feature_extraction.js",
"repo_id": "transformers.js",
"token_count": 2082
} | 294 |
import { pipeline, ZeroShotClassificationPipeline } from "../../src/transformers.js";
import { MAX_MODEL_LOAD_TIME, MAX_TEST_EXECUTION_TIME, MAX_MODEL_DISPOSE_TIME, DEFAULT_MODEL_OPTIONS } from "../init.js";
const PIPELINE_ID = "zero-shot-classification";
export default () => {
describe("Zero-shot Classification",... | transformers.js/tests/pipelines/test_pipelines_zero_shot.js/0 | {
"file_path": "transformers.js/tests/pipelines/test_pipelines_zero_shot.js",
"repo_id": "transformers.js",
"token_count": 1523
} | 295 |
{
// Only include files in the src directory
"include": ["src/**/*"],
"compilerOptions": {
// Tells the compiler to check JS files
"checkJs": true,
"target": "esnext",
"module": "nodenext",
"moduleResolution": "nodenext",
"outDir": "types",
"strict": false,
"skipLibCheck": true,
... | transformers.js/tsconfig.json/0 | {
"file_path": "transformers.js/tsconfig.json",
"repo_id": "transformers.js",
"token_count": 196
} | 296 |
{
"annotations": {
"list": [
{
"builtIn": 1,
"datasource": {
"type": "grafana",
"uid": "-- Grafana --"
},
"enable": true,
"hide": true,
"iconColor": "rgba(0, 211, 255, 1)",
"name": "Annotations & Alerts",
"type": "dashboard"... | transformers/benchmark/grafana_dashboard.json/0 | {
"file_path": "transformers/benchmark/grafana_dashboard.json",
"repo_id": "transformers",
"token_count": 42595
} | 297 |
FROM python:3.9-slim
ENV PYTHONDONTWRITEBYTECODE=1
ARG REF=main
USER root
RUN apt-get update && apt-get install -y time git
ENV UV_PYTHON=/usr/local/bin/python
RUN pip install uv && uv venv
RUN uv pip install --no-cache-dir -U pip setuptools GitPython "git+https://github.com/huggingface/transformers.git@${REF}#egg=tr... | transformers/docker/quality.dockerfile/0 | {
"file_path": "transformers/docker/quality.dockerfile",
"repo_id": "transformers",
"token_count": 168
} | 298 |
apiVersion: v1
kind: PersistentVolume
metadata:
name: huggingface-cluster-disk
spec:
storageClassName: ""
capacity:
storage: 500Gi
accessModes:
- ReadOnlyMany
claimRef:
namespace: default
name: huggingface-cluster-disk-claim
gcePersistentDisk:
pdName: huggingface-cluster-disk
fsType:... | transformers/docker/transformers-pytorch-tpu/dataset.yaml/0 | {
"file_path": "transformers/docker/transformers-pytorch-tpu/dataset.yaml",
"repo_id": "transformers",
"token_count": 274
} | 299 |
# الدردشة مع المحوّلات
إذا كنت تقرأ هذه المقالة، فمن المؤكد أنك على علم بـ **نماذج الدردشة**. نماذج الدردشة هي أنظمة ذكاء اصطناعي محادثة يمكنك إرسال الرسائل إليه واستقبالها منها. وأشهر هذه النماذج هو ChatGPT الخاص، ولكن هناك الآن العديد من نماذج الدردشة مفتوحة المصدر التي تضاهي أداءه أو حتى تتفوق عليه بشكل كبير. هذه ... | transformers/docs/source/ar/conversations.md/0 | {
"file_path": "transformers/docs/source/ar/conversations.md",
"repo_id": "transformers",
"token_count": 13289
} | 300 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/ar/tasks/question_answering.md/0 | {
"file_path": "transformers/docs/source/ar/tasks/question_answering.md",
"repo_id": "transformers",
"token_count": 8612
} | 301 |
<!--Copyright 2020 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/de/add_new_model.md/0 | {
"file_path": "transformers/docs/source/de/add_new_model.md",
"repo_id": "transformers",
"token_count": 23975
} | 302 |
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/de/transformers_agents.md/0 | {
"file_path": "transformers/docs/source/de/transformers_agents.md",
"repo_id": "transformers",
"token_count": 6629
} | 303 |
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/chat_template_tools_and_documents.md/0 | {
"file_path": "transformers/docs/source/en/chat_template_tools_and_documents.md",
"repo_id": "transformers",
"token_count": 4819
} | 304 |
<!---
Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or ... | transformers/docs/source/en/installation.md/0 | {
"file_path": "transformers/docs/source/en/installation.md",
"repo_id": "transformers",
"token_count": 3233
} | 305 |
<!--Copyright 2020 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/main_classes/callback.md/0 | {
"file_path": "transformers/docs/source/en/main_classes/callback.md",
"repo_id": "transformers",
"token_count": 1520
} | 306 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/main_classes/text_generation.md/0 | {
"file_path": "transformers/docs/source/en/main_classes/text_generation.md",
"repo_id": "transformers",
"token_count": 589
} | 307 |
<!--Copyright 2020 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/bert-generation.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/bert-generation.md",
"repo_id": "transformers",
"token_count": 1326
} | 308 |
<!--Copyright 2021 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/byt5.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/byt5.md",
"repo_id": "transformers",
"token_count": 2292
} | 309 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/convnext.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/convnext.md",
"repo_id": "transformers",
"token_count": 1244
} | 310 |
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/efficientnet.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/efficientnet.md",
"repo_id": "transformers",
"token_count": 725
} | 311 |
<!--Copyright 2021 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/fnet.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/fnet.md",
"repo_id": "transformers",
"token_count": 1150
} | 312 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/gpt_neox_japanese.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/gpt_neox_japanese.md",
"repo_id": "transformers",
"token_count": 1075
} | 313 |
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/idefics2.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/idefics2.md",
"repo_id": "transformers",
"token_count": 3213
} | 314 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/levit.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/levit.md",
"repo_id": "transformers",
"token_count": 1801
} | 315 |
<!--Copyright 2021 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/mluke.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/mluke.md",
"repo_id": "transformers",
"token_count": 825
} | 316 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/mvp.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/mvp.md",
"repo_id": "transformers",
"token_count": 1922
} | 317 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/opt.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/opt.md",
"repo_id": "transformers",
"token_count": 8236
} | 318 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/plbart.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/plbart.md",
"repo_id": "transformers",
"token_count": 1586
} | 319 |
<!--Copyright 2021 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/sew-d.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/sew-d.md",
"repo_id": "transformers",
"token_count": 732
} | 320 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/swin.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/swin.md",
"repo_id": "transformers",
"token_count": 1394
} | 321 |
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/tvlt.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/tvlt.md",
"repo_id": "transformers",
"token_count": 1236
} | 322 |
<!--Copyright 2021 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/model_doc/visual_bert.md/0 | {
"file_path": "transformers/docs/source/en/model_doc/visual_bert.md",
"repo_id": "transformers",
"token_count": 1680
} | 323 |
<!---
Copyright 2023 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or ... | transformers/docs/source/en/model_memory_anatomy.md/0 | {
"file_path": "transformers/docs/source/en/model_memory_anatomy.md",
"repo_id": "transformers",
"token_count": 3298
} | 324 |
<!--Copyright 2022 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/perf_train_gpu_one.md/0 | {
"file_path": "transformers/docs/source/en/perf_train_gpu_one.md",
"repo_id": "transformers",
"token_count": 10820
} | 325 |
<!--Copyright 2024 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/quantization/eetq.md/0 | {
"file_path": "transformers/docs/source/en/quantization/eetq.md",
"repo_id": "transformers",
"token_count": 683
} | 326 |
<!--Copyright 2020 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed... | transformers/docs/source/en/task_summary.md/0 | {
"file_path": "transformers/docs/source/en/task_summary.md",
"repo_id": "transformers",
"token_count": 5654
} | 327 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.