

LoopUS: Recasting Pretrained LLMs into Looped Latent Refinement Models
Paper • 2605.11011 • Published • 9
BAELAB, Pusan National University, Busan, Korea
DOLAB, Changwon National University, Changwon, Korea
Taekhyun Park1, Yongjae Lee1, Dohee Kim2, Hyerim Bae1,†
🌟 Github | 🌐 Project Page | 📄 Paper
Looped Depth Up-Scaling (LoopUS) is a post-training framework that converts a standard pretrained LLM into a looped latent refinement model. Instead of extending output traces, LoopUS restructures the model into an encoder, a looped reasoning block, and a decoder, then performs iterative latent refinement in the hidden space. This approach enables test-time compute scaling and improves reasoning-oriented performance without requiring recurrent training from scratch.
This is a re-upload of Thrillcrazyer/Qwen3_1.7B_LoopUS with the context window extended from 40,960 to 262,144 (256K) tokens, matching the Qwen3.5+ series context length.
The Qwen3-1.7B backbone uses full attention with rope_theta = 1,000,000, so the extension is done at load time with YaRN (no weights are modified):
"max_position_embeddings": 262144,
"rope_parameters": {
  "rope_type": "yarn",
  "rope_theta": 1000000,
  "factor": 8.0,
  "original_max_position_embeddings": 32768,
  "beta_fast": 32,
  "beta_slow": 1
}
tokenizer_config.json model_max_length is set to 262144 as well. All credit for the base model and architecture goes to the original authors below.
To use this model, clone the official repository and run the provided scripts:
git clone https://github.com/Thrillcrazyer/LoopUS.git
cd LoopUS
# Install dependencies
uv sync
# Run the chat interface
uv run chat.py --model-name Thrillcrazyer/Qwen3_1.7B_LoopUS
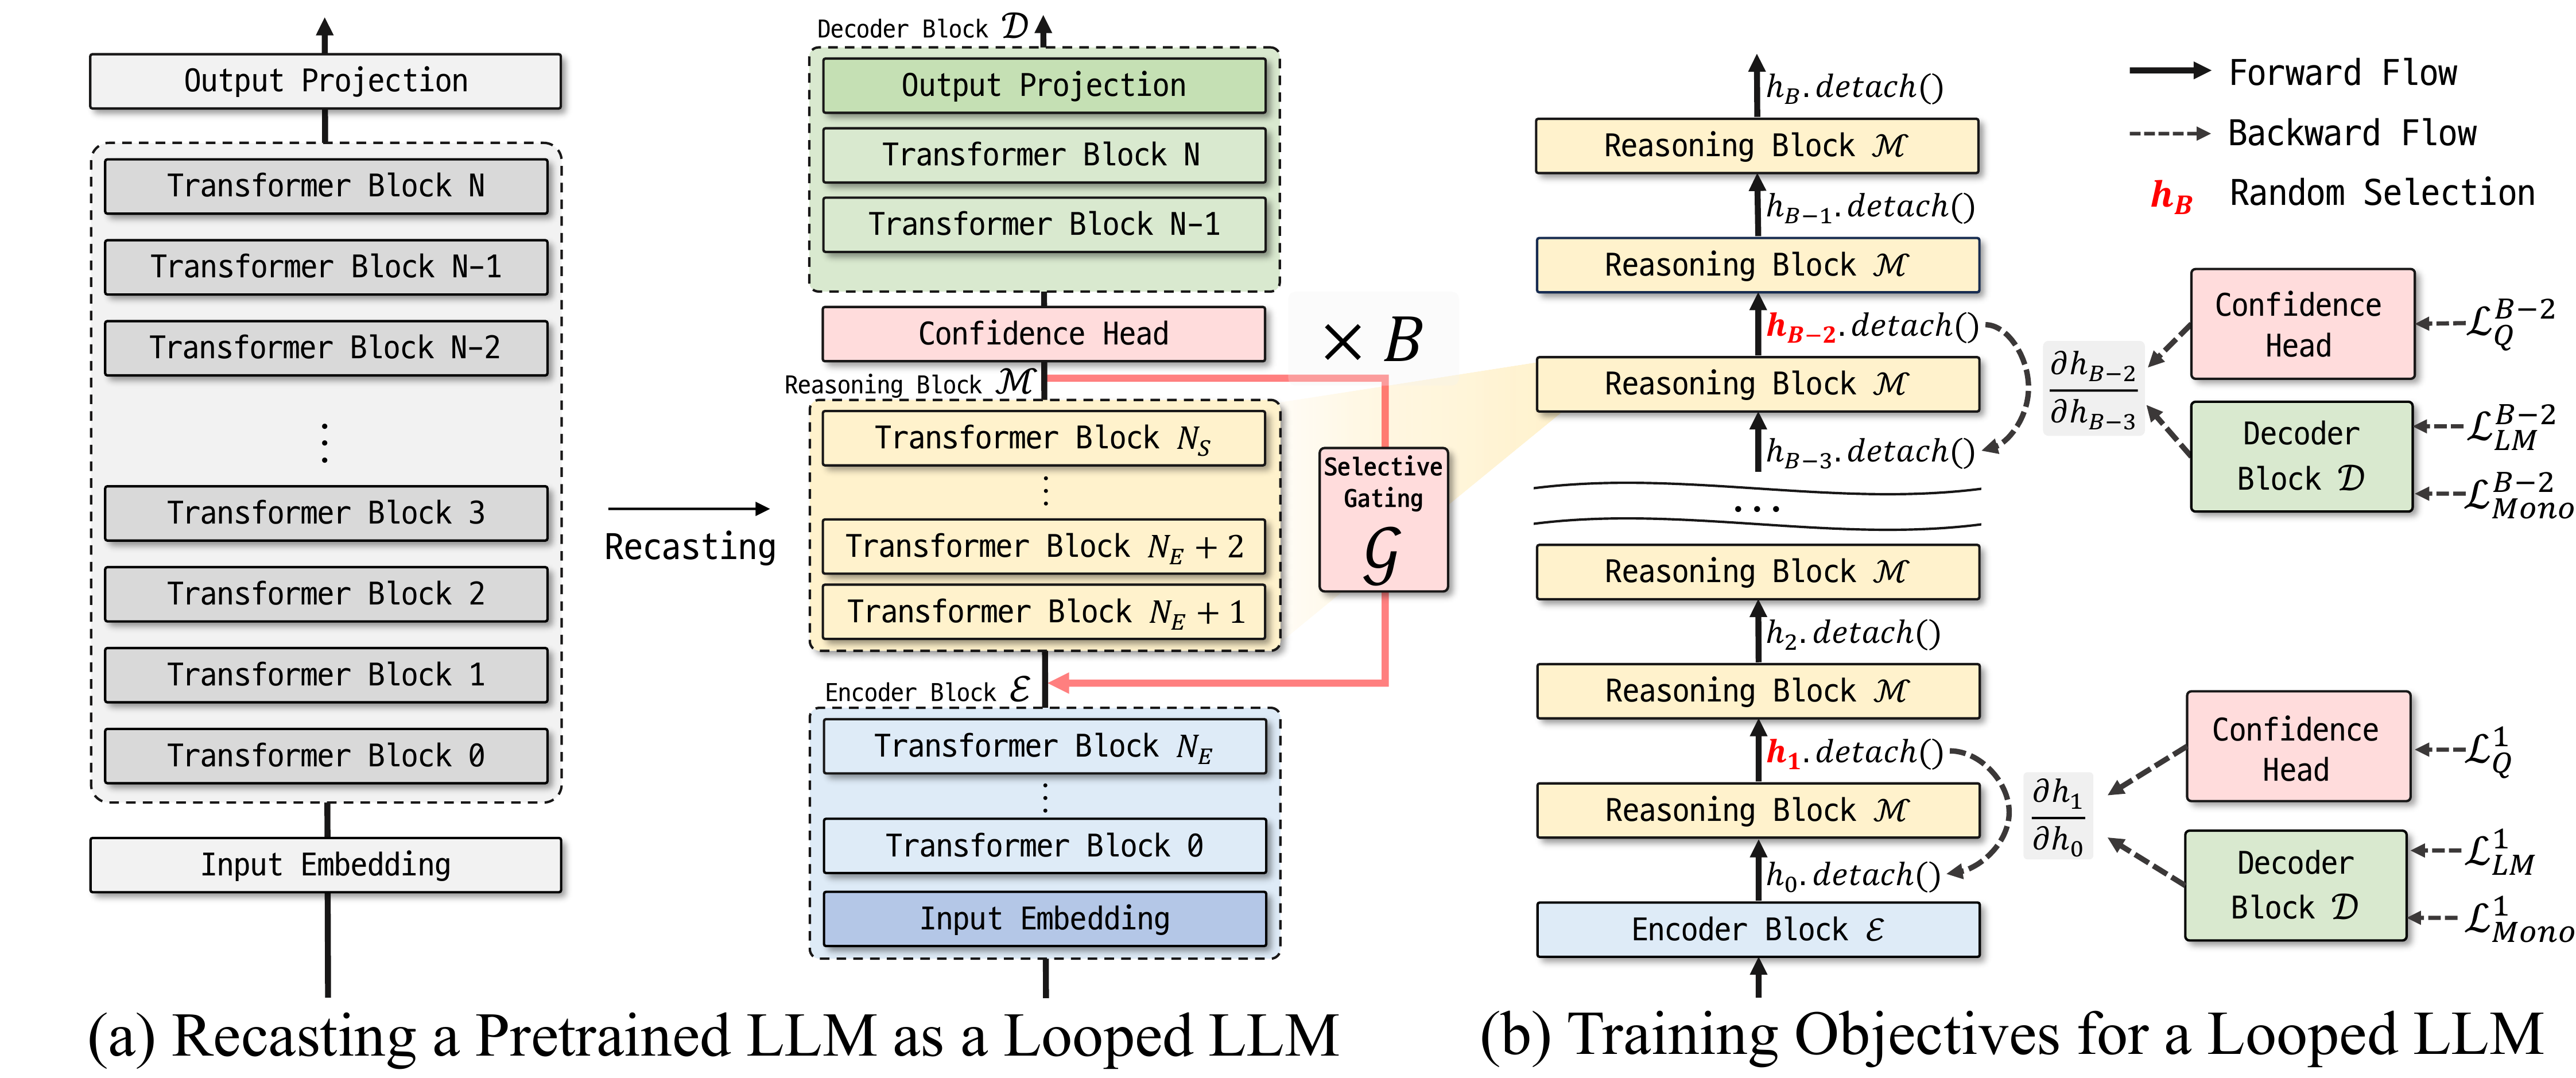
If you find LoopUS useful in your research, please cite the following paper:
@misc{park2026loopus,
      title={LoopUS: Recasting Pretrained LLMs into Looped Latent Refinement Models},
      author={Taekhyun Park and Yongjae Lee and Dohee Kim and Hyerim Bae},
      year={2026},
      eprint={2605.11011},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2605.11011},
}
Base model
Qwen/Qwen3-1.7B-Base