

Medical Text Encoder - 2048-D
Madrimed 1.2 Vision Embed
Model Overview
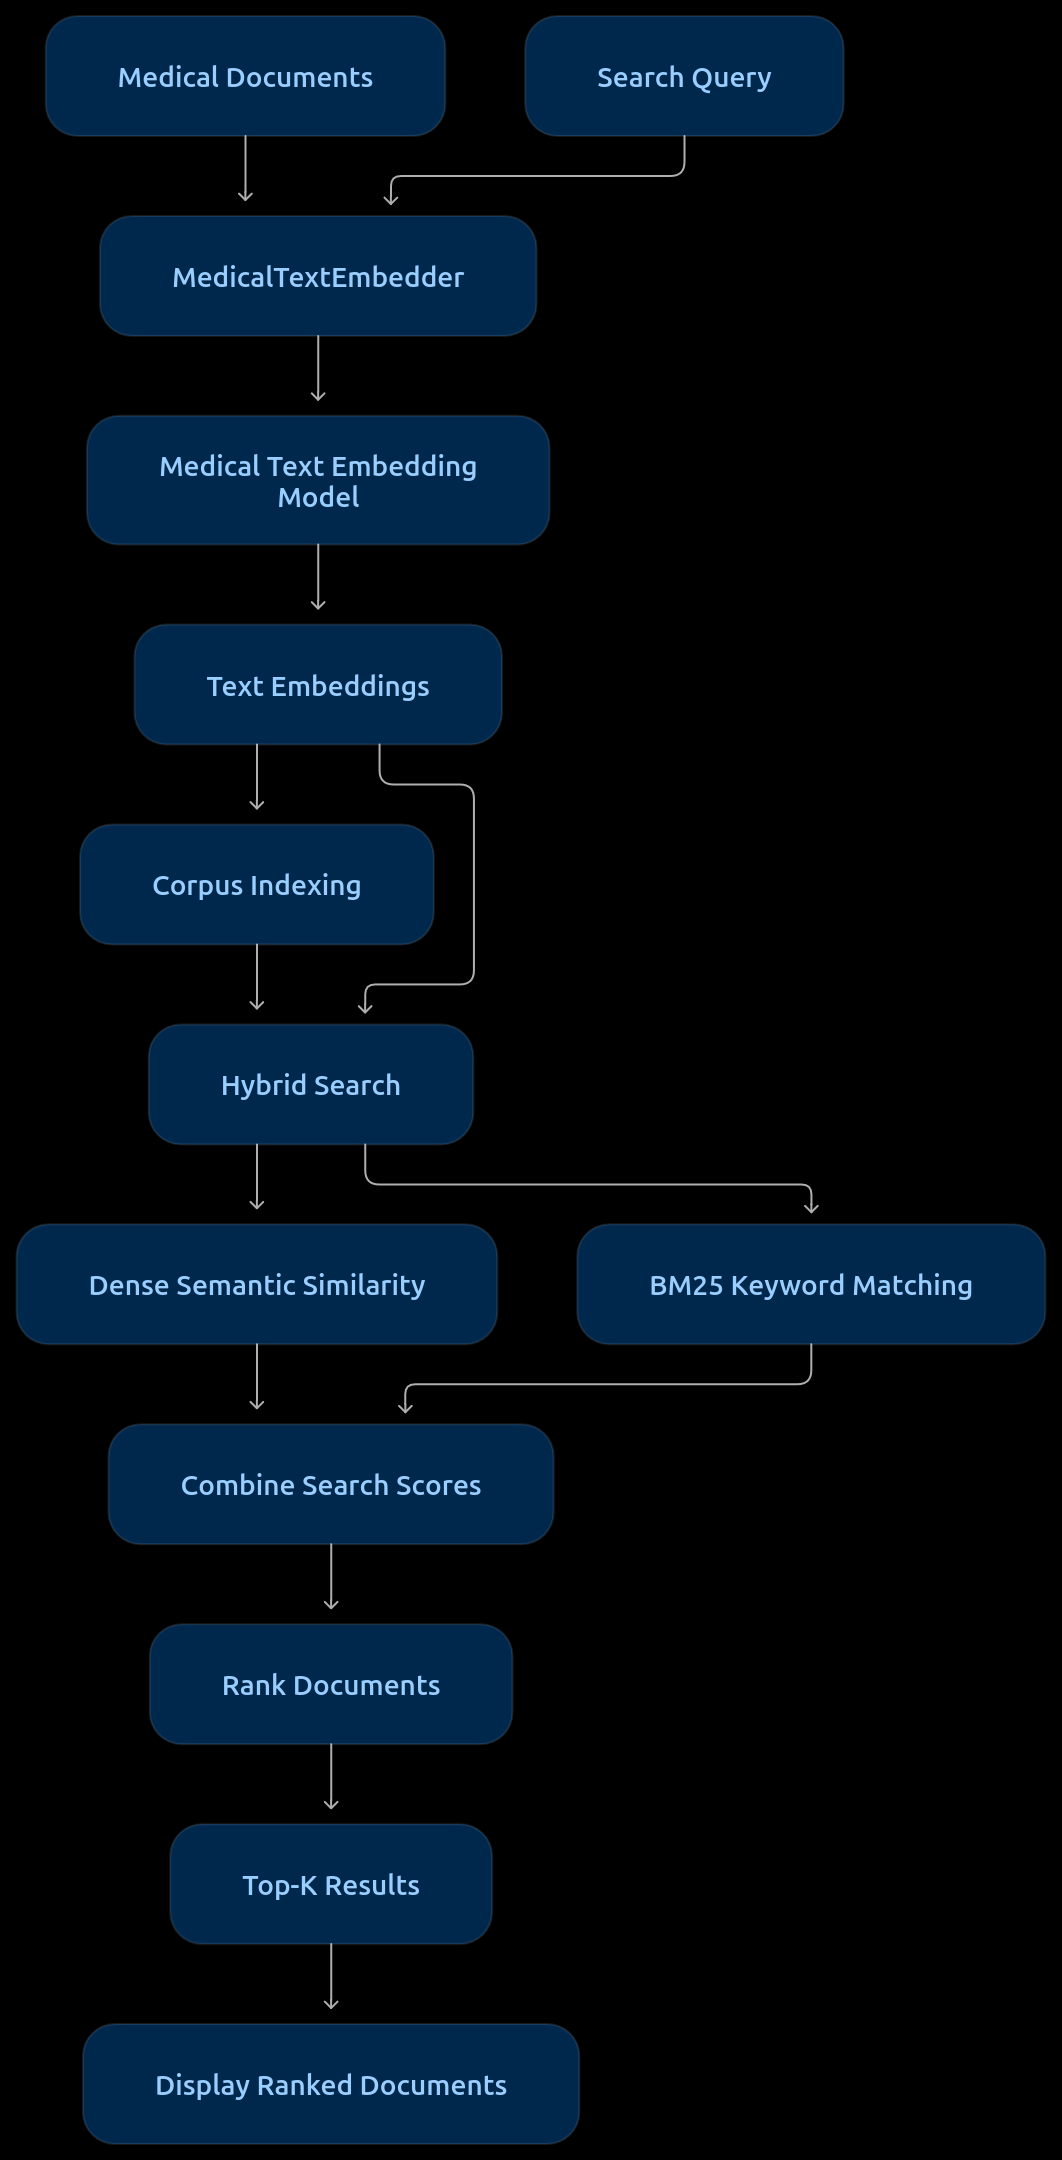
MadriMed-Text-Embed is a clinical text embedding model extracted and conditioned from the madrimed1.2 decoder backbone.
It is architected to serve two primary roles:
- Multimodal Clinical Retrieval (Paired Engine): Designed as the native text-side counterpart to
madrisight/madrimed1.2-vision-embedfor unified cross-modal medical GraphRAG (linking clinical notes, pathology reports, and queries with medical imaging). - Standalone Dense/Hybrid Text Embedder: Operates independently as a high-performance, long-context ($8192$ tokens) biomedical text retriever for EHR search, clinical question answering, and scientific literature retrieval.
Key Architectural Highlights Standalone Text Embedder:
Installation
pip install git+https://github.com/krrish-v/metalliger.git
Example Usage
import torch
from metalliger.utils.text import EmbedderConfig, TextEmbedder

# 1. Your medical documents
documents = [
    "Acute coronary syndrome presents with substernal chest pain radiating to the left arm and jaw, diaphoresis, and ST-segment elevation.",
    "Metformin hydrochloride is the first-line oral biguanide therapy for type 2 diabetes mellitus, contraindicated in severe renal impairment (eGFR < 30).",
    "Marburg hemorrhagic fever requires supportive hospital therapy including fluid balance, electrolyte maintenance, and coagulation factor replacement.",
]

queries = [
    "What is the first-line medication for type 2 diabetes and when is it contraindicated?",
    "Classic presentation and ECG findings of myocardial infarction",
]

config = EmbedderConfig(
    model_dir="madrisight/madrimed1.2-text-embed",
    # 1. Context & architecture
    echo=False,                     # feed the text once (True would feed it twice and pool the 2nd copy, doubling length)
    layers=(8, 18, 8),              # hidden-state layers to pool; layer 8 is listed twice, so it gets double weight in the average
    max_text_tokens=8192,           # longest text (in tokens) kept; anything longer is cut off
    max_batch_tokens=1638400,       # cap on batch_size x padded length per batch (effectively no cap at this value)

    # 2. Pooling & post-processing
    mean_weight=0.5,                # weight of the mean-pooled half of the embedding
    half_weight=0.5,                # weight of the max-pooled half (equal to mean_weight, so the two halves count equally)
    remove_pcs=0,                   # number of top principal components removed ("all-but-the-top"); 0 = off
    zca_alpha=0.0,                  # soft-whitening strength; 0 = off
    standardize=True,               # z-score each embedding dimension using corpus statistics
    separate_query_std=True,        # scale queries by their own std, since queries are short and documents long

    # 3. Lexical & fusion
    hybrid_weight=0.1,              # share of BM25 in the final score (0 = dense only, 0.1 = 10% BM25)
    bm25_k1=1.5,                    # BM25 term-frequency saturation; higher lets repeated terms count for more
    bm25_b=0.6,                     # BM25 length normalisation; 0 = none, 1 = full
    lex_bigrams=True,               # also index adjacent word pairs (e.g. "blood_pressure") for BM25

    # 4. Refinements (all off)
    prf_k=0,                        # Rocchio pseudo-relevance feedback: number of top docs used; 0 = off
    hub_gamma=0.0,                  # hubness (CSLS) penalty strength; 0 = off
    norm_tau=0.0,                   # Sinkhorn temperature over the query batch; 0 = off

    # 5. Token conditioning
    token_zscore=False,             # per-dimension z-score of token states before pooling; off
    mask_outlier_tokens=False,      # drop tokens with abnormally large norms; off
    token_norm=True,                # L2-normalise each token before pooling
)

embedder = TextEmbedder(config)

doc_embeddings = embedder.index_corpus(documents, fit_queries=queries)

# For a seperate Query
#embedder.index_corpus(documents)
#results = embedder.search(query, top_k=2)


# Search top-k clinical passages
for q in queries:
    hits = embedder.search(q, top_k=1)
    print(f"\nQuery: {q}")
    for score, passage in hits:
        print(f" Score: [{score:.4f}], Document: {passage}")
Query: What is the first-line medication for type 2 diabetes and when is it contraindicated?
 Score: [1.0606], Document: Metformin hydrochloride is the first-line oral biguanide therapy for type 2 diabetes mellitus, contraindicated in severe renal impairment (eGFR < 30).

Query: Classic presentation and ECG findings of myocardial infarction
 Score: [0.8468], Document: Acute coronary syndrome presents with substernal chest pain radiating to the left arm and jaw, diaphoresis, and ST-segment elevation.
Benchmark Performance as Standalone embedder
Evaluated across standard MTEB biomedical and clinical retrieval benchmarks:
| Benchmark | Domain | nDCG@10 (%) | MRR@5 (%) |
|---|---|---|---|
| PublicHealthQA | Public Health & Clinical QA | 77.51 | 71.04 |
| TREC-COVID | Biomedical Literature / COVID-19 | 52.28 | 79.90 |
| MedicalQARetrieval | Patient-Doctor Clinical QA | 49.66 | 40.75 |
| ArguAna | Biomedical Counter-Argument Retrieval | 44.42 | 33.57 |
| NFCorpus | Nutrition & Medical Information Retrieval | 31.79 | 49.91 |
Citation
@software{madrimed1.2-text-embed,
  title = {Madrimed 1.2 Text Encoder},
  author = {Madrisight},
  year = {2026},
  url = {https://huggingface.co/madrisight/madrimed1.2-text-embed}
}
- Downloads last month
- 146