new

Get trending papers in your email inbox!

Subscribe

Daily Papers

byAK and the research community

Sep 15

Advanced Pixel Diffusion Model with Guided Sparse Global Refinement

Pixel-space diffusion has recently emerged as a promising direction for high-fidelity image generation by modeling images directly in the original pixel domain. However, pixel-space diffusion is computationally demanding due to the extremely high dimensionality of natural images. For efficiency, existing pixel diffusion models either compromise fine details with large-patch tokenization or confine subsequent refinement within individual patches. Such intra-patch refinement inevitably restricts structural continuity across patch boundaries and long-range token interactions, limiting refinement quality. To address these issues, we propose PixSGR, a novel Pixel diffusion framework with Sparse Global Refinement tailored for modeling the distribution of natural images directly in pixel space. PixSGR starts from a supervised low-channel bottleneck to efficiently capture the low-dimensional manifold of natural images. It then progressively expands the channel dimensionality and spatial resolution to recover increasingly fine-grained structures. At the spatial refinement stage, coarse-scale attention maps preselect globally relevant interactions to pre-sparsify fine-scale attention, enabling non-local refinement beyond isolated patches without the quadratic cost of dense attention. Extensive experiments on ImageNet validate the effectiveness of PixSGR. It achieves an FID of 1.51 at 256times256 and maintains performance when scaled to 512times512, attaining an FID of 1.60.

  • 6 authors
·
Aug 31

GLENS: Global Search via Learning from Solver Iterates with Diffusion Models

We consider the problem of generating a large collection of initial guesses for local minima of multimodal non-convex continuous optimization problems. The goal is for these initial guesses to be high-quality (i.e., a numerical solver converges quickly) and diverse (i.e., represent many different local minima). Identifying multiple locally optimal solutions enables flexible downstream decision-making, but typically requires expensive global search. Existing data-driven methods predict initial guesses using only the final converged optima from offline solver runs, which discards information about the local neighborhoods of solutions and limits the available training data. We propose GLENS (Global Search via Learning from Solver Iterates), a data-efficient global search method that leverages intermediate solver iterates as free data augmentation. GLENS consists of two components: a neighborhood structure model that uses diffusion models to learn the local geometry around optima conditioned on problem parameters, and a solver behavior model that learns refinement directions to further guide samples towards nearby optima during diffusion sampling. Experiments on modified non-convex benchmark problems and a two-robot obstacle-avoidance navigation problem show that GLENS generates high-quality initial guesses while preserving the multimodal distribution of diverse local optima. The resulting initial guesses lead to faster solver convergence across different problem settings and solvers. We also analyze how key hyperparameter choices affect the performance.

  • 3 authors
·
May 28

RefineAnything: Multimodal Region-Specific Refinement for Perfect Local Details

We introduce region-specific image refinement as a dedicated problem setting: given an input image and a user-specified region (e.g., a scribble mask or a bounding box), the goal is to restore fine-grained details while keeping all non-edited pixels strictly unchanged. Despite rapid progress in image generation, modern models still frequently suffer from local detail collapse (e.g., distorted text, logos, and thin structures). Existing instruction-driven editing models emphasize coarse-grained semantic edits and often either overlook subtle local defects or inadvertently change the background, especially when the region of interest occupies only a small portion of a fixed-resolution input. We present RefineAnything, a multimodal diffusion-based refinement model that supports both reference-based and reference-free refinement. Building on a counter-intuitive observation that crop-and-resize can substantially improve local reconstruction under a fixed VAE input resolution, we propose Focus-and-Refine, a region-focused refinement-and-paste-back strategy that improves refinement effectiveness and efficiency by reallocating the resolution budget to the target region, while a blended-mask paste-back guarantees strict background preservation. We further introduce a boundary-aware Boundary Consistency Loss to reduce seam artifacts and improve paste-back naturalness. To support this new setting, we construct Refine-30K (20K reference-based and 10K reference-free samples) and introduce RefineEval, a benchmark that evaluates both edited-region fidelity and background consistency. On RefineEval, RefineAnything achieves strong improvements over competitive baselines and near-perfect background preservation, establishing a practical solution for high-precision local refinement. Project Page: https://limuloo.github.io/RefineAnything/.

MAgICoRe: Multi-Agent, Iterative, Coarse-to-Fine Refinement for Reasoning

Large Language Models' (LLM) reasoning can be improved using test-time aggregation strategies, i.e., generating multiple samples and voting among generated samples. While these improve performance, they often reach a saturation point. Refinement offers an alternative by using LLM-generated feedback to improve solution quality. However, refinement introduces 3 key challenges: (1) Excessive refinement: Uniformly refining all instances can over-correct and reduce the overall performance. (2) Inability to localize and address errors: LLMs have a limited ability to self-correct and struggle to identify and correct their own mistakes. (3) Insufficient refinement: Deciding how many iterations of refinement are needed is non-trivial, and stopping too soon could leave errors unaddressed. To tackle these issues, we propose MAgICoRe, which avoids excessive refinement by categorizing problem difficulty as easy or hard, solving easy problems with coarse-grained aggregation and hard ones with fine-grained and iterative multi-agent refinement. To improve error localization, we incorporate external step-wise reward model (RM) scores. Moreover, to ensure effective refinement, we employ a multi-agent loop with three agents: Solver, Reviewer (which generates targeted feedback based on step-wise RM scores), and the Refiner (which incorporates feedback). To ensure sufficient refinement, we re-evaluate updated solutions, iteratively initiating further rounds of refinement. We evaluate MAgICoRe on Llama-3-8B and GPT-3.5 and show its effectiveness across 5 math datasets. Even one iteration of MAgICoRe beats Self-Consistency by 3.4%, Best-of-k by 3.2%, and Self-Refine by 4.0% while using less than half the samples. Unlike iterative refinement with baselines, MAgICoRe continues to improve with more iterations. Finally, our ablations highlight the importance of MAgICoRe's RMs and multi-agent communication.

  • 5 authors
·
Sep 18, 2024

CraftsMan: High-fidelity Mesh Generation with 3D Native Generation and Interactive Geometry Refiner

We present a novel generative 3D modeling system, coined CraftsMan, which can generate high-fidelity 3D geometries with highly varied shapes, regular mesh topologies, and detailed surfaces, and, notably, allows for refining the geometry in an interactive manner. Despite the significant advancements in 3D generation, existing methods still struggle with lengthy optimization processes, irregular mesh topologies, noisy surfaces, and difficulties in accommodating user edits, consequently impeding their widespread adoption and implementation in 3D modeling software. Our work is inspired by the craftsman, who usually roughs out the holistic figure of the work first and elaborates the surface details subsequently. Specifically, we employ a 3D native diffusion model, which operates on latent space learned from latent set-based 3D representations, to generate coarse geometries with regular mesh topology in seconds. In particular, this process takes as input a text prompt or a reference image and leverages a powerful multi-view (MV) diffusion model to generate multiple views of the coarse geometry, which are fed into our MV-conditioned 3D diffusion model for generating the 3D geometry, significantly improving robustness and generalizability. Following that, a normal-based geometry refiner is used to significantly enhance the surface details. This refinement can be performed automatically, or interactively with user-supplied edits. Extensive experiments demonstrate that our method achieves high efficacy in producing superior-quality 3D assets compared to existing methods. HomePage: https://craftsman3d.github.io/, Code: https://github.com/wyysf-98/CraftsMan

  • 7 authors
·
May 23, 2024 2

GLoRe: When, Where, and How to Improve LLM Reasoning via Global and Local Refinements

State-of-the-art language models can exhibit impressive reasoning refinement capabilities on math, science or coding tasks. However, recent work demonstrates that even the best models struggle to identify when and where to refine without access to external feedback. Outcome-based Reward Models (ORMs), trained to predict correctness of the final answer indicating when to refine, offer one convenient solution for deciding when to refine. Process Based Reward Models (PRMs), trained to predict correctness of intermediate steps, can then be used to indicate where to refine. But they are expensive to train, requiring extensive human annotations. In this paper, we propose Stepwise ORMs (SORMs) which are trained, only on synthetic data, to approximate the expected future reward of the optimal policy or V^{star}. More specifically, SORMs are trained to predict the correctness of the final answer when sampling the current policy many times (rather than only once as in the case of ORMs). Our experiments show that SORMs can more accurately detect incorrect reasoning steps compared to ORMs, thus improving downstream accuracy when doing refinements. We then train global refinement models, which take only the question and a draft solution as input and predict a corrected solution, and local refinement models which also take as input a critique indicating the location of the first reasoning error. We generate training data for both models synthetically by reusing data used to train the SORM. We find combining global and local refinements, using the ORM as a reranker, significantly outperforms either one individually, as well as a best of three sample baseline. With this strategy we can improve the accuracy of a LLaMA-2 13B model (already fine-tuned with RL) on GSM8K from 53\% to 65\% when greedily sampled.

  • 7 authors
·
Feb 13, 2024 1

VideoRepair: Improving Text-to-Video Generation via Misalignment Evaluation and Localized Refinement

Recent text-to-video (T2V) diffusion models have demonstrated impressive generation capabilities across various domains. However, these models often generate videos that have misalignments with text prompts, especially when the prompts describe complex scenes with multiple objects and attributes. To address this, we introduce VideoRepair, a novel model-agnostic, training-free video refinement framework that automatically identifies fine-grained text-video misalignments and generates explicit spatial and textual feedback, enabling a T2V diffusion model to perform targeted, localized refinements. VideoRepair consists of four stages: In (1) video evaluation, we detect misalignments by generating fine-grained evaluation questions and answering those questions with MLLM. In (2) refinement planning, we identify accurately generated objects and then create localized prompts to refine other areas in the video. Next, in (3) region decomposition, we segment the correctly generated area using a combined grounding module. We regenerate the video by adjusting the misaligned regions while preserving the correct regions in (4) localized refinement. On two popular video generation benchmarks (EvalCrafter and T2V-CompBench), VideoRepair substantially outperforms recent baselines across various text-video alignment metrics. We provide a comprehensive analysis of VideoRepair components and qualitative examples.

  • 4 authors
·
Nov 22, 2024 3

LookAgain: Closed-Loop GUI Grounding with Visually Grounded Reflection

Recent graphical user interface (GUI) grounders have significantly advanced single-shot accuracy on standard benchmarks, yet their performance degrades sharply on small targets, densely packed controls and out-of-distribution interfaces. We attribute this gap to a paradigmatic limitation shared by existing approaches: none of them treats a produced coordinate as a hypothesis to be reflected upon and revised under new visual evidence. This manifests as three coupled issues: 1) Lack of post-hoc reflection. The prediction is frozen at the moment of emission, leaving no internal mechanism to challenge or refine it. 2) Visual evidence decoupled from the prediction. The auxiliary visual evidence is gathered to support the upcoming coordinate rather than to scrutinise the one already committed to. 3) Refinement over views, not over predictions. The iterative zoom-in refines the inspected region instead of inheriting a previous coordinate as a spatial prior to be corrected. In this paper, we propose LookAgain, a closed-loop GUI grounder driven by post-prediction visual reflection. LookAgain reformulates grounding as a multi-turn predict-look-again-refine process with two primitives: "locate" posts a coordinate hypothesis, renders a marker on the image and appends a local patch of the predicted region. It anchors the next reasoning step to the previous prediction as a spatial prior; "confirm" accepts or reject the hypothesis and terminates the procedure. We train the LookAgain grounder with SFT on constructed reflective trajectories as a cold start, followed by GRPO with terminal grounding correctness as the sole reward. Extensive experiments show that LookAgain consistently improves performance on both refusal-aware and general GUI grounding benchmarks, achieving state-of-the-art results. Comprehensive ablations further verify the effectiveness of the proposed framework.

  • 6 authors
·
Aug 9

UltraShape 1.0: High-Fidelity 3D Shape Generation via Scalable Geometric Refinement

In this report, we introduce UltraShape 1.0, a scalable 3D diffusion framework for high-fidelity 3D geometry generation. The proposed approach adopts a two-stage generation pipeline: a coarse global structure is first synthesized and then refined to produce detailed, high-quality geometry. To support reliable 3D generation, we develop a comprehensive data processing pipeline that includes a novel watertight processing method and high-quality data filtering. This pipeline improves the geometric quality of publicly available 3D datasets by removing low-quality samples, filling holes, and thickening thin structures, while preserving fine-grained geometric details. To enable fine-grained geometry refinement, we decouple spatial localization from geometric detail synthesis in the diffusion process. We achieve this by performing voxel-based refinement at fixed spatial locations, where voxel queries derived from coarse geometry provide explicit positional anchors encoded via RoPE, allowing the diffusion model to focus on synthesizing local geometric details within a reduced, structured solution space. Our model is trained exclusively on publicly available 3D datasets, achieving strong geometric quality despite limited training resources. Extensive evaluations demonstrate that UltraShape 1.0 performs competitively with existing open-source methods in both data processing quality and geometry generation. All code and trained models will be released to support future research.

  • 13 authors
·
Dec 24, 2025 4

RefineX: Learning to Refine Pre-training Data at Scale from Expert-Guided Programs

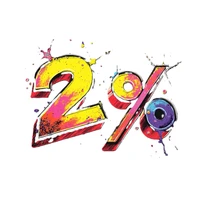
The foundational capabilities of large language models (LLMs) are deeply influenced by the quality of their pre-training corpora. However, enhancing data quality at scale remains a significant challenge, primarily due to the trade-off between refinement effectiveness and processing efficiency. While rule-based filtering remains the dominant paradigm, it typically operates at the document level and lacks the granularity needed to refine specific content within documents. Inspired by emerging work such as ProX, we propose RefineX, a novel framework for large-scale, surgical refinement of pre-training data through programmatic editing tasks. RefineX enables efficient and fine-grained data refinement while reliably preserving the diversity and naturalness of raw text. The core strength of RefineX lies in distilling high-quality, expert-guided end-to-end refinement results into minimal edit-based deletion programs. This high-precision distillation pipeline is used to train an efficient and reliable refine model that can systematically improve every instance in the corpus at scale. We evaluate RefineX across from-scratch pre-training at multiple model scales and find that it consistently outperforms models trained on raw, filtered, or alternatively refined data across diverse downstream tasks. On the 750M model, RefineX yields 2.6%-7.2% average gains on lighteval tasks, and achieves comparable performance using significantly fewer training tokens. Further analysis shows that RefineX reliably enhances text quality with both high efficiency and precision, outperforming prior approaches such as end-to-end generation and Prox-C. These results position RefineX as a scalable, effective, and reliable solution for optimizing pre-training data in modern LLM pipelines.

  • 10 authors
·
Jul 3, 2025 1

GTR: Improving Large 3D Reconstruction Models through Geometry and Texture Refinement

We propose a novel approach for 3D mesh reconstruction from multi-view images. Our method takes inspiration from large reconstruction models like LRM that use a transformer-based triplane generator and a Neural Radiance Field (NeRF) model trained on multi-view images. However, in our method, we introduce several important modifications that allow us to significantly enhance 3D reconstruction quality. First of all, we examine the original LRM architecture and find several shortcomings. Subsequently, we introduce respective modifications to the LRM architecture, which lead to improved multi-view image representation and more computationally efficient training. Second, in order to improve geometry reconstruction and enable supervision at full image resolution, we extract meshes from the NeRF field in a differentiable manner and fine-tune the NeRF model through mesh rendering. These modifications allow us to achieve state-of-the-art performance on both 2D and 3D evaluation metrics, such as a PSNR of 28.67 on Google Scanned Objects (GSO) dataset. Despite these superior results, our feed-forward model still struggles to reconstruct complex textures, such as text and portraits on assets. To address this, we introduce a lightweight per-instance texture refinement procedure. This procedure fine-tunes the triplane representation and the NeRF color estimation model on the mesh surface using the input multi-view images in just 4 seconds. This refinement improves the PSNR to 29.79 and achieves faithful reconstruction of complex textures, such as text. Additionally, our approach enables various downstream applications, including text- or image-to-3D generation.

  • 10 authors
·
Jun 9, 2024

The Beauty of Anisotropic Mesh Refinement: Omnitrees for Efficient Dyadic Discretizations

Structured adaptive mesh refinement (AMR), commonly implemented via quadtrees and octrees, underpins a wide range of applications including databases, computer graphics, physics simulations, and machine learning. However, octrees enforce isotropic refinement in regions of interest, which can be especially inefficient for problems that are intrinsically anisotropic--much resolution is spent where little information is gained. This paper presents omnitrees as an anisotropic generalization of octrees and related data structures. Omnitrees allow to refine only the locally most important dimensions, providing tree structures that are less deep than bintrees and less wide than octrees. As a result, the convergence of the AMR schemes can be increased by up to a factor of the dimensionality d for very anisotropic problems, quickly offsetting their modest increase in storage overhead. We validate this finding on the problem of binary shape representation across 4,166 three-dimensional objects: Omnitrees increase the mean convergence rate by 1.5x, require less storage to achieve equivalent error bounds, and maximize the information density of the stored function faster than octrees. These advantages are projected to be even stronger for higher-dimensional problems. We provide a first validation by introducing a time-dependent rotation to create four-dimensional representations, and discuss the properties of their 4-d octree and omnitree approximations. Overall, omnitree discretizations can make existing AMR approaches more efficient, and open up new possibilities for high-dimensional applications.

  • 3 authors
·
Aug 8, 2025

RefGC-SR^2: Reference-guided Generated Content Super-Resolution and Refinement

Reference-guided generation (e.g., object compositing, customization) has progressed rapidly, yet current pipelines share a fundamental limitation: the object-centric high-resolution reference image (HRRI) provided by users is downsampled to a fixed low-resolution (LR) before being fed into the model, so the fine-grained details are discarded before the output is even produced. In addition, the generation step then introduces its own artifacts (e.g., identity distortion) on top of this loss. Existing reference-guided generated content refinement (RefGCR) methods can correct some of these artifacts but still operate in the LR domain; reference-guided super-resolution (RefSR) methods recover resolution but assume natural-image degradations and ignore the artifact distribution of generative pipelines. To address both gaps in a single formulation, we introduce a new task: reference-guided generated content super-resolution-refinement (RefGC-SR^2), where the original HRRI is reused at the post-processing stage to recover lost details, refine generative artifacts, and upscale the output simultaneously. We construct the first real-world triplet data generation pipeline for this RefGC-SR^2 task, training a diptych-conditioned generator to synthesize paired low-quality anchors that public pretrained models cannot provide. We further present a frequency-aware diffusion transformer model for RefGC-SR^2 that selectively injects fine details from the HRRI while removing generative artifacts. Extensive experiments demonstrate that our RefGC-SR^2 model successfully (i) refines the object identity faithfully with respect to the reference, and (ii) recovers high-resolution details, so that the final result is significantly higher quality and practically more usable compared to existing RefGCR and RefSR baselines.

  • 4 authors
·
Jun 12 2

RefDecoder: Enhancing Visual Generation with Conditional Video Decoding

Video generation powers a vast array of downstream applications. However, while the de facto standard, i.e., latent diffusion models, typically employ heavily conditioned denoising networks, their decoders often remain unconditional. We observe that this architectural asymmetry leads to significant loss of detail and inconsistency relative to the input image. To address this, we argue that the decoder requires equal conditioning to preserve structural integrity. We introduce RefDecoder, a reference-conditioned video VAE decoder by injecting high-fidelity reference image signal directly into the decoding process via reference attention. Specifically, a lightweight image encoder maps the reference frame into the detail-rich high-dimensional tokens, which are co-processed with the denoised video latent tokens at each decoder up-sampling stage. We demonstrate consistent improvements across several distinct decoder backbones (e.g., Wan 2.1 and VideoVAE+), achieving up to +2.1dB PSNR over the unconditional baselines on the Inter4K, WebVid, and Large Motion reconstruction benchmarks. Notably, RefDecoder can be directly swapped into existing video generation systems without additional fine-tuning, and we report across-the-board improvements in subject consistency, background consistency, and overall quality scores on the VBench I2V benchmark. Beyond I2V, RefDecoder generalizes well to a wide range of visual generation tasks such as style transfer and video editing refinement.

  • 5 authors
·
May 13

FixAnything: 3D-Consistent Rendering Refinement via Video Generative Priors

Rendering views using 3D scene representations such as Gaussian Splatting (3DGS), Neural Radiance Fields (NeRF), meshes, or even point clouds produces artifacts when input views are sparse or target views lie far from the input. Recent work mitigates these artifacts using diffusion-based generative priors, but is specialized to individual representations and require custom architectures or extensive retraining. We present FixAnything, a single model for fixing a wide range of rendering artifacts. It does so by repurposing a pretrained video generative model, leveraging its implicit multi-view priors with only minimal modification and lightweight finetuning. Our key insight is that even noisily-rendered sequences preserve camera motion and coarse scene structure, allowing cleanup to be formulated as video-to-video translation. To control what scene structure should be preserved, we introduce a binary mask denoting the clean pixels, enabling the model to anchor its output to high-quality inputs (e.g. training views) while refining the rest. To encourage FixAnything to produce 3D-consistent renderings that support downstream reconstruction, we use camera pose accuracy (recovered via structure-from-motion) as a reward signal for direct preference optimization (DPO). Across four distinct 3D representations, FixAnything consistently improves rendering quality with lightweight finetuning, demonstrating that a single generalist video prior can replace multiple specialist refinement pipelines. The simplicity of the framework enables immediate adoption of stronger future video models without architectural redesign.

  • 3 authors
·
Aug 23

Think Thrice Before You Act: Progressive Thought Refinement in Large Language Models

Recent advancements in large language models (LLMs) have demonstrated that progressive refinement, rather than providing a single answer, results in more accurate and thoughtful outputs. However, existing methods often rely heavily on supervision signals to evaluate previous responses, making it difficult to assess output quality in more open-ended scenarios effectively. Additionally, these methods are typically designed for specific tasks, which limits their generalization to new domains. To address these limitations, we propose Progressive Thought Refinement (PTR), a framework that enables LLMs to refine their responses progressively. PTR operates in two phases: (1) Thought data construction stage: We propose a weak and strong model collaborative selection strategy to build a high-quality progressive refinement dataset to ensure logical consistency from thought to answers, and the answers are gradually refined in each round. (2) Thought-Mask Fine-Tuning Phase: We design a training structure to mask the "thought" and adjust loss weights to encourage LLMs to refine prior thought, teaching them to implicitly understand "how to improve" rather than "what is correct." Experimental results show that PTR significantly enhances LLM performance across ten diverse tasks (avg. from 49.6% to 53.5%) without task-specific fine-tuning. Notably, in more open-ended tasks, LLMs also demonstrate substantial improvements in the quality of responses beyond mere accuracy, suggesting that PTR truly teaches LLMs to self-improve over time.

  • 12 authors
·
Oct 17, 2024

Ortho2CAD: 3D CAD generation from orthographic drawings using vision language models

Engineering design intent is often communicated through rasterized orthographic drawings. However, downstream workflows require editable and parametrically defined 3D computer-aided design (CAD) models. To bridge this gap, we introduce vision language model (VLM) frameworks specifically designed to translate rasterized orthographic drawings into editable CadQuery code, which can then be converted into 3D CAD models. Firstly, due to unavailability of large scale orthographic drawing datasets, we create a pythonOCC-based drawing generator that renders first-angle orthographic projections from STEP models, with dashed hidden lines and bounding box dimensions, and generate over 1 million drawings from existing 3D CAD model datasets. We also create a dataset of 100 drawings with manually dimensioned features. We show that supervised fine-tuning applied on small open-source VLMs when paired CadQuery code is available improves reconstruction accuracy on corresponding test sets. For datasets without code labels, geometry-grounded reinforcement learning is performed which uses generated-solid intersection-over-union (IoU) with ground truth solid as the reward, improving code validity and cross-dataset generalization. Then, an inference time self-refinement framework for frontier VLMs is introduced which repeatedly repairs invalid codes and compares orthographic projections of generated 3D models with the input drawing to revise the CadQuery code. Our self-refinement framework with GPT 5.5 achieves 100% valid code generation and the highest mean IoU across all test sets, with an average relative improvement of more than 11% over the next-best method. We show that leveraging VLMs can effectively pave the way forward for orthographic drawing to 3D CAD reconstruction. Our implementation is available at https://github.com/AdityaJoglekar/Ortho2CAD.

  • 4 authors
·
Aug 10

UniSDF: Unifying Neural Representations for High-Fidelity 3D Reconstruction of Complex Scenes with Reflections

Neural 3D scene representations have shown great potential for 3D reconstruction from 2D images. However, reconstructing real-world captures of complex scenes still remains a challenge. Existing generic 3D reconstruction methods often struggle to represent fine geometric details and do not adequately model reflective surfaces of large-scale scenes. Techniques that explicitly focus on reflective surfaces can model complex and detailed reflections by exploiting better reflection parameterizations. However, we observe that these methods are often not robust in real unbounded scenarios where non-reflective as well as reflective components are present. In this work, we propose UniSDF, a general purpose 3D reconstruction method that can reconstruct large complex scenes with reflections. We investigate both view-based as well as reflection-based color prediction parameterization techniques and find that explicitly blending these representations in 3D space enables reconstruction of surfaces that are more geometrically accurate, especially for reflective surfaces. We further combine this representation with a multi-resolution grid backbone that is trained in a coarse-to-fine manner, enabling faster reconstructions than prior methods. Extensive experiments on object-level datasets DTU, Shiny Blender as well as unbounded datasets Mip-NeRF 360 and Ref-NeRF real demonstrate that our method is able to robustly reconstruct complex large-scale scenes with fine details and reflective surfaces. Please see our project page at https://fangjinhuawang.github.io/UniSDF.

  • 6 authors
·
Dec 20, 2023

LLM Blueprint: Enabling Text-to-Image Generation with Complex and Detailed Prompts

Diffusion-based generative models have significantly advanced text-to-image generation but encounter challenges when processing lengthy and intricate text prompts describing complex scenes with multiple objects. While excelling in generating images from short, single-object descriptions, these models often struggle to faithfully capture all the nuanced details within longer and more elaborate textual inputs. In response, we present a novel approach leveraging Large Language Models (LLMs) to extract critical components from text prompts, including bounding box coordinates for foreground objects, detailed textual descriptions for individual objects, and a succinct background context. These components form the foundation of our layout-to-image generation model, which operates in two phases. The initial Global Scene Generation utilizes object layouts and background context to create an initial scene but often falls short in faithfully representing object characteristics as specified in the prompts. To address this limitation, we introduce an Iterative Refinement Scheme that iteratively evaluates and refines box-level content to align them with their textual descriptions, recomposing objects as needed to ensure consistency. Our evaluation on complex prompts featuring multiple objects demonstrates a substantial improvement in recall compared to baseline diffusion models. This is further validated by a user study, underscoring the efficacy of our approach in generating coherent and detailed scenes from intricate textual inputs.

  • 5 authors
·
Oct 16, 2023 1

RefineBench: Evaluating Refinement Capability of Language Models via Checklists

Can language models (LMs) self-refine their own responses? This question is increasingly relevant as a wide range of real-world user interactions involve refinement requests. However, prior studies have largely tested LMs' refinement abilities on verifiable tasks such as competition math or symbolic reasoning with simplified scaffolds, whereas users often pose open-ended queries and provide varying degrees of feedback on what they desire. The recent advent of reasoning models that exhibit self-reflection patterns in their chains-of-thought further motivates this question. To analyze this, we introduce RefineBench, a benchmark of 1,000 challenging problems across 11 domains paired with a checklist-based evaluation framework. We evaluate two refinement modes: (1) guided refinement, where an LM is provided natural language feedback, and (2) self-refinement, where LMs attempt to improve without guidance. In the self-refinement setting, even frontier LMs such as Gemini 2.5 Pro and GPT-5 achieve modest baseline scores of 31.3% and 29.1%, respectively, and most models fail to consistently improve across iterations (e.g., Gemini-2.5-Pro gains only +1.8%, while DeepSeek-R1 declines by -0.1%). By contrast, in guided refinement, both proprietary LMs and large open-weight LMs (>70B) can leverage targeted feedback to refine responses to near-perfect levels within five turns. These findings suggest that frontier LMs require breakthroughs to self-refine their incorrect responses, and that RefineBench provides a valuable testbed for tracking progress.

Multi-Turn Reflective Masking Elicits Reasoning in Mask Diffusion Models

While reasoning on autoregressive (AR) models is often performed by chain-of-thought reasoning and reflection, their refinement of previous outputs still relies on fully sequential generation, even when only local edits are needed. In contrast, the masking mechanism in Mask Diffusion Models (MDMs) naturally supports explicit local edits on previous outputs, allowing selective refinement without discarding previous answers and generating another from scratch. While this property more closely aligns with how humans correct mistakes by iterative local refinement, existing MDMs do not support multi-turn masking and denoising. We propose Reflective Masking (RM), which elicits such an intrinsic reasoning capability in MDMs via lightweight post-training. RM provides a native test-time scaling, where an MDM iteratively revisits and revises its prior outputs based on evolving context. To exploit insights from previous turns like AR reasoning, we further introduce History Reference, a parameter-free mechanism that leverages intermediate denoising states during revision. Our approach requires no architectural changes and is easily applicable to existing MDMs. Across diverse tasks and modalities, including text generation, Sudoku, and image editing, Reflective Masking consistently outperforms standard masking-based baselines and demonstrates strong generality, positioning RM as a fundamental primitive for reasoning on MDMs.

umd-zhou-lab Tianyi Lab
·
Jun 14 4

Old Photo Restoration via Deep Latent Space Translation

We propose to restore old photos that suffer from severe degradation through a deep learning approach. Unlike conventional restoration tasks that can be solved through supervised learning, the degradation in real photos is complex and the domain gap between synthetic images and real old photos makes the network fail to generalize. Therefore, we propose a novel triplet domain translation network by leveraging real photos along with massive synthetic image pairs. Specifically, we train two variational autoencoders (VAEs) to respectively transform old photos and clean photos into two latent spaces. And the translation between these two latent spaces is learned with synthetic paired data. This translation generalizes well to real photos because the domain gap is closed in the compact latent space. Besides, to address multiple degradations mixed in one old photo, we design a global branch with apartial nonlocal block targeting to the structured defects, such as scratches and dust spots, and a local branch targeting to the unstructured defects, such as noises and blurriness. Two branches are fused in the latent space, leading to improved capability to restore old photos from multiple defects. Furthermore, we apply another face refinement network to recover fine details of faces in the old photos, thus ultimately generating photos with enhanced perceptual quality. With comprehensive experiments, the proposed pipeline demonstrates superior performance over state-of-the-art methods as well as existing commercial tools in terms of visual quality for old photos restoration.

  • 7 authors
·
Sep 14, 2020

OmniFusion: 360 Monocular Depth Estimation via Geometry-Aware Fusion

A well-known challenge in applying deep-learning methods to omnidirectional images is spherical distortion. In dense regression tasks such as depth estimation, where structural details are required, using a vanilla CNN layer on the distorted 360 image results in undesired information loss. In this paper, we propose a 360 monocular depth estimation pipeline, OmniFusion, to tackle the spherical distortion issue. Our pipeline transforms a 360 image into less-distorted perspective patches (i.e. tangent images) to obtain patch-wise predictions via CNN, and then merge the patch-wise results for final output. To handle the discrepancy between patch-wise predictions which is a major issue affecting the merging quality, we propose a new framework with the following key components. First, we propose a geometry-aware feature fusion mechanism that combines 3D geometric features with 2D image features to compensate for the patch-wise discrepancy. Second, we employ the self-attention-based transformer architecture to conduct a global aggregation of patch-wise information, which further improves the consistency. Last, we introduce an iterative depth refinement mechanism, to further refine the estimated depth based on the more accurate geometric features. Experiments show that our method greatly mitigates the distortion issue, and achieves state-of-the-art performances on several 360 monocular depth estimation benchmark datasets.

  • 6 authors
·
Mar 1, 2022

Recursive Code World Models: Building Complex Worlds through Recursive Scene Programs

Code world models represent worlds as executable programs, but this representation alone does not determine how to construct a complex world. We introduce Recursive Code World Models (RCWM), a framework for reconstructing complex 3D worlds in code from a single reference image. RCWM couples a Recursive Scene Program (RSP) representation with a construction solver that recursively calls itself. An RSP represents the executable world as compositional scene code, while each solver call follows the same complete process: establish the whole, recursively reconstruct unresolved parts, and revisit the whole to refine their composition. This global-local-global recursion gives fine-scale structures their own perception-and-editing loops while preserving scene-wide geometry and relationships. Reference-aligned views propagate a shared camera projection across levels, while parent revisitation addresses boundaries, spatial relations, and shared errors that emerge after local refinement. A vision-language coding agent directly compares reference images with scene renders to guide refinement, recursive descent, and return. Across complex scenes, RCWM outperforms prior code-based image-to-scene reconstruction methods. Ablation studies further support the benefits of recursive construction and suggest that deeper calls can improve finer-scale reconstruction. RCWM provides a recursive construction principle for building complex executable worlds from visual evidence.

  • 3 authors
·
Sep 9 1

Lyra: Orchestrating Dual Correction in Automated Theorem Proving

Large Language Models (LLMs) present an intriguing avenue for exploration in the field of formal theorem proving. Nevertheless, their full potential, particularly concerning the mitigation of hallucinations and refinement through prover error messages, remains an area that has yet to be thoroughly investigated. To enhance the effectiveness of LLMs in the field, we introduce the Lyra, a new framework that employs two distinct correction mechanisms: Tool Correction (TC) and Conjecture Correction (CC). To implement Tool Correction in the post-processing of formal proofs, we leverage prior knowledge to utilize predefined prover tools (e.g., Sledgehammer) for guiding the replacement of incorrect tools. Tool Correction significantly contributes to mitigating hallucinations, thereby improving the overall accuracy of the proof. In addition, we introduce Conjecture Correction, an error feedback mechanism designed to interact with prover to refine formal proof conjectures with prover error messages. Compared to the previous refinement framework, the proposed Conjecture Correction refines generation with instruction but does not collect paired (generation, error & refinement) prompts. Our method has achieved state-of-the-art (SOTA) performance on both miniF2F validation (48.0% -> 55.3%) and test (45.5% -> 51.2%). We also present 3 IMO problems solved by Lyra. We believe Tool Correction (post-process for hallucination mitigation) and Conjecture Correction (subgoal adjustment from interaction with environment) could provide a promising avenue for future research in this field.

  • 9 authors
·
Sep 27, 2023

From Denoising to Refining: A Corrective Framework for Vision-Language Diffusion Model

Discrete diffusion models have emerged as a promising direction for vision-language tasks, offering bidirectional context modeling and theoretical parallelization. However, their practical application is severely hindered by a train-inference discrepancy, which leads to catastrophic error cascades: initial token errors during parallel decoding pollute the generation context, triggering a chain reaction of compounding errors and leading to syntactic errors and semantic hallucinations. To address this fundamental challenge, we reframe the generation process from passive denoising to active refining. We introduce ReDiff, a refining-enhanced diffusion framework that teaches the model to identify and correct its own errors. Our approach features a two-stage training process: first, we instill a foundational revision capability by training the model to revise synthetic errors; second, we implement a novel online self-correction loop where the model is explicitly trained to revise its own flawed drafts by learning from an expert's corrections. This mistake-driven learning endows the model with the crucial ability to revisit and refine its already generated output, effectively breaking the error cascade. Extensive experiments demonstrate that ReDiff significantly improves the coherence and factual accuracy of generated content, enabling stable and efficient parallel generation far superior to traditional denoising methods. Our codes and models are available at https://rediff-hku.github.io/.

TheHKU Hong Kong University
·
Oct 22, 2025 2

SpatialCrafter: Single Image World Modeling with Generative 3D Proxies

Explorable image-to-scene generation is essential for applications in gaming, robotics, and virtual reality. Existing methods based on video diffusion model (VDM) commonly rely on incomplete conditioning signals such as sparse point clouds or 2D panoramas, leading to stochastic hallucinations, long-term drifts and suboptimal 3D consistency. We present SpatialCrafter, a novel two-stage framework that addresses these issues by introducing a global 3D proxy for high-fidelity image-to-scene generation. Specifically, we decompose the generation process into global proxy generation and appearance refinement. For proxy generation, we propose a Point-anchored Sparse Structure~(PaSS) Flow module that predicts a spatially aligned and geometrically consistent 3D proxy. For appearance refinement, we re-frame the VDM as a Generative Deferred Refiner which synthesizes high-frequency photorealistic details upon proxy-defined scene geometry. To better integrate the proxy with the pre-trained VDM, we introduce Parallel Geometry Injection and Proxy-Aware Corruption training strategies, which improve robustness to proxy artifacts without disrupting the pretrained generative manifold. Furthermore, as no suitable dataset exists for this explorable scene generation task, we construct a new large-scale dataset of 115K scenes. To the best of our knowledge, it is the first hybrid dataset for image-to-scene generation. Extensive experiments on both synthetic and real-world datasets show that SpatialCrafter outperforms state-of-the-art methods, mitigates long-term drift, and remains robust and consistent under rapid camera motion and extreme viewpoint changes. Our project page: https://fangchuan.github.io/SpatialCrafter/{fangchuan.github.io/SpatialCrafter/}

Relightable Full-Body Gaussian Codec Avatars

We propose Relightable Full-Body Gaussian Codec Avatars, a new approach for modeling relightable full-body avatars with fine-grained details including face and hands. The unique challenge for relighting full-body avatars lies in the large deformations caused by body articulation and the resulting impact on appearance caused by light transport. Changes in body pose can dramatically change the orientation of body surfaces with respect to lights, resulting in both local appearance changes due to changes in local light transport functions, as well as non-local changes due to occlusion between body parts. To address this, we decompose the light transport into local and non-local effects. Local appearance changes are modeled using learnable zonal harmonics for diffuse radiance transfer. Unlike spherical harmonics, zonal harmonics are highly efficient to rotate under articulation. This allows us to learn diffuse radiance transfer in a local coordinate frame, which disentangles the local radiance transfer from the articulation of the body. To account for non-local appearance changes, we introduce a shadow network that predicts shadows given precomputed incoming irradiance on a base mesh. This facilitates the learning of non-local shadowing between the body parts. Finally, we use a deferred shading approach to model specular radiance transfer and better capture reflections and highlights such as eye glints. We demonstrate that our approach successfully models both the local and non-local light transport required for relightable full-body avatars, with a superior generalization ability under novel illumination conditions and unseen poses.

  • 18 authors
·
Jan 24, 2025 2

RefracGS: Novel View Synthesis Through Refractive Water Surfaces with 3D Gaussian Ray Tracing

Novel view synthesis (NVS) through non-planar refractive surfaces presents fundamental challenges due to severe, spatially varying optical distortions. While recent representations like NeRF and 3D Gaussian Splatting (3DGS) excel at NVS, their assumption of straight-line ray propagation fails under these conditions, leading to significant artifacts. To overcome this limitation, we introduce RefracGS, a framework that jointly reconstructs the refractive water surface and the scene beneath the interface. Our key insight is to explicitly decouple the refractive boundary from the target objects: the refractive surface is modeled via a neural height field, capturing wave geometry, while the underlying scene is represented as a 3D Gaussian field. We formulate a refraction-aware Gaussian ray tracing approach that accurately computes non-linear ray trajectories using Snell's law and efficiently renders the underlying Gaussian field while backpropagating the loss gradients to the parameterized refractive surface. Through end-to-end joint optimization of both representations, our method ensures high-fidelity NVS and view-consistent surface recovery. Experiments on both synthetic and real-world scenes with complex waves demonstrate that RefracGS outperforms prior refractive methods in visual quality, while achieving 15x faster training and real-time rendering at 200 FPS. The project page for RefracGS is available at https://yimgshao.github.io/refracgs/.

  • 9 authors
·
Mar 22

Beyond Voxel 3D Editing: Learning from 3D Masks and Self-Constructed Data

3D editing refers to the ability to apply local or global modifications to 3D assets. Effective 3D editing requires maintaining semantic consistency by performing localized changes according to prompts, while also preserving local invariance so that unchanged regions remain consistent with the original. However, existing approaches have significant limitations: multi-view editing methods incur losses when projecting back to 3D, while voxel-based editing is constrained in both the regions that can be modified and the scale of modifications. Moreover, the lack of sufficiently large editing datasets for training and evaluation remains a challenge. To address these challenges, we propose a Beyond Voxel 3D Editing (BVE) framework with a self-constructed large-scale dataset specifically tailored for 3D editing. Building upon this dataset, our model enhances a foundational image-to-3D generative architecture with lightweight, trainable modules, enabling efficient injection of textual semantics without the need for expensive full-model retraining. Furthermore, we introduce an annotation-free 3D masking strategy to preserve local invariance, maintaining the integrity of unchanged regions during editing. Extensive experiments demonstrate that BVE achieves superior performance in generating high-quality, text-aligned 3D assets, while faithfully retaining the visual characteristics of the original input.

  • 9 authors
·
Apr 14

RefineSVG: Visual Feedback-Driven Reinforcement Learning for Image-to-SVG Generation

We propose RefineSVG, a single-step closed-loop visual feedback framework that enables multimodal large language models (MLLMs) to perform high-fidelity image-to-SVG generation through self-correction. Existing MLLM-based approaches rely on single-pass open-loop inference, where the model receives visual input only once and must generate thousands of SVG code tokens without intermediate verification. This paradigm inevitably leads to geometric drift, error accumulation, and visual hallucination on complex images. RefineSVG overcomes this limitation by invoking an external rendering engine after an initial SVG generation pass to compare the rendered output against the target image. The comparison yields a multi-dimensional visual residual map (Diff-Map) that is fed back to the model as a ReAct-style correction signal, driving a targeted correction step. To support this render-observe-correct interaction, we further introduce an SVG-oriented semantic vocabulary that compresses token sequences by over 52%. A progressive training pipeline spanning supervised fine-tuning, rejection-sampling cold-start data construction, and end-to-end agentic reinforcement learning aligns the model with closed-loop visual correction. Extensive experiments show that RefineSVG consistently outperforms existing baselines in reconstruction fidelity, structural accuracy, and code efficiency.Code is available at https://github.com/liuxiaobo66/RefineSVG.

  • 7 authors
·
Jul 29

Agentic Retoucher for Text-To-Image Generation

Text-to-image (T2I) diffusion models such as SDXL and FLUX have achieved impressive photorealism, yet small-scale distortions remain pervasive in limbs, face, text and so on. Existing refinement approaches either perform costly iterative re-generation or rely on vision-language models (VLMs) with weak spatial grounding, leading to semantic drift and unreliable local edits. To close this gap, we propose Agentic Retoucher, a hierarchical decision-driven framework that reformulates post-generation correction as a human-like perception-reasoning-action loop. Specifically, we design (1) a perception agent that learns contextual saliency for fine-grained distortion localization under text-image consistency cues, (2) a reasoning agent that performs human-aligned inferential diagnosis via progressive preference alignment, and (3) an action agent that adaptively plans localized inpainting guided by user preference. This design integrates perceptual evidence, linguistic reasoning, and controllable correction into a unified, self-corrective decision process. To enable fine-grained supervision and quantitative evaluation, we further construct GenBlemish-27K, a dataset of 6K T2I images with 27K annotated artifact regions across 12 categories. Extensive experiments demonstrate that Agentic Retoucher consistently outperforms state-of-the-art methods in perceptual quality, distortion localization and human preference alignment, establishing a new paradigm for self-corrective and perceptually reliable T2I generation.

  • 8 authors
·
Jan 5

Refaçade: Editing Object with Given Reference Texture

Recent advances in diffusion models have brought remarkable progress in image and video editing, yet some tasks remain underexplored. In this paper, we introduce a new task, Object Retexture, which transfers local textures from a reference object to a target object in images or videos. To perform this task, a straightforward solution is to use ControlNet conditioned on the source structure and the reference texture. However, this approach suffers from limited controllability for two reasons: conditioning on the raw reference image introduces unwanted structural information, and it fails to disentangle the visual texture and structure information of the source. To address this problem, we propose Refaçade, a method that consists of two key designs to achieve precise and controllable texture transfer in both images and videos. First, we employ a texture remover trained on paired textured/untextured 3D mesh renderings to remove appearance information while preserving the geometry and motion of source videos. Second, we disrupt the reference global layout using a jigsaw permutation, encouraging the model to focus on local texture statistics rather than the global layout of the object. Extensive experiments demonstrate superior visual quality, precise editing, and controllability, outperforming strong baselines in both quantitative and human evaluations. Code is available at https://github.com/fishZe233/Refacade.

  • 6 authors
·
Dec 4, 2025

SketchDream: Sketch-based Text-to-3D Generation and Editing

Existing text-based 3D generation methods generate attractive results but lack detailed geometry control. Sketches, known for their conciseness and expressiveness, have contributed to intuitive 3D modeling but are confined to producing texture-less mesh models within predefined categories. Integrating sketch and text simultaneously for 3D generation promises enhanced control over geometry and appearance but faces challenges from 2D-to-3D translation ambiguity and multi-modal condition integration. Moreover, further editing of 3D models in arbitrary views will give users more freedom to customize their models. However, it is difficult to achieve high generation quality, preserve unedited regions, and manage proper interactions between shape components. To solve the above issues, we propose a text-driven 3D content generation and editing method, SketchDream, which supports NeRF generation from given hand-drawn sketches and achieves free-view sketch-based local editing. To tackle the 2D-to-3D ambiguity challenge, we introduce a sketch-based multi-view image generation diffusion model, which leverages depth guidance to establish spatial correspondence. A 3D ControlNet with a 3D attention module is utilized to control multi-view images and ensure their 3D consistency. To support local editing, we further propose a coarse-to-fine editing approach: the coarse phase analyzes component interactions and provides 3D masks to label edited regions, while the fine stage generates realistic results with refined details by local enhancement. Extensive experiments validate that our method generates higher-quality results compared with a combination of 2D ControlNet and image-to-3D generation techniques and achieves detailed control compared with existing diffusion-based 3D editing approaches.

  • 4 authors
·
May 10, 2024

Localize-and-Stitch: Efficient Model Merging via Sparse Task Arithmetic

Model merging offers an effective strategy to combine the strengths of multiple finetuned models into a unified model that preserves the specialized capabilities of each. Existing methods merge models in a global manner, performing arithmetic operations across all model parameters. However, such global merging often leads to task interference, degrading the performance of the merged model. In this work, we introduce Localize-and-Stitch, a novel approach that merges models in a localized way. Our algorithm works in two steps: i) Localization: identify tiny (1% of the total parameters) localized regions in the finetuned models containing essential skills for the downstream tasks, and ii) Stitching: reintegrate only these essential regions back into the pretrained model for task synergy. We demonstrate that our approach effectively locates sparse regions responsible for finetuned performance, and the localized regions could be treated as compact and interpretable representations of the finetuned models (tasks). Empirically, we evaluate our method on various vision and language benchmarks, showing that it outperforms existing model merging methods under different data availability scenarios. Beyond strong empirical performance, our algorithm also facilitates model compression and preserves pretrained knowledge, enabling flexible and continual skill composition from multiple finetuned models with minimal storage and computational overhead. Our code is available at https://github.com/uiuctml/Localize-and-Stitch.

  • 5 authors
·
Aug 24, 2024

Refine After Generation: Toward Correct and Concise Patches in LLM-based Program Repair

Large language models (LLMs) have advanced automatic program repair (APR) to the point where agentic systems routinely resolve real-world, repository-level issues. Yet the generated patch has received little scrutiny beyond whether it passes tests. In this paper, we identify patch verbosity as a major yet overlooked concern in LLM-based APR. Characterizing 28 state-of-the-art approaches on SWE-bench Verified, we find that even successful patches are consistently larger and more complex than developer patches, with the median approach producing 121.78% more total changes, 80.91% more net changes, and 43.99% higher cyclomatic complexity. We further show that this verbosity is rooted in capability-oriented design choices such as iterative refinement and broad context, and can hardly be reduced by surface-level controls such as output format or minimality prompts. Motivated by these findings, we formulate post-generation patch refinement and propose RECAP, a lightweight, plug-and-play adapter that attaches to existing repair frameworks after generation. RECAP's refiner is trained via supervised fine-tuning and direct preference optimization with distilled reasoning traces, on a dataset of patch pairs we construct from multiple sources. Across four host systems, prompting, commit-untangling, and minimality-aware baselines reduce patch size only by sacrificing 49 to 217 resolved instances. In contrast, RECAP achieves a substantially better size-correctness tradeoff, cutting average total changes from +242.14% to +4.24% and net changes from +348.24% to -39.75% relative to developer patches while preserving or improving resolution by up to 42 instances. Our results indicate that minimality cannot be simply reduced to syntactic compression, and that decoupling minimization from generation offers a practical path to more reviewable repairs.

  • 7 authors
·
Aug 12

SuperCarver: Texture-Consistent 3D Geometry Super-Resolution for High-Fidelity Surface Detail Generation

Conventional production workflow of high-precision mesh assets necessitates a cumbersome and laborious process of manual sculpting by specialized 3D artists/modelers. The recent years have witnessed remarkable advances in AI-empowered 3D content creation for generating plausible structures and intricate appearances from images or text prompts. However, synthesizing realistic surface details still poses great challenges, and enhancing the geometry fidelity of existing lower-quality 3D meshes (instead of image/text-to-3D generation) remains an open problem. In this paper, we introduce SuperCarver, a 3D geometry super-resolution pipeline for supplementing texture-consistent surface details onto a given coarse mesh. We start by rendering the original textured mesh into the image domain from multiple viewpoints. To achieve detail boosting, we construct a deterministic prior-guided normal diffusion model, which is fine-tuned on a carefully curated dataset of paired detail-lacking and detail-rich normal map renderings. To update mesh surfaces from potentially imperfect normal map predictions, we design a noise-resistant inverse rendering scheme through deformable distance field. Experiments demonstrate that our SuperCarver is capable of generating realistic and expressive surface details depicted by the actual texture appearance, making it a powerful tool to both upgrade historical low-quality 3D assets and reduce the workload of sculpting high-poly meshes.

  • 5 authors
·
Mar 12, 2025

SK-Adapter: Skeleton-Based Structural Control for Native 3D Generation

Native 3D generative models have achieved remarkable fidelity and speed, yet they suffer from a critical limitation: inability to prescribe precise structural articulations, where precise structural control within the native 3D space remains underexplored. This paper proposes SK-Adapter, a simple and yet highly efficient and effective framework that unlocks precise skeletal manipulation for native 3D generation. Moving beyond text or image prompts, which can be ambiguous for precise structure, we treat the 3D skeleton as a first-class control signal. SK-Adapter is a lightweight structural adapter network that encodes joint coordinates and topology into learnable tokens, which are injected into the frozen 3D generation backbone via cross-attention. This smart design allows the model to not only effectively "attend" to specific 3D structural constraints but also preserve its original generative priors. To bridge the data gap, we contribute Objaverse-TMS dataset, a large-scale dataset of 24k text-mesh-skeleton pairs. Extensive experiments confirm that our method achieves robust structural control while preserving the geometry and texture quality of the foundation model, significantly outperforming existing baselines. Furthermore, we extend this capability to local 3D editing, enabling the region specific editing of existing assets with skeletal guidance, which is unattainable by previous methods. Project Page: https://sk-adapter.github.io/

  • 4 authors
·
Mar 14 2

Region-Aware Text-to-Image Generation via Hard Binding and Soft Refinement

In this paper, we present RAG, a Regional-Aware text-to-image Generation method conditioned on regional descriptions for precise layout composition. Regional prompting, or compositional generation, which enables fine-grained spatial control, has gained increasing attention for its practicality in real-world applications. However, previous methods either introduce additional trainable modules, thus only applicable to specific models, or manipulate on score maps within cross-attention layers using attention masks, resulting in limited control strength when the number of regions increases. To handle these limitations, we decouple the multi-region generation into two sub-tasks, the construction of individual region (Regional Hard Binding) that ensures the regional prompt is properly executed, and the overall detail refinement (Regional Soft Refinement) over regions that dismiss the visual boundaries and enhance adjacent interactions. Furthermore, RAG novelly makes repainting feasible, where users can modify specific unsatisfied regions in the last generation while keeping all other regions unchanged, without relying on additional inpainting models. Our approach is tuning-free and applicable to other frameworks as an enhancement to the prompt following property. Quantitative and qualitative experiments demonstrate that RAG achieves superior performance over attribute binding and object relationship than previous tuning-free methods.

  • 9 authors
·
Nov 10, 2024 6

DreamSR: Towards Ultra-High-Resolution Image Super-Resolution via a Receptive-Field Enhanced Diffusion Transformer

Large-scale pre-trained diffusion models have been extensively adopted for real-world image Super-Resolution because of their powerful generative priors through textual guidance. However, when super-resolving high-resolution images with patch-wise inference strategy, most existing diffusion-based SR methods tend to suffer from over-generation, due to the misalignment between the global prompt from LR image and the incomplete semantic information of local patches during each inference step. On the other hand, most existing methods also failed to generate detailed texture in local patches due to the overemphasis on global generation capabilities in network designs and training strategies. To address this issue, we present DreamSR, a novel SR model that suppresses local over-generation and improves fine-detail synthesis, thereby achieving visually faithful results with ultra-high-quality details. Specifically, we propose a dual-branch MM-ControlNet, where the ControlNet generates local textual feature with patch-level prompts while the pre-trained DiT provides global textual feature with global prompts, thereby mitigating over-generation and ensuring semantic consistency across patches. We also design a comprehensive training strategy with stage-specific data processing pipelines and a Receptive-Field Enhancement strategy, enhancing the model's capability to capture patch information and effectively restore local textures. Extensive experiments demonstrate that DreamSR outperforms state-of-the-art methods, providing high-quality SR results. Code and model are available at https://github.com/jerrydong0219/DreamSR.

  • 5 authors
·
May 14

Glob3R: Global Structure-from-Motion with 3D Foundation Models

Recent 3D geometric foundation models, such as VGGT, provide robust feed-forward 3D reconstruction by directly predicting camera poses and 3D scene points from input images. However, their results remain inaccurate, and scaling them to long sequences or large unordered image sets typically requires chunk-wise processing, which can introduce drift and inconsistency. We present Glob3R, a global SfM-style reconstruction built on 3D foundation models. Our key idea is to explicitly optimize feed-forward geometric predictions. To this end, we augment a frozen Pi3X backbone with a lightweight dense matching head that predicts image warps between selected reference frames and neighboring views. These dense warps are converted into sparse but reliable multi-view feature tracks, which provide correspondence constraints for global optimization. We further introduce a keyframe-based sliding-window association strategy that propagates tracks and relative poses across overlapping windows, enabling scalable reconstruction. Finally, we perform global motion averaging and bundle adjustment to refine camera poses, reduce scale inconsistencies, and recover dense scene geometry. Extensive experiments on indoor, outdoor, large-scale driving, and unordered SfM benchmarks demonstrate that Glob3R achieves robust and accurate reconstruction. It consistently improves over feed-forward foundation-model baselines and recent scalable reconstruction methods, while being more robust than classical SfM pipelines. The refined poses also lead to higher-quality neural rendering, validating the benefit of combining foundation-model priors with global geometric optimization. Project page: https://junyuandeng.github.io/Glob3r

  • 10 authors
·
Jul 9

Iterative Refinement Improves Compositional Image Generation

Text-to-image (T2I) models have achieved remarkable progress, yet they continue to struggle with complex prompts that require simultaneously handling multiple objects, relations, and attributes. Existing inference-time strategies, such as parallel sampling with verifiers or simply increasing denoising steps, can improve prompt alignment but remain inadequate for richly compositional settings where many constraints must be satisfied. Inspired by the success of chain-of-thought reasoning in large language models, we propose an iterative test-time strategy in which a T2I model progressively refines its generations across multiple steps, guided by feedback from a vision-language model as the critic in the loop. Our approach is simple, requires no external tools or priors, and can be flexibly applied to a wide range of image generators and vision-language models. Empirically, we demonstrate consistent gains on image generation across benchmarks: a 16.9% improvement in all-correct rate on ConceptMix (k=7), a 13.8% improvement on T2I-CompBench (3D-Spatial category) and a 12.5% improvement on Visual Jenga scene decomposition compared to compute-matched parallel sampling. Beyond quantitative gains, iterative refinement produces more faithful generations by decomposing complex prompts into sequential corrections, with human evaluators preferring our method 58.7% of the time over 41.3% for the parallel baseline. Together, these findings highlight iterative self-correction as a broadly applicable principle for compositional image generation. Results and visualizations are available at https://iterative-img-gen.github.io/

  • 8 authors
·
Jan 21

MatSpray: Fusing 2D Material World Knowledge on 3D Geometry

Manual modeling of material parameters and 3D geometry is a time consuming yet essential task in the gaming and film industries. While recent advances in 3D reconstruction have enabled accurate approximations of scene geometry and appearance, these methods often fall short in relighting scenarios due to the lack of precise, spatially varying material parameters. At the same time, diffusion models operating on 2D images have shown strong performance in predicting physically based rendering (PBR) properties such as albedo, roughness, and metallicity. However, transferring these 2D material maps onto reconstructed 3D geometry remains a significant challenge. We propose a framework for fusing 2D material data into 3D geometry using a combination of novel learning-based and projection-based approaches. We begin by reconstructing scene geometry via Gaussian Splatting. From the input images, a diffusion model generates 2D maps for albedo, roughness, and metallic parameters. Any existing diffusion model that can convert images or videos to PBR materials can be applied. The predictions are further integrated into the 3D representation either by optimizing an image-based loss or by directly projecting the material parameters onto the Gaussians using Gaussian ray tracing. To enhance fine-scale accuracy and multi-view consistency, we further introduce a light-weight neural refinement step (Neural Merger), which takes ray-traced material features as input and produces detailed adjustments. Our results demonstrate that the proposed methods outperform existing techniques in both quantitative metrics and perceived visual realism. This enables more accurate, relightable, and photorealistic renderings from reconstructed scenes, significantly improving the realism and efficiency of asset creation workflows in content production pipelines.

CGTuebingen CG Tübingen
·
Dec 20, 2025 2

SuGaR: Surface-Aligned Gaussian Splatting for Efficient 3D Mesh Reconstruction and High-Quality Mesh Rendering

We propose a method to allow precise and extremely fast mesh extraction from 3D Gaussian Splatting. Gaussian Splatting has recently become very popular as it yields realistic rendering while being significantly faster to train than NeRFs. It is however challenging to extract a mesh from the millions of tiny 3D gaussians as these gaussians tend to be unorganized after optimization and no method has been proposed so far. Our first key contribution is a regularization term that encourages the gaussians to align well with the surface of the scene. We then introduce a method that exploits this alignment to extract a mesh from the Gaussians using Poisson reconstruction, which is fast, scalable, and preserves details, in contrast to the Marching Cubes algorithm usually applied to extract meshes from Neural SDFs. Finally, we introduce an optional refinement strategy that binds gaussians to the surface of the mesh, and jointly optimizes these Gaussians and the mesh through Gaussian splatting rendering. This enables easy editing, sculpting, rigging, animating, compositing and relighting of the Gaussians using traditional softwares by manipulating the mesh instead of the gaussians themselves. Retrieving such an editable mesh for realistic rendering is done within minutes with our method, compared to hours with the state-of-the-art methods on neural SDFs, while providing a better rendering quality.

  • 2 authors
·
Nov 21, 2023 3

S3IM: Stochastic Structural SIMilarity and Its Unreasonable Effectiveness for Neural Fields

Recently, Neural Radiance Field (NeRF) has shown great success in rendering novel-view images of a given scene by learning an implicit representation with only posed RGB images. NeRF and relevant neural field methods (e.g., neural surface representation) typically optimize a point-wise loss and make point-wise predictions, where one data point corresponds to one pixel. Unfortunately, this line of research failed to use the collective supervision of distant pixels, although it is known that pixels in an image or scene can provide rich structural information. To the best of our knowledge, we are the first to design a nonlocal multiplex training paradigm for NeRF and relevant neural field methods via a novel Stochastic Structural SIMilarity (S3IM) loss that processes multiple data points as a whole set instead of process multiple inputs independently. Our extensive experiments demonstrate the unreasonable effectiveness of S3IM in improving NeRF and neural surface representation for nearly free. The improvements of quality metrics can be particularly significant for those relatively difficult tasks: e.g., the test MSE loss unexpectedly drops by more than 90% for TensoRF and DVGO over eight novel view synthesis tasks; a 198% F-score gain and a 64% Chamfer L_{1} distance reduction for NeuS over eight surface reconstruction tasks. Moreover, S3IM is consistently robust even with sparse inputs, corrupted images, and dynamic scenes.

  • 8 authors
·
Aug 14, 2023

CLNeRF: Continual Learning Meets NeRF

Novel view synthesis aims to render unseen views given a set of calibrated images. In practical applications, the coverage, appearance or geometry of the scene may change over time, with new images continuously being captured. Efficiently incorporating such continuous change is an open challenge. Standard NeRF benchmarks only involve scene coverage expansion. To study other practical scene changes, we propose a new dataset, World Across Time (WAT), consisting of scenes that change in appearance and geometry over time. We also propose a simple yet effective method, CLNeRF, which introduces continual learning (CL) to Neural Radiance Fields (NeRFs). CLNeRF combines generative replay and the Instant Neural Graphics Primitives (NGP) architecture to effectively prevent catastrophic forgetting and efficiently update the model when new data arrives. We also add trainable appearance and geometry embeddings to NGP, allowing a single compact model to handle complex scene changes. Without the need to store historical images, CLNeRF trained sequentially over multiple scans of a changing scene performs on-par with the upper bound model trained on all scans at once. Compared to other CL baselines CLNeRF performs much better across standard benchmarks and WAT. The source code, and the WAT dataset are available at https://github.com/IntelLabs/CLNeRF. Video presentation is available at: https://youtu.be/nLRt6OoDGq0?si=8yD6k-8MMBJInQPs

  • 2 authors
·
Aug 28, 2023