

QwenPU-RF (rv1 merge)
Qwen3.5-4B with an RV32 CPU compiled into its weights, used to run exact radio signal processing
inside the model. This is the 19 GB checkpoint behind every Stage 2 result in
github.com/pratx1906/QWENPU-RF: Qwen calls its in-weights RF
tools (rf_analyze, rf_levels, rf_modulation) with an ordinary <tool_call>, the RF program runs
as trace tokens through the model's own layers, every token is checked against a reference RISC-V
machine, and Qwen answers from the printed report.
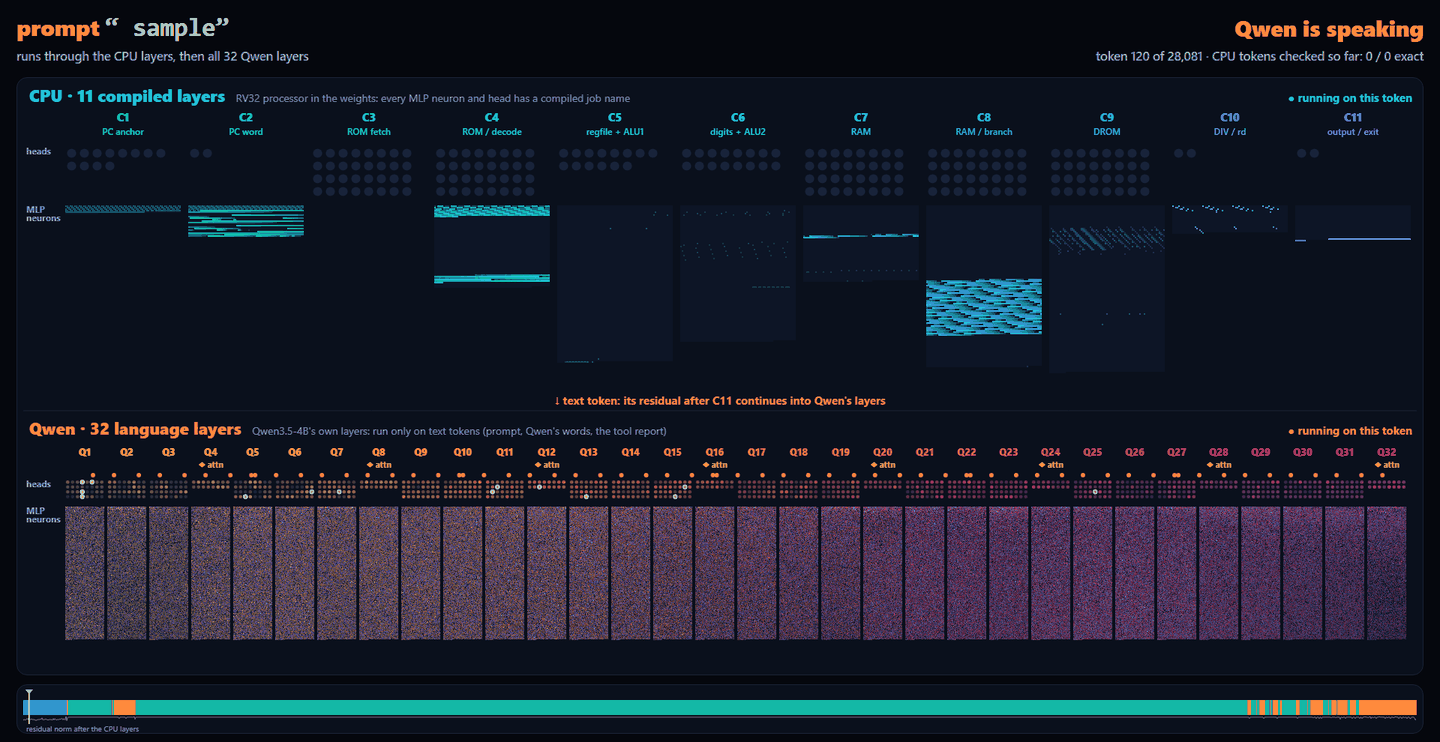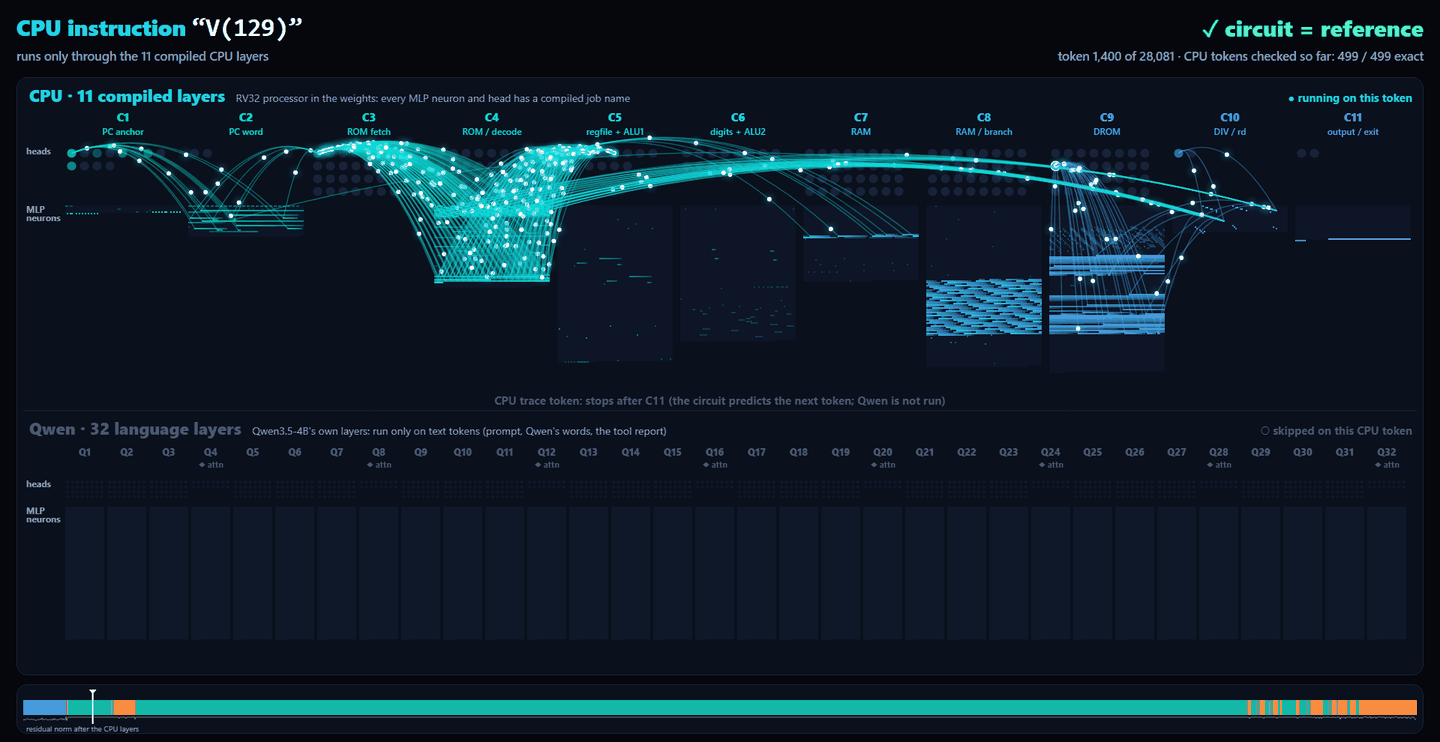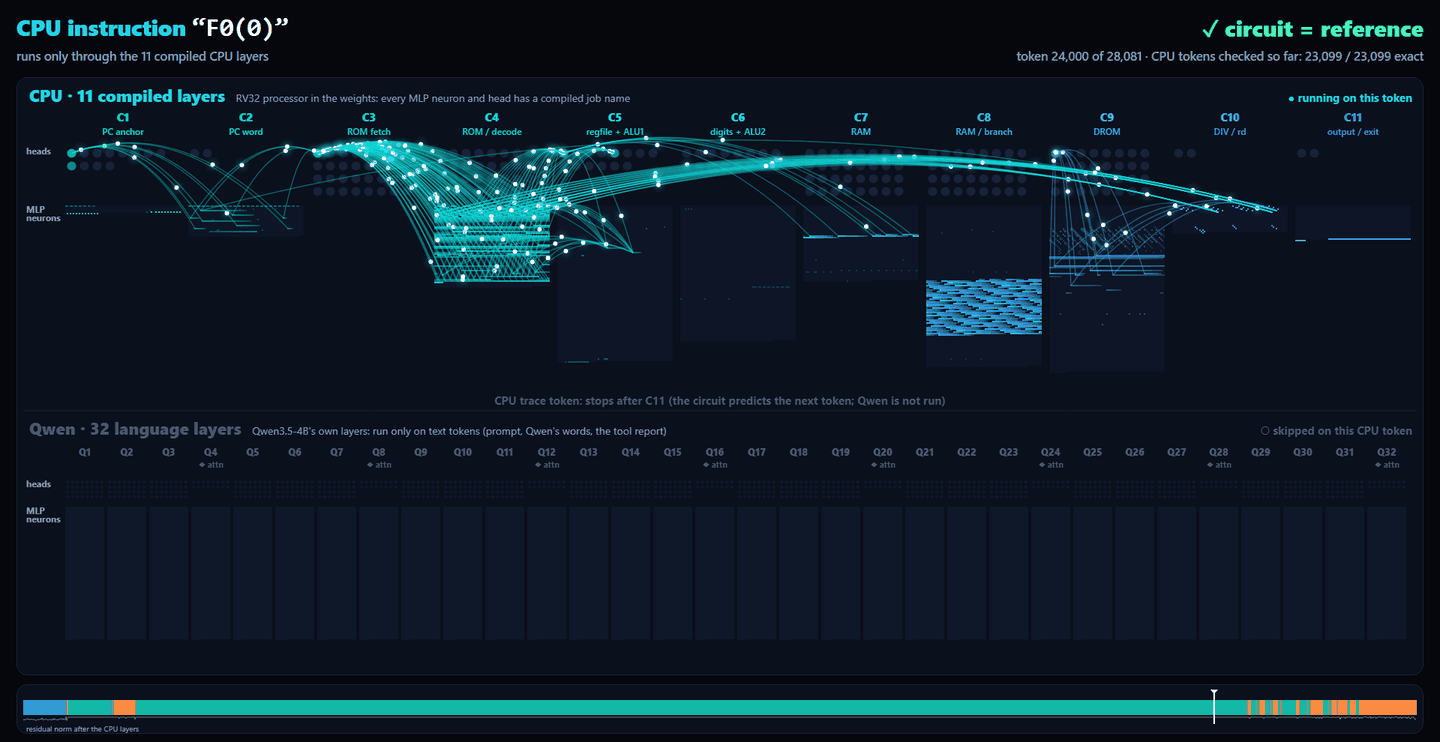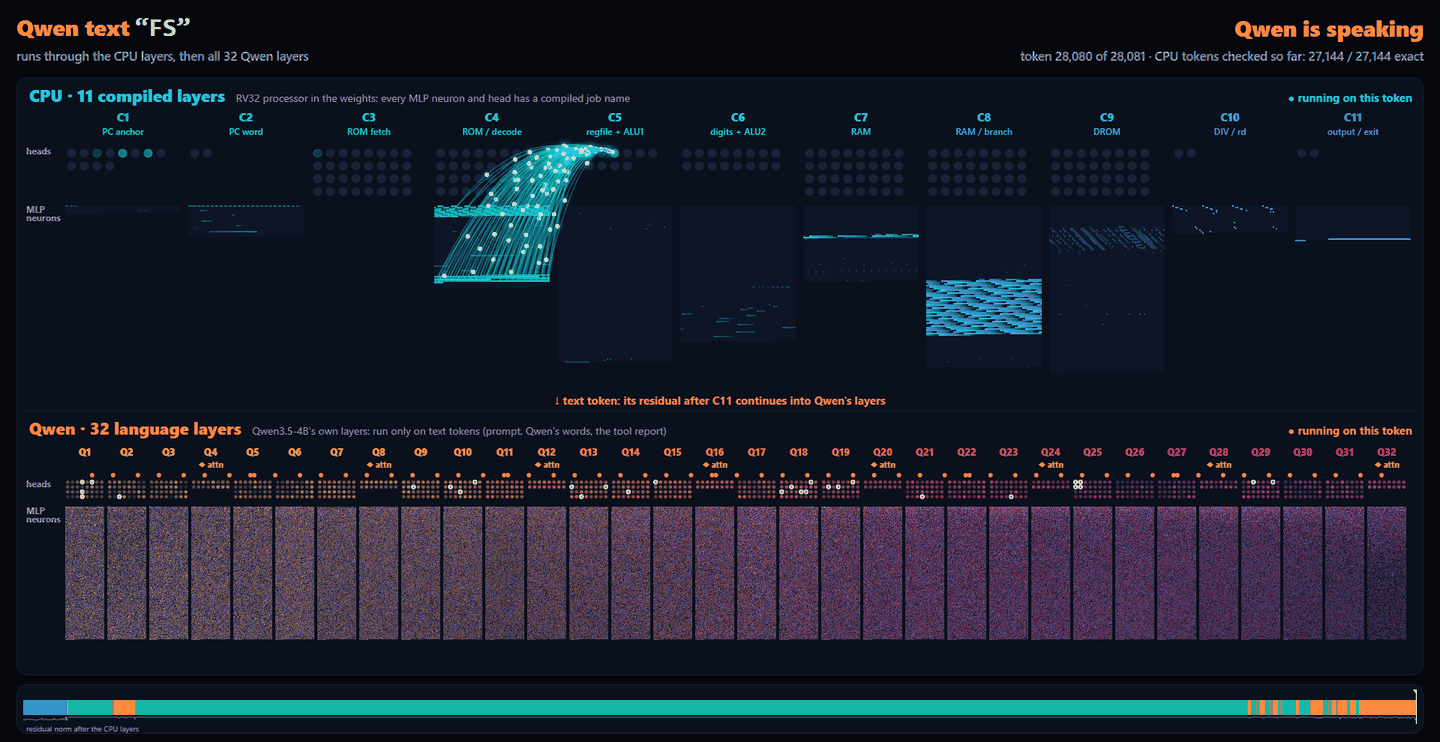
What is in the checkpoint
| Layers | 43 = 11 compiled CPU layers in front of Qwen3.5-4B's 32 |
| Hidden size | 3968 (Qwen's 2560 plus 1408 dimensions for the computer) |
| Compiled circuit | RV32 CPU from QwenPU chipformer at 5af1fc0, plain-CPU layout rv1: 103 heads, 42,202 FFN units, RAM in Gated DeltaNet state |
| Vocabulary | Qwen's tokens plus the CPU trace tokens (offset 248,320) |
| Training | None. The new weights are computed by a compiler; Qwen3.5-4B's own weights are kept |
| Fits | One 24 GB GPU, whole model (unlike the 26.7 GB QwenPU checkpoint with the vector unit) |
Built with python -m chipformer.rv.merge from
Qwen/Qwen3.5-4B at 851bf6e.
How to use
The computer only works through the harness that writes the tool call into its RAM and checks the trace. Use the GitHub repository:
git clone https://github.com/pratx1906/QWENPU-RF && cd QWENPU-RF
python upstream/setup_upstream.py
pip install -e "upstream/QwenPU[hf]" -r requirements.txt
hf download pratx1/QwenPU-RF --local-dir rfpu-data/checkpoints/rfpu-v15/qwen3.5-4b-rv1
python v15/scripts/stage2_chat.py --suite robust --full-gpu rfpu-data/checkpoints/rfpu-v15/qwen3.5-4b-rv1 --chunk 1024
Plain text generation without the harness has not been tested.
Verified results on this checkpoint
All on one RTX 5090 laptop GPU, every chip token checked against the RV32 reference:
- Functional check of these exact files (2026-11-20): Qwen called
rf_levels; 625 text + 26,581 chip tokens; 27,144 / 27,144 circuit tokens equal the reference, 0 mismatches; answer −48.9 / −10.4 dBFS (correct). - 96-question bank: 96/96 circuit-exact, right tool 96/96, 99.0% of numbers in answers traceable to the verified report.
- Unanswerable questions: declined 16/16 with firmware v4's
not_measuredline. - Modulation: Qwen calls
rf_modulation(about 465k chip tokens per call) and names the printed class 10/10.
Details and every caveat: the repository README.
Limits
- About 10⁵–10⁶× slower than a conventional DSP; 27–122 s per question.
- The numbers are verified; Qwen's interpretation of them is checked by an answer checker, not proven.
- "Exact" means bit-exact to a declared 16-bit fixed-point contract, not exact against floating point.
- The modulation classifier was trained and tested on synthetic signals only.
Integrity
SHA-256 of every file is in SHA256SUMS (also in the GitHub repo at
v15/reports/checkpoint-provenance/qwen3.5-4b-rv1.sha256).
License and credits
Apache-2.0, as a modified version of Qwen/Qwen3.5-4B. The compiled CPU comes from QwenPU and Qwenputer by Divyansh Agrawal (code MIT). Please cite those together with QwenPU-RF.
- Downloads last month
- -