| --- |
| title: README |
| emoji: 🗣️ |
| colorFrom: green |
| colorTo: yellow |
| sdk: static |
| pinned: false |
| --- |
| |
|  |
|
|
| # Hebrish · עבריש |
|
|
| **Dictation that gets the Hebrew words right.** |
|
|
|  |
|
|
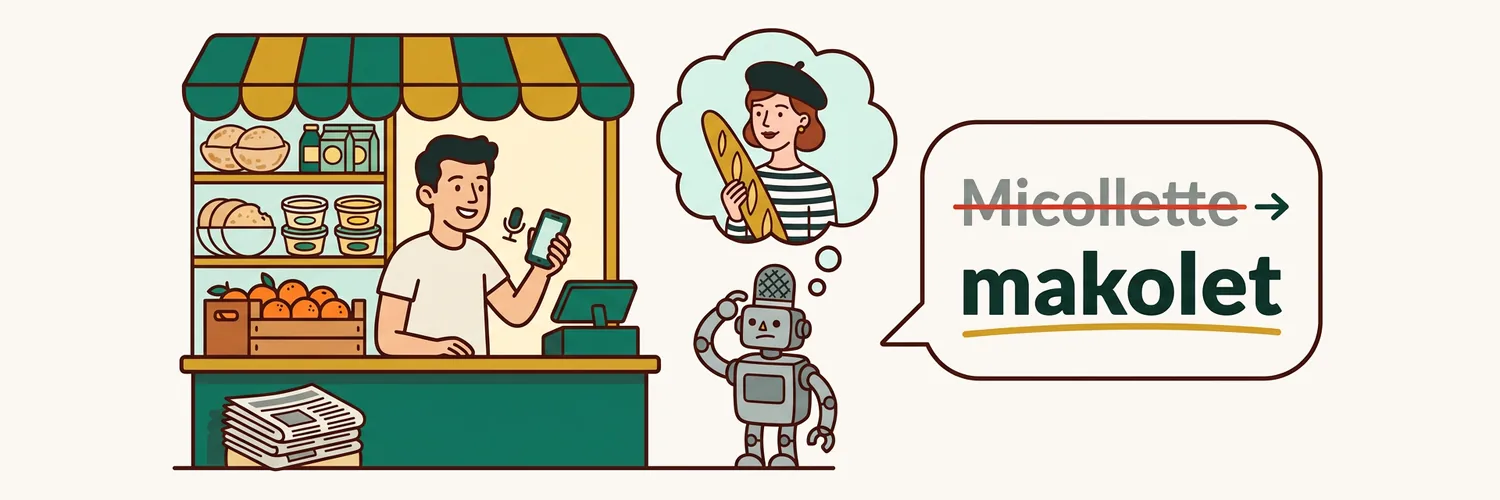
| Ordinary dictation hears *makolet* and writes "Micollette". Hebrish writes the Hebrew word. |
|
|
| Hebrish builds open speech tools for code-switched English–Hebrew, for English-speaking immigrants in Israel and users throughout the Jewish world: speech recognition (ASR) that writes the Hebrew words correctly, and speech synthesis (TTS) that says them correctly. It is a one-person, not-for-profit project by Daniel Rosehill, and its models and data are open. |
|
|
| - **Models:** see them all on one page in the [Hebrish Models Space](https://huggingface.co/spaces/Hebrish/Hebrish-Models). |
| - **Speech recognition (ASR):** |
| - [Sabich](https://huggingface.co/Hebrish/Sabich), recommended in the apps: code-switching plus tech vocabulary. It comes in variants for every size of device: [Qwen3-ASR-1.7B](https://huggingface.co/Hebrish/Sabich-Qwen3-ASR-1.7B) and [Canary-Qwen-2.5B](https://huggingface.co/Hebrish/Sabich-Canary-Qwen-2.5B) for desktop GPUs, [Parakeet-110M](https://huggingface.co/Hebrish/Sabich-Parakeet-110M) for small devices, and [asr4all-S](https://huggingface.co/Hebrish/Sabich-asr4all-S) and [-M](https://huggingface.co/Hebrish/Sabich-asr4all-M) for wearables. |
| - [Jachnun](https://huggingface.co/Hebrish/Jachnun): code-switching only. |
| - [Shakshuka](https://huggingface.co/Hebrish/Shakshuka): streaming, so the words appear while you speak. |
| - Whisper Hebrish: Whisper fine-tunes, where the project started. |
| - On-device builds (GGUF, ONNX, sherpa-onnx, MLX) are in `-<format>` repos. [Which model should I use?](https://hebrish.app/models/choose) |
| - **Speech synthesis (TTS):** |
| - [Meorav](https://hebrish.app/models/meorav): code-switching text-to-speech, a Qwen3-TTS fine-tune that reads code-switched English aloud and pronounces the Hebrew words in it correctly. [Meorav PoC-1](https://huggingface.co/Hebrish/TTS-V1) is the first checkpoint: experimental, open (CC BY-NC 4.0), no benchmark yet. Training code: [Meorav-TTS](https://github.com/Hebrish-ASR/Meorav-TTS). |
| - A [token classifier](https://huggingface.co/Hebrish/Hebrew-Latin-Token-Classifier) that finds romanized Hebrew words in English text, for text-to-speech. |
| - **Data:** read-aloud code-switching sentences and a frozen benchmark, scored by Hebrew-term recall on a clean subset. Results: [hebrish.app/benchmarks](https://hebrish.app/benchmarks). |
| - **Apps:** [Hebrish](https://github.com/Hebrish-ASR/Hebrish-App) runs the models on-device on Android, Linux and Windows. |
|
|
| Everything in one place, including repos still on Daniel's personal account: [the Hebrish collection](https://huggingface.co/collections/Hebrish/hebrish-english-hebrew-code-switching-6ad6143c7de198780425709f). |
|
|
| Website: [hebrish.app](https://hebrish.app) · GitHub: [Hebrish-ASR](https://github.com/Hebrish-ASR) |
|
|


