
Spaces:
Running

Running

metadata
title: README
emoji: 👁️
colorFrom: blue
colorTo: indigo
sdk: static
pinned: false
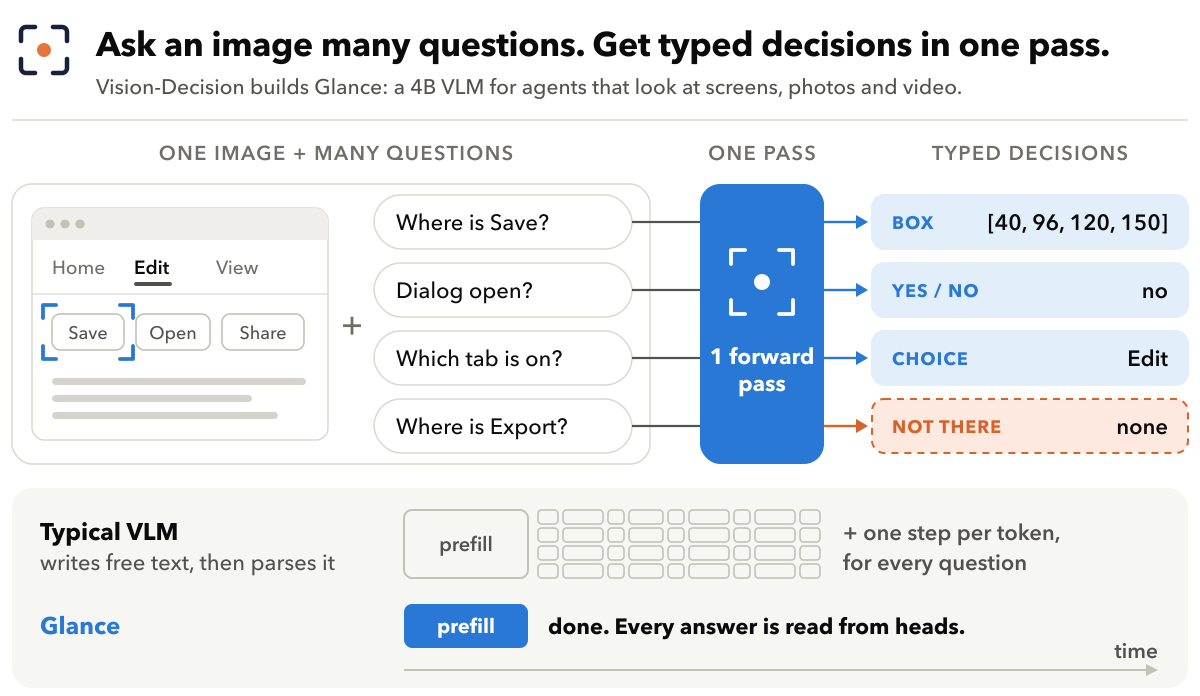
视觉决策模型:一次前向,回答一张图上的许多问题。
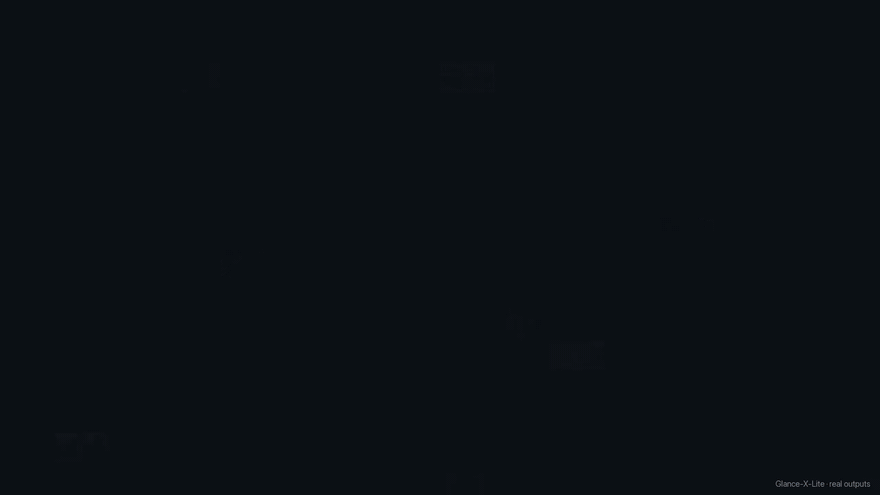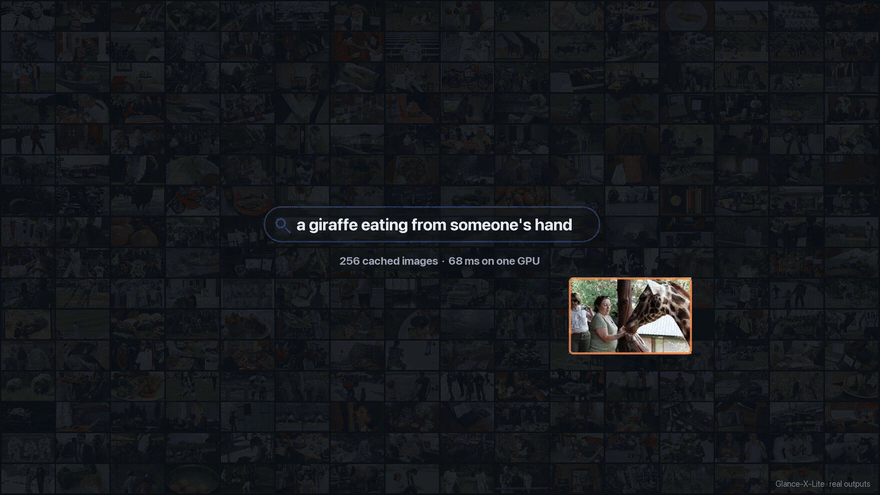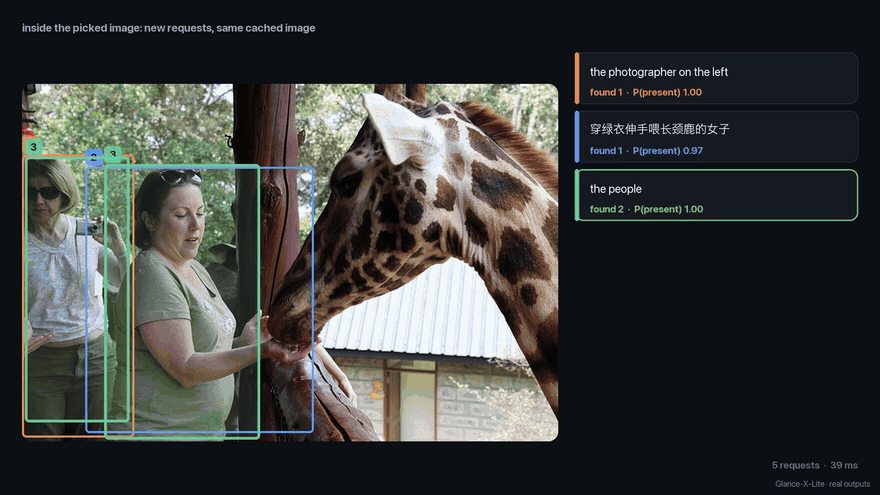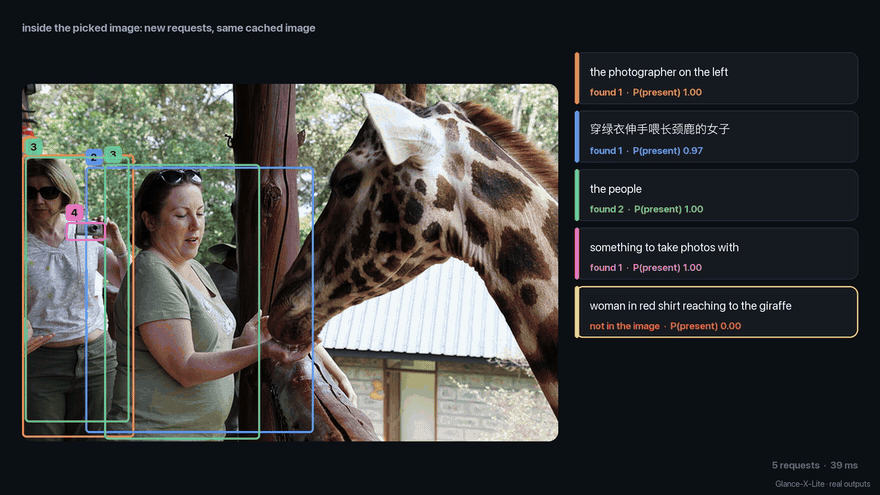
Why. Agents mostly need decisions, not prose: Where is the button? Is it there at all? Which clip shows it? Generative VLMs write every answer token by token, which is slow and turns "not there" into a guess. Glance reads them all from one pass.
Models
| model | what it is |
|---|---|
| Glance-4B-preview | a 4B decision VLM on Qwen3.5-4B: boxes, yes/no, choices and scores, with calibrated "not there", from one prefill |
| Glance-X-4B | bidirectional grounding: reuse the image across requests or the request across images, with multi-box output |
| Glance-X-Lite | a 0.8B Glance-X for Apple silicon and other small devices |
Data
| dataset | what it is |
|---|---|
| Glance-COCO | grounding on COCO images with exact boxes, many phrasings, Chinese requests, hard negatives and multi-target queries; plus training supplements, trainer-format records and the robust evaluation set (formerly Glance-Data) |
| Glance-GUI | synthetic GUI grounding: 18.5k screenshots, 1.08M requests with verified hard negatives |
| Glance-Video | typed-question records for short video clips (annotations only) |
| Glance-Experiments | results and model outputs: the Decision Index run, the referring-negative audit, scan-engine measurements |
Browse by collection: Glance models · Glance training data · Glance evaluation · Collaborator projects
Code
Glance (inference package) · Glance-Core (training, data builders, evaluation) · Glance-Engine (serving engine) · Glance-Video (video and clip scanning) · Glance-X-MLX · Glance-COCO (data pipeline)