

D3 Flash leads 18 local decision configurations on an RTX 2060 6 GB

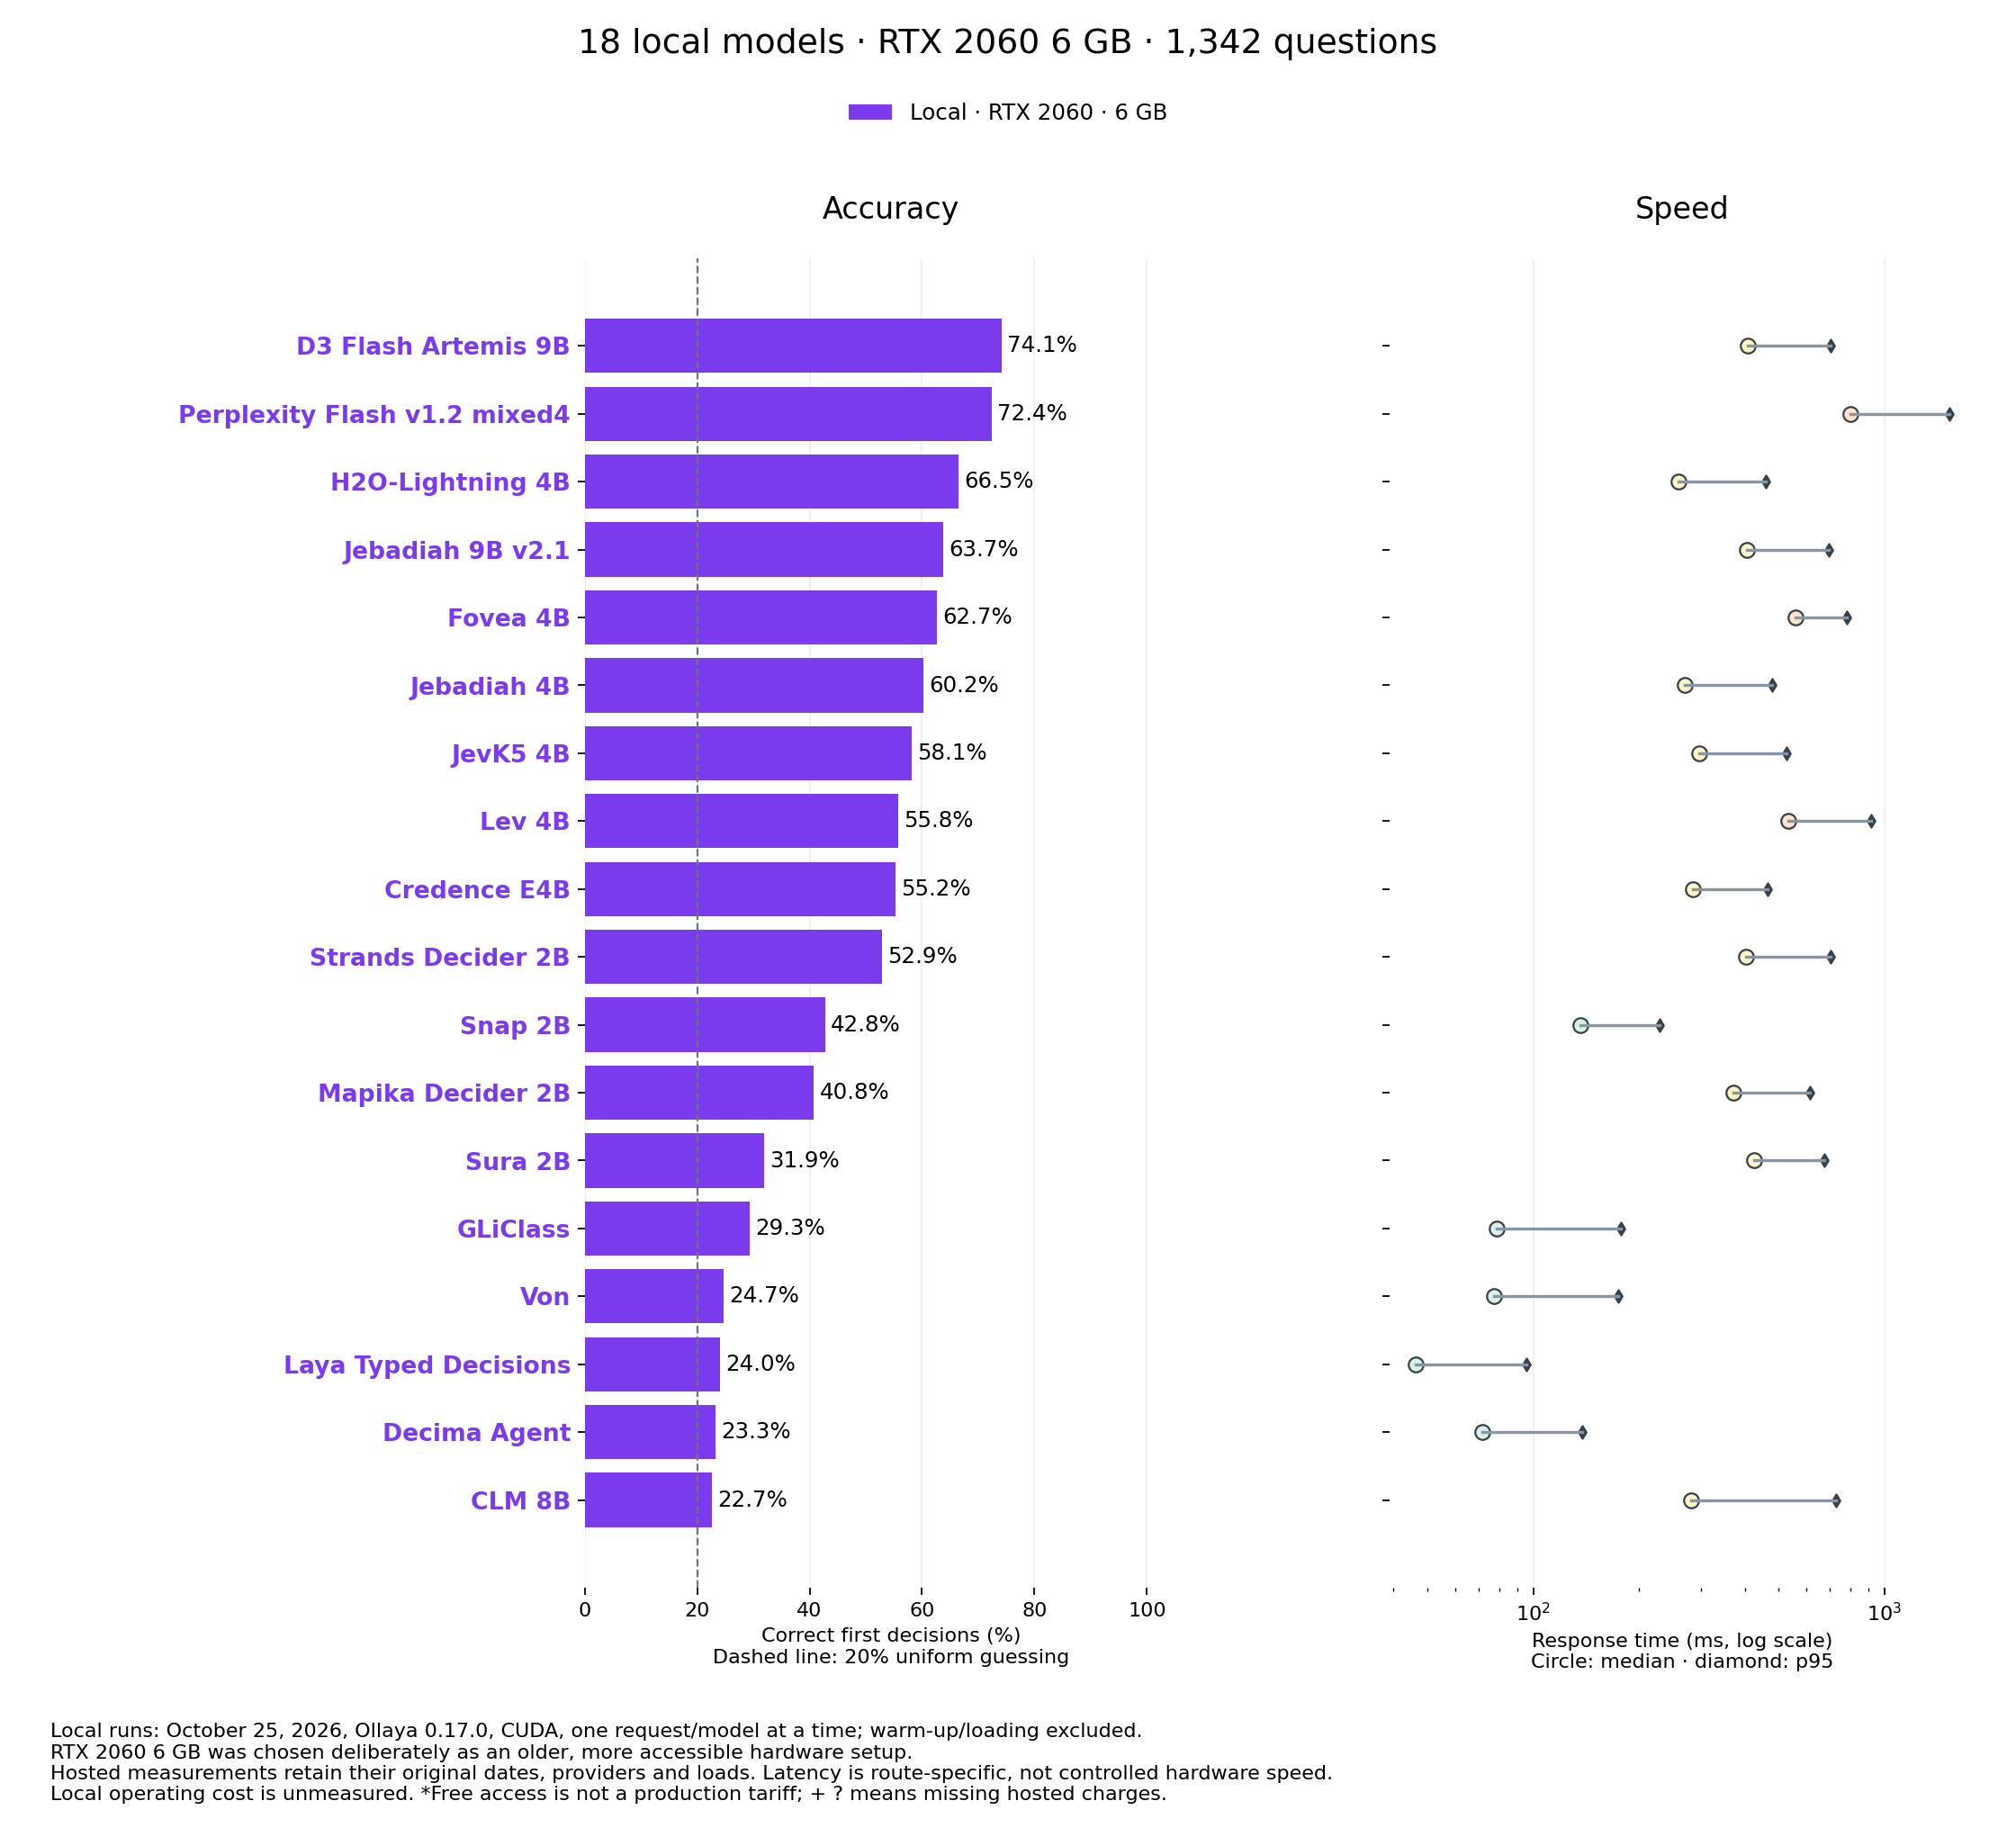
D3 Flash is the highest-scoring local configuration in my System 1 decision benchmark: 995/1,342 correct (74.1%), with a 408 ms median. The comparison now covers 49 routes, including 18 local configurations, on the same 31-category text bank.
I deliberately used an older RTX 2060 with 6 GB VRAM to explore a more accessible setup that readers may already have. The local D3 run used Artemis IQ3_M, served through Ollaya 0.17.0 over the LAN, one request at a time. Loading and warm-up calls are excluded.
| Local configuration | Accuracy | Median | p95 |
|---|---|---|---|
| D3 Flash Artemis 9B | 74.1% | 408 ms | 701 ms |
| Perplexity Flash v1.2 mixed4 | 72.4% | 798 ms | 1,526 ms |
| H2O-Lightning 4B Q8_0 | 66.5% | 259 ms | 459 ms |
D3 scored 43/46 on if-then rules, 40/43 on planning, and 48/51 on explicit preference ordering. Sequential procedures scored 14/48, and spatial tracking 22/49. Three requests exceeded this local runtime's input batch limit and remain unsuccessful in the full-bank score.
The hosted d3-turbo run scored 1,106/1,342 (82.4%), with a 165 ms median and 298 ms p95—the third-lowest median among the 27 hosted decision routes. That run was measured October 20; the local runs October 25, 2026. These are different serving setups.
Full results, questions, category profiles and methods · GitHub repository


Thank you, Theo and Xunzhuo! I have since tested hosted D3 Ultra on both benchmarks, and the comparison with the earlier Turbo runs is interesting.
| Test | D3 Turbo | D3 Ultra |
|---|---|---|
| Text: 1,342 questions | 1,106 correct (82.4%), 165 ms median | 1,124 correct (83.8%), 148 ms median |
| Images: 200 questions | 155 correct (77.5%), 431 ms median | 148 correct (74.0%), 361 ms median |
Ultra answered 18 more text questions correctly, while Turbo answered seven more image questions correctly. On text, Ultra improved from 38/50 to 45/50 on causal intervention questions. On images, Turbo scored 7/10 and Ultra 3/10 on navigation and planning; Ultra scored 9/10 and Turbo 8/10 on spatial relationships. The image categories have ten questions each.
Turbo was tested on October 20 and Ultra on October 27, 2026. The Ultra request explicitly selected vllm-sr/d3-ultra. The current service catalog lists d3-turbo as an alias for Ultra, so I have kept the original Turbo measurements with their test date.