| --- |
| library_name: transformers |
| pipeline_tag: text-generation |
| tags: |
| - custom_code |
| - diffusion |
| - continuous-latent |
| - base-model |
| --- |
| |
| # Cola2 |
|
|
| Cola2 is a continuous-latent language model that co-adapts semantic |
| compression and discrete text generation. It combines a dynamic-compression |
| VAE, a block-causal Diffusion Transformer (DiT), and a span-causal token |
| decoder with latent feedback. |
|
|
| [GitHub](https://github.com/ByteDance-Seed/Cola2) · |
| [中文说明](https://github.com/ByteDance-Seed/Cola2/blob/main/README_zh.md) · |
| [Paper](https://arxiv.org/abs/2610.31305) · |
| [Project page](https://hongcanguo.github.io/Cola2/) |
|
|
| ## Overview |
|
|
| The accompanying paper is titled **“Cola2: Co-Adaptive Hierarchical Language |
| Modeling with Continuous Semantic Compression and Balanced Discrete |
| Generation.”** Cola2 dynamically groups text into semantic spans, represents |
| each span with a compact continuous latent, generates latent blocks with a |
| DiT, and realizes those latents as discrete tokens. |
|
|
| The released checkpoint was trained on 346.03B source tokens and reaches a |
| reported 60.10 average across eight evaluation tasks. These are reported paper |
| results; individual runs may differ because latent generation is stochastic. |
|
|
| This repository contains: |
|
|
| - eight sharded safetensors weight files; |
| - tokenizer and generation configuration files; |
| - Hugging Face Transformers remote-code modules; |
| - normalized JSONL data for eight evaluation tasks; and |
| - `SHA256SUMS` for release-file verification. |
|
|
| The inference implementation, command-line tools, examples, benchmark runner, |
| and documentation are maintained in the |
| [Cola2 GitHub repository](https://github.com/ByteDance-Seed/Cola2). |
| Training code is not included in this release. |
|
|
| ## Project overview |
|
|
| [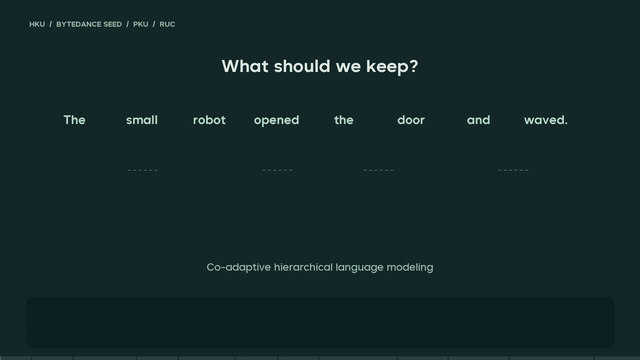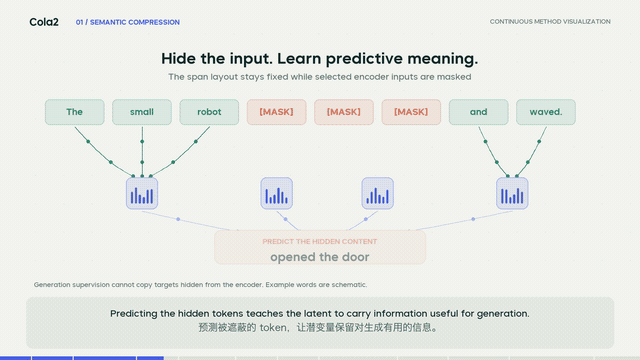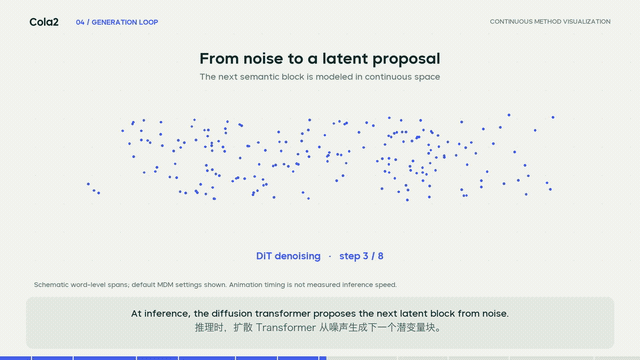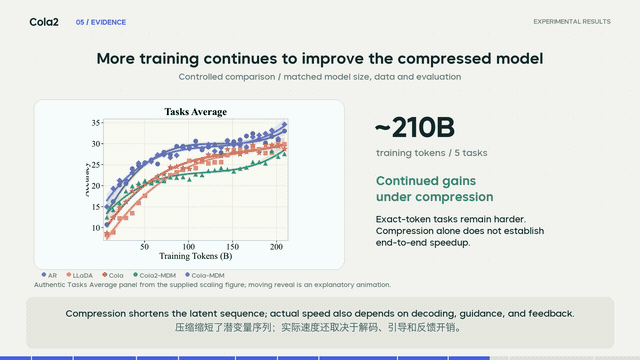](https://github.com/ByteDance-Seed/Cola2/blob/main/assets/videos/cola2-v2-motion-bgm-1080p.mp4) |
|
|
| Click the preview to watch the full video · |
| [Open the interactive project page](https://hongcanguo.github.io/Cola2/) |
|
|
| ## Method |
|
|
|  |
|
|
| Stage I jointly trains the dynamic-compression encoder and the token decoder. |
| Stage II continues adapting that VAE with token-side supervision while an |
| approximately 4B DiT learns the detached latent distribution through Flow |
| Matching. During inference, Cola2 repeatedly proposes a latent block, decodes |
| tokens, and re-encodes the committed text under the fixed span layout so the |
| continuous and discrete histories stay aligned. |
|
|
| ## Controlled scaling |
|
|
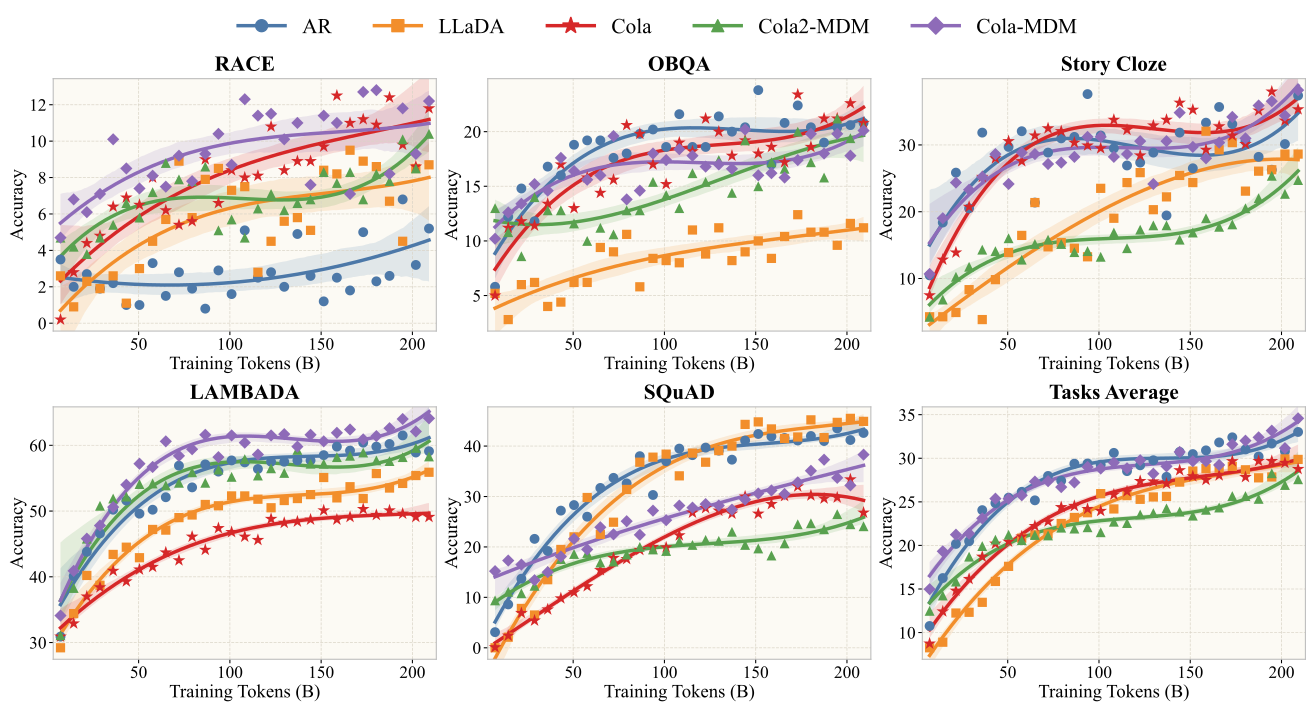
| The controlled study compares AR, LLaDA, Cola DLM, uncompressed Cola-MDM, and |
| compressed Cola2-MDM at matched model size, data, and evaluation settings. |
| Cola-MDM has the strongest aggregate scaling; Cola2-MDM converges more slowly |
| but continues closing its gap to LLaDA after roughly 150B tokens and remains |
| unsaturated at about 210B tokens. |
|
|
|  |
|
|
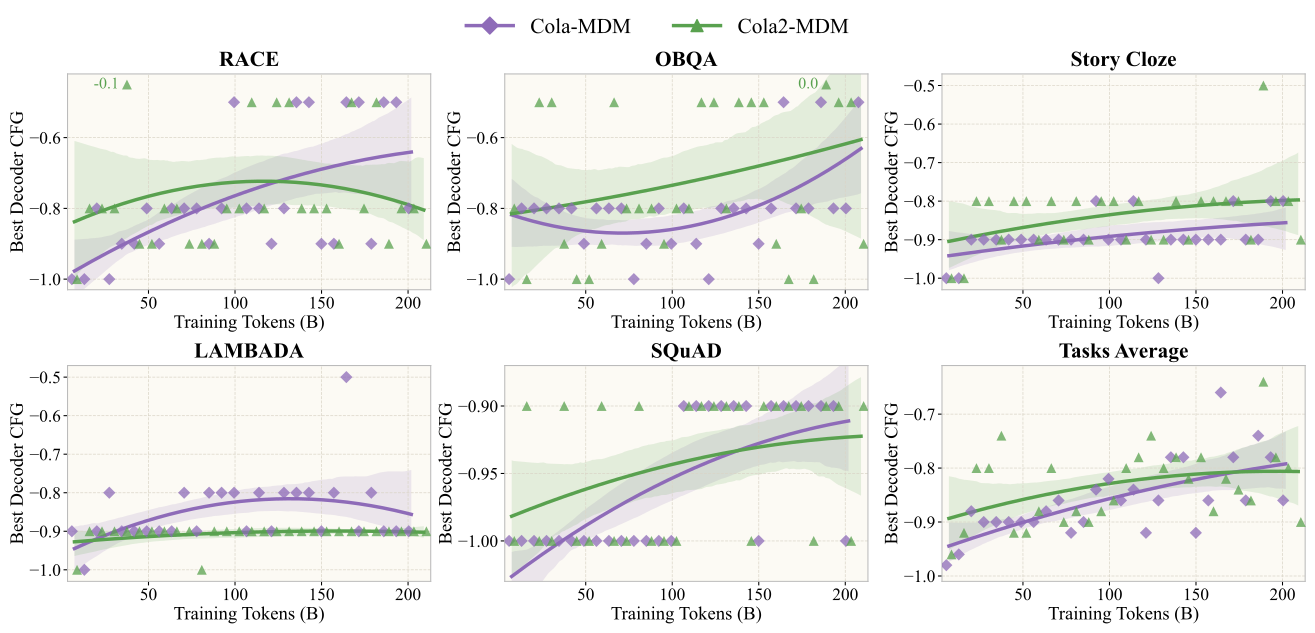
| The optimal decoder classifier-free-guidance weight remains near `-0.9` for |
| most of training and gradually moves toward zero. |
|
|
|  |
|
|
| ## Post-pretraining results |
|
|
| The resource-constrained checkpoint uses 346.03B source tokens. Its latent DiT |
| is still unconverged, yet Cola2 reaches a 60.10 eight-task average and exceeds |
| Llama-3-8B on HellaSwag and StoryCloze with more than 43× fewer reported |
| pretraining tokens. |
|
|
| | Task | Llama-3-8B | Qwen2.5-7B | Qwen3-8B-Base | LLaDA-8B-Base | **Cola2** | |
| |---|---:|---:|---:|---:|---:| |
| | Pretraining tokens | 15T+ | 18T | ~36T | 2.3T | **346B** | |
| | RACE | 75.77 | 89.95 | 90.65 | 87.40 | **69.91** | |
| | NarrativeQA | 42.70 | 32.90 | 37.30 | 36.00 | **32.70** | |
| | HellaSwag | 39.21 | 75.67 | 68.13 | 69.65 | **41.75** | |
| | StoryCloze | 79.49 | 95.09 | 97.44 | 95.94 | **80.42** | |
| | LAMBADA | 75.70 | 71.82 | 71.20 | 67.90 | **63.00** | |
| | ARC-Easy | 90.86 | 96.00 | 97.35 | 93.85 | **87.62** | |
| | TruthfulQA | 63.04 | 69.03 | 72.58 | 64.87 | **54.10** | |
| | MMLU | 63.19 | 70.16 | 72.31 | 61.27 | **51.32** | |
| | **8-task average** | **66.25** | **75.08** | **75.87** | **72.11** | **60.10** | |
|
|
| Values are accuracies (%) except for the token row. Models use different |
| training recipes, tokenizers, and token-counting conventions, so this table |
| contextualizes capability rather than isolating the generation paradigm. |
| Each Cola2 task value is the mean of three latent-noise sampled evaluations; |
| see the |
| [reference results](https://github.com/ByteDance-Seed/Cola2/blob/main/eval_output/full_test_results.md) |
| and |
| [reproduction protocol](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/reproduction.md). |
|
|
| ## Requirements |
|
|
| Python 3.10+, PyTorch 2.2+, Transformers 4.51–4.x, and safetensors 0.4+ are |
| required. CUDA with bfloat16 is recommended. |
|
|
| ```bash |
| python -m pip install "torch>=2.2" "transformers>=4.51,<5" "safetensors>=0.4" accelerate |
| ``` |
|
|
| ## Quick start |
|
|
| This model uses custom Transformers code, so `trust_remote_code=True` is |
| required. |
|
|
| ```python |
| import torch |
| from transformers import AutoModel, AutoTokenizer |
| |
| model_id = "ByteDance-Seed/Cola2" |
| tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True) |
| model = AutoModel.from_pretrained( |
| model_id, |
| trust_remote_code=True, |
| torch_dtype=torch.bfloat16, |
| low_cpu_mem_usage=True, |
| ).to("cuda").eval() |
| |
| prompt = "Question: What is the capital of France? Answer:" |
| inputs = tokenizer(prompt, return_tensors="pt").to(model.device) |
| generator = torch.Generator(device=model.device).manual_seed(42) |
| |
| with torch.inference_mode(): |
| output = model.generate(**inputs, generator=generator) |
| |
| answer = tokenizer.decode( |
| output[0, inputs.input_ids.shape[1] :], |
| skip_special_tokens=True, |
| ) |
| print(answer) |
| ``` |
|
|
| Cola2 is a base model, not an instruction-tuned chat assistant. |
|
|
| ## Default generation preset |
|
|
| Without overrides, `generate()` uses the released paper preset: |
|
|
| - 8-step low-noise-biased Euler DiT schedule; |
| - DiT classifier-free guidance (CFG) scale 10; |
| - decoder CFG scale -0.9; |
| - one latent span per decoder chunk; |
| - dynamic duration and latent feedback; |
| - greedy token selection; and |
| - `max_new_tokens=32`. |
|
|
| Greedy token selection does not make generation deterministic: latent |
| generation starts from Gaussian noise. Pass a seeded `torch.Generator` when |
| comparing outputs. |
|
|
| ## Command line |
|
|
| Clone and install the source repository to use the included chat and benchmark |
| scripts: |
|
|
| ```bash |
| git clone https://github.com/ByteDance-Seed/Cola2.git |
| cd Cola2 |
| python -m pip install -e . |
| |
| export COLA2_MODEL_PATH=ByteDance-Seed/Cola2 |
| bash scripts/run_chat.sh |
| ``` |
|
|
| Use `/reset` to clear local chat history and `/quit` to exit. |
|
|
| ## Evaluation |
|
|
| The `eval_data/` directory contains normalized JSONL files for ARC-Easy, |
| HellaSwag, LAMBADA, MMLU, NarrativeQA, RACE, Story Cloze, and TruthfulQA. To |
| run the 200-example smoke benchmark from a source checkout: |
|
|
| ```bash |
| export COLA2_MODEL_PATH=ByteDance-Seed/Cola2 |
| export GENERATE_TASK_DATA_DIR=/path/to/downloaded/cola2/eval_data |
| bash scripts/run_benchmark_quick.sh --models cola2 |
| ``` |
|
|
| For the full benchmark grid and three-seed paper protocol, see the |
| [evaluation documentation](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/benchmark.md) |
| and |
| [reproduction protocol](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/reproduction.md). |
| The original paper seeds are not published, so small differences from the |
| reference results are expected. |
|
|
| ## Download and verify |
|
|
| ```bash |
| hf download ByteDance-Seed/Cola2 --local-dir /path/to/cola2 |
| cd /path/to/cola2 |
| sha256sum -c SHA256SUMS |
| ``` |
|
|
| ## Documentation |
|
|
| - [Paper overview](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/paper.md) |
| - [Architecture](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/architecture.md) |
| - [Inference](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/inference.md) |
| - [Configuration](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/configuration.md) |
| - [Model card](https://github.com/ByteDance-Seed/Cola2/blob/main/docs/model_card.md) |
| - [Security policy](https://github.com/ByteDance-Seed/Cola2/blob/main/SECURITY.md) |
|
|
| ## Citation |
|
|
| Please cite the [Cola2 arXiv paper](https://arxiv.org/abs/2610.31305). BibTeX |
| and machine-readable metadata are provided in |
| [`CITATION.md`](https://github.com/ByteDance-Seed/Cola2/blob/main/CITATION.md) |
| and |
| [`CITATION.cff`](https://github.com/ByteDance-Seed/Cola2/blob/main/CITATION.cff). |
|
|
| ## License |
|
|
| The repository code is licensed under the |
| [Apache License 2.0](https://github.com/ByteDance-Seed/Cola2/blob/main/LICENSE). |
| Model weights, tokenizer assets, benchmark datasets, and other third-party |
| materials remain subject to their respective terms. See |
| [`NOTICE`](https://github.com/ByteDance-Seed/Cola2/blob/main/NOTICE) for |
| attribution details. |
|
|


