

language:
  - en
tags:
  - multimodal
  - active-perception
  - embodied-ai
  - robotics
  - tactile
  - audio
  - force
  - qwen2.5-omni
pretty_name: ROMA
ROMA: LLM System for Real-World Object-Centric
Multi-Sensory Active Perception
I saw. I touched. I understood.


Ruoxuan Feng*, Yutong Chen*, Ruihua Song, Huan Yang, Zhongyuan Wang, Guocai Yao, Di Hu✉
*Equal contribution ✉Corresponding author
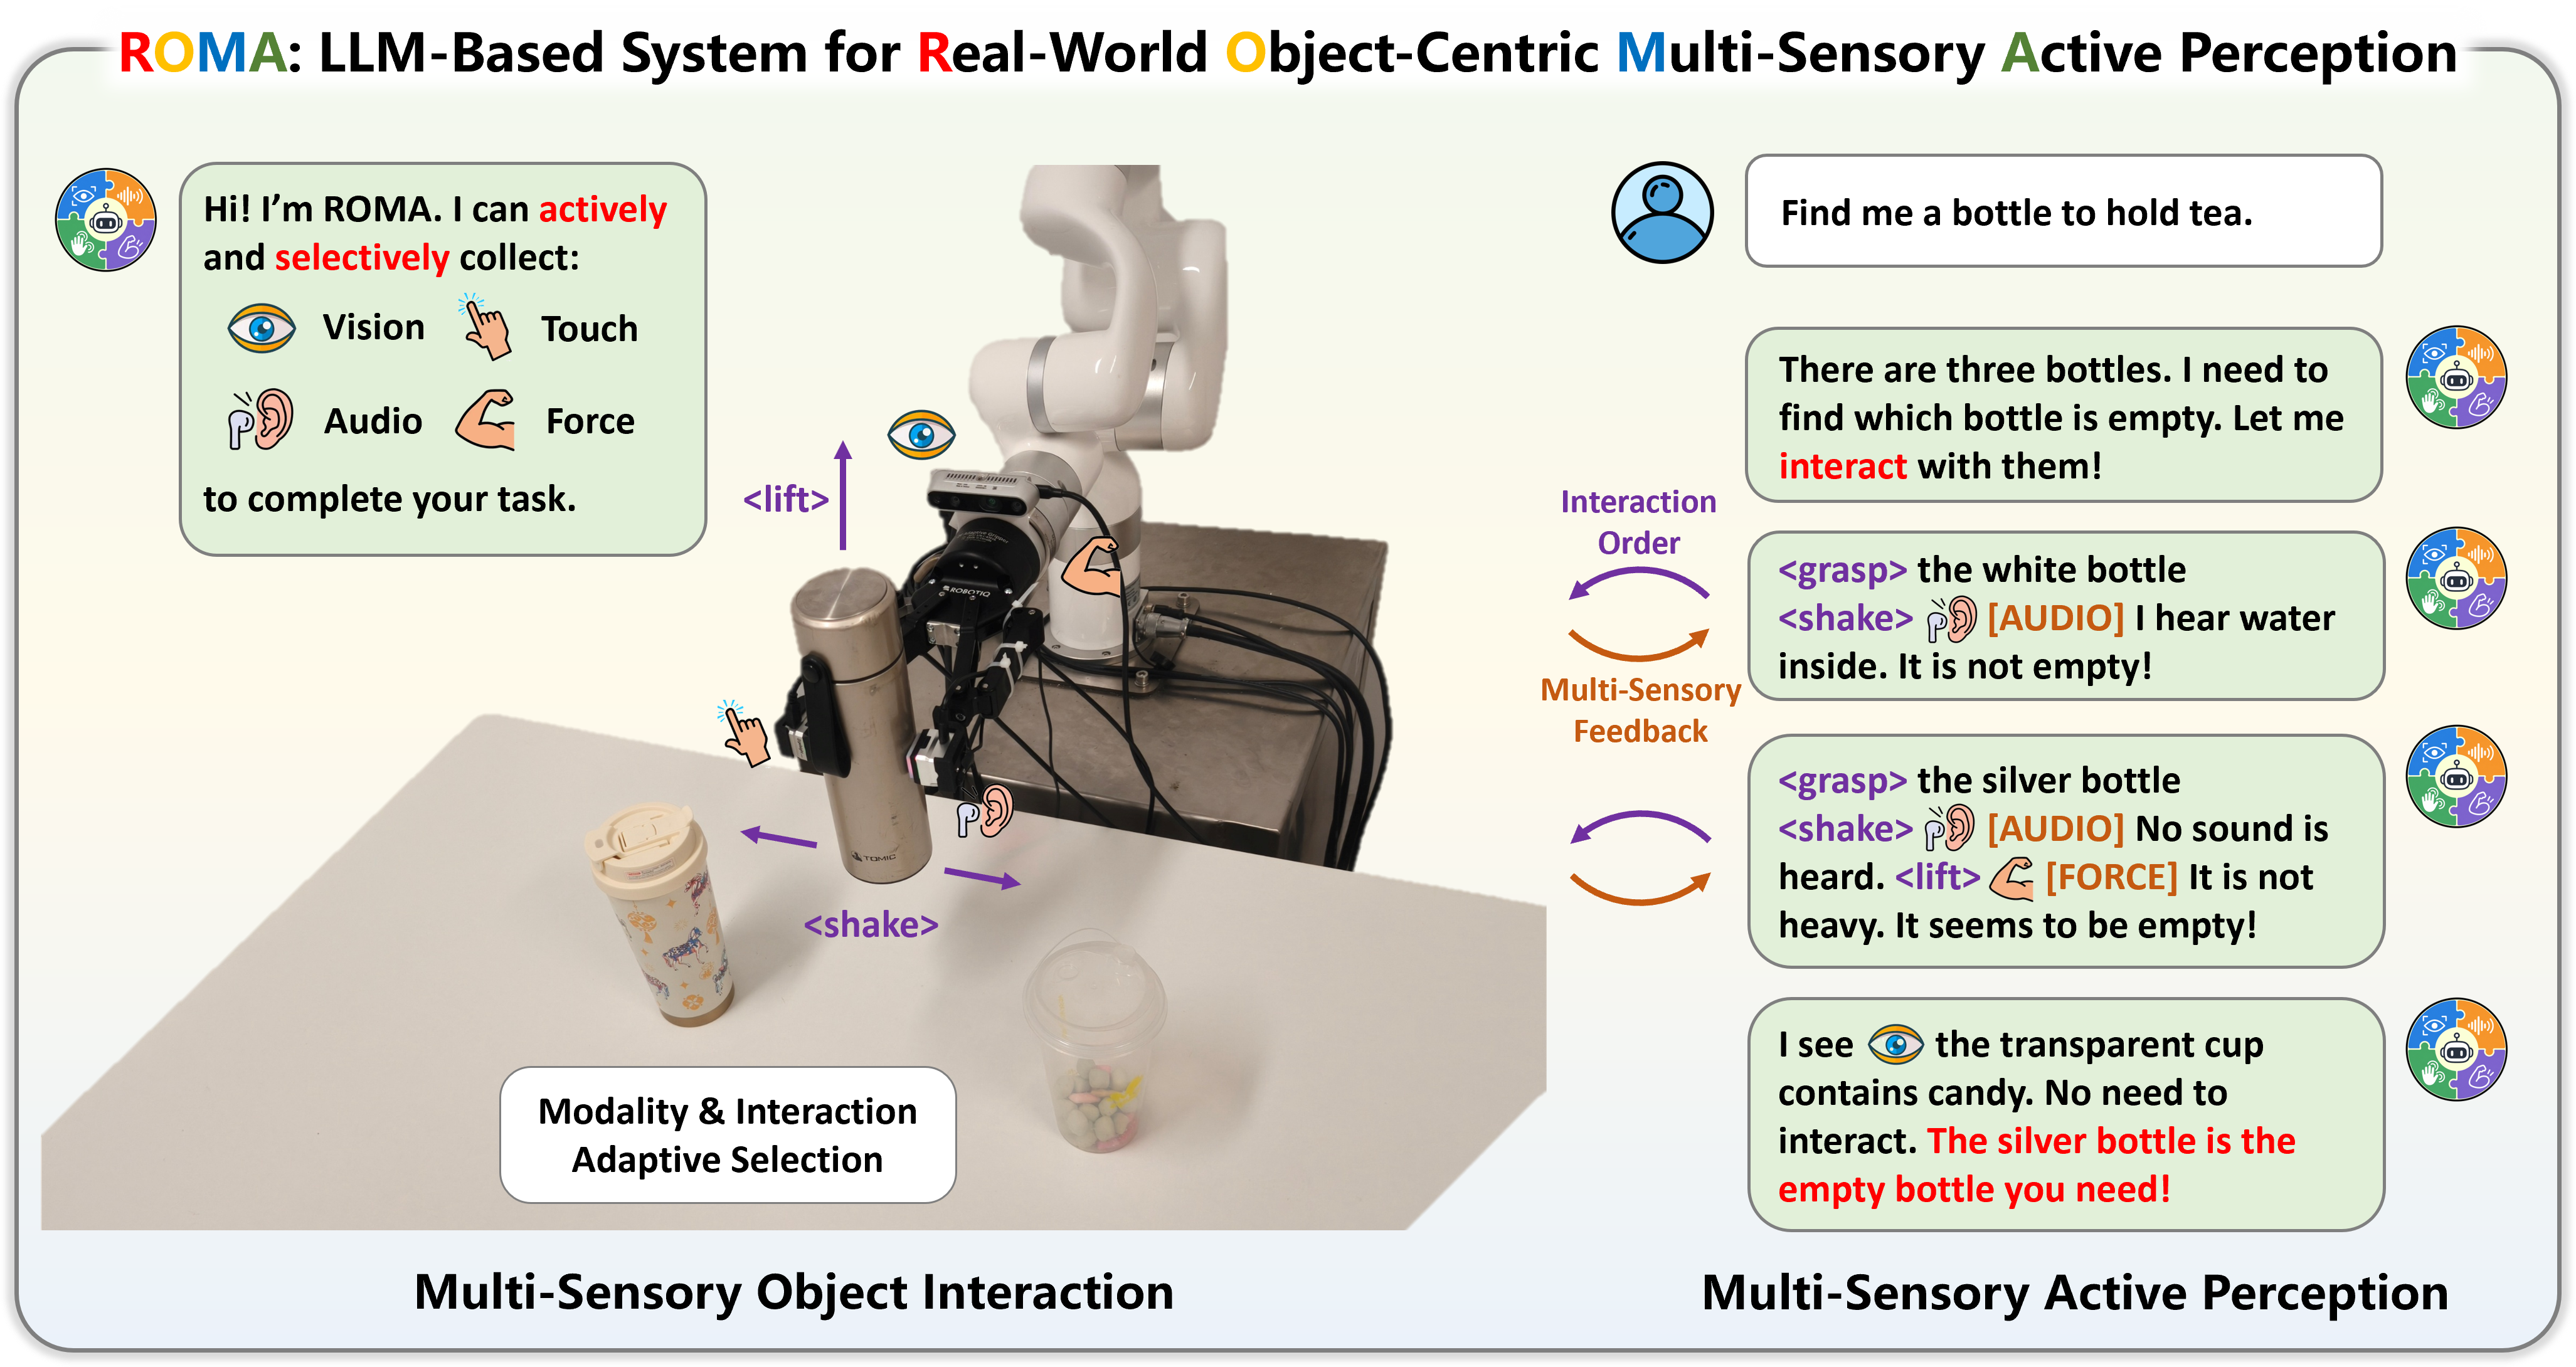
This repository hosts the checkpoint and dataset of ROMA, an LLM-based system for Real-World Object-Centric Multi-Sensory Active Perception. ROMA integrates vision, audio, touch, and force into a reasoning-interaction-feedback loop: the LLM identifies the missing evidence and selects the target object, the interaction (lift, press, collide, shake, rotate, squeeze), and the sensory modalities, while a physical interface executes the interaction and returns the multi-sensory feedback.
What's Inside
| Component | Description | Status |
|---|---|---|
| ROMA-7B checkpoint | Multi-sensory LLM built on Qwen2.5-Omni with action / modality tokens, an audio branch, and an AnyTouch 2 tactile branch, trained with multi-sensory alignment followed by active-perception SFT. | Available |
| ROMI-2K | Real-world multi-sensory object interaction dataset covering nearly 2,000 objects and 6 atomic interactions with synchronized visual, audio, tactile, and force feedback. | Coming soon |
| ROMA Bench | 2,100 scene-level tasks (single-chain, multi-chain, and intent-driven) for evaluating active perception. | Coming soon |
| Demo example scene | One recorded tabletop scene (example_data/1) used by the local web demo. |
Available |
Checkpoint
The ROMA-7B checkpoint directory (ROMA-Qwen2.5-Omni-7B) contains:
ROMA-Qwen2.5-Omni-7B/
├── xxx.safetensors      # base Qwen2.5-Omni-7B model
├── anytouch2.pth        # tactile encoder
├── audio.bin            # fine-tuned audio adapter and encoder
├── tactile.bin          # fine-tuned tactile adapter
└── ROMA-LLM.bin         # ROMA LLM weights
The weights are loaded in this order: base Qwen2.5-Omni, tactile encoder, new action / modality tokens, audio adapter, tactile adapter, ROMA LLM. The loading code is in demo.py of the GitHub repository.
Dataset
ROMI-2K and ROMA Bench are coming soon. They will contain:
- Handheld object collection: 1,657 object-content combinations, each interacted with at 3 grasp locations using 6 atomic interactions, with wrist and third-person views, audio, and tactile feedback.
- Tabletop scene collection (Training Set): 400 scenes recorded with a robotic arm, with visual, audio, tactile, and force feedback, object bounding boxes, and annotations.
- ROMA Bench: 2,100 scene-level active-perception tasks built from the held-out test scenes.
Usage
git clone https://github.com/GeWu-Lab/ROMA.git
cd ROMA
# see the GitHub README for environment setup

hf download GeWu-Lab/ROMA --repo-type dataset --local-dir resources
Citation
@article{feng2026roma,
  title   = {ROMA: LLM System for Real-World Object-Centric Multi-Sensory Active Perception},
  author  = {Feng, Ruoxuan and Chen, Yutong and Song, Ruihua and Yang, Huan and
             Wang, Zhongyuan and Yao, Guocai and Hu, Di},
  journal = {arXiv preprint arXiv:2610.06955},
  url     = {https://arxiv.org/abs/2610.06955},
  year    = {2026}
}