
html_url stringlengths 51 51 | title stringlengths 9 280 | comments stringlengths 63 24.7k | body stringlengths 51 58.6k | comments length int64 16 1.45k | text stringlengths 186 59.1k |
|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/5936 | Sequence of array not supported for most dtype | Here's something I can't explain:
When an array is encoded in the `from_dict` method, the numpy array is converted to a list (thus losing the original dtype, which is transfromed to the nearest builtin Python type)
https://github.com/huggingface/datasets/blob/6ee61e6e695b1df9f232d47faf3a5e2b30b33737/src/datasets/... | ### Describe the bug
Create a dataset composed of sequence of array fails for most dtypes (see code below).
### Steps to reproduce the bug
```python
from datasets import Sequence, Array2D, Features, Dataset
import numpy as np
for dtype in [
"bool", # ok
"int8", # failed
"int16", # failed
... | 132 | Sequence of array not supported for most dtype
### Describe the bug
Create a dataset composed of sequence of array fails for most dtypes (see code below).
### Steps to reproduce the bug
```python
from datasets import Sequence, Array2D, Features, Dataset
import numpy as np
for dtype in [
"bool", # ok
... |
https://github.com/huggingface/datasets/issues/5936 | Sequence of array not supported for most dtype | Arrow only support 1d numpy arrays, so we convert multidim arrays to lists of 1s arrays (and keep the dtype).
Though you noticed that it's concerting to lists and lose the dtype. If it's the case then it's a bug. | ### Describe the bug
Create a dataset composed of sequence of array fails for most dtypes (see code below).
### Steps to reproduce the bug
```python
from datasets import Sequence, Array2D, Features, Dataset
import numpy as np
for dtype in [
"bool", # ok
"int8", # failed
"int16", # failed
... | 40 | Sequence of array not supported for most dtype
### Describe the bug
Create a dataset composed of sequence of array fails for most dtypes (see code below).
### Steps to reproduce the bug
```python
from datasets import Sequence, Array2D, Features, Dataset
import numpy as np
for dtype in [
"bool", # ok
... |
https://github.com/huggingface/datasets/issues/5936 | Sequence of array not supported for most dtype | Ok the conversion to list shouldn't be there indeed ! Could you open a PR to remove it ? | ### Describe the bug
Create a dataset composed of sequence of array fails for most dtypes (see code below).
### Steps to reproduce the bug
```python
from datasets import Sequence, Array2D, Features, Dataset
import numpy as np
for dtype in [
"bool", # ok
"int8", # failed
"int16", # failed
... | 19 | Sequence of array not supported for most dtype
### Describe the bug
Create a dataset composed of sequence of array fails for most dtypes (see code below).
### Steps to reproduce the bug
```python
from datasets import Sequence, Array2D, Features, Dataset
import numpy as np
for dtype in [
"bool", # ok
... |
https://github.com/huggingface/datasets/issues/5286 | FileNotFoundError: Couldn't find file at https://dumps.wikimedia.org/enwiki/20220301/dumpstatus.json | I found a solution
If you specifically install datasets==1.18 and then run
import datasets
wiki = datasets.load_dataset('wikipedia', '20200501.en')
then this should work (it worked for me.) | ### Describe the bug
I follow the steps provided on the website [https://huggingface.co/datasets/wikipedia](https://huggingface.co/datasets/wikipedia)
$ pip install apache_beam mwparserfromhell
>>> from datasets import load_dataset
>>> load_dataset("wikipedia", "20220301.en")
however this results in the follo... | 26 | FileNotFoundError: Couldn't find file at https://dumps.wikimedia.org/enwiki/20220301/dumpstatus.json
### Describe the bug
I follow the steps provided on the website [https://huggingface.co/datasets/wikipedia](https://huggingface.co/datasets/wikipedia)
$ pip install apache_beam mwparserfromhell
>>> from datasets i... |
https://github.com/huggingface/datasets/issues/4681 | IndexError when loading ImageFolder | Hi, thanks for reporting! If there are no examples in ImageFolder, the `label` column is of type `ClassLabel(names=[])`, which leads to an error in [this line](https://github.com/huggingface/datasets/blob/c15b391942764152f6060b59921b09cacc5f22a6/src/datasets/arrow_writer.py#L387) as `asdict(info)` calls `Features({...,... | ## Describe the bug
Loading an image dataset with `imagefolder` throws `IndexError: list index out of range` when the given folder contains a non-image file (like a csv).
## Steps to reproduce the bug
Put a csv file in a folder with images and load it:
```python
import datasets
datasets.load_dataset("imagefold... | 114 | IndexError when loading ImageFolder
## Describe the bug
Loading an image dataset with `imagefolder` throws `IndexError: list index out of range` when the given folder contains a non-image file (like a csv).
## Steps to reproduce the bug
Put a csv file in a folder with images and load it:
```python
import dataset... |
https://github.com/huggingface/datasets/issues/4681 | IndexError when loading ImageFolder | Small pref for the first option, it feels weird to know that `Features()` can be called with a dictionary of types defined as dictionaries instead of type instances. | ## Describe the bug
Loading an image dataset with `imagefolder` throws `IndexError: list index out of range` when the given folder contains a non-image file (like a csv).
## Steps to reproduce the bug
Put a csv file in a folder with images and load it:
```python
import datasets
datasets.load_dataset("imagefold... | 28 | IndexError when loading ImageFolder
## Describe the bug
Loading an image dataset with `imagefolder` throws `IndexError: list index out of range` when the given folder contains a non-image file (like a csv).
## Steps to reproduce the bug
Put a csv file in a folder with images and load it:
```python
import dataset... |
https://github.com/huggingface/datasets/issues/7584 | Add LMDB format support | Hi ! Can you explain what's your use case ? Is it about converting LMDB to Dataset objects (i.e. converting to Arrow) ? | ### Feature request
Add LMDB format support for large memory-mapping files
### Motivation
Add LMDB format support for large memory-mapping files
### Your contribution
I'm trying to add it | 23 | Add LMDB format support
### Feature request
Add LMDB format support for large memory-mapping files
### Motivation
Add LMDB format support for large memory-mapping files
### Your contribution
I'm trying to add it
Hi ! Can you explain what's your use case ? Is it about converting LMDB to Dataset objects (i.e. conver... |
https://github.com/huggingface/datasets/issues/7470 | Is it possible to shard a single-sharded IterableDataset? | Hi ! Maybe you can look for an option in your dataset to partition your data based on a deterministic filter ? For example each worker could stream the data based on `row.id % num_shards` or something like that ? | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | 40 | Is it possible to shard a single-sharded IterableDataset?
I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a sing... |
https://github.com/huggingface/datasets/issues/7470 | Is it possible to shard a single-sharded IterableDataset? | So the recommendation is to start out with multiple shards initially and re-sharding after is not expected to work? :(
Would something like the following work? Some DiskCachingIterableDataset, where worker 0 streams from the datasource, but also writes to disk, and all of the other workers read from what worker 0 wrot... | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | 66 | Is it possible to shard a single-sharded IterableDataset?
I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a sing... |
https://github.com/huggingface/datasets/issues/7470 | Is it possible to shard a single-sharded IterableDataset? | To be honest it would be cool to support native multiprocessing in `IterableDataset.map` so you can parallelize any specific processing step without having to rely on a torch Dataloader. What do you think ?
related: https://github.com/huggingface/datasets/issues/7193 https://github.com/huggingface/datasets/issues/3444... | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | 117 | Is it possible to shard a single-sharded IterableDataset?
I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a sing... |
https://github.com/huggingface/datasets/issues/7470 | Is it possible to shard a single-sharded IterableDataset? | Ohh that would be pretty cool!
Thanks for the suggestions, as there's no actionable items for this repo I'm going to close this issue now. | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | 25 | Is it possible to shard a single-sharded IterableDataset?
I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a sing... |
https://github.com/huggingface/datasets/issues/7470 | Is it possible to shard a single-sharded IterableDataset? | Another usecase for this resharding:
If we have a bunch of jsonl files, and we load it as an IterableDataset with multiple dataloader workers, each file gets naively assigned to a worker.
If the files were not carefully produced to be equally sized, eg if the very last file is significantly shorter, containing just a... | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | 98 | Is it possible to shard a single-sharded IterableDataset?
I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a sing... |
https://github.com/huggingface/datasets/issues/7470 | Is it possible to shard a single-sharded IterableDataset? | > Another usecase for this resharding:
>
> If we have a bunch of jsonl files, and we load it as an IterableDataset with multiple dataloader workers, each file gets naively assigned to a worker.
>
> If the files were not carefully produced to be equally sized, eg if the very last file is significantly shorter, contain... | I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a single thread (not to mention running multiple times incurs mo... | 135 | Is it possible to shard a single-sharded IterableDataset?
I thought https://github.com/huggingface/datasets/pull/7252 might be applicable but looking at it maybe not.
Say we have a process, eg. a database query, that can return data in slightly different order each time. So, the initial query needs to be run by a sing... |
https://github.com/huggingface/datasets/issues/7053 | Datasets.datafiles resolve_pattern `TypeError: can only concatenate tuple (not "str") to tuple` | Hi,
This issue was fixed in `datasets` 2.15.0:
- #6105
You will need to update your `datasets`:
```
pip install -U datasets
``` | ### Describe the bug
in data_files.py, line 332,
`fs, _, _ = get_fs_token_paths(pattern, storage_options=storage_options)`
If we run the code on AWS, as fs.protocol will be a tuple like: `('file', 'local')`
So, `isinstance(fs.protocol, str) == False` and
`protocol_prefix = fs.protocol + "://" if fs.protocol != ... | 23 | Datasets.datafiles resolve_pattern `TypeError: can only concatenate tuple (not "str") to tuple`
### Describe the bug
in data_files.py, line 332,
`fs, _, _ = get_fs_token_paths(pattern, storage_options=storage_options)`
If we run the code on AWS, as fs.protocol will be a tuple like: `('file', 'local')`
So, `isins... |
https://github.com/huggingface/datasets/issues/4143 | Unable to download `Wikepedia` 20220301.en version | Hi! We've recently updated the Wikipedia script, so these changes are only available on master and can be fetched as follows:
```python
dataset_wikipedia = load_dataset("wikipedia", "20220301.en", revision="master")
``` | ## Describe the bug
Unable to download `Wikepedia` dataset, 20220301.en version
## Steps to reproduce the bug
```python
!pip install apache_beam mwparserfromhell
dataset_wikipedia = load_dataset("wikipedia", "20220301.en")
```
## Actual results
```
ValueError: BuilderConfig 20220301.en not found.
Avail... | 28 | Unable to download `Wikepedia` 20220301.en version
## Describe the bug
Unable to download `Wikepedia` dataset, 20220301.en version
## Steps to reproduce the bug
```python
!pip install apache_beam mwparserfromhell
dataset_wikipedia = load_dataset("wikipedia", "20220301.en")
```
## Actual results
```
Value... |
https://github.com/huggingface/datasets/issues/4143 | Unable to download `Wikepedia` 20220301.en version | Hi, how can I load the previous "20200501.en" version of wikipedia which had been downloaded to the default path? Thanks! | ## Describe the bug
Unable to download `Wikepedia` dataset, 20220301.en version
## Steps to reproduce the bug
```python
!pip install apache_beam mwparserfromhell
dataset_wikipedia = load_dataset("wikipedia", "20220301.en")
```
## Actual results
```
ValueError: BuilderConfig 20220301.en not found.
Avail... | 20 | Unable to download `Wikepedia` 20220301.en version
## Describe the bug
Unable to download `Wikepedia` dataset, 20220301.en version
## Steps to reproduce the bug
```python
!pip install apache_beam mwparserfromhell
dataset_wikipedia = load_dataset("wikipedia", "20220301.en")
```
## Actual results
```
Value... |
https://github.com/huggingface/datasets/issues/5230 | dataclasses error when importing the library in python 3.11 | I opened [this issue](https://github.com/python/cpython/issues/99401).
Python's maintainers say that the issue is caused by [this change](https://docs.python.org/3.11/whatsnew/3.11.html#dataclasses).
I believe adding a `__hash__` method to `datasets.utils.version.Version` should solve (at least partially) this issue. | ### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I tried to import the library using the following jupyter note... | 30 | dataclasses error when importing the library in python 3.11
### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I ... |
https://github.com/huggingface/datasets/issues/5230 | dataclasses error when importing the library in python 3.11 | Has this been fixed? I am running into this issue now.
If this has been fixed, could have a new release with this?
| ### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I tried to import the library using the following jupyter note... | 23 | dataclasses error when importing the library in python 3.11
### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I ... |
https://github.com/huggingface/datasets/issues/5230 | dataclasses error when importing the library in python 3.11 | Hi, I am getting error while training
(tensorflow) C:\tensorflow\models\research\object_detection>python train.py --logtostderr --train_dir=training/ --pipeline_config_path=training/faster_rcnn_inception_v2_pets.config
Traceback (most recent call last):
File "C:\tensorflow\models\research\object_detection\train... | ### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I tried to import the library using the following jupyter note... | 126 | dataclasses error when importing the library in python 3.11
### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I ... |
https://github.com/huggingface/datasets/issues/5230 | dataclasses error when importing the library in python 3.11 | @Jayanth1812 and anyone else receiving a similar issue, it most likely has to do with your Python version. Downgrading to Python 3.9 works for me, but doing a downgrade might impact a lot of things. So to be safe and what worked for me was creating a new conda environment and following the installations here: https://t... | ### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I tried to import the library using the following jupyter note... | 76 | dataclasses error when importing the library in python 3.11
### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I ... |
https://github.com/huggingface/datasets/issues/5230 | dataclasses error when importing the library in python 3.11 | @Jayanth1812, you can see in your error stack trace, that the error is caused by the `tensorflow` library, not by the `datasets` library. See:
```
File "C:\Users\x0133252\AppData\Local\anaconda3\envs\tensorflow\Lib\dataclasses.py"
```
You should open an issue in their repository instead: https://github.com/tensor... | ### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I tried to import the library using the following jupyter note... | 38 | dataclasses error when importing the library in python 3.11
### Describe the bug
When I import datasets using python 3.11 the dataclasses standard library raises the following error:
`ValueError: mutable default <class 'datasets.utils.version.Version'> for field version is not allowed: use default_factory`
When I ... |
https://github.com/huggingface/datasets/issues/5781 | Error using `load_datasets` | It looks like an issue with your installation of scipy, can you try reinstalling it ? | ### Describe the bug
I tried to load a dataset using the `datasets` library in a conda jupyter notebook and got the below error.
```
ImportError: dlopen(/Users/gilbertyoung/miniforge3/envs/review_sense/lib/python3.8/site-packages/scipy/sparse/linalg/_isolve/_iterative.cpython-38-darwin.so, 0x0002): Library not ... | 16 | Error using `load_datasets`
### Describe the bug
I tried to load a dataset using the `datasets` library in a conda jupyter notebook and got the below error.
```
ImportError: dlopen(/Users/gilbertyoung/miniforge3/envs/review_sense/lib/python3.8/site-packages/scipy/sparse/linalg/_isolve/_iterative.cpython-38-darw... |
https://github.com/huggingface/datasets/issues/6833 | Super slow iteration with trivial custom transform | Similar issue in text process
```python
tokenizer=AutoTokenizer.from_pretrained(model_dir[args.model])
train_dataset=datasets.load_from_disk(dataset_dir[args.dataset],keep_in_memory=True)['train']
train_dataset=train_dataset.map(partial(dname2func[args.dataset],tokenizer=tokenizer),batched=True,num_proc =50,re... | ### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 800), dtype="uint8")})
ds1 = Dataset.from_dict({"... | 50 | Super slow iteration with trivial custom transform
### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 8... |
https://github.com/huggingface/datasets/issues/6833 | Super slow iteration with trivial custom transform | The transform currently replaces the numpy formatting.
So you're back to copying data to long python lists which is super slow.
It would be cool for the transform to not remove the formatting in this case, but this requires a few changes in the lib | ### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 800), dtype="uint8")})
ds1 = Dataset.from_dict({"... | 45 | Super slow iteration with trivial custom transform
### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 8... |
https://github.com/huggingface/datasets/issues/6833 | Super slow iteration with trivial custom transform | This also (somewhat surprisingly) affects iterable datasets, making map very challenging to use for data with large arrays, unless there is some workaround? | ### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 800), dtype="uint8")})
ds1 = Dataset.from_dict({"... | 23 | Super slow iteration with trivial custom transform
### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 8... |
https://github.com/huggingface/datasets/issues/6833 | Super slow iteration with trivial custom transform | For iterable datasets you should be able to do this without slow downs
```python
ds = ds.with_format("arrow").map(...)
```
I haven't tried with "numpy" though, maybe there is a step that does Arrow -> List -> NumPy instead of Arrow -> NumPy directly. If it's the case it would be cool to avoid that | ### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 800), dtype="uint8")})
ds1 = Dataset.from_dict({"... | 53 | Super slow iteration with trivial custom transform
### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 8... |
https://github.com/huggingface/datasets/issues/6833 | Super slow iteration with trivial custom transform | Thanks! this works for me
However, it raises an error if batched=False and map batch_size isn't explicitly set to 1 due to map's default batch_size affecting the batch size of the RebatchedArrowExamplesIterable - is this a bug? | ### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 800), dtype="uint8")})
ds1 = Dataset.from_dict({"... | 37 | Super slow iteration with trivial custom transform
### Describe the bug
Dataset is 10X slower when applying trivial transforms:
```
import time
import numpy as np
from datasets import Dataset, Features, Array2D
a = np.zeros((800, 800))
a = np.stack([a] * 1000)
features = Features({"a": Array2D(shape=(800, 8... |
https://github.com/huggingface/datasets/issues/7503 | Inconsistency between load_dataset and load_from_disk functionality | Hi ! you can find more info here: https://github.com/huggingface/datasets/issues/5044#issuecomment-1263714347
> What's the recommended approach for this use case? Should I manually process my gsm8k-new dataset to make it compatible with load_dataset? Is there a standard way to convert between these formats?
You can u... | ## Issue Description
I've encountered confusion when using `load_dataset` and `load_from_disk` in the datasets library. Specifically, when working offline with the gsm8k dataset, I can load it using a local path:
```python
import datasets
ds = datasets.load_dataset('/root/xxx/datasets/gsm8k', 'main')
```
output:
```t... | 49 | Inconsistency between load_dataset and load_from_disk functionality
## Issue Description
I've encountered confusion when using `load_dataset` and `load_from_disk` in the datasets library. Specifically, when working offline with the gsm8k dataset, I can load it using a local path:
```python
import datasets
ds = datase... |
https://github.com/huggingface/datasets/issues/7503 | Inconsistency between load_dataset and load_from_disk functionality | Hi @zzzzzec & @lhoestq 👋
Thanks for raising and discussing this — I've submitted a patch that improves this exact scenario. | ## Issue Description
I've encountered confusion when using `load_dataset` and `load_from_disk` in the datasets library. Specifically, when working offline with the gsm8k dataset, I can load it using a local path:
```python
import datasets
ds = datasets.load_dataset('/root/xxx/datasets/gsm8k', 'main')
```
output:
```t... | 21 | Inconsistency between load_dataset and load_from_disk functionality
## Issue Description
I've encountered confusion when using `load_dataset` and `load_from_disk` in the datasets library. Specifically, when working offline with the gsm8k dataset, I can load it using a local path:
```python
import datasets
ds = datase... |
https://github.com/huggingface/datasets/issues/7928 | `load_dataset` `revision` param not respected when fetching from cache | This might be better placed as a feature request not a bug, since the logging `Using the latest cached version of the dataset since sentientfutures/ahb couldn't be found on the Hugging Face Hub` is clear. | ### Describe the bug
`datasets.load_dataset` `revision` semantics are a bit inconsistent when the dataset is not found on the huggingface hub. When fetching the latest cached version of the dataset, the `revision` argument is ignored, so long as any cached versions of the dataset already exist in the HF cache.
### St... | 35 | `load_dataset` `revision` param not respected when fetching from cache
### Describe the bug
`datasets.load_dataset` `revision` semantics are a bit inconsistent when the dataset is not found on the huggingface hub. When fetching the latest cached version of the dataset, the `revision` argument is ignored, so long as an... |
https://github.com/huggingface/datasets/issues/7928 | `load_dataset` `revision` param not respected when fetching from cache | https://github.com/huggingface/datasets/pull/7929 This only solves the case of invalid revisions. Fetching a specific revision from the cache would be more work but I think this is a good start and solves issues like https://github.com/UKGovernmentBEIS/inspect_evals/pull/834#issuecomment-3704689637 | ### Describe the bug
`datasets.load_dataset` `revision` semantics are a bit inconsistent when the dataset is not found on the huggingface hub. When fetching the latest cached version of the dataset, the `revision` argument is ignored, so long as any cached versions of the dataset already exist in the HF cache.
### St... | 33 | `load_dataset` `revision` param not respected when fetching from cache
### Describe the bug
`datasets.load_dataset` `revision` semantics are a bit inconsistent when the dataset is not found on the huggingface hub. When fetching the latest cached version of the dataset, the `revision` argument is ignored, so long as an... |
https://github.com/huggingface/datasets/issues/5276 | Bug in downloading common_voice data and snall chunk of it to one's own hub | Sounds like one of the file is not a valid one, can you make sure you uploaded valid mp3 files ? | ### Describe the bug
I'm trying to load the common voice dataset. Currently there is no implementation to download just par tof the data, and I need just one part of it, without downloading the entire dataset
Help please?

| ### Describe the bug
I'm trying to load the common voice dataset. Currently there is no implementation to download just par tof the data, and I need just one part of it, without downloading the entire dataset
Help please?
.cpu().numpy()` becomes `for x in obj.detach().to(torch.float).cpu().numpy()`
I got the idea from [this ](https://github.com/kohya-ss/sd-webui-additional-networks/pull/128/files) PR where someone was facing a sim... | ### Describe the bug
```
Traceback (most recent call last):
File "train_controlnet_sdxl.py", line 1252, in <module>
main(args)
File "train_controlnet_sdxl.py", line 1013, in main
train_dataset = train_dataset.map(compute_embeddings_fn, batched=True, new_fingerprint=new_fingerprint)
File "/home/mini... | 51 | I train controlnet_sdxl in bf16 datatype, got unsupported ERROR in datasets
### Describe the bug
```
Traceback (most recent call last):
File "train_controlnet_sdxl.py", line 1252, in <module>
main(args)
File "train_controlnet_sdxl.py", line 1013, in main
train_dataset = train_dataset.map(compute_embed... |
https://github.com/huggingface/datasets/issues/4101 | How can I download only the train and test split for full numbers using load_dataset()? | Hi! Can you please specify the full name of the dataset? IIRC `full_numbers` is one of the configs of the `svhn` dataset, and its generation is slow due to data being stored in binary Matlab files. Even if you specify a specific split, `datasets` downloads all of them, but we plan to fix that soon and only download the... | How can I download only the train and test split for full numbers using load_dataset()?
I do not need the extra split and it will take 40 mins just to download in Colab. I have very short time in hand. Please help. | 121 | How can I download only the train and test split for full numbers using load_dataset()?
How can I download only the train and test split for full numbers using load_dataset()?
I do not need the extra split and it will take 40 mins just to download in Colab. I have very short time in hand. Please help.
Hi! Can you ... |
https://github.com/huggingface/datasets/issues/8201 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training. | Hi @aihao2000 ! I was looking into this multi-machine training scenario and just opened a PR (#8203 ) that safely skips feature inference for empty shards during distributed streaming.
please! Check it out and see if it looks like it will resolve the weird bugs you were hitting! | ### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webdataset", data_files=args.train_dataset, split="train", streaming=True,cache_dir='/dev/shm/.cache'
)
args.train... | 48 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training.
### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webd... |
https://github.com/huggingface/datasets/issues/8201 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training. | it looks like there less dataset files (=shards) than ranks. We should improve the error message in that case and suggest to either disable streaming or to run fewer nodes. @aihao2000 are you using `split_dataset_by_node()` or `.shard()` to distributed the dataset among the training nodes ?
Thanks @Wolfram-St for taki... | ### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webdataset", data_files=args.train_dataset, split="train", streaming=True,cache_dir='/dev/shm/.cache'
)
args.train... | 175 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training.
### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webd... |
https://github.com/huggingface/datasets/issues/8201 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training. | @lhoestq I use ```shard``` after ```load_dataset```. Does the number of `.tar` files *have* to be greater than `num_processes`? The number of my target files should also be significantly greater than the number of training processes; furthermore, to the best of my understanding, the `load_dataset` function should not b... | ### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webdataset", data_files=args.train_dataset, split="train", streaming=True,cache_dir='/dev/shm/.cache'
)
args.train... | 115 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training.
### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webd... |
https://github.com/huggingface/datasets/issues/8201 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training. | Can you check the value of `ds.num_shards` ? Or share the code you are using ?
> Does the number of .tar files have to be greater than num_processes?
Yes, this way you can use .shard() and each node has at least one shard to stream from. Otherwise you can use split_dataset_by_node() but if there aren't enough shards,... | ### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webdataset", data_files=args.train_dataset, split="train", streaming=True,cache_dir='/dev/shm/.cache'
)
args.train... | 182 | Encountered an error when loading data in WebDataset format using `load_datasets` during multi-matchines training.
### Describe the bug
Single-machine training works fine, but multi-machine training throws up all sorts of weird bugs. Help me!
### Steps to reproduce the bug
train_dataset = load_dataset(
"webd... |
https://github.com/huggingface/datasets/issues/8159 | tests/conftest.py, tests/_test_patching.py, tests/fixtures/fsspec.py and other files are missing from the PYPI distribution | Hey, ran into something similar a while back when we were packaging a custom dataset loader for a client at v4.7.x. Turns out, PyPI distributions sometimes skip test files and fixtures like `conftest.py` since they're not critical for runtime—honestly, it's a packaging config thing in `setup.py` or `pyproject.toml`. We... | ### Describe the bug
Version: 4.8.5
### Steps to reproduce the bug
n/a
### Expected behavior
n/a
### Environment info
n/a | 76 | tests/conftest.py, tests/_test_patching.py, tests/fixtures/fsspec.py and other files are missing from the PYPI distribution
### Describe the bug
Version: 4.8.5
### Steps to reproduce the bug
n/a
### Expected behavior
n/a
### Environment info
n/a
Hey, ran into something similar a while back when we were packagin... |
https://github.com/huggingface/datasets/issues/6663 | `write_examples_on_file` and `write_batch` are broken in `ArrowWriter` | Thanks for reporting! I've left some comments on the PR on how to fix this recent change rather than reverting it. | ### Describe the bug
`write_examples_on_file` and `write_batch` are broken in `ArrowWriter` since #6636. The order between the columns and the schema is not preserved anymore. So these functions don't work anymore unless the order happens to align well.
### Steps to reproduce the bug
Try to do `write_batch` with any... | 21 | `write_examples_on_file` and `write_batch` are broken in `ArrowWriter`
### Describe the bug
`write_examples_on_file` and `write_batch` are broken in `ArrowWriter` since #6636. The order between the columns and the schema is not preserved anymore. So these functions don't work anymore unless the order happens to align ... |
https://github.com/huggingface/datasets/issues/6663 | `write_examples_on_file` and `write_batch` are broken in `ArrowWriter` | > Thanks for reporting! I've left some comments on the PR on how to fix this recent change rather than reverting it.
I feel that'd be good, but it'd be great to release a hotfix ASAP (a revert is a fast thing to do) so people can continue using this library and then focus on still applying the improvement. | ### Describe the bug
`write_examples_on_file` and `write_batch` are broken in `ArrowWriter` since #6636. The order between the columns and the schema is not preserved anymore. So these functions don't work anymore unless the order happens to align well.
### Steps to reproduce the bug
Try to do `write_batch` with any... | 59 | `write_examples_on_file` and `write_batch` are broken in `ArrowWriter`
### Describe the bug
`write_examples_on_file` and `write_batch` are broken in `ArrowWriter` since #6636. The order between the columns and the schema is not preserved anymore. So these functions don't work anymore unless the order happens to align ... |
https://github.com/huggingface/datasets/issues/7067 | Convert_to_parquet fails for datasets with multiple configs | I have opened an issue in the huggingface-hub repo:
- https://github.com/huggingface/huggingface_hub/issues/2419
I am opening a PR to avoid calling `create_branch` if the branch already exists. | If the dataset has multiple configs, when using the `datasets-cli convert_to_parquet` command to avoid issues with the data viewer caused by loading scripts, the conversion process only successfully converts the data corresponding to the first config. When it starts converting the second config, it throws an error:
... | 25 | Convert_to_parquet fails for datasets with multiple configs
If the dataset has multiple configs, when using the `datasets-cli convert_to_parquet` command to avoid issues with the data viewer caused by loading scripts, the conversion process only successfully converts the data corresponding to the first config. When it ... |
https://github.com/huggingface/datasets/issues/3543 | Allow loading community metrics from the hub, just like datasets | Hi ! Thanks for your message :) This is a great idea indeed. We haven't started working on this yet though. For now I guess you can host your metric on the Hub (either with your model or your dataset) and use `hf_hub_download` to download it (docs [here](https://github.com/huggingface/huggingface_hub/blob/main/docs/hub... | **Is your feature request related to a problem? Please describe.**
Currently, I can load a metric implemented by me by providing the local path to the file in `load_metric`.
However, there is no option to do it with the metric uploaded to the hub.
This means that if I want to allow other users to use it, they must d... | 48 | Allow loading community metrics from the hub, just like datasets
**Is your feature request related to a problem? Please describe.**
Currently, I can load a metric implemented by me by providing the local path to the file in `load_metric`.
However, there is no option to do it with the metric uploaded to the hub.
This... |
https://github.com/huggingface/datasets/issues/3543 | Allow loading community metrics from the hub, just like datasets | Here's the code I used, in case it can be of help to someone else:
```python
import os, shutil
from huggingface_hub import hf_hub_download
def download_metric(repo_id, file_path):
# repo_id: for models "username/model_name", for datasets "datasets/username/model_name"
local_metric_path = hf_hub_download(r... | **Is your feature request related to a problem? Please describe.**
Currently, I can load a metric implemented by me by providing the local path to the file in `load_metric`.
However, there is no option to do it with the metric uploaded to the hub.
This means that if I want to allow other users to use it, they must d... | 55 | Allow loading community metrics from the hub, just like datasets
**Is your feature request related to a problem? Please describe.**
Currently, I can load a metric implemented by me by providing the local path to the file in `load_metric`.
However, there is no option to do it with the metric uploaded to the hub.
This... |
https://github.com/huggingface/datasets/issues/5224 | Seems to freeze when loading audio dataset with wav files from local folder | I just tried to do the same but changing the `.wav` files to `.mp3` files and that doesn't fix it. | ### Describe the bug
I'm following the instructions in [https://huggingface.co/docs/datasets/audio_load#audiofolder-with-metadata](url) to be able to load a dataset from a local folder.
I have everything into a folder, into a train folder and then the audios and csv. When I try to load the dataset and run from term... | 20 | Seems to freeze when loading audio dataset with wav files from local folder
### Describe the bug
I'm following the instructions in [https://huggingface.co/docs/datasets/audio_load#audiofolder-with-metadata](url) to be able to load a dataset from a local folder.
I have everything into a folder, into a train folder a... |
https://github.com/huggingface/datasets/issues/5224 | Seems to freeze when loading audio dataset with wav files from local folder | I don't know if anyone will ever read this but I've tried to upload the same dataset with google colab and the output seems more clarifying. I didn't specify the train/test split so the dataset wasn't fully uploaded (or that is what I understood, might be wrong!!).
Now, including the `drop_metadata` flag I can load ... | ### Describe the bug
I'm following the instructions in [https://huggingface.co/docs/datasets/audio_load#audiofolder-with-metadata](url) to be able to load a dataset from a local folder.
I have everything into a folder, into a train folder and then the audios and csv. When I try to load the dataset and run from term... | 79 | Seems to freeze when loading audio dataset with wav files from local folder
### Describe the bug
I'm following the instructions in [https://huggingface.co/docs/datasets/audio_load#audiofolder-with-metadata](url) to be able to load a dataset from a local folder.
I have everything into a folder, into a train folder a... |
https://github.com/huggingface/datasets/issues/5224 | Seems to freeze when loading audio dataset with wav files from local folder | Yes but it didn't matter. I don't remember which of them I ended up working with. | ### Describe the bug
I'm following the instructions in [https://huggingface.co/docs/datasets/audio_load#audiofolder-with-metadata](url) to be able to load a dataset from a local folder.
I have everything into a folder, into a train folder and then the audios and csv. When I try to load the dataset and run from term... | 16 | Seems to freeze when loading audio dataset with wav files from local folder
### Describe the bug
I'm following the instructions in [https://huggingface.co/docs/datasets/audio_load#audiofolder-with-metadata](url) to be able to load a dataset from a local folder.
I have everything into a folder, into a train folder a... |
https://github.com/huggingface/datasets/issues/4862 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code | Hi hi, instead of using `download_and_extract` function, I only use `download` function: `base_dir = Path(dl_manager.download(urls))`. It turns out that the code works for `datasets==2.2.2`, however, it doesn't work with `datasets==2.4.0`. | ## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import Path
from typing import Dict, List, Tuple
import datasets
import pandas as pd
_CITATION = """\
"""... | 30 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code
## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import... |
https://github.com/huggingface/datasets/issues/4862 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code | Hi @yana-xuyan, thanks for reporting.
Indeed you already found the answer: an Excel file should be just downloaded and not downloaded-and-extracted.
The reason why is that if you call also extract, our library will try to infer the compression format (and extract it). And Excel files are viewed as ZIP files and e... | ## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import Path
from typing import Dict, List, Tuple
import datasets
import pandas as pd
_CITATION = """\
"""... | 96 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code
## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import... |
https://github.com/huggingface/datasets/issues/4862 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code | Hi @albertvillanova, thank you for your reply! Do you have any clue on why the same error still exists with `datasets==2.4.0` even after I don't extract the downloaded file? FYI, if I downgrade to `datasets==2.2.2`, the code works fine. | ## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import Path
from typing import Dict, List, Tuple
import datasets
import pandas as pd
_CITATION = """\
"""... | 39 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code
## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import... |
https://github.com/huggingface/datasets/issues/4862 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code | I guess this has to do with the cache: you should remove the previously-wrongly generated directory from the cache; otherwise `datasets` tries to re-use it. | ## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import Path
from typing import Dict, List, Tuple
import datasets
import pandas as pd
_CITATION = """\
"""... | 25 | Got "AttributeError: 'xPath' object has no attribute 'read'" when loading an excel dataset with my own code
## Describe the bug
A clear and concise description of what the bug is.
## Steps to reproduce the bug
```python
# Sample code to reproduce the bug
# The dataset function is as follows:
from pathlib import... |
https://github.com/huggingface/datasets/issues/5514 | Improve inconsistency of `Dataset.map` interface for `load_from_cache_file` | Hi, thanks for noticing this! We can't just remove the cache control as this allows us to control where the arrow files generated by the ops are written (cached on disk if enabled or a temporary directory if disabled). The right way to address this inconsistency would be by having `load_from_cache_file=None` by default... | ### Feature request
1. Replace the `load_from_cache_file` default value to `True`.
2. Remove or alter checks from `is_caching_enabled` logic.
### Motivation
I stumbled over an inconsistency in the `Dataset.map` interface. The documentation (and source) states for the parameter `load_from_cache_file`:
```
load_... | 54 | Improve inconsistency of `Dataset.map` interface for `load_from_cache_file`
### Feature request
1. Replace the `load_from_cache_file` default value to `True`.
2. Remove or alter checks from `is_caching_enabled` logic.
### Motivation
I stumbled over an inconsistency in the `Dataset.map` interface. The documentati... |
https://github.com/huggingface/datasets/issues/5514 | Improve inconsistency of `Dataset.map` interface for `load_from_cache_file` | Hi! Yes, this seems more plausible. I can implement that. One last thing is the type annotation `load_from_cache_file: bool = None`. Which I then would change to `load_from_cache_file: Optional[bool] = None`. | ### Feature request
1. Replace the `load_from_cache_file` default value to `True`.
2. Remove or alter checks from `is_caching_enabled` logic.
### Motivation
I stumbled over an inconsistency in the `Dataset.map` interface. The documentation (and source) states for the parameter `load_from_cache_file`:
```
load_... | 31 | Improve inconsistency of `Dataset.map` interface for `load_from_cache_file`
### Feature request
1. Replace the `load_from_cache_file` default value to `True`.
2. Remove or alter checks from `is_caching_enabled` logic.
### Motivation
I stumbled over an inconsistency in the `Dataset.map` interface. The documentati... |
https://github.com/huggingface/datasets/issues/7049 | Save nparray as list | In addition, when I use `set_format ` and index the ds, the following error occurs:
the code
```python
ds.set_format(type="np", colums="pixel_values")
```
error
<img width="918" alt="image" src="https://github.com/user-attachments/assets/b28bbff2-20ea-4d28-ab62-b4ed2d944996">
| ### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_image_to_features(inst, ... | 26 | Save nparray as list
### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_ima... |
https://github.com/huggingface/datasets/issues/7049 | Save nparray as list | > Some people use the set_format function to convert the column back, but doesn't this lose precision?
Under the hood the data is saved in Arrow format using the same precision as your numpy arrays?
By default the Arrow data is read as python lists, but you can indeed read them back as numpy arrays with the same p... | ### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_image_to_features(inst, ... | 59 | Save nparray as list
### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_ima... |
https://github.com/huggingface/datasets/issues/7049 | Save nparray as list | > (you can fix your second issue by fixing the typo `colums` -> `columns`)
You are right, I was careless. Thank you. | ### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_image_to_features(inst, ... | 22 | Save nparray as list
### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_ima... |
https://github.com/huggingface/datasets/issues/7049 | Save nparray as list | > > Some people use the set_format function to convert the column back, but doesn't this lose precision?
>
> Under the hood the data is saved in Arrow format using the same precision as your numpy arrays? By default the Arrow data is read as python lists, but you can indeed read them back as numpy arrays with the sa... | ### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_image_to_features(inst, ... | 79 | Save nparray as list
### Describe the bug
When I use the `map` function to convert images into features, datasets saves nparray as a list. Some people use the `set_format` function to convert the column back, but doesn't this lose precision?
### Steps to reproduce the bug
the map function
```python
def convert_ima... |
https://github.com/huggingface/datasets/issues/8197 | Feature Request / Discussion: Skip origin_metadata fetch when streaming=True? | I think it's great that it checks that every file does exist by default. It's relatively cheap since it uses fsspec which caches file info at folder level.
On the other hand why not add skip_origin_metadata=False from @TheDerbiedOne by default to DatasetBuilder and document what it does (load_dataset passes kwargs to ... | Hi team!
I've been looking into the initialization process of the `DatasetBuilder` and noticed that the ETag/origin metadata caching path is executed unconditionally.
While fetching the `origin_metadata` and calculating the ETag is necessary for safely managing a local disk cache when using `as_dataset()`, it seems t... | 52 | Feature Request / Discussion: Skip origin_metadata fetch when streaming=True?
Hi team!
I've been looking into the initialization process of the `DatasetBuilder` and noticed that the ETag/origin metadata caching path is executed unconditionally.
While fetching the `origin_metadata` and calculating the ETag is necessar... |
https://github.com/huggingface/datasets/issues/8197 | Feature Request / Discussion: Skip origin_metadata fetch when streaming=True? | Hi @lhoestq Thanks for taking a look at this!
Regarding the file existence check: skipping _get_origin_metadata actually doesn't remove that safeguard. I think th verification that files exist happens earlier during pattern resolution (around L372-L384 in data_files.py (https://github.com/huggingface/datasets/blob/mai... | Hi team!
I've been looking into the initialization process of the `DatasetBuilder` and noticed that the ETag/origin metadata caching path is executed unconditionally.
While fetching the `origin_metadata` and calculating the ETag is necessary for safely managing a local disk cache when using `as_dataset()`, it seems t... | 97 | Feature Request / Discussion: Skip origin_metadata fetch when streaming=True?
Hi team!
I've been looking into the initialization process of the `DatasetBuilder` and noticed that the ETag/origin metadata caching path is executed unconditionally.
While fetching the `origin_metadata` and calculating the ETag is necessar... |
https://github.com/huggingface/datasets/issues/5386 | `max_shard_size` in `datasets.push_to_hub()` breaks with large files | Hi!
This behavior stems from the fact that we don't always embed image bytes in the underlying arrow table, which can lead to bad size estimation (we use the first 1000 table rows to [estimate](https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/arrow_dataset.py#L4627)... | ### Describe the bug
`max_shard_size` parameter for `datasets.push_to_hub()` works unreliably with large files, generating shard files that are way past the specified limit.
In my private dataset, which contains unprocessed images of all sizes (up to `~100MB` per file), I've encountered cases where `max_shard_siz... | 101 | `max_shard_size` in `datasets.push_to_hub()` breaks with large files
### Describe the bug
`max_shard_size` parameter for `datasets.push_to_hub()` works unreliably with large files, generating shard files that are way past the specified limit.
In my private dataset, which contains unprocessed images of all sizes (... |
https://github.com/huggingface/datasets/issues/3804 | Text builder with custom separator line boundaries | Hi ! Interresting :)
Could you give more details on what kind of separators you would like to use instead ? | **Is your feature request related to a problem? Please describe.**
The current [Text](https://github.com/huggingface/datasets/blob/207be676bffe9d164740a41a883af6125edef135/src/datasets/packaged_modules/text/text.py#L23) builder implementation splits texts with `splitlines()` which splits the text on several line bound... | 21 | Text builder with custom separator line boundaries
**Is your feature request related to a problem? Please describe.**
The current [Text](https://github.com/huggingface/datasets/blob/207be676bffe9d164740a41a883af6125edef135/src/datasets/packaged_modules/text/text.py#L23) builder implementation splits texts with `splitl... |
https://github.com/huggingface/datasets/issues/3804 | Text builder with custom separator line boundaries | Ok I see, maybe there can be a `sep` parameter to allow users to specify what line/paragraph separator they'd like to use | **Is your feature request related to a problem? Please describe.**
The current [Text](https://github.com/huggingface/datasets/blob/207be676bffe9d164740a41a883af6125edef135/src/datasets/packaged_modules/text/text.py#L23) builder implementation splits texts with `splitlines()` which splits the text on several line bound... | 22 | Text builder with custom separator line boundaries
**Is your feature request related to a problem? Please describe.**
The current [Text](https://github.com/huggingface/datasets/blob/207be676bffe9d164740a41a883af6125edef135/src/datasets/packaged_modules/text/text.py#L23) builder implementation splits texts with `splitl... |
https://github.com/huggingface/datasets/issues/3804 | Text builder with custom separator line boundaries | Thanks for requesting this enhancement. We have recently found a somehow related issue with another dataset:
- #3704
Let me make a PR proposal. | **Is your feature request related to a problem? Please describe.**
The current [Text](https://github.com/huggingface/datasets/blob/207be676bffe9d164740a41a883af6125edef135/src/datasets/packaged_modules/text/text.py#L23) builder implementation splits texts with `splitlines()` which splits the text on several line bound... | 24 | Text builder with custom separator line boundaries
**Is your feature request related to a problem? Please describe.**
The current [Text](https://github.com/huggingface/datasets/blob/207be676bffe9d164740a41a883af6125edef135/src/datasets/packaged_modules/text/text.py#L23) builder implementation splits texts with `splitl... |
https://github.com/huggingface/datasets/issues/7461 | List of images behave differently on IterableDataset and Dataset | Hi ! Can you try with `datasets` ^3.4 released recently ? on my side it works with IterableDataset on the recent version :)
```python
In [20]: def train_iterable_gen():
...: images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((12... | ### Describe the bug
This code:
```python
def train_iterable_gen():
images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((128, 128)))
yield {
"images": np.expand_dims(images, axis=0),
"messages": [
... | 157 | List of images behave differently on IterableDataset and Dataset
### Describe the bug
This code:
```python
def train_iterable_gen():
images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((128, 128)))
yield {
"image... |
https://github.com/huggingface/datasets/issues/7461 | List of images behave differently on IterableDataset and Dataset | Hm I tried it here and it works as expected, even on datasets 3.3.2. I guess maybe something in the SFTTrainer is doing additional processing on the dataset, I'll have a look there.
Thanks @lhoestq! | ### Describe the bug
This code:
```python
def train_iterable_gen():
images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((128, 128)))
yield {
"images": np.expand_dims(images, axis=0),
"messages": [
... | 35 | List of images behave differently on IterableDataset and Dataset
### Describe the bug
This code:
```python
def train_iterable_gen():
images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((128, 128)))
yield {
"image... |
https://github.com/huggingface/datasets/issues/5219 | Delta Tables usage using Datasets Library | Hi ! Interesting :) Can you provide concrete examples of cases where it can be useful ? | ### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats but it would be great if Datasets library... | 17 | Delta Tables usage using Datasets Library
### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats... |
https://github.com/huggingface/datasets/issues/5219 | Delta Tables usage using Datasets Library | Few example blogs and posts that might help on this -
1. https://hevodata.com/learn/databricks-delta-tables/
2. https://docs.databricks.com/delta/index.html
Basically, we are looking at utility of Datasets library with Delta Lake Tables.
| ### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats but it would be great if Datasets library... | 28 | Delta Tables usage using Datasets Library
### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats... |
https://github.com/huggingface/datasets/issues/5219 | Delta Tables usage using Datasets Library | `datasets` can already read/write from parquet from/to a cloud storage using fsspec, if I understand correctly it's should be possible to load parquet files as delat lake tables no ? :) Or is there someting missing ? | ### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats but it would be great if Datasets library... | 37 | Delta Tables usage using Datasets Library
### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats... |
https://github.com/huggingface/datasets/issues/5219 | Delta Tables usage using Datasets Library | @lhoestq Per my understanding, delta lake table is a bunch of paruqet files together with the meta to support ACID. For example file 1 contains v0.1 of record A while file 2 contains v0.2 of record A. I am assuming the Hugging face dataset would delegate the read/write delta table to 3rd party lib, maybe pyarrow. Corre... | ### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats but it would be great if Datasets library... | 119 | Delta Tables usage using Datasets Library
### Feature request
Adding compatibility of Datasets library with Delta Format. Elevating the utilities of Datasets library from Machine Learning Scope to Data Engineering Scope as well.
### Motivation
We know datasets library can absorb csv, json, parquet, etc. file formats... |
https://github.com/huggingface/datasets/issues/5186 | Incorrect error message when Dataset.from_sql fails and sqlalchemy not installed | Hi! The first `Dataset.from_sql` call also outputs the "ImportError: Using URI string without sqlalchemy installed." message, but you also get "During handling of the above exception another exception occurred: ..." after which the ValueError is printed. I agree that this behavior makes it easy to miss the original err... | ### Describe the bug
When calling `Dataset.from_sql` (in my case, with sqlite3), it fails with a message ```ValueError: Please pass `features` or at least one example when writing data``` when I don't have `sqlalchemy` installed.
### Steps to reproduce the bug
Make a new sqlite db with `sqlite3` and `pandas` from... | 79 | Incorrect error message when Dataset.from_sql fails and sqlalchemy not installed
### Describe the bug
When calling `Dataset.from_sql` (in my case, with sqlite3), it fails with a message ```ValueError: Please pass `features` or at least one example when writing data``` when I don't have `sqlalchemy` installed.
### ... |
https://github.com/huggingface/datasets/issues/5186 | Incorrect error message when Dataset.from_sql fails and sqlalchemy not installed | Yup ! Alternatively the error can be raised in sql.py before generating the examples ? In `_info` for example | ### Describe the bug
When calling `Dataset.from_sql` (in my case, with sqlite3), it fails with a message ```ValueError: Please pass `features` or at least one example when writing data``` when I don't have `sqlalchemy` installed.
### Steps to reproduce the bug
Make a new sqlite db with `sqlite3` and `pandas` from... | 19 | Incorrect error message when Dataset.from_sql fails and sqlalchemy not installed
### Describe the bug
When calling `Dataset.from_sql` (in my case, with sqlite3), it fails with a message ```ValueError: Please pass `features` or at least one example when writing data``` when I don't have `sqlalchemy` installed.
### ... |
https://github.com/huggingface/datasets/issues/5186 | Incorrect error message when Dataset.from_sql fails and sqlalchemy not installed | yea @lhoestq that would probably be good. The 2nd error is useless if the 1st error is the real reason it failed. | ### Describe the bug
When calling `Dataset.from_sql` (in my case, with sqlite3), it fails with a message ```ValueError: Please pass `features` or at least one example when writing data``` when I don't have `sqlalchemy` installed.
### Steps to reproduce the bug
Make a new sqlite db with `sqlite3` and `pandas` from... | 22 | Incorrect error message when Dataset.from_sql fails and sqlalchemy not installed
### Describe the bug
When calling `Dataset.from_sql` (in my case, with sqlite3), it fails with a message ```ValueError: Please pass `features` or at least one example when writing data``` when I don't have `sqlalchemy` installed.
### ... |
https://github.com/huggingface/datasets/issues/5378 | The dataset "the_pile", subset "enron_emails" , load_dataset() failure | Thanks for reporting @shaoyuta. We are investigating it.
We are transferring the issue to "the_pile" Community tab on the Hub: https://huggingface.co/datasets/the_pile/discussions/4 | ### Describe the bug
When run
"datasets.load_dataset("the_pile","enron_emails")" failure

### Steps to reproduce the bug
Run below code in python cli:
>>> import datasets
>>> datasets.load_dataset(... | 21 | The dataset "the_pile", subset "enron_emails" , load_dataset() failure
### Describe the bug
When run
"datasets.load_dataset("the_pile","enron_emails")" failure

### Steps to reproduce the bug
Run below... |
https://github.com/huggingface/datasets/issues/7744 | dtype: ClassLabel is not parsed correctly in `features.py` | > I think it's "class_label"
I see -- thank you. This works
```yaml
license: mit
language:
- en
tags:
- genomics
- yeast
- transcription
- perturbation
- response
- overexpression
pretty_name: Hackett, 2020 Overexpression
size_categories:
- 1M<n<10M
dataset_info:
features:
...
- name: mechanism
dtype:... | `dtype: ClassLabel` in the README.md yaml metadata is parsed incorrectly and causes the data viewer to fail.
This yaml in my metadata ([source](https://huggingface.co/datasets/BrentLab/yeast_genome_resources/blob/main/README.md), though i changed `ClassLabel` to `string` to using different dtype in order to avoid the ... | 120 | dtype: ClassLabel is not parsed correctly in `features.py`
`dtype: ClassLabel` in the README.md yaml metadata is parsed incorrectly and causes the data viewer to fail.
This yaml in my metadata ([source](https://huggingface.co/datasets/BrentLab/yeast_genome_resources/blob/main/README.md), though i changed `ClassLabel` ... |
https://github.com/huggingface/datasets/issues/7744 | dtype: ClassLabel is not parsed correctly in `features.py` | I generally copy/paste and adapt a YAML from another dataset.
But it's also possible to generate it from `datasets` like that
```python
>>> import yaml
>>> print(yaml.dump(features._to_yaml_list(), sort_keys=False))
- name: start
dtype: int32
- name: end
dtype: int32
- name: restriction
dtype:
class_label:
... | `dtype: ClassLabel` in the README.md yaml metadata is parsed incorrectly and causes the data viewer to fail.
This yaml in my metadata ([source](https://huggingface.co/datasets/BrentLab/yeast_genome_resources/blob/main/README.md), though i changed `ClassLabel` to `string` to using different dtype in order to avoid the ... | 48 | dtype: ClassLabel is not parsed correctly in `features.py`
`dtype: ClassLabel` in the README.md yaml metadata is parsed incorrectly and causes the data viewer to fail.
This yaml in my metadata ([source](https://huggingface.co/datasets/BrentLab/yeast_genome_resources/blob/main/README.md), though i changed `ClassLabel` ... |
https://github.com/huggingface/datasets/issues/3658 | Dataset viewer issue for *P3* | The error is now:
```
Status code: 400
Exception: Status400Error
Message: this dataset is not supported for now.
```
We've disabled the dataset viewer for several big datasets like this one. We hope being able to reenable it soon. | ## Dataset viewer issue for '*P3*'
**Link: https://huggingface.co/datasets/bigscience/P3**
```
Status code: 400
Exception: SplitsNotFoundError
Message: The split names could not be parsed from the dataset config.
```
Am I the one who added this dataset ? No
| 39 | Dataset viewer issue for *P3*
## Dataset viewer issue for '*P3*'
**Link: https://huggingface.co/datasets/bigscience/P3**
```
Status code: 400
Exception: SplitsNotFoundError
Message: The split names could not be parsed from the dataset config.
```
Am I the one who added this dataset ? No
The err... |
https://github.com/huggingface/datasets/issues/3658 | Dataset viewer issue for *P3* | ```
Error code: SplitsNamesError
Exception: SplitsNotFoundError
Message: The split names could not be parsed from the dataset config.
Traceback: Traceback (most recent call last):
File "/src/services/worker/.venv/lib/python3.9/site-packages/datasets/inspect.py", line 354, in get_dataset... | ## Dataset viewer issue for '*P3*'
**Link: https://huggingface.co/datasets/bigscience/P3**
```
Status code: 400
Exception: SplitsNotFoundError
Message: The split names could not be parsed from the dataset config.
```
Am I the one who added this dataset ? No
| 393 | Dataset viewer issue for *P3*
## Dataset viewer issue for '*P3*'
**Link: https://huggingface.co/datasets/bigscience/P3**
```
Status code: 400
Exception: SplitsNotFoundError
Message: The split names could not be parsed from the dataset config.
```
Am I the one who added this dataset ? No
```
Er... |
https://github.com/huggingface/datasets/issues/7627 | Creating a HF Dataset from lakeFS with S3 storage takes too much time! | ### > Update
The bottleneck, from what I understand, was making one network request per file
For 30k images, this meant 30k separate GET requests to the MinIO server through the S3 API, and that was killing the performance
Using webDataset to transform the large number of files to few .tar files and passing “webdata... | Hi,
I’m new to HF dataset and I tried to create datasets based on data versioned in **lakeFS** _(**MinIO** S3 bucket as storage backend)_
Here I’m using ±30000 PIL image from MNIST data however it is taking around 12min to execute, which is a lot!
From what I understand, it is loading the images into cache then buil... | 67 | Creating a HF Dataset from lakeFS with S3 storage takes too much time!
Hi,
I’m new to HF dataset and I tried to create datasets based on data versioned in **lakeFS** _(**MinIO** S3 bucket as storage backend)_
Here I’m using ±30000 PIL image from MNIST data however it is taking around 12min to execute, which is a lot!... |
https://github.com/huggingface/datasets/issues/6467 | New version release request | We will publish it soon (we usually do it in intervals of 1-2 months, so probably next week) | ### Feature request
Hi!
I am using `datasets` in library `xtuner` and am highly interested in the features introduced since v2.15.0.
To avoid installation from source in our pypi wheels, we are eagerly waiting for the new release. So, Does your team have a new release plan for v2.15.1 and could you please share ... | 18 | New version release request
### Feature request
Hi!
I am using `datasets` in library `xtuner` and am highly interested in the features introduced since v2.15.0.
To avoid installation from source in our pypi wheels, we are eagerly waiting for the new release. So, Does your team have a new release plan for v2.15.1... |
https://github.com/huggingface/datasets/issues/4086 | Dataset viewer issue for McGill-NLP/feedbackQA | Hi @cslizc, thanks for reporting.
I have just forced the refresh of the corresponding cache and the preview is working now. | ## Dataset viewer issue for '*McGill-NLP/feedbackQA*'
**Link:** *[link to the dataset viewer page](https://huggingface.co/datasets/McGill-NLP/feedbackQA)*
*short description of the issue*
The dataset can be loaded correctly with `load_dataset` but the preview doesn't work. Error message:
```
Status code: 4... | 21 | Dataset viewer issue for McGill-NLP/feedbackQA
## Dataset viewer issue for '*McGill-NLP/feedbackQA*'
**Link:** *[link to the dataset viewer page](https://huggingface.co/datasets/McGill-NLP/feedbackQA)*
*short description of the issue*
The dataset can be loaded correctly with `load_dataset` but the preview doesn'... |
https://github.com/huggingface/datasets/issues/6788 | A Question About the Map Function | All data is saved in the arrow format on disk.
If you return a tensor it gets converted to arrow before saving to disk when using map.
To get a tensor when you access data elements you can use `dataset.set_format("pt")`.
Note that this just changes how the data is loaded, not how it is stored. | ### Describe the bug
Hello,
I have a question regarding the map function in the Hugging Face datasets.
The situation is as follows: when I load a jsonl file using load_dataset(..., streaming=False), and then utilize the map function to process it, I specify that the returned example should be of type Torch.ten... | 55 | A Question About the Map Function
### Describe the bug
Hello,
I have a question regarding the map function in the Hugging Face datasets.
The situation is as follows: when I load a jsonl file using load_dataset(..., streaming=False), and then utilize the map function to process it, I specify that the returned e... |
https://github.com/huggingface/datasets/issues/6788 | A Question About the Map Function | > All data is saved in the arrow format on disk. If you return a tensor it gets converted to arrow before saving to disk when using map.
>
> To get a tensor when you access data elements you can use `dataset.set_format("pt")`. Note that this just changes how the data is loaded, not how it is stored.
Thank you ver... | ### Describe the bug
Hello,
I have a question regarding the map function in the Hugging Face datasets.
The situation is as follows: when I load a jsonl file using load_dataset(..., streaming=False), and then utilize the map function to process it, I specify that the returned example should be of type Torch.ten... | 122 | A Question About the Map Function
### Describe the bug
Hello,
I have a question regarding the map function in the Hugging Face datasets.
The situation is as follows: when I load a jsonl file using load_dataset(..., streaming=False), and then utilize the map function to process it, I specify that the returned e... |
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | Hi!
You can specify `download_config=DownloadConfig(resume_download=True))` in `load_dataset` to resume the download when re-running the code after the timeout error:
```python
from datasets import load_dataset, DownloadConfig
dataset = load_dataset('the_pile', split='train', cache_dir='F:\datasets', download_... | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.
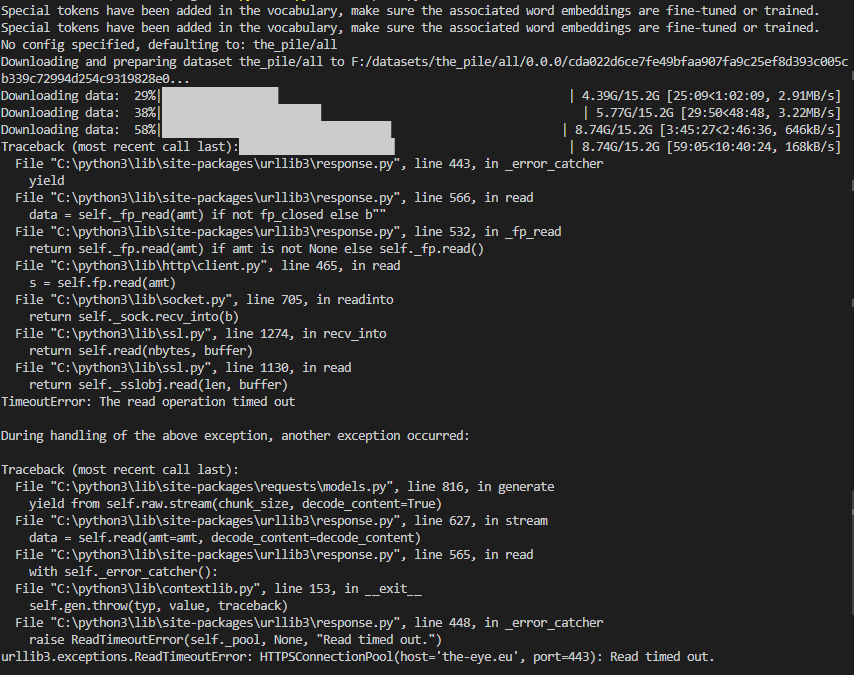
Here are the downloaded files:

Here are the downlo... |
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | @mariosasko , I used your suggestion but its not saving anything , just stops and runs from the same point .
below is the script to download and save on disk .
```
from datasets import load_dataset, DownloadConfig
#load the Pile dataset from Hugging Face Datasets
#dataset = load_dataset('the_pile')
dataset ... | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.

Here are the downloaded files:

Here are the downlo... |
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | @mariosasko , it shows nothing in dataset folder
```
du -sh /mnt/nlp/hugging_face/*
20K /mnt/nlp/hugging_face/datasets
4.0K /mnt/nlp/hugging_face/download_pile.py
```
| ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.

Here are the downloaded files:

Here are the downlo... |
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | @mariosasko
```
root@d20f0ab8f4f8:/mnt/hugging_face# python3 download_pile.py
No config specified, defaulting to: the_pile/all
Downloading and preparing dataset the_pile/all to /mnt/hugging_face/datasets/the_pile/all/0.0.0/6fadc480ecb32470826cbf5900a9558b791ce55d5e9a0fdc8ad653e7b64bb349...
Downloading data file... | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.

Here are the downloaded files:

Here are the downlo... |
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | Users with slow internet speed are doomed (4MB/s). The dataset downloads fine at minimum speed 10MB/s.
Also, when the train splits were generated and then I removed the downloads folder to save up disk space, it started redownloading the whole dataset. Is there any way to use the already generated splits instead? | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.

Here are the downloaded files:

Here are the downlo... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.