
html_url stringlengths 51 51 | title stringlengths 9 280 | comments stringlengths 63 24.7k | body stringlengths 51 58.6k | comments length int64 16 1.45k | text stringlengths 186 59.1k |
|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | @sentialx @mariosasko , anytime on my above script , am I downloading and saving dataset correctly . Please suggest :) | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.
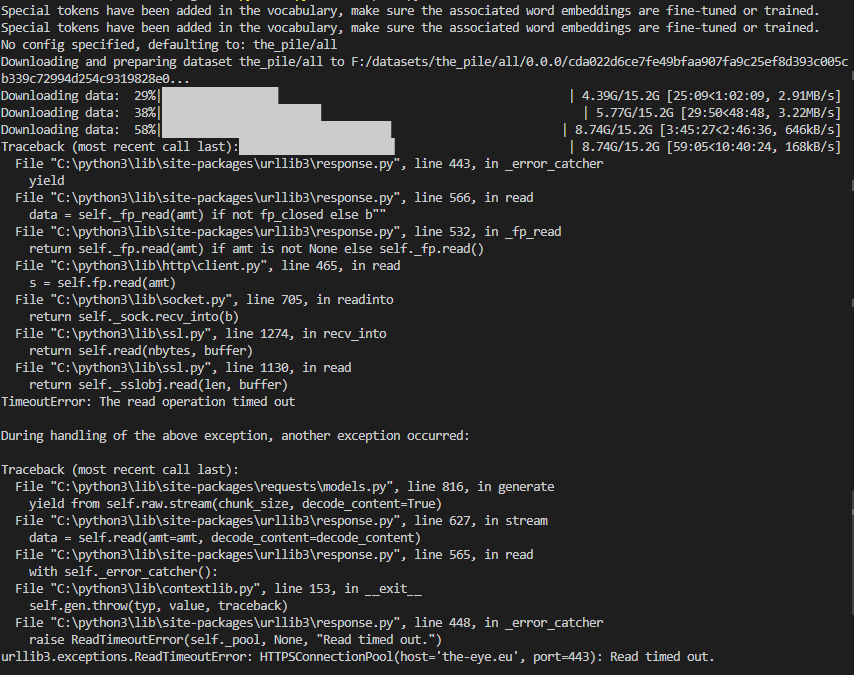
Here are the downloaded files:

Here are the downlo... |
https://github.com/huggingface/datasets/issues/5604 | Problems with downloading The Pile | @sentialx probably worth noting that `resume_download=True` doesn't directly save the dataset to disk, but instead just helps in resuming the dataset resume on interruption as @mariosasko mentions. resolving resumptions after a crash is [an open issue](https://github.com/huggingface/datasets/issues/5380) at the moment. | ### Describe the bug
The downloads in the screenshot seem to be interrupted after some time and the last download throws a "Read timed out" error.

Here are the downloaded files:

Here are the downlo... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | This has so much potential to be great! Also I think you tagged some poor random dude on the internet whose name is also Joao, lol, edited that for you! | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 30 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Noted and I will look into the thread in detail tomorrow once I log back in. | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 16 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | @lhoestq I have used TFRecords with `tf.data` for both vision and text and I can say that they are quite performant. I haven't worked with Feather yet as similarly as I have with TFRecords. If you haven't started the benchmarking script yet, I can prepare a Colab notebook that loads Feather files, converts them into a ... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 86 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > Not yet sure if it's good for modalities like images.
We store images pretty much the same way as tensorflow_datasets (i.e. storing the encoded image bytes, or a path to the local image, so that the image can be decoded on-the-fly), so as long as we use something similar as TFDS for image decoding it should be ok | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 59 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | So for image datasets, we could potentially store the paths in the feather format and decode and read them on the fly? But it introduces an I/O redundancy of having to read the images every time.
With caching it could be somewhat mitigated but it's not a good solution for bigger image datasets. | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 53 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > So for image datasets, we could potentially store the paths in the feather format and decode and read them on the fly?
hopefully yes :)
I double-checked the TFDS source code and they always save the bytes actually, not the path. Anyway we'll see if we run into issues or not (as a first step we can require the ... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 67 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Yes. For images, TFDS actually prepares TFRecords first for encoding and then reuses them for every subsequent call. | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 18 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | @lhoestq @Rocketknight1 I worked on [this PoC](https://gist.github.com/sayakpaul/f7d5cc312cd01cb31098fad3fd9c6b59) that
* Creates Feather files from a medium resolution dataset (`tf_flowers`).
* Explores different options with TensorFlow IO to load the Feather files.
I haven't benchmarked those different option... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 61 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Cool thanks ! If I understand correctly in your PoC you store the flattened array of pixels in the feather file. This will take a lot of disk space.
Maybe we could just save the encoded bytes and let users apply a `map` to decode/transform them into the format they need for training ? Users can use tf.image to do so... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 63 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | @lhoestq this is what I tried:
```py
def read_image(path):
with open(path, "rb") as f:
return f.read()
total_images_written = 0
for step in tqdm.tnrange(int(math.ceil(len(image_paths) / batch_size))):
batch_image_paths = image_paths[step * batch_size : (step + 1) * batch_size]
batch_... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 413 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | @lhoestq I think I was able to make it work in the way you were envisioning. Here's the PoC:
https://gist.github.com/sayakpaul/f7d5cc312cd01cb31098fad3fd9c6b59#file-feather-tf-poc-bytes-ipynb
Some details:
* I am currently serializing the images as strings with `base64`). In comparison to the flattened arrays as... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 107 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Cool thanks ! Too bad the Arrow binary type doesn't seem to be supported in `arrow_io.ArrowFeatherDataset` :/ We would also need it to support Arrow struct type. Indeed images in `datasets` are represented using an Arrow type
```python
pa.struct({"path": pa.string(), "bytes": pa.binary()})
```
not sure yet how hard... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 78 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | If the ArrowFeatherDataset doesn't yet support it, I guess our hands are a bit tied at the moment.
IIUC, in my [latest PoC notebook](https://gist.github.com/sayakpaul/f7d5cc312cd01cb31098fad3fd9c6b59#file-feather-tf-poc-bytes-ipynb), you wanted to see each entry in the feather file to be represented like so?
```... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 52 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > IIUC, in my [latest PoC notebook](https://gist.github.com/sayakpaul/f7d5cc312cd01cb31098fad3fd9c6b59#file-feather-tf-poc-bytes-ipynb), you wanted to see each entry in the feather file to be represented like so?
>
> pa.struct({"path": pa.string(), "bytes": pa.binary()})
Yea because that's the data format we're u... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 108 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > Maybe it would take too much time to be worth exploring, but according to https://github.com/tensorflow/io/issues/1361#issuecomment-819029002 it's possible to add support for binary type in ArrowFeatherDataset.
Should be possible as per the comment but there hasn't been any progress and it's been more than a year.... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 117 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > I don't understand this. I would think TFRecords would also need something similar but I need the context you're coming from.
Users already have a copy of the dataset in Arrow format (we can change this to Feather). So to load the Arrow/feather files to a TF dataset we need TF IO or something like that. Otherwise ... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 116 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Yeah, it looks like in its current state the tfio support for `Feather` is incomplete, so we'd end up having to write a lot of it, or do a conversion that defeats the whole point (because if we're going to convert the whole dataset we might as well convert to `TFRecord`). | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 51 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | @lhoestq Although I think this is a dead-end for now unfortunately, because of the limitations at TF's end, we could still explore automatic conversion to TFRecord, or I could dive into refining `to_tf_dataset()` to yield unbatched samples and/or load samples with multiprocessing to improve throughput. Do you have any ... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 51 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > @lhoestq Although I think this is a dead-end for now unfortunately, because of the limitations at TF's end, we could still explore automatic conversion to TFRecord, or I could dive into refining `to_tf_dataset()` to yield unbatched samples and/or load samples with multiprocessing to improve throughput. Do you have an... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 58 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | If `to_tf_dataset` can be unbatched, then it should be fairly easy for users to convert the TF dataset to TFRecords right ? | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 22 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > If to_tf_dataset can be unbatched, then it should be fairly easy for users to convert the TF dataset to TFRecords right ?
Sort of! A `tf.data.Dataset` is more like an iterator, and does not support sample indexing. `to_tf_dataset()` creates an iterator, but to convert that to `TFRecord`, the user would have to ite... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 67 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Someone would like to try to dive into tfio to fix this ? Sounds like a good opportunity to learn what are the best ways to load a dataset for TF, and also the connections between Arrow and TF.
If we can at least have the Arrow `binary` type working for TF that would be awesome already (issue https://github.com/tens... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 68 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | > Sounds like a good opportunity to learn what are the best ways to load a dataset for TF
The recommended way would likely be a combination of TFRecords and `tf.data`.
Exploring the connection between Arrow and TensorFlow is definitely worth pursuing though. But I am not sure about the implications of storing im... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 91 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | I am currently working on a fine-tuning notebook for the TFSegFormer model (Semantic Segmentation). The resolution is high for both the input images and the labels - (512, 512, 3). Here's the [Colab Notebook](https://colab.research.google.com/drive/1jAtR7Z0lYX6m6JsDI5VByh5vFaNhHIbP?usp=sharing) (it's a WIP so please be... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 62 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Here's a notebook showing the performance difference: https://colab.research.google.com/gist/sayakpaul/d7ca67c90beb47e354942c9d8c0bd8ef/scratchpad.ipynb.
Note that I acknowledge that it's not an apples-to-apples comparison in many aspects (the dataset isn't the same, data serialization format isn't the same, etc.) ... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 41 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Thanks ! I think the speed difference can be partly explained: you use ds.shuffle in your dataset, which is an exact shuffling (compared to TFDS which does buffer shuffling): it slows down query time by 2x to 10x since it has to play with data that are not contiguous.
The rest of the speed difference seems to be cau... | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 66 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/4542 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ? | Fair enough. Can do one without shuffling too. But it's an important one to consider I guess. | To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and load one file at a time in memory.
It seems that using `tensorflow_... | 17 | [to_tf_dataset] Use Feather for better compatibility with TensorFlow ?
To have better performance in TensorFlow, it is important to provide lists of data files in supported formats. For example sharded TFRecords datasets are extremely performant. This is because tf.data can better leverage parallelism in this case, and... |
https://github.com/huggingface/datasets/issues/5654 | Offset overflow when executing Dataset.map | Upd. the above code works if we replace `25` with `1`, but the result value at key "hr" is not a tensor but a list of lists of lists of uint8.
Adding `train_data.set_format("torch")` after map fixes this, but the original issue remains
| ### Describe the bug
Hi, I'm trying to use `.map` method to cache multiple random crops from the image to speed up data processing during training, as the image size is too big.
The map function executes all iterations, and then returns the following error:
```bash
Traceback (most recent call last): ... | 42 | Offset overflow when executing Dataset.map
### Describe the bug
Hi, I'm trying to use `.map` method to cache multiple random crops from the image to speed up data processing during training, as the image size is too big.
The map function executes all iterations, and then returns the following error:
```bash
Tr... |
https://github.com/huggingface/datasets/issues/5654 | Offset overflow when executing Dataset.map | As a workaround, one can replace
`return {"hr": torch.stack([crop_transf(tensor) for _ in range(25)])}`
with
`return {f"hr_crop_{i}": crop_transf(tensor) for i in range(25)}`
and then choose appropriate crop randomly in further processing, but I still don't understand why the original approach doesn't work(
| ### Describe the bug
Hi, I'm trying to use `.map` method to cache multiple random crops from the image to speed up data processing during training, as the image size is too big.
The map function executes all iterations, and then returns the following error:
```bash
Traceback (most recent call last): ... | 41 | Offset overflow when executing Dataset.map
### Describe the bug
Hi, I'm trying to use `.map` method to cache multiple random crops from the image to speed up data processing during training, as the image size is too big.
The map function executes all iterations, and then returns the following error:
```bash
Tr... |
https://github.com/huggingface/datasets/issues/6918 | NonMatchingSplitsSizesError when using data_dir | I confirm there is a bug for data-based Hub datasets when the user passes `data_dir`, which was introduced by PR:
- #6714 | ### Describe the bug
Loading a dataset from with a data_dir argument generates a NonMatchingSplitsSizesError if there are multiple directories in the dataset.
This appears to happen because the expected split is calculated based on the data in all the directories whereas the recorded split is calculated based on t... | 22 | NonMatchingSplitsSizesError when using data_dir
### Describe the bug
Loading a dataset from with a data_dir argument generates a NonMatchingSplitsSizesError if there are multiple directories in the dataset.
This appears to happen because the expected split is calculated based on the data in all the directories whe... |
https://github.com/huggingface/datasets/issues/5612 | Arrow map type in parquet files unsupported | I'm attaching a minimal reproducible example:
```python
from datasets import load_dataset
import pyarrow as pa
import pyarrow.parquet as pq
table_with_map = pa.Table.from_pydict(
{"a": [1, 2], "b": [[("a", 2)], [("b", 4)]]},
schema=pa.schema({"a": pa.int32(), "b": pa.map_(pa.string(), pa.int32())})
)
... | ### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True` solves the issue.
### Steps to reproduce ... | 94 | Arrow map type in parquet files unsupported
### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True... |
https://github.com/huggingface/datasets/issues/5612 | Arrow map type in parquet files unsupported | I've also been wondering about datasets support for Arrow Map datatypes. I had a situation where I had a pandas series of dict[str, float] with hundreds of different possible key values (ie. not bounded), and this got converted to a sequence of structs where every single struct had the entire set of keys.
I worked a... | ### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True` solves the issue.
### Steps to reproduce ... | 88 | Arrow map type in parquet files unsupported
### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True... |
https://github.com/huggingface/datasets/issues/5612 | Arrow map type in parquet files unsupported | (feel free to ignore) polars will not support this type: https://github.com/pola-rs/polars/issues/3942#issuecomment-1202331210
> Polars will not add the map dtype. It's benefit do not outweigh the extra complexity. Maybe we can investigate conversion of maps to struct. But I will have to explore that. | ### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True` solves the issue.
### Steps to reproduce ... | 43 | Arrow map type in parquet files unsupported
### Describe the bug
When I try to load parquet files that were processed with Spark, I get the following issue:
`ValueError: Arrow type map<string, string ('warc_headers')> does not have a datasets dtype equivalent.`
Strangely, loading the dataset with `streaming=True... |
https://github.com/huggingface/datasets/issues/7986 | `Dataset.map()` causes cache miss/fingerprint change when closure captures self containing non-deterministic state. | I suggest metion this in docs specifically for attention with use, tell users explicitly to pass arguments with `fn_kwargs` param or using `functools.partial` to create a pure funcion. | ### Describe the bug
When using `.map()` with a function defined inside a **class (of which has any non-deterministic states)** method (a closure), if that function captures `self` to access a configuration variable (e.g., self.foo), the fingerprint mechanism serializes the entire class instance state.
If the class i... | 28 | `Dataset.map()` causes cache miss/fingerprint change when closure captures self containing non-deterministic state.
### Describe the bug
When using `.map()` with a function defined inside a **class (of which has any non-deterministic states)** method (a closure), if that function captures `self` to access a configurat... |
https://github.com/huggingface/datasets/issues/4531 | Dataset Viewer issue for CSV datasets | Confirmed, it's fixed now. Thanks for reporting, and thanks @coyotte508 for fixing it
<img width="1123" alt="Capture d’écran 2022-06-21 à 10 28 05" src="https://user-images.githubusercontent.com/1676121/174753833-1b453a5a-6a90-4717-bca1-1b5fc6b75e4a.png">
| ### Link
https://huggingface.co/datasets/scikit-learn/breast-cancer-wisconsin
### Description
I'm populating CSV datasets [here](https://huggingface.co/scikit-learn) but the viewer is not enabled and it looks for a dataset loading script, the datasets aren't on queue as well.
You can replicate the problem by sim... | 23 | Dataset Viewer issue for CSV datasets
### Link
https://huggingface.co/datasets/scikit-learn/breast-cancer-wisconsin
### Description
I'm populating CSV datasets [here](https://huggingface.co/scikit-learn) but the viewer is not enabled and it looks for a dataset loading script, the datasets aren't on queue as well.
... |
https://github.com/huggingface/datasets/issues/4791 | Dataset Viewer issue for Team-PIXEL/rendered-wikipedia-english | Thanks for reporting. It's a known issue that should be fixed soon. Meanwhile, I had to manually trigger the dataset viewer. It's OK now.
Note that the extreme aspect ratio of the images generates another issue, that we're inspecting. | ### Link
https://huggingface.co/datasets/Team-PIXEL/rendered-wikipedia-english/viewer/rendered-wikipedia-en/train
### Description
The dataset can be loaded fine but the viewer shows this error:
```
Server Error
Status code: 400
Exception: Status400Error
Message: The dataset does not exist.
```
... | 39 | Dataset Viewer issue for Team-PIXEL/rendered-wikipedia-english
### Link
https://huggingface.co/datasets/Team-PIXEL/rendered-wikipedia-english/viewer/rendered-wikipedia-en/train
### Description
The dataset can be loaded fine but the viewer shows this error:
```
Server Error
Status code: 400
Exception: Sta... |
https://github.com/huggingface/datasets/issues/5045 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted | Could you share the error you got please ? Maybe the full stack trace if you have it ?
Maybe `push_to_hub` be implemented as a single commit @Wauplin ? This way if it fails, the repo is still at the previous (valid) state instead of ending-up in an invalid/incimplete state. | **Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset to raise an error on load_dataset() (ValueError couldn’t cast … because column names do... | 50 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted
**Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset... |
https://github.com/huggingface/datasets/issues/5045 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted | > Maybe push_to_hub be implemented as a single commit ?
I think that would definitely be the way to go. Do you know the reasons why not implementing it like this in the first place ? I guess it is because of not been able to upload all at once with `huggingface_hub` but if there was another reason, please let me kn... | **Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset to raise an error on load_dataset() (ValueError couldn’t cast … because column names do... | 125 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted
**Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset... |
https://github.com/huggingface/datasets/issues/5045 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted | > I think that would definitely be the way to go. Do you know the reasons why not implementing it like this in the first place ? I guess it is because of not been able to upload all at once with huggingface_hub but if there was another reason, please let me know.
Ideally we would want to upload the files iteratively... | **Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset to raise an error on load_dataset() (ValueError couldn’t cast … because column names do... | 147 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted
**Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset... |
https://github.com/huggingface/datasets/issues/5045 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted | > Ideally we would want to upload the files iteratively - and then once everything is uploaded we proceed to commit.
Oh I see. So maybe this has to be done in an implementation specific to `datasets/` as it is not a very common case (upload a bunch of files on the fly).
You can maybe have a look at how `huggingf... | **Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset to raise an error on load_dataset() (ValueError couldn’t cast … because column names do... | 162 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted
**Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset... |
https://github.com/huggingface/datasets/issues/5045 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted | > Could you share the error you got please ? Maybe the full stack trace if you have it ?
Here’s part of the stack trace, that I can reproduce at the moment from a photo I took (potential typos from OCR):
```
ValueError
Traceback (most recent call last)
<ipython-input-4-274613b7d3f5> in <module>
from datasets im... | **Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset to raise an error on load_dataset() (ValueError couldn’t cast … because column names do... | 155 | Automatically revert to last successful commit to hub when a push_to_hub is interrupted
**Is your feature request related to a problem? Please describe.**
I pushed a modification of a large dataset (remove a column) to the hub. The push was interrupted after some files were committed to the repo. This left the dataset... |
https://github.com/huggingface/datasets/issues/6432 | load_dataset does not load all of the data in my input file | You should use `datasets.load_dataset` instead of `nlp.load_dataset`, as the `nlp` package is outdated.
If switching to `datasets.load_dataset` doesn't fix the issue, sharing the JSON file (feel free to replace the data with dummy data) would be nice so that we can reproduce it ourselves. | ### Describe the bug
I have 127 elements in my input dataset. When I do a len on the dataset after loaded, it is only 124 elements.
### Steps to reproduce the bug
train_dataset = nlp.load_dataset(data_args.dataset_path, name=data_args.qg_format, split=nlp.Split.TRAIN)
valid_dataset = nlp.load_dataset(data_... | 44 | load_dataset does not load all of the data in my input file
### Describe the bug
I have 127 elements in my input dataset. When I do a len on the dataset after loaded, it is only 124 elements.
### Steps to reproduce the bug
train_dataset = nlp.load_dataset(data_args.dataset_path, name=data_args.qg_format, split=... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | Hi ! Sure :) you can comment `#self-assign` to assign yourself to this issue.
I can give you some pointers to get started:
`load_dataset` works roughly this way:
1. it instantiate a dataset builder using `load_dataset_builder()`
2. the builder download and prepare the dataset as Arrow files in the cache using `... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 146 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | This use-case is a bit specific, and `load_dataset` already has enough parameters (plus, `streaming=True` also returns an iterable dataset, so we would have to explain the difference), so I think it would be better to add `IterableDataset.from_file` to the API (more flexible and aligned with the goal from https://githu... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 50 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | > This use-case is a bit specific
This allows to use `datasets` for large scale training where map-style datasets are too slow and use too much memory in PyTorch. So I would still consider adding it.
Alternatively we could add this feature one level bellow:
```python
builder = load_dataset_builder(...)
builder... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 54 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | Yes, I see how this can be useful. Still, I think `Dataset.to_iterable` + `IterableDataset.from_file` would be much cleaner in terms of the API design (and more flexible since `load_dataset` can only access the "initial" (unprocessed) version of a dataset).
And since it can be tricky to manually find the "initial" v... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 75 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | > This allows to use datasets for large scale training where map-style datasets are too slow and use too much memory in PyTorch.
I second that. e.g. In my last experiment Oscar-en uses 16GB RSS RAM per process and when using multiple processes the host quickly runs out cpu memory. | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 50 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | >And since it can be tricky to manually find the "initial" version of a dataset in the cache, maybe load_dataset could return an iterable dataset streamed from the cache if streaming=True and the cache is up-to-date.
This is exactly the need on JeanZay (HPC) - I have the dataset cache ready, but the compute node is ... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 81 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | > Yes, I see how this can be useful. Still, I think Dataset.to_iterable + IterableDataset.from_file would be much cleaner in terms of the API design (and more flexible since load_dataset can only access the "initial" (unprocessed) version of a dataset).
I like `IterableDataset.from_file` as well. On the other hand `... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 172 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | > I was suggesting a different parameter just to make explicit the difference between
MosaicML's `streaming` library does the same (tries to stream from the local cache if possible), so logging a message should be explicit enough :). | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 38 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | Hi Both! It has been a while since my first issue so I am gonna go for this one ! #self-assign | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 21 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | https://github.com/huggingface/datasets/pull/5821 should be helpful to implement `IterableDataset.from_file`, since it defines a new ArrowExamplesIterable that takes an Arrow tables generator function (e.g. from a file) and can be used in an IterableDataset | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 31 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | So what's recommanded usage of `IterableDataset.from_file` and `load_dataset`? How about I have multiple arrow files and `load_dataset` is often convenient to handle that. | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 23 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | If you have multiple Arrow files you can load them using
```python
from datasets import load_dataset
data_files = {"train": ["path/to/0.arrow", "path/to/1.arrow", ..., "path/to/n.arrow"]}
ds = load_dataset("arrow", data_files=data_files, streaming=True)
```
This is equivalent to calling `IterableDataset.f... | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 37 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | Hi! 👋 I’d love to help with this feature and was wondering if @mariusz-jachimowicz-83 is still working on it. If not, I’d be happy to pick it up and continue. Let me know! 🙌 | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 34 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | I don't think anyone is working on this at the moment, imo the simplest would be to do it one level below
```python
builder = load_dataset_builder(...)
builder.download_and_prepare()
ids = builder.as_iterable_dataset()
``` | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 31 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/5481 | Load a cached dataset as iterable | Follow-up test added in #7629. for as_iterable_dataset() method.
I’ve added the unit test in a separate PR to keep this one focused on the feature implementation, as the test is optional and can be reviewed independently. | The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streaming=True | 36 | Load a cached dataset as iterable
The idea would be to allow something like
```python
ds = load_dataset("c4", "en", as_iterable=True)
```
To be used to train models. It would load an IterableDataset from the cached Arrow files.
Cc @stas00
Edit : from the discussions we may load from cache when streamin... |
https://github.com/huggingface/datasets/issues/8005 | Multi-channel audio is automatically cast to mono, num_channels is ignored | **Workaround**
Directly load audio using torchcodec, this is what datasets does under the hood (but doesn't maintain multi-channel)
```python
import torchcodec
decoder = torchcodec.decoders.AudioDecoder(audio["bytes"])
audio_samples = decoder.get_all_samples()
audio = audio_samples.data.numpy()
sample_rate = audio_s... | ### Describe the bug
The `num_channels` parameter in `datasets.Audio()` is documented to preserve stereo channels when set to `None` (preserve original) or `2` (explicit stereo), but it currently downmixes all audio to mono regardless of this setting.
### Steps to reproduce the bug
```python
import numpy as np
impor... | 34 | Multi-channel audio is automatically cast to mono, num_channels is ignored
### Describe the bug
The `num_channels` parameter in `datasets.Audio()` is documented to preserve stereo channels when set to `None` (preserve original) or `2` (explicit stereo), but it currently downmixes all audio to mono regardless of this s... |
https://github.com/huggingface/datasets/issues/8005 | Multi-channel audio is automatically cast to mono, num_channels is ignored | Interesting finding :astonished:. I checked the git history, and it looks like after num_channels was introduced, the backward-compat ["array"] contract was not updated accordingly.
Audio(num_channels=...) is passed to AudioDecoder, but decoded_audio["array"] is still forced to mono in the torchcodec wrapper (np.mean(.... | ### Describe the bug
The `num_channels` parameter in `datasets.Audio()` is documented to preserve stereo channels when set to `None` (preserve original) or `2` (explicit stereo), but it currently downmixes all audio to mono regardless of this setting.
### Steps to reproduce the bug
```python
import numpy as np
impor... | 69 | Multi-channel audio is automatically cast to mono, num_channels is ignored
### Describe the bug
The `num_channels` parameter in `datasets.Audio()` is documented to preserve stereo channels when set to `None` (preserve original) or `2` (explicit stereo), but it currently downmixes all audio to mono regardless of this s... |
https://github.com/huggingface/datasets/issues/6843 | IterableDataset raises exception instead of retrying | Thanks, @mariosasko! Related question (although I guess this is a feature request): could we have some kind of exponential back-off for these retries? Here's my reasoning:
- If a one-time accidental error happens, you should retry immediately and will succeed immediately.
- If the Hub has a small outage on the order ... | ### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingface/datasets/issues/6172#issuecomment-1794876229). Si... | 150 | IterableDataset raises exception instead of retrying
### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingf... |
https://github.com/huggingface/datasets/issues/6843 | IterableDataset raises exception instead of retrying | Oh, I've just remembered that we added retries to the `HfFileSystem` in `huggingface_hub` 0.21.0 (see [this](https://github.com/huggingface/huggingface_hub/blob/61b156a4f2e5fe1a492ed8712b26803e2122bde0/src/huggingface_hub/hf_file_system.py#L703)), so I'll close the linked PR as we don't want to retry the retries :).
... | ### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingface/datasets/issues/6172#issuecomment-1794876229). Si... | 43 | IterableDataset raises exception instead of retrying
### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingf... |
https://github.com/huggingface/datasets/issues/6843 | IterableDataset raises exception instead of retrying | @mariosasko The call you linked indeed points to the implementation I linked in my previous comment, yes, but it has no configurability. Arguably, you want to have this hidden backoff under the hood that catches small network disturbances on the time scale of seconds -- perhaps even with hardcoded limits as is the case... | ### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingface/datasets/issues/6172#issuecomment-1794876229). Si... | 179 | IterableDataset raises exception instead of retrying
### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingf... |
https://github.com/huggingface/datasets/issues/6843 | IterableDataset raises exception instead of retrying | I also have my runs crash a surprising amount due to the dataloader crashing because of the hub, some way to address this would be nice. | ### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingface/datasets/issues/6172#issuecomment-1794876229). Si... | 26 | IterableDataset raises exception instead of retrying
### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingf... |
https://github.com/huggingface/datasets/issues/6843 | IterableDataset raises exception instead of retrying | @mariosasko The implementation for retries is still broken and there is still no exponential back-off.
HuggingFace has a two-tiered back-off:
- `huggingface_hub.utils` provides the low-level `http_backoff` function which is used for all HTTP requests. It retries first with 1 second delay, then 2, then 4, then 8, th... | ### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingface/datasets/issues/6172#issuecomment-1794876229). Si... | 319 | IterableDataset raises exception instead of retrying
### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingf... |
https://github.com/huggingface/datasets/issues/6843 | IterableDataset raises exception instead of retrying | I merged a fix for this, thanks for reporting ! It will now retry on any `requests` Timeout error, including ReadTimeoutError: https://github.com/huggingface/datasets/pull/7256 | ### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingface/datasets/issues/6172#issuecomment-1794876229). Si... | 22 | IterableDataset raises exception instead of retrying
### Describe the bug
In light of the recent server outages, I decided to look into whether I could somehow wrap my IterableDataset streams to retry rather than error out immediately. To my surprise, `datasets` [already supports retries](https://github.com/huggingf... |
https://github.com/huggingface/datasets/issues/4915 | FileNotFoundError while downloading wikipedia dataset for any language | Hi @Shilpac20,
As explained in the Wikipedia dataset card: https://huggingface.co/datasets/wikipedia
> You can find the full list of languages and dates [here](https://dumps.wikimedia.org/backup-index.html).
This means that, before passing a specific date, you should first make sure it is available online, as Wi... | ## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this error for any language I try to download.
Environment:
## Step... | 79 | FileNotFoundError while downloading wikipedia dataset for any language
## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this e... |
https://github.com/huggingface/datasets/issues/4915 | FileNotFoundError while downloading wikipedia dataset for any language | Hi, the date that I have specified "20220401" is available for the language "aa". The error persists for any other available dates as present in https://dumps.wikimedia.org/aawiki/. The error is mainly due to apache beam not able to write the downloaded files. Any help on this? | ## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this error for any language I try to download.
Environment:
## Step... | 45 | FileNotFoundError while downloading wikipedia dataset for any language
## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this e... |
https://github.com/huggingface/datasets/issues/4915 | FileNotFoundError while downloading wikipedia dataset for any language | I am struggling with basically the same issue. I am trying to download the German Wikipedia dump.
As per the [documentation](https://huggingface.co/datasets/wikipedia), `"20220301.de"` should be available as a pre-processed dataset.
Issuing the command mentioned in the documentation cited above
from datase... | ## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this error for any language I try to download.
Environment:
## Step... | 175 | FileNotFoundError while downloading wikipedia dataset for any language
## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this e... |
https://github.com/huggingface/datasets/issues/4915 | FileNotFoundError while downloading wikipedia dataset for any language | I am able to start downloading the dataset when trying anything with the recent dumps for 20221201. But obviously, those are the big wiki dumps and I need the smaller preloaded version.
I am now getting some error when the files show up in my cache but it will say FileNotFoundError at the end of the download for som... | ## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this error for any language I try to download.
Environment:
## Step... | 101 | FileNotFoundError while downloading wikipedia dataset for any language
## Describe the bug
Hi, I am currently trying to download wikipedia dataset using
load_dataset("wikipedia", language="aa", date="20220401", split="train",beam_runner='DirectRunner'). However, I end up in getting filenotfound error. I get this e... |
https://github.com/huggingface/datasets/issues/5315 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails | EDIT:
I think in this case, the metadata files (either README or JSON) should not be read (i.e. `self.info.splits` should be None).
One idea:
- I think ideally we should set this behavior when we pass `--save_info` to the CLI `test`
- However, currently, the builder is unaware of this: `save_info` arg is not pas... | ### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's what happened in https://huggingface.co/datasets/mrdbourke/food_vision_199_classes/discussions/2#6385f... | 57 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails
### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's... |
https://github.com/huggingface/datasets/issues/5315 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails | > I think in this case
@albertvillanova You mean in cases when the script was changed?
I suggest that we:
* add a check on the slice (like 'split_name[n%]) kind of format here: https://github.com/huggingface/datasets/blob/main/src/datasets/splits.py#L523 to catch things like this.
* Error here happens before... | ### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's what happened in https://huggingface.co/datasets/mrdbourke/food_vision_199_classes/discussions/2#6385f... | 142 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails
### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's... |
https://github.com/huggingface/datasets/issues/5315 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails | I edited my previous comment:
- First I proposed setting `self.info.splits` to None when `ignore_verifications=True`
- I thought it was the easiest implementation because `ignore_verifications` is passed to `DatasetBuilder.download_and_prepare`
- However, afterwards, I realized this might not be a good idea for ... | ### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's what happened in https://huggingface.co/datasets/mrdbourke/food_vision_199_classes/discussions/2#6385f... | 201 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails
### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's... |
https://github.com/huggingface/datasets/issues/7037 | A bug of Dataset.to_json() function | @albertvillanova I would like to take a shot at this if you aren't working on it currently. Let me know! | ### Describe the bug
When using the Dataset.to_json() function, an unexpected error occurs if the parameter is set to lines=False. The stored data should be in the form of a list, but it actually turns into multiple lists, which causes an error when reading the data again.
The reason is that to_json() writes to the f... | 20 | A bug of Dataset.to_json() function
### Describe the bug
When using the Dataset.to_json() function, an unexpected error occurs if the parameter is set to lines=False. The stored data should be in the form of a list, but it actually turns into multiple lists, which causes an error when reading the data again.
The reas... |
https://github.com/huggingface/datasets/issues/4697 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive | Hi @frgfm, thanks for reporting.
As the error message says, streaming mode is not supported out of the box when the dataset contains TAR archive files.
To make the dataset streamable, you have to use `dl_manager.iter_archive`.
There are several examples in other datasets, e.g. food101: https://huggingface.co/d... | ### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the second one, I'm having trouble with the preview since there is some archive... | 108 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive
### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the sec... |
https://github.com/huggingface/datasets/issues/4697 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive | Hi @albertvillanova :wave:
Thanks! Yeah I saw that but since I didn't have any metadata, I wasn't sure whether I should create them myself.
So one last question:
What is the metadata supposed to be for archives? The relative path of all files in it?
_(Sorry I'm a bit confused since it's quite hard to debug usin... | ### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the second one, I'm having trouble with the preview since there is some archive... | 67 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive
### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the sec... |
https://github.com/huggingface/datasets/issues/4697 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive | Hi @frgfm, streaming a dataset that contains a TAR file requires some tweaks because (contrary to ZIP files), tha TAR archive does not allow random access to any of the contained member files. Instead they have to be accessed sequentially (in the order in which they were put into the TAR file when created) and yielded.... | ### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the second one, I'm having trouble with the preview since there is some archive... | 357 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive
### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the sec... |
https://github.com/huggingface/datasets/issues/4697 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive | Hi @albertvillanova :wave:
Thanks, since my last message, I went through the repo of https://huggingface.co/datasets/food101/blob/main/food101.py and managed to get it to work in the end :pray:
Here it is: https://huggingface.co/datasets/frgfm/imagenette
I appreciate you opening an issue to document the proc... | ### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the second one, I'm having trouble with the preview since there is some archive... | 45 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive
### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the sec... |
https://github.com/huggingface/datasets/issues/4697 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive | Great to see that you manage to make your dataset streamable. :rocket:
I'm closing this issue, as for the docs update there is another issue opened:
- #4711 | ### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the second one, I'm having trouble with the preview since there is some archive... | 28 | Trouble with streaming frgfm/imagenette vision dataset with TAR archive
### Link
https://huggingface.co/datasets/frgfm/imagenette
### Description
Hello there :wave:
Thanks for the amazing work you've done with HF Datasets! I've just started playing with it, and managed to upload my first dataset. But for the sec... |
https://github.com/huggingface/datasets/issues/7468 | function `load_dataset` can't solve folder path with regex characters like "[]" | Hi ! Have you tried escaping the glob special characters `[` and `]` ?
btw note that`AbstractFileSystem.glob` doesn't support regex, instead it supports glob patterns as in the python library [glob](https://docs.python.org/3/library/glob.html)
| ### Describe the bug
When using the `load_dataset` function with a folder path containing regex special characters (such as "[]"), the issue occurs due to how the path is handled in the `resolve_pattern` function. This function passes the unprocessed path directly to `AbstractFileSystem.glob`, which supports regular e... | 31 | function `load_dataset` can't solve folder path with regex characters like "[]"
### Describe the bug
When using the `load_dataset` function with a folder path containing regex special characters (such as "[]"), the issue occurs due to how the path is handled in the `resolve_pattern` function. This function passes the... |
https://github.com/huggingface/datasets/issues/5574 | c4 dataset streaming fails with `FileNotFoundError` | Also encountering this issue for every dataset I try to stream! Installed datasets from main:
```
- `datasets` version: 2.10.1.dev0
- Platform: macOS-13.1-arm64-arm-64bit
- Python version: 3.9.13
- PyArrow version: 10.0.1
- Pandas version: 1.5.2
```
Repro:
```python
from datasets import load_dataset
spig... | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | 655 | c4 dataset streaming fails with `FileNotFoundError`
### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
... |
https://github.com/huggingface/datasets/issues/5574 | c4 dataset streaming fails with `FileNotFoundError` | This problem now appears again, this time with an underlying HTTP 502 status code:
```
aiohttp.client_exceptions.ClientResponseError: 502, message='Bad Gateway', url=URL('https://huggingface.co/datasets/allenai/c4/resolve/1ddc917116b730e1859edef32896ec5c16be51d0/en/c4-validation.00002-of-00008.json.gz')
``` | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | 21 | c4 dataset streaming fails with `FileNotFoundError`
### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
... |
https://github.com/huggingface/datasets/issues/5574 | c4 dataset streaming fails with `FileNotFoundError` | Re-executing a minute later, the underlying cause is an HTTP 403 status code, as reported yesterday:
```
aiohttp.client_exceptions.ClientResponseError: 403, message='Forbidden', url=URL('https://cdn-lfs.huggingface.co/datasets/allenai/c4/4bf6b248b0f910dcde2cdf2118d6369d8208c8f9515ec29ab73e531f380b18e2?response-cont... | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | 22 | c4 dataset streaming fails with `FileNotFoundError`
### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
... |
https://github.com/huggingface/datasets/issues/5574 | c4 dataset streaming fails with `FileNotFoundError` | > It's been resolved again ;)
I'm experiencing the same issue when trying to load this dataset, `FileNotFoundError: https://huggingface.co/datasets/allenai/c4/resolve/1ddc917116b730e1859edef32896ec5c16be51d0/realnewslike/c4-train.00000-of-00512.json.gz` | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | 19 | c4 dataset streaming fails with `FileNotFoundError`
### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
... |
https://github.com/huggingface/datasets/issues/5574 | c4 dataset streaming fails with `FileNotFoundError` | Experiencing the same issues as above : `FileNotFoundError: https://huggingface.co/datasets/allenai/c4/resolve/1ddc917116b730e1859edef32896ec5c16be51d0/en/c4-train.00000-of-01024.json.gz
If the repo is private or gated, make sure to log in with `huggingface-cli login`.`
Have made sure to login as well, issue persis... | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | 33 | c4 dataset streaming fails with `FileNotFoundError`
### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
... |
https://github.com/huggingface/datasets/issues/5574 | c4 dataset streaming fails with `FileNotFoundError` | > Experiencing the same issues as above : `FileNotFoundError: https://huggingface.co/datasets/allenai/c4/resolve/1ddc917116b730e1859edef32896ec5c16be51d0/en/c4-train.00000-of-01024.json.gz If the repo is private or gated, make sure to log in with `huggingface-cli login`.`
>
> Have made sure to login as well, issue p... | ### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("c4", "en", split="train", ... | 41 | c4 dataset streaming fails with `FileNotFoundError`
### Describe the bug
Loading the `c4` dataset in streaming mode with `load_dataset("c4", "en", split="validation", streaming=True)` and then using it fails with a `FileNotFoundException`.
### Steps to reproduce the bug
```python
from datasets import load_dataset
... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | Hi!
You want to use `push_to_hub` (creates Parquet files) instead of `save_to_disk` (creates Arrow files) when creating a Hub dataset. Parquet is designed for long-term storage and takes less space than the Arrow format, and, most importantly, `load_dataset` can parse it, which should fix the viewer.
Regarding ... | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 142 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | One issue here is that Dataset.from_generator can work well for the non 'infinite sampling' version of the dataset. The training set for example is often sampled dynamically given the video files that I have uploaded. I worry that storing the video data as binary means that I'll end up duplicating a lot of the data. Fu... | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 73 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | > storing video data as anything but .mp4
What I mean by storing as `datasets.Value("binary")` is embedding raw MP4 bytes in the Arrow table, but, indeed, this would waste a lot of space if there are duplicates.
So I see two options:
* if one video is not mapped to too many samples, you can embed the video bytes... | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 159 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | @mariosasko Right. If I want my dataset to be streamable, what are the necessary requirements to achieve that within the context of .mp4 binaries like we have here? I guess your second point here would not support that right? | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 39 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | The streaming would work, but the video paths would require using `fsspec.open` to get the content. | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 16 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | Not yet. The (open source) tooling for video is not great in terms of ease of use/performance, so we are discussing internally the best way to support it (one option is creating a new library for video IO, but this will require a lot of work) | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 46 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/5888 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset | True. I spend a good 4 months just mixing and matching existing solutions so I could get performance that would not IO bound my model training.
This is what I ended up with, in case it's useful
https://github.com/AntreasAntoniou/TALI/blob/045cf9e5aa75b1bf2c6d5351fb910fa10e3ff32c/tali/data/data_plus.py#L85 | **Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images, text, audio and video. Now, I could very easily upload a dataset made via datase... | 38 | A way to upload and visualize .mp4 files (millions of them) as part of a dataset
**Is your feature request related to a problem? Please describe.**
I recently chose to use huggingface hub as the home for a large multi modal dataset I've been building. https://huggingface.co/datasets/Antreas/TALI
It combines images,... |
https://github.com/huggingface/datasets/issues/6106 | load local json_file as dataset | Hi! We use PyArrow to read JSON files, and PyArrow doesn't allow different value types in the same column. #5776 should address this.
In the meantime, you can combine `Dataset.from_generator` with the above code to cast the values to the same type. | ### Describe the bug
I tried to load local json file as dataset but failed to parsing json file because some columns are 'float' type.
### Steps to reproduce the bug
1. load json file with certain columns are 'float' type. For example `data = load_data("json", data_files=JSON_PATH)`
2. Then, the error will be trigg... | 42 | load local json_file as dataset
### Describe the bug
I tried to load local json file as dataset but failed to parsing json file because some columns are 'float' type.
### Steps to reproduce the bug
1. load json file with certain columns are 'float' type. For example `data = load_data("json", data_files=JSON_PATH)`
... |
https://github.com/huggingface/datasets/issues/7599 | My already working dataset (when uploaded few months ago) now is ignoring metadata.jsonl | Maybe its been a recent update, but i can manage to load the metadata.jsonl separately from the images with:
```
metadata = load_dataset("PRAIG/SMB", split="train", data_files=["*.jsonl"])
images = load_dataset("PRAIG/SMB", split="train")
```
Do you know it this is an expected behaviour? This makes my dataset viewer t... | ### Describe the bug
Hi everyone, I uploaded my dataset https://huggingface.co/datasets/PRAIG/SMB a few months ago while I was waiting for a conference acceptance response. Without modifying anything in the dataset repository now the Dataset viewer is not rendering the metadata.jsonl annotations, neither it is being d... | 55 | My already working dataset (when uploaded few months ago) now is ignoring metadata.jsonl
### Describe the bug
Hi everyone, I uploaded my dataset https://huggingface.co/datasets/PRAIG/SMB a few months ago while I was waiting for a conference acceptance response. Without modifying anything in the dataset repository now ... |
https://github.com/huggingface/datasets/issues/7599 | My already working dataset (when uploaded few months ago) now is ignoring metadata.jsonl | Hi ! this is because we now expect the metadata file to be inside the directory named after the split "train" (this way each split can have its own metadata and can be loaded independently)
You can fix that by configuring it explicitly in the dataset's README.md header:
```yaml
configs:
- config_name: default
data_... | ### Describe the bug
Hi everyone, I uploaded my dataset https://huggingface.co/datasets/PRAIG/SMB a few months ago while I was waiting for a conference acceptance response. Without modifying anything in the dataset repository now the Dataset viewer is not rendering the metadata.jsonl annotations, neither it is being d... | 92 | My already working dataset (when uploaded few months ago) now is ignoring metadata.jsonl
### Describe the bug
Hi everyone, I uploaded my dataset https://huggingface.co/datasets/PRAIG/SMB a few months ago while I was waiting for a conference acceptance response. Without modifying anything in the dataset repository now ... |
https://github.com/huggingface/datasets/issues/5176 | prepare dataset for cloud storage doesn't work | It looks like an issue with `gcsfs`, are you able to instantiate a `GCSFileSystem` manually ? | ### Describe the bug
Following the [documentation](https://huggingface.co/docs/datasets/filesystems#load-and-save-your-datasets-using-your-cloud-storage-filesystem) and [this PR](https://github.com/huggingface/datasets/pull/4724), I was downloading and storing huggingface dataset to cloud storage.
```
from datasets ... | 16 | prepare dataset for cloud storage doesn't work
### Describe the bug
Following the [documentation](https://huggingface.co/docs/datasets/filesystems#load-and-save-your-datasets-using-your-cloud-storage-filesystem) and [this PR](https://github.com/huggingface/datasets/pull/4724), I was downloading and storing huggingface... |
https://github.com/huggingface/datasets/issues/7413 | Documentation on multiple media files of the same type with WebDataset | Yes this is correct and it works with huggingface datasets as well ! Feel free to include an example here: https://github.com/huggingface/datasets/blob/main/docs/source/video_dataset.mdx | The [current documentation](https://huggingface.co/docs/datasets/en/video_dataset) on a creating a video dataset includes only examples with one media file and one json. It would be useful to have examples where multiple files of the same type are included. For example, in a sign language dataset, you may have a base v... | 21 | Documentation on multiple media files of the same type with WebDataset
The [current documentation](https://huggingface.co/docs/datasets/en/video_dataset) on a creating a video dataset includes only examples with one media file and one json. It would be useful to have examples where multiple files of the same type are i... |
https://github.com/huggingface/datasets/issues/7529 | audio folder builder cannot detect custom split name | Hi! Triaging older issues — reproduced your behavior, but I think this is by design rather than a bug.
The folder-based builders (`audiofolder`/`imagefolder`/`videofolder`) auto-detect splits using a fixed keyword list (`train`, `validation`/`valid`/`val`/`dev`, `test`/`testing`/`eval`/`evaluation`) — see `SPLIT_KEYWO... | ### Describe the bug
when using audio folder builder (`load_dataset("audiofolder", data_dir="/path/to/folder")`), it cannot detect custom split name other than train/validation/test
### Steps to reproduce the bug
i have the following folder structure
```
my_dataset/
├── train/
│ ├── lorem.wav
│ ├── …
│ └── met... | 164 | audio folder builder cannot detect custom split name
### Describe the bug
when using audio folder builder (`load_dataset("audiofolder", data_dir="/path/to/folder")`), it cannot detect custom split name other than train/validation/test
### Steps to reproduce the bug
i have the following folder structure
```
my_datase... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.