

metadata
license: cc-by-nc-sa-4.0
language:
  - en
pretty_name: VideoMemBench
task_categories:
  - video-text-to-text
  - visual-question-answering
size_categories:
  - n<1K
tags:
  - video
  - multi-turn
  - memory
  - benchmark
configs:
  - config_name: default
    data_files:
      - split: test
        path: annotations.jsonl
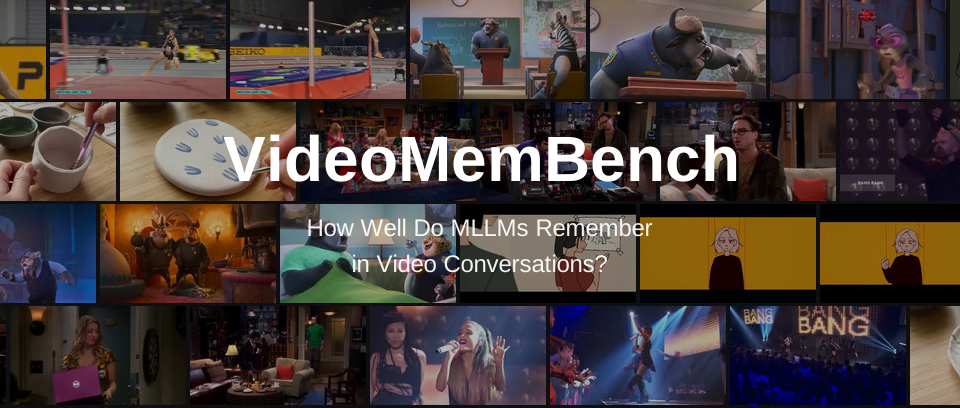
🎬 Benchmark
VideoMemBench evaluates in-context video memory: the ability to retrieve and reuse information established earlier in a multi-turn conversation about a video. Each sample pairs one video with an ordered dialogue, reference answers, and typed dependencies between turns.
- Episodic dependency: a later question revisits a visual episode, entity, or event established in an earlier turn.
- Answer dependency: a later question builds on an earlier answer, requiring information carried through the conversation.
Dependencies are checked for necessity and non-leakage, and answers must be visually grounded. A planner, generator, and judger construct and check dialogues, followed by human expert review. See the paper for construction and collection details.
🏆 Leaderboard
| Rank | Model | TurnAcc All turns |
EpiDepAcc Episodic dependency |
AnsDepAcc Answer dependency |
Overall ↓ Mean score |
|---|---|---|---|---|---|
| 1 |  Claude Opus 5 |
52.3 | 49.1 | 35.7 | 45.7 |
| 2 |  Gemini 3.8 Flash |
50.4 | 46.6 | 30.3 | 42.4 |
| 3 |  Kimi K3 |
50.5 | 49.0 | 27.1 | 42.2 |
| 4 |  GPT-5.6-sol |
50.0 | 47.8 | 27.1 | 41.7 |
| 5 | Gemini 3.5 Flash |
49.6 | 45.5 | 29.7 | 41.6 |
| 6 | GPT-5.5 |
48.0 | 46.5 | 27.0 | 40.5 |
| 7 | Claude Sonnet 5 |
47.8 | 45.3 | 27.3 | 40.2 |
| 8 | Gemini 3.1 Pro Preview |
45.7 | 44.8 | 27.0 | 39.1 |
| 9 | GPT-5.4 |
44.4 | 42.6 | 21.9 | 36.3 |
| 10 |  Qwen3-VL-235B-A22B |
43.1 | 41.6 | 18.6 | 34.4 |
| 11 | Qwen3.5-27B |
42.2 | 39.8 | 20.9 | 34.3 |
| 12 | Qwen3.5-397B-A17B |
42.3 | 40.1 | 20.3 | 34.2 |
| 13 | Qwen3.5-122B-A10B |
42.4 | 39.5 | 19.9 | 33.9 |
| 14 | Qwen3.5-35B-A3B |
38.2 | 36.3 | 18.0 | 30.8 |
| 15 | Qwen3-VL-32B |
39.3 | 35.9 | 17.2 | 30.8 |
| 16 | Qwen3-VL-30B-A3B |
36.4 | 35.1 | 15.8 | 29.1 |
| 17 | Qwen3.5-9B |
34.6 | 33.4 | 12.9 | 27.0 |
| 18 | Qwen3-VL-8B |
34.8 | 32.1 | 12.3 | 26.4 |
| 19 | Qwen3.5-4B |
33.8 | 32.6 | 12.5 | 26.3 |
| 20 | Qwen3-VL-4B |
32.4 | 29.4 | 12.9 | 24.9 |
| 21 | Qwen2.5-VL-32B |
31.7 | 32.6 | 9.6 | 24.6 |
| 22 | Qwen2.5-VL-7B |
26.2 | 24.9 | 8.4 | 19.8 |
| 23 |  Keye-VL-1.5-8B |
25.4 | 24.5 | 8.2 | 19.4 |
| 24 | Qwen2.5-VL-3B |
23.5 | 24.4 | 5.7 | 17.9 |
| 25 | Qwen3.5-0.8B |
21.6 | 21.3 | 5.7 | 16.2 |
🎞️ Evaluation with fewer frames
13 open-weight models evaluated with 64 or 32 fixed frames per video.
64 frames
| Rank | Model | TurnAcc All turns |
EpiDepAcc Episodic dependency |
AnsDepAcc Answer dependency |
Overall ↓ Mean score |
|---|---|---|---|---|---|
| 1 | Qwen3-VL-235B-A22B |
40.3 | 39.3 | 15.6 | 31.7 |
| 2 | Qwen3.5-122B-A10B |
37.8 | 36.5 | 15.2 | 29.8 |
| 3 | Qwen3.5-27B |
37.9 | 36.7 | 14.8 | 29.8 |
| 4 | Qwen3-VL-32B |
37.8 | 36.1 | 14.5 | 29.5 |
| 5 | Qwen3.5-35B-A3B |
37.0 | 36.7 | 13.5 | 29.1 |
| 6 | Qwen3-VL-30B-A3B |
33.6 | 32.9 | 11.5 | 26.0 |
| 7 | Qwen3-VL-8B |
32.7 | 32.0 | 11.9 | 25.5 |
| 8 | Qwen3.5-9B |
33.4 | 33.2 | 9.6 | 25.4 |
| 9 | Qwen3-VL-4B |
31.3 | 30.3 | 12.1 | 24.5 |
| 10 | Keye-VL-1.5-8B |
24.5 | 24.9 | 6.3 | 18.5 |
| 11 | Qwen2.5-VL-7B |
24.1 | 22.7 | 6.4 | 17.7 |
| 12 | Qwen2.5-VL-3B |
22.5 | 22.5 | 5.1 | 16.7 |
| 13 | Qwen3.5-0.8B |
21.0 | 21.1 | 4.7 | 15.6 |
32 frames
| Rank | Model | TurnAcc All turns |
EpiDepAcc Episodic dependency |
AnsDepAcc Answer dependency |
Overall ↓ Mean score |
|---|---|---|---|---|---|
| 1 | Qwen3-VL-235B-A22B |
36.3 | 37.8 | 14.5 | 29.5 |
| 2 | Qwen3.5-122B-A10B |
35.0 | 35.2 | 10.7 | 27.0 |
| 3 | Qwen3.5-35B-A3B |
34.5 | 34.1 | 12.3 | 27.0 |
| 4 | Qwen3.5-27B |
34.9 | 34.2 | 11.7 | 26.9 |
| 5 | Qwen3-VL-32B |
34.1 | 32.6 | 13.1 | 26.6 |
| 6 | Qwen3-VL-30B-A3B |
32.1 | 32.5 | 8.0 | 24.2 |
| 7 | Qwen3.5-9B |
29.8 | 30.4 | 8.6 | 22.9 |
| 8 | Qwen3-VL-8B |
29.4 | 29.4 | 9.2 | 22.7 |
| 9 | Qwen3-VL-4B |
29.0 | 29.0 | 8.8 | 22.3 |
| 10 | Qwen2.5-VL-7B |
23.2 | 23.7 | 4.9 | 17.3 |
| 11 | Keye-VL-1.5-8B |
23.3 | 23.1 | 5.1 | 17.2 |
| 12 | Qwen2.5-VL-3B |
22.6 | 23.4 | 4.7 | 16.9 |
| 13 | Qwen3.5-0.8B |
20.1 | 21.8 | 4.7 | 15.5 |
For download and evaluation instructions, see the GitHub documentation.
📜 License and terms of use
- Dataset annotations: CC BY-NC-SA 4.0.
- For non-commercial academic research and evaluation only. Not for model training.
- Source videos are not covered by this license; their original rights and terms apply.
📚 Citation
@misc{hu2026videomembenchmllmsremembervideo,
  title={VideoMemBench: How Well Do MLLMs Remember in Video Conversations?},
  author={Zhengdong Hu and Chao Wang and Kaituo Feng and Huanjin Yao and Mingfei Lu and Hehe Fan and Yi Yang},
  year={2026},
  eprint={2610.40131},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2610.40131},
}