
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
httpie/cli | python | 1,444 | Investigate increasing Maintainer Productivity with Pull Requests Environments | I would like to make life easier for HTTPie maintainers by implementing [Uffizzi](https://github.com/UffizziCloud/uffizzi)
previews.
Disclaimer: I work on [Uffizzi](https://github.com/UffizziCloud/uffizzi)
Uffizzi is a Open Source full stack previews engine and is completely free for HTTPie (and all open source p... | closed | 2022-10-24T06:30:56Z | 2024-10-30T10:53:39Z | https://github.com/httpie/cli/issues/1444 | [
"enhancement",
"new"
] | waveywaves | 1 |
Miksus/rocketry | pydantic | 165 | ENH: Add github actions for pylint | **Is your feature request related to a problem? Please describe.**
It'd be nice to gradually fix and turn on pylint errors (and maybe latest flake8/black checks). Having it as part of build CI/CD with github actions would help prevent increase of these.
**Describe the solution you'd like**
Add github actions for ... | open | 2022-12-01T22:50:19Z | 2022-12-12T11:02:44Z | https://github.com/Miksus/rocketry/issues/165 | [
"enhancement"
] | marksmayo | 1 |
pytorch/vision | machine-learning | 8,104 | Scheduled workflow failed | Oh no, something went wrong in the scheduled workflow tests/download.
Please look into it:
https://github.com/pytorch/vision/actions/runs/6795955113
Feel free to close this if this was just a one-off error.
cc @pmeier | closed | 2023-11-08T09:04:42Z | 2023-11-09T11:13:57Z | https://github.com/pytorch/vision/issues/8104 | [
"bug",
"module: datasets"
] | github-actions[bot] | 0 |
MagicStack/asyncpg | asyncio | 1,108 | Document how to confirm that `INSERT` worked with prepared statement |
When using `execute()` I can parse the [command output for INSERT](https://www.postgresql.org/docs/current/sql-insert.html) to confirm a single row inserted like `INSERT 0 1`. However, `execute()` does not support the LRU for automatically prepared statements. Can you document how to confirm that the `INSERT` worked ... | open | 2023-11-21T06:59:48Z | 2023-11-21T08:05:37Z | https://github.com/MagicStack/asyncpg/issues/1108 | [] | mbrancato | 2 |
pydata/xarray | numpy | 9,349 | Datatree: API for collapsing subtrees | ### What is your issue?
_Originally posted by @TomNicholas in https://github.com/xarray-contrib/datatree/issues/192_
Multiple people have requested methods for collapsing children or subtrees into single nodes.
Following on from [our discourse discussion](https://discourse.pangeo.io/t/xarray-and-collections-of-f... | open | 2024-08-13T16:28:23Z | 2024-08-13T16:28:23Z | https://github.com/pydata/xarray/issues/9349 | [
"topic-DataTree"
] | flamingbear | 0 |
pyppeteer/pyppeteer | automation | 89 | future: <Future finished exception=NetworkError('Protocol error (Target.detachFromTarget): No session with given id')> | * sometimes application throws the following exception, How to handle and avoid such exceptions. and what are the causes that are making an exception?
```
Future exception was never retrieved
future: <Future finished exception=NetworkError('Protocol error (Target.detachFromTarget): No session with given id')>
pyp... | closed | 2020-04-20T22:48:20Z | 2020-04-21T02:03:32Z | https://github.com/pyppeteer/pyppeteer/issues/89 | [
"fixed-in-2.1.1"
] | arbazkiraak | 2 |
plotly/dash-table | dash | 365 | Tooltips are positioned incorrectly with fixed rows and/or columns | closed | 2019-02-07T18:24:23Z | 2019-02-07T23:45:24Z | https://github.com/plotly/dash-table/issues/365 | [
"dash-type-bug"
] | Marc-Andre-Rivet | 0 | |
supabase/supabase-py | fastapi | 618 | Need to access private schemas through Client | **Describe the bug**
I'm currently using https://supabase.com/docs/reference/python/start , service api , the data is not from a user, i basically just need to add data into the database for users. I've also added private to Exposed schemas and don't know if that's the best idea, basically all my data live inside priv... | closed | 2023-11-20T10:29:12Z | 2023-12-01T08:39:50Z | https://github.com/supabase/supabase-py/issues/618 | [] | JohnDotOwl | 2 |
httpie/cli | rest-api | 609 | timeout < 30 only? | I am setting timeout to 300 seconds (to test an AWS lambda function + API Gateway), but HTTPie continues to timeout at 30 seconds. Is there an upper limit set at 30 seconds? I'´m using
`http --timeout=300 POST https://...` | closed | 2017-09-11T13:29:07Z | 2019-08-30T12:23:52Z | https://github.com/httpie/cli/issues/609 | [] | pyvotal-cguers | 5 |
ets-labs/python-dependency-injector | asyncio | 745 | The library can't handle async generators | Based on the example [FastAPI + SQLAlchemy example](https://python-dependency-injector.ets-labs.org/examples/fastapi-sqlalchemy.html) from the documentation i made a myself implementation for work with connections of Async SQLA Core. But I came across the fact that your library does not support working with asynchronou... | open | 2023-09-14T22:30:53Z | 2025-03-09T08:05:48Z | https://github.com/ets-labs/python-dependency-injector/issues/745 | [
"feature"
] | alexted | 16 |
sqlalchemy/alembic | sqlalchemy | 599 | Detect whether Alembic is running | I have a couple of event listeners configured for SQLAlchemy but I don't want to be them running during Alembic operations. I tried to put environment variable within `env.py` and use it when registering SA hooks but `env.py` runs after it. How can I properly detect whether Alembic is running and not register SA hooks?... | closed | 2019-09-03T12:13:54Z | 2019-09-13T10:46:33Z | https://github.com/sqlalchemy/alembic/issues/599 | [
"question"
] | decaz | 5 |
hankcs/HanLP | nlp | 1,285 | 同一个词在不同的句子中分词结果不一致 | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2019-09-22T08:21:41Z | 2020-01-01T10:48:39Z | https://github.com/hankcs/HanLP/issues/1285 | [
"ignored"
] | lxw0109 | 2 |
jupyterlab/jupyter-ai | jupyter | 1,126 | Use the magic command in the cell to specify the base API URL | <!-- Welcome! Thank you for contributing. These HTML comments will not render in the issue.
Before creating a new issue:
* Search for relevant issues
* Follow the issue reporting guidelines:
https://jupyterlab.readthedocs.io/en/latest/getting_started/issue.html
-->
## Description
code:
%%ai chatgpt
hello
... | open | 2024-11-28T07:28:47Z | 2024-11-28T07:29:37Z | https://github.com/jupyterlab/jupyter-ai/issues/1126 | [
"bug"
] | tanzf123 | 1 |
JaidedAI/EasyOCR | pytorch | 1,300 | [BUG] Resize operation in CRAFT post processing | This PR: https://github.com/JaidedAI/EasyOCR/pull/1050 modifies the interpolation to use `Image.Resampling.LANCZOS`
Although the resize happens using `cv2.resize` which does not treat it as `LANCZOS` rather the enum evaluates to constant `1` which is `CV_INTER_LINEAR`
https://github.com/npinto/opencv/blob/master/... | open | 2024-08-31T07:22:52Z | 2024-08-31T07:22:52Z | https://github.com/JaidedAI/EasyOCR/issues/1300 | [] | ash2703 | 0 |
matterport/Mask_RCNN | tensorflow | 2,643 | model.detect - set confidence threshold while running inference | How can I set the confidence threshold for the inference module?
I am using the `detect` function in the `model` module and want to set a lower confidence. Where can I do that?
| closed | 2021-07-22T05:17:31Z | 2021-07-22T06:44:58Z | https://github.com/matterport/Mask_RCNN/issues/2643 | [] | mansi-aggarwal-2504 | 0 |
pydantic/pydantic-core | pydantic | 945 | After upgrading pydantic-core from 2.6.3 -> 2.7.0, pydantic wont work anymore | 
Error Log:
> Traceback (most recent call last):
> File "C:\Users\guita\Documents\dev\SwarmIntelligence Project\SwarmIntelligenceBackend\main.py", line 5, in <module>
> from fastapi import FastAPI
> ... | closed | 2023-09-05T00:09:35Z | 2023-09-05T10:53:28Z | https://github.com/pydantic/pydantic-core/issues/945 | [
"unconfirmed"
] | Raphael2b3 | 2 |
blacklanternsecurity/bbot | automation | 1,451 | Don't Increment Scope Distance for Hostless Events | Events without hosts associated with them, such as `FILESYSTEM`, should probably not have their scope distance incremented. | closed | 2024-06-12T13:12:11Z | 2024-08-02T14:54:18Z | https://github.com/blacklanternsecurity/bbot/issues/1451 | [
"enhancement"
] | TheTechromancer | 6 |
NullArray/AutoSploit | automation | 1,244 | Running Autosploit | Hi
I have installed autosploit but when I run
python2 autosploit.py -C msf "my ip" 4444 -e
it just says "Executing command 'python2 autosploit.py -C msf "my ip" 4444 -e'" and doesn't return any output
At this point I haven't included any shodan/censys key. Im trying it with another PC at home and Im using... | open | 2020-02-10T19:52:41Z | 2020-03-21T21:09:28Z | https://github.com/NullArray/AutoSploit/issues/1244 | [
"need-more-info"
] | ampf27 | 1 |
cvat-ai/cvat | computer-vision | 8,530 | Issue with Loading Larger Video Jobs | I am currently running the docker version of CVAT. Everything works great. I am able to load videos of 200 frames easily. Now I have the problem that I want to annotate a video with around 70 000 frames. Whenever I try to load the job I get the following error after around a minute of loading:
', 'vacuuming floor'). Two video files were downloaded but the program crashed later on because of a key error 'clay pottery making'
### Code to reproduce issue
```
im... | open | 2025-01-10T20:03:39Z | 2025-01-10T20:04:03Z | https://github.com/voxel51/fiftyone/issues/5372 | [
"bug"
] | ChystovaK | 0 |
QingdaoU/OnlineJudge | django | 149 | How to add more language support, such as Ruby | Beside of C, C++, Java, ... I want to add more language support such as Ruby or Javascript
Could you please tell me how to do that ? what module should I change or update? | closed | 2018-05-15T04:05:15Z | 2018-06-28T06:03:34Z | https://github.com/QingdaoU/OnlineJudge/issues/149 | [] | anonymept | 4 |
Lightning-AI/pytorch-lightning | deep-learning | 19,907 | I think it's deadly necessary to add docs or tutorials for handling the case when We return multiple loaders in test_dataloaders() method? I think it | ### 📚 Documentation
I know that LightningDataModule supports return multiple dataloaders ,like list of dataloaders, or dict of dataloaders in LightningDataModule. But how to handle the test in LightningModule?
We always need print respective information of the computation upon each test_loader, and save the figs d... | open | 2024-05-25T11:01:27Z | 2024-05-25T11:01:48Z | https://github.com/Lightning-AI/pytorch-lightning/issues/19907 | [
"docs",
"needs triage"
] | onbigion13 | 0 |
vllm-project/vllm | pytorch | 14,808 | [Usage]: how to reduce the number of processes of compile_worker | ### Your current environment
vllm: 0.7.3
`vllm serve Qwen/Qwen2.5-7B-Instruct --host 0.0.0.0 --port 6015 --disable-log-requests --max_num_seqs=200 --max_num_batched_tokens=256 -tp=4 --served-model-name Qwen2.5-7B-Instruct --max_model_len=4096 --block-size=16 --gpu-memory-utilization=0.3 --uvicorn-log-level=warning --d... | open | 2025-03-14T08:33:36Z | 2025-03-22T02:39:35Z | https://github.com/vllm-project/vllm/issues/14808 | [
"usage"
] | FanYaning | 4 |
pandas-dev/pandas | data-science | 60,560 | BUG: inconsistent return types from __getitem__ vs iteration | ### Pandas version checks
- [X] I have checked that this issue has not already been reported.
- [X] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [X] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/dev/ge... | open | 2024-12-13T16:17:51Z | 2025-02-11T23:54:01Z | https://github.com/pandas-dev/pandas/issues/60560 | [
"Bug",
"Needs Discussion",
"API - Consistency"
] | gboeing | 6 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 1,143 | Difference between --model pix2pix, --model test and --eval when inference | What options are recommended for the test script if I want to generate images using pix2pix? Thanks | closed | 2020-09-08T01:33:37Z | 2020-09-14T12:22:57Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1143 | [] | Liyw979 | 2 |
mitmproxy/pdoc | api | 595 | Disable "Ancestors" for only Certain Classes | I am generating PDoc documents for a few enum classes. I do not want to include the "Ancestors (in MRO)" output for enum classes, since its clearly an enum.
The recommended way to do this is:
```
{% extends "default/module.html.jinja2" %}
{% block inherited_members scoped %}{% endblock %}
```
However, this wo... | closed | 2023-07-27T00:41:49Z | 2023-08-09T08:27:13Z | https://github.com/mitmproxy/pdoc/issues/595 | [
"enhancement"
] | lgnashold | 1 |
onnx/onnx | machine-learning | 6,133 | the model for UniqueOp in backend test is not always correct for different input | # Bug Report
### Is the issue related to model conversion?
<!-- If the ONNX checker reports issues with this model then this is most probably related to the converter used to convert the original framework model to ONNX. Please create this bug in the appropriate converter's GitHub repo (pytorch, tensorflow-onnx, sk... | open | 2024-05-08T18:59:14Z | 2024-05-08T19:01:43Z | https://github.com/onnx/onnx/issues/6133 | [
"bug"
] | chentong319 | 0 |
browser-use/browser-use | python | 1,061 | langgraph compatibility | ### Type of Documentation Issue
Missing documentation
### Documentation Page
not sure
### Issue Description
Hi,
I'd like to put a browser use agent in a langgraph swarm setup. In order to do this, I think I basically need to wrap it as a react agent with langgraph `create_react_agent`. Is it possible to expose th... | open | 2025-03-18T17:52:42Z | 2025-03-18T17:52:42Z | https://github.com/browser-use/browser-use/issues/1061 | [
"documentation"
] | austinmw | 0 |
plotly/dash | data-science | 2,921 | Compiling a Plotly Dash app with Nuitka the Python Compiler [Feature Request] | I would like to ask for help regarding the [issue](https://github.com/Nuitka/Nuitka/issues/2988). This issue results in a Plotly Dash app compiled with [Nuitka ](https://nuitka.net/) crushing with "OSError: could not get source code". I got a response from one of the Nuitka maintainers asking for help: [https://github.... | closed | 2024-07-14T22:38:09Z | 2024-07-15T13:54:32Z | https://github.com/plotly/dash/issues/2921 | [] | dmitrii-erkin | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 850 | What is the role of ImagePool | Hi, I am wondering what sense does 'ImagePool' make? Does it favor the training of D?
| open | 2019-11-19T13:16:52Z | 2019-11-19T13:16:52Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/850 | [] | daifeng2016 | 0 |
babysor/MockingBird | pytorch | 145 | 选择加载本地录音文件m4a报错,请问是什么原因 | Traceback (most recent call last):
File "D:\software\Anaconda3\envs\pytorch\lib\site-packages\librosa\core\audio.py", line 149, in load
with sf.SoundFile(path) as sf_desc:
File "D:\software\Anaconda3\envs\pytorch\lib\site-packages\soundfile.py", line 629, in __init__
self._file = self._open(file, mode_i... | open | 2021-10-13T19:27:40Z | 2021-10-27T14:13:59Z | https://github.com/babysor/MockingBird/issues/145 | [] | zyyzyx | 1 |
onnx/onnx | scikit-learn | 6,090 | Is there a way to swap a set of parameters inside of an .onnx / .ort graph with an identically shaped set of parameters? | # Ask a Question
### Question
I want to be able to swap params at inference time to facilitate a LoRA deployment.
Eg. in torch, I could do
```python
class myModel(nn.Module):
def __init__(self):
super().__init__()
self.linear = nn.Linear(4,8)
self.act = nn.Sigmoid()
d... | closed | 2024-04-18T17:33:47Z | 2024-06-21T18:44:47Z | https://github.com/onnx/onnx/issues/6090 | [
"question"
] | jakemdaly | 8 |
HumanSignal/labelImg | deep-learning | 868 | data augmentation after label images |
Hi, i labeled some images, but i would like to do some data augmentation and save images with the new augmented data, can you help me, please
| open | 2022-04-27T21:11:00Z | 2022-04-27T21:11:35Z | https://github.com/HumanSignal/labelImg/issues/868 | [] | epenaintecol | 0 |
huggingface/datasets | deep-learning | 7,471 | Adding argument to `_get_data_files_patterns` | ### Feature request
How about adding if the user already know about the pattern?
https://github.com/huggingface/datasets/blob/a256b85cbc67aa3f0e75d32d6586afc507cf535b/src/datasets/data_files.py#L252
### Motivation
While using this load_dataset people might use 10M of images for the local files.
However, due to sear... | open | 2025-03-21T07:17:53Z | 2025-03-21T07:17:53Z | https://github.com/huggingface/datasets/issues/7471 | [
"enhancement"
] | SangbumChoi | 0 |
ets-labs/python-dependency-injector | asyncio | 608 | Wiring: closures introspection | Wiring can potentially introspect closures which can help on the way of making ``@inject`` unnecessary | open | 2022-07-17T01:21:38Z | 2022-07-27T01:44:38Z | https://github.com/ets-labs/python-dependency-injector/issues/608 | [
"feature",
"research",
"help appreciated"
] | rmk135 | 1 |
robotframework/robotframework | automation | 5,371 | Profile memory usage | I have got simple test (with LOOP to reproduce my problem):
```
*** Test Cases ***
Mem Leak
Log Start Sleep ... console=${True}
Sleep 3s
${l} = Create List
FOR ${i} IN RANGE ${30000}
${a} = Set Variable XXX
END
Log End Test ... console=${True}
Sleep 3s
```
I see that robo... | open | 2025-03-18T06:03:18Z | 2025-03-21T14:12:44Z | https://github.com/robotframework/robotframework/issues/5371 | [
"priority: medium",
"effort: medium"
] | silent-nekto | 3 |
microsoft/nni | tensorflow | 5,582 | from nni_assets.compression.mobilenetv2 import MobileNetV2 not found | I follow the docs from https://nni.readthedocs.io/en/latest/tutorials/quantization_speedup.html. I installed the NNI from source, master branch. mobilenetv2 was not listed in https://github.com/microsoft/nni/tree/master/nni_assets)
/compression/. | open | 2023-05-26T08:08:10Z | 2023-05-29T02:29:54Z | https://github.com/microsoft/nni/issues/5582 | [] | aininot260 | 0 |
holoviz/panel | plotly | 6,854 | Landuse classification example error | I am trying to reproduce the example at
https://examples.holoviz.org/gallery/landuse_classification/Image_Classification.html
#### ALL software version info
bokeh=3.4.1=pyhd8ed1ab_0
holoviews=1.18.3=pyhd8ed1ab_0
hvplot=0.10.0=pyhd8ed1ab_0
intake=2.0.5=pyhd8ed1ab_0
intake-xarray=0.7.0=pyhd8ed1ab_0
jupyterlab... | open | 2024-05-20T21:05:12Z | 2024-05-21T21:22:50Z | https://github.com/holoviz/panel/issues/6854 | [] | ials | 4 |
deepspeedai/DeepSpeed | deep-learning | 6,914 | Train batch size errors | [rank0]: AssertionError: Check batch related parameters. train_batch_size is not equal to micro_batch_per_gpu * gradient_acc_step * world_size 8 != 2 * 1 * 1
在前面的dist.world_size打印获取=4,但是依然不行 | closed | 2024-12-25T09:56:11Z | 2025-01-24T15:53:18Z | https://github.com/deepspeedai/DeepSpeed/issues/6914 | [] | lckkkk02 | 4 |
microsoft/qlib | deep-learning | 1,748 | US 1min Data 404 Client Error | ## ❓ Questions and Help
We sincerely suggest you to carefully read the [documentation](http://qlib.readthedocs.io/) of our library as well as the official [paper](https://arxiv.org/abs/2009.11189). After that, if you still feel puzzled, please describe the question clearly under this issue.
Hi, I tried to downloa... | closed | 2024-02-20T20:51:37Z | 2025-02-18T03:21:20Z | https://github.com/microsoft/qlib/issues/1748 | [
"question"
] | l0ngc | 5 |
roboflow/supervision | computer-vision | 1,269 | Trigger when detection lost | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Question
I use supervision for visitor counting inside specific area.
The whole system was running well except for one area only (let's call it area X).... | closed | 2024-06-07T05:59:41Z | 2024-06-11T12:38:46Z | https://github.com/roboflow/supervision/issues/1269 | [
"question"
] | wong-kene | 4 |
microsoft/nni | machine-learning | 5,418 | RuntimeError: NNI manager closed connection | <!--
Here is an issue template for NNI student program China. You are encouraged to raise concerns about any issue and share your ideas of NNI or our student program. Both Chinese and English are acceptable.
If it is a general question / idea of NNI, you could just make a short summary.
If it is a op... | open | 2023-03-02T17:43:54Z | 2023-03-20T01:14:27Z | https://github.com/microsoft/nni/issues/5418 | [] | szhang963 | 4 |
ansible/awx | django | 15,402 | Missing update function for AWX CLI for constructed inventory | ### Please confirm the following
- [X] I agree to follow this project's [code of conduct](https://docs.ansible.com/ansible/latest/community/code_of_conduct.html).
- [X] I have checked the [current issues](https://github.com/ansible/awx/issues) for duplicates.
- [X] I understand that AWX is open source software pro... | open | 2024-07-26T15:59:18Z | 2024-08-02T17:48:00Z | https://github.com/ansible/awx/issues/15402 | [
"type:bug",
"component:api",
"component:ui",
"needs_triage",
"community"
] | kalpanachinnappan | 0 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 752 | stuck at encoder | when i try to record my voice every thing goes well untill it says "loading the encoder encoder\saved_models\pretrained.pt" the path is C:\Users\ytty\OneDrive\Bureaublad\voice clone\Real-Time_Voice_Cloning\Real-Time-Voice-Cloning-master\encoder\saved_models, how can this be fixed? (says SV2TTS is not responding) | closed | 2021-05-11T07:03:09Z | 2021-05-30T07:44:16Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/752 | [] | ytty-tyyt | 1 |
waditu/tushare | pandas | 975 | 复权与非复权k线数据的返回结构不一致 | 主体数据没问题,但以split方式存储数据时,会发现未复权的数据,index是序号(好像是这两天刚发生的变动),而复权的数据,index是日期(与以前一样)
可以比较如下语句:
df = ts.pro_bar(pro_api=pro, ts_code='600695', freq='D', start_date='20170101', end_date='20190315')
df.to_json(file, orient='split', force_ascii='false')
df = ts.pro_bar(pro_api=pro, ts_code='600695', adj='qfq', freq='D', st... | closed | 2019-03-23T02:52:33Z | 2019-03-25T13:08:05Z | https://github.com/waditu/tushare/issues/975 | [] | shellinger | 1 |
huggingface/transformers | machine-learning | 36,015 | Idefics2 model seems to ignore the user textual prompt | ### System Info
- `transformers` version: 4.46.3
- Platform: Linux-4.18.0-477.27.1.el8_8.x86_64-x86_64-with-glibc2.28
- Python version: 3.12.7
- Huggingface_hub version: 0.24.6
- Safetensors version: 0.4.5
- Accelerate version: not installed
- Accelerate config: not found
- PyTorch version (GPU?): 2.5.1 (True)
- Tenso... | closed | 2025-02-03T14:07:36Z | 2025-02-04T10:47:12Z | https://github.com/huggingface/transformers/issues/36015 | [
"bug"
] | jlmeunier | 5 |
pyg-team/pytorch_geometric | deep-learning | 9,212 | Graph loader (NeighborLoader, HGTLoader, etc) mysteriously crash on RCDD dataset | ### 🐛 Describe the bug
I am trying to use the newly incorporated dataset `RCDD` since PyG 2.5. However, when I try to feed the dataset into heterogeneous graph loader, such as `NeighborLoader` or `HGTLoader`, both of them mysteriously crash and complain "Segmentation Fault".
You can reproduce it using:
```python... | closed | 2024-04-17T21:10:17Z | 2024-04-26T12:09:44Z | https://github.com/pyg-team/pytorch_geometric/issues/9212 | [
"bug"
] | junhongmit | 4 |
d2l-ai/d2l-en | tensorflow | 2,020 | [PyTorch] Porting Chapter Recommender Systems | Currently, the only missing chapter in the PyTorch port of the book is [Recommender Systems](https://d2l.ai/chapter_recommender-systems/index.html). Given the number of requests that we have been receiving regarding this section, and rising interest among readers, this is a good time to add PyTorch support.
This Iss... | open | 2022-01-24T02:17:14Z | 2023-11-02T15:59:13Z | https://github.com/d2l-ai/d2l-en/issues/2020 | [
"enhancement",
"pytorch-adapt-track"
] | AnirudhDagar | 8 |
dynaconf/dynaconf | flask | 681 | Parameters passing order, while configuring Dynaconf | Why environment variables is more important than explicit class parameters, if I use both of type configuration of Dynaconf.
For example, if I enabled the export ENVIRONMENTS_FOR_DYNACONF=true, than the Dynaconf(environments=False) is ignored | open | 2021-10-18T07:23:19Z | 2022-09-21T17:09:55Z | https://github.com/dynaconf/dynaconf/issues/681 | [
"hacktoberfest",
"RFC"
] | shvilime | 1 |
neuml/txtai | nlp | 811 | Add agents example notebook | Add notebook covering txtai agents | closed | 2024-11-17T11:43:01Z | 2024-11-18T18:29:21Z | https://github.com/neuml/txtai/issues/811 | [] | davidmezzetti | 0 |
mljar/mljar-supervised | scikit-learn | 636 | switch off shap exceptions printouts | closed | 2023-07-06T13:19:07Z | 2023-07-06T13:20:56Z | https://github.com/mljar/mljar-supervised/issues/636 | [] | pplonski | 1 | |
opengeos/streamlit-geospatial | streamlit | 118 | None of the apps are opening on the website | I get an error on every app I select, the error looks like the following:
"Oh no.
Error running app. If this keeps happening, please [contact support](https://github.com/giswqs/streamlit-geospatial/issues/new)." | closed | 2023-04-21T21:15:59Z | 2024-01-29T13:17:22Z | https://github.com/opengeos/streamlit-geospatial/issues/118 | [] | priyapatel1 | 2 |
arnaudmiribel/streamlit-extras | streamlit | 215 | "add_vertical_space" is not accessed | ### Description
I can't access to "add_vertical_space" and it is not shown between the methods that I can use.

, I got this when I try to load cached dataset.
```
Traceback (most recent call last): ... | closed | 2024-11-13T06:27:24Z | 2024-11-28T10:55:17Z | https://github.com/pytorch/vision/issues/8726 | [] | Met4physics | 2 |
scikit-optimize/scikit-optimize | scikit-learn | 338 | Default base_estimator for Optimizer | Currently, the constructor of `Optimizer` expects `base_estimator`.
It would be a good default I think to have the same GaussianProcessRegressor as in `gp_minimize` when `base_estimator=None`.
(Reproducing that logic is not trivial for the user, hence that would be a nice shortcut.) | closed | 2017-04-03T10:47:35Z | 2017-06-26T10:08:20Z | https://github.com/scikit-optimize/scikit-optimize/issues/338 | [
"API",
"Easy"
] | glouppe | 0 |
plotly/dash | data-visualization | 2,986 | [REGRESSION] Number of no_output must match number of outputs in dash==2.18.0 | In `dash==2.18.0`, the number of `no_update ` returned must match the number of outputs. This is not true in earlier versions of Dash.
This can be resolved by making `no_update` match but is a regression.
Consider:
```python
import dash
from dash import html, dcc, Input, Output, no_update
# Initialize the D... | closed | 2024-09-05T17:39:04Z | 2024-09-17T13:53:23Z | https://github.com/plotly/dash/issues/2986 | [
"regression",
"bug",
"P1"
] | ndrezn | 4 |
plotly/plotly.py | plotly | 4,363 | DatetimeProperties.to_pydatetime is deprecated | /Library/Frameworks/Python.framework/Versions/3.11/lib/python3.11/site-packages/_plotly_utils/basevalidators.py:105: FutureWarning:
The behavior of DatetimeProperties.to_pydatetime is deprecated, in a future version this will return a Series containing python datetime objects instead of an ndarray. To retain the old... | closed | 2023-09-17T16:40:09Z | 2023-10-12T17:19:42Z | https://github.com/plotly/plotly.py/issues/4363 | [] | VelizarVESSELINOV | 8 |
vimalloc/flask-jwt-extended | flask | 52 | Support two simultaneous token configs | This is the situation:
- Users are authenticated via httpOnly JWT cookies with double submit csrf cookies (refresh tokens as well).
- API clients use Authorization bearer tokens with IP whitelisting and no CSRF tokens (limited scope of operations, public API etc). The bearer token is sent to the API as JSON payload a... | closed | 2017-06-07T04:28:04Z | 2017-06-14T23:41:19Z | https://github.com/vimalloc/flask-jwt-extended/issues/52 | [] | edv4rd0 | 10 |
dmlc/gluon-nlp | numpy | 1,243 | [Numpy Refactor] [Installation] Add Official Dockerfile support | As in AllenNLP, the user is able to build the docker: https://github.com/allenai/allennlp/#installing-using-docker
We should offer something similar to the user. | closed | 2020-06-10T07:36:19Z | 2020-08-20T16:23:41Z | https://github.com/dmlc/gluon-nlp/issues/1243 | [
"enhancement",
"numpyrefactor"
] | sxjscience | 2 |
aiortc/aiortc | asyncio | 785 | aiortc with OpenCV imshow | Hey guys, im having the same issue!
### Discussed in https://github.com/aiortc/aiortc/discussions/734
<div type='discussions-op-text'>
<sup>Originally posted by **ahmadmughees** June 6, 2022</sup>
Hi, Thanks for amazing framework,
I just encounter a bug when using aiortc and OpenCV imshow fuction.
Wh... | closed | 2022-10-20T16:21:23Z | 2023-01-22T20:18:28Z | https://github.com/aiortc/aiortc/issues/785 | [] | praveenVnktsh | 2 |
litl/backoff | asyncio | 145 | [Feature Suggestion] - Exception in _call_handlers | Would be great to know which exception was thrown in handlers from decorator exception tuple in `backoff.on_exception`. Maybe receive exception as extra kwargs in _call_handlers. What you guys think?
| closed | 2021-12-08T21:57:25Z | 2022-10-05T14:30:03Z | https://github.com/litl/backoff/issues/145 | [] | philliparente | 1 |
graphql-python/graphene-django | graphql | 1,324 | Dead Project? | It looks like there hasn't been a release in over a year and a half. Is there an active maintainer anymore? | closed | 2022-05-28T18:30:07Z | 2022-09-23T22:49:42Z | https://github.com/graphql-python/graphene-django/issues/1324 | [
"🐛bug"
] | robd003 | 8 |
ageitgey/face_recognition | machine-learning | 1,156 | returned location coordinates ordering (y1, x2, y2, x1) | * face_recognition version: 1.2.3
* Python version: 3.8.2
* Operating System: Ubuntu 16.04
### Description
I'm trying to take the union of two face detection modules (one is face_recognition).
But the locations coordinates of the faces are different from the other module's coordinates.
face_recognition loc... | open | 2020-06-10T14:45:55Z | 2021-04-29T22:32:27Z | https://github.com/ageitgey/face_recognition/issues/1156 | [] | salelkafrawy | 1 |
AirtestProject/Airtest | automation | 724 | py脚本打包成exe后运行不了 | (请尽量按照下面提示内容填写,有助于我们快速定位和解决问题,感谢配合。否则直接关闭。)
**(重要!问题分类)**
* 测试开发环境AirtestIDE使用问题 -> https://github.com/AirtestProject/AirtestIDE/issues
**描述问题bug**
(简洁清晰得概括一下遇到的问题是什么。或者是报错的traceback信息。)
将py程序,用pyinstaller打包成exe进行直接执行
程序用到的包,和运行情况如图显示(已经在执行路径下放了adb.exe)

However such features are not compatible with Features.encode_example/decode_example if they require special encoding / decoding logic because encod... | open | 2024-10-11T19:20:11Z | 2024-11-08T15:10:58Z | https://github.com/huggingface/datasets/issues/7220 | [] | alex-hh | 2 |
gradio-app/gradio | data-visualization | 9,951 | `example_labels` does not work for ChatInterface | ### Describe the bug
Based on the screenshot, when using `additional_inputs` in ChatInterface and providing example prompts, you must manually include default values for these additional inputs in the examples; otherwise, they will be set to `None`. However, I dislike the examples being displayed beneath the chatbot a... | closed | 2024-11-13T09:42:15Z | 2024-11-20T20:58:01Z | https://github.com/gradio-app/gradio/issues/9951 | [
"bug"
] | jamie0725 | 4 |
CorentinJ/Real-Time-Voice-Cloning | tensorflow | 641 | Failed to load the native TensorFlow runtime. | I have been trying to set this Voice Cloning up for a while and I get this error: `Failed to load the native TensorFlow runtime.` I am using Windows, and I set up a virtual environment on Anaconda. This error comes with `ImportError: DLL load failed: A dynamic link library (DLL) initialization routine failed.` I have i... | closed | 2021-01-24T05:35:22Z | 2021-01-24T21:23:15Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/641 | [] | Dezlite | 6 |
babysor/MockingBird | pytorch | 840 | 训练到 640k就自动停止了,从新开始也会自动停止 | 下面是开始训练的信息。程序跑了几天,跑到640k以后就自动停止了。从新开始就出现下面的信息,然后又自动停止了。
是需要在哪里改 epoch 总数吗?
python synthesizer_train.py lu ./dataset/SV2TTS/synthesizer
Arguments:
run_id: lu
syn_dir: ./dataset/SV2TTS/synthesizer
models_dir: synthesizer/saved_models/
save_every: 1000
backup_ever... | closed | 2023-02-27T02:29:31Z | 2023-03-29T13:36:24Z | https://github.com/babysor/MockingBird/issues/840 | [] | ttkrpink | 2 |
omar2535/GraphQLer | graphql | 12 | Add unit testing framework | - Add a unit testing framework
- Make GitHub actions run unit tests on every PR & push | closed | 2021-11-30T07:59:53Z | 2021-12-10T00:34:19Z | https://github.com/omar2535/GraphQLer/issues/12 | [
"➕enhancement"
] | omar2535 | 1 |
JaidedAI/EasyOCR | pytorch | 1,350 | EasyOCR not reading Japanese text | For some reason unknown to me EasyOCR will or will not at times read clearly legible Japanese text at random and I need help getting to the bottom of why? Can anyone help?

```
img = cv2.imread(imgap)
if img is Non... | open | 2024-12-17T23:53:37Z | 2024-12-17T23:53:37Z | https://github.com/JaidedAI/EasyOCR/issues/1350 | [] | TLiley2 | 0 |
gradio-app/gradio | data-visualization | 10,850 | Could not create share link. Please check your internet connection or our status page: https://status.gradio.app. | ### Describe the bug
Hi, I am using the latest version of Gradio.
But I encounter this problem:

Do you know how can I solve this problem? Thank you very much!
### Have you searched existing issues? 🔎
- [x] I have search... | closed | 2025-03-21T04:00:17Z | 2025-03-22T22:36:48Z | https://github.com/gradio-app/gradio/issues/10850 | [
"bug"
] | Allen-Zhou729 | 7 |
vitalik/django-ninja | rest-api | 652 | API key not populated for Django test client | **Describe the bug**
I have implemented authentication by extending `APIKeyHeader`. It works fine when running the Django server and passing the API key as a header, but not when I try to unit-test my API with a Django test client.
My auth class (it uses the supplied API key to lookup a "Client" object in the dat... | closed | 2023-01-17T09:55:34Z | 2023-01-18T16:59:30Z | https://github.com/vitalik/django-ninja/issues/652 | [] | cornel-masson | 2 |
JaidedAI/EasyOCR | machine-learning | 1,065 | error in reader = Reader(languages) |
The line : reader = Reader(languages)
giving the below error when running a script which is use easyocr from c# application with multi-thread , each thread will initiate a process which will call the python script
An error occurred: 'charmap' codec can't encode character '\u2588' in position 12: character maps... | open | 2023-06-25T10:47:23Z | 2023-06-25T10:47:23Z | https://github.com/JaidedAI/EasyOCR/issues/1065 | [] | RamadanHussein | 0 |
quokkaproject/quokka | flask | 265 | Admin/Accounts/Roles errors: "create a copy" and "publish/unpublish" in "with selected" | attempting to create a copy of a role results in a failure because role model has no attribute "slug"
same goes for publish/unpublish, with no attribute
| closed | 2015-07-18T16:34:46Z | 2015-07-20T03:12:36Z | https://github.com/quokkaproject/quokka/issues/265 | [
"bug",
"EASY"
] | oktools | 1 |
flasgger/flasgger | flask | 29 | Unable to create global definitions | Due to the use of 'id' for schemas $ref to a defined schema doesn't work.
When running example application 'example_app.py' you can see that the GET method (get /v1/users/{team_id}) using $ref to reference #/definitions/User returns ' [ null ]'
With the current implementation the reference should be done like this:
$... | closed | 2016-07-14T12:59:13Z | 2017-03-22T17:04:57Z | https://github.com/flasgger/flasgger/issues/29 | [
"bug"
] | klarsen73 | 1 |
huggingface/diffusers | pytorch | 10,790 | Lower VRAM usage in CPU offload for Flux ControlNet Pipeline | **Is your feature request related to a problem? Please describe.**
I have a 24GB VRAM GPU. When running a diffusion model like Flux1, I can barely fit the model in memory during inference with batch size 1. Enabling CPU offload does not help because the offload does not occur between the controlnet forward pass and th... | open | 2025-02-14T10:56:10Z | 2025-03-20T15:03:22Z | https://github.com/huggingface/diffusers/issues/10790 | [
"stale"
] | NielsPichon | 15 |
gradio-app/gradio | machine-learning | 10,844 | Feature Request: Add Mermaid Support to gr.Markdown() Component | - [x] I have searched to see if a similar issue already exists.
### **Is your feature request related to a problem? Please describe.**
Currently, the `gr.Markdown()` component in Gradio supports basic Markdown rendering but lacks native integration for Mermaid diagrams. This limitation forces users to manually embed... | open | 2025-03-20T09:27:19Z | 2025-03-23T21:28:12Z | https://github.com/gradio-app/gradio/issues/10844 | [] | xiaoyingv | 2 |
tiangolo/uvicorn-gunicorn-fastapi-docker | fastapi | 42 | Why is my app stuck at booting new workers? | I have a rather simple python script that loads a large file in the beginning, before defining the fastapi endpoints.
```
app = FastAPI()
embeddings = np.load('embeddings.npy') # 15 sec to load
```
This takes about 15 seconds on a normal laptop. The app runs fine if i start it with vanilla uvicorn without a dock... | closed | 2020-05-08T08:50:12Z | 2022-12-19T22:00:03Z | https://github.com/tiangolo/uvicorn-gunicorn-fastapi-docker/issues/42 | [] | timpal0l | 4 |
noirbizarre/flask-restplus | flask | 434 | How can I create custom http methods? | On the same resource, if I want to create two get methods how can I create. Can I give custom names to HTTP method? | open | 2018-05-10T12:13:32Z | 2018-05-17T18:13:21Z | https://github.com/noirbizarre/flask-restplus/issues/434 | [] | vimox-shah | 1 |
allenai/allennlp | nlp | 5,467 | error message: "zipfile.BadZipFile: File is not a zip file" after installation | After installing AllenNLP, the command `allennlp` failed with the error message `zipfile.BadZipFile: File is not a zip file`
The problem disappeared by installing the popular data sets of NLTK
It would be good if these datasets were added automatically during installation | closed | 2021-11-16T17:26:21Z | 2021-12-01T16:09:45Z | https://github.com/allenai/allennlp/issues/5467 | [
"stale"
] | eriktks | 3 |
wkentaro/labelme | deep-learning | 1,488 | ValueError: <labelme.shape.Shape object at 0x000001BFA54D6310> is not in list | ### Provide environment information
Traceback (most recent call last):
File "E:\anaconda3\envs\PY311\Lib\site-packages\labelme\widgets\canvas.py", line 973, in keyReleaseEvent
index = self.shapes.index(self.selectedShapes[0])
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
ValueError: <labelme.shape.Sh... | open | 2024-08-27T08:12:01Z | 2024-08-27T08:12:01Z | https://github.com/wkentaro/labelme/issues/1488 | [
"issue::bug"
] | intbingbing | 0 |
exaloop/codon | numpy | 112 | package python modules together |
Can codon package codon files and dependent python modules (using `from python import`) in the same standalone executable binary like `nuitka`, rather than the executable binary needing to look for specially configured python modules in the machine environment? | open | 2022-12-15T12:11:57Z | 2022-12-19T20:43:20Z | https://github.com/exaloop/codon/issues/112 | [
"enhancement"
] | cyw3 | 1 |
dynaconf/dynaconf | flask | 783 | dynaconf list tells I am in "development" mode, when choosing no environement. | **Describe the bug**
when working with environments, the command `dynaconf -i path.to.settings list` displays by default `working in development environment`. It's confusing because it seems more logical to call it `default` environement. For example I have default values, and two environements called `dev` and `pro... | open | 2022-08-03T16:41:00Z | 2023-04-11T16:17:16Z | https://github.com/dynaconf/dynaconf/issues/783 | [
"enhancement"
] | antoine-gallix | 3 |
streamlit/streamlit | deep-learning | 10,190 | Click (not selection) events for dataframes, charts, and maps | ### Checklist
- [X] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [X] I added a descriptive title and summary to this issue.
### Summary
We recently added selection events for dataframes, Plotly/Altair charts, and PyDeck maps. Sometimes, you just... | open | 2025-01-14T22:26:55Z | 2025-01-14T22:27:19Z | https://github.com/streamlit/streamlit/issues/10190 | [
"type:enhancement",
"feature:st.dataframe",
"feature:st.altair_chart",
"feature:st.plotly_chart",
"feature:st.pydeck_chart",
"area:events"
] | jrieke | 1 |
replicate/cog | tensorflow | 1,269 | Output Unknown error handling prediction. | Hi, I am trying to return an image using model prediction and it's throwing me an unknown error, In local I am able to get the output out of the model but in replicate it throws the above error.
##Base Code
from cog import BasePredictor, Input, Path,File
import os
import cv2
from PIL import Image
import pand... | open | 2023-08-23T06:27:25Z | 2024-02-19T15:56:19Z | https://github.com/replicate/cog/issues/1269 | [
"Backend"
] | swapnil-lader | 0 |
marshmallow-code/marshmallow-sqlalchemy | sqlalchemy | 156 | AttributeError: type object '<Schema>' has no attribute 'TYPE_MAPPING | I am using `marshmallow-sqlalchemy==0.15.0` when i am running into the below problem:
`AttributeError: type object '<Schema>' has no attribute 'TYPE_MAPPING'`
The marshmallow deserialization class I have is given below:
```
from marshmallow_sqlalchemy import ModelSchema
from data_models.entity.user import Us... | closed | 2018-11-06T19:39:00Z | 2018-11-07T00:44:34Z | https://github.com/marshmallow-code/marshmallow-sqlalchemy/issues/156 | [] | lordlabakdas | 1 |
ydataai/ydata-profiling | pandas | 1,530 | No module named 'ydata_profiling' | ### Current Behaviour
after installing ydata using the following command
conda install -c conda-forge ydata-profiling
I can use
from ydata_profiling import ProfileReport
in the python cmd window. However, in the jupyter notebook I get the
following error:
ModuleNotFoundError: No module named 'ydata_... | closed | 2024-01-26T05:31:03Z | 2024-09-06T02:33:35Z | https://github.com/ydataai/ydata-profiling/issues/1530 | [
"needs-triage"
] | makgul1 | 4 |
scikit-learn/scikit-learn | data-science | 30,554 | scikit-learn 1.6 changed behavior of growing trees | ### Describe the bug
While porting scikit-survival to support scikit-learn 1.6, I noticed that one test failed due to trees in a random forest having a different structure (see [this GitHub Actions log](https://github.com/sebp/scikit-survival/actions/runs/12449071339/job/34754313599)).
Using git bisect, I could d... | closed | 2024-12-28T22:31:43Z | 2025-03-15T21:02:16Z | https://github.com/scikit-learn/scikit-learn/issues/30554 | [
"Bug",
"module:tree"
] | sebp | 3 |
huggingface/datasets | deep-learning | 7,381 | Iterating over values of a column in the IterableDataset | ### Feature request
I would like to be able to iterate (and re-iterate if needed) over a column of an `IterableDataset` instance. The following example shows the supposed API:
```
def gen():
yield {"text": "Good", "label": 0}
yield {"text": "Bad", "label": 1}
ds = IterableDataset.from_generator(gen)
texts = d... | open | 2025-01-28T13:17:36Z | 2025-02-18T17:15:51Z | https://github.com/huggingface/datasets/issues/7381 | [
"enhancement"
] | TopCoder2K | 2 |
coqui-ai/TTS | deep-learning | 3,328 | [Question]How can I add ground truth duration for VITs Training? | Thanks for your excellent working.
I've used vits for training my own datasets, but missing some pronounce phonemes. Now I want to try to add ground truth duration as input training not compute from SDP model.
I am very happy if you can procedure some code to do it.
One more times, thank you very much.
| closed | 2023-11-28T11:16:32Z | 2023-12-07T13:36:01Z | https://github.com/coqui-ai/TTS/issues/3328 | [
"feature request"
] | phamkhactu | 0 |
ymcui/Chinese-BERT-wwm | tensorflow | 155 | wwm是否可以提取固定向量? | 您好,请问是否wwm是否也是可以像谷歌bert一样,Using BERT to extract fixed feature vectors呢 | closed | 2020-10-27T00:42:09Z | 2020-11-06T10:40:04Z | https://github.com/ymcui/Chinese-BERT-wwm/issues/155 | [
"stale"
] | 1535966643 | 6 |
huggingface/transformers | python | 36,609 | Making attention mechanism stackable | ### Feature request
I'm porting [DeepSpeed Ulysses sequence parallelism](https://github.com/deepspeedai/DeepSpeed/blob/master/blogs/deepspeed-ulysses/README.md) from Megatron-Deepspeed to the HF transformers ecosphere so that everybody could use this SP implementation. I'm integrating it into [ArcticTraining](https://... | open | 2025-03-07T17:58:44Z | 2025-03-24T11:02:15Z | https://github.com/huggingface/transformers/issues/36609 | [
"Feature request"
] | stas00 | 3 |
aiogram/aiogram | asyncio | 513 | Chat.update_chat() fails for private chats obtained from Bot.get_chat() | ## Context
* Operating System: Windows 10
* Python Version: 3.9.0
* aiogram version: 2.11.2
* aiohttp version: 3.7.3
* uvloop version (if installed): N/A
## Expected Behavior
`Chat` is updated successfully.
## Current Behavior
A `TypeError` is raised.
## Failure Information (for bugs)
### Steps to Re... | closed | 2021-02-22T17:03:37Z | 2022-02-08T00:30:41Z | https://github.com/aiogram/aiogram/issues/513 | [
"bug",
"confirmed"
] | jonowo | 5 |
nl8590687/ASRT_SpeechRecognition | tensorflow | 23 | train_mspeech有关问题? | 我将数据集存放在D盘,data_thchs30文件我不会查看,在训练过程报以下错误:
FileNotFoundError: [Errno 2] No such file or directory: 'D:\\语音数据集\\data_thchs30\\train\\C13_571.wav'
可以请教一下吗?
| closed | 2018-07-06T08:37:12Z | 2018-07-18T04:10:53Z | https://github.com/nl8590687/ASRT_SpeechRecognition/issues/23 | [] | KratosWang | 8 |
jumpserver/jumpserver | django | 14,390 | [Question] api接口调用问题反馈,API 创建账号,并加密密钥信息 | ### 产品版本
v3.10.13
### 版本类型
- [ ] 社区版
- [X] 企业版
- [ ] 企业试用版
### 安装方式
- [ ] 在线安装 (一键命令安装)
- [X] 离线包安装
- [ ] All-in-One
- [ ] 1Panel
- [ ] Kubernetes
- [ ] 源码安装
### ⭐️ 需求描述
我通过API调用的方式添加资产账号,账号为密文,需要用到cookie中的jms_public_key,由于jms_public_key不是固定的,这样自己获取cookies加密的话是不是有些浪费资源了,我调用哪个接口获取cookies呢,实际上我调用的接口只有一个目的那就是获取cook... | closed | 2024-11-01T06:52:08Z | 2024-11-07T03:09:10Z | https://github.com/jumpserver/jumpserver/issues/14390 | [
"⭐️ Feature Request"
] | yuanxixue | 7 |
xlwings/xlwings | automation | 1,898 | xlwings read large number incorrectly from xlsx | #### Windows
#### Versions of xlwings 0.27.6, Excel 16.0.14332_20204 and Python 3.10.3
#### xlwings read large number incorrectly from xlsx
Bug reproduction repo: https://github.com/Hoffma... | closed | 2022-04-21T15:26:59Z | 2022-05-21T17:51:04Z | https://github.com/xlwings/xlwings/issues/1898 | [] | HoffmanZheng | 1 |
docarray/docarray | pydantic | 1,592 | Field of type `List[str]` is shown as `str` in the output of `DocList.summary` | When defining a field's type using `List[str]`:
```python
class TestDoc(BaseDoc):
str_list: List[str]
dl = DocList[TestDoc]([TestDoc(str_list=[]), TestDoc(str_list=["1"])])
dl.summary()
```
Output:
```
╭─────── DocList Summary ───────╮
│ │
│ Type DocList[TestDoc] │... | closed | 2023-05-30T18:29:32Z | 2023-05-31T08:41:34Z | https://github.com/docarray/docarray/issues/1592 | [] | lazyhope | 4 |
nonebot/nonebot2 | fastapi | 3,025 | Plugin: 团购 | ### PyPI 项目名
nonebot-plugin-buy
### 插件 import 包名
nonebot_plugin_buy
### 标签
[]
### 插件配置项
_No response_ | closed | 2024-10-16T16:46:43Z | 2024-10-18T12:57:58Z | https://github.com/nonebot/nonebot2/issues/3025 | [
"Plugin"
] | Onimaimai | 8 |
JaidedAI/EasyOCR | machine-learning | 599 | `reformat_input` does not support handle transparent grayscale image | `reformat_input` doesn't handle grayscale images with transparency channel (`image.mode == "LA"`).
This happens because codepath handling np.arrays in `reformat_input` in `utils.py` doesn't hit any branch if it has 2 channels (`image.shape[2] == 2`). Only cases for 1, 3 and 4 channels are handled: https://github.co... | closed | 2021-11-23T12:40:00Z | 2022-08-07T05:01:23Z | https://github.com/JaidedAI/EasyOCR/issues/599 | [] | justasbr1 | 0 |
Subsets and Splits
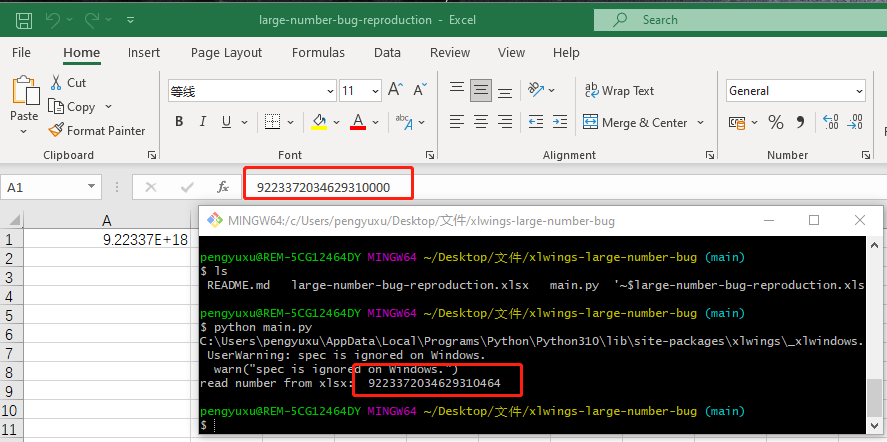
No community queries yet
The top public SQL queries from the community will appear here once available.