
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
CorentinJ/Real-Time-Voice-Cloning | pytorch | 1,170 | Missing or murmuring words after synthesizing | Hi there,
I tried it more than a year ago and I remember it was working fine with "demo_cli". At the time, I was using Mac Bigfur.
Now, i tried again, with Mac Monterey. There are missing words or some words just murmuring and not clear at all. Tried wav, mp3 and m4a and it's reproducible.
Does anyone know wh... | open | 2023-03-05T21:35:08Z | 2023-03-05T21:35:08Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1170 | [] | alann07 | 0 |
nltk/nltk | nlp | 2,797 | How to create a custom model for a trigram tagger? | closed | 2021-09-06T17:05:56Z | 2021-10-22T10:38:37Z | https://github.com/nltk/nltk/issues/2797 | [
"tagger",
"invalid"
] | mmargegaj | 6 | |
keras-team/autokeras | tensorflow | 900 | Include the BERT model in the search space | <!---
Please label your issue with `feature_request`.
-->
### Feature Description
<!---
A clear and concise description of idea/feature. If it is related to some problem you are facing, then explain the problem.
-->
### Reason
<!---
A clear and concise description of why this feature would be useful for ... | closed | 2020-01-16T21:47:59Z | 2020-09-24T20:10:25Z | https://github.com/keras-team/autokeras/issues/900 | [
"feature request",
"pinned"
] | haifeng-jin | 0 |
onnx/onnxmltools | scikit-learn | 400 | ONNX does not support "multi:softmax" of XgBoost | Hi,
first I wanted to thank you for the nice library.
I am trying to convert XgBoost mult-nomial/multi-class logistic regression to ONNX. Checking the source code I have noticed that the file "_parse.py" does not support "multi:softmax", but only "multi:softprob". Indeed, the predictions are all logits and not th... | closed | 2020-05-30T19:44:17Z | 2021-01-21T06:28:27Z | https://github.com/onnx/onnxmltools/issues/400 | [] | PaoloRanzi81 | 1 |
huggingface/datasets | tensorflow | 6,985 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType' | ### Describe the bug
I have been struggling with this for two days, any help would be appreciated. Python 3.10
```
from setfit import SetFitModel
from huggingface_hub import login
access_token_read = "cccxxxccc"
# Authenticate with the Hugging Face Hub
login(token=access_token_read)
# Load the models fr... | closed | 2024-06-19T13:22:28Z | 2025-03-14T18:47:53Z | https://github.com/huggingface/datasets/issues/6985 | [] | firmai | 14 |
Lightning-AI/pytorch-lightning | machine-learning | 20,409 | Errors when deploying PyTorch Lightning Model to AWS SageMaker TrainingJobs: SMDDP does not support ReduceOp | ### Bug description
Hi, I am trying to follow the DDP (Distributed Data Parallel) guidance ([Guide 1](https://aws.amazon.com/blogs/machine-learning/run-pytorch-lightning-and-native-pytorch-ddp-on-amazon-sagemaker-training-featuring-amazon-search/), [Guide 2](https://docs.aws.amazon.com/sagemaker/latest/dg/data-paral... | closed | 2024-11-09T00:58:05Z | 2024-11-09T20:40:07Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20409 | [
"bug",
"needs triage",
"ver: 2.4.x"
] | ZihanChen1995 | 0 |
freqtrade/freqtrade | python | 11,272 | Multi-core Support for Backtesting Function | Operating system: mac os
Python Version: Python 3.11.5
CCXT version: ccxt==4.4.43
Freqtrade Version: freqtrade 2024.12
Hello Freqtrade team,
I'm currently running backtesting operations on my system which has 24 CPU cores available. I've noticed that the backtesting function appears to be utilizing only a single core... | closed | 2025-01-22T09:45:11Z | 2025-01-23T10:38:05Z | https://github.com/freqtrade/freqtrade/issues/11272 | [
"Question"
] | GabrielBertoli | 2 |
deepfakes/faceswap | machine-learning | 1,079 | the following arguments are required: -m/--model-dir | Thanks for your jobs, when I run 'python faceswap.py convert', it raise this error, how can I download the trained model | closed | 2020-10-09T12:25:54Z | 2020-10-09T14:19:48Z | https://github.com/deepfakes/faceswap/issues/1079 | [] | guanyonglai | 1 |
explosion/spaCy | machine-learning | 12,954 | Lemmatization issues [Italian][Spanish][French] | Hello,
As a follow up on #11298 #11347, I would like to report some lemmatization problems with the spaCy 3.6 models for Italian, Spanish and French. We did not have these issues with the 3.2 version.
## How to reproduce the behaviour
Here are some examples:
| Language | Text ... | open | 2023-09-04T12:53:05Z | 2023-11-13T10:02:19Z | https://github.com/explosion/spaCy/issues/12954 | [
"lang / it",
"lang / fr",
"lang / es",
"feat / lemmatizer",
"perf / accuracy"
] | databill86 | 8 |
fastapiutils/fastapi-utils | fastapi | 115 | [FEATURE] Adjust task delay duration before first call | **Is your feature request related to a problem? Please describe.**
For now, `repeat_every` decorator only allows us to delay the first call exactly 1 interval with `wait_first` set to `True`. We can't do things like wait for 1 minute, then execute the task every 1 hour.
**Describe the solution you'd like**
Make `w... | open | 2020-09-30T06:47:59Z | 2021-04-05T10:09:49Z | https://github.com/fastapiutils/fastapi-utils/issues/115 | [
"enhancement"
] | lqmanh | 1 |
robusta-dev/robusta | automation | 850 | Support Grouping of Alerts in Robusta when grouped alerts are received from Alertmanager | **Is your feature request related to a problem?**
When multiple alerts come in that have been grouped by Alertmanager robusta sends a single alert for each
**Describe the solution you'd like**
Robusta should respect the grouping of the alerts and just send one message with all of the alerts details to the configur... | open | 2023-05-04T15:05:49Z | 2024-03-26T23:32:20Z | https://github.com/robusta-dev/robusta/issues/850 | [] | RoryDoherty | 2 |
pinry/pinry | django | 120 | docker-compose installation does not work | I ran the installation as explained in the README:
`docker-compose up`
`docker-compose exec web python3 manage.py migrate --settings=pinry.settings.docker`
Everything worked nicely but now I don't see the static files:
 and found no similar feature requests.
### Description
https://github.com/pcb9382/PlateRecognition
### Use case
https://github.com/pcb9382/PlateRecognition
### Additional
https://github.com/pcb9382/P... | closed | 2023-12-26T05:48:24Z | 2024-02-05T00:21:16Z | https://github.com/ultralytics/yolov5/issues/12550 | [
"enhancement",
"Stale"
] | pcb9382 | 2 |
microsoft/unilm | nlp | 748 | TrOCR - Segmentation Issue | Do we need to manually segment the following image before we give it to the model for the final predictions? Is there a built-in segmentation module within TrOCR? If not, is there some external tool we can leverage for this purpose?

```... | closed | 2024-09-20T22:07:28Z | 2024-10-04T10:11:02Z | https://github.com/pydantic/logfire/issues/436 | [
"bug"
] | bllchmbrs | 5 |
drivendataorg/cookiecutter-data-science | data-science | 16 | Compatibility of pack to create api driven projects | Hi there! Loved the project, this really reflects the maturity of data science projects and where we are standing. So good!
I rise this issue as I was wondering if the current structure can be adapted to an api-driven project. This is, a project in which the analysis and data flow may be related to an api definition.
... | closed | 2016-04-28T16:56:43Z | 2018-04-14T12:56:46Z | https://github.com/drivendataorg/cookiecutter-data-science/issues/16 | [
"folder-layout",
"needs-discussion"
] | ricalanis | 8 |
koxudaxi/datamodel-code-generator | fastapi | 2,345 | yaml.scanner.ScannerError | **Describe the bug**
I am running
```python
datamodel-codegen --input spectraSchema.json --input-file-type jsonschema --output gen.MnovaSpectraModel.py
```
**Error message received**
```bash
Traceback (most recent call last):
File "/nas/.local/lib/python3.10/site-packages/datamodel_code_generator/__main__.py", line... | closed | 2025-03-14T15:24:58Z | 2025-03-14T17:37:45Z | https://github.com/koxudaxi/datamodel-code-generator/issues/2345 | [] | kuhlaid | 1 |
brightmart/text_classification | nlp | 69 | 哪里可以找到train-zhihu4-only-title-all.txt文件?? | closed | 2018-07-17T10:00:16Z | 2018-07-17T11:55:26Z | https://github.com/brightmart/text_classification/issues/69 | [] | XuHan-Hub | 0 | |
piccolo-orm/piccolo | fastapi | 526 | Add support for tablespaces | ### Discussed in https://github.com/piccolo-orm/piccolo/discussions/525
<div type='discussions-op-text'>
<sup>Originally posted by **theelderbeever** May 24, 2022</sup>
Background on the question... some of our tables are very large and our deployment infrastructure limits us to 16TB of disk space per provisione... | open | 2022-05-24T16:35:56Z | 2022-05-24T16:35:56Z | https://github.com/piccolo-orm/piccolo/issues/526 | [
"enhancement"
] | dantownsend | 0 |
jordaneremieff/djantic | pydantic | 23 | Support for BigAutoField | [`BigAutoField`](https://docs.djangoproject.com/en/dev/ref/models/fields/#bigautofield), is the default value of [`DEFAULT_AUTO_FIELD`](https://docs.djangoproject.com/en/dev/ref/settings/#std:setting-DEFAULT_AUTO_FIELD) for new [Django-3.2 projects](https://docs.djangoproject.com/en/dev/releases/3.2/#customizing-type-o... | closed | 2021-04-09T10:38:26Z | 2021-04-09T13:09:18Z | https://github.com/jordaneremieff/djantic/issues/23 | [] | raratiru | 1 |
plotly/dash | plotly | 2,597 | enable linking to dashboard including state | **Is your feature request related to a problem? Please describe.**
Outputs from Dashboards are often shared via screenshots, but the lineage is lost this way. This is because there is currently no easy way to share a dashboard including the state. When using Google Maps you can share your current URL and the other per... | open | 2023-07-12T09:09:08Z | 2024-08-13T19:35:50Z | https://github.com/plotly/dash/issues/2597 | [
"feature",
"P3"
] | JulianWgs | 0 |
OpenBB-finance/OpenBB | machine-learning | 6,817 | [🕹️] Publish a LinkedIn post or a Twitter Thread (🕹️ 150-500 Points) | ### What side quest or challenge are you solving?
Publish a LinkedIn post
### Points
150-500
### Description
_No response_
### Provide proof that you've completed the task
https://www.linkedin.com/posts/harshraj1512_opensource-financetool-investmentresearch-activity-7253401682892447744-sxQF?utm_source=share&utm_... | closed | 2024-10-19T15:06:07Z | 2024-10-21T13:04:02Z | https://github.com/OpenBB-finance/OpenBB/issues/6817 | [] | harshraj1512 | 3 |
voxel51/fiftyone | data-science | 5,465 | [BUG] Recall sweep in compute PR curves | ### Describe the problem
Changes to include `mAR` in `evaluate_detections` from https://github.com/voxel51/fiftyone/pull/5274 introduced a `recall_sweep` variable returned from `_compute_pr_curves()`.
https://github.com/voxel51/fiftyone/blob/2d105564805bd25bf91598941634d2bf59ee12c4/fiftyone/utils/eval/coco.py#L710
An... | closed | 2025-02-04T07:10:26Z | 2025-02-28T22:52:47Z | https://github.com/voxel51/fiftyone/issues/5465 | [
"bug"
] | wickeat | 4 |
lepture/authlib | django | 150 | Support multiple audiences for OpenIDCode | It should be possible to provide multiple audiences to JWT Tokens via OpenIDCode child classes.
`authlib.oidc.core.grants.code.OpenIDCode` & `authlib.oidc.core.grants.implicit.OpenIDImplicitGrant` both use `generate_id_token` from `authlib.oidc.core.grants.util` to generate id_token payloads.
`generate_id_token` ... | closed | 2019-09-20T12:16:45Z | 2019-10-08T11:55:00Z | https://github.com/lepture/authlib/issues/150 | [
"spec",
"server"
] | callamd | 3 |
ets-labs/python-dependency-injector | flask | 369 | Add option "required" to the config.from_* methods | > Re: ``config.from_yaml('not_existent.yaml')``
> I would usually expect to have an exception raised when trying to do something with non-existent resources.
I agree. This is a design error. It didn't look like that when I designed it initially. Sort of hindsight bias :)
I can not change ``config.from_yaml('not_... | closed | 2021-01-21T15:01:56Z | 2021-01-27T13:44:26Z | https://github.com/ets-labs/python-dependency-injector/issues/369 | [
"feature"
] | rmk135 | 5 |
scrapy/scrapy | python | 6,121 | Scheduler initializes disk queue even if `JOBDIR` is empty string | # Description
By default, `JOBDIR` is the empty string per documentation. This makes `SpiderState` extension to be disabled by default and `RFPDupeFilter` to not save fingerprints to file `requests.seen`. However, request scheduler still creates disk queue. The leads to inconsistences: pending requests will be saved... | closed | 2023-10-24T17:12:21Z | 2023-10-31T13:37:27Z | https://github.com/scrapy/scrapy/issues/6121 | [
"bug",
"good first issue"
] | Prometheus3375 | 0 |
Layout-Parser/layout-parser | computer-vision | 9 | Gives wrong results when the code is run for some images in a loop | The code works when it is run for a single image. But when I run the same code in a loop for few images from the publaynet dataset, cached results seem to apply (i.e. The bounding boxes overlap and the boxes for the previous images are also put in the current image). | closed | 2021-02-05T17:20:10Z | 2021-04-12T06:33:24Z | https://github.com/Layout-Parser/layout-parser/issues/9 | [] | surajsubramanian | 4 |
ivy-llc/ivy | tensorflow | 28,834 | sum | open | 2024-10-10T19:32:11Z | 2024-10-11T23:03:05Z | https://github.com/ivy-llc/ivy/issues/28834 | [
"Sub Task"
] | amoungui | 1 | |
Avaiga/taipy | data-visualization | 1,668 | [🐛 BUG] Taipy Installation from git not working (with Conda) | ### What went wrong? 🤔
Dependencies are not installed. Taipy is installed but not working.
```python
(enterprise) C:\Users\jacta>conda create -n test_2 python=3.12
Collecting package metadata (current_repodata.json): done
Solving environment: done
==> WARNING: A newer version of conda exists. <==
curr... | closed | 2024-08-14T12:04:50Z | 2024-08-26T09:16:05Z | https://github.com/Avaiga/taipy/issues/1668 | [
"🟥 Priority: Critical",
"🖧 Devops",
"💥Malfunction"
] | FlorianJacta | 4 |
pyjanitor-devs/pyjanitor | pandas | 863 | Scrub readthedocs.io from repo | # Brief Description of Fix
The dev team has elected to use GitHub pages for documentation instead of Read the Docs. This means documentation has moved from https://pyjanitor.readthedocs.io/ to https://pyjanitor-devs.github.io/pyjanitor/
A quick search of the repo for `readthedocs.io` reveals that there are some l... | closed | 2021-08-11T22:21:55Z | 2021-08-12T14:29:17Z | https://github.com/pyjanitor-devs/pyjanitor/issues/863 | [
"docfix"
] | loganthomas | 0 |
vitalik/django-ninja | rest-api | 478 | Reuse existing Schema for validating standard requests data. | Is it possible to reuse an existing Schema for validating the POST data of a standard (not API) request?
If yes, could you provide an example please? | closed | 2022-06-20T09:18:35Z | 2022-06-20T12:15:03Z | https://github.com/vitalik/django-ninja/issues/478 | [] | fabiocaccamo | 3 |
unytics/bigfunctions | data-visualization | 29 | [new]: `sleep(time ms)` | ### Check the idea has not already been suggested
- [X] I could not find my idea in [existing issues](https://github.com/unytics/bigfunctions/issues?q=is%3Aissue+is%3Aopen+label%3Anew-bigfunction)
### Edit the title above with self-explanatory function name and argument names
- [X] The function name and the argument... | open | 2022-12-07T16:34:00Z | 2024-07-26T07:00:15Z | https://github.com/unytics/bigfunctions/issues/29 | [
"new-bigfunction"
] | Mmoncadaisla | 4 |
Kanaries/pygwalker | pandas | 491 | alternative for display_chart() in flask. | display_chart() only works in jupyter notebook.How can I render a chart's image whose spec is already available? | open | 2024-03-20T15:47:59Z | 2024-03-22T15:15:43Z | https://github.com/Kanaries/pygwalker/issues/491 | [] | anandakrishnankb | 1 |
HumanSignal/labelImg | deep-learning | 721 | How to copy several folders into one with YOLO format? | <!--
Please provide as much as detail and example as you can.
You can add screenshots if appropriate.
-->
I have different folders with annotated images with the same objects and logic:
```
folder_a
- a_01.jpg
- a_01.txt
- a_02.jpg
- a_02.jpg
- classes.txt
folder_b
- b_01.jpg
- b_01.txt
- b_02.... | open | 2021-03-13T18:17:37Z | 2022-09-12T07:35:50Z | https://github.com/HumanSignal/labelImg/issues/721 | [] | einareinarsson | 1 |
sinaptik-ai/pandas-ai | data-science | 1,633 | 💡 Add this project to awesome-italia-opensource | I founded Italia Open-Source, a community that aims to share and grow the Italian open-source world and, more generally, to highlight Italian tech excellence.
Our website [italiaopensource.com](https://italiaopensource.com/) is based on open data that reside on the [awesome-italia-opensource](https://github.com/italia... | closed | 2025-02-24T11:06:22Z | 2025-03-11T17:06:47Z | https://github.com/sinaptik-ai/pandas-ai/issues/1633 | [] | FabrizioCafolla | 2 |
open-mmlab/mmdetection | pytorch | 11,258 | The mAP for most of my categories is NaN. Why? | 
The following is my config
```python
auto_scale_lr = dict(base_batch_size=16, enable=False)
backend_args = None
data_root = 'data/coco/'
dataset_type = 'CocoDataset'
default_hooks = dict(... | open | 2023-12-06T11:43:02Z | 2023-12-06T11:43:24Z | https://github.com/open-mmlab/mmdetection/issues/11258 | [] | da-orange-zi | 0 |
pennersr/django-allauth | django | 3,650 | SAML EntityID can't be used in MS Azure AD / Entra ID SSO | ### The issue
The `EntityID` used in the xml metadata file of the ServiceProvider SP ( / the allauth host) is built automatically using the metadata endpoint url for the provider:
The value is automatically generated from [allauth/socialaccount/providers/saml/utils.py#L43-L45](https://github.com/pennersr/django-a... | closed | 2024-02-21T13:27:51Z | 2024-05-04T13:23:21Z | https://github.com/pennersr/django-allauth/issues/3650 | [] | wrabit | 4 |
ray-project/ray | tensorflow | 51,193 | [Ray Serve]: "RuntimeError: No CUDA GPUs are available" when running vllm with ray | ### What happened + What you expected to happen
Hello everyone, since this is my first time creating an issue, so I apologize in advance for any mistakes or missing details. Thanks in advance for your patience!
## the bug
When running this [tutorial on Ray Serve](https://docs.ray.io/en/latest/serve/tutorials/vllm-exam... | open | 2025-03-09T09:39:10Z | 2025-03-10T22:23:23Z | https://github.com/ray-project/ray/issues/51193 | [
"bug",
"triage",
"serve"
] | RixinLiu | 0 |
mwaskom/seaborn | data-visualization | 3,533 | Try `to_pandas` rather than erroring if interchanging to pandas doesn't work? | Here's an example of some code which currently raises:
```python
import seaborn as sns
import polars as pl
df = pl.DataFrame({'a': [1,2,3], 'b': [4,5,6], 'c': [[1,2], [4,5], [6,7]]})
sns.catplot(
data=df,
x="a",
y="b",
)
```
There's a really long error message, but the gist of it is
```
Value... | open | 2023-10-19T19:29:55Z | 2023-10-28T13:51:29Z | https://github.com/mwaskom/seaborn/issues/3533 | [
"enhancement"
] | MarcoGorelli | 0 |
Anjok07/ultimatevocalremovergui | pytorch | 1,358 | Error Ultimate Vocal Remove | Last Error Received:
Process: Demucs
If this error persists, please contact the developers with the error details.
Raw Error Details:
AssertionError: ""
Traceback Error: "
File "UVR.py", line 6591, in process_start
File "separate.py", line 825, in seperate
File "separate.py", line 970, in demix_de... | open | 2024-05-19T10:07:25Z | 2024-05-19T10:07:25Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1358 | [] | ehabelgaby | 0 |
strawberry-graphql/strawberry | fastapi | 3,432 | buggy generic interfaces | ```
import strawberry
from typing import Optional, Generic, TypeVar, List
from strawberry.scalars import JSON
GenericType = TypeVar("GenericType")
@strawberry.interface
class BlockInterface:
id: strawberry.ID
disclaimer: Optional[str] = strawberry.field(default=None, description='Richtext')
@stra... | closed | 2024-04-02T14:26:14Z | 2025-03-20T15:56:39Z | https://github.com/strawberry-graphql/strawberry/issues/3432 | [
"bug"
] | Speedy1991 | 3 |
ultralytics/yolov5 | pytorch | 13,066 | Labelling Objects Occluded objects in Extreme Environment | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
I am dealing with object detection of objects with similar color that are occlude each ot... | closed | 2024-06-03T15:46:46Z | 2024-10-20T19:47:14Z | https://github.com/ultralytics/yolov5/issues/13066 | [
"question",
"Stale"
] | Avv22 | 5 |
ymcui/Chinese-LLaMA-Alpaca-2 | nlp | 77 | 合併 LoRa model 不成功, 沒有產生最終模型檔 | ### 提交前必须检查以下项目
- [X] 请确保使用的是仓库最新代码(git pull),一些问题已被解决和修复。
- [X] 我已阅读[项目文档](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki)和[FAQ章节](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki/常见问题)并且已在Issue中对问题进行了搜索,没有找到相似问题和解决方案
- [X] 第三方插件问题:例如[llama.cpp](https://github.com/ggerganov/llama.cpp)、[text-generation-w... | closed | 2023-08-04T07:23:48Z | 2023-08-04T10:11:17Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/issues/77 | [] | wennycooper | 2 |
koaning/scikit-lego | scikit-learn | 327 | [DOCS] look for misspellings in documentation | run codespell on our docs to see if there's a common spelling error in the docs
(odds are that there's one or two in the code too). | closed | 2020-05-01T15:46:02Z | 2020-05-05T14:13:26Z | https://github.com/koaning/scikit-lego/issues/327 | [
"documentation"
] | tomasborrella | 1 |
davidsandberg/facenet | computer-vision | 1,149 | Improve performance with gender as additional parameter | @davidsandberg Most face-recognition systems will have some sort of human intervention, in such scenarios , we can have gender as an additional parameter along with training faces or testing images. Can we not make use of this critical information ? Wouldn't it be better if we cluster dataset into gender groups ? Testi... | open | 2020-04-07T09:45:24Z | 2020-04-07T09:58:51Z | https://github.com/davidsandberg/facenet/issues/1149 | [] | gokulkrshna | 0 |
nschloe/tikzplotlib | matplotlib | 328 | Conversion of fill_between to \path fails when using datetime axes | The following MWE creates a simple plot with a line and a shaded area between two other lines using `pyplot.fill_between`.
```python
import matplotlib.pyplot as plt
import matplotlib.dates as mdates
import tikzplotlib
from datetime import datetime, timedelta
times = datetime.now(), datetime.now() + timedelta(... | closed | 2019-08-25T00:28:23Z | 2020-01-01T23:33:50Z | https://github.com/nschloe/tikzplotlib/issues/328 | [] | harenbrs | 0 |
mljar/mercury | data-visualization | 456 | Ipywidgets HBox not working in server | I want to display 2 plots side-by-side. When working in Jupyter notebook, I'm able to use ipywidget's Hbox, like this:

On the other hand, when I startup the local server, I can see only this:
:
a: List = Field([])
```
is not working | open | 2022-07-01T03:22:56Z | 2022-07-01T03:22:56Z | https://github.com/bauerji/flask-pydantic/issues/52 | [] | fainle | 0 |
bigscience-workshop/petals | nlp | 220 | chat.petals integration with Hugging Face Spaces | Currently, you can use the model either directly, via [this notebook](https://colab.research.google.com/drive/1DqaqGkI6ab92WeXDGMStWt_l8BPHUaIj#scrollTo=OJ7AFOumIYlY), or through http://chat.petals.ml/ .
The latter is a self-hosted chat app that runs code similar to the colab notebook, but wraps it with a simple web... | open | 2023-01-17T16:15:22Z | 2023-02-19T01:40:50Z | https://github.com/bigscience-workshop/petals/issues/220 | [
"good first issue",
"help wanted"
] | justheuristic | 4 |
activeloopai/deeplake | tensorflow | 2,663 | [BUG] ds.visualize cannot work offline in jupyter notebook with local dataset | ### Severity
P1 - Urgent, but non-breaking
### Current Behavior
I try ds.visualize in jupyter notebook with loacl dataset, it failed to visualize the dataset.Like this

It reported a failure to connect to... | closed | 2023-10-18T04:03:10Z | 2023-10-18T19:23:00Z | https://github.com/activeloopai/deeplake/issues/2663 | [
"bug"
] | alphabet-lgtm | 7 |
tensorpack/tensorpack | tensorflow | 653 | import halted; None in sys.modules | debug.py
import torch
import torch.nn.functional as F
from torch.autograd import Variable
import torch.nn as nn
import numpy as np
import os
import time
import config as cfg
... | closed | 2018-02-14T01:36:51Z | 2018-05-30T20:59:36Z | https://github.com/tensorpack/tensorpack/issues/653 | [
"installation/environment"
] | bilipa | 7 |
stitchfix/hamilton | numpy | 150 | [prototype] NVMTabular support | **Is your feature request related to a problem? Please describe.**
NVMTabular is a way to write ETL feature code for nvidia GPUs. Is there a Hamilton way to help organize the workflow required to run NVMTabular?
**Describe the solution you'd like**
The goal of the prototype is to figure out how Hamilton could be b... | closed | 2022-07-08T05:07:39Z | 2023-02-26T17:11:04Z | https://github.com/stitchfix/hamilton/issues/150 | [
"documentation",
"enhancement"
] | skrawcz | 1 |
modin-project/modin | data-science | 6,998 | ValueError: Function did not transform | ```python
import modin.pandas as pd
import pandas
import numpy as np
pandas.Series([1,2,3,4]).transform([np.sqrt, np.exp]) # <- works
pd.Series([1,2,3,4]).transform([np.sqrt, np.exp]) # <- failed
```
Traceback:
```python
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "C... | open | 2024-03-04T14:23:48Z | 2024-03-07T14:27:45Z | https://github.com/modin-project/modin/issues/6998 | [
"bug 🦗",
"pandas concordance 🐼",
"P2"
] | anmyachev | 0 |
deepinsight/insightface | pytorch | 2,636 | Citation for buffalo_l | Hello,
Thank you for this great work.
Which would be the most appropriate paper to cite for the buffalo_l model?
Thanks,
Brooke | open | 2024-08-26T21:35:56Z | 2024-08-28T18:43:21Z | https://github.com/deepinsight/insightface/issues/2636 | [] | BStephen99 | 2 |
jupyter-incubator/sparkmagic | jupyter | 714 | Endpoint Password Field Should Be Shielded for Security | # overview
Ideally, when a user enters a password it should be shielded like a traditional password field.
## current state:
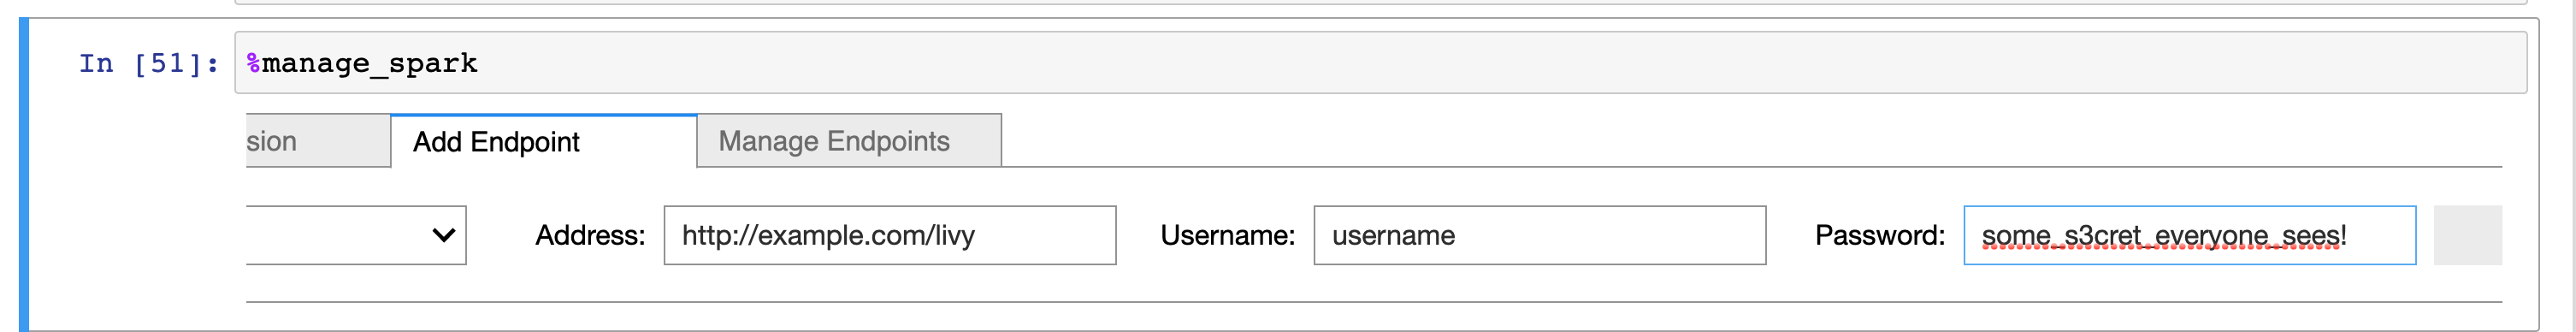
## future state:

2023-02-16 04:03:37 File "/usr/local/lib/python3.9/site-packa... | closed | 2023-02-16T04:13:23Z | 2023-02-17T03:05:55Z | https://github.com/Kav-K/GPTDiscord/issues/152 | [
"bug",
"help wanted",
"good first issue",
"high-prio"
] | saphtea | 2 |
huggingface/datasets | pandas | 7,287 | Support for identifier-based automated split construction | ### Feature request
As far as I understand, automated construction of splits for hub datasets is currently based on either file names or directory structure ([as described here](https://huggingface.co/docs/datasets/en/repository_structure))
It would seem to be pretty useful to also allow splits to be based on ide... | open | 2024-11-10T07:45:19Z | 2024-11-19T14:37:02Z | https://github.com/huggingface/datasets/issues/7287 | [
"enhancement"
] | alex-hh | 3 |
plotly/dash | dash | 3,057 | Serious performance issues related to React context | When using components associated with the `XxxProvider`, severe performance issues can arise when there is a large amount of page content. Here are some examples related to well-known component libraries in the Dash ecosystem:
- with `dmc`
In `dmc`, it is required that the application be wrapped inside the `MantinePr... | closed | 2024-11-02T03:28:25Z | 2025-02-06T14:21:32Z | https://github.com/plotly/dash/issues/3057 | [
"performance",
"P1"
] | CNFeffery | 4 |
jupyterhub/repo2docker | jupyter | 1,002 | Binder not using Project.toml in binder folder | <!-- Thank you for contributing. These HTML commments will not render in the issue, but you can delete them once you've read them if you prefer! -->
### Bug description
Coming from this [discussion](https://discourse.jupyter.org/t/project-toml-in-binder-subdirectory-not-installing-packages/6265/2)
When trying to... | open | 2021-01-13T13:04:01Z | 2021-01-13T13:04:03Z | https://github.com/jupyterhub/repo2docker/issues/1002 | [] | Cornelius-G | 1 |
aws/aws-sdk-pandas | pandas | 2,295 | read_parquet() categories argument gone | Hey,
Just wondering why read_parquet no longer has a `categories` argument. I can't find any mention if it in change notes either. Thanks! | closed | 2023-05-24T16:15:35Z | 2023-05-30T09:09:51Z | https://github.com/aws/aws-sdk-pandas/issues/2295 | [
"question"
] | matthewyakubiw | 1 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 584 | Pytorch not working on RTX 30X0 nvidia GPU (CUDA capability sm_86) | Hi everyone,
I just bought a Nvidia RTX 3070 and I was thrilled to do some training with it but it appears Pytorch doesn't work with my new GPU...
Here is the message I get, and there is no help on the pytorch webpage.
"
GeForce RTX 3070 with CUDA capability sm_86 is not compatible with the current PyTorch i... | closed | 2020-11-02T13:09:21Z | 2020-11-02T17:06:25Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/584 | [] | rallandr | 2 |
matterport/Mask_RCNN | tensorflow | 2,286 | ValueError: No such layer: rpn_class_loss | Selecting layers to train
In model: rpn_model
---------------------------------------------------------------------------
ValueError Traceback (most recent call last)
<ipython-input-11-1c26b876e251> in <module>()
----> 1 model.train(dataset_train,dataset_val,epochs=50,learning_rate=... | closed | 2020-07-18T13:47:59Z | 2023-04-16T20:05:36Z | https://github.com/matterport/Mask_RCNN/issues/2286 | [] | BheemReddySoumyaReddy25 | 1 |
sczhou/CodeFormer | pytorch | 42 | Testing Datasets | Hi.
Thanks for the awesome work.
How could I get the testing datasets (e.g., CelebA-Test, WIDER-Test) used in your paper? | closed | 2022-10-05T06:42:18Z | 2022-10-05T07:55:00Z | https://github.com/sczhou/CodeFormer/issues/42 | [] | achusky | 1 |
stitchfix/hamilton | numpy | 41 | Prototype Data Quality Feature | **Is your feature request related to a problem? Please describe.**
When creating pipelines, data issues can silently wreak havoc; your code didn't change but the data did and now things are wonky...
To combat that, there are projects like [pandera](https://pandera.readthedocs.io/en/stable/) that allow you to annota... | closed | 2022-02-01T00:19:16Z | 2022-07-13T17:07:04Z | https://github.com/stitchfix/hamilton/issues/41 | [
"enhancement",
"product idea"
] | skrawcz | 8 |
ultralytics/ultralytics | pytorch | 18,903 | What is YOLOv11's training configurations to reproduce the reported COCO results? | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
I have reviewed the related issues, and I believe my training hyperparameter... | closed | 2025-01-26T14:42:14Z | 2025-01-27T01:35:54Z | https://github.com/ultralytics/ultralytics/issues/18903 | [
"question",
"detect"
] | sunsmarterjie | 6 |
0xTheProDev/fastapi-clean-example | pydantic | 7 | What naming convention is used in this project | Hi,
It would be great if you could clarify the naming convention used in the project for naming class, methods and variables. | closed | 2023-04-12T09:20:15Z | 2023-04-25T07:36:13Z | https://github.com/0xTheProDev/fastapi-clean-example/issues/7 | [] | Wrufesh | 2 |
suitenumerique/docs | django | 155 | ✨(frontend) more place for the editor | ## Feature Request
Get more place to the editor. Don't limit the editor to the size of the screen.

| closed | 2024-08-02T15:18:01Z | 2024-08-06T10:29:07Z | https://github.com/suitenumerique/docs/issues/155 | [
"enhancement",
"frontend"
] | AntoLC | 0 |
paperless-ngx/paperless-ngx | machine-learning | 8,602 | [BUG] Same API call not giving same results when queried from different hosts | ### Description
I am getting different results for the document count overall and for inbox when querying the API from various devices. Also it does not conform with the statistics in the frontend
Query 1: https://my.paperless.com/api/tags/64/
Query 2: https://my.paperless.com//api/documents/
Postman (MacOS... | closed | 2025-01-04T21:28:23Z | 2025-02-04T03:05:12Z | https://github.com/paperless-ngx/paperless-ngx/issues/8602 | [
"not a bug"
] | DenisKevljanin | 5 |
modoboa/modoboa | django | 2,229 | Can't send/receive E-Mails internally/externally at all | # Impacted versions
* OS Type: Debian
* OS Version: 10
* Modoboa: 1.17.0
* installer used: Yes
* Webserver: Nginx
# Steps to reproduce
install dependencies, open ports
freshly install Modoboa with the installer
reboot server
go to mail.example.com
add a domain
make all the dns records
wait for checks... | closed | 2021-04-24T22:57:52Z | 2021-07-07T23:39:21Z | https://github.com/modoboa/modoboa/issues/2229 | [] | itzMiney | 7 |
keras-team/keras | tensorflow | 20,407 | Falied to load gru layer weights to gru cell, Layer 'gru_cell' expected 3 variables, but received 0 variables during loading | Using tensorflow 2.16.1 with keras 3.5.0 falied to load pretrained gru layers weights to a gru cell.
the tow layer are defined as below
For gru layers:
t_rnn_1 = keras.layers.GRU(units=64, return_sequences=True)(t_in_1)
t_rnn_2 = keras.layers.GRU(units=64, return_sequences=True)(t_rnn_1)
t_dense_c ... | closed | 2024-10-25T02:59:39Z | 2024-12-19T02:06:21Z | https://github.com/keras-team/keras/issues/20407 | [
"stat:awaiting response from contributor",
"stale",
"type:Bug"
] | victorVoice | 7 |
davidsandberg/facenet | computer-vision | 307 | validate on own dataset: tensor 'input:0' has different shape | Hi,
When trying to validate on my own data set with images that are 64x64 I set image size to 64 but it has an issue. It says
``` Cannot feed value of shape (100, 64, 64, 3) for Tensor u'input:0', which has shape '(?, 160, 160, 3)'```
Is there a way to reshape the placeholder or is the model architecture spec... | closed | 2017-06-02T19:44:33Z | 2017-07-15T16:22:15Z | https://github.com/davidsandberg/facenet/issues/307 | [] | ljstrnadiii | 2 |
ludwig-ai/ludwig | computer-vision | 3,676 | Error: unit test tests/ludwig/utils/test_image_utils.py::test_resize_image fails | **Describe the bug**
In the torch nightly, not distributed test suite, this test fails: `tests/ludwig/utils/test_image_utils.py::test_resize_image` with this error
```
> assert torch.equal(output_img, expected_img)
E assert False
E + where False = <built-in method equal of type object at 0x7f4b... | closed | 2023-09-28T22:24:34Z | 2023-09-29T15:46:28Z | https://github.com/ludwig-ai/ludwig/issues/3676 | [] | jimthompson5802 | 0 |
miguelgrinberg/Flask-Migrate | flask | 223 | Changelog not up-to-date with v2.2.1 | Please add release notes for 2.2.1 | closed | 2018-08-21T09:52:17Z | 2018-08-22T08:20:23Z | https://github.com/miguelgrinberg/Flask-Migrate/issues/223 | [] | basvdheuvel | 0 |
microsoft/nni | deep-learning | 5,679 | Comparison exception: The values for attribute 'shape' do not match: torch.Size([]) != torch.Size([1, 1, 40, 40, 2]). | **Describe the issue**:
I prune yolov7 model with L1Pruner. I followed this guide https://github.com/microsoft/nni/blob/master/examples/compression/pruning/norm_pruning.py . I added this code after this line https://github.com/WongKinYiu/yolov7/blob/84932d70fb9e2932d0a70e4a1f02a1d6dd1dd6ca/train.py#L100
```
from... | open | 2023-09-17T09:08:59Z | 2024-02-26T01:29:47Z | https://github.com/microsoft/nni/issues/5679 | [] | aidevmin | 7 |
pydantic/pydantic-ai | pydantic | 1,093 | Response caching | ### Description
If I embed Pydantic AI into a system that is much larger than it is, I will sometimes want to debug the rest of the system without burning through API tokens and minutes. For this purpose, some competitive APIs like LiteLLM provide a caching layer.
https://docs.litellm.ai/docs/caching/all_caches
http... | open | 2025-03-10T18:35:51Z | 2025-03-22T18:46:52Z | https://github.com/pydantic/pydantic-ai/issues/1093 | [] | prescod | 2 |
pallets-eco/flask-sqlalchemy | flask | 463 | Why Flask-SqlAlchemy instead of pure SqlAlchemy? | Why should I use this module instead of the pure sqlalchemy? | closed | 2017-01-16T18:54:34Z | 2020-12-05T21:18:11Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/463 | [] | theobouwman | 1 |
nteract/papermill | jupyter | 251 | Cannot run papermill from a virtual environment - NoSuchKernel error | Hello,
I am trying to execute a ipython notebook using the CLI (or papermil.execute_notebook) but get a NoSuchKernel error. Is there anything to do to configure the Kernel before running papermill?
The virtual environment was created with `pipenv install papermill` and entered using `pipenv shell`
```
(test_p... | closed | 2018-11-12T11:19:38Z | 2021-07-08T13:11:40Z | https://github.com/nteract/papermill/issues/251 | [] | eapetitfils | 9 |
ageitgey/face_recognition | machine-learning | 879 | Detecting face from Uploaded files in aiohttp. RuntimeError: Expected writable numpy.ndarray with shape set. | * face_recognition version: 1.2.3
* Python version: 3.7.3
* Operating System: Mac 10.14.4
### Description
I wrote a small microservice in which I was getting images in HTTP POST requests and I was trying to recognize them and save their encodings into the database so that no existing face comes again.
It wa... | open | 2019-07-08T07:40:43Z | 2019-07-08T07:40:43Z | https://github.com/ageitgey/face_recognition/issues/879 | [] | hassanAwanAlvi | 0 |
huggingface/datasets | computer-vision | 7,268 | load_from_disk | ### Describe the bug
I have data saved with save_to_disk. The data is big (700Gb). When I try loading it, the only option is load_from_disk, and this function copies the data to a tmp directory, causing me to run out of disk space. Is there an alternative solution to that?
### Steps to reproduce the bug
when trying ... | open | 2024-10-31T11:51:56Z | 2024-10-31T14:43:47Z | https://github.com/huggingface/datasets/issues/7268 | [] | ghaith-mq | 1 |
ray-project/ray | tensorflow | 50,942 | Release test long_running_serve_failure.aws failed | Release test **long_running_serve_failure.aws** failed. See https://buildkite.com/ray-project/release/builds/34295#01954657-db9b-4031-85cc-6dc7cb1de7b7 for more details.
Managed by OSS Test Policy | closed | 2025-02-27T08:15:09Z | 2025-02-28T05:19:36Z | https://github.com/ray-project/ray/issues/50942 | [
"bug",
"P0",
"triage",
"serve",
"release-test",
"ray-test-bot",
"weekly-release-blocker",
"stability"
] | can-anyscale | 1 |
mitmproxy/pdoc | api | 387 | Naming Style Consistent | Hi, when I look through the source code and document online, I found most cases, the name of the attributes is snake case, like `own_members, class_variables, instance_variables`, but `classmethods, staticmethods ` are not.
Are there concerns regarding this?
I am happy to submit the PR and keep the naming style co... | closed | 2022-04-27T13:18:33Z | 2022-04-27T13:25:45Z | https://github.com/mitmproxy/pdoc/issues/387 | [
"enhancement"
] | Max-ChenFei | 1 |
zihangdai/xlnet | nlp | 238 | How do we mask and predict words in sentence in xlnet? how to do next word prediction in xlnet? | First of all thanks XLnet community.
I am actually beginner for XLnet.
I want to do **Next word prediction by using XLnet.** How can i do this?
and I have my own domain-specific datasets(1000 lines), finetune this dataset in xlnet.
is this dataset enoughfor us to get good results? | open | 2019-10-07T04:43:40Z | 2019-10-07T04:50:18Z | https://github.com/zihangdai/xlnet/issues/238 | [] | MuruganR96 | 0 |
deepinsight/insightface | pytorch | 2,634 | About test_res | In the document, it says:
If you need to run test cases, you will need to download the required [resource files](https://drive.google.com/file/d/1i4uC-dZTQxdVgn2rP0ZdfJTMkJIXgYY4/view?usp=sharing): test_res.
But when I visit this url, it seems the resource is not available. So, where can I get these resources? | open | 2024-08-19T11:31:59Z | 2024-08-23T07:34:48Z | https://github.com/deepinsight/insightface/issues/2634 | [] | jeyawn | 1 |
STVIR/pysot | computer-vision | 49 | No module named 'pysot | I have
export PYTHONPATH=/home/cbl/PycharmProjects/pysot-master/pysot:$PYTHONPATH | closed | 2019-06-14T06:49:35Z | 2019-06-14T07:49:03Z | https://github.com/STVIR/pysot/issues/49 | [] | ghost | 6 |
ultralytics/yolov5 | pytorch | 12,805 | low validation accuracy at the end of 300 epochs | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
Hi team,
I have added extra layers to the yolov5 model with 214 layers to increase the... | closed | 2024-03-10T19:32:59Z | 2024-04-21T00:22:47Z | https://github.com/ultralytics/yolov5/issues/12805 | [
"question",
"Stale"
] | geekdreamer04 | 2 |
WZMIAOMIAO/deep-learning-for-image-processing | deep-learning | 721 | yolov3_spp正负样本匹配device设置 | > https://github.com/WZMIAOMIAO/deep-learning-for-image-processing/blob/80681e81327320a37cfc35b754d8204a5156e9c2/pytorch_object_detection/yolov3_spp/build_utils/utils.py#L287
在跑模型时跳的bug,`at`的device为cpu,下面需要添加一行
`at = at.to(targets.device)`
| open | 2023-03-02T01:46:19Z | 2023-10-13T10:42:54Z | https://github.com/WZMIAOMIAO/deep-learning-for-image-processing/issues/721 | [] | jiaerfei | 2 |
paperless-ngx/paperless-ngx | django | 8,566 | [BUG] media folder - some folders are missing in archive | ### Description
The folder structure of the media folder ist not equal. Some folders are missing and the files within. Folder pathes are used for the structure.
In some rare cases, the "orginals" folder looks like expected, and the "archive" folder is not in sync.
There are differences in the folder structure ... | closed | 2024-12-29T23:02:38Z | 2024-12-30T00:36:49Z | https://github.com/paperless-ngx/paperless-ngx/issues/8566 | [
"not a bug"
] | Puffo19 | 1 |
graphdeco-inria/gaussian-splatting | computer-vision | 946 | The latest code merge has brought about new problems into render.py | 
| open | 2024-08-25T11:57:33Z | 2024-08-26T09:47:02Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/946 | [] | haggleSS | 3 |
newpanjing/simpleui | django | 183 | 使用 simpleui 后, collectstatic 出现大量异常输出 | **bug描述**
简单的描述下遇到的bug:
使用 pip install 的方式安装的 simpleui, 然后每次 python manage.py collectstatic 时, 会出现大量的异常标准输出, 类似如下:
If this is not what you want, make sure every static file has a unique path.
Found another file with the destination path 'admin/img/tooltag-arrowright.svg'. It will be ignored since only th... | closed | 2019-11-22T04:02:10Z | 2019-11-22T05:33:20Z | https://github.com/newpanjing/simpleui/issues/183 | [
"bug"
] | lowmanisbusy | 2 |
graphql-python/graphene-django | django | 1,007 | Unreliable reload_graphene_settings | `reload_graphene_settings` creates a new settings object, so settings imported via `from .settings import graphene_settings` don't get reloaded. | open | 2020-07-21T16:14:47Z | 2020-07-21T16:14:47Z | https://github.com/graphql-python/graphene-django/issues/1007 | [
"🐛bug"
] | andriilahuta | 0 |
sgl-project/sglang | pytorch | 4,703 | Failed to deploy the [microsoft--Phi-3-small-128k-instruct] model | Greetings, everyone.
Corresponding to title, I use following command to deploy the [microsoft--Phi-3-small-128k-instruct] model:
python -m sglang.launch_server --model-path /home/nvidia/.cache/huggingface/hub/models--microsoft--Phi-3-small-128k-instruct/snapshots/ad85cab62be398dc90203c4377a4ccbf090fbb36 --host 0.0.0.... | closed | 2025-03-24T02:35:25Z | 2025-03-24T15:19:26Z | https://github.com/sgl-project/sglang/issues/4703 | [] | sdecoder | 2 |
joeyespo/grip | flask | 7 | Add argument to render GitHub-Flavored Markdown | Like the [Markdown Rendering API](http://developer.github.com/v3/markdown/), provide a mechanism for rendering GitHub-Flavored Markdown instead of the default of plain Markdown.
Suggested argument is `--gfm`
| closed | 2012-12-07T04:10:07Z | 2013-09-06T13:11:37Z | https://github.com/joeyespo/grip/issues/7 | [
"enhancement"
] | joeyespo | 1 |
opengeos/leafmap | streamlit | 822 | Exclude Unnamed Layers from Layer Manager Widget | <!-- Please search existing issues to avoid creating duplicates. -->
### Environment Information
- leafmap version: 0.35.8
- Python version: 3.9.19
### Description
The "layer_manager_gui" function currently adds all layers, including unnamed ones, to the the layer manager widget. These layers did not e... | closed | 2024-07-12T09:08:34Z | 2024-07-12T16:53:25Z | https://github.com/opengeos/leafmap/issues/822 | [
"bug"
] | MolZoo | 0 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 841 | 执行 cycle预训练权重 第三步的时候 我这里报错 说不支持同时切割多个维度 | File "/root/miniconda3/envs/pytorch-CycleGAN-and-pix2pix/lib/python3.5/site-packages/torch/jit/frontend.py", line 422, in build_Subscript
raise NotSupportedError(base.range(), "slicing multiple dimensions at the same time isn't supported yet")
torch.jit.frontend.NotSupportedError: slicing multiple dimensions at ... | open | 2019-11-14T10:31:00Z | 2019-11-14T10:31:00Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/841 | [] | zhihaoWang1994 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.