
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
pytest-dev/pytest-randomly | pytest | 242 | Provide reverse order | As a developer, I want to execute the tests in reverse order to reveal test dependencies.
Given that the natural order of execution is O={t1, ..., tn}, maybe provide a command line switch that allows to run all tests on reverse order reverse(O)={tn, ..., t1}.
Motivation:
An empirical study [0] on the test ind... | closed | 2020-04-03T17:09:07Z | 2020-05-11T16:02:37Z | https://github.com/pytest-dev/pytest-randomly/issues/242 | [] | thbde | 6 |
onnx/onnx | tensorflow | 6,022 | Equivalent Implementations to ScatterElements operator | ### Question
I am implementing a GNN model and compiling it using [Concrete ML](https://docs.zama.ai/concrete-ml), in which the underlying is an ONNX conversion using ONNX 1.13.1. However, Concrete ML has yet to implement the ScatterElements ONNX operator in their library, resulting in a `ValueError: The following ONN... | open | 2024-03-14T03:58:16Z | 2024-03-14T15:38:29Z | https://github.com/onnx/onnx/issues/6022 | [
"question"
] | fabecode | 3 |
koxudaxi/datamodel-code-generator | pydantic | 1,638 | Modular references require output directory error | **Describe the bug**
When working with a jsonschema and invoking the model generator, one encounters following error:
`Modular references require an output directory, not a file`
It appears that the naming causes this error
` "title": "GenomeStudio 2.0 - Methylation Module",
`
**To Reproduc... | open | 2023-10-23T20:57:49Z | 2023-11-08T15:54:24Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1638 | [
"enhancement"
] | yogeshVU | 1 |
jonaswinkler/paperless-ng | django | 246 | Changes to the logic of the OCRmyPDF parser. | There are a couple issues with it right now.
1. We could support automatic page rotation, there's support for that.
2. Options like `deskew` and `clean-final` don't work since paperless will occasionally use a mode that's incompatible with these options
3. For some documents, PDF conversion straight up fails.
4. ... | closed | 2021-01-02T00:40:05Z | 2021-02-22T21:52:38Z | https://github.com/jonaswinkler/paperless-ng/issues/246 | [
"feature request",
"fixed in next release"
] | jonaswinkler | 3 |
napari/napari | numpy | 7,044 | [test-bot] pip install --pre is failing | The --pre Test workflow failed on 2024-07-01 00:38 UTC
The most recent failing test was on windows-latest py3.12 pyqt6
with commit: b87e9c7e430b5ff98225a86b92233ca913a95ff0
Full run: https://github.com/napari/napari/actions/runs/9736077993
(This post will be updated if another test fails, as long as this issu... | closed | 2024-07-01T00:38:28Z | 2024-07-01T02:44:27Z | https://github.com/napari/napari/issues/7044 | [
"bug"
] | github-actions[bot] | 1 |
huggingface/pytorch-image-models | pytorch | 2,186 | [FEATURE] Chaining pooled output to classifier | ## Motivation
Chaining **un**pooled output to classifier has been [implemented](https://huggingface.co/docs/timm/feature_extraction#chaining-unpooled-output-to-classifier) and can be done as follows:
```python
model = timm.create_model('vit_medium_patch16_reg1_gap_256', pretrained=True)
output = model.forward_featu... | closed | 2024-05-24T18:49:42Z | 2024-05-27T22:35:36Z | https://github.com/huggingface/pytorch-image-models/issues/2186 | [
"enhancement"
] | ZeyuSun | 2 |
arogozhnikov/einops | tensorflow | 128 | [Feature suggestion] std in reduce? | Hi, I was calculating the per-channel mean and std of the video dataset so that I can normalize my input videos. Normally I would do something like this
```python
# number of videos = 74
# number of frames = 8
# image size = 224
# channel = RGB
videos = np.random.random((74, 8, 224, 224, 3))
videos = rearrange(v... | closed | 2021-07-20T16:50:02Z | 2021-11-03T08:56:24Z | https://github.com/arogozhnikov/einops/issues/128 | [
"wontfix",
"feature suggestion"
] | chris-tkinter | 2 |
biolab/orange3 | pandas | 6,067 | TAB/CSV files read differently on different operating systems | **What's wrong?**
Data from TAB/CSV files with `'` characters after delimiter (e.g. at the beginning of the sentence) are sometimes misread on Linux/macOS. Look at the next section for details.
**How can we reproduce the problem?**
1. Open File widget
2. Load https://github.com/biolab/orange3-text/blob/master/or... | open | 2022-07-20T13:41:12Z | 2023-01-10T10:58:58Z | https://github.com/biolab/orange3/issues/6067 | [
"bug"
] | PrimozGodec | 0 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 970 | I'm confused about the names of tests results | Hello, I run the cycle_gan model with --direction BtoA and I'm confused abut the names of the test results, despite reading all issues about it.
I have images with the following names
img_fake_A.png
img_fake_B.png
img_real_A.png
img_fake_B.png
img_rec_A.png
img_rec_B.png
can you pls explain what is the connec... | open | 2020-03-26T18:14:04Z | 2020-03-27T16:25:55Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/970 | [] | TavRotenberg | 1 |
Sanster/IOPaint | pytorch | 315 | Installing xformers? | How installing xformers? i got this error
ERROR: pip's dependency resolver does not currently take into account all the packages that are installed. This behaviour is the source of the following dependency conflicts.
xformers 0.0.20.dev526 requires torch==2.0.0, but you have torch 2.0.1 which is incompatible.
torc... | open | 2023-05-31T00:00:31Z | 2023-07-03T11:40:54Z | https://github.com/Sanster/IOPaint/issues/315 | [] | mitsuke-code | 2 |
huggingface/transformers | deep-learning | 36,001 | past_key_values not being set in model_inputs keys | ### System Info
`transformers-cli env`
```bash
Copy-and-paste the text below in your GitHub issue and FILL OUT the two last points.
- `transformers` version: 4.48.2
- Platform: Linux-5.15.167.4-microsoft-standard-WSL2-x86_64-with-glibc2.35
- Python version: 3.10.12
- Huggingface_hub version: 0.28.1
- Safetensors ver... | closed | 2025-02-01T11:06:26Z | 2025-03-12T08:03:52Z | https://github.com/huggingface/transformers/issues/36001 | [
"bug"
] | AEJaspan | 2 |
ARM-DOE/pyart | data-visualization | 1,260 | ENH: Add a new example showing hydrometeor classification and QPE functionality | At the recent ERAD tutorials, there were some great new tutorials put together by the meteoswiss/meteofrance team (@wolfidan @jfigui )
[Sample notebook](https://openradarscience.org/erad2022/notebooks/pyart/exercice1_swiss_thunderstorm.html)
It would be nice to have a concise example of this in our examples galle... | closed | 2022-09-14T15:42:30Z | 2022-11-08T14:49:43Z | https://github.com/ARM-DOE/pyart/issues/1260 | [
"component: pyart.retrieve",
"Docs"
] | mgrover1 | 3 |
pyqtgraph/pyqtgraph | numpy | 3,212 | Setting a better light source position for Pyqtgraph: GLMeshItem shaderProgram called 'shaded' | <!-- In the following, please describe your issue in detail! -->
<!-- If some sections do not apply, just remove them. -->
### Short description
I am using pyqtgraph.opengl for graphics and display of STL files on my UI. I am using phong shading technique called 'shaded' param with pyqtgraph.opengl.GLMeshItem API.... | open | 2025-01-07T07:08:47Z | 2025-01-07T08:08:08Z | https://github.com/pyqtgraph/pyqtgraph/issues/3212 | [] | nagarjunvinukonda | 1 |
d2l-ai/d2l-en | data-science | 2,424 | Policy Optimization and PPO | Dear all,
While the book currently has a small section on Reinforcement Learning covering MDPs, value iteration, and the Q-Learning algorithm, the book still does not cover an important family of algorithms: **Policy optimization algorithms**.
It'd be great to include an overview of the taxonomy of algorithms as ... | open | 2023-01-07T23:49:38Z | 2023-01-08T17:09:36Z | https://github.com/d2l-ai/d2l-en/issues/2424 | [] | BrianPulfer | 3 |
alirezamika/autoscraper | web-scraping | 21 | Cannot support Chinese | closed | 2020-09-12T07:28:14Z | 2020-09-13T18:13:54Z | https://github.com/alirezamika/autoscraper/issues/21 | [] | carrie-chris | 1 | |
serengil/deepface | machine-learning | 1,090 | Question: basemodel DbLib.py | Consider [this line](https://github.com/serengil/deepface/blob/dea697c6ec5b89375cdbc376aa680a10f4231c42/deepface/basemodels/Dlib.py#L67) in DbLib.py
```python
self.layers = [DlibMetaData()]
```
What exactly is this for ? (member layers is not accessed anywhere) | closed | 2024-03-10T14:46:32Z | 2024-03-10T14:59:28Z | https://github.com/serengil/deepface/issues/1090 | [
"enhancement"
] | AndreaLanfranchi | 2 |
3b1b/manim | python | 1,809 | The last segment of the geometry will suddenly disappear in the showpassingflash animation | Code:
s=Square()
c=Circle()
v=VGroup(s,c).arrange(RIGHT,buff=1)
self.play(ShowPassingFlash(v,time_width=1,run_time=4))
self.wait()
Output:
https://user-images.githubusercontent.com/101418800/167929000-e0e8a110-29fc-408e-82d0-ebf94f6f40d7.mp4
| open | 2022-05-11T19:16:34Z | 2022-05-17T06:09:20Z | https://github.com/3b1b/manim/issues/1809 | [
"bug"
] | inoxch | 1 |
alirezamika/autoscraper | web-scraping | 13 | Not very reasonable, a lot of things change |
Not very reasonable, a lot of things change | closed | 2020-09-10T07:31:31Z | 2020-09-10T13:33:58Z | https://github.com/alirezamika/autoscraper/issues/13 | [] | abbabb123 | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,520 | uc not working | uc is not bypassing even with me clicking manually
| closed | 2023-08-29T10:04:37Z | 2023-09-19T12:30:38Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1520 | [] | devCanario | 3 |
ClimbsRocks/auto_ml | scikit-learn | 397 | Serving predictions through AWS Lambda? | Has anyone served auto_ml predictions using AWS lambda? I tried, per the normal process of creating a lambda deployment package I was getting the libraries as I received error messages that they were needed. I bundled auto_ml, dill, deap, pathos, then pp, and then the next error I received was "cannot import name '_... | open | 2018-04-16T22:03:18Z | 2018-04-16T22:03:18Z | https://github.com/ClimbsRocks/auto_ml/issues/397 | [] | JonHolman | 0 |
miguelgrinberg/python-socketio | asyncio | 192 | Invalid HTTP method | I got the aio example running but it did throw some errors. I was still able to connect via browser and test everything out. Still, here's what I got when I started up https://github.com/miguelgrinberg/python-socketio/blob/master/examples/aiohttp/app.py
```
======== Running on http://0.0.0.0:8080 ========
(Press C... | closed | 2018-07-15T20:33:10Z | 2019-01-13T22:22:10Z | https://github.com/miguelgrinberg/python-socketio/issues/192 | [
"question"
] | bitnom | 2 |
ultralytics/ultralytics | machine-learning | 18,893 | The docker image with jupyter tag doesn't support GPU? | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
I am trying to do some experiments on ultralytics/ultralytics:8.3.67-jupyte... | open | 2025-01-25T23:04:58Z | 2025-01-29T11:12:27Z | https://github.com/ultralytics/ultralytics/issues/18893 | [
"question",
"devops"
] | darouwan | 5 |
fastapi-users/fastapi-users | asyncio | 1,224 | Unable to install library on Mac M1 | ## Describe the bug
I'm trying to install the library in a virtualenv with the command
```
pip install 'fastapi-users[sqlalchemy]'
```
but I receive the following error
```
Collecting fastapi-users[sqlalchemy]
Using cached fastapi_users-11.0.0-py3-none-any.whl (38 kB)
Requirement already satisfied: ema... | closed | 2023-06-08T09:37:59Z | 2023-06-08T11:20:19Z | https://github.com/fastapi-users/fastapi-users/issues/1224 | [
"bug"
] | michele-grifa | 0 |
deepset-ai/haystack | pytorch | 8,627 | Investigate the possibility of removing `dataframe` field from `Document` | I've been thinking about dropping the `Dataframe` field in Haystack `Document` dataclass for a few reasons:
- Users are already using text representations (CSV, Markdown) that LLMs handle great - even for originally tabular data
- Pandas `DataFrame` creates serialization headaches. (e.g. in Hayhooks)
- Pandas is a... | closed | 2024-12-11T17:21:38Z | 2025-01-16T14:57:18Z | https://github.com/deepset-ai/haystack/issues/8627 | [
"P2"
] | anakin87 | 3 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 789 | Works in Spanish? | closed | 2021-07-06T02:14:51Z | 2022-08-03T17:04:08Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/789 | [] | johnfelipe | 31 | |
LibreTranslate/LibreTranslate | api | 303 | Switch Languages Button not visible in Dark Mode | This is just a small display problem:

I fixed it by adding `color: white;` to the element:
.find({'$text': {'$search': 'Olympus Corportion'}}, {'score': {'$meta': 'textScore'}}).sort({'score': {'$meta': 'textScore'}})
```
What should I do? | closed | 2019-06-12T08:56:58Z | 2019-12-16T10:21:05Z | https://github.com/pyeve/eve/issues/1287 | [
"stale"
] | yuri2peter | 1 |
python-visualization/folium | data-visualization | 1,907 | backslashes in popup break page. | **Describe the bug**
It seems if a backslash followed by a number is included in the text of a popup, the map will fail to generate. Once the map is generated, if an attempt to load the map is map, no map is displayed and the following error is present in the browser console.
```
Uncaught SyntaxError: octal escape s... | open | 2024-03-24T21:14:31Z | 2024-05-18T14:16:45Z | https://github.com/python-visualization/folium/issues/1907 | [
"bug"
] | jrjdavidson | 9 |
OpenVisualCloud/CDN-Transcode-Sample | dash | 22 | The time format display incorrect when first time playing dash stream in VOD mode | [Issue Description]
The time format display incorrect when first time playing dash stream in VOD mode. After the first transcoding is completed, the time format will be normal.
On Chrome browser, the time shows “-14:-8”.
On Firefox browser, the time shows “2501999792983:36:31”.
On Microsoft Edge, the time shows “59... | open | 2019-04-24T05:28:59Z | 2019-07-10T05:05:42Z | https://github.com/OpenVisualCloud/CDN-Transcode-Sample/issues/22 | [] | enzomao | 4 |
pytest-dev/pytest-cov | pytest | 627 | no-data-collected under unix when using filterwarnings in pytest.ini | # Summary
First of all sorry for this incomplete bug report (no reproducer). Feel free to close it, but I figured it might still help somebody.
The problem is that the coverage data collection fails if the `filterwarnings` option in `pytest.ini` is used to ignore a custom warning defined in our project, but only ... | closed | 2024-01-05T13:59:38Z | 2024-09-17T22:32:04Z | https://github.com/pytest-dev/pytest-cov/issues/627 | [] | mariuswallraff | 5 |
MaartenGr/BERTopic | nlp | 1,952 | Huggingface transformer does not load as expected | Hello,
Instead of using `sentence-transformers/all-MiniLM-L6-v2`, I wanted to try out a custom embedding model from Huggingface. I read previous opened and closed issues and found the following approaches:

y = np.array([0, 0, 1, 1] * FAC... | open | 2024-11-19T18:22:19Z | 2024-11-23T19:15:33Z | https://github.com/statsmodels/statsmodels/issues/9428 | [] | louisabraham | 4 |
kaliiiiiiiiii/Selenium-Driverless | web-scraping | 221 | Can I use it in selenium grid | I want to run this in selenium grid, how can i do it | closed | 2024-05-09T09:43:12Z | 2024-05-09T12:42:53Z | https://github.com/kaliiiiiiiiii/Selenium-Driverless/issues/221 | [] | razzl | 1 |
newpanjing/simpleui | django | 515 | django5.1.7中安装simpleui,fore_text报错 | **bug描述**
* *Bug description * *
简单的描述下遇到的bug:
Briefly describe the bugs encountered:
**重现步骤**
** repeat step **
1.
2.
3.
**环境**
** environment**
1.Operating System:
(Windows/Linux/MacOS)....
2.Python Version:
3.Django Version:
4.SimpleUI Version:
**Description**
| open | 2025-03-23T15:16:19Z | 2025-03-23T15:16:19Z | https://github.com/newpanjing/simpleui/issues/515 | [
"bug"
] | yemaobumei | 0 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 236 | Automate Cover Letter Reuse Across Multiple Job Applications | Currently, the program successfully applies to Company X and generates a tailored cover letter for that application. However, for subsequent applications to different companies, the same cover letter is reused. | closed | 2024-09-02T07:49:35Z | 2024-09-03T14:37:15Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/236 | [] | gorkenvm | 4 |
jupyterhub/zero-to-jupyterhub-k8s | jupyter | 2,955 | Setup on AWS: Validation error cluster not yet healthy | I was following the documentation [here](https://z2jh.jupyter.org/en/stable/kubernetes/amazon/step-zero-aws.html) to setup k8s on AWS and on step 12, at `kops validate cluster`, I was getting `Validation Failed
Error: Validation failed: cluster not yet healthy`
The debug message in `kops validate cluster` was:
```... | closed | 2022-11-24T07:53:30Z | 2022-11-29T14:09:30Z | https://github.com/jupyterhub/zero-to-jupyterhub-k8s/issues/2955 | [
"documentation"
] | arunppsg | 1 |
scikit-optimize/scikit-optimize | scikit-learn | 462 | sklearn-0.19: deprecation warnings of y_train_mean | In sklearn-0.19, the `y_train_mean` of `GaussianProcessorRegressor` has been deprecated. See:
https://github.com/scikit-learn/scikit-learn/blob/ec0dbf0399c4187a1d17e66de17265c67588373f/sklearn/gaussian_process/gpr.py#L153
This results in tons of warnings, as scikit-optimize itself depends on this attribute, at http... | closed | 2017-08-03T13:10:01Z | 2017-08-06T11:00:38Z | https://github.com/scikit-optimize/scikit-optimize/issues/462 | [
"Bug",
"Easy"
] | glouppe | 9 |
fastapi-users/fastapi-users | asyncio | 1,335 | forget password return null in responce body instead of token ? | ## Describe the bug
A clear and concise description of what the bug is.
## To Reproduce
Steps to reproduce the behavior:
1. Go to '...'
2. Click on '....'
3. Scroll down to '....'
4. See error
## Expected behavior
A clear and concise description of what you expected to happen.
## Configuration
-... | closed | 2024-01-05T13:21:39Z | 2024-01-05T13:30:10Z | https://github.com/fastapi-users/fastapi-users/issues/1335 | [
"bug"
] | udayzee05 | 0 |
wkentaro/labelme | computer-vision | 633 | Question about group ID | I'm labeling for a instances segmentation project. The number of my class is one. And the class is cow. I notice that there is a new option group ID. I know I need to fill the object label with cow-1, cow-2... But the group ID of them should be the same or not? | closed | 2020-03-26T14:17:56Z | 2022-06-25T05:12:42Z | https://github.com/wkentaro/labelme/issues/633 | [] | Coconut443 | 15 |
deeppavlov/DeepPavlov | tensorflow | 1,218 | Warnings in basic_clasf_reader for valid and test files | An absence of valid-test files shouldn't be a reason for [warnings](https://github.com/deepmipt/DeepPavlov/blob/master/deeppavlov/dataset_readers/basic_classification_reader.py#L109)
because this is expected behavior when I pass only test.csv file and split data in data-iterator
It can be a `log.info` but even better... | closed | 2020-05-14T15:23:39Z | 2020-05-27T15:09:46Z | https://github.com/deeppavlov/DeepPavlov/issues/1218 | [] | grayskripko | 4 |
axnsan12/drf-yasg | django | 703 | django drf-yasg with_ui url does not identify | hi when I add drf_yasg urls in the urls.py the with_ui method doesn't identify and work.
urlpatterns = [
url(r'^swagger(?P<format>\.json|\.yaml)$', schema_view.without_ui(cache_timeout=0), name='schema-json'),
url(r'^swagger/$', schema_view.with_ui('swagger', cache_timeout=0), name='schema-swagger-ui'),
... | open | 2021-02-22T08:35:38Z | 2025-03-07T12:12:57Z | https://github.com/axnsan12/drf-yasg/issues/703 | [
"triage"
] | hossein-shahsavan | 0 |
tensorflow/tensor2tensor | machine-learning | 1,920 | Aadm is slower than Adafactor | Hi,
I found that training Transformers with Adam is three times slower than with Adafactor.
Here is the command I am using for Adam:
```
t2t-trainer \
--data_dir=./t2t/t2t_data \
--problem=translate_ende_wmt32k \
--model=transformer \
--hparams_set=transformer_base \
--hparams="batch_size=1024,learni... | open | 2022-11-26T12:00:10Z | 2022-11-26T12:00:10Z | https://github.com/tensorflow/tensor2tensor/issues/1920 | [] | shizhediao | 0 |
Johnserf-Seed/TikTokDownload | api | 443 | [BUG]根据作品发布日期区间下载作品似乎失效 | **描述出现的错误**
conf.ini文件中的[interval]参数配置后下载时未生效。
https://github.com/Johnserf-Seed/TikTokDownload/blob/a5359ee44a271c3ebd31dfe8a4b6a1df11b1e929/conf.ini#LL23C1-L28C13
**bug复现**
复现这次行为的步骤:
根据参数提示设置为interval = 2023-05-01|2023-06-01
**截图**
",
"额外求助(help wanted)",
"无效(invalid)"
] | hex0317 | 2 |
quokkaproject/quokka | flask | 365 | [Possible python3 bug] Always an extra "None" author added to every post | When creating a new post on python 3.5.2 with a single author, there always appears another author of None appended to the list when pulling content.get_authors() from templates, this causes the multiple authors code in the pure theme to subsequently crash when it can't pull the display name of None.
Line 45, quokka/t... | closed | 2016-07-12T05:35:45Z | 2016-07-18T20:47:59Z | https://github.com/quokkaproject/quokka/issues/365 | [
"bug"
] | Roukoswarf | 3 |
NullArray/AutoSploit | automation | 960 | Divided by zero exception336 | Error: Attempted to divide by zero.336 | closed | 2019-04-19T16:03:50Z | 2019-04-19T16:35:38Z | https://github.com/NullArray/AutoSploit/issues/960 | [] | AutosploitReporter | 0 |
openapi-generators/openapi-python-client | fastapi | 1,060 | Can't generate client for spec with refs in allOf | **Describe the bug**
I'm attempting to use openapi-python-client to generate a client for the new [XPipe API](https://github.com/xpipe-io/xpipe/blob/master/openapi.yaml), but it's failing with "Cannot take allOf a non-object". I've boiled it down to the following minimal reproducer. I *think* what the original spec ... | closed | 2024-06-16T23:18:09Z | 2024-06-16T23:55:31Z | https://github.com/openapi-generators/openapi-python-client/issues/1060 | [] | coandco | 1 |
sinaptik-ai/pandas-ai | data-visualization | 1,289 | Docker build failing - | ### System Info
Latest code from repo
### 🐛 Describe the bug
RUN poetry install --no-root
Installing dependencies from lock file
Package operations: 81 installs, 1 update, 0 removals
- Installing idna (3.7)
- Installing sniffio (1.3.1)
- Installing anyio (4.4.0)
- Installing certifi (2024.7.4)
- Instal... | closed | 2024-07-22T22:25:36Z | 2024-10-16T08:30:40Z | https://github.com/sinaptik-ai/pandas-ai/issues/1289 | [
"bug"
] | jithin77 | 1 |
coleifer/sqlite-web | flask | 32 | basic auth | Is there a simple way to require authentication when accessing the web page? | closed | 2017-06-02T18:03:36Z | 2017-06-02T19:51:38Z | https://github.com/coleifer/sqlite-web/issues/32 | [] | erpadmin | 2 |
pytorch/vision | computer-vision | 8,713 | `torchvision.ops.boxes.batched_nms` slow on large box numbers | ### 🐛 Describe the bug
## Description
`torchvision.ops.boxes.batched_nms` on CUDA GPU slows down considerably when then number of bounding boxes involved increases.
The slow down is associated with Device -> Host transfer, and is linked to the iterative part of the Non Maximum Suppression (NMS) algorithm. In a ... | closed | 2024-11-06T12:58:13Z | 2025-02-20T17:16:10Z | https://github.com/pytorch/vision/issues/8713 | [] | Ghelfi | 1 |
marshmallow-code/flask-smorest | rest-api | 264 | define requestInterceptor to handle XSRF cookie to header inside Swagger UI | I'm using flask-security to generate session and csrf tokens. It set's a cookie and the web frontend is expected to copy that cookie to every model-changing request.
Swagger offers the [requestInterceptor](https://github.com/swagger-api/swagger-ui/blob/master/docs/usage/configuration.md#network) option to define a f... | open | 2021-07-29T10:48:36Z | 2021-07-29T22:46:01Z | https://github.com/marshmallow-code/flask-smorest/issues/264 | [] | heeplr | 4 |
pytest-dev/pytest-mock | pytest | 82 | Usage examples are really needed. | The README is extensive but does not a single runnable example. | closed | 2017-04-24T08:40:32Z | 2017-04-24T13:44:44Z | https://github.com/pytest-dev/pytest-mock/issues/82 | [] | gtzampanakis | 5 |
slackapi/python-slack-sdk | asyncio | 1,268 | Unable run script through large number of user accounts | (Filling out the following details about bugs will help us solve your issue sooner.)
### Reproducible in:
```bash
pip freeze | grep
python --version Python
sw_vers && uname -v # or `ver`
```
#### The Slack SDK version
Installed on windows
slack_sdk 3.15.1
(Paste the output of `pip freeze | grep slack`... | closed | 2022-09-21T13:30:21Z | 2022-09-21T17:10:16Z | https://github.com/slackapi/python-slack-sdk/issues/1268 | [
"question"
] | plegault3397 | 3 |
tensorpack/tensorpack | tensorflow | 1,414 | Throughput monitor in distributed training using Horovod trainer | Hi, @ppwwyyxx. I encountered a problem that I couldn't understand.
I am training FasterRCNN provided in the example and using custom datasets. The training environment is two nodes with 16 GPUs (8 GPUs in each node).
I firstly train this model on one node (8GPUs), the throughput is 40 images/s. However, when I ... | closed | 2020-03-30T08:17:02Z | 2020-03-30T18:43:33Z | https://github.com/tensorpack/tensorpack/issues/1414 | [] | jiangzihanict | 4 |
JaidedAI/EasyOCR | machine-learning | 760 | How to create the files for running a custom model? | The EasyOCR ReadME states that the following three files are required to use a custom model:
custom_model.pth, custom_model.yaml, and custom_model.py.
How are we supposed to create the custom_model.yaml and custom_model.py files?
Are we supposed to copy functions / classes from modules.py? If so, TPS and Attenti... | open | 2022-06-20T11:39:14Z | 2024-07-19T21:43:21Z | https://github.com/JaidedAI/EasyOCR/issues/760 | [] | sameearif88 | 2 |
wandb/wandb | tensorflow | 8,924 | [Bug]: | ### Describe the bug
wandb version: '0.18.6'
python version: 3.11.4
NAME="Ubuntu"
VERSION="18.04.6 LTS (Bionic Beaver)"
ID=ubuntu
ID_LIKE=debian
PRETTY_NAME="Ubuntu 18.04.6 LTS"
VERSION_ID="18.04"
HOME_URL="https://www.ubuntu.com/"
SUPPORT_URL="https://help.ubuntu.com/"
BUG_REPORT_URL="https://bugs.launchpad.net/ubunt... | closed | 2024-11-20T04:32:08Z | 2024-11-20T14:35:05Z | https://github.com/wandb/wandb/issues/8924 | [
"ty:bug",
"a:sdk"
] | waltsims | 2 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 787 | Datasets cannot be downloaded | hi! I cannot download datasets for cyclegan for testing model. Please Help!

| closed | 2019-10-10T15:46:01Z | 2019-10-11T17:00:00Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/787 | [] | coditive | 5 |
microsoft/nni | deep-learning | 5,409 | darts.py example not working in /nni/examples/tutorials/darts.py | **Describe the issue**:
darts.py is not working.
**Environment**: Windows 10
- NNI version: 2.10
- Training service (local|remote|pai|aml|etc): local
- Client OS: Windows 10
- Server OS (for remote mode only): N/A
- Python version: 3.8.10
- PyTorch/TensorFlow version: torch==1.13.1+cu116, tensorflow==2.10.0... | closed | 2023-02-27T18:10:23Z | 2023-03-02T01:45:57Z | https://github.com/microsoft/nni/issues/5409 | [] | Tyler-Jay-Stevahn | 5 |
aio-libs-abandoned/aioredis-py | asyncio | 750 | xread returns nothing | Redis 6.0.3
Python: 3.8.2
aioredis: 1.3.1
Nothing is returned by xread in aioredis. redis-cli returns the stream properly.
```
import asyncio
import aioredis
loop = asyncio.get_event_loop()
async def main():
stream = 'chennai'
fields = {
'foo': 'bar'
}
redis = await ai... | closed | 2020-05-21T07:18:10Z | 2020-05-22T00:07:51Z | https://github.com/aio-libs-abandoned/aioredis-py/issues/750 | [] | bitnom | 2 |
PablocFonseca/streamlit-aggrid | streamlit | 99 | ImportError: cannot import name 'QUOTE_NONNUMERIC' | when i try this example, it do not worked.
```url
https://share.streamlit.io/pablocfonseca/streamlit-aggrid/main/examples/example.py?example=Fixed%20Key%20Parameter
``` | closed | 2022-06-08T08:56:43Z | 2024-04-04T17:53:22Z | https://github.com/PablocFonseca/streamlit-aggrid/issues/99 | [] | AlitaIcon | 0 |
deezer/spleeter | deep-learning | 252 | [Bug] anaconda window goes crazy | <!-- PLEASE READ THIS CAREFULLY :
- Any issue which does not respect following template or lack of information will be considered as invalid and automatically closed
- First check FAQ from wiki to see if your problem is not already known
-->
## Description
Running spleeter windows 10, anaconda prompt screen wa... | open | 2020-01-28T09:29:33Z | 2020-04-15T09:51:31Z | https://github.com/deezer/spleeter/issues/252 | [
"bug",
"invalid"
] | smoratti | 1 |
dunossauro/fastapi-do-zero | sqlalchemy | 330 | Atualizar a página inicial - "O que você vai aprender" | Diversas coisas foram adicionadas desde que essa sessão foi criada, devemos atualizar:
https://fastapidozero.dunossauro.com/#o-que-voce-vai-aprender | closed | 2025-02-28T18:06:19Z | 2025-03-07T11:40:11Z | https://github.com/dunossauro/fastapi-do-zero/issues/330 | [] | dunossauro | 0 |
MorvanZhou/tutorials | numpy | 20 | can not get the graph | hi , I used your code , and run in the terminal , but i can not get the graph as your video shows , can you explain and try again whether the code has left some sentence . thanks | closed | 2016-11-05T12:44:03Z | 2016-11-11T16:51:57Z | https://github.com/MorvanZhou/tutorials/issues/20 | [] | WoNiuHu | 11 |
fastapi/sqlmodel | pydantic | 228 | Unable to use original type hint by defining relationship | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | open | 2022-01-19T02:43:47Z | 2024-11-14T10:22:24Z | https://github.com/fastapi/sqlmodel/issues/228 | [
"question"
] | Whitroom | 5 |
gradio-app/gradio | machine-learning | 9,991 | Using `gr.render()` leads to RuntimeError: dictionary changed size during iteration | ### Describe the bug
Hello. I often get this error stack when I use gradio to draw a complex page in one page.
I think it is same issue #9410.
I tried to find, why this issue is occurred. I created a reproduction code by reading the relevant code while looking at the error stack.
I think the reason is `render` ... | closed | 2024-11-19T03:01:52Z | 2024-11-28T17:42:16Z | https://github.com/gradio-app/gradio/issues/9991 | [
"bug",
"pending clarification"
] | BLESS11186 | 6 |
modin-project/modin | data-science | 7,232 | Remove Series.dt.to_timestamp | There's no such method in pandas: https://github.com/modin-project/modin/blob/9fa326f6fd53eb0e3192b3eca72382a6388117fe/modin/pandas/series_utils.py#L823 | open | 2024-04-30T12:14:51Z | 2024-05-01T07:40:17Z | https://github.com/modin-project/modin/issues/7232 | [
"pandas concordance 🐼",
"P3"
] | sfc-gh-mvashishtha | 3 |
ccxt/ccxt | api | 24,677 | Blofin - fetch_ohlcv is not working properly, especially "since" | ### Operating System
Linux Debian12
### Programming Languages
Python
### CCXT Version
4.4.43
### Description
I could swear it worked last month, but maybe Blofin has changed the API.
In the function you can enter any value under “since”, it only ever returns the last 1000 values.
Does anyone have a soluti... | open | 2024-12-28T12:37:12Z | 2024-12-29T09:17:31Z | https://github.com/ccxt/ccxt/issues/24677 | [
"question"
] | AltePfeife | 2 |
vitalik/django-ninja | pydantic | 312 | TestClient lacks of authentication | Comparing to DRF API Client, which has force_authenticate method, here I can’t authenticate user in tests. Are there any plans for fixing that? | open | 2022-01-04T10:58:59Z | 2024-04-22T11:22:24Z | https://github.com/vitalik/django-ninja/issues/312 | [] | VityasZV | 13 |
mithi/hexapod-robot-simulator | dash | 69 | Modify to be more pythonic | - [x] Remove `type` parameter for `def make_translate_slider` It is not used and it doesn't make any sense.
https://github.com/mithi/hexapod-robot-simulator/blob/5c1f8a187e7497a37e9b2b5d66ec2fe72b3cc61f/widgets/ik_ui.py#L34
- [x] Use None instead of {} as default parameter as per convention
https://github.com/mit... | closed | 2020-04-19T21:47:19Z | 2020-04-20T13:13:42Z | https://github.com/mithi/hexapod-robot-simulator/issues/69 | [
"good first issue",
"low hanging fruit",
"code quality"
] | mithi | 0 |
miguelgrinberg/python-socketio | asyncio | 1,433 | Client timeout doesn't work | **Describe the bug**
Creating a client and connecting to a non-existent endpoint doesn't timeout as expected. It just hangs/cycles.
**To Reproduce**
```
from socketio import Client
sio = Client(engineio_logger=True)
print("attempting to connect...")
sio.connect(
"http://localhost:7777",
retry=5,
wait=Tru... | open | 2025-02-20T17:29:30Z | 2025-02-21T19:11:41Z | https://github.com/miguelgrinberg/python-socketio/issues/1433 | [] | olivasmaybell | 1 |
onnx/onnx | deep-learning | 6,602 | Installing onnxrruntime (GPU) -1.14.1 on Ubuntu 22.04 reports an error | # Ask a Question
When I installed ONNXruntime v1.14.1 on Ubuntu, I executed the command "./build. sh -- skipthests -- config Release -- build_sthared_lib -- parallel -- use_cuda -- CUDA_ home/var/local/CUDA-11.1-- CUDNN_home/var/local/CUDA-11.1-- use_tensorrt -- tensort_home/home/ps/rain/YK/task/TensorRT-8.5.3.1" and ... | closed | 2024-12-30T02:05:10Z | 2024-12-30T20:39:24Z | https://github.com/onnx/onnx/issues/6602 | [
"question"
] | yuan-kai-design | 1 |
coqui-ai/TTS | python | 2,669 | [Bug] Cannot Find SC-Glow TTS Pretrained Checkpoints | ### Describe the bug
I do not find SC-Glow TTS pretrained checkpoints. Is this a bug for me?
>>> model_name
['tts_models/multilingual/multi-dataset/your_tts', 'tts_models/bg/cv/vits', 'tts_models/cs/cv/vits', 'tts_models/da/cv/vits', 'tts_models/et/cv/vits', 'tts_models/ga/cv/vits', 'tts_models/en/ek1/tacotron2', ... | closed | 2023-06-12T19:09:48Z | 2023-06-12T20:22:38Z | https://github.com/coqui-ai/TTS/issues/2669 | [
"bug"
] | ZhichaoWang970201 | 1 |
ultralytics/ultralytics | deep-learning | 18,755 | cifar100 dataset cannot be loaded | closed | 2025-01-18T15:19:31Z | 2025-01-18T17:34:26Z | https://github.com/ultralytics/ultralytics/issues/18755 | [
"bug",
"dependencies",
"detect"
] | cainiao123s | 2 | |
exaloop/codon | numpy | 285 | Can I use codon with pytorch and other deep learning libraries for faster multithreading ? | As I said in the title,is it possible to use deep learning frameworks like pytorch to take advantage of codon's multithreading ? Also would there be any problems using the gpu with pytorch ? | closed | 2023-03-21T16:52:48Z | 2024-11-09T20:30:29Z | https://github.com/exaloop/codon/issues/285 | [] | UygarUsta99 | 2 |
gevent/gevent | asyncio | 1,917 | Missing wheels for Linux and Python 3.11 | In light of the [changelog](https://github.com/gevent/gevent/blob/master/CHANGES.rst), this might be expected, but I thought to report it just in case.
It is not currently possible to install gevent on Docker 3.11.0rc2-slim.
```
$ docker run --rm -ti python:3.11.0rc2-slim bash
# pip install gevent
...
ERROR: Fa... | closed | 2022-10-24T09:16:15Z | 2022-10-26T20:37:15Z | https://github.com/gevent/gevent/issues/1917 | [
"Status: not gevent",
"Status: wontfix",
"Status: cantfix"
] | alexprengere | 2 |
getsentry/sentry | django | 86,905 | Mobile Replay: `beforeXyz` options | This issue is to discuss/track, which `beforeXyz` options we want to add to Mobile SDKs for Session Replay (if any).
## Background
We currently provide a few `beforeXyz` options that users can use to adapt specific behaviours. From the [docs](https://docs.sentry.io/platforms/javascript/session-replay/configuration/):... | open | 2025-03-12T16:34:39Z | 2025-03-21T13:50:09Z | https://github.com/getsentry/sentry/issues/86905 | [
"Product Area: Replays"
] | kahest | 6 |
MagicStack/asyncpg | asyncio | 270 | Pool cleanup/reset | Both curiosity and a request.
https://github.com/MagicStack/asyncpg/blob/2f558c23a24b574da46e04e3479c7857579e31c4/asyncpg/connection.py#L1180
Why this level of complexity rather than the use of the DISCARD keyword?
https://www.postgresql.org/docs/9.6/static/sql-discard.html
Would a DISCARD ALL not do the ri... | closed | 2018-03-05T17:12:53Z | 2018-03-05T17:27:12Z | https://github.com/MagicStack/asyncpg/issues/270 | [] | mike-hart | 4 |
skforecast/skforecast | scikit-learn | 204 | consider improve the efficiency maybe? | The functionality of the package is mostly satisfying, but with all due respect, when i compare the performance of skforecast with the model i develop by myself, i found it much slower to use the framework. Once i dive deep into the source code, it comes out that the efficiency problem needs some focus. For example, th... | closed | 2022-08-03T09:09:58Z | 2022-10-26T07:30:21Z | https://github.com/skforecast/skforecast/issues/204 | [] | Bennett561 | 2 |
deepset-ai/haystack | pytorch | 8,912 | `tools_strict` option in `OpenAIChatGenerator` broken with `ComponentTool` | **Describe the bug**
When using `ComponentTool` and setting `tools_strict=True` OpenAI API is complaining that `additionalProperties` of the schema is not `false`.
**Error message**
```---------------------------------------------------------------------------
BadRequestError Traceback (most ... | closed | 2025-02-24T13:42:08Z | 2025-03-03T15:23:26Z | https://github.com/deepset-ai/haystack/issues/8912 | [
"P1"
] | tstadel | 0 |
babysor/MockingBird | pytorch | 366 | 最后一步GUI打不开,没有界面 | 模型已经导入之后,但是在cmd运行demo [toolbox.py的时候没有GUI界面。]( @)
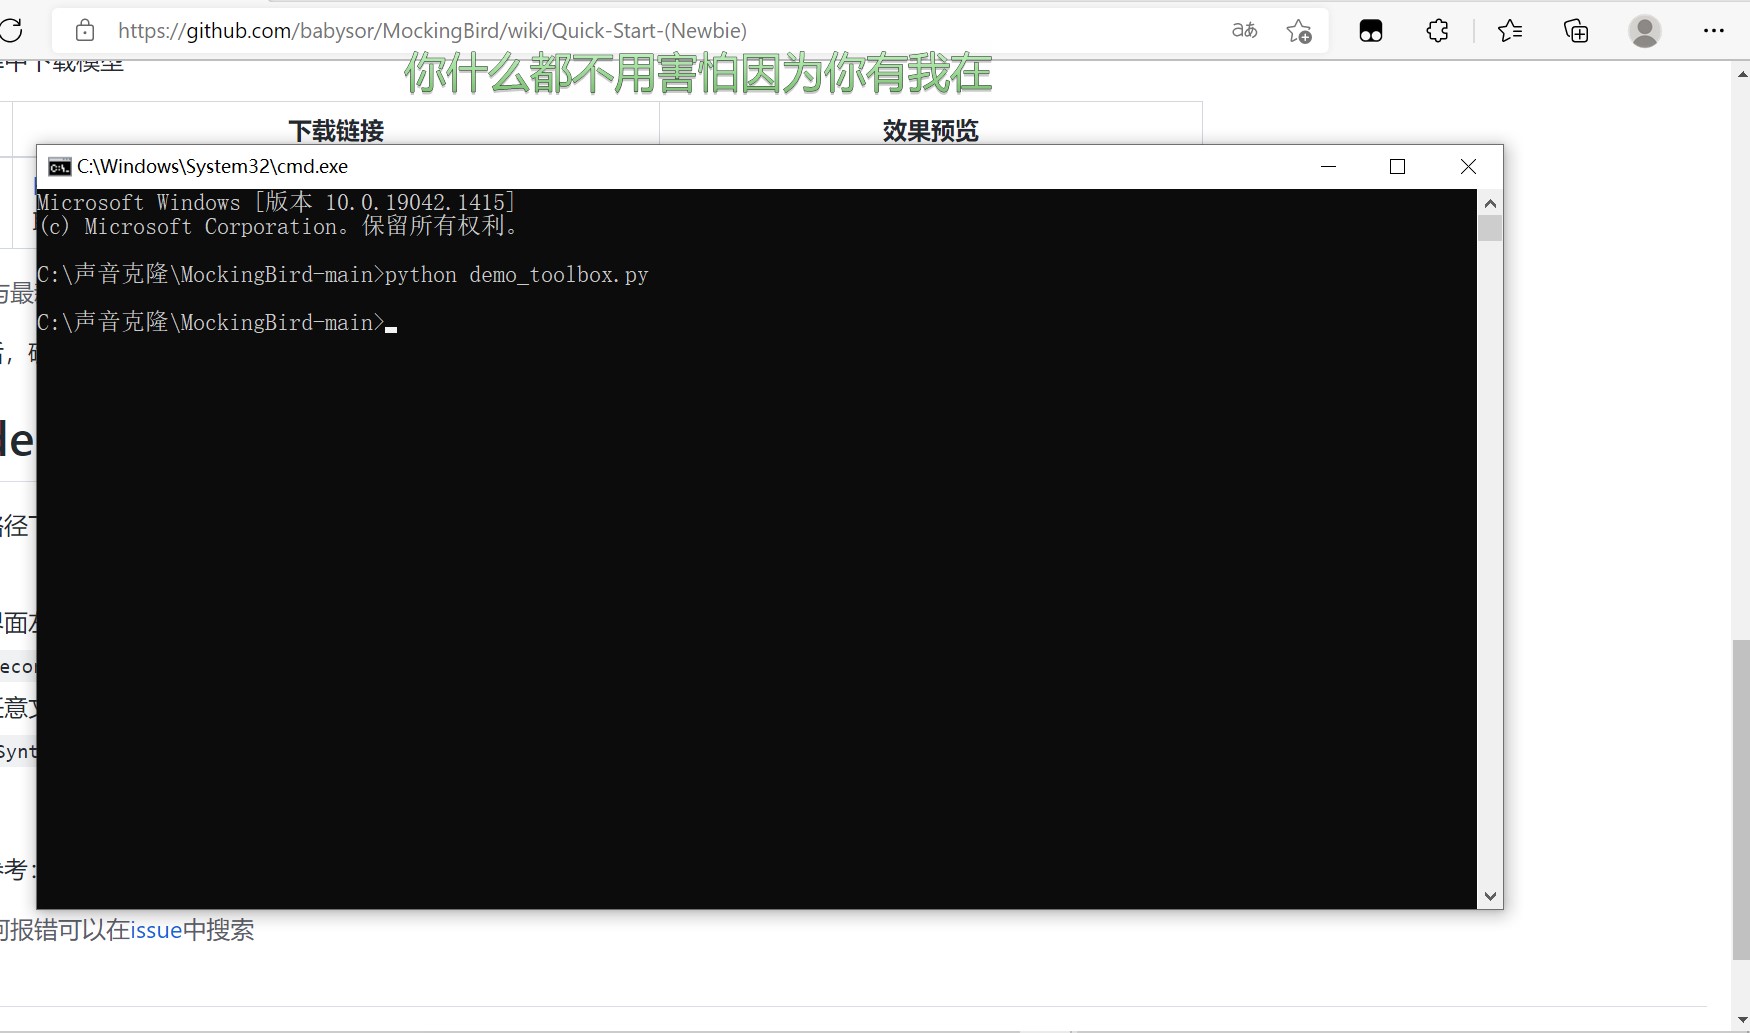
这是怎么回事?
| closed | 2022-02-01T10:46:46Z | 2022-02-27T07:50:32Z | https://github.com/babysor/MockingBird/issues/366 | [] | greedyMaeter | 1 |
microsoft/nni | deep-learning | 5,082 | How could I know the cuda number in each trail? | **Describe the issue**:
As title,
there are two gpus used in my nni experiment,
but I couldn't find the way how to know cuda number in each trail...
I tried adding "print(torch.cuda.current_device())" in my code,
but the result is not the cuda number used in nni.
**Environment**:
- NNI version: 2.4.0
- ... | closed | 2022-08-24T08:14:31Z | 2022-08-25T03:30:59Z | https://github.com/microsoft/nni/issues/5082 | [] | yumei86 | 1 |
scikit-optimize/scikit-optimize | scikit-learn | 601 | Code Commenting Style | I probably should keep quiet. I really don't mean to hound you, I am trying to help. But I think the new code of conduct is partially aimed at shutting me up. Don't worry, as soon as my open PR is finished you'll get rid of me :-)
But I noticed two commits when I solved merge-conflicts for my open PR and I think the... | closed | 2018-01-12T11:42:52Z | 2018-01-12T21:30:14Z | https://github.com/scikit-optimize/scikit-optimize/issues/601 | [] | Hvass-Labs | 0 |
dask/dask | pandas | 10,975 | dask-expr: DataFrame.map_partitions no longer takes a `token` keyword | **Describe the issue**:
The `map_partitions` method of the `dd.DataFrame` collection no longer accepts the `token` keyword in the dask-expr version.
It's certainly not a critical keyword (and with dask-expr you could also create a custom expr subclass instead of using `map_partitions` if you want to have more fin... | closed | 2024-03-04T13:16:28Z | 2024-03-05T10:37:03Z | https://github.com/dask/dask/issues/10975 | [
"dataframe"
] | jorisvandenbossche | 1 |
yihong0618/running_page | data-visualization | 412 | [BUG]: Total data cannot be generated for visualization | [Total-data-messing](https://user-images.githubusercontent.com/16186646/236655527-6b30995f-d8da-40e8-9bf4-69c3812e8561.webm) | closed | 2023-05-07T03:12:23Z | 2023-05-12T13:39:04Z | https://github.com/yihong0618/running_page/issues/412 | [
"bug"
] | shaonianche | 0 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 884 | Using a different speaker encoder | Hello, I really appreciate the work on display here. I was just wondering if I could use a different speaker encoder. If someone used a different encoder, could you explain the difficulties of replacing the encoder and how the results were different from the speaker encoder already in use? | closed | 2021-11-02T13:01:41Z | 2021-11-04T22:21:37Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/884 | [] | AhmedHashish123 | 7 |
jina-ai/serve | machine-learning | 5,747 | Allow passing `grpc-channel-options` | **Describe the feature**
Like `grpc_server_options`, we should allow users to pass `grpc_channel_options` to allow passing options while setting up the channel for the stub while calling the rpc. This should be valid for Client, Gateway & Head
| closed | 2023-03-08T09:05:03Z | 2023-03-20T11:03:40Z | https://github.com/jina-ai/serve/issues/5747 | [] | deepankarm | 1 |
statsmodels/statsmodels | data-science | 8,786 | ENH: Alternative Kernels in HAC estimation | Actually, RegressionResults 'kernel' only allows for Bartlett and Uniform kernel weighing functions in the context of robust linear regression, which are taken from "statsmodels.stats.sandwich_covariance.cov_hac".
It's pretty clear from the literature (authors such as Kiefer, Voegelsang , Sun, Philips, etc.) that k... | open | 2023-04-11T15:40:02Z | 2023-04-12T12:54:28Z | https://github.com/statsmodels/statsmodels/issues/8786 | [] | itsNH98 | 9 |
sqlalchemy/alembic | sqlalchemy | 405 | Altering columns to add on delete cascade does not work | **Migrated issue, originally created by skytreader ([@skytreader](https://github.com/skytreader))**
Tested on MySQL 5.7.16-0ubuntu0.16.04.1 (Ubuntu) with alembic 0.8.9.
Minimal test case:
Create some tables with FK relationship. The foreign key must also be a primary key.
```
create table parent (
`id` int(11) ... | closed | 2016-12-24T19:28:25Z | 2016-12-25T22:49:31Z | https://github.com/sqlalchemy/alembic/issues/405 | [
"bug"
] | sqlalchemy-bot | 3 |
autokey/autokey | automation | 883 | "preferences" window is not available | ### AutoKey is a Xorg application and will not function in a Wayland session. Do you use Xorg (X11) or Wayland?
Xorg
### Has this issue already been reported?
- [X] I have searched through the existing issues.
### Is this a question rather than an issue?
- [X] This is not a question.
### What type of issue is thi... | open | 2023-07-17T16:56:39Z | 2023-07-18T18:28:37Z | https://github.com/autokey/autokey/issues/883 | [
"invalid",
"user support"
] | IIVQ | 8 |
wger-project/wger | django | 1,690 | Website is incredibly slow lately | ## Steps to Reproduce
<!-- Please include as many steps to reproduce so that we can replicate the problem. -->
Open the website
Go to workouts, pick one, open it
**Expected results:** <!-- what did you expect to see? -->
It should load
**Actual results:** <!-- what did you see? -->
Stuck like this for mi... | closed | 2024-06-05T15:23:08Z | 2024-07-04T14:59:49Z | https://github.com/wger-project/wger/issues/1690 | [] | sTiKyt | 2 |
huggingface/transformers | pytorch | 36,440 | tokenizers.apply_chat_template with continue_final_message=True with </think> token | ### System Info
This is very similar to [this](https://github.com/huggingface/transformers/issues/35433) issue but since it's slightly different I made a new issue. This is on transformers 4.49.0
I was working with ```deepseek-ai/DeepSeek-R1-Distill-Qwen-32B``` and I found that the below gives an exception saying subs... | closed | 2025-02-27T03:11:05Z | 2025-03-03T18:03:05Z | https://github.com/huggingface/transformers/issues/36440 | [
"bug"
] | isamu-isozaki | 3 |
OpenInterpreter/open-interpreter | python | 1,317 | Error gpt-4-vision-preview has been deprecated | ### Describe the bug
Each time use interpreter --vision, it is automatically set to gpt-4-vision-preview, but gpt-4-vision-preview has been eliminated by OpenAI and cannot be used

### Reproduce
Each... | open | 2024-06-22T15:41:31Z | 2024-06-25T16:31:40Z | https://github.com/OpenInterpreter/open-interpreter/issues/1317 | [] | zhongerxin | 2 |
pytorch/pytorch | python | 149,303 | Allow Privateuse1 device for validating the arguments to sparse compressed tensor factory functions | ### 🚀 The feature, motivation and pitch
https://github.com/pytorch/pytorch/commit/bb8c4ecc6d7d546d553c0883422c53705355236d
similar to this commit, can we allow privateuse1 device to pass this TORCH_CHECK?
### Alternatives
_No response_
### Additional context
_No response_
cc @NmomoN @mengpenghui @fwenguang @cdzh... | open | 2025-03-17T08:10:47Z | 2025-03-17T15:34:56Z | https://github.com/pytorch/pytorch/issues/149303 | [
"triaged",
"module: PrivateUse1"
] | ClowDragon | 2 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 753 | longer sentences and higher sample rate downloads? | Hi just wondering how long of an audio clip you need to record which would allow you to write longer sentences to generate? secondly when i download the file its only at 16khz, is there a way to download at higher sample rates like 44.1 or 48khz? | closed | 2021-05-11T19:06:31Z | 2021-05-30T07:30:54Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/753 | [] | mindblowingaiart | 3 |
autokey/autokey | automation | 215 | Feature request: Autokey for Windows | I was so happy to see Autokey and to read about. What a great idea to use python as a tool for text expansion. I was sad to see that Autokey hadn't a windows version.
Will there be a windows version in the near future?
Does anyone know if there is a similar software (with the possibility to use python scripts)?
... | open | 2018-11-09T10:59:20Z | 2018-11-13T11:37:14Z | https://github.com/autokey/autokey/issues/215 | [] | Remiol | 3 |
erdewit/ib_insync | asyncio | 586 | Multiple issues with version 0.9.83 | I am experiencing a number of issues after upgrading to the latest release. This starts right after connecting if orders are present:
```
Error handling fields: <cut for privacy>
Traceback (most recent call last):
File "<home>/.local/lib/python3.11/site-packages/ib_insync/decoder.py", line 198, in interpret
... | closed | 2023-05-04T19:03:41Z | 2023-05-05T16:29:48Z | https://github.com/erdewit/ib_insync/issues/586 | [] | this-user | 4 |
mitmproxy/pdoc | api | 753 | TypeError: argument of type '_SentinelObject' is not iterable (`unittest.mock`) | #### Problem Description
`pdoc` fails to generate API documentation for the `unittest.mock` module.
#### Steps to reproduce the behavior:
```sh
pdoc --output-directory /tmp/docs unittest.mock
```
```py
Traceback (most recent call last):
File "/private/tmp/pdoc/.venv/bin/pdoc", line 8, in <module>
.... | closed | 2024-10-22T23:47:00Z | 2024-10-23T23:42:05Z | https://github.com/mitmproxy/pdoc/issues/753 | [
"bug"
] | bryant-finney | 0 |
recommenders-team/recommenders | machine-learning | 1,557 | [Help Wanted] LightFM Example Notebook | ### Description
LightFM. When at prediction point the model.predict brings a problematic error which I cannot resolve. Have spent hours doing trial-and-error but cannot understand what the issue is.
### In which platform does it happen?
Jupyter Notebook
Python 3.7
### How do we replicate the issue?
Run exam... | closed | 2021-10-26T15:29:38Z | 2021-11-01T09:37:04Z | https://github.com/recommenders-team/recommenders/issues/1557 | [
"bug"
] | drodri321 | 2 |
TencentARC/GFPGAN | deep-learning | 605 | Straight hair added to African-American photos | I'm using GFPGANv1.3.pth model and I found that when it tried to restore photos of African Americans, it placed straight hair strands on them. Their hair is naturally black and curly. I'm thinking this model didn't include enough of them in the training set. | open | 2025-03-01T01:39:46Z | 2025-03-01T01:50:08Z | https://github.com/TencentARC/GFPGAN/issues/605 | [] | git9875 | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.