
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
dynaconf/dynaconf | django | 637 | [RFC] sqlalchemy based loader | **Is your feature request related to a problem? Please describe.**
We've been mulling over displaying some of our settings to our users in a UI.
This is just some simple application level settings - for example: `maintenance = True / False` to enable or disable maintenance mode
**Describe the solution you'd like**... | open | 2021-08-11T04:01:40Z | 2022-06-29T13:56:55Z | https://github.com/dynaconf/dynaconf/issues/637 | [
"wontfix",
"Not a Bug",
"RFC"
] | AbdealiLoKo | 1 |
chatopera/Synonyms | nlp | 22 | 关于词向量文件words.vector的训练 | 请问词向量是怎么训练出来的?是类似gensim.models.word2vec里“标准的”词向量训练过程吗? | closed | 2018-01-15T09:43:49Z | 2018-01-16T06:09:26Z | https://github.com/chatopera/Synonyms/issues/22 | [
"duplicate"
] | wangzhe258369 | 2 |
xlwings/xlwings | automation | 2,072 | xlwings Server: add table support | closed | 2022-10-28T13:36:28Z | 2023-03-26T19:42:25Z | https://github.com/xlwings/xlwings/issues/2072 | [
"Server"
] | fzumstein | 1 | |
davidsandberg/facenet | tensorflow | 774 | using the pretained model and finetuning,but get a low accuracy with lfw,how to explain... | i used the model trained by the author about 20180402-114759 using VGGface2 to finetune.
however, i use the MS-Cleb-1M as training data,but accuracy is about 0.70 after epcoch 200.
i wonder is there something wrong with my parameters or something else?
tks a lot~
dose any can help me ?
max_nrof_epochs: 300
lfw_p... | open | 2018-05-31T02:28:39Z | 2018-05-31T02:28:39Z | https://github.com/davidsandberg/facenet/issues/774 | [] | qianchen94 | 0 |
pytorch/pytorch | machine-learning | 149,658 | unexpected kwarg 'no_python_abi_suffix' when installing stable version of pytorch with sam2 | ### 🐛 Describe the bug
Installing sam2, which requires a build of a cpp extension and pytorch 2.6 used to work. today this now doesn't but nothing has changed about my environment
```
> [wherobots-inference-gpu 13/14] RUN uv pip install -e dockers/gpu/. --extra-index-url https://download.pytorch.org/whl/cu124 --ind... | closed | 2025-03-20T20:17:10Z | 2025-03-21T17:26:07Z | https://github.com/pytorch/pytorch/issues/149658 | [
"high priority",
"triage review",
"module: build",
"module: cpp-extensions",
"has workaround"
] | rbavery | 4 |
huggingface/pytorch-image-models | pytorch | 1,803 | Python 3.7 Import Error | It looks like `timm == 0.9.0` introduces an error for Python 3.7 environments.
```
File "/opt/hostedtoolcache/Python/3.7.16/x64/lib/python3.7/site-packages/timm/models/beit.py", line 43, in <module>
from typing import Callable, Final, Optional, Tuple, Union
ImportError: cannot import name 'Final' from 'typing... | closed | 2023-05-12T15:59:15Z | 2023-05-12T17:08:30Z | https://github.com/huggingface/pytorch-image-models/issues/1803 | [
"bug"
] | davidmezzetti | 5 |
schemathesis/schemathesis | graphql | 2,136 | [BUG] Parametrization incompatibility with falcon ASGI apps | ### Checklist
- [x] I checked the [FAQ section](https://schemathesis.readthedocs.io/en/stable/faq.html#frequently-asked-questions) of the documentation
- [x] I looked for similar issues in the [issue tracker](https://github.com/schemathesis/schemathesis/issues)
- [x] I am using the latest version of Schemathesis
... | closed | 2024-04-16T20:33:12Z | 2024-04-29T19:48:47Z | https://github.com/schemathesis/schemathesis/issues/2136 | [
"Priority: High",
"Type: Bug",
"Python: ASGI"
] | BrandonWiebe | 5 |
davidteather/TikTok-Api | api | 459 | [FEATURE_REQUEST] - Getting Your Following List (With a detailed plan) | So, after some digging in the network tab, it looks like the logged-in user's following list can be retrieved via these URLS (on browser at least):
### **Initial List**
For whatever reason, when you first access the web version, you will send off a call some (count varries) of your top accounts:
`https://m.tikto... | open | 2021-01-02T07:53:04Z | 2021-05-26T15:14:55Z | https://github.com/davidteather/TikTok-Api/issues/459 | [
"feature_request"
] | Bengejd | 6 |
pytorch/pytorch | numpy | 149,670 | DISABLED test_lazy_module_speculation_log_divergence (__main__.NNModuleTests) | Platforms: linux, rocm
This test was disabled because it is failing in CI. See [recent examples](https://hud.pytorch.org/flakytest?name=test_lazy_module_speculation_log_divergence&suite=NNModuleTests&limit=100) and the most recent trunk [workflow logs](https://github.com/pytorch/pytorch/runs/39123845623).
Over the pa... | open | 2025-03-20T21:41:15Z | 2025-03-21T15:02:15Z | https://github.com/pytorch/pytorch/issues/149670 | [
"module: nn",
"triaged",
"module: flaky-tests",
"skipped"
] | pytorch-bot[bot] | 1 |
gevent/gevent | asyncio | 1,091 | Remove Py2 Source Files from Py3 sdist + wheel | * gevent version: 1.2.2
* Python version: Python 3.6.3
* Operating System: CentOS Linux release 7.4.1708 (Core)
Linux devbox 4.6.7 #69 SMP Tue Nov 14 16:47:15 PST 2017 x86_64 x86_64 x86_64 GNU/Linux
### Description:
Can we separate out the Python 2 only .py files so they don't get included into the Py3 wheel /... | closed | 2018-02-04T22:42:34Z | 2018-02-05T05:26:05Z | https://github.com/gevent/gevent/issues/1091 | [] | cooperlees | 3 |
littlecodersh/ItChat | api | 783 | upload 较大的zip总是有问题,正常上传,手机上却下载不了,总显示“继续下载”,应该是没完全上传 | 在提交前,请确保您已经检查了以下内容!
- [x] 您可以在浏览器中登陆微信账号,但不能使用`itchat`登陆
- [x] 我已经阅读并按[文档][document] 中的指引进行了操作
- [x] 您的问题没有在[issues][issues]报告,否则请在原有issue下报告
- [x] 本问题确实关于`itchat`, 而不是其他项目.
- [x] 如果你的问题关于稳定性,建议尝试对网络稳定性要求极低的[itchatmp][itchatmp]项目
请使用`itchat.run(debug=True)`运行,并将输出粘贴在下面:
```
[在这里粘贴完整日志]
```
您的itchat版本为... | open | 2019-01-17T01:58:05Z | 2019-01-17T02:02:19Z | https://github.com/littlecodersh/ItChat/issues/783 | [] | tj0120 | 2 |
StackStorm/st2 | automation | 5,918 | Failed to register action from pack "aws": found duplicate key "headers" | ## SUMMARY
Register content job failing (stackstorm/stackstorm-job-st2-register-content-xxxxx) when run from Helm chart
### STACKSTORM VERSION
This occurs with both v0.100.0 and v0.110.0 of the helm chart
##### OS, environment, install method
EKS Kubernetes using helm chart from https://github.com/StackS... | closed | 2023-03-02T15:43:24Z | 2023-03-09T15:55:17Z | https://github.com/StackStorm/st2/issues/5918 | [] | lordpengwin | 2 |
wagtail/wagtail | django | 12,098 | the TODO note should be ermoved | I think the following TODO note is no longer valid, am I wrong?
https://github.com/wagtail/wagtail/blob/d0647f328861ed6cb5b8527ce1c01c6e5b32a98b/wagtail/images/fields.py#L189
| closed | 2024-06-29T16:47:52Z | 2024-10-10T18:03:33Z | https://github.com/wagtail/wagtail/issues/12098 | [] | hazho | 0 |
yzhao062/pyod | data-science | 49 | The KNN example is incorrect | The KNN example is incorrect
There is no get_outliers_inliers in pyod
`from pyod.utils.data import generate_data
from pyod.utils.data import get_outliers_inliers` | closed | 2019-01-04T08:44:40Z | 2019-01-04T08:50:25Z | https://github.com/yzhao062/pyod/issues/49 | [] | chenygie | 1 |
biolab/orange3 | scikit-learn | 6,243 | Distances widget needs improvements in documentation and interface | **What's your use case?**
When using the Distances widget to compute the correlation between features (columns), the computation returns values inconsistent with the documentation. For instance, the documentation says that for the spearman correlation, the value of the Spearman correlation is scaled to the interval ... | closed | 2022-12-07T13:53:52Z | 2023-02-03T13:02:16Z | https://github.com/biolab/orange3/issues/6243 | [
"wish",
"meal"
] | BlazZupan | 5 |
keras-team/keras | python | 20,809 | Tensorboard not working with Trainer Pattern | I'm using the Keras Trainer pattern as illustrated [here](https://keras.io/examples/keras_recipes/trainer_pattern/). The issue when using this pattern is that when you use Tensorboard only the top level weights are being recorded.
The reason for this is that `Tensorboard` is recording the weights for the all the laye... | open | 2025-01-24T09:58:16Z | 2025-02-27T17:18:14Z | https://github.com/keras-team/keras/issues/20809 | [
"stat:awaiting keras-eng",
"type:Bug"
] | GeraudK | 7 |
jofpin/trape | flask | 134 | always getting this error even before the attack begins | 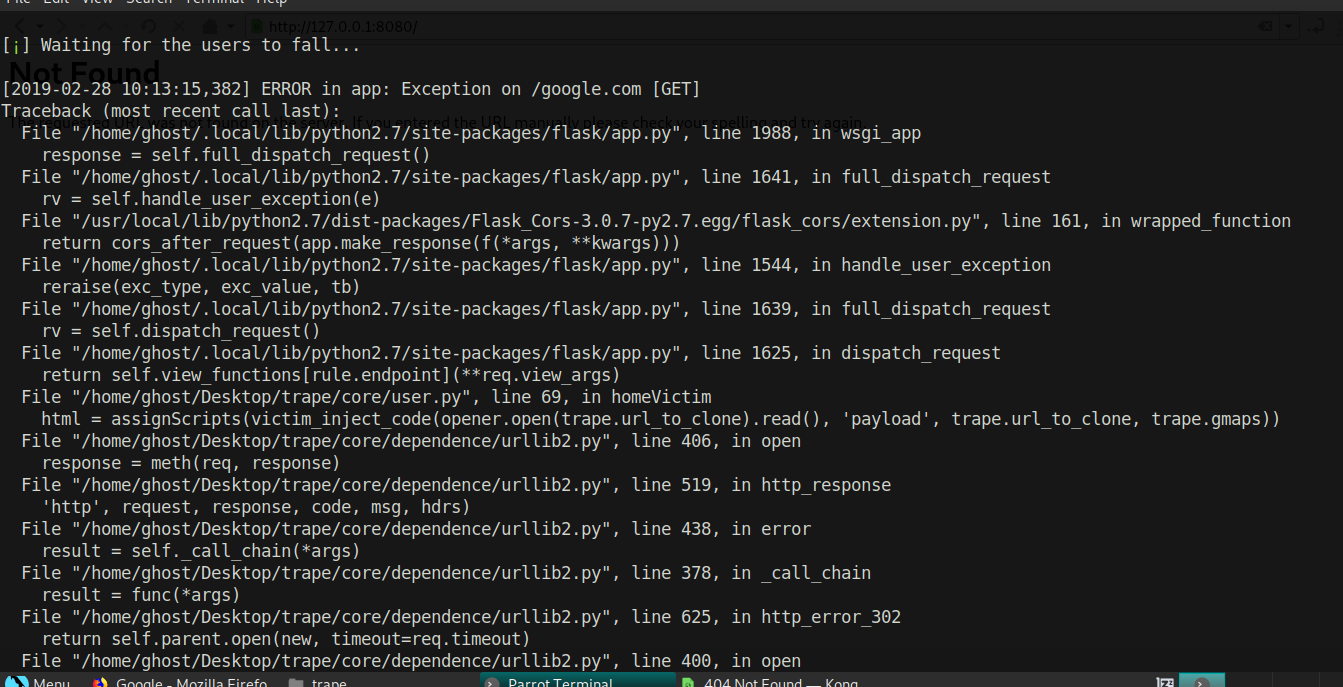
| open | 2019-02-28T09:17:28Z | 2019-03-31T10:34:35Z | https://github.com/jofpin/trape/issues/134 | [] | lordcharlx | 2 |
babysor/MockingBird | deep-learning | 183 | 用colab和谷歌云服务器预处理时,出现了AssertionError |
~/MockingBird$ python pre.py dateAISHELL3 -d aishell3
Traceback (most recent call last):
File "pre.py", line 57, in <module>
assert args.datasets_root.exists()
AssertionError
colab和谷歌云都出现了相同的错误,版本都是用git clone 抓取的最新版
| closed | 2021-10-31T10:03:31Z | 2021-12-26T03:23:50Z | https://github.com/babysor/MockingBird/issues/183 | [] | kulu2001 | 2 |
iperov/DeepFaceLab | deep-learning | 657 | labelme error when running 5. XSeg) data_dst edit.bat | ## Expected behavior
Trying to run the new XSeg editor
## Actual behavior
XSeg editor won't run. Executable file labelme.exe appears to be missing from the pre-built Windows 10 release. The Command-line error is: "'labelme' is not recognized as an internal or external command, operable program or batch file.... | closed | 2020-03-15T20:24:35Z | 2020-03-16T06:08:17Z | https://github.com/iperov/DeepFaceLab/issues/657 | [] | gessyoo | 1 |
horovod/horovod | tensorflow | 3,507 | pip install can not find PyTorch | **Environment:**
1. Framework: PyTorch
2. Framework version: 1.9
3. Horovod version: 0.24.2
4. MPI version: 4.0.5
5. CUDA version: 11.0.1
6. NCCL version: 2.8.3
7. Python version: 3.8.6
8. Spark / PySpark version:
9. Ray version:
10. OS and version: Ubuntu
11. GCC version: 10.2.0
12. CMake version:
**Bug... | closed | 2022-04-07T15:38:33Z | 2022-10-08T08:53:42Z | https://github.com/horovod/horovod/issues/3507 | [
"wontfix"
] | Tobblatzius | 5 |
explosion/spaCy | deep-learning | 12,976 | span_ruler is not working on ENT patterns | <!-- NOTE: For questions or install related issues, please open a Discussion instead. -->
Text : "A 50-year-old male patient lodges chief complaint pain in lower right side of chest for three days associated with burning in epigastrium. History is cuffed with sputum."
Get Ent in Doc :
0 | 50-year | 2 | 5 | Age
... | closed | 2023-09-12T12:50:18Z | 2023-09-13T06:21:35Z | https://github.com/explosion/spaCy/issues/12976 | [
"feat / spanruler"
] | kamlesh0606 | 1 |
tensorflow/tensor2tensor | deep-learning | 930 | How to reset the learning rate when finetuning model | ### Description
I met a problem when I trained my En-Zh model, that I want to sample a part of training data to fine tune my model wihin 5 epochs. Due to the large training steps = 2300000 , the learning rate is so small (2e-5) that I can't get significant experimental phenomena which I do right or not. I want to gain... | closed | 2018-07-11T03:40:44Z | 2018-07-16T02:47:32Z | https://github.com/tensorflow/tensor2tensor/issues/930 | [] | libeineu | 2 |
gradio-app/gradio | data-visualization | 10,151 | Cannot use the api in javascript | ### Describe the bug
i am using api to request in javascript but it is not working
### Have you searched existing issues? 🔎
- [X] I have searched and found no existing issues
### Reproduction
```python
import gradio as gr
```
### Screenshot
_No response_
### Logs
_No response_
### System Info
```shel... | closed | 2024-12-07T08:09:40Z | 2024-12-11T18:37:05Z | https://github.com/gradio-app/gradio/issues/10151 | [
"bug"
] | codeumabidev | 1 |
miLibris/flask-rest-jsonapi | sqlalchemy | 189 | JSON API Client error | I am using a react-admin client to invoke my json-api backend.....
I am getting the following URL:
http://localhost:4500/parameters?filter[id][]=2&filter[id][]=3&filter[id][]=4
which is returning only one record, because is being traslated to:
[{'name': 'id', 'op': 'eq', 'val': '2'}]
But, in case I run... | open | 2020-06-04T15:08:23Z | 2020-06-04T15:08:23Z | https://github.com/miLibris/flask-rest-jsonapi/issues/189 | [] | rubenghio | 0 |
PaddlePaddle/ERNIE | nlp | 78 | when bert use save_inference_model, the __model__ is imcomplete | after I finetune and then
```shell
$python -u predict_classifier.py --task_name ${TASK_NAME} \
--use_cuda false \
--batch_size 1 \
--data_dir ${DATA_PATH} \
--vocab_path ${BERT_BASE_PATH}/vocab.txt \
--do_lower_case true \
--init_checkpoint ${... | closed | 2019-04-07T12:42:13Z | 2019-04-07T12:50:06Z | https://github.com/PaddlePaddle/ERNIE/issues/78 | [] | daiwk | 1 |
pytorch/pytorch | python | 149,244 | torch.sum_of_squares() | ### 🚀 The feature, motivation and pitch
It would be equivalent to `torch.linalg.vector_norm(..., ord=2) ** 2`.
In my codebase, 14/18 of the norm calls have `** 2` immediately after. So the sum of squares is more common than the vector norm.
This is slightly faster because `vector_norm` calls `sqrt`, which is extran... | open | 2025-03-15T01:45:28Z | 2025-03-18T07:54:54Z | https://github.com/pytorch/pytorch/issues/149244 | [
"triaged",
"module: python frontend"
] | ad8e | 4 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 493 | [FEATURE]: Add option to blacklist 1099 jobs | ### Feature summary
Most of the interview requests are from 1099 jobs (life insurance, mulit level marketing, etc)
### Feature description
It would be nice for an option to prevent the bot from applying to jobs that have 1099 only in the job description.
### Motivation
_No response_
### Alternatives considered
_... | closed | 2024-10-07T19:59:10Z | 2024-10-13T17:45:15Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/493 | [
"enhancement"
] | cwort40 | 0 |
long2ice/fastapi-cache | fastapi | 15 | support `filter` argument in cache decorator | It would be nice to have an optional parameter such as `filter` in the `@cache` decorator that took as input a python callable w/ the wrapped function's `*args` and `**kwargs` and returned a boolean as to whether or not to cache.
The default could just be always true e.g. `lambda x: True` but users may want more nua... | open | 2021-04-06T18:40:02Z | 2023-05-15T12:55:11Z | https://github.com/long2ice/fastapi-cache/issues/15 | [
"enhancement"
] | mattshin | 3 |
SALib/SALib | numpy | 603 | Correct description of Saltelli's sampling | Sergei Kucherenko shared the following with me (sorry I am laking time right now to make a PR, though I thought that could be also left as a good first PR 😅):
> I have a remark with regards to SaLib, namely in the Section on Sobol’ Sensitivity Analysis it says: “Saltelli’s scheme extends the Sobol’ sequence in a wa... | closed | 2024-02-14T23:42:52Z | 2024-02-18T18:57:13Z | https://github.com/SALib/SALib/issues/603 | [
"documentation",
"good_for_first_issue"
] | tupui | 1 |
adbar/trafilatura | web-scraping | 26 | Fails to parse on mangled DOCTYPE | This HTML document fails to extract any content using current trafilatura: <https://firstmonday.org/ojs/index.php/fm/article/download/10274/9729?inline=1>
From experimentation, I believe this is due to the mangled DOCTYPE line:
<!DOCTYPE HTML PUBLIC "-//W3C//DTD HTML 4.01 Transitional//EN" 2012"http://www.w3.... | closed | 2020-10-30T22:48:38Z | 2020-11-06T15:19:39Z | https://github.com/adbar/trafilatura/issues/26 | [] | bnewbold | 2 |
ansible/awx | django | 15,180 | Cannot create multiple workflow approvals | ### Please confirm the following
- [X] I agree to follow this project's [code of conduct](https://docs.ansible.com/ansible/latest/community/code_of_conduct.html).
- [X] I have checked the [current issues](https://github.com/ansible/awx/issues) for duplicates.
- [X] I understand that AWX is open source software provide... | open | 2024-05-12T12:29:38Z | 2024-05-12T12:30:04Z | https://github.com/ansible/awx/issues/15180 | [
"type:bug",
"component:api",
"component:ui",
"needs_triage",
"community"
] | yarons | 0 |
apache/airflow | machine-learning | 47,988 | Do not call runtime-checks api from the task sdk anymore | ### Body
https://github.com/apache/airflow/pull/47893 removed the significance of doing: `/task_instances/{uuid}/runtime-checks` during task runs. We did it earlier to register asset changes but that has fundamentally changed in https://github.com/apache/airflow/pull/47677.
Since that API doesnt do much, it would be ... | open | 2025-03-20T07:57:56Z | 2025-03-21T09:21:52Z | https://github.com/apache/airflow/issues/47988 | [
"area:API",
"kind:meta",
"priority:medium",
"area:task-execution-interface-aip72",
"area:task-sdk"
] | amoghrajesh | 2 |
lucidrains/vit-pytorch | computer-vision | 81 | Regression on stacked images | I want to perform regression by stacking 2 images, I was a bit confused on how to do it. Any help is appreciated.
Thank you. | closed | 2021-03-12T17:20:24Z | 2021-03-13T10:49:27Z | https://github.com/lucidrains/vit-pytorch/issues/81 | [] | surajmahangade | 8 |
adamerose/PandasGUI | pandas | 171 | Split or merge columns | I've done some `pandasgui` research, but cannot see how to split or merge columns.
For example, my data may have separate date and time columns - which I wish to `merge` into one date-time column. Or, I may have an address column which I wish to `split` into house-number and street-name.
My first guess was to us... | open | 2021-09-14T15:48:42Z | 2021-09-14T15:48:42Z | https://github.com/adamerose/PandasGUI/issues/171 | [
"enhancement"
] | IanMayo | 0 |
liangliangyy/DjangoBlog | django | 651 | 代码结构做了一些调整 | 作者你好。
简单的调整了下代码结构,看着比较清晰;
已经自测过了。没问题。刚刚提交了pr。 | closed | 2023-04-10T09:06:12Z | 2023-04-17T03:02:10Z | https://github.com/liangliangyy/DjangoBlog/issues/651 | [] | nightzjp | 0 |
sinaptik-ai/pandas-ai | pandas | 1,456 | After testing the same data, the accuracy of pandasai operating Excel is higher than that of operating MySQL. What is the reason for this? | After testing the same data, the accuracy of pandasai operating Excel is higher than that of operating MySQL. What is the reason for this? please! | closed | 2024-12-09T03:07:19Z | 2024-12-13T15:37:35Z | https://github.com/sinaptik-ai/pandas-ai/issues/1456 | [] | lwdnxu | 0 |
ijl/orjson | numpy | 1 | Subtypes of serializable types are not serializable | ```python
import json
import orjson
class MyDict(dict):
pass
my_dict = MyDict({"id": 1})
json.dumps(my_dict) # works
orjson.dumps(my_dict) # fails
```
Error:
```
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: Type is not JSON serializable: MyDict
``` | closed | 2018-11-25T20:01:02Z | 2018-11-26T18:36:38Z | https://github.com/ijl/orjson/issues/1 | [] | konstin | 4 |
vllm-project/vllm | pytorch | 14,557 | [Feature]: how to know the tokens length of a request including images | ### 🚀 The feature, motivation and pitch
ValueError: This model's maximum context length is 32768 tokens. However, you requested 794483 tokens (793483 in the messages, 1000 in the completion). Please reduce the length of the messages or completion.
The --max-model-len 49152 has been set,I have submitted 5 requests ,a... | open | 2025-03-10T11:46:29Z | 2025-03-12T13:30:59Z | https://github.com/vllm-project/vllm/issues/14557 | [
"feature request"
] | kaihekaihe | 8 |
Farama-Foundation/PettingZoo | api | 476 | Error when running tutorial 13 lines | When running the tutorial from [here](https://github.com/PettingZoo-Team/PettingZoo/blob/master/tutorials/13_lines.py)
I get the following error:
`Traceback (most recent call last):
File "G:/Projects/furry-disco/prj.py", line 13, in <module>
env = ss.concat_vec_envs_v0(env, 8, num_cpus=2, base_class='stabl... | closed | 2021-09-02T12:59:20Z | 2021-09-05T00:58:50Z | https://github.com/Farama-Foundation/PettingZoo/issues/476 | [] | bogdanvaduva9 | 2 |
lepture/authlib | flask | 340 | oAuth 2 async server integration (aiohttp) | **Is your feature request related to a problem? Please describe.**
I'm looking to see if there is any interest/availability of an async HTTP server integration for oauth2, with one such as aiohttp.
**Describe the solution you'd like**
If possible, I'd love to have one, potentially PR'ing it in myself.
**Des... | closed | 2021-05-01T21:48:08Z | 2021-10-18T13:01:11Z | https://github.com/lepture/authlib/issues/340 | [] | space55 | 1 |
deezer/spleeter | deep-learning | 610 | [Discussion] Mono processing | I'm processing real-time microphone audio through Spleeter in an attempt to separate the actual voice from extraneous music picked up by the vocal mics. It's working quite well.
I'd like to optimize my processing. Currently, I'm duplicating the samples and passing a stereo signal to be split because that is how al... | closed | 2021-04-13T23:57:27Z | 2021-04-15T14:57:05Z | https://github.com/deezer/spleeter/issues/610 | [
"question"
] | aughey | 1 |
ipython/ipython | jupyter | 13,952 | make ipython works with different python versions cleanly | on Linux if I do:
pip3.10 install --user ipython
pip3.11 install --user ipython
They both use the same ipython file at $HOME/.local/bin/ipython, I would expect there are both ipython3.10 and ipython3.11 created so I can specify which python version my ipython is supposed to work with. The default ipython can be ... | open | 2023-02-25T18:28:48Z | 2023-02-25T20:25:28Z | https://github.com/ipython/ipython/issues/13952 | [] | laoshaw | 3 |
piskvorky/gensim | machine-learning | 3,555 | Always, each row of word2vec model txt format file starts with word and the rest is vector. But the function save_word2vec_format of the code make it starting with index. Is it a Bug? | https://github.com/piskvorky/gensim/blob/54dfec9909041817371ed96a4a53e36dc1b398d9/gensim/models/keyedvectors.py#L1639C2-L1670C110
``` python
store_order_vocab_keys = self.index_to_key
keys_to_write = itertools.chain(range(0, index_id_count), store_order_vocab_keys)
for key in keys_to_write:
key_v... | closed | 2024-07-31T09:49:07Z | 2024-11-12T17:29:09Z | https://github.com/piskvorky/gensim/issues/3555 | [] | rollingdeep | 5 |
deepspeedai/DeepSpeed | deep-learning | 6,900 | nv-nightly CI test failure | The Nightly CI for https://github.com/microsoft/DeepSpeed/actions/runs/12522082953 failed.
| closed | 2024-12-20T01:07:45Z | 2024-12-30T17:55:43Z | https://github.com/deepspeedai/DeepSpeed/issues/6900 | [
"ci-failure"
] | github-actions[bot] | 0 |
klen/mixer | sqlalchemy | 28 | Skip Django related models generation when primary key is provided | It would be nice to skip generation of related Django model when related key is provided. Example:
```
class Author(models.Model):
...
class Book(models.Model):
author = models.ForeignKey(Author)
...
# don't generate extra author instance
mixer.blend(Book, author_id=3)
```
##
<bountysource-plug... | open | 2014-11-19T11:58:48Z | 2016-12-31T21:20:14Z | https://github.com/klen/mixer/issues/28 | [] | DXist | 0 |
napari/napari | numpy | 7,524 | [test-bot] pip install --pre is failing | The --pre Test workflow failed on 2025-01-14 00:31 UTC
The most recent failing test was on macos-latest py3.12 pyqt6
with commit: 8c31249ee856033f1f5fe6b0b4c7c43745e19b06
Full run: https://github.com/napari/napari/actions/runs/12758461328
(This post will be updated if another test fails, as long as this issue remain... | closed | 2025-01-14T00:31:45Z | 2025-01-14T01:45:33Z | https://github.com/napari/napari/issues/7524 | [
"bug"
] | github-actions[bot] | 2 |
Lightning-AI/pytorch-lightning | data-science | 20,234 | Add support to Llama 3.1 | ### Description & Motivation
In the Tensor Parallel example [here](https://github.com/Lightning-AI/pytorch-lightning/tree/master/examples/fabric/tensor_parallel) while the proposed model is a Llama3 like model, the forward pass is different from the Llama3.1 model in the official code [here](https://github.com/meta-... | open | 2024-08-28T19:03:22Z | 2024-08-29T15:13:46Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20234 | [
"feature",
"needs triage"
] | loretoparisi | 1 |
kizniche/Mycodo | automation | 685 | MQTT hostname variable mismatch | ## Mycodo Issue Report:
- Specific Mycodo Version: 7.7.1
#### Problem Description
Please list:
- Connect to MQTT host
### Errors
- Could not connect to host
### Root cause
The variable for hostname input is called mqtt_hostname
https://github.com/kizniche/Mycodo/blob/37c5a3e09b40fe28961fe421c... | closed | 2019-09-11T09:25:08Z | 2019-09-11T21:34:26Z | https://github.com/kizniche/Mycodo/issues/685 | [] | jlb-qi | 1 |
stanfordnlp/stanza | nlp | 448 | Arabic NER model trained on OntoNotes | OntoNotes contains an Arabic dataset with 300k words with 18 entities.
I see that the current model was trained on AQMAR which only supports 4 entities.
Is there a reason why OntoNotes was not used for Arabic?
Having a model trained on 18 entities would be much better.
Thanks! | closed | 2020-08-20T12:36:19Z | 2021-01-05T18:21:35Z | https://github.com/stanfordnlp/stanza/issues/448 | [
"enhancement",
"stale"
] | dhruvrnaik | 3 |
OpenBB-finance/OpenBB | machine-learning | 6,090 | [Bug] Cannot search for a term with spaces in it in the funds menu of OpenBB Terminal | **Describe the bug**
(I'm not 100% clear on whether this is a bug or a feature, feels more like a bug to me.)
When using /funds/search I am not able to search for multiword terms. I would like to be able to search for a term with spaces in it.
**To Reproduce**
I've tried these:
- `/funds/search multiword fun... | closed | 2024-02-17T00:19:40Z | 2024-02-26T20:12:35Z | https://github.com/OpenBB-finance/OpenBB/issues/6090 | [] | caballerofelipe | 0 |
pytest-dev/pytest-mock | pytest | 375 | mocker.stub() is a coroutine function | ```
def test_icf_sync(mocker):
func = mocker.stub('func')
assert not inspect.iscoroutinefunction(func)
def test_icf_async(mocker):
func = mocker.async_stub('func')
assert inspect.iscoroutinefunction(func)
```
Expected: `mocker.stub()` returns something that doesn't resemble a coroutine.
... | open | 2023-07-24T17:08:54Z | 2023-07-25T12:54:01Z | https://github.com/pytest-dev/pytest-mock/issues/375 | [
"question"
] | AstraLuma | 1 |
ansible/ansible | python | 84,790 | display interrupted runners | ### Summary
If I run an ansible playbook on a hundred machines and one of them hangs, and I interrupt ansible, I don't get to know which machine it was that blocked up my playbook. the [task executor](https://github.com/ansible/ansible/blob/09391f38f009ec58b5759dbd74df34fd281ef3ac/lib/ansible/executor/task_executor.py... | open | 2025-03-06T21:37:20Z | 2025-03-17T16:08:22Z | https://github.com/ansible/ansible/issues/84790 | [
"feature"
] | simonLeary42 | 4 |
huggingface/datasets | tensorflow | 7,212 | Windows do not supprot signal.alarm and singal.signal | ### Describe the bug
signal.alarm and signal.signal are used in the load.py module, but these are not supported by Windows.
### Steps to reproduce the bug
lighteval accelerate --model_args "pretrained=gpt2,trust_remote_code=True" --tasks "community|kinit_sts" --custom_tasks "community_tasks/kinit_evals.py" --output... | open | 2024-10-10T12:00:19Z | 2024-10-10T12:00:19Z | https://github.com/huggingface/datasets/issues/7212 | [] | TomasJavurek | 0 |
hankcs/HanLP | nlp | 1,373 | java代码以后维护吗? | 你好作者,我刚刚买了你们的书,发现今天源码都换成py了,请问以后java部分还会同步更新吗? | closed | 2020-01-02T15:39:05Z | 2020-01-02T19:02:31Z | https://github.com/hankcs/HanLP/issues/1373 | [] | Wang-JiaMing | 1 |
babysor/MockingBird | deep-learning | 35 | sounddevice报错问题 | 在win10默认情况下系统编码格式为gbk,在运行demo_toolbox.py时会报错:
```
UnicodeDecodeError: 'utf-8' codec can't decode byte 0xc2 in position 6: invalid continuation byte
```
打开`D:\Env\anaconda3\Lib\site-packages\sounddevice.py`移动到573行,有相关报错的issue,更改为`mbcs`后错误变成:
```
UnicodeDecodeError: 'mbcs' codec can't decode bytes in position 0--1:... | closed | 2021-08-23T02:23:39Z | 2021-09-22T08:41:11Z | https://github.com/babysor/MockingBird/issues/35 | [] | lonelyman0108 | 1 |
SYSTRAN/faster-whisper | deep-learning | 794 | Are timestamp tokens used in previous text? | According to Figure 1 in the whisper paper, during training, the previous text tokens does not contain timestamp tokens. However, using trascribe with `without_timestamps=False` and `condition_on_previous_text=True`, the prompt tokens (which contains previous text) get passed into model with the timestamp tokens. Print... | open | 2024-04-19T09:07:13Z | 2024-04-19T13:30:18Z | https://github.com/SYSTRAN/faster-whisper/issues/794 | [] | George0828Zhang | 0 |
apragacz/django-rest-registration | rest-api | 100 | Resend activation link | ### Checklist
* [x] I read [Contribution Guidelines](https://github.com/apragacz/django-rest-registration/blob/master/CONTRIBUTING.md#issues)
* [x] I searched [the documentation](https://django-rest-registration.readthedocs.io/) to ensure that the requested feature is not already implemented and described
* ... | closed | 2020-01-30T06:22:18Z | 2020-02-22T21:20:08Z | https://github.com/apragacz/django-rest-registration/issues/100 | [
"type:feature-request"
] | 14MR | 4 |
robusta-dev/robusta | automation | 1,272 | "Robusta currently does not have the option to customize the resend alert time" | Default Robusta's resend time alert by Robusta's Playbook is 15 minutes. I suggest we should have an option for users to customize this time to avoid noisy alerts.
Description:
This time it called: "Repeat interval":
The waiting time to resend an alert after they have successfully been sent.
Thanks you so much! | open | 2024-01-31T03:37:27Z | 2024-01-31T03:37:52Z | https://github.com/robusta-dev/robusta/issues/1272 | [] | anhlt190199 | 1 |
httpie/cli | rest-api | 600 | The content of a response is not return on 413 | When trying to post through Google Load Balancer I get this error and the response it not returned from the Nginx but the curl version works.
```
$ http -f POST XXX \
> variables='XXXX' \
> file@./testfile.dat
http: error: ConnectionError: ('Connection aborted.', BrokenPipeError(32, 'Broken pipe')) while doing P... | closed | 2017-08-09T12:20:37Z | 2023-05-26T11:09:20Z | https://github.com/httpie/cli/issues/600 | [] | kevinsimper | 5 |
axnsan12/drf-yasg | rest-api | 89 | Examples for Schema props and Parameters | Is it possible to specify example param values in a schema?
e.g.:
````
@swagger_auto_schema(method='get',
manual_parameters=[
openapi.Parameter('serial', openapi.IN_QUERY, type=openapi.TYPE_STRING, example="785343")
],
respo... | closed | 2018-03-21T12:13:48Z | 2018-08-06T13:52:44Z | https://github.com/axnsan12/drf-yasg/issues/89 | [] | eadmaster | 1 |
hzwer/ECCV2022-RIFE | computer-vision | 77 | 怎样才能调用NVdia的显卡运行? | hello,hzwer你好,我的配置是1050ti4G i57300HQ 内存16G。按照usage run 的第一个案例输入指令运行的时候CPU占用100了,内存占用也很高。但是显存占用接近零。要怎样才能调动显卡运行呢? | closed | 2020-12-22T08:34:31Z | 2020-12-23T15:14:14Z | https://github.com/hzwer/ECCV2022-RIFE/issues/77 | [] | csncxf | 2 |
hankcs/HanLP | nlp | 734 | 常见姓名识别出错:赵红 | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2018-01-04T07:49:05Z | 2018-01-04T08:00:47Z | https://github.com/hankcs/HanLP/issues/734 | [
"improvement"
] | dbmove | 1 |
pywinauto/pywinauto | automation | 880 | Some tools for the toolbelt (and GPL license discussion) | I am not sure how deep into the Windows API pywinauto dives or where the line is drawn until something is not considered "GUI"
Here are some things I wrote for accessing different portions of the Windows API, they might be useful and they might not... I wanted to share. dealing with ctypes and the Windows API does ... | open | 2020-01-12T04:43:55Z | 2020-01-19T21:20:57Z | https://github.com/pywinauto/pywinauto/issues/880 | [
"question"
] | kdschlosser | 15 |
errbotio/errbot | automation | 1,004 | Errbot quits if a command filter is not implemented correctly | Traceback (most recent call last):
File "/home/gbin/.virtualenvs/errbot/bin/errbot", line 11, in <module>
load_entry_point('errbot', 'console_scripts', 'errbot')()
File "/home/gbin/projects/errbot/errbot/cli.py", line 297, in main
bootstrap(backend, root_logger, config, restore)
File "/home/gbin/proj... | closed | 2017-05-09T21:46:51Z | 2017-07-03T14:15:06Z | https://github.com/errbotio/errbot/issues/1004 | [] | gbin | 0 |
nerfstudio-project/nerfstudio | computer-vision | 3,512 | Problems with rendering | When I use Nerfacto to train my own dataset, the rendered results are not inside the bounding box, but outside it
| closed | 2024-11-05T01:35:31Z | 2024-11-05T01:40:16Z | https://github.com/nerfstudio-project/nerfstudio/issues/3512 | [] | cwh01 | 1 |
pyqtgraph/pyqtgraph | numpy | 3,092 | Windows only: bad performence / stuck when QApplication and QMainWindow are used? | Hello,
I have this Qt application that shows multiple graphs and updates them using a 1ms `QTimer` (as fast as possible). I developed most of it on a Linux machine, and after it got into shape, I tried to deploy it on a Windows machine (the target platform), and I was surprised to see how buggy / slow it is!
Here... | open | 2024-07-11T15:46:29Z | 2024-07-28T09:46:58Z | https://github.com/pyqtgraph/pyqtgraph/issues/3092 | [] | doronbehar | 4 |
huggingface/diffusers | deep-learning | 10,839 | Dreambooth LoRA Flux training last step error | ### Describe the bug
As soon as the training is done and the code wants to clear up and do its last steps I get this error
Steps: 99%|█████████▉| 397/400 [07:45<00:03, 1.16s/it, loss=0.397, lr=1]
Steps: 100%|█████████▉| 398/400 [07:47<00:02, 1.20s/it, lo... | open | 2025-02-20T10:14:43Z | 2025-03-22T15:02:51Z | https://github.com/huggingface/diffusers/issues/10839 | [
"bug",
"stale"
] | PluginBOXone | 16 |
ray-project/ray | pytorch | 51,262 | [core][gpu-objects] Garbage collection for in-actor GPU objects | ### Description
We should garbage-collect the GPU objects in the in-actor store when their reference count reaches 0 for both the sender / receiver actors.
### Use case
_No response_ | open | 2025-03-11T18:49:27Z | 2025-03-11T22:04:38Z | https://github.com/ray-project/ray/issues/51262 | [
"enhancement",
"P0",
"core",
"gpu-objects"
] | kevin85421 | 0 |
strawberry-graphql/strawberry-django | graphql | 209 | After update to version 0.8 the GraphQL type of field with method resolver is generated as 'DjangoModelType' | <!-- Provide a general summary of the bug in the title above. -->
<!--- This template is entirely optional and can be removed, but is here to help both you and us. -->
<!--- Anything on lines wrapped in comments like these will not show up in the final text. -->
## Describe the Bug
Given the [models](https://gi... | closed | 2022-11-07T17:34:27Z | 2025-03-20T15:57:09Z | https://github.com/strawberry-graphql/strawberry-django/issues/209 | [
"bug"
] | Zlira | 5 |
tensorlayer/TensorLayer | tensorflow | 1,153 | AttributeError: module 'tensorflow.python.framework.ops' has no attribute '_TensorLike' | ### New Issue Checklist
- I have read the [Contribution Guidelines](https://github.com/tensorlayer/tensorlayer/blob/master/CONTRIBUTING.md)
- I searched for [existing GitHub issues](https://github.com/tensorlayer/tensorlayer/issues)
### Issue Description
AttributeError: module 'tensorflow.python.framework.ops... | closed | 2022-02-14T13:18:29Z | 2022-02-15T02:14:55Z | https://github.com/tensorlayer/TensorLayer/issues/1153 | [] | jaried | 2 |
Yorko/mlcourse.ai | pandas | 609 | The link - https://mlcourse.ai/video - gives a 404 error. | In 'Fall 2019. Quiz 1. Decision trees and Random Forests' assignment - at the link -
https://nbviewer.jupyter.org/github/Yorko/mlcourse.ai/blob/master/jupyter_english/quizzes_fall2019/quiz1_trees_forests.ipynb?flush_cache=true
the link 'https://mlcourse.ai/video'
which is part of the sentence - 'There are 5 v... | closed | 2019-09-09T11:35:01Z | 2019-09-09T14:53:34Z | https://github.com/Yorko/mlcourse.ai/issues/609 | [] | vidyabhandary | 1 |
lepture/authlib | flask | 244 | Add more specificity to docstrings | Currently in the docstrings I see various references to sections of what I presume is the documentation - see the image below for an example. Are these outdated or am I just not able to find them? Thanks for any help!

translate = pipe_translate.predict("Sziasztok, mi a helyzet?")
and the predict part takes about 5 second, and I have an A100 GPU,
... | open | 2021-05-31T15:52:29Z | 2021-07-17T05:28:34Z | https://github.com/JohnSnowLabs/nlu/issues/52 | [
"question"
] | kormoczi | 13 |
albumentations-team/albumentations | deep-learning | 1,599 | [tech debt] Add automatic check to validate that links in Readme are valid | I think, there should be some tool for pre-commit hook to check that. | closed | 2024-03-20T02:54:06Z | 2024-10-31T03:00:45Z | https://github.com/albumentations-team/albumentations/issues/1599 | [
"good first issue",
"Tech debt"
] | ternaus | 0 |
supabase/supabase-py | fastapi | 102 | Replace makefile for poetry scripts | This would be more integrated with the poetry ecosystem as well as it would enhance compatibility w windows | closed | 2021-12-22T00:31:56Z | 2022-10-21T09:32:26Z | https://github.com/supabase/supabase-py/issues/102 | [
"good first issue",
"hacktoberfest"
] | dreinon | 0 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 634 | Synthesizer doesn't work in Python 3.8+ | The synthesizer uses Tensorflow 1.x, which is not supported in Python 3.8 or higher. We need help to upgrade the synthesizer model.
* In #370, we tried upgrading the code to Tensorflow 2.x. However, the differences between TF 1.x and 2.x are significant. Even switching to an existing TF 2.x Tacotron model would requ... | closed | 2021-01-20T02:23:35Z | 2021-11-12T23:08:39Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/634 | [] | ghost | 7 |
keras-rl/keras-rl | tensorflow | 380 | Issue importing keras-rl on tensorflow-macos | The tensorflow-macos branch is currently archived so I was hoping someone could help me find a fix for this Import error. Im trying to import keras-rl packages and its throwing errors because TensorFlow does not have a function that keras uses during import. Idk if there's a previous version of keras-rl that would fix ... | open | 2021-09-10T15:49:07Z | 2024-07-16T09:08:04Z | https://github.com/keras-rl/keras-rl/issues/380 | [] | Sebewe | 4 |
pallets-eco/flask-wtf | flask | 494 | CSRF Token does not attach to session | I'm using Flask as an API and ReactJS for my front-end, and followed the [CSRF Protection Docs with Javascript Requests (Axios)](https://flask-wtf.readthedocs.io/en/0.15.x/csrf/#javascript-requests).
#### Please follow my Init App file to see my code: <https://gist.github.com/Arthurdb1999/c72226800f19d6c8553d216fb17... | open | 2021-12-09T14:52:42Z | 2023-07-25T18:55:11Z | https://github.com/pallets-eco/flask-wtf/issues/494 | [
"csrf"
] | Arthurdb1999 | 2 |
twopirllc/pandas-ta | pandas | 62 | Parallel Calculation of Indicators | Hi, thanks for the amazing library!
Is there a way to perform parallel processing of the technical indicators, especially if you are trying to calculate all of them, such as
```
df.ta.strategy(name='all')
``` | closed | 2020-06-07T03:08:22Z | 2020-06-17T17:21:56Z | https://github.com/twopirllc/pandas-ta/issues/62 | [
"enhancement"
] | athenawisdoms | 2 |
Evil0ctal/Douyin_TikTok_Download_API | web-scraping | 192 | [BUG] Internal Server Error | 请帮我解决这个问题
| closed | 2023-04-03T09:00:35Z | 2023-04-05T10:36:27Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/192 | [
"BUG"
] | cauindo113 | 5 |
vitalik/django-ninja | rest-api | 526 | Access request user in schema resolve function | I have likes model between users, meaning that I can like other's profile.
I am looking forward to include likes count in schema, when accessing others profile, so that I can pass data to frontend.
```
class DetailedProfileSchema(Schema):
id: uuid.UUID
.....
likes_count: int
def resolve_likes... | closed | 2022-08-12T10:14:18Z | 2022-10-19T13:05:18Z | https://github.com/vitalik/django-ninja/issues/526 | [] | ssandr1kka | 5 |
InstaPy/InstaPy | automation | 6,270 | Selenium Automation for Two Factor Authentication | @timgrossmann
When the instagram's TFA method is enabled and we gave our backup codes in the InstaPy instance, the code is typed in the security code box but there is a functional error in that part.
By default, Instagram asks the user to enter the code from the Authenticator app. What InstaPy does is that it typ... | open | 2021-07-11T05:56:31Z | 2021-11-29T23:57:56Z | https://github.com/InstaPy/InstaPy/issues/6270 | [] | arunpmurugavel24 | 4 |
waditu/tushare | pandas | 837 | income 的report_type=11,不能拿到数据 | df = pro.income(ts_code='601019.SH', start_date='20110101', end_date='20181122', fields='',report_type=11)
结果为空
df = pro.income(ts_code='601019.SH', start_date='20110101', end_date='20181122', fields='',report_type=1)
能拿到数据,但是ann_date与f_ann_date并未起到区分作用,即不同的数据条目是重复的,我并不能看到最早发布财报的日期及数据。
leonfeng2010 | open | 2018-11-22T02:41:28Z | 2018-11-22T02:50:40Z | https://github.com/waditu/tushare/issues/837 | [] | leonfeng2010 | 0 |
predict-idlab/plotly-resampler | data-visualization | 57 | Wondering about the license | Hello.
I really like this software and I have been using it a lot.
Now that I would want to use it in our company, where we run a local dash app. The app is used by me and my colleagues to share results with each other. But after reading the license it seems that I can not use this internally within our company? | closed | 2022-05-13T09:53:11Z | 2022-06-29T09:23:53Z | https://github.com/predict-idlab/plotly-resampler/issues/57 | [
"question"
] | prokie | 4 |
jmcnamara/XlsxWriter | pandas | 598 | Feature Request: clone method in Format | For usability, it would be nice if the `Format` class supports `clone` method.
For example, if `clone` method exists.
```
f = wb.add_format({
'bottom': 1,
'align': 'center',
'valign': 'vcenter',
'font_size': 14
})
sheet.merge_range('B5:D5', 'Sample Text1', f)
sheet.merge_range('B7:C7', '... | closed | 2019-02-08T06:29:23Z | 2019-02-09T10:35:56Z | https://github.com/jmcnamara/XlsxWriter/issues/598 | [
"feature request"
] | jrog612 | 1 |
python-restx/flask-restx | api | 474 | Release schedule ETA | Hello,
I've noticed that the compatibility fix for Werkzeug and Flask have been merged.
I was wondering if there is an estimated date for when there will be a release version available
to use and update projects to. | closed | 2022-09-16T13:03:34Z | 2022-11-01T18:36:35Z | https://github.com/python-restx/flask-restx/issues/474 | [
"question"
] | zcherry17 | 9 |
MilesCranmer/PySR | scikit-learn | 337 | BoundsError in custom eval_tree_array | ### What happened?
I tried to run '_eval_tree_array' with array that has different dimensions then cX in 'eval_tree_array'
And if i understand correctly after test runs l've got an error ''
### Version
0.18.0
### Operating System
macOS
### Interface
Jupyter Notebook
### Relevant log output
```shell
BoundsE... | closed | 2023-05-25T12:02:26Z | 2023-05-26T16:19:01Z | https://github.com/MilesCranmer/PySR/issues/337 | [
"bug"
] | DenisSvirin | 8 |
TencentARC/GFPGAN | pytorch | 336 | Control the strength of restoration effect | Hi. Is there any way to control the strength of restoration effect? | open | 2023-02-13T09:51:47Z | 2023-02-13T15:20:15Z | https://github.com/TencentARC/GFPGAN/issues/336 | [] | ntvuongg | 1 |
tensorpack/tensorpack | tensorflow | 1,211 | Data loading for small/tiny images | Hi, Dear all,
Tensorpack provides great and flexible data loading module, which is super fast. I have a question about data loading for tiny/small images (e.g., with size 32x128). If I have one billion of these images to loading, is there any good solution on how to load these image for training without considering t... | closed | 2019-05-24T08:05:39Z | 2019-05-24T08:51:08Z | https://github.com/tensorpack/tensorpack/issues/1211 | [] | Remember2018 | 2 |
sqlalchemy/sqlalchemy | sqlalchemy | 9,985 | mypy fails if WriteOnlyMapped is used in join() | ### Ensure stubs packages are not installed
- [X] No sqlalchemy stub packages is installed (both `sqlalchemy-stubs` and `sqlalchemy2-stubs` are not compatible with v2)
### Verify if the api is typed
- [X] The api is not in a module listed in [#6810](https://github.com/sqlalchemy/sqlalchemy/issues/6810) so it should ... | closed | 2023-06-20T13:41:19Z | 2023-06-21T17:57:34Z | https://github.com/sqlalchemy/sqlalchemy/issues/9985 | [
"bug",
"orm",
"typing",
"near-term release"
] | asvetlov | 3 |
jupyter/nbgrader | jupyter | 1,063 | Implement support for nbgrader in JupyterLab | Hello,
I saw a video about using nbgrader, and it seems that you have done a great job.
I was wondering if it is possible to install nbgrader extension for `JupyterLab` within the jupyterhub?
Can you please help me, how to do that?
thanks for your time. | closed | 2019-01-23T17:01:10Z | 2019-05-28T22:14:02Z | https://github.com/jupyter/nbgrader/issues/1063 | [
"duplicate",
"enhancement"
] | alirezamecheng | 3 |
huggingface/pytorch-image-models | pytorch | 1,599 | [BUG] ViT ImageNet1K weights | **Describe the bug**
In Version: 0.5.4 for example, dose vit_tiny_patch16_224 means vit_tiny trained from scratch on ImageNet1K?
However, in the current Version 0.6, vit_tiny_patch16_224 means vit_tiny pretrained on 21k and then fine-tuned on in1k, which is very misleading and leading to errors for down-stream experi... | closed | 2022-12-23T03:05:49Z | 2023-02-02T04:44:51Z | https://github.com/huggingface/pytorch-image-models/issues/1599 | [
"bug"
] | hellojialee | 2 |
browser-use/browser-use | python | 1,068 | OpenRouters | ### Bug Description
It needs to work with OpenRouters and customized IPs. It's really bad to be stuck with OpenAI.
### Reproduction Steps
.
### Code Sample
```python
.
```
### Version
.
### LLM Model
Other (specify in description)
### Operating System
.
### Relevant Log Output
```shell
``` | open | 2025-03-19T08:16:59Z | 2025-03-23T13:59:40Z | https://github.com/browser-use/browser-use/issues/1068 | [
"bug"
] | andersonxavier | 1 |
falconry/falcon | api | 2,283 | Add `Typing :: Typed` Trove classifier | Add `Typing :: Typed` [Trove classifier](https://pypi.org/classifiers/) to our package's metadata.
Not sure what the exact requirements are, but I think once the current typing workload is completed, we should qualify. | closed | 2024-08-20T11:19:16Z | 2024-08-27T06:01:40Z | https://github.com/falconry/falcon/issues/2283 | [
"good first issue",
"maintenance",
"typing"
] | vytas7 | 0 |
google-deepmind/sonnet | tensorflow | 31 | Fedora 24 Sonnet Installation Issue | posted on Issue #23 but since it's closed, I am guessing that it is not being review.
I used pip to upgrade TensorFlow to 1.1 but having an error when trying to configure the headers to bazel build:
```
[cmwatson@xx tensorflow]$ ./configure
Please specify the location of python. [Default is /usr/bin/python]:
... | closed | 2017-05-09T19:48:20Z | 2017-05-22T17:12:07Z | https://github.com/google-deepmind/sonnet/issues/31 | [] | curtismwatson | 5 |
MagicStack/asyncpg | asyncio | 955 | Connection pool aenter get connection from queue and not return connection to user. | * **asyncpg version**: 0.26.0
* **PostgreSQL version**: 12
* **Do you use a PostgreSQL SaaS? If so, which? Can you reproduce
the issue with a local PostgreSQL install?**: no, local installation
* **Python version**: 3.9
* **Platform**: linux, centos8
* **Do you use pgbouncer?**: no
* **Did you install async... | closed | 2022-09-19T15:36:15Z | 2023-10-09T17:07:53Z | https://github.com/MagicStack/asyncpg/issues/955 | [] | matemax | 1 |
tatsu-lab/stanford_alpaca | deep-learning | 236 | Training loss curve like stairs. | I'm trying to rerun the training and the loss curve dramatic drops after each epoch, does anyone know why? Below is a loss curve I trained with 3 epochs
<img width="333" alt="image" src="https://user-images.githubusercontent.com/5069709/233734443-394a8f44-da70-41af-9bdb-359b90a97d8c.png">
| closed | 2023-04-21T21:05:34Z | 2023-07-06T07:45:05Z | https://github.com/tatsu-lab/stanford_alpaca/issues/236 | [] | yuanzhedong | 8 |
nteract/papermill | jupyter | 409 | 1.1.0 Release | Going to release 1.1.0 in the next day or two now that nbconvert 5.6.0 is out! If there's any outstanding small items not PR'd / merged that one would like in, please post on the thread. A changelog PR to follow. | closed | 2019-08-09T04:23:47Z | 2019-08-16T20:05:32Z | https://github.com/nteract/papermill/issues/409 | [] | MSeal | 2 |
pallets-eco/flask-wtf | flask | 39 | Project documentation page seems to be outdated | The project documentation page linked in the README (http://packages.python.org/Flask-WTF/) seems to be outdated.
I noticed this error because the rename of the csrf_token field. The documentation was correctly upgraded but it seems that you didn't uploaded the changes to pypi.
Cheers
| closed | 2012-05-18T16:14:30Z | 2021-05-30T01:24:46Z | https://github.com/pallets-eco/flask-wtf/issues/39 | [] | jorgebastida | 2 |
LAION-AI/Open-Assistant | python | 3,377 | Moderator message search on edited messages shows incorrect results | When a message is edited, message search will still return that message if the original content matches the search phrase, even if the new content doesn't. This also results in the moderator message table showing the original content in the search view and not showing the 'edited' tag.
You can see this by going the ... | closed | 2023-06-10T21:59:26Z | 2023-06-11T18:48:09Z | https://github.com/LAION-AI/Open-Assistant/issues/3377 | [
"bug",
"backend"
] | someone13574 | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.