
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
graphistry/pygraphistry | jupyter | 51 | Set API key based on local user profile, if available | IPython already has a notion of user built in, so rather than each user baking in their API key (and the setting getting confused when notebooks get shared), dynamically lookup the API key based on who is logged into IPython.
This has been becoming a bit of an issue in practice in team settings.
( + @thibaudh @pade... | closed | 2016-01-23T22:21:32Z | 2016-02-25T00:35:21Z | https://github.com/graphistry/pygraphistry/issues/51 | [
"enhancement",
"p3"
] | lmeyerov | 3 |
ckan/ckan | api | 8,060 | Contributing guide / Python coding standards links to Python 2 documents | [The Contributing guide](https://docs.ckan.org/en/latest/contributing/index.html)'s [_Python coding standards_ page](https://docs.ckan.org/en/latest/contributing/python.html) contains a few links to Python documentation which refer to the Python 2 documentation, in sections _[Logging](https://docs.ckan.org/en/latest/co... | closed | 2024-02-06T15:11:01Z | 2024-02-13T13:03:43Z | https://github.com/ckan/ckan/issues/8060 | [] | Chealer | 0 |
flasgger/flasgger | api | 5 | Flasgger miss insert `<br>` elements whem we format html elements inside yml description. | Flasgger miss insert `<br>` elements whem we format html elements inside yml description.
Compare:
```
def post(self):
"""
Some text
<table><tr><th>**Title 1**</th><th>**Title 2**</th></tr><tr><td>field 1</td><td>desc</td></tr><tr><td>field 2</td><td>desc descdesc desc.</td></tr><tr><td>field 3</td><td>b... | closed | 2015-08-31T13:22:38Z | 2015-08-31T20:54:23Z | https://github.com/flasgger/flasgger/issues/5 | [] | ederfmartins | 2 |
mckinsey/vizro | pydantic | 1,008 | Kedro-Vizro integration | @antonymilne wrote:
> I'd love to hear any more feedback/ideas you have for the kedro integration. At the moment it's pretty lightweight but I'd like to try and make it deeper.
@gtauzin wrote:
>
> Actually, I've been thinking to open an issue on the kedro issue tracker to discuss this. Here are a few ideas:
>
> 1.... | open | 2025-02-11T10:05:20Z | 2025-03-19T17:30:30Z | https://github.com/mckinsey/vizro/issues/1008 | [
"Feature Request :nerd_face:"
] | antonymilne | 1 |
kennethreitz/responder | graphql | 260 | Feature request: Trio/Curio support | Not sure how it would actually look like, but would be great to see support for [Trio](https://github.com/python-trio/trio) (or maybe [Curio](https://github.com/dabeaz/curio) in Responder (and Requests) 🙂
Some others are starting to add support, e.g., [Hypercorn](https://www.reddit.com/r/Python/comments/9xak3w/hype... | closed | 2018-12-11T10:36:10Z | 2019-04-29T21:18:26Z | https://github.com/kennethreitz/responder/issues/260 | [] | beorn | 1 |
tensorpack/tensorpack | tensorflow | 1,346 | Increasing the batch size in faster rcnn training. | How to increase batch size for faster rcnn training? I am not able find the batch size parameter in the config.py or anywhere else.
| closed | 2019-10-16T08:37:11Z | 2019-10-16T08:47:14Z | https://github.com/tensorpack/tensorpack/issues/1346 | [
"duplicate"
] | dvlshah | 1 |
pyqtgraph/pyqtgraph | numpy | 2,549 | ROI cannot remove handle correctly | when a handle of a RectROI is removed, it is still shown in the view.
```python
from deps.pyqtgraph_master_v20221209 import pyqtgraph as pg
from PyQt5.QtWidgets import *
import numpy as np
if __name__ == '__main__':
app = QApplication([])
win = pg.GraphicsView()
vb = pg.ViewBox(invertY=True)
... | open | 2022-12-09T17:17:20Z | 2023-05-14T12:06:08Z | https://github.com/pyqtgraph/pyqtgraph/issues/2549 | [] | Fokatu | 2 |
MaartenGr/BERTopic | nlp | 2,018 | `transform` method not handling single embeddings or strings given to it. | **Issue**
Currently the `transform` method of the `BERTopic` has to recieve a list of strings as the documents and if embeddings are present then it needs to be a 2darray of shape (len(documents, embedding_dimension). This requires extra reshape calls when trying to call the `transform` method on a single document.
... | open | 2024-05-29T07:03:27Z | 2024-05-31T13:31:06Z | https://github.com/MaartenGr/BERTopic/issues/2018 | [] | 1jamesthompson1 | 1 |
alteryx/featuretools | scikit-learn | 2,556 | Support dask 2023.4.0 in Featuretools | closed | 2023-04-20T13:47:40Z | 2023-07-27T13:37:02Z | https://github.com/alteryx/featuretools/issues/2556 | [] | gsheni | 0 | |
dask/dask | numpy | 11,426 | xarray.rolling().construct() and sliding_window_view chunking behaviour | Using ``.rolling().construct()`` will inject new dimensions into an array with ``sliding_window_view`` under the hood. NumPy is clever about this by arranging things to be a view of the underlying array and thus not increasing the memory footprint. Problems are starting to show up if you call a follow up operation that... | closed | 2024-10-11T13:15:54Z | 2024-11-05T12:31:09Z | https://github.com/dask/dask/issues/11426 | [
"array"
] | phofl | 1 |
unionai-oss/pandera | pandas | 1,278 | add_missing_columns issues with non-standard dtypes, non-None null default values | Recently added DataFrame schema config option 'add_missing_columns' doesn't support the following scenarios. Requesting to add support.
1) Non-python types such as Numpy's np.int8, np.int16, etc. fail validation when coerce=False because the default value is applied as a 64-bit int/float dtype. Assignment works okay... | closed | 2023-07-29T00:30:17Z | 2023-10-18T14:59:27Z | https://github.com/unionai-oss/pandera/issues/1278 | [
"bug"
] | derinwalters | 0 |
aiogram/aiogram | asyncio | 1,646 | bot can't send webapp button in a private channel "BUTTON_TYPE_INVALID" | ### Checklist
- [x] I am sure the error is coming from aiogram code
- [x] I have searched in the issue tracker for similar bug reports, including closed ones
### Operating system
windows 10
### Python version
3.12
### aiogram version
latest
### Expected behavior
bot should send webapp button in a private chann... | closed | 2025-02-27T07:48:30Z | 2025-02-27T17:45:58Z | https://github.com/aiogram/aiogram/issues/1646 | [
"invalid",
"upstream"
] | Ildivo | 1 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 4,019 | When exporting a report the various dates within the report (e.g. calendar entries, time stamps) may differentiate from what the recipient sees. | ### What version of GlobaLeaks are you using?
4.14.5
### What browser(s) are you seeing the problem on?
All
### What operating system(s) are you seeing the problem on?
Windows
### Describe the issue
The extracted dates for calendar entries contain a random UTC time (9 or 10.00pm).
For other dates it contains th... | open | 2024-03-11T14:07:45Z | 2024-10-08T11:38:32Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/4019 | [
"T: Bug"
] | elbill | 3 |
horovod/horovod | deep-learning | 3,266 | What does shard mean in the lightning PetastormDataModule? | Hi!
I'm playing a bit with your lightning datamodule https://github.com/horovod/horovod/blob/master/horovod/spark/lightning/datamodule.py and I can't make it work. It's complaining about shard count/number of row-groups.
My code:
```python
path = "file:///dbfs/file.parquet"
dm = PetastormDataModule(path, pat... | closed | 2021-11-09T17:45:43Z | 2024-05-28T13:41:28Z | https://github.com/horovod/horovod/issues/3266 | [] | jiwidi | 1 |
Lightning-AI/pytorch-lightning | data-science | 20,075 | ModelCheckpoint save ckpts at the end of every epoch even in step-saving strategy | ### Bug description
When `ModelCheckpoint` is enabled and **no validation set is given**, the trainer still save the model checkpoint at the end of every epoch.
I have turn on the `every_n_train_steps=1000` and `every_n_epochs=None`. And the expected behavior according to the docs of [ModelCheckpoint API](https://l... | open | 2024-07-12T09:53:49Z | 2024-07-12T09:54:03Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20075 | [
"bug",
"needs triage",
"ver: 2.2.x"
] | leonardodalinky | 0 |
KevinMusgrave/pytorch-metric-learning | computer-vision | 292 | Choose FAISS gpu usage | Hi,
Thanks a lot for the library !
I had an issue using AccuracyCalculator because FAISS was using other gpus than the one I was working on.
Would it be possible to change the function [`get_knn`](https://github.com/KevinMusgrave/pytorch-metric-learning/blob/master/src/pytorch_metric_learning/utils/stat_utils.py... | closed | 2021-03-18T10:26:50Z | 2021-11-28T19:24:37Z | https://github.com/KevinMusgrave/pytorch-metric-learning/issues/292 | [
"enhancement",
"fixed in dev branch"
] | elias-ramzi | 5 |
apify/crawlee-python | web-scraping | 884 | Consider using `lazy_object_proxy` for `service_locator` to simplify resetting the test environment | If `service_locator` was a `lazy_object_proxy`, we could just re-set `crawlee._service_locator.service_locator` to a new instance of `ServiceLocator` and we wouldn't need to do this here and in crawlee tests (code duplication across different packages is kinda painful)
_Originally posted by @janbuchar in https://githu... | open | 2025-01-08T13:13:27Z | 2025-01-15T13:27:19Z | https://github.com/apify/crawlee-python/issues/884 | [
"t-tooling"
] | janbuchar | 0 |
hankcs/HanLP | nlp | 1,008 | 能否在依存句法分析的过程中使用指定分词器再做后续处理? | <!--
注意事项和版本号必填,否则不回复。若希望尽快得到回复,请按模板认真填写,谢谢合作。
-->
## 注意事项
请确认下列注意事项:
* 我已仔细阅读下列文档,都没有找到答案:
- [首页文档](https://github.com/hankcs/HanLP)
- [wiki](https://github.com/hankcs/HanLP/wiki)
- [常见问题](https://github.com/hankcs/HanLP/wiki/FAQ)
* 我已经通过[Google](https://www.google.com/#newwindow=1&q=HanLP)和[issue区检... | closed | 2018-10-31T01:56:46Z | 2020-01-01T10:56:13Z | https://github.com/hankcs/HanLP/issues/1008 | [
"ignored"
] | starpipi | 3 |
collerek/ormar | sqlalchemy | 1,139 | FastpAPI state has not database | Hello everyone
There is a problem using ormar with fastapi,
`database_ = app.state.database`
my complete code:
async def connect_database(app: FastAPI) -> None:
database_ = app.state.database
if not database_.is_connected:
await database_.connect()
async def disconnect_database(
ap... | closed | 2023-07-10T18:13:22Z | 2023-07-17T15:20:10Z | https://github.com/collerek/ormar/issues/1139 | [
"bug"
] | Kokoserver | 4 |
explosion/spacy-course | jupyter | 85 | Missing implementation to output matches from the matcher at chapter1_03_rule-based-matching.md | ## Phenomenon
There is the output of the matches from the matcher at [chapter1_03_rule-based-matching.md Matching lexical attributes](https://github.com/ines/spacy-course/blob/master/chapters/en/slides/chapter1_03_rule-based-matching.md#matching-lexical-attributes), but the implementation to get it is missing.
``... | open | 2020-09-21T13:15:50Z | 2020-09-21T13:16:59Z | https://github.com/explosion/spacy-course/issues/85 | [] | icoxfog417 | 0 |
thtrieu/darkflow | tensorflow | 387 | Valueerror : mmap length is greater than file size | I have got a problem when I was loading the model to initial the model,there exists yolo-tiny.weights in bin content and the yolo-tiny.cfg is in cfg/vi/.and I am sure the road is right.could you solve it for me.
flow --model /home/sys324/pycharm/Zxx_Project/darkflow-master/cfg/v1/yolo-tiny.cfg --load /home/sys324... | open | 2017-08-29T03:33:33Z | 2020-05-26T10:03:04Z | https://github.com/thtrieu/darkflow/issues/387 | [] | QueenJuliaZxx | 3 |
sktime/sktime | data-science | 7,289 | [BUG] `ExpandingCutoffSplitter` index out of bounds when `step_length` > 1 and used with `evaluate` | **Describe the bug**
<!--
A clear and concise description of what the bug is.
-->
This bug occurs in the ExpandingCutoffSplitter class when the step_length parameter is greater than 1 and is used in conjunction with the evaluate function. Specifically, an "index out of bounds" error is triggered, suggesting that ... | closed | 2024-10-17T16:19:59Z | 2024-10-18T04:48:19Z | https://github.com/sktime/sktime/issues/7289 | [
"bug",
"module:splitters&resamplers"
] | ninedigits | 4 |
piccolo-orm/piccolo | fastapi | 770 | Document `MigrationManager.get_table_from_snapshot` | We have a feature which is currently undocumented.
By using `MigrationManager.get_table_from_snapshot` you can get a table from the migration history.
```python
from piccolo.apps.migrations.auto.migration_manager import MigrationManager
from piccolo.table import Table
ID = "2023-02-09T12:53:36:698501"
VER... | open | 2023-02-22T16:57:57Z | 2023-02-22T16:57:57Z | https://github.com/piccolo-orm/piccolo/issues/770 | [
"documentation"
] | dantownsend | 0 |
jadore801120/attention-is-all-you-need-pytorch | nlp | 59 | KeyError on testing | After fixing a key error about tensor integer types, running translate.py seems to return KeyErrors with numbers, and checking with python seems to indicate that they are missing(the keys).
But skipping keys that are non-existent inside the write loop seems to return poor results.
result of pred.txt after running cod... | closed | 2018-08-23T06:05:46Z | 2018-08-27T06:39:31Z | https://github.com/jadore801120/attention-is-all-you-need-pytorch/issues/59 | [] | dksehdals216 | 2 |
jofpin/trape | flask | 292 | cannot import name JSONDecodeError | Linux mint (20.1) here
Steps to reproduce:
Normally installing everything
Had to install "Flask-SocketIO<5.0.0" (python2 pip install "Flask-SocketIO<5.0.0")
Installed flask (pip2 install flask)
Installed requests (pip2 install requests)
Honestly no idea how to fix this, I've looked around and I know w... | open | 2021-01-12T18:15:10Z | 2021-01-14T12:35:33Z | https://github.com/jofpin/trape/issues/292 | [] | LocalTerrorist1 | 1 |
jazzband/django-oauth-toolkit | django | 603 | Grant type client_credentials implementation | Hello,
We are implementing a OAuth 2.0 provider using `django-oauth-toolkit` and `django-rest-framework` for a ecommerce site using `django-oscar`. We have a SPA and our API, it makes sense to use `client_credentials` grant type as requests between SPA and API are only machine to machine.
https://github.com/jazz... | closed | 2018-05-29T07:31:55Z | 2019-05-29T13:43:52Z | https://github.com/jazzband/django-oauth-toolkit/issues/603 | [] | mekza | 1 |
LAION-AI/Open-Assistant | python | 3,510 | Implement inference rate limits | closed | 2023-06-23T09:13:39Z | 2023-06-30T18:03:48Z | https://github.com/LAION-AI/Open-Assistant/issues/3510 | [
"inference"
] | olliestanley | 0 | |
nl8590687/ASRT_SpeechRecognition | tensorflow | 113 | tensorflow.python.framework.errors_impl.InvalidArgumentError: sequence_length(3) <= 200 | 我按照AI柠檬的方法又给模型加上了aishell和primewords,但是在训练的时候,时不时的就会出现如下的错误,各位大神们能否帮看看是啥问题?
`Traceback (most recent call last):
File "train_mspeech.py", line 51, in <module>
ms.TrainModel(datapath, epoch = 50, batch_size = 64, save_step = 500)
File "/home/yx/ASRT_SpeechRecognition/SpeechModel251.py", line 199, in Tra... | closed | 2019-04-30T10:37:20Z | 2021-11-22T13:58:13Z | https://github.com/nl8590687/ASRT_SpeechRecognition/issues/113 | [] | xuchenxing | 5 |
docarray/docarray | fastapi | 1,188 | DocIndex: config via yaml file | It would be nice if a doc index could be configured via yaml file. Raised by Shukri from Weaviate (can't find his GH :/ ) | open | 2023-02-28T13:26:08Z | 2023-03-12T17:28:07Z | https://github.com/docarray/docarray/issues/1188 | [] | JohannesMessner | 1 |
HumanSignal/labelImg | deep-learning | 862 | A small suggestion | I suggest setting the shortcut key for adding the matrix(w) to a key near enter, which may be more convenient, otherwise it is tiring to press w and then press enter with one hand. | open | 2022-03-29T17:34:56Z | 2022-05-18T20:14:34Z | https://github.com/HumanSignal/labelImg/issues/862 | [] | wyfffffei | 1 |
aminalaee/sqladmin | asyncio | 187 | Add some screenshots to the documentation | ### Checklist
- [X] There are no similar issues or pull requests for this yet.
### Is your feature related to a problem? Please describe.
I would really like to see some screenshots in the documentation similar to Fastapi Admin
This will help you better understand what the admin panel is like without downloading ... | closed | 2022-06-20T07:07:31Z | 2022-06-22T08:59:57Z | https://github.com/aminalaee/sqladmin/issues/187 | [] | FyZzyss | 2 |
pallets/flask | python | 5,279 | Issue with Werkzeug bump |
I have a few Flask applications running on Flask 2.3.2. On deployment today, the 2 apps went down. Error:
File "/tmp/8dbc37810e69912/wsgi.py", line 3, in <module>
2023-10-03T02:41:50.698042229Z from application import create_app
2023-10-03T02:41:50.698045529Z File "/tmp/8dbc37810e69912/application/__init... | closed | 2023-10-03T03:17:10Z | 2023-10-04T04:03:57Z | https://github.com/pallets/flask/issues/5279 | [] | ghawes85 | 2 |
ray-project/ray | data-science | 51,321 | [core][autoscaler][v2] do not removing nodes for upcoming resource requests | ### What happened + What you expected to happen
The issues described in https://github.com/ray-project/ray/pull/51122 still happen with autoscaler v2.
### Versions / Dependencies
Ray 2.43.0
### Reproduction script
See https://github.com/ray-project/ray/pull/51122
### Issue Severity
None | open | 2025-03-12T23:16:06Z | 2025-03-21T01:39:41Z | https://github.com/ray-project/ray/issues/51321 | [
"bug",
"core-autoscaler"
] | rueian | 2 |
HumanSignal/labelImg | deep-learning | 119 | make: *** No rule to make target `qt4py2'. |
When i run << make qt4py2 >> i get this --> make: *** No rule to make target `qt4py2'. Stop.
Can anyone help me with this?
- El Capitan 10.11.6
- Qt4
| closed | 2017-07-18T12:50:27Z | 2020-02-14T14:11:47Z | https://github.com/HumanSignal/labelImg/issues/119 | [] | rilias | 4 |
anselal/antminer-monitor | dash | 17 | Custom 404 error page | I am thinking in adding a custom 404 error page that I found and really liked.
Since we don't have a logo for the AntminerMonitor yet I think it is OK if we add an irrelevant image.
I could really need some feedback on that.
:
File "/opt/Real-ESRGAN/inference_realesrgan.py", line 7, i... | closed | 2021-12-12T16:57:56Z | 2021-12-12T17:01:17Z | https://github.com/xinntao/Real-ESRGAN/issues/185 | [] | geeknik | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 932 | Is Selenium 4 supported or should I be using 3.XX? | I just need to know if Selenium 4 is supported or if I should be using Selenium 3.XX.
Thanks,
andy | open | 2022-12-01T21:49:51Z | 2022-12-06T14:44:48Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/932 | [] | andycccccccc | 1 |
ultralytics/ultralytics | computer-vision | 18,970 | YOLOv8 Classifiction export to XML doesn't work!!! | Hi guys, I've trained a classifier of 373 classes with yolov8n. I've used this piece of code to convert my `.pt` model to `.xml`:
```
import openvino
from ultralytics import YOLO
import shutil
MODEL_NAME = "./make_yoloV8_372.pt"
model = YOLO(MODEL_NAME, task='classify')
model.export(format='openvino')
```
But, `xml... | closed | 2025-02-02T08:37:01Z | 2025-02-04T07:06:05Z | https://github.com/ultralytics/ultralytics/issues/18970 | [
"question",
"classify",
"exports"
] | image-rcdat | 4 |
graphdeco-inria/gaussian-splatting | computer-vision | 739 | Why is the reconstruction result not satisfactory? |


 | **Problem**: The aiomysql.Pool cannot detect certain situations when MariaDB breaks connections from the server side, and the pool will permanently continue to hand out (via acquire()) these broken connections, even though each use of that connection will cause PyMySQL exceptions (either OperationalError or InternalErr... | closed | 2018-09-14T00:06:45Z | 2022-01-26T17:41:39Z | https://github.com/aio-libs/aiomysql/issues/340 | [
"bug"
] | rspreen | 3 |
PokeAPI/pokeapi | graphql | 567 | Blastoise showing up undefined. | "https://pokeapi.co/api/v2/pokemon/blastoise shows as undefined". Works when doing this however : "https://pokeapi.co/api/v2/pokemon/9" | closed | 2021-01-29T08:11:52Z | 2021-01-29T09:41:26Z | https://github.com/PokeAPI/pokeapi/issues/567 | [] | chrisdogtn | 1 |
yinkaisheng/Python-UIAutomation-for-Windows | automation | 33 | Control.CaptureToImage(path) black screenshot UWP Apps | The CaptureToImage() method doesn't work with UWP application. It takes black screenshots.
For "ApplicationFrameWindow" Class Name.
**---- Code ----** (Exp:)
`import uiautomation as uiauto
calculatorWindow = uiauto.WindowControl(Name="Calculator") # The UWP calculator app
calculatorWindow.CaptureToImage("d:\\ca... | closed | 2018-05-17T14:10:42Z | 2018-05-21T11:14:34Z | https://github.com/yinkaisheng/Python-UIAutomation-for-Windows/issues/33 | [] | salihaMr | 4 |
wkentaro/labelme | deep-learning | 923 | [Feature] Import VGG Annotator .json to Labelme | I am trying to use Labelme2voc.py to generate masks png but i already finished creating polygon annotation to +1000 pictures in VGG Annotator. i don't see any way to import to Labelme to edit or to export as Labelme's json so i can use labelme2voc :(
is there any way to import VGG's json to Labelme?
i tried to conv... | closed | 2021-09-26T09:46:22Z | 2021-10-23T21:08:19Z | https://github.com/wkentaro/labelme/issues/923 | [] | GhamdiOmar | 4 |
NullArray/AutoSploit | automation | 577 | no arguments have been passed----02 | 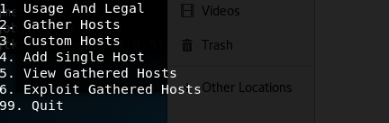
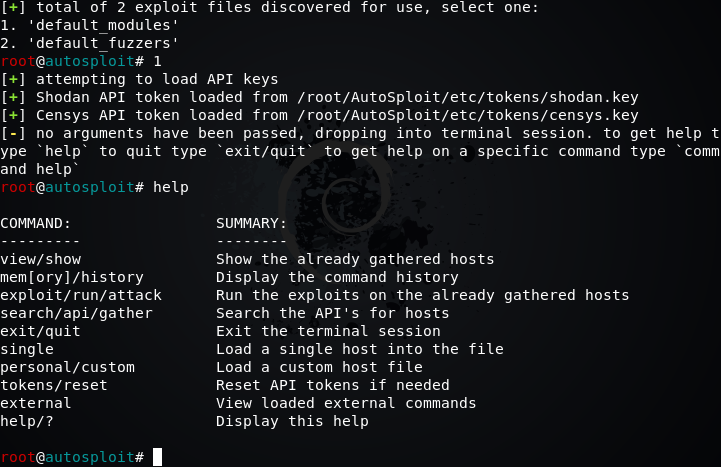
Hello, continue to ask you questions.
Why did you jump directly after selecting the mode, and... | closed | 2019-03-19T09:41:14Z | 2019-04-03T12:49:19Z | https://github.com/NullArray/AutoSploit/issues/577 | [] | CXXHK | 1 |
Kanaries/pygwalker | matplotlib | 569 | How to display percentage number on top of arc aka. the pie chart? | now, there isn't such function yet? also, is there any way to annotate numbers on any chart generated?
so that pygwalker at current stage is for prototyping? | open | 2024-06-04T08:01:59Z | 2024-06-05T03:00:37Z | https://github.com/Kanaries/pygwalker/issues/569 | [
"enhancement",
"good first issue",
"graphic-walker",
"P2"
] | tomriddle1234 | 2 |
plotly/dash-bio | dash | 174 | Nested props of component don't have default values as defined in .react.js file | if there are default values defined in the `defaultProps` of the .react.js file, they are not accessible through `dash.dependencies.Input` or `dash.dependencies.State`
```
COMPONENT.propTypes = {
givenProp: PropTypes.shape({
subprop1: PropTypes.string,
subprop2: PropTypes.int,
})
... | closed | 2019-02-14T22:59:42Z | 2021-05-04T20:27:46Z | https://github.com/plotly/dash-bio/issues/174 | [
"bug",
"higher scope"
] | Bachibouzouk | 2 |
dpgaspar/Flask-AppBuilder | flask | 1,808 | Question - Is there anyway that we can dynamic add view | Just a general question,
Is there any way that we can dynamic add view ?
For example, I have a model "Department", and I want to have two separate tab in dropdown menu like :

100 (dfs_pred[DEFAULT_USER_COL] == train[DEFAULT_USER_COL])
101 & (dfs_pred[DEFAULT_ITEM_COL] == tra... | closed | 2021-10-29T14:54:08Z | 2021-11-02T17:49:19Z | https://github.com/recommenders-team/recommenders/issues/1560 | [
"bug"
] | xlsrln | 3 |
uriyyo/fastapi-pagination | fastapi | 555 | Getting error when using sqlalchemy2.0 style | `paginate(session.execute(select(Model)).all())` returns TypeError: list.count() takes exactly one argument (0 given)
| closed | 2023-03-02T14:14:39Z | 2023-03-03T03:11:57Z | https://github.com/uriyyo/fastapi-pagination/issues/555 | [] | jenn0pal | 4 |
RomelTorres/alpha_vantage | pandas | 247 | Current price is not being shown. | I wrote the following code.
```
from alpha_vantage.timeseries import TimeSeries
import pandas as pd
api_key='******************'
ts = TimeSeries(key=api_key, output_format = 'pandas')
data, meta_data = ts.get_intraday(symbol = 'MSFT',interval = '1min', outputsize = 'full')
print(data)
```
But the latest price ... | closed | 2020-07-21T19:23:10Z | 2020-07-21T19:41:46Z | https://github.com/RomelTorres/alpha_vantage/issues/247 | [] | samar-080301 | 1 |
cvat-ai/cvat | tensorflow | 8,829 | No idea how to add another label to the same task? | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce

### Expected Behavior
I shoul... | closed | 2024-12-15T20:35:03Z | 2024-12-16T07:32:21Z | https://github.com/cvat-ai/cvat/issues/8829 | [
"question"
] | AntDX316 | 1 |
pennersr/django-allauth | django | 3,675 | Microsoft logins vulnerable to account takeovers via CVE-2023-36871 | In our app we discovered that arbitrary accounts could be taken over via Microsoft social login due to [CVE-2023-36871](https://msrc.microsoft.com/update-guide/vulnerability/CVE-2023-36871). Essentially, the `mail` attribute is not verified and can be changed to [arbitrary values in the Azure portal](https://www.crowds... | closed | 2024-03-06T22:35:23Z | 2024-11-18T16:33:23Z | https://github.com/pennersr/django-allauth/issues/3675 | [
"Unconfirmed",
"Awaiting input"
] | mziv | 2 |
waditu/tushare | pandas | 1,262 | ts.pro_bar接口中均价与均量数据提取异常 | ts.pro_bar接口中均价与均量数据提取异常,‘20180316’之前MA50为空,‘20180126’之前MA20为空,MA是基于提取数据计算的,导致如果要提取一天的数据,为了保证可以读取MA50,时间跨度要选到这一日之前的50个交易日。严重消耗访问量
df = ts.pro_bar(ts_code='000001.SZ', adj='qfq', start_date='20180101', end_date='20181111',ma=[10,20,50,])
id:ChrisLau
email:tongxia19950413@163.com | closed | 2020-01-18T11:17:38Z | 2020-01-20T02:42:53Z | https://github.com/waditu/tushare/issues/1262 | [] | qinshang0925 | 1 |
sebastianruder/NLP-progress | machine-learning | 197 | Conll-2003 uncomparable results | Because of the small size the training set of Conll-2003, some authors incorporated the development set as a part of training data after tuning the hyper-parameters. Consequently, not all results are directly comparable.
Train+dev:
-------------
Flair embeddings (Akbik et al., 2018)
Peters et al. (2017)
Yang et ... | closed | 2019-01-07T14:46:52Z | 2019-01-13T13:43:02Z | https://github.com/sebastianruder/NLP-progress/issues/197 | [] | ghaddarAbs | 28 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 3,899 | Permission denied error to /var/globaleaks/files in my Kubernetes Pod | ### What version of GlobaLeaks are you using?
4.13.22
### What browser(s) are you seeing the problem on?
_No response_
### What operating system(s) are you seeing the problem on?
Linux
### Describe the issue
I have containerized Globaleaks to be used in Kubernetes and was able to get the pod to successfully run ... | closed | 2023-12-18T19:37:39Z | 2024-01-08T10:16:07Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/3899 | [
"T: Bug",
"Triage"
] | Andrew-Moy | 6 |
unit8co/darts | data-science | 1,841 | Target aggregated features for historical_forecast | **Is your feature request related to a current problem? Please describe.**
I am using target aggregated window features (mean,sum,slope...) as past covariates for training/predicting Xgboost model in Darts with historical_forecasts method. To use this type of features i would need to recalculate them after each iterat... | closed | 2023-06-20T10:56:14Z | 2023-06-20T12:19:15Z | https://github.com/unit8co/darts/issues/1841 | [
"triage"
] | wojnarabc | 1 |
google-research/bert | nlp | 1,148 | Can RoBERTa be fine-tuned on unlabeled data? | Im new working with language models, need some help
Can i pre train RoBERTa with data set having just one column i-e sentences and no labels or anything? | open | 2020-09-16T06:39:13Z | 2020-09-16T06:39:13Z | https://github.com/google-research/bert/issues/1148 | [] | HamzaYounis | 0 |
nteract/papermill | jupyter | 269 | Support `allow_errors` flag from `nbconvert` | It looks like the `nbconvert` execute preprocessor supports an `allow_errors` flag that lets a notebook continue running whenever errors are encountered and instead just logs them: https://github.com/jupyter/nbconvert/blob/02c5cd1424b65da018f244e0f033a3dde55f76ca/nbconvert/preprocessors/execute.py#L121-L132
I certai... | closed | 2018-12-11T17:10:38Z | 2020-06-10T16:24:47Z | https://github.com/nteract/papermill/issues/269 | [] | bnaul | 7 |
getsentry/sentry | python | 87,163 | Starred Projects in Insights | 
another option how to do this is:
We will always attempt to show 5 projects in that sidebar.
If you have 2 starred projects, we will show 2 starred + 3 most used ones.
If you have 0 starred projects, we will show 5 most used one... | closed | 2025-03-17T10:44:28Z | 2025-03-17T13:46:32Z | https://github.com/getsentry/sentry/issues/87163 | [] | matejminar | 0 |
amisadmin/fastapi-amis-admin | sqlalchemy | 46 | 如何明确指定侧边栏菜单中各个项的顺序 | 目前感觉是按注册路由的顺序来算的,有办法明确指定吗? | closed | 2022-09-22T03:58:07Z | 2022-09-22T10:01:56Z | https://github.com/amisadmin/fastapi-amis-admin/issues/46 | [] | Chaoyingz | 2 |
pyjanitor-devs/pyjanitor | pandas | 475 | [ENH] Keeping a history of every operation applied to a DataFrame | A whacky idea dreamed up during the sprint.
This would essentially record for you your data processing pipeline (on the DataFrame bit at least). Metadata could go in a `.pj` accessor in the dataframe / series.
Fun challenges include:
* Detecting use of all Pandas functions, not just PyJanitor ones
* Minimizin... | closed | 2019-07-15T20:59:10Z | 2019-12-17T13:18:37Z | https://github.com/pyjanitor-devs/pyjanitor/issues/475 | [
"enhancement",
"good advanced issue"
] | zbarry | 8 |
pytest-dev/pytest-xdist | pytest | 335 | ImportError with --looponfail and "python -m pytest" if project is not installed | For some reason I am getting an ImportError for the project itself when using `--looponfail` with `python -m pytest`, and the project not being installed via `pip install -e .`.
The workaround is to either `pip install -e .` the project, or use `-o django_find_project=1`, which will massage `sys.path` based on the `... | open | 2018-08-28T12:41:24Z | 2018-08-29T15:36:23Z | https://github.com/pytest-dev/pytest-xdist/issues/335 | [
"bug"
] | blueyed | 1 |
SYSTRAN/faster-whisper | deep-learning | 1,011 | [bug] distil-small conversion results in junk! | Running `distil-small.en` works. However, when converting HF weights (directly copied from my HF cache) with
```bash
ct2-transformers-converter --model "$CHECKPOINT_DIR" --output_dir faster-whisper-test --copy_files tokenizer.json preprocessor_config.json --quantization float16
```
and infer (same code with which i... | closed | 2024-09-15T13:18:46Z | 2024-09-15T13:37:05Z | https://github.com/SYSTRAN/faster-whisper/issues/1011 | [] | SinanAkkoyun | 1 |
geopandas/geopandas | pandas | 3,528 | BUG: Unable to intercept SQLalchemy event when gpd do COPY | - [X] I have checked that this issue has not already been reported.
- [X] I have confirmed this bug exists on the latest version of geopandas.
- [ ] (optional) I have confirmed this bug exists on the main branch of geopandas.
---
#### Code Sample, a copy-pastable example
```python
import pandas as pd
import geopan... | closed | 2025-03-13T20:48:55Z | 2025-03-14T11:14:04Z | https://github.com/geopandas/geopandas/issues/3528 | [
"needs info"
] | naub1n | 2 |
comfyanonymous/ComfyUI | pytorch | 7,295 | Use without ui | ### Your question
Hi, I have my workflow and the corresponding models, I can run it and generate images using the ui. But I have thousands of prompts and I don’t want to input them one by one by myself. So I wonder if there any method to automatically input them or if I can run my workflow without using ui, so that I ... | closed | 2025-03-18T09:04:28Z | 2025-03-18T09:12:12Z | https://github.com/comfyanonymous/ComfyUI/issues/7295 | [
"User Support"
] | QiqLiang | 2 |
ultralytics/ultralytics | pytorch | 19,419 | Small classes data surprisingly, has highest mAP. | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
When im finetuning yolov11n with my custom dataset with custom classes. Alum... | closed | 2025-02-25T12:49:54Z | 2025-02-25T19:38:33Z | https://github.com/ultralytics/ultralytics/issues/19419 | [
"question",
"detect"
] | nisrinaam29 | 4 |
Esri/arcgis-python-api | jupyter | 1,839 | update function for webmap doesn't work (but no error is given) | **Describe the bug**
I am trying to update a webmap (webmap2) with the all the content,symbology etc from another webmap (webmap1).
When I use the update function with the definition of webmap1, True is returned, while webmap2 isn't changed at all
**To Reproduce**
 or `ckanext/datatablesview/public/vendor/DataTables/i18n/` (2.10), the file names of Chinese locales should be `zh_Hant_TW.json` and `zh_Hans_CN.json` (rather than `zh_Han... | closed | 2024-09-10T07:20:56Z | 2024-09-17T15:15:05Z | https://github.com/ckan/ckan/issues/8424 | [
"Good for Contribution"
] | u10313335 | 4 |
biolab/orange3 | numpy | 6,999 | Crash on "Show help" and "Create report" | <!--
Thanks for taking the time to report a bug!
If you're raising an issue about an add-on (i.e., installed via Options > Add-ons), raise an issue in the relevant add-on's issue tracker instead. See: https://github.com/biolab?q=orange3
To fix the bug, we need to be able to reproduce it. Please answer the following qu... | closed | 2025-01-20T22:25:37Z | 2025-01-24T08:20:06Z | https://github.com/biolab/orange3/issues/6999 | [
"bug report"
] | GuidoBartoli | 5 |
huggingface/datasets | numpy | 6,533 | ted_talks_iwslt | Error: Config name is missing | ### Describe the bug
Running load_dataset using the newest `datasets` library like below on the ted_talks_iwslt using year pair data will throw an error "Config name is missing"
see also:
https://huggingface.co/datasets/ted_talks_iwslt/discussions/3
likely caused by #6493, where the `and not config_kwargs` part... | closed | 2023-12-26T00:38:18Z | 2023-12-30T18:58:21Z | https://github.com/huggingface/datasets/issues/6533 | [] | rayliuca | 2 |
ultralytics/yolov5 | pytorch | 12,969 | Is it possible to add ShuffleNetV2 as backbone in the official repo? | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
According to the information I found, ShuffleNetV2 has achieved a good balance in ... | closed | 2024-04-28T02:57:21Z | 2024-10-20T19:44:59Z | https://github.com/ultralytics/yolov5/issues/12969 | [
"question",
"Stale"
] | superbayes | 3 |
gee-community/geemap | streamlit | 1,340 | ee.Date.advance() get error. | <!-- Please search existing issues to avoid creating duplicates. -->
### Environment Information

### Description
I want to use `ee.Date().advance()` to add time step by step. But I got a false resu... | closed | 2022-11-21T14:19:18Z | 2022-11-21T14:21:22Z | https://github.com/gee-community/geemap/issues/1340 | [
"bug"
] | flying318 | 1 |
roboflow/supervision | machine-learning | 1,181 | Request: as_coco Parameter Adjustment for sv.DetectionDataset in Supervision API | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Description
I am currently utilizing the `as_coco` function from **_sv.DetectionDataset_** within the Supervision API extensively and find it incredibly ... | open | 2024-05-09T04:53:51Z | 2024-05-14T11:00:28Z | https://github.com/roboflow/supervision/issues/1181 | [
"enhancement"
] | YoungjaeDev | 7 |
mlflow/mlflow | machine-learning | 14,214 | [FR] Support AMD GPU system metrics | ### Willingness to contribute
Yes. I would be willing to contribute this feature with guidance from the MLflow community.
### Proposal Summary
Current GPUMonitor relies on pynvml, which only supports Nvidia GPUs. Adding AMD GPU support would be a helpful plus
### Motivation
> #### What is the use case for this fea... | open | 2025-01-09T03:43:50Z | 2025-02-24T02:54:15Z | https://github.com/mlflow/mlflow/issues/14214 | [
"enhancement",
"help wanted"
] | kaixin96 | 3 |
mwaskom/seaborn | data-science | 2,746 | `histplot` is showing wrong counts. | I'm working with a dataset, and when I try to use `sns.histplot` the results are demonstrably wrong.
[issue.csv](https://github.com/mwaskom/seaborn/files/8110666/issue.csv)
```python
data = pd.read_csv("issue.csv", index_col=0, dtype={"collection_name": "category"})
plt.figure(figsize=(12, 10))
sns.histplo... | closed | 2022-02-21T16:11:20Z | 2022-03-04T11:51:46Z | https://github.com/mwaskom/seaborn/issues/2746 | [
"question"
] | matteosantama | 4 |
liangliangyy/DjangoBlog | django | 736 | comments.admin中管理后台评论管理模型中点击文章显示已被删除或不存在问题 | <!--
如果你不认真勾选下面的内容,我可能会直接关闭你的 Issue。
提问之前,建议先阅读 https://github.com/ruby-china/How-To-Ask-Questions-The-Smart-Way
-->
**我确定我已经查看了** (标注`[ ]`为`[x]`)
- [x] [DjangoBlog的readme](https://github.com/liangliangyy/DjangoBlog/blob/master/README.md)
- [x] [配置说明](https://github.com/liangliangyy/DjangoBlog/blob/master/bin... | open | 2024-07-19T13:10:42Z | 2025-01-08T12:04:03Z | https://github.com/liangliangyy/DjangoBlog/issues/736 | [] | JOYCAT-Q | 1 |
krish-adi/barfi | streamlit | 16 | Need more documentation! | Hey @krish-adi ,
The package was really helpful,
I think it will be help full to add more details on classes
- Blocks
- Computation engine
and also about functions and its parameters
I had hard time finding it from code
| open | 2023-04-07T05:38:15Z | 2025-01-15T23:23:29Z | https://github.com/krish-adi/barfi/issues/16 | [
"help wanted"
] | skycreeds | 9 |
aeon-toolkit/aeon | scikit-learn | 2,179 | [BUG] freeze on import of aeon.classification.convolution_based | ### Describe the bug
Hi,
when doing
```python
from aeon.classification.convolution_based import Arsenal
```
it takes forever.
- It was working a few days back. In fact in the old venv it still works. (**Edit:** might be that the 1st loading always takes long. [Not quite sure how long it should take...]... | open | 2024-10-11T11:33:33Z | 2024-10-16T09:59:01Z | https://github.com/aeon-toolkit/aeon/issues/2179 | [
"bug",
"classification"
] | user706 | 11 |
FactoryBoy/factory_boy | django | 963 | Extend `SelfAttribute` with some `callback` kwarg, for convenience | #### The problem
Quite a lot of times I'd like to refine a value that can be accessed with a `SelfAttribute`. This can normally be done by combining it with a `LazyAttribute` and 1 or 2 param variables, but it'd be quite convenient if that was a shortcut so one didn't have to write that out explicitly every time. And ... | closed | 2022-07-14T11:16:03Z | 2022-09-17T15:45:11Z | https://github.com/FactoryBoy/factory_boy/issues/963 | [] | flaeppe | 7 |
jmcnamara/XlsxWriter | pandas | 183 | Error in install via tarball process | i used:
```
tar -zxvf XlsxWriter-0.6.3.tar.gz
cd XlsxWriter-0.6.3
sudo python setup.py install
```
and this is what was displayed
```
running install
...
copying xlsxwriter/chartsheet.py -> build/lib/xlsxwriter
running build_scripts
creating build/scripts-2.4
copying and adjusting examples/vba_extract.py -> build/... | closed | 2014-11-13T16:56:46Z | 2014-11-17T20:57:55Z | https://github.com/jmcnamara/XlsxWriter/issues/183 | [
"question",
"ready to close"
] | david-teasdale | 7 |
JaidedAI/EasyOCR | deep-learning | 496 | Dataset recommendation for written words long or short numbers | Does anyone know of an existing dataset (or datasets) that include written words, long numbers (ex. 489211) and digits? I've searched for a few days but haven't found anything. | closed | 2021-07-27T20:40:05Z | 2022-03-02T09:25:04Z | https://github.com/JaidedAI/EasyOCR/issues/496 | [] | ctcheune | 0 |
serengil/deepface | deep-learning | 451 | How to adjust thresholds for find and verify | I've ran the script to generate the 'rules' and new value of the threshold as the tutorial on fine tuning explained but still running any other verification or find command still marks the distance threshold as 0.4.
I'd like to know if there is any way to change it directly rather than having to add a check to compa... | closed | 2022-04-05T19:41:22Z | 2022-04-08T11:04:36Z | https://github.com/serengil/deepface/issues/451 | [
"question"
] | Henrix-Andre | 1 |
neuml/txtai | nlp | 168 | Store text content | Currently, txtai only supports loading text into approximate nearest neighbor indices. This method will store an id and a vector field. It is assumed that data is externally stored and the id returned by txtai would then be used to resolve records with this other store.
This change will add a new option. While the ... | closed | 2021-12-14T00:17:14Z | 2021-12-14T03:08:04Z | https://github.com/neuml/txtai/issues/168 | [] | davidmezzetti | 0 |
521xueweihan/HelloGitHub | python | 2,736 | 【开源自荐】: Light-Flow - 一个免编排的任务编排框架 | 仓库地址:[https://github.com/Bilibotter/light-flow](https://github.com/Bilibotter/light-flow)
中文文档:[https://github.com/Bilibotter/light-flow/blob/master/README.cn.md](https://github.com/Bilibotter/light-flow/blob/master/README.cn.md)
# 特性亮点
- **免编排**:不需使用规则语言,只需关注任务执行时机,让任务编排变得简单直观。
- **独特上下文机制**:既实现了关联任务之间的上下文连通,也... | closed | 2024-04-22T15:21:44Z | 2024-04-24T11:56:11Z | https://github.com/521xueweihan/HelloGitHub/issues/2736 | [] | Bilibotter | 0 |
MaartenGr/BERTopic | nlp | 2,026 | Identical topics: some become outliers, some are assigned to their topic | I'm using using BERTopic 0.16.2 and I'm trying to understand why about a third of my documents are categorized as outliers. `len(docs)` is 7578 and the number of documents in my largest topics are
```
0 -1 2454
1 0 207
2 1 203
3 2 1... | open | 2024-06-01T11:16:27Z | 2024-06-03T07:20:14Z | https://github.com/MaartenGr/BERTopic/issues/2026 | [] | tophee | 1 |
matplotlib/mplfinance | matplotlib | 484 | Potential for 'labeling' candlesticks on a candlestick chart | I'm looking to label the candlesticks but have been unable to find a way to do so. You can see an example below where they're labeled as 1s and 2s.

Is there any possible way to create this type of outco... | closed | 2021-12-24T15:17:10Z | 2021-12-24T18:52:27Z | https://github.com/matplotlib/mplfinance/issues/484 | [
"question"
] | AlexSopa | 1 |
HumanSignal/labelImg | deep-learning | 700 | (tensorflow) C:\Users\Anurag sharma\Desktop\project\subclass_classifier\labelImg>pyrcc5 -o resources.py resources.qrc 'C:/Users/Anurag' is not recognized as an internal or external command, operable program or batch file. | <!--
Can anybody suggest a workaround for this? -->
- **OS:** Windows 10
- **PyQt version:** 5
| open | 2021-02-03T17:45:07Z | 2021-05-02T11:52:58Z | https://github.com/HumanSignal/labelImg/issues/700 | [] | anurag0308 | 2 |
httpie/cli | api | 1,423 | version 3.2.1 is not real single-binary | ## Checklist
- [x] I've searched for similar issues.
- [x] I'm using the latest version of HTTPie.
---
## Minimal reproduction code and steps
1. download httpie 3.2.1 (latest httpie version) to centos7 machine
2. run "./http"
## Current result
```
Error loading Python lib '/tmp/_MEITUP865/libpython3.... | open | 2022-07-21T05:38:28Z | 2022-08-07T00:08:10Z | https://github.com/httpie/cli/issues/1423 | [
"bug",
"new"
] | wgqimut | 1 |
Significant-Gravitas/AutoGPT | python | 8,910 | Integration with AI/ML API | ### Duplicates
- [X] I have searched the existing issues
### Summary 💡
Receiving and sending requests to our API
### Examples 🌈
https://aimlapi.com/
### Motivation 🔦
Hi!
I am a Python developer working at AI/ML API.
We want to give your users the opportunity to use our models, such as Qwen/Qwen2.5-72B-Instr... | open | 2024-12-09T09:41:33Z | 2025-03-21T02:04:45Z | https://github.com/Significant-Gravitas/AutoGPT/issues/8910 | [
"Stale"
] | waterstark | 3 |
holoviz/panel | matplotlib | 6,888 | VS Code + notebook setup, Panel + Param, no reactivity when using `pn.template` | #### Versions
bokeh==3.4.1
ipykernel==6.29.4
jupyter-bokeh==4.0.4
panel==1.4.4
param==2.1.0
#### Expected and observed behavior
```python
import panel as pn
import param
pn.extension()
text = pn.widgets.TextInput()
@param.depends(text.param.value, watch=True)
def _update(value):
print(valu... | open | 2024-06-02T11:45:58Z | 2024-06-27T09:48:47Z | https://github.com/holoviz/panel/issues/6888 | [] | earshinov | 1 |
pywinauto/pywinauto | automation | 1,143 | Menu and Dialog Box Difficulties | <removed> | closed | 2021-11-04T11:03:52Z | 2021-11-18T04:11:26Z | https://github.com/pywinauto/pywinauto/issues/1143 | [
"question"
] | challengemkr20 | 1 |
deeppavlov/DeepPavlov | tensorflow | 1,355 | TypeError: rsub() received an invalid combination of arguments - got (Tensor, str), but expected one of: | Want to contribute to DeepPavlov? Please read the [contributing guideline](http://docs.deeppavlov.ai/en/master/devguides/contribution_guide.html) first.
Please enter all the information below, otherwise your issue may be closed without a warning.
**DeepPavlov version** (you can look it up by running `pip show ... | closed | 2020-12-02T21:41:11Z | 2020-12-10T08:23:47Z | https://github.com/deeppavlov/DeepPavlov/issues/1355 | [
"bug"
] | vcjob | 2 |
sgl-project/sglang | pytorch | 4,425 | [Bug] 0.4.4post1 Currently Flashinfer MLA only supports topk=1 for speculative decoding | ### Checklist
- [x] 1. I have searched related issues but cannot get the expected help.
- [x] 2. The bug has not been fixed in the latest version.
- [x] 3. Please note that if the bug-related issue you submitted lacks corresponding environment info and a minimal reproducible demo, it will be challenging for us to repr... | closed | 2025-03-14T10:47:58Z | 2025-03-14T17:57:12Z | https://github.com/sgl-project/sglang/issues/4425 | [] | whybeyoung | 1 |
aiortc/aiortc | asyncio | 361 | possible memory leak with janus example and Alsa MediaRecorder | Hi there, first: thanks for the great project, its really cool :)
I am using the janus.py example as a starting point for a projet, and am noting a very fast accumulation of memory as soon as I add a 'live' MediaRecorder.
It seems easy to reproduce, around line [241](https://github.com/aiortc/aiortc/blob/master/e... | closed | 2020-05-13T22:37:36Z | 2021-02-15T16:28:59Z | https://github.com/aiortc/aiortc/issues/361 | [] | carltondraught | 4 |
joerick/pyinstrument | django | 137 | Error with Pyinstrument 4.0.0: RuntimeError: Could not find app.js. If you are running pyinstrument from a git checkout, run 'python setup.py build' to compile the Javascript (requires nodejs). | Python Version: 3.7.10
OS: Ubuntu 18.04.5
Steps to reproduce:
```
pip install pyinstrument==4.0.0
python test.py
```
where `test.py` is:
```
import time
from pyinstrument import Profiler
profiler = Profiler()
profiler.start()
time.sleep(1)
profiler.stop()
profiler.output_html()
```
... | closed | 2021-07-27T07:14:53Z | 2021-08-06T07:55:07Z | https://github.com/joerick/pyinstrument/issues/137 | [] | ndodda-amazon | 5 |
wandb/wandb | data-science | 8,700 | [Bug-App]: Relative Time on X-axis Not Showing Meaningful Units | ### Describe the bug
When I use "Relative Time (Wall)" or "Relative Time (Process)", it gives me no units (is about 40k for 12 hours, so probably in seconds). It used to show it in minutes or hours dynamically. This makes it very hard to understand the time axis and not nice to share updates with my labmates.
Current... | open | 2024-10-23T23:04:30Z | 2025-01-14T14:26:54Z | https://github.com/wandb/wandb/issues/8700 | [
"ty:bug",
"a:app"
] | tylerlum | 18 |
microsoft/nni | pytorch | 4,779 | Google Colab WebUI NAS | **Describe the issue**:
I found the documentation for running the WebUI in google colab: https://nni.readthedocs.io/en/v2.7/sharings/nni_colab_support.html?highlight=colab
Is it possible to get the WebUI in google colab running nas with exp (exp_config & exp.run)?
I followed the documentation until I run into an i... | closed | 2022-04-19T15:01:31Z | 2022-05-03T01:17:15Z | https://github.com/microsoft/nni/issues/4779 | [] | NotSure2732 | 7 |
ageitgey/face_recognition | python | 688 | batch_face_locations performance using GPU with large datasets | ### System properties
* Memory: 32 GB
* CPU: Intel(R) Xeon(R) W-2123 CPU @ 3.60GHz
* OS: Ubuntu 16.04.5 LTS 64-Bit
* GPU: GTX1080 Ti 11 GB
* NVIDIA-SMI 410.48
* Driver Version: 410.48
* Dlib Version: 19.15.0
* Face Recognition Version: 1.2.3
* Photo size: 240x320
### Description
I have bunch of photo... | open | 2018-11-26T11:42:59Z | 2018-12-02T03:36:08Z | https://github.com/ageitgey/face_recognition/issues/688 | [] | fottofatto | 3 |
Lightning-AI/pytorch-lightning | pytorch | 19,616 | Can't use `self.log` as an instance variable in a Callback | ### Bug description
The log attribute of the callback seems to be replaced at some point.
Not sure if this is expected (to me it's weird).
Below is the simplest code to reproduce this behavior.
### What version are you seeing the problem on?
v2.1, v2.2
### How to reproduce the bug
```python
class MyCallBack(Ca... | closed | 2024-03-12T09:13:39Z | 2024-03-14T01:12:43Z | https://github.com/Lightning-AI/pytorch-lightning/issues/19616 | [
"bug",
"callback",
"logging",
"ver: 2.1.x"
] | blackwint3r | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.