
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
Evil0ctal/Douyin_TikTok_Download_API | api | 518 | [BUG] ERROR: ACCESS DENIED | ***Platform where the error occurred?***: Douyin
***The endpoint where the error occurred?***: (WEB) /api/hybrid/video_data?url=
***Submitted input value?***: (any videos or example url video) or https://www.douyin.com/user/MS4wLjABAAAAcMI81XJI-7nHmdmRrdGGe24GTJQe5XbIAPzIrNWfvwpc2r2tNmRwlPOd-lak3c5D?from_tab_name... | closed | 2024-12-08T16:06:01Z | 2024-12-08T16:13:07Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/518 | [
"BUG",
"enhancement"
] | dokimkhanh | 1 |
RasaHQ/rasa | machine-learning | 13,103 | What does RASA mean? | In one of my lectures, the professor showed this RASA framework, when I asked about what the name meant, the Professor said that there is no information about it on the website. I also searched for it but to no avail.
Does anyone know what RASA means or the origin of RASA? | open | 2025-03-02T05:09:43Z | 2025-03-02T05:09:43Z | https://github.com/RasaHQ/rasa/issues/13103 | [] | imbdb | 0 |
man-group/arctic | pandas | 707 | arctic import error with Pandas 0.24 | #### Arctic Version
```
1.73.0
```
#### Arctic Store
```
# VersionStore, TickStore, or ChunkStore
```
#### Platform and version
macOS Mojave 10.14.2, py 3.7.2
#### Description of problem and/or code sample that reproduces the issue
getting the following traceback with `pandas 0.24` while all wo... | closed | 2019-02-01T01:13:34Z | 2019-02-02T22:05:06Z | https://github.com/man-group/arctic/issues/707 | [] | stnatter | 2 |
httpie/cli | python | 611 | Set non-zero return code on error | This would be very convenient way to fail fast scripts that run with `-e`
This would be like `curl --fail` only without swallowing the output.
It looks that now the return code is always 0.
```
$ http -v PUT invalid://httpbin.org/put API-Key:foo hello=world
http: error: InvalidSchema: No connection adapter... | closed | 2017-09-20T13:02:43Z | 2017-09-20T13:28:00Z | https://github.com/httpie/cli/issues/611 | [] | jakub-bochenski | 2 |
LAION-AI/Open-Assistant | python | 3,544 | Hardware requirement for SFT for LLaMa 65B | What's the hardware requirement for full parameter fine-tuning for LLaMa 65B? | closed | 2023-07-05T07:30:30Z | 2023-07-11T17:20:42Z | https://github.com/LAION-AI/Open-Assistant/issues/3544 | [
"question"
] | dittops | 2 |
microsoft/MMdnn | tensorflow | 727 | mmdnn.conversion.caffe.errors.ConversionError: No handler found for node kind: Power (expected: map_power) | I am trying to convert a caffe model to tensorflow, and encounter the following errors:
mmdnn.conversion.caffe.errors.ConversionError: No handler found for node kind: Power (expected: map_power)
Can someone here help me ?thank you.
| open | 2019-08-30T01:09:18Z | 2019-09-09T03:00:17Z | https://github.com/microsoft/MMdnn/issues/727 | [] | xianfengju | 1 |
opengeos/leafmap | plotly | 145 | 21_ts_inspector not rendering sat image in split map mode | Ran the notebook # ts inspector on binder.
Entered a planet API but the split map is not showing satellite imagery.
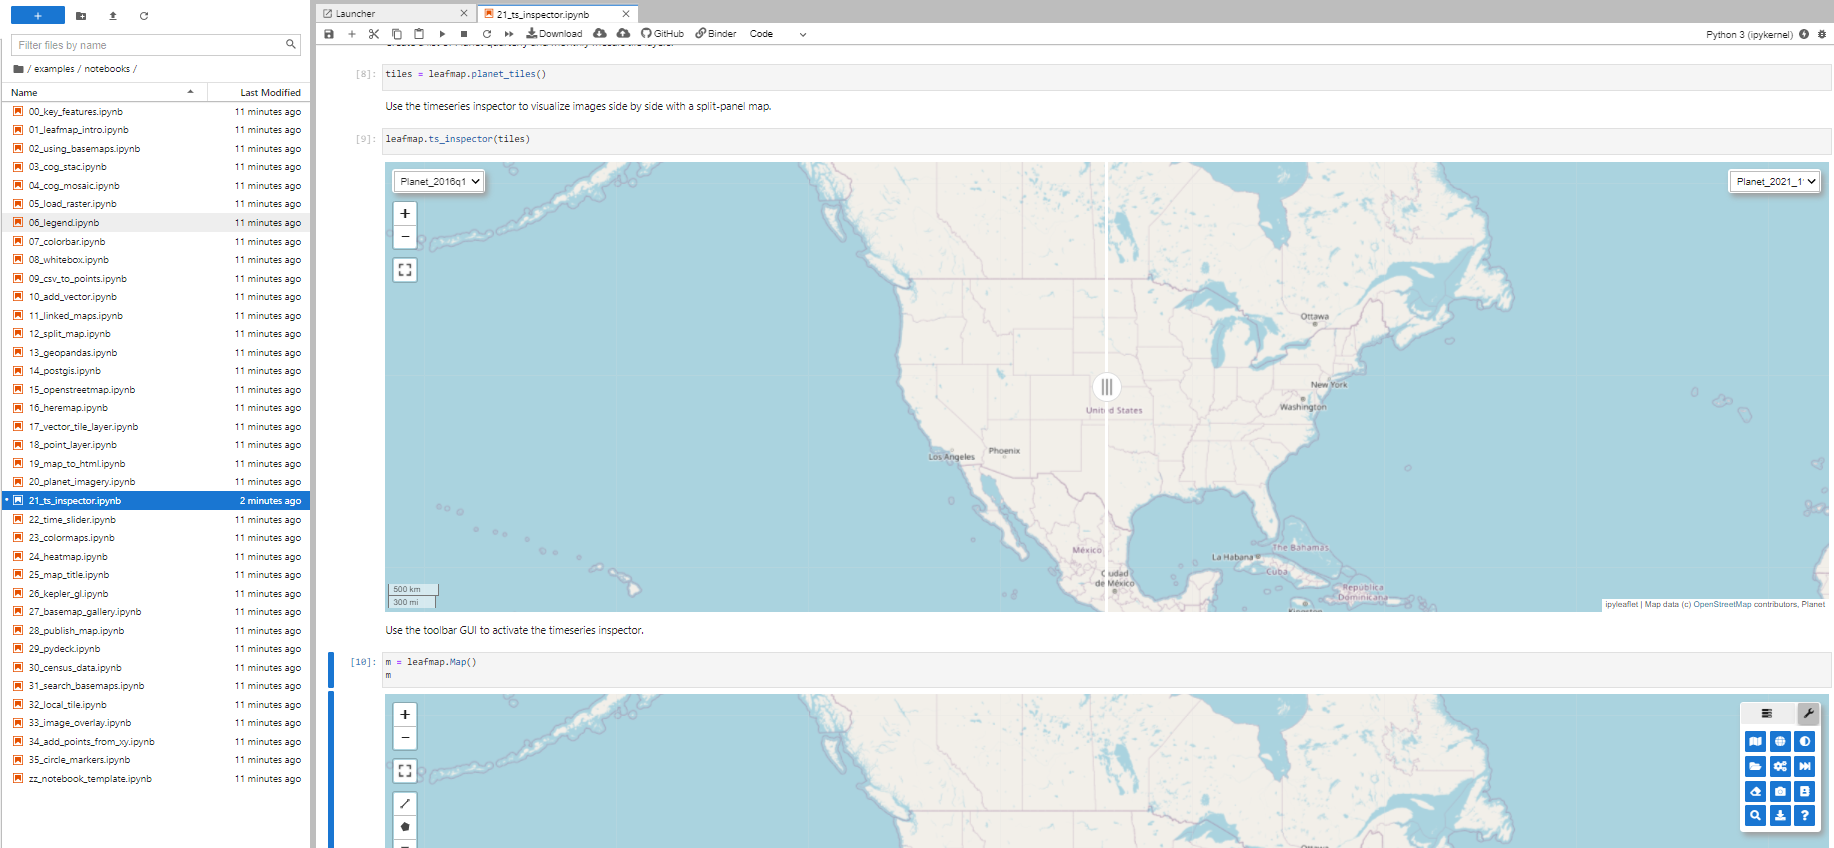
| closed | 2021-12-18T02:48:52Z | 2021-12-18T03:47:15Z | https://github.com/opengeos/leafmap/issues/145 | [
"bug"
] | Niko-La | 5 |
capitalone/DataProfiler | pandas | 455 | CVE-2021-33430 (High) detected in numpy-1.19.0-cp37-cp37m-manylinux2010_x86_64.whl - autoclosed | ## CVE-2021-33430 - High Severity Vulnerability
<details><summary><img src='https://whitesource-resources.whitesourcesoftware.com/vulnerability_details.png' width=19 height=20> Vulnerable Library - <b>numpy-1.19.0-cp37-cp37m-manylinux2010_x86_64.whl</b></p></summary>
<p>NumPy is the fundamental package for array compu... | closed | 2022-04-07T13:18:31Z | 2022-05-13T15:45:38Z | https://github.com/capitalone/DataProfiler/issues/455 | [
"Mend: dependency security vulnerability"
] | mend-for-github-com[bot] | 1 |
laughingman7743/PyAthena | sqlalchemy | 476 | pyathena hijacks pandas s3fs | Using pyathena's results-to-pandas conversion feature breaks pandas `to_csv` function.
Minimum reproducible example:
```python
>>> from pyathena.pandas.util import as_pandas
>>> import pandas as pd
>>> df = pd.DataFrame({"foo": [1,2,3]})
>>> df.to_csv("s3://...")
Traceback (most recent call last):
File "/... | closed | 2023-10-09T15:16:39Z | 2023-10-09T15:25:51Z | https://github.com/laughingman7743/PyAthena/issues/476 | [] | graydenshand | 2 |
rgerum/pylustrator | matplotlib | 57 | `linestyle` should also accept tuples an not just strings | Tuples could also be used to create custom linestyles.
Example: https://matplotlib.org/stable/gallery/lines_bars_and_markers/linestyles.html
Currently linestyle is a `TextWidget`. But since tuples are passed as tuples and not as text, this is incompatible.
I don't yet have an idea of a good modular way to impleme... | closed | 2023-01-25T10:40:27Z | 2023-02-28T20:50:29Z | https://github.com/rgerum/pylustrator/issues/57 | [] | JoostScheffer | 1 |
graphistry/pygraphistry | jupyter | 574 | [BUG] feature_utils unit tests failing mypy | **Describe the bug**
Regular PR fails on mypy analysis of feature_utils: https://github.com/graphistry/pygraphistry/actions/runs/9800176651/job/27061697437?pr=573
**PyGraphistry API client environment**
- Where run: GHA CI
- Version: 0.33.8 (main)
**Additional context**
```
+ mypy --config-file mypy.... | open | 2024-07-04T22:14:12Z | 2024-07-05T15:30:13Z | https://github.com/graphistry/pygraphistry/issues/574 | [
"bug",
"help wanted",
"p3",
"good-first-issue",
"infra"
] | lmeyerov | 1 |
pyjanitor-devs/pyjanitor | pandas | 1,412 | add `change_index_dtype` to documentation | `change_index_dtype` is missing from the pyjanitor docs | closed | 2024-10-02T10:44:18Z | 2024-10-27T18:28:15Z | https://github.com/pyjanitor-devs/pyjanitor/issues/1412 | [] | samukweku | 0 |
vitalik/django-ninja | pydantic | 340 | ModelSchema: related objects | Hi, is there support for related objects in `ModelSchema`?
With the following Django model:
```python
class Example(Model):
hash =models.CharField(max_length=255)
version = models.ForeignKey('core.Version', on_delete=models.CASCADE, null=True, db_index=False)
```
I have a version object:
```
In... | open | 2022-01-27T21:10:26Z | 2025-03-08T09:41:35Z | https://github.com/vitalik/django-ninja/issues/340 | [] | pedro-prose | 3 |
ageitgey/face_recognition | python | 1,160 | Slow first calls to face_encodings() | * face_recognition version:
```
>>> face_recognition.__version__
'1.2.3'
```
* Python version:
```
$ python3 --version
Python 3.6.9
```
* Operating System:
```
$ lsb_release -a
No LSB modules are available.
Distributor ID: Ubuntu
Description: Ubuntu 18.04.4 LTS
Release: 18.04
Codename: ... | open | 2020-06-12T09:24:41Z | 2021-11-18T06:39:07Z | https://github.com/ageitgey/face_recognition/issues/1160 | [] | dalgibbard | 2 |
marcomusy/vedo | numpy | 817 | Make drilled mesh using two boundary points.. | I try to make drilled mesh.
i find boundary points in two separate stl files.
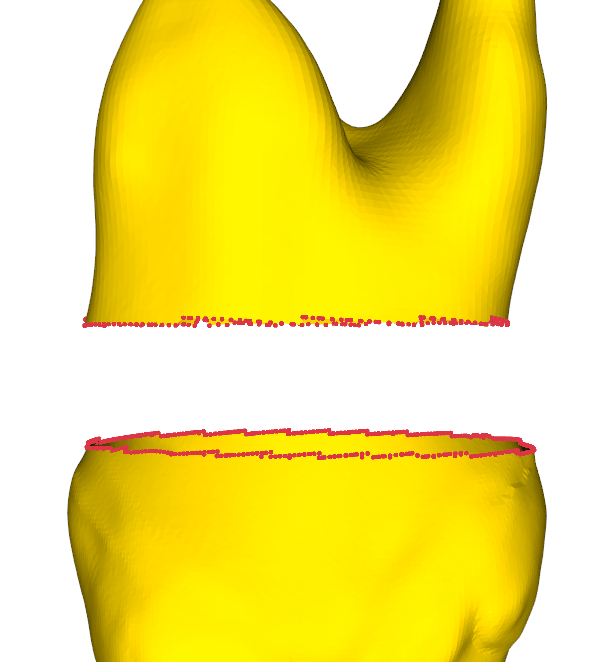
And i want to connect this separate stl files.
I used delaunay2d() and reconstruct_surface().
dealunay2d() is make like t... | closed | 2023-02-21T08:03:30Z | 2023-03-06T00:24:13Z | https://github.com/marcomusy/vedo/issues/817 | [] | HyungJoo-Kwon | 16 |
Lightning-AI/pytorch-lightning | pytorch | 20,453 | "FileNotFoundError: The provided path is not a valid DeepSpeed checkpoint" when using strategy='deepspeed_stage_2' | ### Bug description
I'm encountering the error "FileNotFoundError: The provided path is not a valid DeepSpeed checkpoint" while trying to resume training using PyTorch Lightning with strategy='deepspeed_stage_2'. My training script saves only a .ckpt file, but DeepSpeed seems to require additional files for restoring ... | open | 2024-11-26T16:40:05Z | 2024-11-26T16:40:20Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20453 | [
"bug",
"needs triage",
"ver: 2.4.x"
] | ShiweiWu98 | 0 |
home-assistant/core | asyncio | 140,714 | Button on the dashboard gets triggered when switching tabs in the Home Assistant mobile app for iOS | ### The problem
For quite some time, I've noticed instances where our garage door opens unexpectedly, and no one in the family knows who triggered it. After observing these occurrences, I discovered that sometimes, when switching between dashboard tabs, a button on the newly opened tab is activated without any user in... | open | 2025-03-16T11:27:15Z | 2025-03-16T11:28:58Z | https://github.com/home-assistant/core/issues/140714 | [] | mariusz-schimke | 0 |
inducer/pudb | pytest | 615 | New Release | **Is your feature request related to a problem? Please describe.**
After #612 we should make a new release.
WDYT
**Describe the solution you'd like**
I'd like to see a new release.
**Describe alternatives you've considered**
I have not considered any alternatives.
**Additional context**
https://... | closed | 2023-10-06T18:00:21Z | 2023-10-06T19:01:30Z | https://github.com/inducer/pudb/issues/615 | [
"enhancement"
] | jgarte | 1 |
lepture/authlib | django | 452 | Accept/Mark Skip SSL verification while fetching JWKs keys | **Is your feature request related to a problem? Please describe.**
We have Okta as IDP which is serving self signed certs. While making the GET and POST requests to OKTA for code and token exchange, verify=False works fine. While the call made to authorize_access_token requests for JWKs which has no way to skip SSL ... | open | 2022-04-11T23:31:31Z | 2025-02-21T08:57:07Z | https://github.com/lepture/authlib/issues/452 | [
"feature request",
"client"
] | gem-aman | 0 |
taverntesting/tavern | pytest | 476 | How to use nested list if the list name has a dot in its name | Hello I am trying to save body from my response, however my response contains a "dot" in its list variable name, in that case how do i traverse to my list.
Example: I am trying to do something like this in my test
```
response:
status_code: 200
save:
body:
self_link: v1.Project.se... | closed | 2019-11-14T00:48:56Z | 2019-11-20T14:52:53Z | https://github.com/taverntesting/tavern/issues/476 | [] | wizardOutlaw | 1 |
ymcui/Chinese-BERT-wwm | tensorflow | 42 | 关于模型input embedding | 原模型样例:input:[CLS] 我 爱 中 国 [SEP]
Token embedding:E([CLS]) E(我) E(爱) E(中) E(国) E([SEP])
+
Segment embedding:E(A) E(A) E(A) E(A) E(A) E(A)
+
Position embedding:E(0) E(1) E(2) E(3) E(4) E(5)
那现在的模型是没变,还是为:
input:[CLS] 我 爱 中国 [SEP]
Token embedding:E([CLS]) E(我) E(爱) E(中国) E([SEP])
+
Segment embedding:E(A) E(A) E(A... | closed | 2019-09-12T05:07:48Z | 2019-09-12T09:22:58Z | https://github.com/ymcui/Chinese-BERT-wwm/issues/42 | [] | liawa | 2 |
streamlit/streamlit | data-science | 10,776 | Be able to deselect an `st.radio` when `index=None` | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
Created as a feature request and not a bug because obviously that's not something you overlooked.
Both `st.s... | open | 2025-03-14T07:16:11Z | 2025-03-15T01:20:37Z | https://github.com/streamlit/streamlit/issues/10776 | [
"type:enhancement",
"feature:st.radio"
] | VERBOSE-01 | 2 |
jupyterlab/jupyter-ai | jupyter | 1,259 | Bug?: Can't copy response to clipboard | I'm still getting used to the chat window and working out the flow. Currently I rarely have a notebook open that I'm working on. I see the set of Cell action icons at the bottom, and I've tried the "Copy" icon however it never does anything for me (not sure if bug). I actually want to copy the information so I can j... | closed | 2025-02-23T01:06:41Z | 2025-03-06T01:27:23Z | https://github.com/jupyterlab/jupyter-ai/issues/1259 | [
"bug"
] | wkvolkman | 12 |
graphdeco-inria/gaussian-splatting | computer-vision | 754 | Missing pointclouds | I want to use TankandTemples dataset to run guassian.But when I use the viewer, I find points within a certain z are missing and the initial point clouds seems ok. I don't know how to fix the bug

 by clicking into the account menu (in the top right) and selecting 'Config variables'.
[View the update logs](https://app.dependabo... | closed | 2020-09-24T05:48:53Z | 2020-09-25T22:15:14Z | https://github.com/aio-libs/aiopg/issues/733 | [] | dependabot-preview[bot] | 0 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 686 | [BUG]: Fails to apply to jobs even after meeting suitability score | ### Describe the bug
It doesn't apply to any jobs even if I meet the minimum job suitable score. I even put the minimum score as 1 and it still says I don't meet it.
### Steps to reproduce

... | closed | 2024-10-30T19:56:24Z | 2024-11-01T19:42:25Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/686 | [
"bug"
] | hiashley | 2 |
microsoft/Bringing-Old-Photos-Back-to-Life | pytorch | 204 | Face_Enhancement model converting to onnx failure | Hello,
Thanks for the great work. I'm trying to convert this model into onnx, but have met a few issues.
The `mv` and `dot` operator used by PyTorch's `spectral_norm` was one of them. Following https://github.com/onnx/onnx/issues/3006#issuecomment-690303884 I coverted them to `matmul` in my own implementation of ... | open | 2021-11-20T15:31:58Z | 2022-05-20T02:58:05Z | https://github.com/microsoft/Bringing-Old-Photos-Back-to-Life/issues/204 | [] | cjenkins5614 | 7 |
opengeos/leafmap | jupyter | 989 | Did you drop leafmap.connect_postgis?? | ### Environment Information
- leafmap version: 0.40.1
- Python version: 3.12.3
- Operating System: Ubuntu 24.04.1
### Description
I did a fresh install of leafmap this morning and discovered that leafmap.connect_postgis is no longer working. Did you drop it?
I see that there is now common.read_postgis... | closed | 2024-11-19T08:24:57Z | 2024-11-20T02:39:14Z | https://github.com/opengeos/leafmap/issues/989 | [
"bug"
] | glemoine62 | 2 |
ClimbsRocks/auto_ml | scikit-learn | 152 | rethink how we handle compute_power | what are truly the most impactful things to be optimizing?
we should probably be checking feature_selection='KeepAll' earlier in the process, and probably not checking feature selection types as much (they're hella expensive).
maybe again look into randomizedsearchcv, and letting the user directly pass in number... | closed | 2016-12-16T01:42:52Z | 2017-03-12T01:19:32Z | https://github.com/ClimbsRocks/auto_ml/issues/152 | [] | ClimbsRocks | 1 |
youfou/wxpy | api | 243 | 无法添加公众号 | 当我尝试通过某个微信号或用户名添加公众号的时候返回error_code 1,还是我弄错了么
报错如下
```
In [8]: bot.add_mp(user = "youhuibangdan")
---------------------------------------------------------------------------
ResponseError Traceback (most recent call last)
<ipython-input-8-2539a44dfb8c> in <module>()
----> 1 bot.add_mp... | open | 2018-01-01T07:43:45Z | 2018-01-01T07:43:45Z | https://github.com/youfou/wxpy/issues/243 | [] | pcmid | 0 |
ageitgey/face_recognition | machine-learning | 1,223 | Add ability to reuse raw_face_landmarks | When calling `face_recognition.face_encodings()` and then `face_recognition.face_landmarks()`, the internal method `_raw_face_landmarks()` is being called twice.
It would be great to have a possibility to optionally provide the `raw_face_landmarks` as a parameter if we already have it, just like `face_locations`.
| open | 2020-10-02T10:36:22Z | 2020-10-02T10:36:38Z | https://github.com/ageitgey/face_recognition/issues/1223 | [] | TimoZikeli | 0 |
pyppeteer/pyppeteer | automation | 364 | Implement `page.setDefaultTimeout` | To set default timeout to page object, puppeteer has [`page.setDefaultTimeout`](https://github.com/puppeteer/puppeteer/pull/3854) and [`page.setDefaultNavigationTimeout`](https://github.com/puppeteer/puppeteer/pull/3969).
`page.setDefaultTimeout` affects:
- `page.waitFor(selectorOrFunctionOrTimeout[, options[, ..... | closed | 2022-03-10T07:04:24Z | 2022-11-02T20:40:12Z | https://github.com/pyppeteer/pyppeteer/issues/364 | [] | eggplants | 0 |
biolab/orange3 | data-visualization | 6,953 | Invisible labels in the nomogram in dark mode | In dark mode, labels in nomogram are not shown.
To reproduce, open Orange in dark mode, show a nomogram for some data. The background is white, axis and tick labels are visible, variable names are not. Even switching the dark mode off doesn't help.
If you close Orange, switch off dark mode, and open Orange again,... | closed | 2024-12-12T17:24:33Z | 2024-12-12T17:25:02Z | https://github.com/biolab/orange3/issues/6953 | [
"bug report"
] | janezd | 1 |
nalepae/pandarallel | pandas | 256 | Pandarallel very slow after loading huge dataframe | ## General
- **Operating System**: Ubuntu
- **Python version**: 3.11
- **Pandas version**: 2.0.3
- **Pandarallel version**: main branch
## Acknowledgement
- [x] My issue is **NOT** present when using `pandas` without alone (without `pandarallel`)
- [x] If I am on **Windows**, I read the [Troubleshooting p... | open | 2023-11-11T09:26:01Z | 2024-04-27T11:01:29Z | https://github.com/nalepae/pandarallel/issues/256 | [] | lpuglia | 2 |
flasgger/flasgger | api | 294 | [Bug] KeyError on schema properties with parse flag set and using `id`. | I was trying to validate querystring parameters but am getting this problem:
```
from flask import Flask, jsonify, request
from flasgger import Swagger, swag_from
app = Flask(__name__)
swagger = Swagger(app, parse=True)
swagger_spec = {
'parameters': [{
'name': 'palette',
'in': 'query... | open | 2019-04-11T19:59:22Z | 2019-04-11T20:00:56Z | https://github.com/flasgger/flasgger/issues/294 | [] | alexlatchford | 0 |
pandas-dev/pandas | python | 60,729 | BUG: Series.mask incorrectly replaces positions of pd.NA in the cond argument | ### Pandas version checks
- [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [x] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/dev/ge... | open | 2025-01-18T06:32:44Z | 2025-03-01T04:31:39Z | https://github.com/pandas-dev/pandas/issues/60729 | [
"Bug",
"Missing-data",
"NA - MaskedArrays",
"Arrow"
] | kartoria | 6 |
microsoft/nni | data-science | 5,320 | Hello NAS ModuleNotFoundError: No module named 'model' | Hi, I'm using the Hello Nas! tutorial to run my own experiments with a custom dataset and search space. My search space has a single parameter, which controls the conditional generation of the network. It is a network with multiple input branches, and the parameter controls after how many convolutional blocks the branc... | closed | 2023-01-19T16:18:14Z | 2023-01-26T15:27:58Z | https://github.com/microsoft/nni/issues/5320 | [] | JuliaWasala | 2 |
vllm-project/vllm | pytorch | 14,495 | [Feature]: num of LoRAs requested by the batch is larger than num lora slots | ### 🚀 The feature, motivation and pitch
In the below code:
def activate_adapter(
self,
lora_id: int,
) -> bool:
"""Move LoRA into a GPU buffer to be used in the forward pass."""
if lora_id in self._active_adapters:
return False
first_free_sl... | closed | 2025-03-08T15:38:35Z | 2025-03-08T16:35:28Z | https://github.com/vllm-project/vllm/issues/14495 | [
"feature request"
] | chenhongyu2048 | 0 |
lexiforest/curl_cffi | web-scraping | 345 | [Feature] implement `trust_env` | **Is your feature request related to a problem? Please describe.**
It seems that `requests.Session(trust_env=False)` is not implemented, from my test and your code. I suppose it is possible cuz `--noproxy` can be provided to `curl` command.
**Describe the solution you'd like**
Grateful for implementing it.
**... | open | 2024-07-09T10:15:25Z | 2024-07-16T04:49:17Z | https://github.com/lexiforest/curl_cffi/issues/345 | [
"enhancement"
] | rknyip | 2 |
cvat-ai/cvat | computer-vision | 8,887 | "docker-compose up" got error on Orangepi5 | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
There are 2 ways to reproduce the bug, both ending in output
```
root@orangepi5:/home/orangepi/dev/external/cvat# docker-... | closed | 2024-12-28T21:06:11Z | 2024-12-28T21:50:34Z | https://github.com/cvat-ai/cvat/issues/8887 | [
"bug"
] | PospelovDaniil | 1 |
piskvorky/gensim | nlp | 2,597 | It is not possible to set values for BM25 model hyperparameters (K1, B, and EPSILON) | <!--
**IMPORTANT**:
- Use the [Gensim mailing list](https://groups.google.com/forum/#!forum/gensim) to ask general or usage questions. Github issues are only for bug reports.
- Check [Recipes&FAQ](https://github.com/RaRe-Technologies/gensim/wiki/Recipes-&-FAQ) first for common answers.
Github bug reports that d... | closed | 2019-09-06T14:57:44Z | 2020-01-08T03:51:14Z | https://github.com/piskvorky/gensim/issues/2597 | [] | marcelo-dalmeida | 13 |
slackapi/python-slack-sdk | asyncio | 1,243 | Using say() with files_info method posts multiple messages | Hello!
As I mention in the title, I'm using the files_info method to get the name, link and content of uploaded files in a channels, and then using the say() method to post this information in a channel.
Whenever I do this, however, the bots sends multiple messages instead of just one, non-stopping, to the point th... | closed | 2022-07-21T10:08:18Z | 2022-07-22T08:37:23Z | https://github.com/slackapi/python-slack-sdk/issues/1243 | [
"question"
] | lautaropacellaDR | 5 |
pytest-dev/pytest-cov | pytest | 529 | RecursionError: maximum recursion depth exceeded with --cov-report=html | I tried generating a coverage report using `pytest --cov-report=html --cov srmb` and got `RecursionError: maximum recursion depth exceeded`:
```
INTERNALERROR> Traceback (most recent call last):
INTERNALERROR> File "/Users/pownissa/anaconda3/lib/python3.7/site-packages/_pytest/main.py", line 257, in wrap_sessio... | open | 2022-03-20T00:38:59Z | 2022-04-22T16:21:56Z | https://github.com/pytest-dev/pytest-cov/issues/529 | [] | npow | 5 |
plotly/dash | plotly | 3,166 | Allow a hook for `custom_data` into the `callback_context` | Would like for the ability to set `custom_data` inside of `callback_context`. This would give the flexibility to establish a variable that can be accessed by any function done within the context of a callback. Including background callbacks to grant access to things like user settings, etc.
---
@gvwilson would be goo... | closed | 2025-02-14T16:08:32Z | 2025-02-21T19:03:10Z | https://github.com/plotly/dash/issues/3166 | [
"feature"
] | BSd3v | 1 |
PaddlePaddle/PaddleHub | nlp | 2,256 | hub serving部署成功一段时间后,会出现post请求超时错误 | 欢迎您反馈PaddleHub使用问题,非常感谢您对PaddleHub的贡献!
在留下您的问题时,辛苦您同步提供如下信息:
- 版本、环境信息
1)PaddleHub和PaddlePaddle版本:请提供您的PaddleHub和PaddlePaddle版本号,例如PaddleHub1.4.1,PaddlePaddle1.6.2
paddle-bfloat 0.1.7
paddle-serving-app 0.9.0
paddle-serving-client 0.9.0
paddle-serving-server 0.9.0
paddle-serving-serve... | open | 2023-05-21T02:40:29Z | 2024-02-26T04:59:32Z | https://github.com/PaddlePaddle/PaddleHub/issues/2256 | [] | waizao | 5 |
biolab/orange3 | numpy | 6,884 | Corpus widget and feature importance widget don't appear in Orange | **What's wrong?**
I've just downloaded orange and am following instructions. I can't find the corpus on feature importance widget on my device. When I search for them they don't appear.
**How can we reproduce the problem?**
Not sure
**What's your environment?**
<!-- To find your Orange version, see "Hel... | open | 2024-08-27T13:36:28Z | 2025-02-21T07:35:35Z | https://github.com/biolab/orange3/issues/6884 | [
"bug report"
] | LouisAllgoodMOJ | 7 |
jina-ai/serve | machine-learning | 5,604 | Add the JinaRPC service to workerRuntime and HeadRuntime | Add the JinaRPC service to workerRuntime and HeadRuntime. This will allow jina client to communicate with both runtimes using `stream=True`.
Currently `stream=False` already works but not tested.
Add tests for client communicating with both runtimes in both cases | closed | 2023-01-16T16:38:50Z | 2023-01-25T14:18:56Z | https://github.com/jina-ai/serve/issues/5604 | [] | alaeddine-13 | 0 |
open-mmlab/mmdetection | pytorch | 11,767 | 在MM-grounding-dino的项目中,做微调,使用自定义数据集,准备做REC任务,数据集格式是什么? | **Notice**
There are several common situations in the reimplementation issues as below
1. Reimplement a model in the model zoo using the provided configs
2. Reimplement a model in the model zoo on other dataset (e.g., custom datasets)
3. Reimplement a custom model but all the components are implemented in MMDet... | open | 2024-06-05T02:34:12Z | 2024-06-05T02:34:28Z | https://github.com/open-mmlab/mmdetection/issues/11767 | [
"reimplementation"
] | MLwudi | 0 |
graphql-python/graphene | graphql | 626 | Mutation.Field() doesn't propagate the keywords arguments | I noticed that the Field method of the Mutation class is not propagating the keywords arguments that
are passed to it.
```
class Mutation(ObjectType):
...
@classmethod
def Field(cls, *args, **kwargs):
return Field(
cls._meta.output, args=cls._meta.arguments, resolver=cls._meta... | closed | 2017-12-12T17:39:36Z | 2018-02-18T13:57:47Z | https://github.com/graphql-python/graphene/issues/626 | [] | mottetm | 1 |
apragacz/django-rest-registration | rest-api | 144 | Cannot change superuser email when using custom flag field and createsuperuser | ### Describe the bug
I changed the default flag field with `USER_VERIFICATION_FLAG_FIELD` and created a superuser with the Django command `createsuperuser`. Changing this superuser's email results in an error when verifying the email.
### Expected behavior
Superuser email is changed.
### Actual behavior
... | open | 2021-05-26T15:43:14Z | 2021-06-03T13:01:19Z | https://github.com/apragacz/django-rest-registration/issues/144 | [
"type:bug"
] | Neraste | 3 |
timkpaine/lantern | plotly | 78 | plotly support upper x label | closed | 2017-10-18T02:05:09Z | 2017-10-25T02:34:08Z | https://github.com/timkpaine/lantern/issues/78 | [
"feature",
"plotly/cufflinks"
] | timkpaine | 1 | |
microsoft/nni | pytorch | 5,489 | a nodejs error when using NNI {"error":"A system error occurred: uv_os_get_passwd returned ENOENT (no such file or directory)" | **Environment**:
- NNI version: 2.10
- Training service: local
- Machine OS: CentOS 6.3
- Python version: 3.9
- PyTorch/TensorFlow version: 1.12.1
- Is conda/virtualenv/venv used?: yes
- Is running in Docker?: no
**ERROR MESSAGE**:
```
[2023-03-29 15:24:12] Creating experiment, Experiment ID: 36ymuxit
[202... | open | 2023-03-29T08:19:27Z | 2023-04-03T02:58:12Z | https://github.com/microsoft/nni/issues/5489 | [] | zZer0o | 3 |
recommenders-team/recommenders | machine-learning | 1,287 | [BUG] error in fastai NVMLError_LibRmVersionMismatch: RM has detected an NVML/RM version mismatch. | ### Description
<!--- Describe your issue/bug/request in detail -->
error in fastai version
```
E 3 from .core import *
E 4 from .basic_data import *
E 5 from .data_block import *
E
E /anaconda/envs/reco_gpu/lib/python3.6/site-packages/f... | closed | 2021-01-22T09:10:09Z | 2021-01-25T14:47:19Z | https://github.com/recommenders-team/recommenders/issues/1287 | [
"bug"
] | miguelgfierro | 1 |
open-mmlab/mmdetection | pytorch | 11,799 | set randomness= dict(seed=138011772,deterministic=True) in config file, RuntimeError in anchor_head.py | When I train Faster-rcnn with the following setting in config file:
```none
randomness= dict(seed=138011772,deterministic=True)
```
I get the following error:
```none
File "/mmdetection-main/mmdet/models/dense_heads/anchor_head.py", line 505, in loss_by_feat
cls_reg_targets = self.get_targets(
Fil... | open | 2024-06-18T09:07:39Z | 2025-03-16T11:05:30Z | https://github.com/open-mmlab/mmdetection/issues/11799 | [] | ttt0666 | 1 |
vitalik/django-ninja | pydantic | 800 | [BUG] pydantic version error | **Describe the bug**
A clear and concise description of what the bug is.
**Versions (please complete the following information):**
python = "^3.9"
pydantic = "<2.0.0"
requests = "^2.31.0"
django-ninja = "^0.22.2"
```
poetry add pydantic>2
```
error:
```
Updating dependencies
Resolving dependencies...... | open | 2023-07-21T02:41:30Z | 2023-07-21T06:28:31Z | https://github.com/vitalik/django-ninja/issues/800 | [] | j5255089 | 1 |
PaddlePaddle/models | computer-vision | 5,286 | 如何直接调用模型? | 如何像pytorch一样能直接调用各种模型,比如像
torchvision.models.detection.fasterrcnn_resnet_fpn(pretrained=true),model.eval()
这样很方便
| open | 2021-03-13T07:51:38Z | 2024-02-26T05:09:08Z | https://github.com/PaddlePaddle/models/issues/5286 | [] | lao-xu | 2 |
vaexio/vaex | data-science | 1,419 | [BUG-REPORT] concat use resolver=’strict’ report error | I use concat Concatenates DataFrames, An error occurs when resolver=’strict’ is used.
```
df = vx.open("/dataAN/sales.hdf5")
df1 = vx.open("/dataAN/sales.hdf5")
dfc= vx.concat([df1,df], resolver='strict')
ERROR:Thread-3:vaex:error evaluating: Invoice_Number at rows 0-5
Traceback (most recent call last):
Fi... | closed | 2021-06-19T03:52:17Z | 2021-06-22T01:32:40Z | https://github.com/vaexio/vaex/issues/1419 | [] | heyuqi1970 | 2 |
twopirllc/pandas-ta | pandas | 384 | vwap | How to have different vwap with different inputs ? | closed | 2021-09-01T19:12:06Z | 2021-09-03T02:23:13Z | https://github.com/twopirllc/pandas-ta/issues/384 | [
"info"
] | Ylelmon | 15 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 1,006 | Mio | ###
- _**
1.
- [x] @ecoopnet
**_ | closed | 2020-04-25T20:22:25Z | 2020-04-25T20:22:49Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1006 | [] | angeloko23 | 0 |
holoviz/panel | plotly | 7,707 | For IntSlider, the increment is not expected if set min=0, max=590 | #### ALL software version info
8.1.5
See below.

When I move the slider to next, it becomes 31.

This is not expected. It should be 29.
... | closed | 2025-02-13T08:04:25Z | 2025-02-13T08:34:12Z | https://github.com/holoviz/panel/issues/7707 | [] | morganh-nv | 2 |
xinntao/Real-ESRGAN | pytorch | 294 | Very noisy training curves when trying to fine-tune with paired data, what am I doing wrong? | I'm trying to train Real-ESRGAN with 400 images.
The training curves are very noisy, especially the perceptual loss (l_g_precep).
I've tried to use various different learning rates.
I'm using 4 GPUs with 5 images on each GPU
 is already doing much, but has ... | open | 2024-02-08T07:11:25Z | 2024-02-22T17:38:14Z | https://github.com/PokeAPI/pokeapi/issues/1036 | [] | GreatNovaDragon | 4 |
itamarst/eliot | numpy | 324 | Ability to record source file and line number in log messages | Implementation sketch:
```python
import inspect
import os.path
from eliot import FileDestination, __file__ as _eliot_prefix
_eliot_prefix = os.path.dirname(_eliot_prefix)
class LineNumberDestination(object):
def __init__(self, file_like):
self._dest = FileDestination(file_like)
def __call... | open | 2018-07-19T15:25:34Z | 2023-02-09T17:35:38Z | https://github.com/itamarst/eliot/issues/324 | [
"enhancement"
] | itamarst | 2 |
miguelgrinberg/Flask-SocketIO | flask | 1,201 | Not firing events on server when using Blueprints | **Your question**
I want to implement Socket.io on an application with many Blueprints, using 2 namespaces (for now). However, even when my client is connecting to the server, the server is refusing to fire the events.
**Additional context**
I recently refractored from a non-blueprint architecture, where everythin... | closed | 2020-03-04T17:12:44Z | 2020-06-30T22:59:41Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1201 | [
"question"
] | vijuarez | 6 |
FlareSolverr/FlareSolverr | api | 289 | FlareSolver crashes after running for the first time. | ### Environment
* **FlareSolverr version**: 2.1.0
* **Last working FlareSolverr version**: none
* **Operating system**: Windows 2019 Server Standard Edition
* **Are you using Docker**: [yes/no] no
* **FlareSolverr User-Agent (see log traces or / endpoint)**: ??
* **Are you using a proxy or VPN?** [yes/no] no
*... | closed | 2022-01-31T18:30:46Z | 2022-04-16T18:59:58Z | https://github.com/FlareSolverr/FlareSolverr/issues/289 | [
"more information needed"
] | SmoothAdmin | 4 |
sczhou/CodeFormer | pytorch | 248 | Nejh2 | open | 2023-06-11T06:58:34Z | 2023-06-11T06:58:34Z | https://github.com/sczhou/CodeFormer/issues/248 | [] | javid525 | 0 | |
Evil0ctal/Douyin_TikTok_Download_API | web-scraping | 320 | [Feature request] 大佬,请更新docker镜像的3.9版本 | 大佬,请更新docker镜像的3.9版本
docker hub上最新的镜像还是3.8。 | closed | 2024-01-17T10:08:10Z | 2024-03-25T22:32:21Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/320 | [
"enhancement"
] | HHBK201 | 1 |
QingdaoU/OnlineJudge | django | 228 | 反向代理时,Referer检查错误 | 登录时,console中提示/api/login返回403错误
gunicorn.log中相关日志:
[2019-02-20 15:06:31] - [WARNING] - [django.security.csrf:160] - Forbidden (Referer checking failed - https://oj.***.info/ does not match any trusted origins.): /api/login
手动在/app/oj/settings.py文件中添加
CSRF_TRUSTED_ORIGINS = ['oj.***.info']
后可正常访问... | closed | 2019-02-20T17:38:53Z | 2019-02-22T04:37:54Z | https://github.com/QingdaoU/OnlineJudge/issues/228 | [] | chang196700 | 2 |
keras-team/keras | tensorflow | 20,106 | Unrecognized keyword arguments passed to LSTM: {'batch_input_shape' | model = Sequential()
model.add(LSTM(4, batch_input_shape=(1, X_train.shape[1], X_train.shape[2]), stateful=True))
model.add(Dense(1))
model.compile(loss='mean_squared_error', optimizer='adam')
model.fit(X_train, y_train, epochs=100, batch_size=1, verbose=1, shuffle=False)
ValueError: Unrecognized keyword argumen... | closed | 2024-08-09T19:19:55Z | 2025-03-22T12:16:24Z | https://github.com/keras-team/keras/issues/20106 | [
"type:support",
"stat:awaiting response from contributor"
] | Ineedsomehelpah | 7 |
huggingface/datasets | machine-learning | 7,018 | `load_dataset` fails to load dataset saved by `save_to_disk` | ### Describe the bug
This code fails to load the dataset it just saved:
```python
from datasets import load_dataset
from transformers import AutoTokenizer
MODEL = "google-bert/bert-base-cased"
tokenizer = AutoTokenizer.from_pretrained(MODEL)
dataset = load_dataset("yelp_review_full")
def tokenize_functi... | open | 2024-07-01T12:19:19Z | 2024-12-03T11:26:17Z | https://github.com/huggingface/datasets/issues/7018 | [] | sliedes | 4 |
robotframework/robotframework | automation | 5,346 | Alternative status when suite setup or suite teardown fail. | # Enhancement Request
This is my use case:
- When my suite setup fails, I would like to mark the tests as skipped rather than failed. And I would like the final suite status to be failed.
- When my suite teardown fails, I would like to preserve each tests results, rather than have them marked as failed. And I would l... | open | 2025-02-20T08:10:24Z | 2025-02-27T12:59:20Z | https://github.com/robotframework/robotframework/issues/5346 | [] | gohierf | 1 |
developmentseed/lonboard | data-visualization | 329 | Move accessor length validation to serialization step | Currently we validate accessor length in `_validate_accessor_length` on the layer itself, but that's probably not able to dynamically validate all accessors, even those added by an extension. Instead, we can check during serialization that the length of the column is the same as the length of the table. | closed | 2024-01-26T17:00:13Z | 2024-01-26T19:41:28Z | https://github.com/developmentseed/lonboard/issues/329 | [] | kylebarron | 0 |
strawberry-graphql/strawberry | asyncio | 3,382 | Pyright type issue with strawberry.file_uploads.Upload | ## Describe the Bug
VSCode and Pyright give me red squiggly lines when using `strawberry.file_uploads.Upload`.
Repro:
Save a file with the contents:
```
from strawberry.file_uploads import Upload
async def read(f: Upload) -> bytes:
data = await f.read()
return data
```
Then run `pyright`... | open | 2024-02-15T07:13:15Z | 2025-03-20T15:56:36Z | https://github.com/strawberry-graphql/strawberry/issues/3382 | [
"documentation"
] | axiomofjoy | 4 |
autokey/autokey | automation | 551 | new user, expansion not occuring. Downloaded through apt, system: PopOS, i3wm. | ## Classification:
-> Bug
## Reproducibility:
sudo apt install autokey-qt
write a snippet, add a hotkey and a shortcut to expand
save
try the snippet, fail on both hotkey (alt-shift-p) and shortcut (qqp)
tried also: removing autokey-qt, installing ak-gtk, same issue
->Always
## Version
AutoKey versi... | closed | 2021-05-25T18:20:23Z | 2023-05-01T09:36:21Z | https://github.com/autokey/autokey/issues/551 | [] | thor314 | 4 |
timkpaine/lantern | plotly | 177 | fix revisions in requirements.txt | closed | 2018-12-25T13:50:41Z | 2018-12-29T21:01:40Z | https://github.com/timkpaine/lantern/issues/177 | [
"feature"
] | timkpaine | 0 | |
dynaconf/dynaconf | fastapi | 747 | [bug] Cannot merge using env var with dict that has empty string as its key | **SOLUTION IN** https://github.com/pulp/pulpcore/pull/3146/files
**Describe the bug**
I tried to use an env_var to merge a dictionary, but it has the key '' which is not able to work, although I expected it to work.
**To Reproduce**
I tried to set this variable:
` PULP_LOGGING={'dynaconf_merge': True, 'logg... | closed | 2022-05-03T14:55:40Z | 2022-08-29T17:08:13Z | https://github.com/dynaconf/dynaconf/issues/747 | [
"bug",
"Not a Bug"
] | bmbouter | 2 |
zappa/Zappa | django | 673 | [Migrated] Inconsistent amount of scheduled events in outputs of "update" & "status" commands | Originally from: https://github.com/Miserlou/Zappa/issues/1725 by [tunghim](https://github.com/tunghim)
<!--- Provide a general summary of the issue in the Title above -->
## Context
When I run
`$ zappa update {env_name}`
Scheduled events are being shown in the output properly.
![screenshot from 2018-12-07 ... | closed | 2021-02-20T12:32:45Z | 2024-04-13T17:36:51Z | https://github.com/zappa/Zappa/issues/673 | [
"no-activity",
"auto-closed"
] | jneves | 2 |
pyeventsourcing/eventsourcing | sqlalchemy | 106 | Getting save errors with various class construtions | I'm still trying to tackle an example app and making progress in some directions but still failing to understand the fundamentals in this library so please know that I'm super appreciative of your patience. Once I figure this out I hope to make the example library very clear and runnable.
I'm trying to understand ho... | closed | 2017-10-17T09:37:41Z | 2017-10-17T17:44:51Z | https://github.com/pyeventsourcing/eventsourcing/issues/106 | [] | dgonzo | 8 |
aimhubio/aim | data-visualization | 2,847 | Dry-run option? | Hi!
Is there a way to specify a dry run? E.g. to not write anything to disk without needing to uncomment run.track() calls? | open | 2023-06-16T10:24:54Z | 2023-06-27T17:33:37Z | https://github.com/aimhubio/aim/issues/2847 | [
"type / question"
] | axelbr | 4 |
ading2210/poe-api | graphql | 205 | Using the gpt4 model to answer the effect is gpt3.5 | The situation is the same for gpt-4 or gpt-4-32k. You can find that the model is not wrong when you log in to poe, but the answer is definitely not gpt4. | open | 2023-07-26T16:06:56Z | 2023-08-02T21:32:18Z | https://github.com/ading2210/poe-api/issues/205 | [
"bug"
] | suidu-pro | 5 |
sqlalchemy/sqlalchemy | sqlalchemy | 10,548 | Conflict in Instrumentation between SQLAlchemy and Pydantic Leading to AttributeError | ### Describe the bug
When using SQLAlchemy with Pydantic's dataclass integration for defining ORM models, there is an inconsistency in the behavior of object instantiation and relationship setting. The issue arises when creating multiple instances of a SQLAlchemy model and setting relationships via the initializer (co... | closed | 2023-10-26T15:19:10Z | 2023-10-26T19:38:52Z | https://github.com/sqlalchemy/sqlalchemy/issues/10548 | [
"wontfix / out of scope",
"pydantic"
] | chipxsd | 3 |
scrapy/scrapy | python | 6,023 | formatted string to KeyError exception . | at the `scrapy/scrapy/spiderloader.py` at line `89`, the f string is passed directly as exception arg.
which looks like this when the error is trigered.
<img width="877" alt="Screenshot 2023-08-26 at 20 47 15" src="https://github.com/scrapy/scrapy/assets/106245122/eb819645-e2b4-49cd-9156-ed4e71acf669"> | closed | 2023-08-26T17:52:11Z | 2023-08-27T11:43:31Z | https://github.com/scrapy/scrapy/issues/6023 | [
"needs more info"
] | ma-habibi | 2 |
ResidentMario/geoplot | matplotlib | 235 | naive question (sloved) | closed | 2021-05-04T21:25:40Z | 2021-05-04T21:30:30Z | https://github.com/ResidentMario/geoplot/issues/235 | [] | shuaichenchang | 0 | |
sloria/TextBlob | nlp | 172 | python -m textblob.download_corpora not working | here's the output
```[nltk_data] Error loading brown: HTTP Error 405: Not allowed.
[nltk_data] Error loading punkt: HTTP Error 405: Not allowed.
[nltk_data] Error loading wordnet: HTTP Error 405: Not allowed.
[nltk_data] Error loading averaged_perceptron_tagger: HTTP Error 405:
[nltk_data] Not allowed.
[nlt... | closed | 2017-07-26T06:30:11Z | 2018-01-03T00:48:08Z | https://github.com/sloria/TextBlob/issues/172 | [] | weiztech | 7 |
google-deepmind/sonnet | tensorflow | 215 | ValueError("None values not supported.") when using all_reduce on gradients with TPU | Hi, I am trying to use SONNET to adapt ENFORMER training code provided here:
https://github.com/deepmind/deepmind-research/blob/master/enformer/enformer-training.ipynb
However, the authors recommend a TPU instead of a GPU. I am following this guide as a template to do distributed training, trying to adapt it to a T... | closed | 2021-08-27T21:12:37Z | 2021-08-28T16:47:12Z | https://github.com/google-deepmind/sonnet/issues/215 | [] | a3cel2 | 1 |
qubvel-org/segmentation_models.pytorch | computer-vision | 584 | Use Unet decoder separately with output from pretrained resnet18 | Hi, I have written an encoder block using pretrained resnet 18 and deleted the average pooling and fc layers in the end. The output that I get from the encoder is of shape (BS, 512, H, W) and I want to pass this into your unet decoder part only which is here:
https://github.com/qubvel/segmentation_models.pytorch/blob/... | closed | 2022-04-03T21:59:19Z | 2022-06-10T02:16:11Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/584 | [
"Stale"
] | Nakkhatra | 2 |
wger-project/wger | django | 1,780 | Problem when adding new exercise to routine | ## Steps to Reproduce
<!-- Please include as many steps to reproduce so that we can replicate the problem. -->
1. Create new routine
2. Add new training day to routine
3. Add exercise
4. Start typing "Row" and wait for autocompletion
**Expected results:**
Exercise can be added
**Actual results:**
An ex... | closed | 2024-09-30T18:44:46Z | 2024-10-16T10:02:09Z | https://github.com/wger-project/wger/issues/1780 | [] | franznemeth | 3 |
matterport/Mask_RCNN | tensorflow | 2,555 | can anyone help me to convert .h5 file to pb for custom dataset? | got this error when i try to convert
```
import onnx
import keras2onnx
# Load the keras model
model = load_model('/content/drive/MyDrive/thirip2/mask_rcnn_bottle_0002.h5')
# Convert it into onnx
onnx_model = keras2onnx.convert_keras(model, model.name)
# Save the model as flower.onnx
onnx.save_mod... | closed | 2021-05-03T13:47:21Z | 2021-08-02T14:11:23Z | https://github.com/matterport/Mask_RCNN/issues/2555 | [] | Jeffin21 | 1 |
ultralytics/ultralytics | pytorch | 19,178 | Should I train my model with non-paper cup objects as defective?(YOLO11) | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
I am developing a model for classifying paper cups as either acceptable or d... | open | 2025-02-11T07:47:40Z | 2025-02-11T09:27:33Z | https://github.com/ultralytics/ultralytics/issues/19178 | [
"question"
] | kkoma-dev | 1 |
ultralytics/ultralytics | pytorch | 19,697 | YOLOv8n validation on DOTA v2.0 dataset | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Hello! When I use the YOLOv8n model to save TXT results (predictions_merged_... | open | 2025-03-14T09:51:52Z | 2025-03-14T20:11:45Z | https://github.com/ultralytics/ultralytics/issues/19697 | [
"question",
"detect"
] | HornGate | 2 |
sinaptik-ai/pandas-ai | data-science | 1,418 | FileNotFoundError: [Errno 2] No such file or directory: '/Users/cindy/Documents/AI/jiaoxing/jiaoxing/.venv/lib/python3.11/site-packages/pandasai/pipelines/chat/dataframe.csv' | ### System Info
python3.11/ macos 13.2.1/ pandasai later
------------------
After uploading the excel data and querying for a while,
this problem always occurs in the end: FileNotFoundError: [Errno 2] No such file or directory: '/Users/cindy/Documents/AI/jiaoxing/jiaoxing/.venv/lib/python3.11/site-packages/pandasai... | closed | 2024-10-30T03:04:46Z | 2025-02-05T16:00:14Z | https://github.com/sinaptik-ai/pandas-ai/issues/1418 | [
"bug"
] | bjpenck | 4 |
roboflow/supervision | deep-learning | 1,388 | Create new cookbook for utilizing supervision methods to easily create YOLO datasets for training | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Description
I find myself creating dataset structures and split in train, valid, test and images, labels folders multiple times. The whole process could ... | open | 2024-07-21T16:37:17Z | 2024-08-05T07:52:54Z | https://github.com/roboflow/supervision/issues/1388 | [
"enhancement"
] | xaristeidou | 7 |
PokeAPI/pokeapi | api | 591 | Pokemon list does not include Unown forms | The list of pokemon served at https://pokeapi.co/api/v2/pokemon/?limit=2000 does not include any of the Unown forms for some reason.
As a result of this the encounter table can't reference any of the Unown forms, I have not found any way to fix this or what is causing it. | open | 2021-03-11T23:04:22Z | 2021-03-30T02:05:42Z | https://github.com/PokeAPI/pokeapi/issues/591 | [] | SimplyBLGDev | 12 |
pytest-dev/pytest-mock | pytest | 44 | Two tracebacks with assert_wrapper / wrap_assert_has_calls | When using `assert_has_calls` I am seeing two tracebacks, but the first one should not be there?!
```
Traceback (most recent call last):
File "…/pytest-mock/pytest_mock.py", line 155, in assert_wrapper
__wrapped_mock_method__(*args, **kwargs)
File "/usr/lib64/python3.5/unittest/mock.py", line 824, in assert_ha... | closed | 2016-05-20T11:25:34Z | 2016-06-01T22:27:18Z | https://github.com/pytest-dev/pytest-mock/issues/44 | [] | blueyed | 5 |
mwaskom/seaborn | data-science | 3,293 | seaborn.objects.Band - Examples not working as expected | This is in reference to the examples on [`seaborn.objects.Band`](https://seaborn.pydata.org/generated/seaborn.objects.Band.html).
**Tested in `python 3.11`, `pandas 1.5.3`, `matplotlib 3.7.0`, `seaborn 0.12.2`**
1. The examples don't work without the imported data being specified (e.g. `seaice = sns.load_dataset(... | closed | 2023-03-10T23:05:00Z | 2023-03-10T23:36:27Z | https://github.com/mwaskom/seaborn/issues/3293 | [] | trenton3983 | 1 |
ultralytics/yolov5 | deep-learning | 13,348 | How can I see F1-score and precision/recall curves for validation set ? | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
Hello! I can see the F1-score for the training dataset after completing the training proc... | open | 2024-10-09T05:32:56Z | 2024-11-09T13:03:27Z | https://github.com/ultralytics/yolov5/issues/13348 | [
"question"
] | Grhanas | 2 |
RobertCraigie/prisma-client-py | pydantic | 1,067 | Field's named 'models' cause issues with resolving pydantic models. | ## Bug description
Given a schema
```prisma
datasource db {
provider = "sqlite"
url = "file:./dev.db"
}
generator py {
provider = "prisma-client-py"
}
model A {
id Int @id @default(autoincrement())
B B @relation(fields: [bId], references: [id])
bId Int
}
model B {
id Int @... | open | 2025-03-03T12:04:53Z | 2025-03-03T12:04:53Z | https://github.com/RobertCraigie/prisma-client-py/issues/1067 | [] | sammaxwellxyz | 0 |
Neoteroi/BlackSheep | asyncio | 421 | Handled exception is logged as unhandled | **Describe the bug**
Blacksheep erroneously logs an error saying that an exception is unhandled despite it being handled:
```python
from blacksheep.server import Application
app = Application()
@app.router.get('/type-error')
async def type_error():
raise TypeError()
@app.exception_handler(Exceptio... | closed | 2023-10-12T19:33:02Z | 2023-12-31T12:31:52Z | https://github.com/Neoteroi/BlackSheep/issues/421 | [] | mohd-akram | 1 |
bregman-arie/devops-exercises | python | 200 | Found many questions without Answers | Hi @bregman-arie ,
Thanks for the resource. But there a lot of questions unanswered in `devops-exercises/exercises/ansible/README.md`. It would be great if you can add the answers.
Thanks. | closed | 2022-01-21T16:57:13Z | 2022-01-25T05:11:28Z | https://github.com/bregman-arie/devops-exercises/issues/200 | [] | Krushna-Prasad-Sahoo | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.