
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
nvbn/thefuck | python | 1,018 | `eval $(thefuck --alias)` is slow | Hello,
I'm cleaning up my zshrc/aliasrc & with the help of https://github.com/ohmyzsh/ohmyzsh/issues/5327#issuecomment-455763912 I've noticed that `eval $(thefuck --alias)` slows down my shell by a lot!
The startup time changed from ~140ms to ~50ms once I disabled the evaluation of the alias.
Wouldn't it be fa... | open | 2019-12-06T15:34:59Z | 2020-12-01T18:53:54Z | https://github.com/nvbn/thefuck/issues/1018 | [] | kiprasmel | 2 |
Evil0ctal/Douyin_TikTok_Download_API | fastapi | 224 | 获取用户主页作品接口返回出现错误 | https://api.tikhub.io/douyin/user_profile_videos_data
这个接口返回{"status":false,"platform":"douyin","endpoint":"/douyin/user_profile_videos_data/","total_time":null,"message":"解析失败,检查参数/Parse failed, check parameters","video_id":null,"sec_user_id":null,"has_more":null,"cursor":null,"next_url":null,"count":null,"aweme_list... | closed | 2023-07-17T18:22:55Z | 2023-08-04T09:31:32Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/224 | [
"BUG"
] | ghost | 7 |
pytorch/pytorch | machine-learning | 149,325 | ☂️ MPS support for large tensors | ### 🐛 Describe the bug
Random ATen operations that use MPS backend can fail with `Error: total bytes of NDArray > 2**32` or other such errors that expect either tensor size to be less than 4Gb, or total number of elements to be indexable by 32-bit index.
This is umbrella issue to track those (should be searchable b... | open | 2025-03-17T16:13:24Z | 2025-03-17T16:17:51Z | https://github.com/pytorch/pytorch/issues/149325 | [
"module: crash",
"triaged",
"module: 64-bit",
"module: mps"
] | malfet | 0 |
iperov/DeepFaceLab | deep-learning | 961 | Error: module 'tensorflow' has no attribute 'ConfigProto' | Technically, not an issue with the main PC program. Have suddenly started getting this error on colab:
[CPU] : CPU
[0] : Tesla V100-SXM2-16GB
[0] Which GPU indexes to choose? :
0
Error: module 'tensorflow' has no attribute 'ConfigProto'
Traceback (most recent call last):
File "/content/DeepFaceLab/mainscr... | closed | 2020-12-03T15:32:08Z | 2020-12-05T23:28:23Z | https://github.com/iperov/DeepFaceLab/issues/961 | [] | tania010 | 0 |
Gozargah/Marzban | api | 1,161 | grpc settings | سلام، حالت دفالتی که idle_timeout: 60 قرار داده مدام باعث قطع ارتباط میشه و بایستی قطع و وصل کنه کاربر تا کار کنه، من تو پنل مقدار رو از 60 به صفر تغییر میدم منتهی این تغییر اعمال نمیشه

.
Currently the link is:
Read the documentation at the `http://docs.viewflow.io/ <http://docs.viewflow.io/introduction.html>`_
....shoul... | closed | 2016-11-15T01:35:08Z | 2016-11-15T06:38:04Z | https://github.com/viewflow/viewflow/issues/165 | [] | jagu2012 | 2 |
Kanaries/pygwalker | plotly | 141 | Update QR | The group chat QR code has expired, please update it. Thanks a lot! | closed | 2023-06-25T09:15:53Z | 2023-07-01T02:11:33Z | https://github.com/Kanaries/pygwalker/issues/141 | [] | lichaoahcil | 1 |
CTFd/CTFd | flask | 2,641 | Improving release process (SLSA and SBOMs) | Hello Kevin and folks here :grin:
The current CTFd build and release process **works**, but we can -and need- to go further.
Why ? TL;DR: **security**... [SLSA Level 3](https://slsa.dev/get-started#slsa-3), SBOMs, etc.
The current release process can be summarized as follows (to my understanding of course, feel ... | open | 2024-10-21T16:57:24Z | 2024-10-23T08:34:23Z | https://github.com/CTFd/CTFd/issues/2641 | [] | pandatix | 1 |
tfranzel/drf-spectacular | rest-api | 1,329 | Generated schema is not compatible with jsonschema's referencing | I've currently implemented schema validation of API responses in my tests using [python-jsonschema](https://github.com/python-jsonschema)'s RefResolver. Everything works perfectly!
```py
from typing import Any
import openapi_schema_validator
from drf_spectacular.settings import spectacular_settings
from jsonsche... | open | 2024-11-12T06:49:17Z | 2024-11-12T06:49:17Z | https://github.com/tfranzel/drf-spectacular/issues/1329 | [] | stefanofusai | 0 |
thtrieu/darkflow | tensorflow | 1,044 | Missing output boxes. | Trained on my own data set. 8 classes, at step 11790 - loss 0.15480981767177582 and going down, I changed the number of classes in the config as well as the filters on the last layer to 65 (5*(classes+5)). Here is the command I used for training :
!python3 flow --model cfg/yolov2-voc-8c.cfg --train --dataset ../Train... | closed | 2019-05-31T16:13:27Z | 2020-04-01T18:35:44Z | https://github.com/thtrieu/darkflow/issues/1044 | [] | GioLomia | 15 |
mlfoundations/open_clip | computer-vision | 311 | ImageNet mean/std for timm pretrained weights | Currently, I think we're using [OpenAI mean/std](https://github.com/mlfoundations/open_clip/blob/694554495aedf97ac046e53a690ecd86aee96274/src/open_clip/constants.py#L1) even for timm pretrained image models.
Better to use [ImageNet mean/std](https://github.com/rwightman/pytorch-image-models/blob/18ec173f95aa220af753... | closed | 2022-12-21T05:06:21Z | 2023-10-24T16:17:37Z | https://github.com/mlfoundations/open_clip/issues/311 | [] | usuyama | 3 |
mlfoundations/open_clip | computer-vision | 384 | MuLaN | The new [MusicLM](https://arxiv.org/abs/2301.11325) relies on an audio CLIP named [MuLaN](https://arxiv.org/abs/2208.12415)
I will build out an initial implementation [here](https://github.com/lucidrains/musiclm-pytorch), but eventually we should also get the audio encoder design into open clip, so that we can do au... | open | 2023-01-27T19:22:19Z | 2023-02-05T17:29:54Z | https://github.com/mlfoundations/open_clip/issues/384 | [] | lucidrains | 11 |
tfranzel/drf-spectacular | rest-api | 1,126 | Django 5 Support? | **Describe the bug**
Th readme mentions nothing about Django5 support. Is this project abandoned?
**To Reproduce**
Look at the README. Django 5 was release a bit ago but it doesn't seem to be officially supported, and that means this would block upgrades, right?
**Expected behavior**
I expect all modern rele... | closed | 2023-12-09T01:46:33Z | 2023-12-21T21:24:23Z | https://github.com/tfranzel/drf-spectacular/issues/1126 | [] | duaneking | 3 |
Miserlou/Zappa | flask | 2,092 | Certify with tags | ## Context
Tag is missing in API gateway
## Expected Behavior
The tag shall be added to API gateway
## Actual Behavior
The tag is not added
## Steps to Reproduce
1. zappa certify xxx
| open | 2020-04-30T02:35:43Z | 2020-04-30T02:35:43Z | https://github.com/Miserlou/Zappa/issues/2092 | [] | weasteam | 0 |
K3D-tools/K3D-jupyter | jupyter | 427 | marching_cubes with color from array | Hi, is it possible to give a color to the iso surfaces that come out of k3d.marching_cubes(A) based on an array with the same dimensions as A? Right now I could only set a uniform color. Thanks. | closed | 2023-08-03T15:30:28Z | 2024-01-15T08:27:44Z | https://github.com/K3D-tools/K3D-jupyter/issues/427 | [
"Next release"
] | sTamaroTum | 4 |
aws/aws-sdk-pandas | pandas | 2,685 | chunked = True in wr.s3.read_parquet is not working as expected | ### Describe the bug
Hi, I've used wr.s3.read_parquet to load my parquet file from s3. I have a very huge file in s3. A single file has 1 Million rows, which I can't load in my memory so I've tried to use chunked = True. but still memory is getting full. Also tried with chunked = 10000 but the same issue.
I've 32 GB ... | closed | 2024-02-22T07:37:05Z | 2024-03-01T17:48:23Z | https://github.com/aws/aws-sdk-pandas/issues/2685 | [
"bug"
] | PankajJ08 | 1 |
AirtestProject/Airtest | automation | 1,239 | 元素定位工具能不能独立出来 | 元素定位工具能不能独立出来 | open | 2024-08-19T13:24:13Z | 2024-09-05T12:22:55Z | https://github.com/AirtestProject/Airtest/issues/1239 | [] | aogg | 2 |
scikit-hep/awkward | numpy | 2,975 | Fix docs toolchain | Right now we'll pin it, but we should upgrade to sphinx 7. | closed | 2024-01-21T09:14:49Z | 2024-02-02T14:27:44Z | https://github.com/scikit-hep/awkward/issues/2975 | [
"docs"
] | agoose77 | 0 |
rthalley/dnspython | asyncio | 241 | Does not build on Windows | In an Anaconda 2 environment, I get
`IOError: [Errno 13] Permission denied: 'c:\\users\\...\\appdata\\local\\temp\\1\\pip-moorgy-build\\tests/example1.good'`
Is the problem that the `tests/example1.good` should be `tests\\example1.good`?
| closed | 2017-03-14T15:03:20Z | 2017-03-14T15:18:49Z | https://github.com/rthalley/dnspython/issues/241 | [] | zoof | 2 |
saulpw/visidata | pandas | 2,410 | Some issues during first time testing vdsql | **Small description**
1. I needed to install `sqlalchemy` which is undocumented ([source](https://github.com/saulpw/visidata/tree/develop/visidata/apps/vdsql#readme))
2. `vdsql mysql://root:@localhost/mysql` causes an error:
_OperationalError: (2003, "Can't connect to MySQL server on 'localhost' ([Errno 111] ... | open | 2024-05-21T20:39:20Z | 2024-08-27T09:45:18Z | https://github.com/saulpw/visidata/issues/2410 | [
"bug",
"vdsql"
] | p3k | 8 |
indico/indico | flask | 6,190 | Add an option to send an email after event has been ended | we are doing workshops and all event organization is done via Indico
we offer 2 workshops a month and user can choose an appointment and self register
we automated reminders via email (to remind that workshop will start in day and 2 hours) but we want to send also an automated email AFTER workshop ended to all part... | open | 2024-02-19T17:19:50Z | 2024-02-19T17:19:50Z | https://github.com/indico/indico/issues/6190 | [
"enhancement"
] | Saxomania | 0 |
aio-libs/aiomysql | asyncio | 415 | Execute multiple query on one same connection will mess up the results sometimes. | The following code execute two querys, the first return rows, and the second return total count. Sometimes the first query's result `rows` is `{'count_1': 5}`, which is the second count query's result. Does it allowed to execute multiple querys on one same connection?
```python
async def list_(self, *, status=... | closed | 2019-06-19T02:57:53Z | 2019-06-19T08:01:24Z | https://github.com/aio-libs/aiomysql/issues/415 | [] | jaggerwang | 2 |
hyperspy/hyperspy | data-visualization | 2,610 | Confusion between tilt stage and tilt_alpha | Reading velox files, the imported metadata include both a tilt stage value and a tilt_alpha value. I think it should be the same, isn't it ?
If that's correct, maybe we should use only alpha, beta and the elevation angle for simplication. Based on these three, the take-off angle can be recalculated. | closed | 2020-12-28T15:16:48Z | 2021-03-04T21:47:36Z | https://github.com/hyperspy/hyperspy/issues/2610 | [] | CorentinLG | 4 |
lux-org/lux | pandas | 255 | [DOCUMENTATION] AttributeError: 'VisList' object has no attribute 'topK' | I followed the tutorial of https://hub.gke2.mybinder.org/user/lux-org-lux-binder-85yxv12x/notebooks/tutorial/8-custom-action.ipynb, when run the codes below, I got an AttributeError:
```
for vis in vlist:
# Percentage Change Between G10 v.s. non-G10 countries
a = vis.data.iloc[0,1]
b = vis.data.iloc[1... | closed | 2021-02-09T03:50:56Z | 2021-02-19T06:09:36Z | https://github.com/lux-org/lux/issues/255 | [
"documentation"
] | vnnw | 2 |
laurentS/slowapi | fastapi | 32 | FastAPI 'RateLimitExceeded' is not defined | I am trying the FastAPI example and I get :
```
File "./basic.py", line 13, in <module>
app.add_exception_handler(RateLimitExceeded, _rate_limit_exceeded_handler)
NameError: name 'RateLimitExceeded' is not defined
```
Python 3.9
fastapi 0.63.0
slowapi 0.1.3 | closed | 2021-01-09T09:36:30Z | 2021-01-10T15:18:52Z | https://github.com/laurentS/slowapi/issues/32 | [] | vbrinza | 2 |
ydataai/ydata-profiling | jupyter | 1,530 | No module named 'ydata_profiling' | ### Current Behaviour
after installing ydata using the following command
conda install -c conda-forge ydata-profiling
I can use
from ydata_profiling import ProfileReport
in the python cmd window. However, in the jupyter notebook I get the
following error:
ModuleNotFoundError: No module named 'ydata_... | closed | 2024-01-26T05:31:03Z | 2024-09-06T02:33:35Z | https://github.com/ydataai/ydata-profiling/issues/1530 | [
"needs-triage"
] | makgul1 | 4 |
SYSTRAN/faster-whisper | deep-learning | 211 | CUDA out of memory error when iterating on segments | Hi @guillaumekln ,
I am trying out the code that you have shared and facing some trouble when iterating over the segments.
Getting a cuda out of memory error after a few iterations.
May I know what is the cause of this and how it can be fixed?
Since it is able to iterate over a few segments, are those segme... | closed | 2023-05-08T11:53:07Z | 2023-06-02T16:24:42Z | https://github.com/SYSTRAN/faster-whisper/issues/211 | [] | tusharagarwal25 | 4 |
python-restx/flask-restx | api | 159 | Not possible to use namespace.param() to specify the same parameter in different locations | ### **Code**
```python
@namespace.param(name="asdf", _in="query")
@namespace.param(name="asdf", _in="json")
```
### **Expected Behavior**
I would expect the above code to result in two parameters with two different locations. This should be possible b/c in openapi the parameters section is a list.
... | open | 2020-06-21T16:58:22Z | 2020-06-21T16:58:46Z | https://github.com/python-restx/flask-restx/issues/159 | [
"bug"
] | ColdHeat | 0 |
jonaswinkler/paperless-ng | django | 781 | Configure backend from frontend | It would be comfortable and better UX if I could configure the backend from the frontend (i.e. what I now can do with environment variables).
For one thing, it's easier to change it via a browser than to restart the docker container with a different set of env vars. Additionally, it's much easier to discover possible ... | open | 2021-03-16T09:48:52Z | 2021-03-24T11:38:16Z | https://github.com/jonaswinkler/paperless-ng/issues/781 | [
"feature request"
] | jonaswinkler | 7 |
Tanuki/tanuki.py | pydantic | 13 | Support for Gunicorn | Currently only Uvicorn is supported, and therefore this project doesn't support multiple worker threads. We should add support for Gunicorn to support that popular usecase. | open | 2023-10-30T11:59:13Z | 2023-10-30T11:59:13Z | https://github.com/Tanuki/tanuki.py/issues/13 | [] | JackHopkins | 0 |
ebhy/budgetml | fastapi | 8 | [BUG] | **Describe the bug**
A clear and concise description of what the bug is.
**To Reproduce**
Steps to reproduce the behavior:
1. Go to '...'
2. Click on '....'
3. Scroll down to '....'
4. See error
**Expected behavior**
A clear and concise description of what you expected to happen.
**Screenshots**
If applicable, add s... | closed | 2021-02-13T09:47:02Z | 2021-02-15T14:24:13Z | https://github.com/ebhy/budgetml/issues/8 | [] | aniket23456 | 2 |
keras-team/keras | tensorflow | 20,111 | Are the docs correct for the RNN description of `batch_shape` ? | [In the description the RNN it says](https://github.com/keras-team/keras/blob/933579d3c4a585f236982d05d3a74921f9567415/keras/src/layers/rnn/rnn.py#L105-L110) it says:
> If sequential model:
> `batch_input_shape=(...)` to the first layer in your model.
Yet seems that the parameter `batch_input_shape` w... | closed | 2024-08-11T07:43:09Z | 2024-08-14T17:10:11Z | https://github.com/keras-team/keras/issues/20111 | [
"type:support"
] | newresu | 5 |
HumanSignal/labelImg | deep-learning | 614 | Potentially wrong pip version in README.rst for MacOS Python 3 Virtualenv (line 100) | Followed instructions for Mac OS Python 3 Virtualenv (Recommended)
Ran the following without hiccups
```
brew install python3
pip3 install pipenv
```
Ran this command -> `pipenv run pip install pyqt5==5.13.2 lxml`
Got the following error:
```
Courtesy Notice: Pipenv found itself running within a virtual envi... | open | 2020-07-03T23:47:07Z | 2020-07-03T23:47:07Z | https://github.com/HumanSignal/labelImg/issues/614 | [] | RCAVelez | 0 |
widgetti/solara | jupyter | 466 | Formula symbols | Is there an overview that shows which objects support rendering of (LaTex) symbols?
I read that [Markdown](https://solara.dev/api/markdown) can be used, but I am looking for a way to label InputFloat and Button with formula symbols which does not seem to be supported.
Btw, #175 can be closed, couldn't it? | closed | 2024-01-15T16:46:04Z | 2024-01-25T08:10:52Z | https://github.com/widgetti/solara/issues/466 | [] | liebsc21 | 3 |
MaartenGr/BERTopic | nlp | 1,329 | Results after outliers reduction | Hi,
As you adviced, after outliers reduction I did:
`self.topic_model.update_topics(self.corpus, topics=self.new_topics)`
as a last step of my workflow. I realized that topic descriptions after updating topics contain stopwords. The KKeyBERT, MMR nad POS descriptions did not change. I tried to:
`self.topic_model.ge... | closed | 2023-06-09T18:38:18Z | 2023-06-10T06:19:29Z | https://github.com/MaartenGr/BERTopic/issues/1329 | [] | piotrcelinski | 2 |
DistrictDataLabs/yellowbrick | matplotlib | 1,211 | Diagnostic Plots for Linear Regression Analysis | If not already considered or being developed it would be neat to have some standard diagnostic plots for linear regression analysis mainly
a. residual vs fitted
b. normal q-q
c. scale-location
d. residual vs leverage
as shown in https://data.library.virginia.edu/diagnostic-plots/. Example plots
<img width="4... | open | 2022-01-25T09:56:08Z | 2022-05-21T18:36:09Z | https://github.com/DistrictDataLabs/yellowbrick/issues/1211 | [
"type: feature"
] | pkaf | 4 |
harry0703/MoneyPrinterTurbo | automation | 108 | APITimeoutError: Request timed out | 请问是我配置有问题吗?我这边可以科学上网的

openai的密钥也是设置了的

| closed | 2024-03-29T04:32:07Z | 2024-03-30T07:35:06Z | https://github.com/harry0703/MoneyPrinterTurbo/issues/108 | [] | gaoxinghua951 | 4 |
dynaconf/dynaconf | fastapi | 866 | [bug] vault loader API versions are incorrect | **Describe the bug**
vault_loader class issues:
When we try to get the data from the vault, the service runs the load function in vault_loader. For each HVAC version he should go to the specific version. Instead, it runs the wrong version.
when trying to run data = client.secrets.kv.read_secret(
... | open | 2023-02-12T14:02:37Z | 2023-08-21T19:42:52Z | https://github.com/dynaconf/dynaconf/issues/866 | [
"bug"
] | eladhaz05 | 2 |
scrapy/scrapy | web-scraping | 6,086 | scrapy first 3 crawled pages, save the information of the last crawled page | Hello evreyone, thanks for read my problem
I crawled the website information. I first visited a certain page of the website, and after obtaining the article URL, I combined the current article comment count with the article URL to access all the comment pages of each article.
But I encountered a problem. When crawlin... | closed | 2023-10-05T02:49:17Z | 2023-10-07T08:32:12Z | https://github.com/scrapy/scrapy/issues/6086 | [] | susan561234 | 2 |
BlinkDL/RWKV-LM | pytorch | 126 | Guidance/Feature request: Training or using RWKV or Rwkv-4-Raven for text summarization? | Hi!
Awesome work on RWKV!
Guidance/Feature request: Training or using RWKV or Rwkv-4-Raven for text summarization? | closed | 2023-05-25T06:35:09Z | 2023-06-14T03:45:30Z | https://github.com/BlinkDL/RWKV-LM/issues/126 | [] | DIGist | 1 |
plotly/dash-core-components | dash | 968 | `higlight_config` argument to `dcc.Markdown` has by default no effect in `dcc>=1.13` | As stated in the `dcc.Markdown` documentation (https://dash.plotly.com/dash-core-components/markdown) you can use
> highlight_config (dict; optional): Config options for syntax highlighting. highlight_config is a dict with keys:
> theme (a value equal to: 'dark', 'light'; optional): Color scheme; default 'ligh... | open | 2021-05-10T09:14:25Z | 2021-10-28T20:07:54Z | https://github.com/plotly/dash-core-components/issues/968 | [] | anders-kiaer | 2 |
jstrieb/github-stats | asyncio | 97 | Update README.md to reflect changes made by GitHub regarding generating a token | GitHub has made some changes to how tokens can now be generated. A new `fine-grained` token has been introduced supporting different options, while the token supporting the options referenced in the README.md is now named the `classic` token. | closed | 2023-05-02T06:51:00Z | 2025-03-09T17:09:23Z | https://github.com/jstrieb/github-stats/issues/97 | [] | R055A | 0 |
errbotio/errbot | automation | 934 | Flows don't send the message of the last step return | * [ ] Reporting a bug
When trying to Make a step execute automatically errbot would execute the command
'second' but would not return the message in the chat
### I am running...
* Errbot version: 4.2.2
* OS version: CenOS 6.8
* Python version: 2.7
* Using a virtual environment: yes
### Issue description
T... | open | 2016-12-16T15:42:28Z | 2019-06-18T13:30:51Z | https://github.com/errbotio/errbot/issues/934 | [
"type: bug",
"feature: Flows"
] | CyberRoute | 2 |
proplot-dev/proplot | matplotlib | 356 | Plotting stuff example gives `ValueError' | I'm learning proplot according to the documents. When trying [Plotting stuff](https://proplot.readthedocs.io/en/latest/basics.html#Plotting-stuff) example, it gives a `ValueError: DiscreteNorm is not invertible.`
My maplotlib and proplot version are as follows:
```python
In [1]: matplotlib.__version__
Out[1]: '... | closed | 2022-04-23T14:10:54Z | 2023-03-29T05:45:02Z | https://github.com/proplot-dev/proplot/issues/356 | [
"bug"
] | chenyulue | 1 |
art049/odmantic | pydantic | 468 | `key_name` doesn't work when field is `id` | # Bug
`key_name` doesn't work when `id`
### Current Behavior
```python
class Project(Model):
id: str = Field(unique=True, key_name="project_id")
```
TypeError: can't automatically generate a primary field since an 'id' field already exists
```
Traceback (most recent call last):
File "D:\Python... | open | 2024-05-01T03:02:40Z | 2024-10-30T12:24:13Z | https://github.com/art049/odmantic/issues/468 | [
"bug"
] | z0z0r4 | 3 |
open-mmlab/mmdetection | pytorch | 12,287 | A bug feedback about assertions (Level: warning) | edition: mmdet v3.3.0, Version hash code: af063a6
Location: mmdet.datasets.transforms.geometric.py:: line 85-93
contents:
```
assert isinstance(min_mag, float), \
f'min_mag should be type float, got {type(min_mag)}.'
assert isinstance(max_mag, float), \
f'max_mag should be type float, got {type(max_mag)... | open | 2025-01-09T05:55:13Z | 2025-01-09T07:23:53Z | https://github.com/open-mmlab/mmdetection/issues/12287 | [] | name-used | 1 |
dropbox/PyHive | sqlalchemy | 75 | Allow inputting passwords to hive connection | Hello all!
I was wondering why there is no fields or parameters to put in the passwords when we are connecting to hive server? I think it's something that pyhive could easily support.. Maybe I missed it but I could not figure out :p
If there is a workaround, please tell me how. Otherwise, I can work on adding that f... | closed | 2016-07-22T16:01:58Z | 2016-07-22T20:27:58Z | https://github.com/dropbox/PyHive/issues/75 | [] | dighjd12 | 2 |
AirtestProject/Airtest | automation | 411 | 图片匹配的RGB模式不起作用 | **描述问题bug**
图片匹配的RGB模式不起作用
checkbox按钮,安亮后是蓝色,否则是灰色。
RGB模式的图片查找,并不能区别按钮颜色的变化
**相关截图**
按钮未点亮时,选择第一个按钮
$ git pull
$ python demo-model.py
INFO: Started server process [23792]
INFO: Waiting for application startup.
INFO: Application startup complete.
INFO: Uvicorn running on http://127.0.0.1:8000 (Press CTRL+C to quit)
INFO: 127.0.0.1:13268 - "GET / HTTP/1.1" 404 N... | closed | 2022-04-26T08:30:54Z | 2022-04-26T08:53:41Z | https://github.com/amisadmin/fastapi-amis-admin/issues/20 | [] | wanghaisheng | 2 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 741 | How long do my voice recordings need to be for it to sound good and can there be background noise or anything? How long do my voice recordings need to be and can there be background noise or anything else? | closed | 2021-04-22T12:36:37Z | 2021-04-22T20:15:55Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/741 | [] | KiwoNtV | 1 | |
graphdeco-inria/gaussian-splatting | computer-vision | 628 | Some bugs in getProjectionMatrix() | It seems that there are some bugs in `getProjectionMatrix()` according to http://www.songho.ca/opengl/gl_projectionmatrix.html.
I understand that we never use the normalized z value anywhere, but it would be better to learn from the source code if these bugs could be fixed.
https://github.com/graphdeco-inria/gaus... | closed | 2024-01-23T08:40:27Z | 2024-04-18T09:33:01Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/628 | [] | chenguolin | 2 |
horovod/horovod | deep-learning | 3,244 | pytorch_lightning_mnist.py example is not working with GPU | **Environment:**
torch==1.7.1
pytorch-lightning==1.3.8
horovod==master branch
**Bug report:**
Reproduce with `horovodrun -np 1 -H agent11240-phx4:1 python pytorch_lightning_mnist.py --epochs 1`
It fails in test step since model weights are on cpu:
```
Epoch 0: 100% 946/948 [00:10<00:00, 86.76it/s, loss=0.438,... | closed | 2021-10-27T22:14:39Z | 2021-10-28T15:26:04Z | https://github.com/horovod/horovod/issues/3244 | [
"bug"
] | chongxiaoc | 0 |
deepspeedai/DeepSpeed | pytorch | 5,649 | Install issue with setuptools 70 | ## When I install deepspeed
> pip install deepspeed
I got the error
```shell
Collecting deepspeed
Using cached http://xxxx/pypi/packages/deepspeed/0.14.2/deepspeed-0.14.2.tar.gz (1.3 MB)
Preparing metadata (setup.py) ... error
error: subprocess-exited-with-error
× python setup.py egg_info did ... | closed | 2024-06-12T13:19:14Z | 2024-06-13T08:38:52Z | https://github.com/deepspeedai/DeepSpeed/issues/5649 | [
"bug",
"deepspeed-chat"
] | myBigbug | 2 |
piskvorky/gensim | data-science | 3,127 | AttributeError: 'Doc2Vec' object has no attribute 'dv’ | #### Problem description
A simple call to model.docvecs.most_similar results in an error. Seems to have forgotten about 'dv' as model.dv.most_similar results in a similar error:
```
DeprecationWarning: Call to deprecated `docvecs` (The `docvecs` property has been renamed `dv`.).
model.docvecs.most_similar(app... | open | 2021-04-27T06:30:15Z | 2023-12-12T15:16:40Z | https://github.com/piskvorky/gensim/issues/3127 | [
"bug",
"need info",
"impact HIGH",
"reach MEDIUM"
] | sagol | 28 |
jacobgil/pytorch-grad-cam | computer-vision | 12 | Why the results were different after each run? | I implemented grad-cam with a program from another project (using tensorflow to train my own data), but the results were different after each run. Have you ever experienced this?
Your help is very important to me. I hope to receive your reply. | closed | 2018-09-17T03:30:12Z | 2018-11-25T19:23:31Z | https://github.com/jacobgil/pytorch-grad-cam/issues/12 | [] | hydxqing | 1 |
abhiTronix/vidgear | dash | 100 | SSL: CERTIFICATE_VERIFY_FAILED with YouTube Mode in CamGear on macOS | <!--
Please note that your issue will be fixed much faster if you spend about
half an hour preparing it, including the exact reproduction steps and a demo.
If you're in a hurry or don't feel confident, it's fine to report bugs with
less details, but this makes it less likely they'll get fixed soon... | closed | 2020-01-20T13:04:30Z | 2020-01-29T05:30:14Z | https://github.com/abhiTronix/vidgear/issues/100 | [
"SOLVED :checkered_flag:",
"EXTERNAL BUG :space_invader:"
] | abhiTronix | 1 |
streamlit/streamlit | data-visualization | 10,550 | Discrepancy of selectbox value in AppTest | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
Hi, great project - keep up the great work!
... | open | 2025-02-27T22:12:38Z | 2025-03-03T14:02:33Z | https://github.com/streamlit/streamlit/issues/10550 | [
"type:enhancement"
] | ams1 | 4 |
AirtestProject/Airtest | automation | 528 | 咱们的ide后续会考虑开源嘛? | 咱们的ide后续会考虑开源嘛? | closed | 2019-09-14T07:52:35Z | 2019-09-15T07:22:30Z | https://github.com/AirtestProject/Airtest/issues/528 | [] | shuyabin | 1 |
huggingface/datasets | computer-vision | 6,603 | datasets map `cache_file_name` does not work | ### Describe the bug
In the documentation `datasets.Dataset.map` arg `cache_file_name` is said to be a string, but it doesn't work.
### Steps to reproduce the bug
1. pick a dataset
2. write a map function
3. do `ds.map(..., cache_file_name='some_filename')`
4. it crashes
### Expected behavior
It will tell you t... | open | 2024-01-18T23:08:30Z | 2024-01-28T04:01:15Z | https://github.com/huggingface/datasets/issues/6603 | [] | ChenchaoZhao | 2 |
google-research/bert | tensorflow | 665 | Why was use_one_hot_embeddings set to FLAG.use_tpu in line 855 in run_classifier.py ? | In line 847 to line 855 in run_classifier.py, the code is as follows:
` model_fn = model_fn_builder(
bert_config=bert_config,
num_labels=len(label_list),
init_checkpoint=FLAGS.init_checkpoint,
learning_rate=FLAGS.learning_rate,
num_train_steps=num_train_steps,
num_warmup_step... | open | 2019-05-26T07:25:27Z | 2019-05-27T08:28:34Z | https://github.com/google-research/bert/issues/665 | [] | chiaminchuang | 1 |
LibrePhotos/librephotos | django | 537 | 2 scolling bars on "faces recognition" page | In bug report #517 I noted that there was some problem to see scrolling bar with dark mode in faces recognition page. I understand a bit more now.
On that picture (standard mode) you can see that 2 scrolling bars are present on the right of the screen. A thin one and a large one. And only the thin one is usable.
 and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
I got an issue when I try to convert to tflite.
python.exe export.py --data="models/yolo... | closed | 2023-11-29T07:07:09Z | 2023-12-04T16:59:29Z | https://github.com/ultralytics/yolov5/issues/12440 | [
"question"
] | sinnuswong | 4 |
flaskbb/flaskbb | flask | 407 | Exception when cliking on "edit" user | As admin, when I click on "edit" in the user list, I get "Server error" in the browser and the following Exception in the logs:
[2018-02-05 06:48:15,058] ERROR in app: Exception on /admin/users/4/edit [GET]
Traceback (most recent call last):
File "/usr/local/lib/python3.6/site-packages/flask_themes2/__init__.... | closed | 2018-02-05T06:54:02Z | 2018-04-15T07:47:50Z | https://github.com/flaskbb/flaskbb/issues/407 | [
"bug"
] | ghislainp | 10 |
seleniumbase/SeleniumBase | pytest | 3,160 | Could not start a new session. Response code 500. Message: session not created: Chrome failed to start: exited normally. (session not created: DevToolsActivePort file doesn't exist) | package pcm;
import java.io.File;
import java.io.FileInputStream;
import java.io.IOException;
import java.time.Duration;
import java.util.List;
import java.util.Properties;
import org.openqa.selenium.chrome.ChromeOptions;
import org.apache.commons.compress.compressors.FileNameUtil;
import org.apache.commons.... | closed | 2024-09-23T07:25:08Z | 2024-09-23T12:42:25Z | https://github.com/seleniumbase/SeleniumBase/issues/3160 | [
"invalid"
] | yash2880 | 1 |
charlesq34/pointnet | tensorflow | 10 | Cannot run train.py in part_seg | Hi,
I'm currently running the PointNet code. However, I cannot run train.py in part_seg as mentioned in the "README". Also there seems to be bugs in the code -- I myself fixed some. Is this code the final one? It seems like this is not the complete or even wrong version.
Thanks,
Yiru | closed | 2017-05-10T01:01:38Z | 2018-05-23T13:50:44Z | https://github.com/charlesq34/pointnet/issues/10 | [] | YiruS | 2 |
pydantic/bump-pydantic | pydantic | 59 | Syntax error with built in library (multiprocessing) | Trying to run bump-pydantic with rocketry library which uses multiprocessing, and then this error caused by something inside multiprocessing.
Can't understand much what's going on based on error's output.
```
manimozaffar@Manis-MacBook-Pro-2 rocketry % bump-pydantic rocketry
RemoteTraceback:
"""
Traceba... | closed | 2023-07-08T09:34:46Z | 2023-07-10T14:03:55Z | https://github.com/pydantic/bump-pydantic/issues/59 | [] | ManiMozaffar | 5 |
scrapy/scrapy | web-scraping | 6,291 | AttributeError: 'Decompressor' object has no attribute 'process' | ### Description
I am getting an error from running the demo example. `AttributeError: 'Decompressor' object has no attribute 'process'`. It. looks like it is an internal library to `scrapy`.
### Steps to Reproduce
I am using the demo example from the website: https://scrapy.org/
Create the file: `myspider.... | closed | 2024-03-13T20:57:46Z | 2024-03-13T22:15:46Z | https://github.com/scrapy/scrapy/issues/6291 | [] | phillipshaong | 1 |
sgl-project/sglang | pytorch | 3,752 | [Bug] sglang encounter Watchdog timeout error | ### Checklist
- [x] 1. I have searched related issues but cannot get the expected help.
- [x] 2. The bug has not been fixed in the latest version.
- [x] 3. Please note that if the bug-related issue you submitted lacks corresponding environment info and a minimal reproducible demo, it will be challenging for us to repr... | open | 2025-02-21T09:06:02Z | 2025-03-18T06:03:43Z | https://github.com/sgl-project/sglang/issues/3752 | [] | wangdaw2023 | 8 |
dmlc/gluon-cv | computer-vision | 1,315 | mxnet 2.0 commit may cause faster rcnn and mask rcnn cannot be trained | https://github.com/apache/incubator-mxnet/pull/17749
This commit may cause rcnn/mask-rcnn cannot be trained.
https://github.com/dmlc/gluon-cv/blob/3c4150a964c776e4f7da0eb30b55ab05b7554c8d/gluoncv/data/transforms/presets/rcnn.py#L162 | closed | 2020-05-23T01:19:25Z | 2021-05-22T06:40:50Z | https://github.com/dmlc/gluon-cv/issues/1315 | [
"Stale"
] | chinakook | 1 |
oegedijk/explainerdashboard | plotly | 105 | Improvement: Ability to use other backends besides Flask f.ex. FastAPI | Hi I'm playing with deployment of ExplainerDashboard. Would it be possible to support other backends besides Flask in the future. F.ex. I want to deploy to GCP and use oauth so I had a previous FastAPI script as a base with implemented oauth. But eventhough I can deploy the ExplainerHub with this although the hub itsel... | closed | 2021-03-30T07:26:41Z | 2023-07-06T14:42:36Z | https://github.com/oegedijk/explainerdashboard/issues/105 | [] | jruokolainen | 10 |
explosion/spaCy | deep-learning | 13,231 | Incorrect lemmatization | <!-- NOTE: For questions or install related issues, please open a Discussion instead. -->
I was running the sentence `"Folgst du der Weser weiter, fährst du durch das Oldenburger Land, wo du eindrucksvolle Naturschutzgebiete, Wälder und Moore erlebst, bis du nach Nordenham gelangst."` through spacy and noticed that `"... | closed | 2024-01-10T22:32:14Z | 2024-02-15T00:02:17Z | https://github.com/explosion/spaCy/issues/13231 | [
"lang / de",
"models",
"feat / lemmatizer",
"perf / accuracy"
] | msal4 | 2 |
ydataai/ydata-profiling | pandas | 1,618 | ModuleNotFoundError: No module named 'pkg_resources' | ### Current Behaviour
Thanks for the great repository!
Currently fails on the import with
```python
import ydata_profilling
```
Resulting in:
```
Traceback (most recent call last):
File "c:\Users\foo\test.py", line 9, in <module>
import ydata_profiling
File "C:\Users\foo\AppData\Local\pypoe... | open | 2024-07-12T09:32:44Z | 2024-11-15T10:35:08Z | https://github.com/ydataai/ydata-profiling/issues/1618 | [
"information requested ❔"
] | abdrysdale | 3 |
holoviz/panel | matplotlib | 6,852 | Tabulator inputs trigger keyboard shortcuts | I'm experiencing the same issue as discussed in #6314, but only limited to Tabulator inputs
#### ALL software version info
Panel 1.4.2
JupyterLab 4.1.6
#### Description of expected behavior and the observed behavior
Expecting to enter any numbers without issues.
In reality, if I try to write numbers into ta... | closed | 2024-05-19T18:45:15Z | 2024-05-20T11:46:35Z | https://github.com/holoviz/panel/issues/6852 | [] | eaglesemanation | 1 |
mwaskom/seaborn | data-science | 2,923 | scipy links in documentation are broken | I have been looking into the documentation for [`seaborn.clustermap`](https://seaborn.pydata.org/generated/seaborn.clustermap.html#seaborn.clustermap) since I need to understand some details of that, and it appears that the links to the underlying scipy methods are broken. I can't find the documentation here on github,... | closed | 2022-07-25T05:46:04Z | 2022-07-25T22:28:12Z | https://github.com/mwaskom/seaborn/issues/2923 | [] | joha1 | 3 |
Miksus/rocketry | pydantic | 191 | @app.task('daily.at("21:00") before Friday') | **Describe the bug**
above statements results in rocketry.parse.utils.exception.ParserError: Could not find parser for string 'daily.at'.
**To Reproduce**
Steps to reproduce the behavior.
**Expected behavior**
Statement should run every MO,TUE,WED,THUR,FRI at 21:00
**Desktop (please complete the following inf... | open | 2023-02-09T10:34:58Z | 2023-02-09T13:44:12Z | https://github.com/Miksus/rocketry/issues/191 | [
"bug"
] | faulander | 1 |
jupyterhub/repo2docker | jupyter | 545 | Emit an EXPOSE entry for ports specified in -p to repo2docker | Primarily as documentation in the built image rather than anything particularly useful for repo2docker itself. However, we have to remember that ports are really a runtime parameter, and make sure we think about caching issues with adding an EXPOSE.
Split from https://github.com/jupyter/repo2docker/issues/533#issuec... | open | 2019-01-05T20:55:52Z | 2021-05-17T20:44:31Z | https://github.com/jupyterhub/repo2docker/issues/545 | [
"enhancement"
] | yuvipanda | 3 |
ivy-llc/ivy | numpy | 28,216 | Fix Ivy Failing Test: tensorflow - shape.shape__bool__ | closed | 2024-02-07T18:30:06Z | 2024-02-09T09:27:04Z | https://github.com/ivy-llc/ivy/issues/28216 | [
"Sub Task"
] | fnhirwa | 0 | |
yihong0618/running_page | data-visualization | 12 | One thought, share your running page | One thought.
If you want to share your own running homepage, you can generate it and write the URL in the readme, then submit pr and I'll merge it. | open | 2020-10-13T05:22:12Z | 2025-03-24T07:31:04Z | https://github.com/yihong0618/running_page/issues/12 | [
"user-demo"
] | yihong0618 | 87 |
flairNLP/flair | nlp | 3,614 | [Bug]: `identify_dynamic_embeddings` does not work for `DataPair` | ### Describe the bug
The training util `identify_dynamic_embeddings` does not look properly at the embeddings for the `first` and `second`. It probably makes more sense to have a member function for each `DataPoint` class, instead of checking `isinstance` within an external function. There could still be an outer func... | open | 2025-02-07T19:04:14Z | 2025-02-07T19:04:14Z | https://github.com/flairNLP/flair/issues/3614 | [
"bug"
] | MattGPT-ai | 0 |
sqlalchemy/sqlalchemy | sqlalchemy | 10,139 | immediateload is leaking an internal symbol | ### Discussed in https://github.com/sqlalchemy/sqlalchemy/discussions/10138
this is super weird, so, figure out what this is
```py
import asyncio
from typing import Optional
import sqlalchemy as sa
import sqlalchemy.ext.asyncio as sa_async
import sqlalchemy.orm as orm
Base = orm.declarative_base()
... | closed | 2023-07-24T23:29:31Z | 2023-07-29T03:09:04Z | https://github.com/sqlalchemy/sqlalchemy/issues/10139 | [
"bug",
"orm",
"loader options",
"asyncio",
"near-term release"
] | zzzeek | 1 |
tflearn/tflearn | data-science | 649 | IndexError: list index out of range using the minimal example from README.md | While using this code (to re-create):
+ I am using `tf 1.0.0`
+ Docker image: `jupyter/datascience-notebook` plus tf conda-installed
```
from sklearn.preprocessing import LabelEncoder
from keras.utils import np_utils
labels = ['Male', 'Female'] * 5
encoder = LabelEncoder()
encoder.fit(labels)
labels = encoder... | open | 2017-03-05T08:45:17Z | 2017-05-14T12:14:19Z | https://github.com/tflearn/tflearn/issues/649 | [] | jakubLangr | 4 |
tpvasconcelos/ridgeplot | plotly | 197 | Importing ridgeplot fails with scipy 1.14.1 with "symbol not found in flat namespace '_npy_cabs'" | This is more of an FYI for visibility than an issue that needs action, but importing ridgeplot fails when using scipy 1.14.1 ("symbol not found in flat namespace '_npy_cabs'")
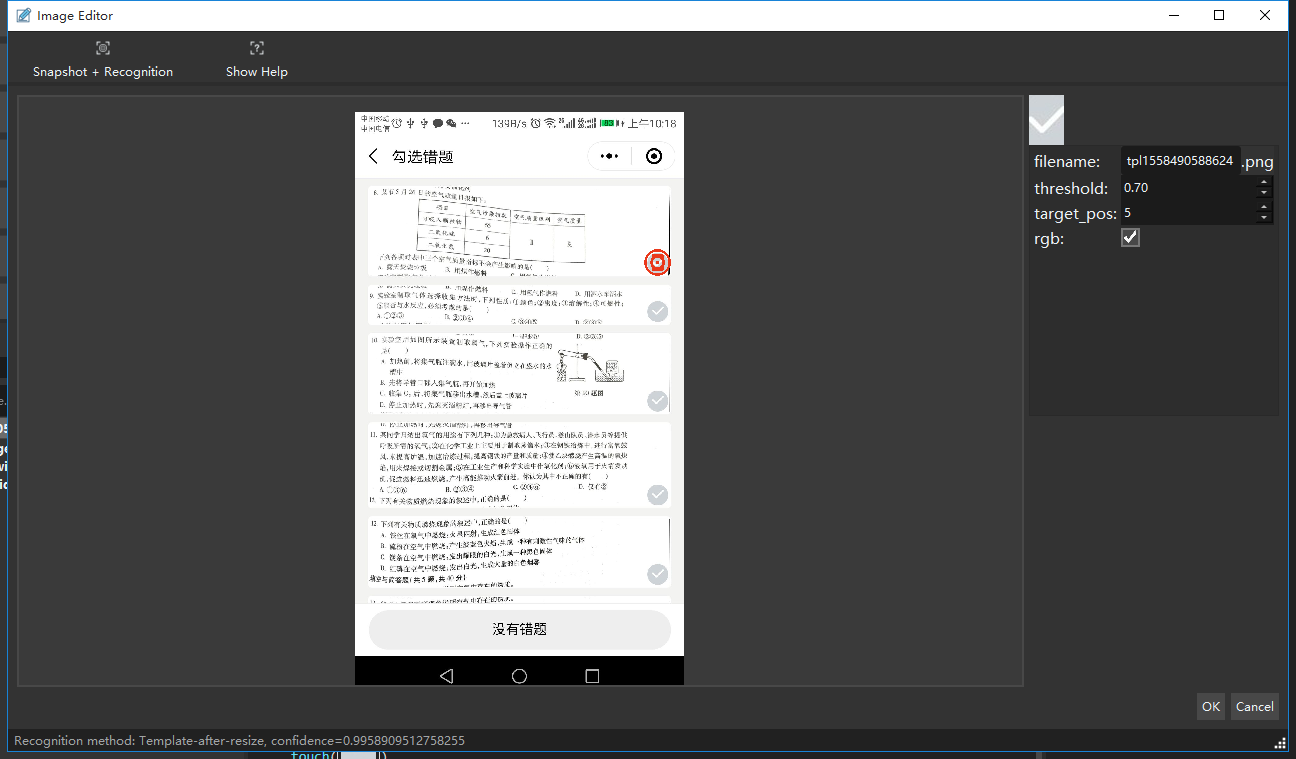
Issue has been raised with scipy maintainers: https://github.com/scipy/scipy/issues/21434
I'm on Mac OS 14.6.1, Python 3.10.14. Downgradin... | closed | 2024-09-16T16:12:17Z | 2024-10-08T10:19:11Z | https://github.com/tpvasconcelos/ridgeplot/issues/197 | [
"good first issue",
"dependencies"
] | cduvallet | 5 |
hbldh/bleak | asyncio | 1,531 | NoneType error when calling client.pair() on Android | * bleak version: 0.21.1
* Python version: 3.11
* Operating System: Android 13
* BlueZ version (`bluetoothctl -v`) in case of Linux:
### Description
The p4android backend seem to have a bug in the BleakClientP4Android.pair() method.
When called, the function is working but always crash with the exception `Typ... | open | 2024-03-29T15:32:34Z | 2024-04-28T23:58:26Z | https://github.com/hbldh/bleak/issues/1531 | [
"bug",
"Backend: Android"
] | skywodd | 1 |
MilesCranmer/PySR | scikit-learn | 44 | How force algorithm make an equation with all inputs? | Hi,
I used the algorithm its unique and fine, but I have a problem,
I.e I have some data, **including 1000 row, and 4 columns**, it has **3 inputs (x1,x2,x3)** and one **output (y)** when I run the algorithm it makes an equation like: **y=10*x1+2*x3** , (it just includes x1 and x3)
The problem is that the result e... | closed | 2021-05-11T22:33:20Z | 2021-06-19T19:48:27Z | https://github.com/MilesCranmer/PySR/issues/44 | [] | danial1995 | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.