
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
wandb/wandb | data-science | 8,952 | [Feature]: Change the way to get `local_image_sha` | ### Description
When we call `wandb server start`, the `wandb.docker.image_id` function was called to get the `local_image_sha`. It works if I just pull the image from docker. But once I use docker save and docker load to deploy the wandb server (no internet avaliable that can not pull image), the `RepoDigests` field ... | closed | 2024-11-27T02:47:58Z | 2024-11-27T15:04:17Z | https://github.com/wandb/wandb/issues/8952 | [
"ty:feature"
] | ease-zh | 1 |
Nemo2011/bilibili-api | api | 283 | [需求] 一次性获取多个资源信息 | 见 https://github.com/Nemo2011/bilibili-api/issues/273
有这样的接口吗?没找到......
https://api.bilibili.com/x/v3/fav/resource/infos?resources=483975876:2,780365689:2
在思考除了视频为2以外的其他类型参数,以及是否有必要加入此接口 | open | 2023-05-12T14:07:56Z | 2023-08-16T15:57:44Z | https://github.com/Nemo2011/bilibili-api/issues/283 | [
"need",
"feature",
"GUGU"
] | z0z0r4 | 0 |
dsdanielpark/Bard-API | api | 160 | Crash in new released version | AttributeError: 'Bard' object has no attribute 'google_translator_api_key'
if self.google_translator_api_key is not None:
File "/usr/local/lib/python3.9/site-packages/bardapi/core.py", line 107, in get_answer
b = bard.get_answer(text)
File "/app/helpers/bard.py", line 20, in chatbard
t = ... | closed | 2023-08-09T14:03:28Z | 2023-08-10T10:54:45Z | https://github.com/dsdanielpark/Bard-API/issues/160 | [] | Yorddyyorddy | 5 |
trevorstephens/gplearn | scikit-learn | 283 | const_range error | <!-- Thanks for contributing to gplearn!
Please ensure you have taken a look at the contribution guidelines:
https://gplearn.readthedocs.io/en/stable/contributing.html -->
**Describe the bug**
<!-- A clear and concise description of what the bug is.-->if I set the parameter--const_range as (-1.0,1.0), then when I... | closed | 2022-11-24T07:38:15Z | 2022-11-25T01:06:25Z | https://github.com/trevorstephens/gplearn/issues/283 | [
"bug"
] | geli666 | 6 |
allenai/allennlp | data-science | 4,716 | Docstring for AllenNlpTestCase is out-of-date | https://github.com/allenai/allennlp/blob/ae7cf85b8f755f086341a087aeca1ba7c1df3769/allennlp/common/testing/test_case.py#L14
This docstring suggests that the TestCase class should subclass `unittest.TestCase` but it does not do so. Should this be updated or is this intentional? | closed | 2020-10-07T18:45:07Z | 2020-10-12T17:07:00Z | https://github.com/allenai/allennlp/issues/4716 | [
"Good First Issue",
"Contributions welcome"
] | nicolasahar | 2 |
AUTOMATIC1111/stable-diffusion-webui | deep-learning | 15,892 | [Bug]: partially initialized module 'modules.sd_samplers_common' has no attribute 'SamplerData' (most likely due to a circular import) | ### Checklist
- [ ] The issue exists after disabling all extensions
- [ ] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [ ] The issue exists in the current version of the webui
- [X] The issue has not been reported before... | closed | 2024-05-26T11:57:36Z | 2024-05-29T14:28:38Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15892 | [
"bug-report"
] | sunsn1997 | 1 |
ultralytics/ultralytics | python | 18,825 | AutoBatch not working with rtdetr model | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and found no similar bug report.
### Ultralytics YOLO Component
Train
### Bug
Autobatch is not working with RTDETR model.
```log
TensorBoard: Start with 'tensorboard --logdir runs/detec... | closed | 2025-01-22T12:31:58Z | 2025-02-03T14:24:23Z | https://github.com/ultralytics/ultralytics/issues/18825 | [
"bug",
"detect"
] | DUPASYoann | 3 |
pyjanitor-devs/pyjanitor | pandas | 751 | [TST] Investigate Windows Build | # Brief Description
The Windows build never fails when it should. #738 comments out the windows build in `.azure-pipelines/pipeline-master.yml` so that it doesn't run until properly debugged.
# Notes
- This issue is a placeholder for reminding the dev team to debug the windows build.
| open | 2020-09-18T01:12:42Z | 2020-09-18T21:15:01Z | https://github.com/pyjanitor-devs/pyjanitor/issues/751 | [
"good intermediate issue",
"available for hacking",
"infrastructure",
"good advanced issue",
"hacktoberfest"
] | loganthomas | 0 |
chezou/tabula-py | pandas | 53 | Repeating headers | # Summary of your issue
I have the same table continuing on multiple pages and on each page the header is written again.
This makes sense in a pdf format, but not in a csv.
Is there a way so that it ignores the headers and only converts the table?
For example, convert_without_header=True
| closed | 2017-09-05T14:15:02Z | 2019-02-11T13:40:21Z | https://github.com/chezou/tabula-py/issues/53 | [
"enhancement"
] | pranali3215 | 4 |
getsentry/sentry | django | 87,686 | [Flaky CI]: AssertionError: assert {'id': 25, 'i...d': None, ...} == {'integration...y': None, ...} | ### Flakiness Type
Assertion failure
### Name of Job
backend
### Name of Test
tests/sentry/workflow_engine/handlers/action/notification/test_metric_alert.py::TestBaseMetricAlertHandler::test_invoke_legacy_registry
### Link to Test Run
https://github.com/getsentry/sentry/actions/runs/13954892986/job/39063431349
... | open | 2025-03-23T16:41:40Z | 2025-03-23T16:42:00Z | https://github.com/getsentry/sentry/issues/87686 | [
"Type: CI Flakiness",
"Product Area: Alerts"
] | bc-sentry | 1 |
numpy/numpy | numpy | 28,400 | BUG: numpy.histogram tries to allocate 98TB of memory with bins="auto" | ### Describe the issue:
For some data arrays, `np.histogram` tries to allocate absurd amount of memory and crashes. This happens with `bins = "auto"` and supposedly is a result of miscalculation of required number of bins.
### Reproduce the code example:
```python
import numpy as np
Z = np.array(
[
1.9... | closed | 2025-02-27T16:26:34Z | 2025-03-17T07:39:33Z | https://github.com/numpy/numpy/issues/28400 | [
"00 - Bug"
] | ilyapopov | 5 |
flaskbb/flaskbb | flask | 530 | demo not working | Fix demo page https://test.flaskbb.org/
502 Bad Gateway
| closed | 2019-07-28T21:26:51Z | 2019-10-09T06:54:48Z | https://github.com/flaskbb/flaskbb/issues/530 | [
"wontfix"
] | ghost | 1 |
JaidedAI/EasyOCR | machine-learning | 805 | Unicode decoder issue | When we are translating the pdf or txt file it will give the error Unicode decoder. The language i am trying is Bulgarian right now. | open | 2022-07-30T06:05:22Z | 2022-07-30T06:05:22Z | https://github.com/JaidedAI/EasyOCR/issues/805 | [] | divyeshvora2007 | 0 |
piskvorky/gensim | data-science | 3,342 | cleanup of vestigial `Morfessor`, `Varembed`, `gensim.models.wrapper(s)` references? | #### Problem description
I noticed that usage of Morfessor has mostly been removed, but there are some vestigial references to it in a few files. I would just submit a pull request for this, but I'm not sure if the files that reference Morfessor (especially as `.travis.yml`) should just get removed or kept and updat... | closed | 2022-05-05T01:29:42Z | 2022-05-05T13:41:55Z | https://github.com/piskvorky/gensim/issues/3342 | [] | pabs3 | 7 |
ydataai/ydata-profiling | data-science | 1,015 | Exception in thread ExecutorManagerThread: | ### Current Behaviour
I get the following error because I more than 63 core on my machine and I don't see option to pass max n_job in pandas_profiling
Thanks
```
Exception in thread ExecutorManagerThread:
Traceback (most recent call last):
File "C:\Users\User\anaconda3\lib\threading.py", line 973, in _boo... | open | 2022-07-29T06:18:36Z | 2023-01-11T02:55:44Z | https://github.com/ydataai/ydata-profiling/issues/1015 | [
"bug 🐛"
] | dansleboby | 2 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,156 | UC(3.4.6) No such file or directory: '/root/.local/share/undetected_chromedriver/undetected/chromedriver' | Hi,
Thanks in advance for supporting a great library. I just installed this library (latest version) in the linux server. But, I'm getting this error when I try to run `UC.Chrome`:

```
FileNotFoundEr... | closed | 2023-03-25T07:51:56Z | 2023-03-31T04:03:27Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1156 | [] | soft-top-notch | 7 |
mckinsey/vizro | plotly | 235 | Consider using dbc components to enable dbc.themes | ### What's the problem this feature will solve?
Following up on: https://github.com/mckinsey/vizro/pull/205#issuecomment-1866195799
Currently, the dashboard looks off if people try to add their [dbc.themes ](https://dash-bootstrap-components.opensource.faculty.ai/docs/themes/) as external stylesheets as our compo... | open | 2023-12-21T13:20:40Z | 2023-12-23T22:27:27Z | https://github.com/mckinsey/vizro/issues/235 | [
"Feature Request :nerd_face:"
] | huong-li-nguyen | 3 |
laurentS/slowapi | fastapi | 233 | poetry install slowapi Error | **Describe the bug**
I tried using Poetry to install SlowAPI in Python 3.11, but it got an error message...
```shell
(p:\LexTrade\backend\.conda) PS P:\LexTrade\backend> poetry add slowapi
Using version ^0.1.9 for slowapi
Updating dependencies
Resolving dependencies... (0.0s)
The current project's supported Python ... | open | 2025-02-27T20:44:28Z | 2025-03-16T09:41:41Z | https://github.com/laurentS/slowapi/issues/233 | [] | xcenweb | 1 |
pykaldi/pykaldi | numpy | 279 | Failed to install pykaldi | I followed the instructions and ran the following to commands to install pykaldi:
```
git clone https://github.com/pykaldi/pykaldi.git
cd pykaldi
sudo apt-get install autoconf automake cmake curl g++ git graphviz libatlas3-base libtool make pkg-config subversion unzip wget zlib1g-dev
sudo apt install intel-mkl-6... | open | 2021-06-20T10:38:43Z | 2022-02-07T11:27:33Z | https://github.com/pykaldi/pykaldi/issues/279 | [] | soroushhashemifar | 3 |
waditu/tushare | pandas | 1,693 | 指数-同花顺概念和行业指数 | 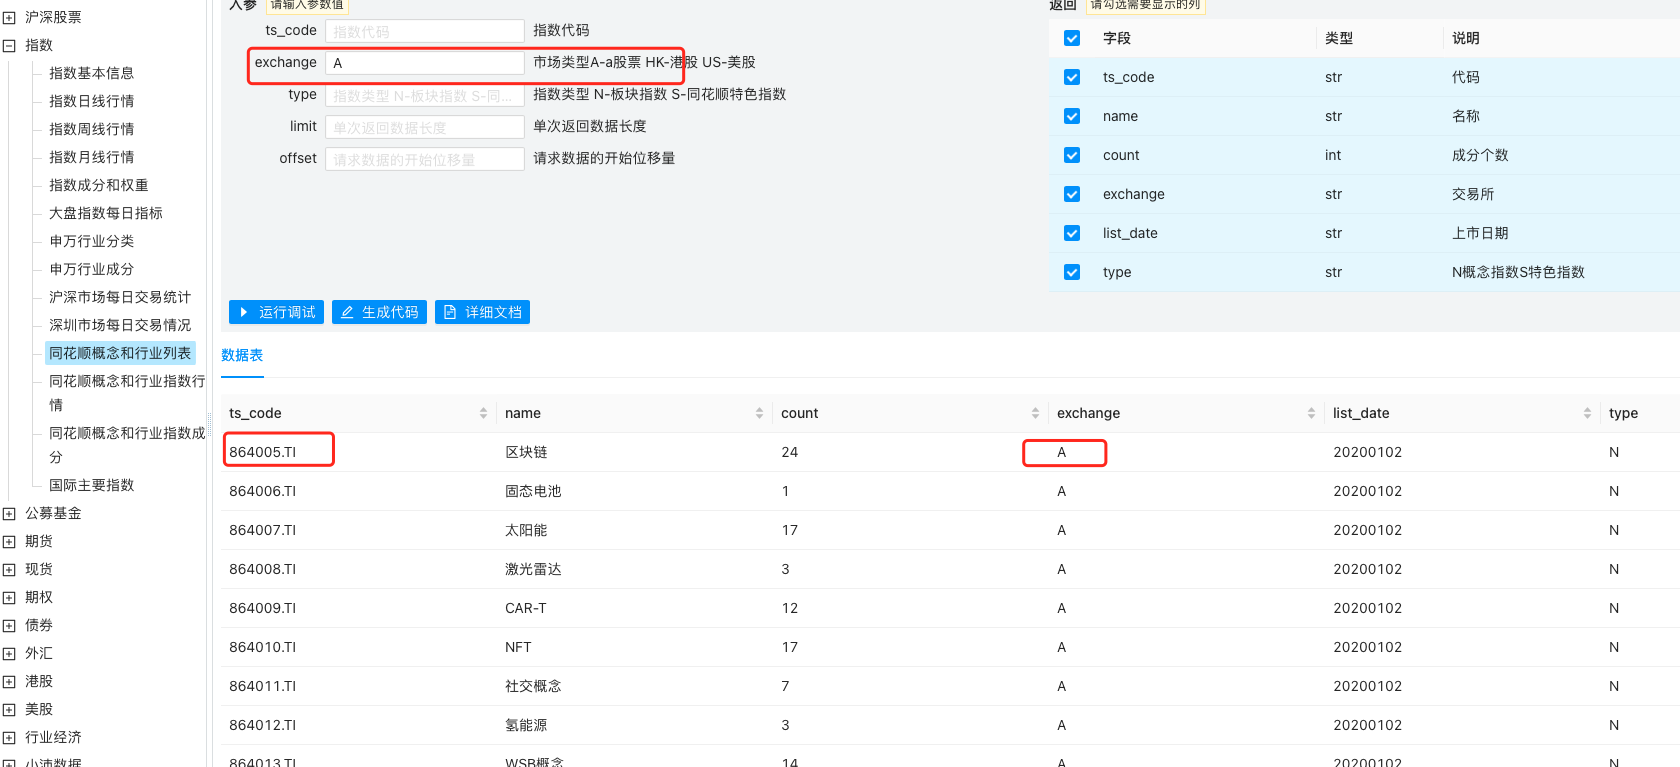
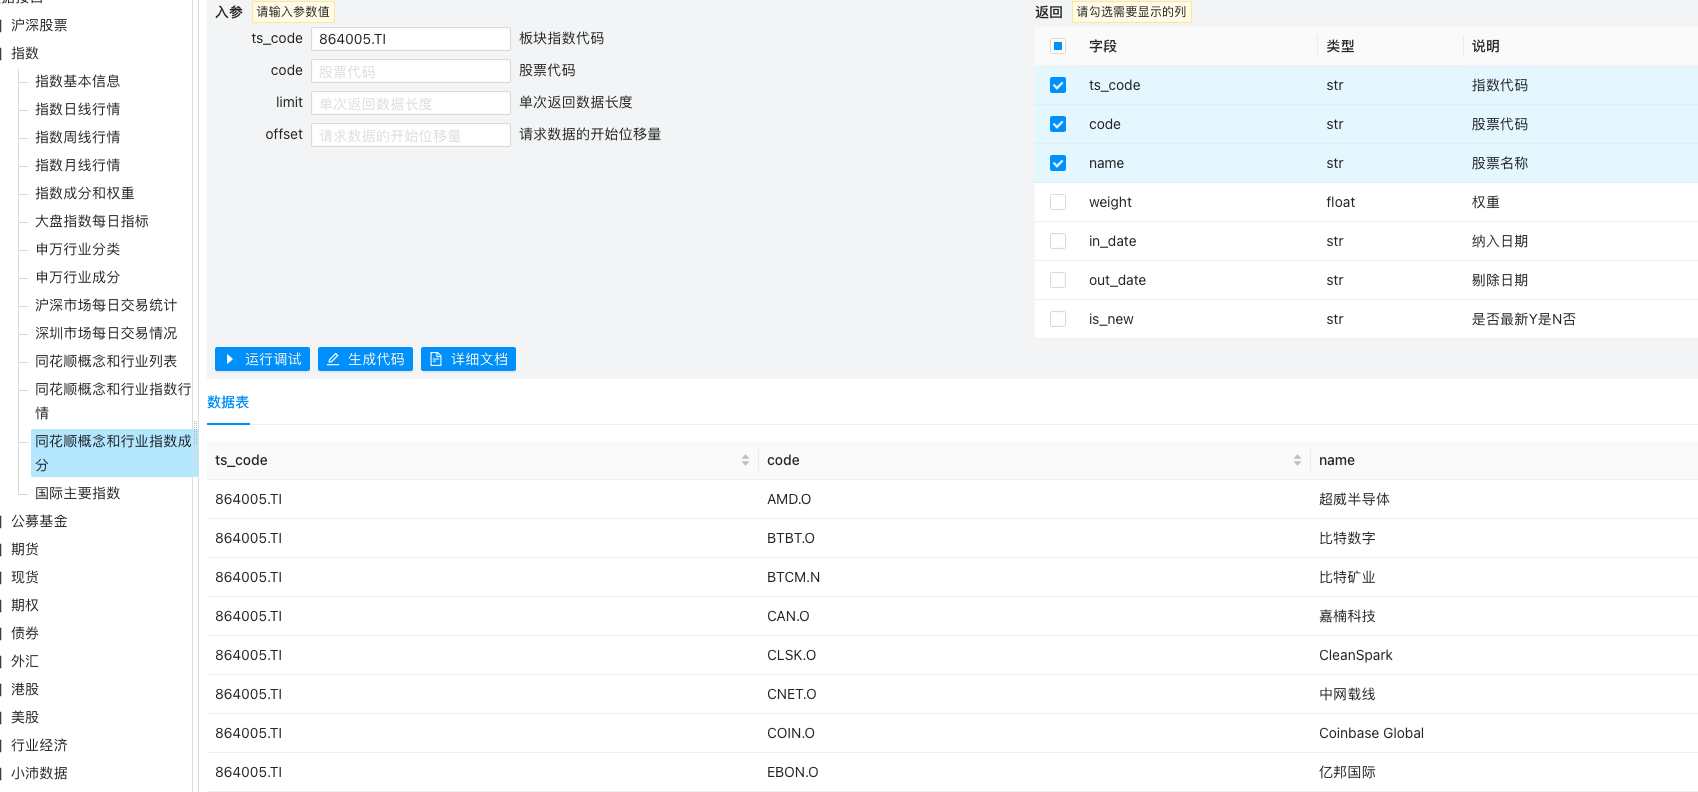
同花顺概念列表返回的数据有错误,交易所字段是A股,实际不是。
id:132... | open | 2023-02-20T04:38:29Z | 2023-02-20T04:38:29Z | https://github.com/waditu/tushare/issues/1693 | [] | cbps | 0 |
JaidedAI/EasyOCR | deep-learning | 804 | Cannot process high bit-depth grayscale numpy array | Where you convert from a grayscale numpy array to a cv2 image
https://github.com/JaidedAI/EasyOCR/blob/b7ddee30c6a02f7643fc2ac52b6da84263752f92/easyocr/utils.py#L709
cv2 gives an error for high bit-depth images
```
> Unsupported depth of input image:
> 'VDepth::contains(depth)'
> where
> 'depth' is 4 (CV... | open | 2022-07-29T10:25:16Z | 2022-07-29T10:25:16Z | https://github.com/JaidedAI/EasyOCR/issues/804 | [] | howff | 0 |
agronholm/anyio | asyncio | 49 | Crashed task does not cancel siblings if host task has finished | If a host task is waiting for task in a task group to finish and one of them raises an exception, this does not cancel the other subtasks even though it should. This works correctly on trio, but not on the other backends. | closed | 2019-04-06T15:12:59Z | 2019-04-07T19:32:28Z | https://github.com/agronholm/anyio/issues/49 | [
"asyncio",
"curio"
] | agronholm | 0 |
tflearn/tflearn | tensorflow | 754 | Exception: Feed dict asks for variable named 'targets' but no such variable is known to exist | I Am Following This Tutorial Series On Youtube-https://www.youtube.com/watch?v=I1qT-VbA_MM
In this I am Trying To Create the Model required to Actually Play The Fame.I have the Proper Data but once i run The Script,i get the error- Exception: Feed dict asks for variable named 'targets' but no such variable is known ... | open | 2017-05-12T18:25:05Z | 2018-05-25T04:26:04Z | https://github.com/tflearn/tflearn/issues/754 | [] | blaine12100 | 2 |
graphql-python/graphene | graphql | 1,384 | Cannot use Enums in mutations that are inside input types | * **What is the current behavior?**
Cannot use Enums in mutations that are inside input types. The input type never renders the field that was created as an enum.
While doing different attempts sometimes I get a duplicated type, like the one described in this issue:
https://github.com/graphql-python/graphene/issue... | closed | 2021-10-18T16:16:08Z | 2022-06-29T17:11:25Z | https://github.com/graphql-python/graphene/issues/1384 | [
"🐛 bug"
] | federico-piazza | 4 |
janosh/pymatviz | plotly | 16 | Add interactive ptable_heatmap | Write a Plotly version of `ptable_heatmap`:
https://github.com/janosh/ml-matrics/blob/58bfa7513dcf6d75e9bba3a3dac4fc8a1a54cd6e/ml_matrics/elements.py#L61-L71
Related: https://github.com/materialsproject/pymatgen/issues/1288 | closed | 2021-10-14T10:00:00Z | 2021-11-14T16:12:58Z | https://github.com/janosh/pymatviz/issues/16 | [
"enhancement"
] | janosh | 0 |
nolar/kopf | asyncio | 1,145 | Custom resource watchers die but operator does not in environments with restricted Kubernetes API access | ### Long story short
When the operator's service account has limited access to the Kubernetes cluster (such as an RBAC that only gives it access to the current namespace), the watchers may die (such as due to a temporary auth issue) and never recover. This results in the operator continuing to run, but not monitorin... | open | 2024-12-10T21:13:05Z | 2024-12-12T21:04:45Z | https://github.com/nolar/kopf/issues/1145 | [
"bug"
] | james-mchugh | 2 |
axnsan12/drf-yasg | django | 235 | Swagger not fetching details from swagger_auto_schema | I am using **swagger_auto_schema** in **function based views** like below. It seems like **Swagger** is not using the **annotations** at all. What am I doing wrong?
urls.py
```
from django.conf.urls import url
from .views import check_phone
urlpatterns = [
url(r'^check_phone/?', check_phone),
]
```
views.... | closed | 2018-10-18T21:01:13Z | 2018-10-23T06:09:54Z | https://github.com/axnsan12/drf-yasg/issues/235 | [] | deepakzipgo | 4 |
FactoryBoy/factory_boy | django | 225 | post equivalent for lazy_attribute | Hi,
I would like to add abstration in my UserFactory(). I would like to give the user password as a parameter of my factory and let the factory generate the hashed password. For example, I would like to do something like this:
``` python
user = UserFactory(password='foo')
print(user.password) # prints a hash of the p... | closed | 2015-08-14T18:22:31Z | 2020-04-10T04:02:05Z | https://github.com/FactoryBoy/factory_boy/issues/225 | [
"Q&A",
"Doc",
"NeedInfo"
] | gilbsgilbs | 4 |
microsoft/nni | pytorch | 5,383 | The following code block gives me error | The following code block gives me error
```
import bz2
import urllib.request
import numpy as np
from sklearn.datasets import load_svmlight_file
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.linear_model import LogisticRegression
from s... | closed | 2023-02-19T14:12:35Z | 2023-09-15T04:22:12Z | https://github.com/microsoft/nni/issues/5383 | [] | AbdelrahmanHamdy1996 | 3 |
automl/auto-sklearn | scikit-learn | 1,461 | Rename all variables named `rval` | We should rename all variables named `rval` because they are an abbreviation that is not immediately clear (return_value). Moreover, there's one occasion where the abbreviation stands for run_value (https://github.com/automl/auto-sklearn/blob/184b4dc279c498ed8eadeb620873b46e8230d83f/autosklearn/estimators.py), which co... | closed | 2022-05-05T13:32:47Z | 2022-06-14T12:36:09Z | https://github.com/automl/auto-sklearn/issues/1461 | [
"maintenance"
] | mfeurer | 1 |
keras-team/keras | data-science | 20,351 | Flexible loss configuration for nested/multi outputs losses learning in Keras | Following the [guidelines](https://github.com/keras-team/keras/blob/master/CONTRIBUTING.md#step-1-open-an-issue).
### Proof of concept: https://github.com/nicolaspi/keras-nested-loss
### Description
Currently, Keras has limited support for specifying losses for complex, nested model outputs. I propose an enhanceme... | closed | 2024-10-14T11:42:35Z | 2024-10-15T17:31:24Z | https://github.com/keras-team/keras/issues/20351 | [] | nicolaspi | 1 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 338 | get_debug_queries() returns an empty list when app.debug is set late | I'm using Flask-Debugtoolbar which is using Flask-SQLAlchemy `get_debug_queries()` to profile Flask apps. I found it is always 0 query all the time.
Firstly I thought it's something wrong with Flask-Debugtoolbar, but with logging, I found Flask-SQLAlchemy `get_debug_queries()` always returns `[]`.
Then I tried it wit... | closed | 2015-10-13T08:24:23Z | 2020-12-05T21:31:14Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/338 | [] | kxxoling | 9 |
aleju/imgaug | machine-learning | 31 | Random Crop Position of a Fixed Size | Not a bug, a question.
Is it possible to use the crop function to randomly crop an image to a fixed size? I.e.: crop 256x256 images to 224x224 at a random position (within the image area)?
Thank you. | closed | 2017-04-29T10:25:00Z | 2019-05-26T05:07:20Z | https://github.com/aleju/imgaug/issues/31 | [] | J6767 | 5 |
kennethreitz/responder | graphql | 440 | AttributeError: module 'typesystem' has no attribute 'SchemaDefinitions' | Using apistar 0.2.7
Seeing this error at responder startup:
```
Traceback (most recent call last):
File "/app/dinghy_ping/services/api.py", line 1, in <module>
import responder
File "/usr/local/lib/python3.7/dist-packages/responder/__init__.py", line 1, in <module>
from .core import *
File "/... | closed | 2020-08-14T21:58:37Z | 2020-08-14T22:07:21Z | https://github.com/kennethreitz/responder/issues/440 | [] | sepulworld | 2 |
xinntao/Real-ESRGAN | pytorch | 656 | replicate demo suddenly not working | it seems that the replicate demo has suddenly borked itself, with no real explanation, the error you get when you try to upscale is below:
Prediction input failed validation: {"detail":[{"loc":["body","input","tile"],"msg":"none is not an allowed value","type":"type_error.none.not_allowed"}]}
this happens even if yo... | closed | 2023-07-04T22:37:27Z | 2023-09-18T12:23:53Z | https://github.com/xinntao/Real-ESRGAN/issues/656 | [] | pakieFNF | 0 |
mljar/mljar-supervised | scikit-learn | 794 | Error message on K means clustering | ## Error for 55_NearestNeighbors
The least populated class in y has only 1 member, which is too few. The minimum number of groups for any class cannot be less than 2.
Traceback (most recent call last):
File "C:\Users\User\anaconda3\lib\site-packages\supervised\base_automl.py", line 1095, in _fit
trained = self.t... | open | 2025-03-20T19:12:23Z | 2025-03-21T07:25:54Z | https://github.com/mljar/mljar-supervised/issues/794 | [] | Selphie14100 | 1 |
iterative/dvc | machine-learning | 10,097 | Delete datasets that have been pulled locally so that sensitive data sets can be cleaned up easily | In an open-source project I am working on: [Automatic Classifiers for Peace](https://gitlab.com/automatic-classifiers-for-peace/acfp) we have used dvc to manage shared data in the project.
This shared data can contain sensitive information and I would like a simple way (hopefully using dvc) to remove all the data s... | closed | 2023-11-16T11:11:53Z | 2023-12-01T13:57:47Z | https://github.com/iterative/dvc/issues/10097 | [] | benjamincerigo | 2 |
Yorko/mlcourse.ai | pandas | 669 | do you have similar code like lesson10_part9_imbalance.ipynb but for lightGBM | do you have similar code like lesson10_part9_imbalance.ipynb but for lightGBM
https://github.com/Yorko/mlcourse.ai/blob/master/jupyter_russian/topic10_boosting/lesson10_part9_imbalance.ipynb
or catboost
to understand what is better? | closed | 2020-06-08T17:18:10Z | 2020-06-09T10:42:16Z | https://github.com/Yorko/mlcourse.ai/issues/669 | [
"question"
] | Sandy4321 | 1 |
marcomusy/vedo | numpy | 420 | can i convert a shape file to a vedo.shape? | Hi, I have a polygon saved in shp format. I would like to try the Extrude in vedo on my polygon. However, it seems I need to convert my shape file to the vedo shape file in order I have the possibility to use the extrude function
Could you please guide me how can I convert my polygon to the vedo shape?
Thanks a lot! | closed | 2021-06-23T10:22:26Z | 2021-06-25T11:27:37Z | https://github.com/marcomusy/vedo/issues/420 | [] | sahar-github | 2 |
huggingface/transformers | deep-learning | 36,567 | torch_dtype is actually used now? | ### System Info
different transformers versions. see description
### Who can help?
@ArthurZucker
### Information
- [ ] The official example scripts
- [ ] My own modified scripts
### Tasks
- [ ] An officially supported task in the `examples` folder (such as GLUE/SQuAD, ...)
- [ ] My own task or dataset (give det... | open | 2025-03-05T18:38:34Z | 2025-03-11T00:51:17Z | https://github.com/huggingface/transformers/issues/36567 | [
"bug"
] | dakinggg | 3 |
pytorch/pytorch | deep-learning | 149,839 | Custom Autograd Functions Don't Work in C++ if it takes Tensors[] as arguments | ### 🐛 Describe the bug
This kind of custom operators don;t seem to work :
```
TORCH_LIBRARY_FRAGMENT(cuequivariance_ops_torch, m)
{
// Define an operator schema ... | open | 2025-03-24T03:07:33Z | 2025-03-24T19:25:10Z | https://github.com/pytorch/pytorch/issues/149839 | [
"module: cpp",
"module: autograd",
"triaged"
] | borisfom | 1 |
microsoft/qlib | deep-learning | 1,140 | Install in Win: error: command 'H:\\VisualStudio\\VC\\Tools\\MSVC\\14.29.30133\\bin\\HostX86\\x86\\link.exe' failed with exit code 1120 | build\lib.win32-cpython-37\qlib\data\_libs\rolling.cp37-win_amd64.pyd : fatal error LNK1120: 108 个无法解析的外部命令
error: command 'H:\\VisualStudio\\VC\\Tools\\MSVC\\14.29.30133\\bin\\HostX86\\x86\\link.exe' failed with exit code 1120
[end of output]
## ❓ Questions and Help
We sincerely suggest you to car... | closed | 2022-06-19T13:03:20Z | 2022-12-29T18:02:07Z | https://github.com/microsoft/qlib/issues/1140 | [
"question",
"stale"
] | ArtificialZeng | 4 |
plotly/dash-table | plotly | 461 | autodetecting column types so that numeric filtering works? | 
Some options:
Mentioned by @alexcjohnson :
> re: auto-detecting column type - we could probably work in an `auto` type that works similarly to plotly.js, but probably much easier (and more robu... | open | 2019-06-07T16:50:17Z | 2020-02-03T20:59:52Z | https://github.com/plotly/dash-table/issues/461 | [] | chriddyp | 1 |
sunscrapers/djoser | rest-api | 164 | Add a CHANGELOG | Is there one? Can someone add one?
I saw a new `0.5.1` release and couldn't find the changes easily.
| closed | 2016-09-02T08:05:33Z | 2023-04-15T13:50:43Z | https://github.com/sunscrapers/djoser/issues/164 | [] | decentral1se | 10 |
Asabeneh/30-Days-Of-Python | pandas | 652 | Python | open | 2025-03-16T15:16:11Z | 2025-03-16T15:16:11Z | https://github.com/Asabeneh/30-Days-Of-Python/issues/652 | [] | rayanenfi04 | 0 | |
onnx/onnx | machine-learning | 6,278 | Precision Loss During Weight Transfer from ONNX to MLPack Model | I am currently working on transferring weights from an ONNX model to an MLPack model (MLPack is a machine learning library in C++). While the weight transfer process completes correctly and the output appears to be accurate, I am experiencing precision issues in the initial layer. Specifically, there are inaccuracies a... | closed | 2024-08-04T04:33:47Z | 2024-08-12T18:08:36Z | https://github.com/onnx/onnx/issues/6278 | [
"question"
] | kumarutkarsh1248 | 3 |
agronholm/anyio | asyncio | 143 | Object stream send is blocked after receive_nowait | This issue concerns `master@efa6071`
It appears that memory object stream sends may become blocked even if there is space in the buffer.
Here's a failing scenario:
```python
import anyio
async def main():
send, receive = anyio.create_memory_object_stream(1)
await send.send_nowait('hello')
... | closed | 2020-08-05T16:04:36Z | 2020-08-05T19:50:59Z | https://github.com/agronholm/anyio/issues/143 | [] | mjwestcott | 1 |
coqui-ai/TTS | pytorch | 3,534 | [Bug] Slow length computation after commit 5dcc16d | ### Describe the bug
I got the issue of increasingly slow length computation during vits preprocessing. After the last commit 5dcc16d, the time to compute length for .wav files from M-AILABS dataset takes 32 times longer to analyse. I narrowed down the problem to `_compute_lengths` method in [dataset.py](https://githu... | closed | 2024-01-20T18:19:28Z | 2024-03-02T00:44:45Z | https://github.com/coqui-ai/TTS/issues/3534 | [
"bug",
"wontfix"
] | daniilrobnikov | 1 |
graphql-python/graphene-sqlalchemy | graphql | 157 | abstract = True has been deprecated, plz update your example | I tried a very simple subclass as described in your example from README but it doesn't work at all.
```
class ActiveSQLAlchemyObjectType(SQLAlchemyObjectType):
class Meta:
abstract = True
@classmethod
def get_node(cls, info, id):
return cls.get_query(info)
class Article(ActiveSQ... | closed | 2018-08-21T17:01:26Z | 2023-02-24T14:55:22Z | https://github.com/graphql-python/graphene-sqlalchemy/issues/157 | [] | puorc | 4 |
pytorch/pytorch | python | 149,332 | ONNX: export failure ❌ 1.1s: Exporting the operator 'aten::fft_fft2' to ONNX opset version 17 is not supported. | ### 🚀 The feature, motivation and pitch
Exporting the operator 'aten::fft_fft2' to ONNX opset version 18 is not supported.
Trying to convert torch model to onnx model.
How can I solve this problem?
(Da) D:\Create\YOLOv8-TensorRT-main>E:/anaconda3/envs/Da/python.exe d:/Create/YOLOv8-TensorRT-main/export.py
Ultralytics... | open | 2025-03-17T17:41:31Z | 2025-03-20T18:53:47Z | https://github.com/pytorch/pytorch/issues/149332 | [
"module: onnx",
"triaged"
] | EvelynCarter | 12 |
lukas-blecher/LaTeX-OCR | pytorch | 353 | [FR] `model(file)` copies the predicted latex to the clipboard | `model(file)` copies the predicted latex to the clipboard. I'd like to disable this behavior when calling the model from Python. | open | 2023-12-29T16:47:24Z | 2023-12-29T16:47:24Z | https://github.com/lukas-blecher/LaTeX-OCR/issues/353 | [] | NightMachinery | 0 |
babysor/MockingBird | deep-learning | 71 | Windows11 配置FFmpeg环境变量没有用 | 
配置好后cmd搜索FFmpeg -version提示找不到该命令,重启电脑也没用. | closed | 2021-09-01T01:25:37Z | 2021-09-01T01:26:50Z | https://github.com/babysor/MockingBird/issues/71 | [] | hexiosr | 0 |
zihangdai/xlnet | tensorflow | 252 | Python2 to Python3? | Hi,
Thanks for xlnet. Is there any plan to convert this code into python3? Thanks | open | 2019-12-05T10:36:33Z | 2020-09-28T02:56:57Z | https://github.com/zihangdai/xlnet/issues/252 | [] | hammad26 | 1 |
huggingface/diffusers | pytorch | 10,124 | [models] allow specifying block numbers in `enable_gradient_checkpointing()` to speed up training | As brought up in https://github.com/huggingface/diffusers/pull/9982#issuecomment-2517826764 by @bghira, I think we could support this directly in the `enable_gradient_checkpointing()` method we expose for the models.
Users could specify the block interval they want gradient checkpointing to be applied in and we tak... | closed | 2024-12-05T03:09:00Z | 2025-01-28T01:21:47Z | https://github.com/huggingface/diffusers/issues/10124 | [
"stale",
"training",
"performance"
] | sayakpaul | 3 |
newpanjing/simpleui | django | 247 | simplePro on_delete设置为models.DO_NOTHING时,删除该外键会报错 | **bug描述**
* *Bug description * *
简单的描述下遇到的bug:
Briefly describe the bugs encountered:
**重现步骤**
** repeat step **
```
models.py
class A(models.Model):
batch = models.ForeignKey(Batch,verbose_name=u"批号",on_delete=models.DO_NOTHING)
# 注意on_delete=models.DO_NOTHING
class Batch(models.Model):
tes... | closed | 2020-04-02T02:02:20Z | 2020-04-15T06:57:53Z | https://github.com/newpanjing/simpleui/issues/247 | [
"bug"
] | xojisi | 0 |
autogluon/autogluon | scikit-learn | 3,950 | [BUG]standalone flag not working for yolox_l & CLIP | On Ubuntu 20, g4dn.xlarge, Autogluon 1.0, for multimodal object detection (medium quality preset, i.e. yolox_l) and for image-text-matching (high quality preset, i.e. clip) the default is to save models with standalone set to True. However, saving them with 'standalone=False' doesn't make a difference at all. Looks lik... | open | 2024-02-26T18:54:17Z | 2024-11-26T21:47:07Z | https://github.com/autogluon/autogluon/issues/3950 | [
"bug: unconfirmed",
"Needs Triage",
"module: multimodal"
] | rxjx | 1 |
milesmcc/shynet | django | 144 | Update to new version | Hi
Is there a guide on how to go about properly updating the shynet version on an existing setup without breaking anything? | closed | 2021-05-25T02:24:25Z | 2021-05-25T05:11:39Z | https://github.com/milesmcc/shynet/issues/144 | [] | assman | 2 |
mwaskom/seaborn | matplotlib | 3,619 | location and orientation of split violins | Thanks for the amazing work btw.
My problem is about placement of violinplots. I only need the left half of the violins for my categories.
`sns.violinplot(data=df_temp, x="numSq", y="cell_fpr", hue="numSq", dodge=True, inner=None, split=True, ax=ax1d, native_scale=False)`
I am using split=True
but seaborn... | closed | 2024-01-17T18:59:41Z | 2024-10-09T13:22:50Z | https://github.com/mwaskom/seaborn/issues/3619 | [] | AdityaAsopa | 7 |
blb-ventures/strawberry-django-plus | graphql | 258 | Query resolution is really slow | Hi there,
thank you for this nice library. It really simplifies generating a GraphQL schema for Django projects compared to graphene-django.
I have created a Django model with 13 scalar fields (String, Int, DateTime) , 9 ForeignKey relations of which i query only two fields each (i.e name and id field) and 4 ManyT... | closed | 2023-07-04T10:55:40Z | 2023-07-06T15:55:39Z | https://github.com/blb-ventures/strawberry-django-plus/issues/258 | [] | TWeidi | 15 |
FlareSolverr/FlareSolverr | api | 630 | [yggtorrent] (updating) Exception: System.Threading.Tasks.TaskCanceledException | **Please use the search bar** at the top of the page and make sure you are not creating an already submitted issue.
Check closed issues as well, because your issue may have already been fixed.
### How to enable debug and html traces
[Follow the instructions from this wiki page](https://github.com/FlareSolverr/Fl... | closed | 2022-12-20T20:17:36Z | 2022-12-21T08:09:02Z | https://github.com/FlareSolverr/FlareSolverr/issues/630 | [
"duplicate"
] | DaGreenX | 4 |
explosion/spaCy | deep-learning | 12,415 | Efficiently use NVIDIA gpu for model inference or prediction task |
I have trained spacy model with custom dataset and it's working fine for inference (or prediction task) on CPU.
Now I 'm looking to upgrade to GPU, Here I'm facing an issue related to GPU memory overload.
I have created a django project in which I use this spacy model, and deployed the Django project using guni... | closed | 2023-03-14T05:50:43Z | 2023-04-14T00:02:28Z | https://github.com/explosion/spaCy/issues/12415 | [] | Anand195 | 2 |
scanapi/scanapi | rest-api | 42 | Implement env vars properly | Stop declaring the env vars on scanapi.yaml file and start getting these variables in fact from the env. | closed | 2019-08-12T15:14:28Z | 2019-08-14T18:39:43Z | https://github.com/scanapi/scanapi/issues/42 | [
"Feature",
"Good First Issue"
] | camilamaia | 0 |
pydantic/pydantic | pydantic | 11,352 | BaseModel derived typing.Annotated metadata treated as type instead | ### Initial Checks
- [x] I confirm that I'm using Pydantic V2
### Description
I want to pass metadata to the types of my field, so that I can use the data statically later. I figured it would be nice to have the data in a `BaseModel` derived class in order to have validation on it. A minimal (but failing) example of... | closed | 2025-01-28T15:33:24Z | 2025-01-30T09:39:56Z | https://github.com/pydantic/pydantic/issues/11352 | [
"bug V2",
"pending",
"awaiting author response"
] | DenSinH | 5 |
dpgaspar/Flask-AppBuilder | rest-api | 2,083 | Superset sending default Authorization header while requesting access_token | Hi,
We are seeing some validation check failures on our OAuth provider side when superset is making a call to get the access_token
It seems that superset is trying to send some sort of default non-empty `Authorization` header while trying to access for token
Getting a default value of Authorization header being pa... | open | 2023-07-12T07:02:04Z | 2023-07-12T09:22:23Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/2083 | [] | Utsavjain4561 | 0 |
scikit-learn/scikit-learn | machine-learning | 30,810 | Windows free-threaded CPython 3.13 ValueError: concurrent send_bytes() calls are not supported | Noticed in [build log](https://github.com/scikit-learn/scikit-learn/actions/runs/13233133978/job/36933421850#step:5:2813). An automated issue was opened in https://github.com/scikit-learn/scikit-learn/issues/30801 and closed the next day.
This needs some investigation to figure out whether this can be reproduced local... | open | 2025-02-11T14:44:27Z | 2025-02-11T14:47:02Z | https://github.com/scikit-learn/scikit-learn/issues/30810 | [
"Bug",
"Needs Investigation",
"free-threading",
"OS:Windows"
] | lesteve | 0 |
nonebot/nonebot2 | fastapi | 3,173 | Plugin: 奶龙魔法 | ### PyPI 项目名
nonebot-plugin-nailongmagic
### 插件 import 包名
nonebot_plugin_nailongmagic
### 标签
[{"label":"SD","color":"#3645e3"},{"label":"nailong","color":"#edd81b"},{"label":"func","color":"#43ed1b"}]
### 插件配置项
```dotenv
```
### 插件测试
- [ ] 如需重新运行插件测试,请勾选左侧勾选框 | closed | 2024-12-07T15:58:16Z | 2024-12-15T03:01:26Z | https://github.com/nonebot/nonebot2/issues/3173 | [
"Plugin",
"Publish"
] | Refound-445 | 8 |
sgl-project/sglang | pytorch | 4,171 | [Bug] Qwen2.5-VL-7B-Instruct Inference Server crashes | ### Checklist
- [x] 1. I have searched related issues but cannot get the expected help.
- [x] 2. The bug has not been fixed in the latest version.
- [x] 3. Please note that if the bug-related issue you submitted lacks corresponding environment info and a minimal reproducible demo, it will be challenging for us to repr... | open | 2025-03-07T08:17:40Z | 2025-03-21T12:34:29Z | https://github.com/sgl-project/sglang/issues/4171 | [
"visIon-LM"
] | felmoreno1726 | 9 |
aiogram/aiogram | asyncio | 1,484 | Aiogram doesn't work properly if one field of a `StatesGroup` is a `default_field` | ### Checklist
- [X] I am sure the error is coming from aiogram code
- [X] I have searched in the issue tracker for similar bug reports, including closed ones
### Operating system
Ubuntu 22.04.3 LTS (WSL)
### Python version
3.11.7
### aiogram version
3.5.0
### Expected behavior
 and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
So, I am running yolov5 to perform live detection with webcam. I want to retrieve the vid... | closed | 2023-12-05T05:45:35Z | 2024-01-15T00:22:35Z | https://github.com/ultralytics/yolov5/issues/12466 | [
"question",
"Stale"
] | itsjustrafli | 3 |
BeanieODM/beanie | asyncio | 775 | [BUG] [need help]validate_on_save's behavior | **Describe the bug**
please regret for my bad english.
beanie's behavior maybe not the same as before.
i always use `model_copy(update=schema.model_dump())` to update an document (it used to be `.copy(update=schema.dict())`),
but i found the data in database not the same as use ODM, eg: `PydanticObjectId` will b... | closed | 2023-11-10T03:15:38Z | 2024-02-27T06:31:12Z | https://github.com/BeanieODM/beanie/issues/775 | [
"bug"
] | hd10180 | 5 |
keras-team/keras | tensorflow | 20,260 | Model weights not saved if a custom layer class contains a list of layers named self._layers | Hi everyone,
I would like to point out a problem that I found while developing a custom model: layer's weights are not saved if a Model subclass initializes a custom layer that contains sublayers in a class-level list variable called `self._layers`. The code below proves the issue and should illustrates it better.
... | open | 2024-09-16T14:50:50Z | 2024-09-16T22:56:49Z | https://github.com/keras-team/keras/issues/20260 | [
"type:Bug"
] | mpetteno | 2 |
CPJKU/madmom | numpy | 178 | fix stuck Appveyor builds | All of a sudden, Appveyor builds got stuck. Needs investigation. See https://github.com/appveyor/ci/issues/923 for more details.
| closed | 2016-07-20T18:47:51Z | 2017-09-18T19:13:26Z | https://github.com/CPJKU/madmom/issues/178 | [] | superbock | 0 |
jofpin/trape | flask | 203 | Trape run error | Traceback (most recent call last):
File "trape.py", line 23, in <module>
from core.utils import utils #
File "/data/data/com.termux/files/home/trape/core/utils.py", line 23, in <module>
import http.client
ImportError: No module named http.client
| open | 2020-01-22T09:23:05Z | 2020-01-22T17:40:26Z | https://github.com/jofpin/trape/issues/203 | [] | anukiller | 6 |
kensho-technologies/graphql-compiler | graphql | 977 | Add better type hint for the output query type when compiling to a SQL backend | Currently, `CompilationResult` is an untyped `namedtuple`, which means that it's unclear what is the type of its `query` attribute. For non-SQL backends, it appears to be `str`, but for SQL it seems to be some `SQLAlchemy`-specific type and it's not clear which of its superclasses/protocols we should claim as the retur... | open | 2020-12-07T22:26:05Z | 2021-05-12T20:49:34Z | https://github.com/kensho-technologies/graphql-compiler/issues/977 | [
"user friendliness",
"maintainer quality-of-life"
] | obi1kenobi | 0 |
proplot-dev/proplot | matplotlib | 248 | incompatibilities with matplotlib 3.4 | ### Description
(Updating this issue from original problem).
It seems that matplotlib 3.4 has changed some of their internals that proplot was relying on, and now several things are broken.
1. proplot throws an error on import. I believe it's from using a private method of `matplotlib.cbook`: `_suppress_matplotlib... | closed | 2021-04-01T19:51:38Z | 2021-07-01T21:45:31Z | https://github.com/proplot-dev/proplot/issues/248 | [
"bug",
"dependencies"
] | scottstanie | 6 |
deezer/spleeter | deep-learning | 633 | [Discussion] Separate using original training models | Hi! Spleeter is very useful repository! Thx!
You can refer to [the official spleeter wiki](https://github.com/deezer/spleeter/wiki/2.-Getting-started#train-model) to proceed with the training.
In this issue, I will show you the next step, how I use original models to separate test sounds.
I used the spleeter... | open | 2021-06-21T14:41:53Z | 2021-07-16T09:24:42Z | https://github.com/deezer/spleeter/issues/633 | [
"question"
] | makobouzu | 1 |
aiortc/aioquic | asyncio | 227 | Example DoQ resolver and long responses | Something goes wrong when I query a domain where I expect a really long answer (approximately 10kB or more). As an example, I would recommend querying the domain `cmts1-dhcp.longlines.com`.
Example (don't forget to add your own DoQ resolver IP):
```
python3 examples/doq_client.py --dns_type A --query cmts1-dhcp.lo... | closed | 2021-09-21T14:10:28Z | 2022-02-07T16:08:41Z | https://github.com/aiortc/aioquic/issues/227 | [] | Payne-X6 | 1 |
AUTOMATIC1111/stable-diffusion-webui | pytorch | 15,795 | [Bug]: Automatic1111 works extremelly slow if Silly Tavern is also running at the same time | ### Checklist
- [X] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [X] The issue has not been reported ... | open | 2024-05-15T05:32:07Z | 2024-05-15T07:44:02Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/15795 | [
"bug-report"
] | guispfilho | 0 |
TencentARC/GFPGAN | deep-learning | 470 | Kamal ansari | Kamal ansari | open | 2023-12-08T04:25:21Z | 2023-12-08T04:25:21Z | https://github.com/TencentARC/GFPGAN/issues/470 | [] | Iejeheu | 0 |
neuml/txtai | nlp | 486 | Limit duckdb==0.8.0 to workaround Windows build issue | See https://github.com/duckdb/duckdb/issues/7933
| closed | 2023-06-13T16:32:17Z | 2023-06-13T19:02:54Z | https://github.com/neuml/txtai/issues/486 | [] | davidmezzetti | 2 |
gradio-app/gradio | data-science | 10,462 | Multiple Users Access | ### Describe the bug
Hi all,
I hope you’re doing well!
We have been utilizing the Hugging Face Space ([Voice Assistant Demo](https://huggingface.co/spaces/Siddhant/Voice_Assistant_Demo)) as a prototype system for teaching a course. However, we’ve encountered an issue where conflicts arise when multiple users interac... | closed | 2025-01-29T17:57:25Z | 2025-01-29T20:11:52Z | https://github.com/gradio-app/gradio/issues/10462 | [
"bug"
] | siddhu001 | 1 |
idealo/image-super-resolution | computer-vision | 185 | Error when trying to use predictor. | When trying to use predictor, I cannot load weights:
```{python}
---------------------------------------------------------------------------
AttributeError Traceback (most recent call last)
<ipython-input-10-5a083bc3c5b8> in <module>
2 #!mkdir -p data/output
3 predictor = ... | open | 2021-03-05T14:25:12Z | 2022-01-06T23:22:01Z | https://github.com/idealo/image-super-resolution/issues/185 | [] | avacaondata | 1 |
public-apis/public-apis | api | 3,534 | Apis | closed | 2023-06-11T18:44:19Z | 2023-06-12T21:13:03Z | https://github.com/public-apis/public-apis/issues/3534 | [] | Okao-Emmanuel | 0 | |
huggingface/diffusers | deep-learning | 10,755 | Difference in Output When Using PIL.Image vs numpy.array for Image and Mask Input. | hi.
I get different results when providing image and mask as input using PIL.Image versus numpy. array. Why does this happen?
Is there an issue with my normalization method?
| pillow | array |
|---|---|
|  | , deferred=True)
```
It gave a naming error -- as SQL Alchemy generated column name on that. Hence we label it:
```
d_column = column_property(
func.pg_func(id).label('test'), deferred=True)
```
All works fin... | open | 2018-08-27T10:12:37Z | 2022-05-15T12:54:52Z | https://github.com/graphql-python/graphene-sqlalchemy/issues/161 | [
"bug"
] | jagusiak | 1 |
aiogram/aiogram | asyncio | 1,324 | breaking changes | ### Checklist
- [X] I am sure the error is coming from aiogram code
- [X] I have searched in the issue tracker for similar bug reports, including closed ones
### Operating system
Linux kanairo-desktop 5.15.0-1032-realtime #35-Ubuntu 2023 x86_64 x86_64 x86_64 GNU/Linux
### Python version
Python 3.10.12
### aiogram... | closed | 2023-09-26T14:46:37Z | 2023-09-26T20:54:56Z | https://github.com/aiogram/aiogram/issues/1324 | [
"upstream"
] | sxcntqnt | 1 |
graphql-python/graphene-django | django | 1,461 | add validation on input | Hi everyone,
How can i have validation like max length or min length on InputObjecttypes?
i found issue that opened at 2017 about to my topic nut it dose not work for me | closed | 2023-09-16T10:18:59Z | 2023-09-16T16:09:05Z | https://github.com/graphql-python/graphene-django/issues/1461 | [
"✨enhancement"
] | elyashedayat0101 | 1 |
AntonOsika/gpt-engineer | python | 1,165 | Implement a Unified Configuration File for Project Settings | ## Feature description
I propose the implementation of a general, unified configuration file in TOML format for the gpt-engineer project. This configuration file would serve as a centralized repository for various project settings, including but not limited to:
- API keys for OpenAPI and the corresponding model con... | open | 2024-06-05T00:21:28Z | 2024-07-04T17:29:12Z | https://github.com/AntonOsika/gpt-engineer/issues/1165 | [
"enhancement",
"size:L"
] | similato87 | 4 |
unit8co/darts | data-science | 2,018 | Timeseries definitions precission | **Update time series definitions of guaranteed**
in the chapter, '*TimeSeries are guaranteed to:*', you said that '*Have a monotonically increasing time index, without holes (without missing dates)*'.
I guess it should be said "*strictly monotonically*" otherwise, it does not assure that timestamps are uniques.
... | closed | 2023-10-04T07:44:20Z | 2023-10-30T07:03:30Z | https://github.com/unit8co/darts/issues/2018 | [
"documentation"
] | VincentMagn | 4 |
AUTOMATIC1111/stable-diffusion-webui | pytorch | 16,794 | [Bug]: Filename not found issue | ### Checklist
- [X] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [ ] The issue has not been reported before... | closed | 2025-01-13T16:38:19Z | 2025-01-17T07:23:54Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/16794 | [
"not-an-issue"
] | skaba04 | 3 |
graphql-python/graphene | graphql | 780 | Adding Query InputField examples to the docs | This page is the closest example for how to use an InputField:
http://docs.graphene-python.org/en/latest/types/mutations/
But it never shows how to also use it in a Query.
This example, however, does: https://github.com/graphql-python/graphene/blob/master/examples/complex_example.py#L18
It even shows how to... | closed | 2018-06-26T20:46:09Z | 2019-08-05T22:17:53Z | https://github.com/graphql-python/graphene/issues/780 | [
"wontfix",
"📖 documentation"
] | adamdavis40208 | 5 |
plotly/dash-core-components | dash | 391 | DCC Dropdown doesn't open when child of Tab that is initially hidden | We have created a layout with two tabs. When we put a `dcc.Dropdown` element on the tab that is initially hidden, the dropdown will not open.
This issue is present in both Chrome and Firefox on Windows and Linux.
| open | 2018-10-02T12:04:08Z | 2018-11-28T20:40:31Z | https://github.com/plotly/dash-core-components/issues/391 | [] | brylie | 3 |
mljar/mercury | data-visualization | 349 | Long running tasks | Hi!
Could you please advise how to deal with long running tasks (10+ minutes)?
Currently I face an issue with notebook run gets interrupted after 5 minute of execution.
According to the logs the worker is marked as Stale and the whole thing restarts after that.
Thanks in advance!
ENV:
OS: macOS Ventura 13.... | closed | 2023-08-23T15:04:05Z | 2024-07-16T10:47:16Z | https://github.com/mljar/mercury/issues/349 | [] | SergeyKudrenko | 4 |
ydataai/ydata-profiling | jupyter | 1,431 | Bug Report: missing values not recognized after pandas convert_dtypes() | ### Current Behaviour
After applying `convert_dtypes()` method from pandas, ydata profiling no longer recognizes missing values (pd.NA).
### Expected Behaviour
After applying `convert_dtypes()`, the profiling report should recognize missing values.``
### Data Description
df = pd.DataFrame(
{
"feature... | closed | 2023-08-25T08:22:31Z | 2023-09-27T07:04:41Z | https://github.com/ydataai/ydata-profiling/issues/1431 | [
"bug 🐛"
] | baptiste-pasquierQB | 1 |
matplotlib/matplotlib | data-science | 29,237 | [Doc]: Website _very_ slow | ### Documentation Link
_No response_
### Problem
I don't know what the appropriate place is to submit this, but I found recently that the documentation website is extremely slow, to the point of being unusable. It takes upward of a minute to resolve a search, and any page seems to 'hang'. I can interrupt this in Saf... | open | 2024-12-05T18:17:33Z | 2024-12-13T06:55:48Z | https://github.com/matplotlib/matplotlib/issues/29237 | [
"Documentation"
] | matthiasfabry | 5 |
yzhao062/pyod | data-science | 442 | How to tackle missing value and new type value in input | Hi,
thanks for your contribution of pyod. It helps a lot.
It seems that the framework cannot tackle the missing value problem. When I use OrdinalEncoder to encode the input, the missing values and unknown_values are set as np.nan, then pyod either outputs all nan value or return the error: ValueError: Input ... | open | 2022-09-20T16:37:36Z | 2022-09-23T13:40:52Z | https://github.com/yzhao062/pyod/issues/442 | [] | Andrew-Zhu | 3 |
zappa/Zappa | flask | 807 | [Migrated] Use a unique project archive url for slim project deploys | Originally from: https://github.com/Miserlou/Zappa/issues/1964 by [bxjx](https://github.com/bxjx)
Solves issue https://github.com/Miserlou/Zappa/issues/1963 | closed | 2021-02-20T12:51:52Z | 2024-04-13T19:09:54Z | https://github.com/zappa/Zappa/issues/807 | [
"no-activity",
"auto-closed"
] | jneves | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.