
html_url stringlengths 51 51 | comments stringlengths 67 24.7k | title stringlengths 6 280 | body stringlengths 51 36.2k | comment_length int64 16 1.45k | text stringlengths 190 38.3k | embeddings list |
|---|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/5468 | Hi! I agree it would be nice to have a method like that. Instead of `keep_columns`, we can name it `select_columns` to be more aligned with PyArrow's naming convention (`pa.Table.select`). | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 30 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.012716583907604218,
0.40214574337005615,
-0.08417332172393799,
-0.08924133330583572,
0.2792765200138092,
0.1114496961236,
0.3214443027973175,
0.2497984617948532,
-0.08651253581047058,
0.4152001142501831,
-0.3178649842739105,
0.3874146342277527,
-0.26129233837127686,
0.22763366997241974,
... |
https://github.com/huggingface/datasets/issues/5468 | Hi, I am a newbie to open source and would like to contribute. @mariosasko can I take up this issue ? | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 21 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.06664405018091202,
0.25283578038215637,
-0.09896302968263626,
0.033473312854766846,
0.24726547300815582,
0.05422393977642059,
0.36674442887306213,
0.14424610137939453,
0.09209352731704712,
0.397882342338562,
-0.34325695037841797,
0.1846708059310913,
-0.29425686597824097,
0.32242444157600... |
https://github.com/huggingface/datasets/issues/5468 | Hey, I also want to work on this issue I am a newbie to open source. | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 16 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.037629663944244385,
0.2596352696418762,
-0.08372737467288971,
0.017997317016124725,
0.27951300144195557,
0.04990813136100769,
0.33469143509864807,
0.1424269825220108,
0.11139391362667084,
0.431147962808609,
-0.37091001868247986,
0.21859422326087952,
-0.33139416575431824,
0.32999956607818... |
https://github.com/huggingface/datasets/issues/5468 | This sounds related to https://github.com/huggingface/datasets/issues/5474
I'm fine with `select_columns`, or we could also override `select` to also accept a list of columns maybe ? | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 24 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.050467267632484436,
0.1115712821483612,
-0.08281216770410538,
0.023936228826642036,
0.36612218618392944,
0.15828926861286163,
0.27888673543930054,
0.18231356143951416,
0.2217264175415039,
0.39142554998397827,
-0.4084475636482239,
0.21928231418132782,
-0.3540951907634735,
0.28962343931198... |
https://github.com/huggingface/datasets/issues/5468 | @lhoestq, I am planning to add a member function to the dataset class to perform the selection operation. Do you think its the right way to proceed? or there is a better option ? | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 34 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.05245943367481232,
0.3182416260242462,
-0.07823828607797623,
0.009625410661101341,
0.16037361323833466,
0.07437045127153397,
0.29126784205436707,
0.1360301971435547,
0.11689527332782745,
0.47716251015663147,
-0.31609901785850525,
0.2363905906677246,
-0.3058532774448395,
0.234331905841827... |
https://github.com/huggingface/datasets/issues/5468 | Unless @mariosasko thinks otherwise, I think it can go in `Dataset.select()` :)
Though some parameters like keep_in_memory, indices_cache_file_name or writer_batch_size wouldn't when selecting columns, so we would need to update the docstring as well | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 34 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
-0.07380063831806183,
0.33195358514785767,
-0.1016116514801979,
-0.032014310359954834,
0.3175688683986664,
0.09239644557237625,
0.3140401244163513,
0.22060759365558624,
0.1462215781211853,
0.4289715886116028,
-0.32285431027412415,
0.2718319892883301,
-0.33240994811058044,
0.202827394008636... |
https://github.com/huggingface/datasets/issues/5468 | If someone wants to give it a shot, feel free to comment `#self-assign` and it will assign the issue to you.
Feel free to ping us here if you have questions or if we can help :) | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 37 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.02513507753610611,
0.2663191258907318,
-0.09592504799365997,
-0.008970072492957115,
0.3466668725013733,
0.09045290946960449,
0.37154558300971985,
0.2256159782409668,
0.11660045385360718,
0.4302631616592407,
-0.3185146450996399,
0.24153432250022888,
-0.3358711004257202,
0.2463354021310806... |
https://github.com/huggingface/datasets/issues/5468 | I would rather have this functionality as a separate method. IMO it's always better to be explicit than to have an API where a single method can do different/uncorrelated things (somewhat reminds me of Pandas, and there is probably a good reason why PyArrow is more rigid in this aspect). | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 50 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
0.020111702382564545,
0.39976438879966736,
-0.0942908525466919,
-0.08801001310348511,
0.2750343382358551,
0.06968864798545837,
0.406215101480484,
0.23664875328540802,
-0.02431836724281311,
0.4129239618778229,
-0.3411766290664673,
0.3137819766998291,
-0.34520652890205383,
0.1896675229072570... |
https://github.com/huggingface/datasets/issues/5468 | In the end I also think it would be nice to have it as a separate method, this way we can also have it for `IterableDataset` (which can't have `select` for indices) | Allow opposite of remove_columns on Dataset and DatasetDict | ### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COLUMNS_TO_KEEP)
gigaspeech = gigaspeech.remove_columns(column... | 32 | Allow opposite of remove_columns on Dataset and DatasetDict
### Feature request
In this blog post https://huggingface.co/blog/audio-datasets, I noticed the following code:
```python
COLUMNS_TO_KEEP = ["text", "audio"]
all_columns = gigaspeech["train"].column_names
columns_to_remove = set(all_columns) - set(COL... | [
-0.059547629207372665,
0.2965109348297119,
-0.11649046093225479,
-0.02090546116232872,
0.26692667603492737,
0.12014485150575638,
0.3992058038711548,
0.22160521149635315,
0.12385550141334534,
0.4325326681137085,
-0.3550335764884949,
0.252955824136734,
-0.37047243118286133,
0.241177693009376... |
https://github.com/huggingface/datasets/issues/5464 | Thanks for reporting, @sarahwie.
Please note this issue was already fixed in `datasets` 2.6.0 version:
- #5040
If you update your `datasets` version, you will be able to load the dataset:
```
pip install -U datasets
``` | NonMatchingChecksumError for hendrycks_test | ### Describe the bug
The checksum of the file has likely changed on the remote host.
### Steps to reproduce the bug
`dataset = nlp.load_dataset("hendrycks_test", "anatomy")`
### Expected behavior
no error thrown
### Environment info
- `datasets` version: 2.2.1
- Platform: macOS-13.1-arm64-arm-64bit
- Pyt... | 37 | NonMatchingChecksumError for hendrycks_test
### Describe the bug
The checksum of the file has likely changed on the remote host.
### Steps to reproduce the bug
`dataset = nlp.load_dataset("hendrycks_test", "anatomy")`
### Expected behavior
no error thrown
### Environment info
- `datasets` version: 2.2.1
... | [
-0.00027408450841903687,
0.07948169112205505,
-0.06093335524201393,
0.0809246227145195,
0.07030583918094635,
-0.02445623278617859,
0.05884633585810661,
0.6205694675445557,
0.19508545100688934,
0.079721599817276,
-0.08397641777992249,
0.2846689224243164,
0.13756686449050903,
-0.394675046205... |
https://github.com/huggingface/datasets/issues/5461 | Ccing @dwofk (the author of `fast-depth`).
Thanks, @awsaf49 for reporting this. I believe this is because the NYU Depth V2 shipped from `fast-depth` is already preprocessed.
If you think it might be better to have the NYU Depth V2 dataset from BTS [here](https://huggingface.co/datasets/sayakpaul/nyu_depth_v2) f... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 56 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Good catch ! Ideally it would be nice to have the datasets in the raw form, this way users can choose whatever processing they want to apply | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 27 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | > Ccing @dwofk (the author of `fast-depth`).
>
> Thanks, @awsaf49 for reporting this. I believe this is because the NYU Depth V2 shipped from `fast-depth` is already preprocessed.
>
> If you think it might be better to have the NYU Depth V2 dataset from BTS [here](https://huggingface.co/datasets/sayakpaul/nyu_dep... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 155 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | I think BTS. Repositories like https://github.com/vinvino02/GLPDepth usually use BTS. Also, just for clarity, the PR will be to https://huggingface.co/datasets/sayakpaul/nyu_depth_v2. Once we have worked it out, we can update the following things:
* https://github.com/huggingface/blog/pull/718
* https://huggingface... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 55 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | @sayakpaul If I get this right I have to,
1. Create a PR on https://huggingface.co/datasets/sayakpaul/nyu_depth_v2
2. Create a PR on https://github.com/huggingface/blog
3. Create a PR on https://github.com/huggingface/datasets to update https://github.com/huggingface/datasets/blob/main/docs/source/depth_estimation.m... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 30 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Yup opening a PR to use BTS on https://huggingface.co/datasets/sayakpaul/nyu_depth_v2 sounds good :) Thanks for the help ! | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 17 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Finally, I have found the origin of the **discretized depth map**. When I first loaded the datasets from HF I noticed it was 30GB but in DenseDepth data is only 4GB with dtype=uint8. This means data from fast-depth (before loading to HF) must have high precision. So when I tried to dig deeper by directly loading depth_... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 270 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Thanks so much for digging into this.
Since the second solution entails changes to core datatypes in `datasets`, I think it's better to go with the first solution.
@lhoestq WDYT? | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 30 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | @sayakpaul Yes, Solution 1 requires minimal change and provides no precision loss. But I think support for `uint16` image would be a great addition as many datasets come with `uint16` image. For example [UW-Madison GI Tract Image Segmentation](https://www.kaggle.com/competitions/uw-madison-gi-tract-image-segmentation) ... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 77 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Using Array2D makes it not practical to use to train a model - in `transformers` we expect an image type.
There is a pull request to support more precision than uint8 in Image() here: https://github.com/huggingface/datasets/pull/5365/files
we can probably merge it today and do a release right away | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 47 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Fantastic, @lhoestq!
@awsaf49 then let's wait for the PR to get merged and then take the next steps? | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 18 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | The PR adds support for uint16 which is ok for BTS if I understand correctly, would it be ok for you ? | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 22 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | If the main issue with the current version of NYU we have on the Hub is related to the precision loss stemming from `Image()`, I'd prefer if `Image()` supported float32 as well. | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 32 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | I also prefer `float32` as it offers more precision. But I'm not sure if we'll be able to visualize image with `float32` precision. | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 23 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | We could have a separate loading for the float32 one using Array2D, but I feel like it's less convenient to use due to the amount of disk space and because it's not an Image() type. That's why I think uint16 is a better solution for users | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 46 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Yep. I just tested from the PR and it works:
```python
>>> train_dataset = load_dataset("sayakpaul/nyu_depth_v2", split="train", streaming=True)
Downloading readme: 100%|██████████████████| 8.71k/8.71k [00:00<00:00, 3.60MB/s]
>>> next(iter(train_dataset))
{'... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 120 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Great! the case is closed! This issue has been solved and I have to say, it was quite the thrill ride. I felt like Sherlock Holmes, solving a mystery and finding the bug🕵️♂️. But in all seriousness, it was a pleasure working on this issue and I'm glad we could get to the bottom of it.
On another note, should I con... | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 77 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Haha thanks Mr Holmes :p
maybe let's close this issue when we're done updating the blog post and the documentation | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 20 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | @awsaf49 thank you for your hard work!
I am a little unsure why the other links need to be updated, though. They all rely on datasets internally. | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 27 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | I think depth_map still shows discretized version. It would be nice to have corrected one.
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/datasets/depth_est_target_viz.png" width = 300> | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 20 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Also, I think we need to make some changes in the code to visualize depth_map as it is `float32` . `plot.imshow()` supports either [0, 1] + float32 or [0. 255] + uint8 | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 32 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5461 | Oh yes! Do you want to start with the fixes? Please feel free to say no but I wanted to make sure your contributions are reflected properly in our doc and the blog :) | Discrepancy in `nyu_depth_v2` dataset | ### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different from actual ones. Here is a side-by-sid... | 34 | Discrepancy in `nyu_depth_v2` dataset
### Describe the bug
I think there is a discrepancy between depth map of `nyu_depth_v2` dataset [here](https://huggingface.co/docs/datasets/main/en/depth_estimation) and actual depth map. Depth values somehow got **discretized/clipped** resulting in depth maps that are different... | [
0.23812708258628845,
-0.6135583519935608,
-0.004315335303544998,
0.4543876647949219,
-0.08939266204833984,
-0.08266986906528473,
-0.08205530047416687,
0.21562305092811584,
-0.4176969528198242,
0.32503944635391235,
-0.31374356150627136,
0.16545598208904266,
0.259694367647171,
-0.19970452785... |
https://github.com/huggingface/datasets/issues/5458 | Hi! Yes, that's correct. When `streaming` is `True`, only split names can be specified as `split`, and for slicing, you have to use `.skip`/`.take` instead.
E.g.
`load_dataset("lhoestq/demo1",revision=None, streaming=True, split="train[:3]")`
rewritten with `.skip`/`.take`:
`load_dataset("lhoestq/demo1",revisi... | slice split while streaming | ### Describe the bug
When using the `load_dataset` function with streaming set to True, slicing splits is apparently not supported.
Did I miss this in the documentation?
### Steps to reproduce the bug
`load_dataset("lhoestq/demo1",revision=None, streaming=True, split="train[:3]")`
causes ValueError: Bad split:... | 35 | slice split while streaming
### Describe the bug
When using the `load_dataset` function with streaming set to True, slicing splits is apparently not supported.
Did I miss this in the documentation?
### Steps to reproduce the bug
`load_dataset("lhoestq/demo1",revision=None, streaming=True, split="train[:3]")`
... | [
-0.5406310558319092,
0.23080375790596008,
-0.012679282575845718,
0.055922865867614746,
0.21875804662704468,
-0.009209945797920227,
0.49410802125930786,
0.2683310806751251,
-0.2659660279750824,
0.17080582678318024,
-0.13953116536140442,
0.37412887811660767,
-0.13417571783065796,
0.311876118... |
https://github.com/huggingface/datasets/issues/5457 | Hi!
This issue is due to our audio/image datasets not being self-contained. This allows us to save disk space (files are written only once) but also leads to the issues like this one. We plan to make all our datasets self-contained in Datasets 3.0.
In the meantime, you can run the following map to ensure your da... | prebuilt dataset relies on `downloads/extracted` | ### Describe the bug
I pre-built the dataset:
```
python -c 'import sys; from datasets import load_dataset; ds=load_dataset(sys.argv[1])' HuggingFaceM4/general-pmd-synthetic-testing
```
and it can be used just fine.
now I wipe out `downloads/extracted` and it no longer works.
```
rm -r ~/.cache/huggingface... | 76 | prebuilt dataset relies on `downloads/extracted`
### Describe the bug
I pre-built the dataset:
```
python -c 'import sys; from datasets import load_dataset; ds=load_dataset(sys.argv[1])' HuggingFaceM4/general-pmd-synthetic-testing
```
and it can be used just fine.
now I wipe out `downloads/extracted` and it... | [
-0.23342031240463257,
-0.32519757747650146,
-0.01748107373714447,
0.3917652666568756,
0.29942944645881653,
0.001867249608039856,
0.045917414128780365,
-0.003527865745127201,
-0.07234806567430496,
0.12349636852741241,
-0.19353316724300385,
-0.023835262283682823,
-0.14854159951210022,
0.1215... |
https://github.com/huggingface/datasets/issues/5457 | Understood. Thank you, Mario.
Perhaps the solution could be very simple - move the extracted files into the directory of the cached dataset? Which would make it self-contained already and won't require waiting for a new major release. Unless I'm missing some back-compat nuance.
But regardless if X relies on Y - i... | prebuilt dataset relies on `downloads/extracted` | ### Describe the bug
I pre-built the dataset:
```
python -c 'import sys; from datasets import load_dataset; ds=load_dataset(sys.argv[1])' HuggingFaceM4/general-pmd-synthetic-testing
```
and it can be used just fine.
now I wipe out `downloads/extracted` and it no longer works.
```
rm -r ~/.cache/huggingface... | 76 | prebuilt dataset relies on `downloads/extracted`
### Describe the bug
I pre-built the dataset:
```
python -c 'import sys; from datasets import load_dataset; ds=load_dataset(sys.argv[1])' HuggingFaceM4/general-pmd-synthetic-testing
```
and it can be used just fine.
now I wipe out `downloads/extracted` and it... | [
-0.23342031240463257,
-0.32519757747650146,
-0.01748107373714447,
0.3917652666568756,
0.29942944645881653,
0.001867249608039856,
0.045917414128780365,
-0.003527865745127201,
-0.07234806567430496,
0.12349636852741241,
-0.19353316724300385,
-0.023835262283682823,
-0.14854159951210022,
0.1215... |
https://github.com/huggingface/datasets/issues/5454 | Something that'd be nice to have is "manual update of state". One of the learning from training LLMs is the ability to skip some batches whenever we notice huge spike might be handy. | Save and resume the state of a DataLoader | It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to have a PyTorch Sampler state that can be sav... | 33 | Save and resume the state of a DataLoader
It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to ... | [
-0.5903909206390381,
0.1260583996772766,
0.008841346949338913,
0.09381064772605896,
0.035903286188840866,
-0.04264596849679947,
0.08397180587053299,
0.1245691180229187,
0.09366587549448013,
0.1594846546649933,
-0.048977144062519073,
0.3148062825202942,
-0.49717244505882263,
0.0750831440091... |
https://github.com/huggingface/datasets/issues/5454 | Your outline spec is very sound and clear, @lhoestq - thank you!
@thomasw21, indeed that would be a wonderful extra feature. In Megatron-Deepspeed we manually drained the dataloader for the range we wanted. I wasn't very satisfied with the way we did it, since its behavior would change if you were to do multiple ran... | Save and resume the state of a DataLoader | It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to have a PyTorch Sampler state that can be sav... | 97 | Save and resume the state of a DataLoader
It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to ... | [
-0.5778517723083496,
0.0768948346376419,
0.05009643733501434,
-0.0014429278671741486,
-0.04135371372103691,
-0.06766049563884735,
0.2971259355545044,
0.07434363663196564,
-0.04055030643939972,
0.17337939143180847,
-0.22597862780094147,
0.2864455580711365,
-0.34364569187164307,
0.3720189929... |
https://github.com/huggingface/datasets/issues/5454 | Hi there! I think this is a critical issue and have an urgent need for it, in my attempt to train on a super large-scale dataset using `datasets`. It is impossible to resume a time-consuming (like one month) experiment by iterating all seen data again, which could possibly cost several days.
@stas00 @thomasw21 @lhoe... | Save and resume the state of a DataLoader | It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to have a PyTorch Sampler state that can be sav... | 63 | Save and resume the state of a DataLoader
It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to ... | [
-0.5742829442024231,
0.28346580266952515,
-0.016857072710990906,
0.12780524790287018,
-0.01520814560353756,
-0.1207970380783081,
0.225341796875,
0.06700681149959564,
0.054651111364364624,
0.053413935005664825,
-0.0897180587053299,
0.18916106224060059,
-0.31394723057746887,
0.20049962401390... |
https://github.com/huggingface/datasets/issues/5454 | No update so far, I wonder if someone implemented a resumable pytorch Sampler somwhere.
Then regarding resuming a streaming dataset, we'd first like to have an efficient way to skip shards automatically but this is not implemented yet | Save and resume the state of a DataLoader | It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to have a PyTorch Sampler state that can be sav... | 38 | Save and resume the state of a DataLoader
It would be nice when using `datasets` with a PyTorch DataLoader to be able to resume a training from a DataLoader state (e.g. to resume a training that crashed)
What I have in mind (but lmk if you have other ideas or comments):
For map-style datasets, this requires to ... | [
-0.545052170753479,
0.18089738488197327,
0.0189497172832489,
0.1065581887960434,
-0.02983911521732807,
-0.19417406618595123,
0.21635058522224426,
0.0065643880516290665,
0.032244451344013214,
0.07169634848833084,
-0.06208065152168274,
0.20047464966773987,
-0.3609520196914673,
0.296282708644... |
https://github.com/huggingface/datasets/issues/5451 | Hi ! Could you share the full stack trace ? Which dataset did you try to load ?
it may be related to https://github.com/huggingface/datasets/pull/5640 | ImageFolder BadZipFile: Bad offset for central directory | ### Describe the bug
I'm getting the following exception:
```
lib/python3.10/zipfile.py:1353 in _RealGetContents │
│ │
│ 1350 │ │ # self.start_dir: Position of start of central directory ... | 24 | ImageFolder BadZipFile: Bad offset for central directory
### Describe the bug
I'm getting the following exception:
```
lib/python3.10/zipfile.py:1353 in _RealGetContents │
│ │
│ 1350 │ │ # self.start_dir... | [
-0.30214861035346985,
-0.12889057397842407,
0.00013352558016777039,
0.5274218320846558,
0.3718421459197998,
0.0452704131603241,
-0.03887476399540901,
0.1373579055070877,
-0.2835584878921509,
0.111539825797081,
0.0965227335691452,
0.02506321668624878,
-0.054753489792346954,
-0.1096770465373... |
https://github.com/huggingface/datasets/issues/5451 | The `BadZipFile` error means the ZIP file is corrupted, so I'm closing this issue as it's not directly related to `datasets`. | ImageFolder BadZipFile: Bad offset for central directory | ### Describe the bug
I'm getting the following exception:
```
lib/python3.10/zipfile.py:1353 in _RealGetContents │
│ │
│ 1350 │ │ # self.start_dir: Position of start of central directory ... | 21 | ImageFolder BadZipFile: Bad offset for central directory
### Describe the bug
I'm getting the following exception:
```
lib/python3.10/zipfile.py:1353 in _RealGetContents │
│ │
│ 1350 │ │ # self.start_dir... | [
-0.385819673538208,
-0.010460525751113892,
-0.012386996299028397,
0.5257977247238159,
0.27683886885643005,
0.06778986006975174,
-0.04070861265063286,
0.14764100313186646,
-0.3230074346065521,
0.1038583368062973,
0.12979817390441895,
0.07092404365539551,
-0.04522545635700226,
-0.22738981246... |
https://github.com/huggingface/datasets/issues/5451 | For others that find this issue following a `BadZipFile` error, I had the same problem because I had a file in a folder dataset `my-image.target` and the datasets library was incorrectly determining that the (PNG) file was a zip archive. When it tried to extract the file, this error occurred.
Updating to `datasets=... | ImageFolder BadZipFile: Bad offset for central directory | ### Describe the bug
I'm getting the following exception:
```
lib/python3.10/zipfile.py:1353 in _RealGetContents │
│ │
│ 1350 │ │ # self.start_dir: Position of start of central directory ... | 58 | ImageFolder BadZipFile: Bad offset for central directory
### Describe the bug
I'm getting the following exception:
```
lib/python3.10/zipfile.py:1353 in _RealGetContents │
│ │
│ 1350 │ │ # self.start_dir... | [
-0.340802937746048,
0.04916214942932129,
-0.015479233115911484,
0.4781762659549713,
0.3053164780139923,
0.02558206021785736,
-0.04669615626335144,
0.1812160611152649,
-0.31356924772262573,
0.09213098138570786,
0.10882578790187836,
0.04875485599040985,
-0.05684617906808853,
-0.2204920947551... |
https://github.com/huggingface/datasets/issues/5450 | A possible hint: The function it seems to be spending a lot of time in (when iterating over the original dataset) is `_get_mp` in the PIL JPEG decoder:

| to_tf_dataset with a TF collator causes bizarrely persistent slowdown | ### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets that, when you iterate over them with `to_tf_dataset` **and** a data colla... | 29 | to_tf_dataset with a TF collator causes bizarrely persistent slowdown
### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets th... | [
-0.23047463595867157,
-0.06307940185070038,
0.056947752833366394,
0.1785081923007965,
0.26043063402175903,
0.053447335958480835,
0.2793619930744171,
0.18530429899692535,
-0.3290843963623047,
0.28478312492370605,
-0.12698468565940857,
0.4587996006011963,
-0.0764392837882042,
-0.009690806269... |
https://github.com/huggingface/datasets/issues/5450 | If "mp" is multiprocessing, this might suggest some kind of negative interaction between the JPEG decoder and TF's handling of processes/threads. Note that we haven't merged the parallel `to_tf_dataset` PR yet, so it's not caused by that PR! | to_tf_dataset with a TF collator causes bizarrely persistent slowdown | ### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets that, when you iterate over them with `to_tf_dataset` **and** a data colla... | 38 | to_tf_dataset with a TF collator causes bizarrely persistent slowdown
### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets th... | [
-0.25837022066116333,
-0.07155791670084,
0.07093451917171478,
0.15416017174720764,
0.2888793349266052,
0.023602217435836792,
0.27065566182136536,
0.17421698570251465,
-0.4144013226032257,
0.31717151403427124,
-0.1040777936577797,
0.4773678183555603,
-0.07838495075702667,
0.0282794460654258... |
https://github.com/huggingface/datasets/issues/5450 | Update: MP isn't multiprocessing at all, it's an internal PIL method for loading metadata from JPEG files. No idea why that would be a bottleneck, but I'll see if a Python profiler can't figure out where the time is actually being spent. | to_tf_dataset with a TF collator causes bizarrely persistent slowdown | ### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets that, when you iterate over them with `to_tf_dataset` **and** a data colla... | 42 | to_tf_dataset with a TF collator causes bizarrely persistent slowdown
### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets th... | [
-0.26886749267578125,
-0.0859384685754776,
0.07341063767671585,
0.1562882959842682,
0.2705060839653015,
0.028361208736896515,
0.3037559390068054,
0.14333954453468323,
-0.38831573724746704,
0.3228149712085724,
-0.12251170724630356,
0.467703253030777,
-0.06810688972473145,
0.0365348011255264... |
https://github.com/huggingface/datasets/issues/5450 | After further profiling, the slowdown is in the C methods for JPEG decoding that are included as part of PIL. Because Python profilers can't inspect inside that, I don't have any further information on which lines exactly are responsible for the slowdown or why.
In the meantime, I'm going to suggest switching from `... | to_tf_dataset with a TF collator causes bizarrely persistent slowdown | ### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets that, when you iterate over them with `to_tf_dataset` **and** a data colla... | 76 | to_tf_dataset with a TF collator causes bizarrely persistent slowdown
### Describe the bug
This will make more sense if you take a look at [a Colab notebook that reproduces this issue.](https://colab.research.google.com/drive/1rxyeciQFWJTI0WrZ5aojp4Ls1ut18fNH?usp=sharing)
Briefly, there are several datasets th... | [
-0.19386005401611328,
0.03455589711666107,
0.02873832732439041,
0.18287545442581177,
0.2498311996459961,
0.09574054181575775,
0.29584985971450806,
0.24303993582725525,
-0.32839906215667725,
0.32617220282554626,
-0.12927186489105225,
0.4373801350593567,
-0.08544526249170303,
-0.038066826760... |
https://github.com/huggingface/datasets/issues/5444 | Looks like a duplicate of https://github.com/huggingface/datasets/issues/1948.
I also think these should be logged as INFO messages, but let's see what @lhoestq thinks. | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 22 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
0.14982546865940094,
-0.21058626472949982,
-0.05635574832558632,
0.3685871362686157,
0.20154359936714172,
0.316570520401001,
0.391324520111084,
0.2663445472717285,
0.14894583821296692,
-0.18562638759613037,
-0.005769647657871246,
0.27930912375450134,
-0.37144947052001953,
0.156527057290077... |
https://github.com/huggingface/datasets/issues/5444 | It can be considered unexpected to see a `map` function return instantaneously. The warning is here to explain this case by mentioning that the cache was used. I don't expect first time users (only seeing warnings) to guess that the cache works this way | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 44 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
0.0166570246219635,
-0.07572843879461288,
-0.08646492660045624,
0.2924629747867584,
0.2787711024284363,
0.26734790205955505,
0.24067944288253784,
0.3686366081237793,
0.3335387110710144,
-0.11565133184194565,
-0.0401441715657711,
0.3138652741909027,
-0.30156368017196655,
-0.1306746602058410... |
https://github.com/huggingface/datasets/issues/5444 | Oh, so it's intentional? Do all Hugging Face packages use `warning` when using cache?
I guess feel free to close this issue then. | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 23 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
0.14408499002456665,
-0.22918927669525146,
-0.0032130591571331024,
0.3233471214771271,
0.37744376063346863,
0.3381856083869934,
0.31798118352890015,
0.285707950592041,
0.3093981146812439,
-0.12606379389762878,
-0.003065604716539383,
0.0036432258784770966,
-0.26750603318214417,
0.0705038458... |
https://github.com/huggingface/datasets/issues/5444 | Yes it's intentional for `map`. For `load_dataset` it's also intentional but for a different reason: it shows where in the cache the dataset is located, in case the user wants to clear the cache. | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 34 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
0.11643531918525696,
-0.19251157343387604,
-0.03884262591600418,
0.3318285048007965,
0.264274001121521,
0.3550267815589905,
0.36194515228271484,
0.32492658495903015,
0.4101952016353607,
-0.1853105127811432,
-0.011977534741163254,
0.4151664972305298,
-0.21757519245147705,
-0.045103754848241... |
https://github.com/huggingface/datasets/issues/5444 | OK I see. It's surprising to me that these are considered "something unexpected happened", the concept of cache is pretty common.
Has a user every actually complained that they ran their code once, and it took a minute while the data downloaded, then ran their code again and it ran really fast (and completed success... | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 183 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
0.1495266705751419,
0.012142464518547058,
-0.04143375903367996,
0.30160579085350037,
0.1850385069847107,
0.27511492371559143,
0.31567853689193726,
0.17848314344882965,
0.13307029008865356,
-0.1757880449295044,
0.12940087914466858,
0.16204211115837097,
-0.43204909563064575,
-0.1107401102781... |
https://github.com/huggingface/datasets/issues/5444 | I see your point and I'm not closed to switching to INFO, but I think those logs are important to make the library less opaque. I also just checked `transformers` scripts and they default to INFO which is nice. However for colab users the default is still WARNING iirc, and it counts as one of the main env where `datase... | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 94 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
-0.07937072962522507,
0.07965405285358429,
0.02984810620546341,
0.056106533855199814,
0.19800136983394623,
0.1777946949005127,
0.4890157878398895,
0.2522009611129761,
0.0068496838212013245,
0.16207541525363922,
0.0032054148614406586,
0.3687070310115814,
-0.27727413177490234,
0.081741765141... |
https://github.com/huggingface/datasets/issues/5444 | These kinds of messages are logged as INFO in Transformers, so we should probably be consistent with them | info messages logged as warnings | ### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from the Python docs for reference:
* I... | 18 | info messages logged as warnings
### Describe the bug
Code in `datasets` is using `logger.warning` when it should be using `logger.info`.
Some of these are probably a matter of opinion, but I think anything starting with `logger.warning(f"Loading chached` clearly falls into the info category.
Definitions from ... | [
0.0693158358335495,
-0.15233160555362701,
-0.06864529103040695,
0.25989431142807007,
0.29669255018234253,
0.17542390525341034,
0.3664940297603607,
0.28376659750938416,
0.07602947950363159,
-0.08946321904659271,
0.04998615384101868,
0.30867671966552734,
-0.31391817331314087,
-0.000153981149... |
https://github.com/huggingface/datasets/issues/5442 | Hi!
We use [`fsspec`](https://github.com/fsspec/filesystem_spec) to integrate with storage providers. You can find more info (and the usage examples) in [our docs](https://huggingface.co/docs/datasets/v2.8.0/filesystems#download-and-prepare-a-dataset-into-a-cloud-storage).
[`gdrivefs`](https://github.com/fsspec/... | OneDrive Integrations with HF Datasets | ### Feature request
First of all , I would like to thank all community who are developed DataSet storage and make it free available
How to integrate our Onedrive account or any other possible storage clouds (like google drive,...) with the **HF** datasets section.
For example, if I have **50GB** on my **Onedrive*... | 67 | OneDrive Integrations with HF Datasets
### Feature request
First of all , I would like to thank all community who are developed DataSet storage and make it free available
How to integrate our Onedrive account or any other possible storage clouds (like google drive,...) with the **HF** datasets section.
For exa... | [
-0.22796817123889923,
0.09350572526454926,
-0.12087246775627136,
0.06623038649559021,
0.09376972168684006,
0.19753454625606537,
0.19331827759742737,
-0.1268387883901596,
0.20081692934036255,
0.2274128943681717,
-0.26401931047439575,
-0.33771616220474243,
0.07262596487998962,
0.597121119499... |
https://github.com/huggingface/datasets/issues/5437 | Hi! Can you please share the directory structure of your image folder and the `load_dataset` call? We decode images with Pillow, and Pillow supports RGBA PNGs, so this shouldn't be a problem.
| Can't load png dataset with 4 channel (RGBA) | I try to create dataset which contains about 9000 png images 64x64 in size, and they are all 4-channel (RGBA). When trying to use load_dataset() then a dataset is created from only 2 images. What exactly interferes I can not understand.
I try to create dataset which contains about 9000 png images 64x64 in size, and they are all 4-channel (RGBA). When trying to use load_dataset() then a dataset is created from only 2 images. What exactly interferes I can not understand. | I try to create dataset which contains about 9000 png images 64x64 in size, and they are all 4-channel (RGBA). When trying to use load_dataset() then a dataset is created from only 2 images. What exactly interferes I can not understand.
I try to create dataset which contains about 9000 png images 64x64 in size, and they are all 4-channel (RGBA). When trying to use load_dataset() then a dataset is created from only 2 images. What exactly interferes I can not understand. | I try to create dataset which contains about 9000 png images 64x64 in size, and they are all 4-channel (RGBA). When trying to use load_dataset() then a dataset is created from only 2 images. What exactly interferes I can not understand.
I try to create dataset which contains about 9000 png images 64x64 in size, and they are all 4-channel (RGBA). When trying to use load_dataset() then a dataset is created from only 2 images. What exactly interferes I can not understand., it states:
> Using take (or skip) prevents future calls to shuffle from shuffling the dataset shards order, otherwise the taken examples cou... | 77 | Wrong statement in "Load a Dataset in Streaming mode" leads to data leakage
### Describe the bug
In the [Split your dataset with take and skip](https://huggingface.co/docs/datasets/v1.10.2/dataset_streaming.html#split-your-dataset-with-take-and-skip), it states:
> Using take (or skip) prevents future calls to shu... | [
-0.23544634878635406,
-0.3448910713195801,
0.04568539187312126,
0.2079867720603943,
0.09651220589876175,
-0.10035929828882217,
0.15472190082073212,
-0.008569551631808281,
-0.08035459369421005,
0.21870066225528717,
-0.22085176408290863,
0.26449593901634216,
-0.16437017917633057,
0.288862586... |
https://github.com/huggingface/datasets/issues/5435 | Also note that you are referring to an outdated documentation page: datasets 1.10.2 version
Current datasets version is 2.8.0 and the corresponding documentation page is: https://huggingface.co/docs/datasets/stream#split-dataset | Wrong statement in "Load a Dataset in Streaming mode" leads to data leakage | ### Describe the bug
In the [Split your dataset with take and skip](https://huggingface.co/docs/datasets/v1.10.2/dataset_streaming.html#split-your-dataset-with-take-and-skip), it states:
> Using take (or skip) prevents future calls to shuffle from shuffling the dataset shards order, otherwise the taken examples cou... | 26 | Wrong statement in "Load a Dataset in Streaming mode" leads to data leakage
### Describe the bug
In the [Split your dataset with take and skip](https://huggingface.co/docs/datasets/v1.10.2/dataset_streaming.html#split-your-dataset-with-take-and-skip), it states:
> Using take (or skip) prevents future calls to shu... | [
-0.3435990810394287,
-0.32089072465896606,
0.020285114645957947,
0.11951372027397156,
0.04799376055598259,
-0.10927797108888626,
0.15338920056819916,
0.013209741562604904,
-0.1192818433046341,
0.22939851880073547,
-0.17026352882385254,
0.3156094253063202,
-0.1657131016254425,
0.25119936466... |
https://github.com/huggingface/datasets/issues/5435 | Hi @albertvillanova thanks for your reply and your explaination here.
Sorry for the confusion as I'm not actually a user of your repo and I just happen to find the thread by Google (and didn't read carefully).
Great to know that and you made everything very clear now.
Thanks for your time and sorry for the co... | Wrong statement in "Load a Dataset in Streaming mode" leads to data leakage | ### Describe the bug
In the [Split your dataset with take and skip](https://huggingface.co/docs/datasets/v1.10.2/dataset_streaming.html#split-your-dataset-with-take-and-skip), it states:
> Using take (or skip) prevents future calls to shuffle from shuffling the dataset shards order, otherwise the taken examples cou... | 63 | Wrong statement in "Load a Dataset in Streaming mode" leads to data leakage
### Describe the bug
In the [Split your dataset with take and skip](https://huggingface.co/docs/datasets/v1.10.2/dataset_streaming.html#split-your-dataset-with-take-and-skip), it states:
> Using take (or skip) prevents future calls to shu... | [
-0.30101022124290466,
-0.31945836544036865,
0.01897687464952469,
0.14208625257015228,
0.07016025483608246,
-0.13381195068359375,
0.14968569576740265,
0.01595323532819748,
-0.10752077400684357,
0.19779837131500244,
-0.13916067779064178,
0.30087047815322876,
-0.14255280792713165,
0.271045833... |
https://github.com/huggingface/datasets/issues/5433 | Sorry, it was us:[^1] https://github.com/iterative/cml/pull/1317 & https://github.com/iterative/cml/issues/1319#issuecomment-1385599559; should be fixed with [v0.18.17](https://github.com/iterative/cml/releases/tag/v0.18.17).
[^1]: More or less, see https://github.com/yargs/yargs/issues/873. | Support latest Docker image in CI benchmarks | Once we find out the root cause of:
- #5431
we should revert the temporary pin on the Docker image version introduced by:
- #5432 | 18 | Support latest Docker image in CI benchmarks
Once we find out the root cause of:
- #5431
we should revert the temporary pin on the Docker image version introduced by:
- #5432
Sorry, it was us:[^1] https://github.com/iterative/cml/pull/1317 & https://github.com/iterative/cml/issues/1319#issuecomment-1385599559... | [
-0.6130570769309998,
-0.29239365458488464,
-0.10609729588031769,
-0.16350755095481873,
0.1334022581577301,
-0.20803946256637573,
0.3374069631099701,
0.28598207235336304,
-0.15508368611335754,
0.4208764433860779,
0.2168097347021103,
0.2165181040763855,
-0.010055327787995338,
-0.011116780340... |
https://github.com/huggingface/datasets/issues/5433 | Hi @0x2b3bfa0, thanks a lot for the investigation, the context about the the root cause and for fixing it!!
We are reviewing your PR to unpin the container image. | Support latest Docker image in CI benchmarks | Once we find out the root cause of:
- #5431
we should revert the temporary pin on the Docker image version introduced by:
- #5432 | 29 | Support latest Docker image in CI benchmarks
Once we find out the root cause of:
- #5431
we should revert the temporary pin on the Docker image version introduced by:
- #5432
Hi @0x2b3bfa0, thanks a lot for the investigation, the context about the the root cause and for fixing it!!
We are reviewing your PR... | [
-0.6018890142440796,
-0.35306012630462646,
-0.1828647255897522,
0.09429213404655457,
0.13937292993068695,
-0.2540072202682495,
0.32534098625183105,
0.2550433278083801,
-0.04308368265628815,
0.4227411448955536,
0.2362530529499054,
0.2828245460987091,
0.14544565975666046,
0.17262423038482666... |
https://github.com/huggingface/datasets/issues/5430 | Some of the shard files now have 0 number of rows.
We have opened an issue in the Apache Beam repo:
- https://github.com/apache/beam/issues/25041 | Support Apache Beam >= 2.44.0 | Once we find out the root cause of:
- #5426
we should revert the temporary pin on apache-beam introduced by:
- #5429 | 23 | Support Apache Beam >= 2.44.0
Once we find out the root cause of:
- #5426
we should revert the temporary pin on apache-beam introduced by:
- #5429
Some of the shard files now have 0 number of rows.
We have opened an issue in the Apache Beam repo:
- https://github.com/apache/beam/issues/25041 | [
-0.09712105244398117,
-0.17724692821502686,
-0.11105605959892273,
0.1344011425971985,
0.0597832165658474,
-0.3304859399795532,
0.3070106506347656,
0.5164263844490051,
-0.1447831094264984,
0.47725218534469604,
0.07314237207174301,
-0.08870691061019897,
-0.030461039394140244,
0.0247543305158... |
https://github.com/huggingface/datasets/issues/5428 | Hi! Sure, feel free to submit a PR. Maybe if we want to be consistent with the existing API, it would be cleaner to directly add support for `fsspec` paths in `Dataset.load_faiss_index`/`Dataset.save_faiss_index` in the same manner as it was done in `Dataset.load_from_disk`/`Dataset.save_to_disk`. | Load/Save FAISS index using fsspec | ### Feature request
From what I understand `faiss` already support this [link](https://github.com/facebookresearch/faiss/wiki/Index-IO,-cloning-and-hyper-parameter-tuning#generic-io-support)
I would like to use a stream as input to `Dataset.load_faiss_index` and `Dataset.save_faiss_index`.
### Motivation
In... | 42 | Load/Save FAISS index using fsspec
### Feature request
From what I understand `faiss` already support this [link](https://github.com/facebookresearch/faiss/wiki/Index-IO,-cloning-and-hyper-parameter-tuning#generic-io-support)
I would like to use a stream as input to `Dataset.load_faiss_index` and `Dataset.save_... | [
-0.30190861225128174,
-0.016891837120056152,
0.0011663064360618591,
0.026373671367764473,
-0.03606123477220535,
-0.14312487840652466,
0.14452746510505676,
0.08800764381885529,
0.30429112911224365,
0.3937056064605713,
-0.0766865462064743,
-0.024885470047593117,
0.121365487575531,
0.58028531... |
https://github.com/huggingface/datasets/issues/5427 | Thanks for reporting, @ilos-vigil.
We have transferred this issue to the corresponding dataset on the Hugging Face Hub: https://huggingface.co/datasets/id_clickbait/discussions/1 | Unable to download dataset id_clickbait | ### Describe the bug
I tried to download dataset `id_clickbait`, but receive this error message.
```
FileNotFoundError: Couldn't find file at https://md-datasets-cache-zipfiles-prod.s3.eu-west-1.amazonaws.com/k42j7x2kpn-1.zip
```
When i open the link using browser, i got this XML data.
```xml
<?xml versi... | 19 | Unable to download dataset id_clickbait
### Describe the bug
I tried to download dataset `id_clickbait`, but receive this error message.
```
FileNotFoundError: Couldn't find file at https://md-datasets-cache-zipfiles-prod.s3.eu-west-1.amazonaws.com/k42j7x2kpn-1.zip
```
When i open the link using browser, i... | [
-0.29217180609703064,
0.007941976189613342,
-0.04316461831331253,
0.3713676631450653,
0.2508446276187897,
0.2711386978626251,
0.3126252591609955,
0.3343467712402344,
-0.01812402904033661,
-0.07456420361995697,
-0.16542458534240723,
0.15880736708641052,
0.15100638568401337,
0.28887933492660... |
https://github.com/huggingface/datasets/issues/5425 | Hi!
`Dataset.sort` calls `df.sort_values` internally, and `df.sort_values` brings all the "sort" columns in memory, so sorting on multiple keys could be very expensive. This makes me think that maybe we can replace `df.sort_values` with `pyarrow.compute.sort_indices` - the latter can also sort on multiple keys and ... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 109 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
-0.10800600796937943,
0.06251589953899384,
-0.17726771533489227,
0.06900654733181,
0.35974523425102234,
-0.07434122264385223,
0.13469451665878296,
0.19574327766895294,
-0.03912913799285889,
0.1555030196905136,
-0.062490154057741165,
0.4349202513694763,
-0.0016665048897266388,
0.17523601651... |
https://github.com/huggingface/datasets/issues/5425 | @mariosasko If I understand the code right, using `pyarrow.compute.sort_indices` would also require changes to the `select` method if it is meant to sort multiple keys. That's because `select` only accepts 1D input for `indices`, not an iterable or similar which would be required for multiple keys unless you want some ... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 64 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
-0.023225218057632446,
0.14701546728610992,
-0.1609548032283783,
0.04371648654341698,
0.31552597880363464,
-0.01964309811592102,
0.2077915370464325,
0.21705685555934906,
-0.25569960474967957,
0.16988110542297363,
-0.06244167685508728,
0.42477181553840637,
0.02193928137421608,
0.20094740390... |
https://github.com/huggingface/datasets/issues/5425 | @MichlF No, it doesn't require modifying select because sorting on multiple keys also returns a 1D array.
It's easier to understand with an example:
```python
>>> import pyarrow as pa
>>> import pyarrow.compute as pc
>>> table = pa.table({
... "name": ["John", "Eve", "Peter", "John"],
... "surname": ["... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 76 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
-0.056908998638391495,
0.1014106273651123,
-0.21444381773471832,
-0.040863826870918274,
0.2572183609008789,
0.016521215438842773,
0.13104724884033203,
0.17361603677272797,
-0.13526830077171326,
0.1211918517947197,
-0.09460040926933289,
0.4578697979450226,
-0.03541870787739754,
0.1905054152... |
https://github.com/huggingface/datasets/issues/5425 | Thanks for clarifying.
I can prepare a PR to address this issue. This would be my first PR here so I have a few maybe silly questions but:
- What is the preferred input type of `sort_keys` for the sort method? A sequence with name, order tuples like pyarrow's `sort_indices` requires?
- What about backwards compatabi... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 112 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
0.11508460342884064,
0.1414811909198761,
-0.10742226988077164,
0.019289996474981308,
0.3735998272895813,
-0.03553654998540878,
0.1930680274963379,
0.10855557769536972,
-0.16140499711036682,
0.07203362137079239,
-0.026555918157100677,
0.32967060804367065,
-0.054732196033000946,
0.2641139030... |
https://github.com/huggingface/datasets/issues/5425 | I think we can have the following signature:
```python
def sort(
self,
column_names: Union[str, Sequence[str]],
reverse: Union[bool, Sequence[bool]] = False,
kind="deprecated",
null_placement: str = "last",
keep_in_memory: bool = False,
load_from_cache_fi... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 127 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
0.06601063907146454,
0.1372281014919281,
-0.16857990622520447,
-0.07267682254314423,
0.35078462958335876,
0.05755624920129776,
0.1764533519744873,
0.23617888987064362,
-0.028036240488290787,
0.04099021479487419,
-0.07484543323516846,
0.3425303101539612,
-0.10433493554592133,
0.248468667268... |
https://github.com/huggingface/datasets/issues/5425 | I am pretty much done with the PR. Just one clarification: `Sequence` in `arrow_dataset.py` is a custom dataclass from `features.py` instead of the `type.hinting` class `Sequence` from Python. Do you suggest using that custom `Sequence` class somehow ? Otherwise signature currently reads instead:
```Python
def so... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 119 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
0.054977431893348694,
0.10999922454357147,
-0.1699933409690857,
0.010580700822174549,
0.2577597200870514,
-0.014489054679870605,
0.15814873576164246,
0.20468489825725555,
-0.06443072110414505,
-0.013975650072097778,
0.060723237693309784,
0.41847285628318787,
-0.13011476397514343,
0.2602278... |
https://github.com/huggingface/datasets/issues/5425 | I meant `typing.Sequence` (`datasets.Sequence` is a feature type).
Regarding `null_placement`, I think we can support both `at_start` and `at_end`, and `last` and `first` (for backward compatibility; convert internally to `at_end` and `at_start` respectively). | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 33 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
0.025415346026420593,
0.042111173272132874,
-0.15855005383491516,
0.08235734701156616,
0.24547500908374786,
0.0047666579484939575,
0.21588340401649475,
0.1473596692085266,
-0.11042676120996475,
0.05442574620246887,
0.0009612850844860077,
0.2459622621536255,
0.010052569210529327,
0.31489458... |
https://github.com/huggingface/datasets/issues/5425 | > I meant typing.Sequence (datasets.Sequence is a feature type).
Sorry, I actually meant `typing.Sequence` and not `type.hinting`. However, the issue is still that `dataset.Sequence` is imported in `arrow_dataset.py` so I cannot import and use `typing.Sequence` for the `sort`'s signature without overwriting the `dat... | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 119 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
0.07531026005744934,
0.08347338438034058,
-0.10561542212963104,
0.025613311678171158,
0.30770301818847656,
0.039005622267723083,
0.2000206857919693,
0.2002663016319275,
0.09513292461633682,
-0.022417031228542328,
0.030367515981197357,
0.3968812823295593,
-0.14236213266849518,
0.32774618268... |
https://github.com/huggingface/datasets/issues/5425 | You can avoid the name collision by renaming `typing.Sequence` to `Sequence_` when importing:
```python
from typing import Sequence as Sequence_
``` | Sort on multiple keys with datasets.Dataset.sort() | ### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggested solution:
> ... having something similar to panda... | 21 | Sort on multiple keys with datasets.Dataset.sort()
### Feature request
From discussion on forum: https://discuss.huggingface.co/t/datasets-dataset-sort-does-not-preserve-ordering/29065/1
`sort()` does not preserve ordering, and it does not support sorting on multiple columns, nor a key function.
The suggeste... | [
-0.0001977980136871338,
-0.030910223722457886,
-0.21666103601455688,
-0.004868576303124428,
0.23341313004493713,
0.06577920913696289,
0.14013491570949554,
0.21374475955963135,
-0.002910759299993515,
0.09664604067802429,
-0.058280736207962036,
0.2569772005081177,
-0.046703875064849854,
0.33... |
https://github.com/huggingface/datasets/issues/5424 | Hi! You can get a `DatasetDict` if you pass a dictionary with read instructions as follows:
```python
instructions = [
ReadInstruction(split_name="train", from_=0, to=10, unit='%', rounding='closest'),
ReadInstruction(split_name="dev", from_=0, to=10, unit='%', rounding='closest'),
ReadInstruction(spli... | When applying `ReadInstruction` to custom load it's not DatasetDict but list of Dataset? | ### Describe the bug
I am loading datasets from custom `tsv` files stored locally and applying split instructions for each split. Although the ReadInstruction is being applied correctly and I was expecting it to be `DatasetDict` but instead it is a list of `Dataset`.
### Steps to reproduce the bug
Steps to reproduc... | 51 | When applying `ReadInstruction` to custom load it's not DatasetDict but list of Dataset?
### Describe the bug
I am loading datasets from custom `tsv` files stored locally and applying split instructions for each split. Although the ReadInstruction is being applied correctly and I was expecting it to be `DatasetDict`... | [
-0.01815449446439743,
-0.2128513902425766,
-0.08146754652261734,
0.458576500415802,
0.15075650811195374,
0.1885736733675003,
0.3720724582672119,
0.28502658009529114,
0.6990025043487549,
0.21726228296756744,
-0.38054004311561584,
0.262927770614624,
-0.1385861039161682,
0.11160560697317123,
... |
https://github.com/huggingface/datasets/issues/5422 | I can confirm that the error exists!
I'm trying to read 3 parquet files locally:
```python
from datasets import load_dataset, Features, Value, ClassLabel
review_dataset = load_dataset(
"parquet",
data_files={
"train": os.path.join(sentiment_analysis_data_path, "train.parquet"),
"valida... | Datasets load error for saved github issues | ### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: An error occurred while generating the dataset... | 95 | Datasets load error for saved github issues
### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: ... | [
-0.47101521492004395,
0.07906532287597656,
0.05953499674797058,
0.466485857963562,
0.22032469511032104,
0.09920288622379303,
0.3799692690372467,
0.2986513376235962,
0.09120292961597443,
-0.0145169198513031,
0.04182369261980057,
0.0986110121011734,
-0.2837833762168884,
0.18024827539920807,
... |
https://github.com/huggingface/datasets/issues/5422 | @Extremesarova I think this is a different issue, but understand using features could be a work-around.
It seems the field `closed_at` is `null` in many cases.
I've not found a way to specify only a single feature without (succesfully) specifiying the full and quite detailed set of expected features. Using this fea... | Datasets load error for saved github issues | ### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: An error occurred while generating the dataset... | 66 | Datasets load error for saved github issues
### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: ... | [
-0.47101521492004395,
0.07906532287597656,
0.05953499674797058,
0.466485857963562,
0.22032469511032104,
0.09920288622379303,
0.3799692690372467,
0.2986513376235962,
0.09120292961597443,
-0.0145169198513031,
0.04182369261980057,
0.0986110121011734,
-0.2837833762168884,
0.18024827539920807,
... |
https://github.com/huggingface/datasets/issues/5422 | Found this when searching for the same error, looks like based on #3965 it's just an issue with the data. I found that changing `df = pd.DataFrame.from_records(all_issues)` to `df = pd.DataFrame.from_records(all_issues).dropna(axis=1, how='all').drop(['milestone'], axis=1)` from the fetch_issues function fixed the issu... | Datasets load error for saved github issues | ### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: An error occurred while generating the dataset... | 65 | Datasets load error for saved github issues
### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: ... | [
-0.47101521492004395,
0.07906532287597656,
0.05953499674797058,
0.466485857963562,
0.22032469511032104,
0.09920288622379303,
0.3799692690372467,
0.2986513376235962,
0.09120292961597443,
-0.0145169198513031,
0.04182369261980057,
0.0986110121011734,
-0.2837833762168884,
0.18024827539920807,
... |
https://github.com/huggingface/datasets/issues/5422 | I have this same issue. I saved a dataset to disk and now I can't load it. | Datasets load error for saved github issues | ### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: An error occurred while generating the dataset... | 17 | Datasets load error for saved github issues
### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: ... | [
-0.47101521492004395,
0.07906532287597656,
0.05953499674797058,
0.466485857963562,
0.22032469511032104,
0.09920288622379303,
0.3799692690372467,
0.2986513376235962,
0.09120292961597443,
-0.0145169198513031,
0.04182369261980057,
0.0986110121011734,
-0.2837833762168884,
0.18024827539920807,
... |
https://github.com/huggingface/datasets/issues/5422 | Hi @folterj , I faced same issue while creating `issues_dataset` (https://huggingface.co/learn/nlp-course/chapter5/5?fw=pt). The fix which worked for me was loading the *.jsonl file as pd.read_json and then converting it into a Dataset using datasets API.
```
import pandas as pd
df=pd.read_json("datasets-issues.json... | Datasets load error for saved github issues | ### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: An error occurred while generating the dataset... | 55 | Datasets load error for saved github issues
### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: ... | [
-0.47101521492004395,
0.07906532287597656,
0.05953499674797058,
0.466485857963562,
0.22032469511032104,
0.09920288622379303,
0.3799692690372467,
0.2986513376235962,
0.09120292961597443,
-0.0145169198513031,
0.04182369261980057,
0.0986110121011734,
-0.2837833762168884,
0.18024827539920807,
... |
https://github.com/huggingface/datasets/issues/5422 | I understand some work-around suggestions would be to not use load_dataset(), and instead using a different API function. Another alternative would be using the same function using streaming, as I had already suggested in my original post.
However, the fact remains that there is an issue in this function as reported. | Datasets load error for saved github issues | ### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: An error occurred while generating the dataset... | 51 | Datasets load error for saved github issues
### Describe the bug
Loading a previously downloaded & saved dataset as described in the HuggingFace course:
issues_dataset = load_dataset("json", data_files="issues/datasets-issues.jsonl", split="train")
Gives this error:
datasets.builder.DatasetGenerationError: ... | [
-0.47101521492004395,
0.07906532287597656,
0.05953499674797058,
0.466485857963562,
0.22032469511032104,
0.09920288622379303,
0.3799692690372467,
0.2986513376235962,
0.09120292961597443,
-0.0145169198513031,
0.04182369261980057,
0.0986110121011734,
-0.2837833762168884,
0.18024827539920807,
... |
https://github.com/huggingface/datasets/issues/5421 | Closing as case-insensitivity should be only for URL redirection on the Hub. In the APIs, we will only support the canonical name (https://github.com/huggingface/moon-landing/pull/2399#issuecomment-1382085611) | Support case-insensitive Hub dataset name in load_dataset | ### Feature request
The dataset name on the Hub is case-insensitive (see https://github.com/huggingface/moon-landing/pull/2399, internal issue), i.e., https://huggingface.co/datasets/GLUE redirects to https://huggingface.co/datasets/glue.
Ideally, we could load the glue dataset using the following:
```
from d... | 23 | Support case-insensitive Hub dataset name in load_dataset
### Feature request
The dataset name on the Hub is case-insensitive (see https://github.com/huggingface/moon-landing/pull/2399, internal issue), i.e., https://huggingface.co/datasets/GLUE redirects to https://huggingface.co/datasets/glue.
Ideally, we cou... | [
-0.06038140878081322,
-0.33880117535591125,
-0.003661602735519409,
0.09023308753967285,
0.22566425800323486,
0.06747236102819443,
0.33013883233070374,
0.22485360503196716,
0.2462349236011505,
0.25057345628738403,
-0.30751410126686096,
0.30302223563194275,
0.05275782197713852,
0.26188415288... |
https://github.com/huggingface/datasets/issues/5419 | Hi! Thanks for pointing out this inconsistency. Changing the default value at this point is probably not worth it, considering we've started discussing the state of the task API internally - we will most likely deprecate the current one and replace it with a more robust solution that relies on the `train_eval_index` fi... | label_column='labels' in datasets.TextClassification and 'label' or 'label_ids' in transformers.DataColator | ### Describe the bug
When preparing a dataset for a task using `datasets.TextClassification`, the output feature is named `labels`. When preparing the trainer using the `transformers.DataCollator` the default column name is `label` if binary or `label_ids` if multi-class problem.
It is required to rename the column... | 62 | label_column='labels' in datasets.TextClassification and 'label' or 'label_ids' in transformers.DataColator
### Describe the bug
When preparing a dataset for a task using `datasets.TextClassification`, the output feature is named `labels`. When preparing the trainer using the `transformers.DataCollator` the default ... | [
-0.09878356009721756,
-0.028301045298576355,
0.08245216310024261,
0.17236338555812836,
0.5925765633583069,
0.16195091605186462,
0.8654409646987915,
0.14585193991661072,
-0.3619142770767212,
0.3564334511756897,
0.0737442672252655,
0.6325088739395142,
-0.12174072861671448,
0.0247124433517456... |
https://github.com/huggingface/datasets/issues/5419 | The task templates API has been deprecated (will be removed in version 3.0), so I'm closing this issue. | label_column='labels' in datasets.TextClassification and 'label' or 'label_ids' in transformers.DataColator | ### Describe the bug
When preparing a dataset for a task using `datasets.TextClassification`, the output feature is named `labels`. When preparing the trainer using the `transformers.DataCollator` the default column name is `label` if binary or `label_ids` if multi-class problem.
It is required to rename the column... | 18 | label_column='labels' in datasets.TextClassification and 'label' or 'label_ids' in transformers.DataColator
### Describe the bug
When preparing a dataset for a task using `datasets.TextClassification`, the output feature is named `labels`. When preparing the trainer using the `transformers.DataCollator` the default ... | [
-0.09878356009721756,
-0.028301045298576355,
0.08245216310024261,
0.17236338555812836,
0.5925765633583069,
0.16195091605186462,
0.8654409646987915,
0.14585193991661072,
-0.3619142770767212,
0.3564334511756897,
0.0737442672252655,
0.6325088739395142,
-0.12174072861671448,
0.0247124433517456... |
https://github.com/huggingface/datasets/issues/5418 | Thanks for your proposal, @zanussbaum. Yes, I agree that would definitely be a nice feature to have! | Add ProgressBar for `to_parquet` | ### Feature request
Add a progress bar for `Dataset.to_parquet`, similar to how `to_json` works.
### Motivation
It's a bit frustrating to not know how long a dataset will take to write to file and if it's stuck or not without a progress bar
### Your contribution
Sure I can help if needed | 17 | Add ProgressBar for `to_parquet`
### Feature request
Add a progress bar for `Dataset.to_parquet`, similar to how `to_json` works.
### Motivation
It's a bit frustrating to not know how long a dataset will take to write to file and if it's stuck or not without a progress bar
### Your contribution
Sure I can help i... | [
-0.23243607580661774,
0.22826933860778809,
-0.20800255239009857,
-0.17253261804580688,
0.03399203345179558,
0.06189589202404022,
0.04962766170501709,
0.3795414865016937,
-0.2564491927623749,
0.2358810007572174,
0.5789780020713806,
0.46180975437164307,
-0.047420188784599304,
0.6257507801055... |
https://github.com/huggingface/datasets/issues/5418 | That would be awesome ! You can comment `#self-assign` to assign you to this issue and open a PR :) Will be happy to review | Add ProgressBar for `to_parquet` | ### Feature request
Add a progress bar for `Dataset.to_parquet`, similar to how `to_json` works.
### Motivation
It's a bit frustrating to not know how long a dataset will take to write to file and if it's stuck or not without a progress bar
### Your contribution
Sure I can help if needed | 25 | Add ProgressBar for `to_parquet`
### Feature request
Add a progress bar for `Dataset.to_parquet`, similar to how `to_json` works.
### Motivation
It's a bit frustrating to not know how long a dataset will take to write to file and if it's stuck or not without a progress bar
### Your contribution
Sure I can help i... | [
-0.20450934767723083,
0.19203177094459534,
-0.21544021368026733,
-0.09467726945877075,
0.016251038759946823,
0.020993225276470184,
0.008307268843054771,
0.3782072365283966,
-0.21084396541118622,
0.17210456728935242,
0.520796537399292,
0.48783087730407715,
0.036368392407894135,
0.5576763749... |
https://github.com/huggingface/datasets/issues/5414 | Thanks for reporting, @Nithin-Holla.
This is a known issue for multiple datasets and we are investigating it:
- See e.g.: https://huggingface.co/datasets/ami/discussions/3 | Sharding error with Multilingual LibriSpeech | ### Describe the bug
Loading the German Multilingual LibriSpeech dataset results in a RuntimeError regarding sharding with the following stacktrace:
```
Downloading and preparing dataset multilingual_librispeech/german to /home/nithin/datadrive/cache/huggingface/datasets/facebook___multilingual_librispeech/german/... | 21 | Sharding error with Multilingual LibriSpeech
### Describe the bug
Loading the German Multilingual LibriSpeech dataset results in a RuntimeError regarding sharding with the following stacktrace:
```
Downloading and preparing dataset multilingual_librispeech/german to /home/nithin/datadrive/cache/huggingface/datas... | [
-0.35538509488105774,
-0.1440388262271881,
0.00005328282713890076,
0.5673330426216125,
0.06083418056368828,
-0.15621952712535858,
0.6092427372932434,
0.1827296018600464,
-0.1970876306295395,
0.07945073395967484,
0.14631274342536926,
-0.5302386283874512,
-0.20963874459266663,
0.201295867562... |
https://github.com/huggingface/datasets/issues/5413 | Hi ! Thanks for reporting :)
I managed to reproduce the hub using
```python
from datasets import concatenate_datasets, Dataset, load_from_disk
Dataset.from_dict({"a": range(9)}).save_to_disk("tmp/ds1")
ds1 = load_from_disk("tmp/ds1")
ds1 = concatenate_datasets([ds1, ds1])
Dataset.from_dict({"b": range(6)... | concatenate_datasets fails when two dataset with shards > 1 and unequal shard numbers | ### Describe the bug
When using `concatenate_datasets([dataset1, dataset2], axis = 1)` to concatenate two datasets with shards > 1, it fails:
```
File "/home/xzg/anaconda3/envs/tri-transfer/lib/python3.9/site-packages/datasets/combine.py", line 182, in concatenate_datasets
return _concatenate_map_style_data... | 140 | concatenate_datasets fails when two dataset with shards > 1 and unequal shard numbers
### Describe the bug
When using `concatenate_datasets([dataset1, dataset2], axis = 1)` to concatenate two datasets with shards > 1, it fails:
```
File "/home/xzg/anaconda3/envs/tri-transfer/lib/python3.9/site-packages/dataset... | [
-0.396820604801178,
0.015007436275482178,
-0.057298701256513596,
0.3943532407283783,
-0.054824382066726685,
0.02378690242767334,
0.37211182713508606,
0.38663989305496216,
-0.3439653813838959,
0.11458097398281097,
-0.028211813420057297,
0.1879984438419342,
0.10284189879894257,
0.28127148747... |
https://github.com/huggingface/datasets/issues/5412 | Hi ! It fails because the dataset is already being prepared by your first run. I'd encourage you to prepare your dataset before using it for multiple trainings.
You can also specify another cache directory by passing `cache_dir=` to `load_dataset()`. | load_dataset() cannot find dataset_info.json with multiple training runs in parallel | ### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code throws this error.
If there is a workaround to ignore the cache I think that would ... | 40 | load_dataset() cannot find dataset_info.json with multiple training runs in parallel
### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code... | [
-0.31740477681159973,
0.09060066938400269,
0.043627262115478516,
0.540564239025116,
0.07730032503604889,
0.29940834641456604,
0.48144444823265076,
0.43623432517051697,
0.18919557332992554,
-0.040755175054073334,
0.2500571608543396,
0.18446309864521027,
0.1398070901632309,
-0.10856324434280... |
https://github.com/huggingface/datasets/issues/5412 | Thank you! What do you mean by prepare it beforehand? I am unclear how to conduct dataset preparation outside of using the `load_dataset` function. | load_dataset() cannot find dataset_info.json with multiple training runs in parallel | ### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code throws this error.
If there is a workaround to ignore the cache I think that would ... | 24 | load_dataset() cannot find dataset_info.json with multiple training runs in parallel
### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code... | [
-0.31740477681159973,
0.09060066938400269,
0.043627262115478516,
0.540564239025116,
0.07730032503604889,
0.29940834641456604,
0.48144444823265076,
0.43623432517051697,
0.18919557332992554,
-0.040755175054073334,
0.2500571608543396,
0.18446309864521027,
0.1398070901632309,
-0.10856324434280... |
https://github.com/huggingface/datasets/issues/5412 | You can have a separate script that does load_dataset + map + save_to_disk to save your prepared dataset somewhere. Then in your training script you can reload the dataset with load_from_disk | load_dataset() cannot find dataset_info.json with multiple training runs in parallel | ### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code throws this error.
If there is a workaround to ignore the cache I think that would ... | 31 | load_dataset() cannot find dataset_info.json with multiple training runs in parallel
### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code... | [
-0.31740477681159973,
0.09060066938400269,
0.043627262115478516,
0.540564239025116,
0.07730032503604889,
0.29940834641456604,
0.48144444823265076,
0.43623432517051697,
0.18919557332992554,
-0.040755175054073334,
0.2500571608543396,
0.18446309864521027,
0.1398070901632309,
-0.10856324434280... |
https://github.com/huggingface/datasets/issues/5412 | Thank you! I believe I was running additional map steps after loading, resulting in the cache conflict. | load_dataset() cannot find dataset_info.json with multiple training runs in parallel | ### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code throws this error.
If there is a workaround to ignore the cache I think that would ... | 17 | load_dataset() cannot find dataset_info.json with multiple training runs in parallel
### Describe the bug
I have a custom local dataset in JSON form. I am trying to do multiple training runs in parallel. The first training run runs with no issue. However, when I start another run on another GPU, the following code... | [
-0.31740477681159973,
0.09060066938400269,
0.043627262115478516,
0.540564239025116,
0.07730032503604889,
0.29940834641456604,
0.48144444823265076,
0.43623432517051697,
0.18919557332992554,
-0.040755175054073334,
0.2500571608543396,
0.18446309864521027,
0.1398070901632309,
-0.10856324434280... |
https://github.com/huggingface/datasets/issues/5408 | Hi ! On macos I tried with
- py 3.9.11
- datasets 2.8.0
- transformers 4.25.1
- dill 0.3.4
and I was able to hash `prepare_dataset` correctly:
```python
from datasets.fingerprint import Hasher
Hasher.hash(prepare_dataset)
```
What version of transformers do you have ? Can you try to call `Hasher.hash` on ... | dataset map function could not be hash properly | ### Describe the bug
I follow the [blog post](https://huggingface.co/blog/fine-tune-whisper#building-a-demo) to finetune a Cantonese transcribe model.
When using map function to prepare dataset, following warning pop out:
`common_voice = common_voice.map(prepare_dataset,
remove_... | 64 | dataset map function could not be hash properly
### Describe the bug
I follow the [blog post](https://huggingface.co/blog/fine-tune-whisper#building-a-demo) to finetune a Cantonese transcribe model.
When using map function to prepare dataset, following warning pop out:
`common_voice = common_voice.map(prepare_... | [
-0.053248368203639984,
-0.17688876390457153,
0.10579607635736465,
0.10368239134550095,
0.37583127617836,
0.08446527272462845,
0.18014377355575562,
0.1769525557756424,
-0.1404319554567337,
0.05729890614748001,
-0.1641332507133484,
0.23005756735801697,
-0.23561489582061768,
-0.03130532428622... |
https://github.com/huggingface/datasets/issues/5408 | Thanks for your prompt reply.
I update datasets version to 2.8.0 and the warning is gong. | dataset map function could not be hash properly | ### Describe the bug
I follow the [blog post](https://huggingface.co/blog/fine-tune-whisper#building-a-demo) to finetune a Cantonese transcribe model.
When using map function to prepare dataset, following warning pop out:
`common_voice = common_voice.map(prepare_dataset,
remove_... | 16 | dataset map function could not be hash properly
### Describe the bug
I follow the [blog post](https://huggingface.co/blog/fine-tune-whisper#building-a-demo) to finetune a Cantonese transcribe model.
When using map function to prepare dataset, following warning pop out:
`common_voice = common_voice.map(prepare_... | [
-0.053248368203639984,
-0.17688876390457153,
0.10579607635736465,
0.10368239134550095,
0.37583127617836,
0.08446527272462845,
0.18014377355575562,
0.1769525557756424,
-0.1404319554567337,
0.05729890614748001,
-0.1641332507133484,
0.23005756735801697,
-0.23561489582061768,
-0.03130532428622... |
https://github.com/huggingface/datasets/issues/5406 | Hi ! I just tested locally and or colab and it works fine for 2.9 on `sst2`.
Also the code that is shown in your stack trace is not present in the 2.9 source code - so I'm wondering how you installed `datasets` that could cause this ? (you can check by searching for `[0:{label_ids[-1] + 1}]` in the [2.9 codebase](ht... | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 76 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.22732442617416382,
-0.24561378359794617,
0.04529472440481186,
0.20780959725379944,
0.199201762676239,
0.03519997000694275,
0.14738115668296814,
0.2325325608253479,
-0.0484992191195488,
0.1013566255569458,
-0.2688959240913391,
0.2893790006637573,
-0.015856094658374786,
0.4024367332458496... |
https://github.com/huggingface/datasets/issues/5406 | For what it's worth, I've also gotten this error on 2.9.0, and I've tried uninstalling an reinstalling
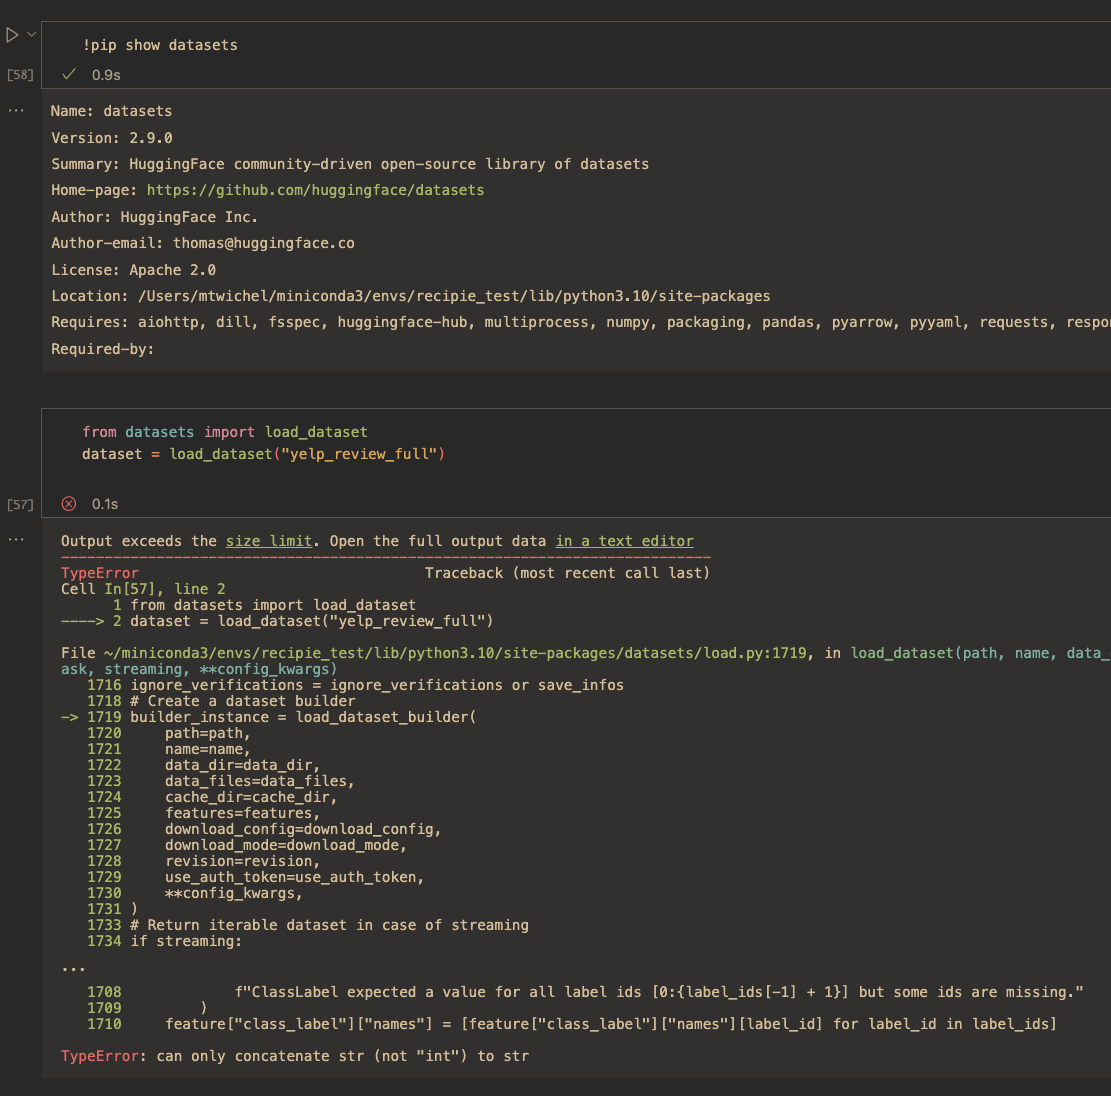
I'm very new to this package (I was following this tutorial: https://h... | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 54 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.18984419107437134,
-0.1490582972764969,
0.05108950287103653,
0.1353098452091217,
0.32842177152633667,
0.07523161172866821,
0.1657152622938156,
0.21379077434539795,
-0.18478915095329285,
0.10597953200340271,
-0.24782675504684448,
0.0915505588054657,
-0.16757458448410034,
0.28415268659591... |
https://github.com/huggingface/datasets/issues/5406 | @ntrpnr @mtwichel Did you install `datasets` with conda ?
I suspect that `datasets` 2.9 on conda still have this issue for some reason. When I install `datasets` with `pip` I don't have this error. | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 34 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.29786011576652527,
-0.10467885434627533,
-0.012508589774370193,
0.14362932741641998,
0.2556246221065521,
0.11021026968955994,
0.13265112042427063,
0.2993508577346802,
-0.15901389718055725,
0.2137516736984253,
-0.27657002210617065,
0.22942739725112915,
-0.012035636231303215,
0.2879793643... |
https://github.com/huggingface/datasets/issues/5406 | > @ntrpnr @mtwichel Did you install datasets with conda ?
I did yeah, I wonder if that's the issue | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 19 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.2563299536705017,
-0.20079030096530914,
-0.027708718553185463,
0.1521577537059784,
0.26354312896728516,
0.06652151048183441,
0.12212396413087845,
0.32635775208473206,
-0.09369569271802902,
0.1999366730451584,
-0.28735411167144775,
0.2094787359237671,
-0.020035043358802795,
0.29376557469... |
https://github.com/huggingface/datasets/issues/5406 | I just checked on conda at https://anaconda.org/HuggingFace/datasets/files
and everything looks fine, I got
```python
f"ClassLabel expected a value for all label ids [0:{int(label_ids[-1]) + 1}] but some ids are missing."
```
as expected in features.py line 1760 (notice the "int()") to not have the TypeError.
... | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 70 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.15835686028003693,
-0.05639722943305969,
-0.010462924838066101,
0.2370172142982483,
0.23716694116592407,
0.0927690863609314,
0.14984548091888428,
0.23796415328979492,
-0.10564172267913818,
0.07009131461381912,
-0.33842355012893677,
0.1702398955821991,
-0.02874184027314186,
0.34571921825... |
https://github.com/huggingface/datasets/issues/5406 | Could you also try this in your notebook ? In case your python kernel doesn't match the `pip` environment in your shell
```python
import datasets; datasets.__version__
```
and
```
!which python
```
```python
import sys; sys.executable
``` | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 37 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.3279574513435364,
-0.1958094835281372,
-0.03432757034897804,
0.1615750938653946,
0.2325248420238495,
0.09833087027072906,
0.05983089655637741,
0.29804566502571106,
-0.031901367008686066,
0.19195953011512756,
-0.2993573248386383,
0.3222474455833435,
-0.008617701008915901,
0.2766529321670... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.