
html_url stringlengths 51 51 | comments stringlengths 67 24.7k | title stringlengths 6 280 | body stringlengths 51 36.2k | comment_length int64 16 1.45k | text stringlengths 190 38.3k | embeddings list |
|---|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/5406 | Mmmm, just a potential clue:
Where are you running your Python code? Is it the Spyder IDE?
I have recently seen some users reporting conflicting Python environments while using Spyder...
Maybe related:
- #5487 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 34 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.29983484745025635,
-0.09081185609102249,
-0.04046102613210678,
0.13161787390708923,
0.2025178074836731,
-0.0062173232436180115,
0.1295606642961502,
0.28173109889030457,
0.10443808138370514,
0.15001174807548523,
-0.30522167682647705,
0.2753985524177551,
-0.0435803048312664,
0.34281623363... |
https://github.com/huggingface/datasets/issues/5406 | Other potential clue:
- Had you already imported `datasets` before pip-updating it? You should first update datasets, before importing it. Otherwise, you need to restart the kernel after updating it. | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 30 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.32500261068344116,
-0.2863328158855438,
-0.03993138670921326,
0.13353319466114044,
0.27544668316841125,
0.05622175335884094,
0.03539176285266876,
0.3018190562725067,
-0.0034165605902671814,
0.2401101440191269,
-0.22619369626045227,
0.32073768973350525,
-0.02289063297212124,
0.2280566543... |
https://github.com/huggingface/datasets/issues/5406 | I installed `datasets` with Conda using `conda install datasets` and got this issue.
Then I tried to reinstall using
`
conda install -c huggingface -c conda-forge datasets
`
The issue is now fixed. | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str` | `datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: can only concatenate str (not "int") to str
```
This is because we started to update the metadat... | 33 | [2.6.1][2.7.0] Upgrade `datasets` to fix `TypeError: can only concatenate str (not "int") to str`
`datasets` 2.6.1 and 2.7.0 started to stop supporting datasets like IMDB, ConLL or MNIST datasets.
When loading a dataset using 2.6.1 or 2.7.0, you may this error when loading certain datasets:
```python
TypeError: ... | [
-0.2678487002849579,
-0.08024764060974121,
-0.019542239606380463,
0.17858248949050903,
0.28097787499427795,
0.02839319407939911,
0.09635546803474426,
0.3116196095943451,
-0.1848117709159851,
0.14354614913463593,
-0.325702965259552,
0.1784275621175766,
-0.019120579585433006,
0.3038986325263... |
https://github.com/huggingface/datasets/issues/5405 | Hi @Breakend,
Indeed, the attribute `size_in_bytes` refers to the size of the entire dataset configuration, for all splits (size of downloaded files + Arrow files), not the specific split.
This is also the case for `download_size` (downloaded files) and `dataset_size` (Arrow files).
The size of the Arrow files f... | size_in_bytes the same for all splits | ### Describe the bug
Hi, it looks like whenever you pull a dataset and get size_in_bytes, it returns the same size for all splits (and that size is the combined size of all splits). It seems like this shouldn't be the intended behavior since it is misleading. Here's an example:
```
>>> from datasets import load_da... | 76 | size_in_bytes the same for all splits
### Describe the bug
Hi, it looks like whenever you pull a dataset and get size_in_bytes, it returns the same size for all splits (and that size is the combined size of all splits). It seems like this shouldn't be the intended behavior since it is misleading. Here's an example:
... | [
-0.09145722538232803,
-0.3927055895328522,
-0.08924195170402527,
0.4507644474506378,
0.17124557495117188,
-0.07393284142017365,
0.33963584899902344,
0.4547300338745117,
-0.0024918317794799805,
0.23375040292739868,
0.056193768978118896,
-0.0806049257516861,
0.14824604988098145,
0.1330352723... |
https://github.com/huggingface/datasets/issues/5402 | `load_from_disk` must be used on datasets saved using `save_to_disk`: they correspond to fully serialized datasets including their state.
On the other hand, `download_and_prepare` just downloads the raw data and convert them to arrow (or parquet if you want). We are working on allowing you to reload a dataset saved ... | Missing state.json when creating a cloud dataset using a dataset_builder | ### Describe the bug
Using `load_dataset_builder` to create a builder, run `download_and_prepare` do upload it to S3. However when trying to load it, there are missing `state.json` files. Complete example:
```python
from aiobotocore.session import AioSession as Session
from datasets import load_from_disk, load_da... | 66 | Missing state.json when creating a cloud dataset using a dataset_builder
### Describe the bug
Using `load_dataset_builder` to create a builder, run `download_and_prepare` do upload it to S3. However when trying to load it, there are missing `state.json` files. Complete example:
```python
from aiobotocore.session... | [
-0.2532854676246643,
0.19776982069015503,
0.008729618042707443,
0.48059043288230896,
0.13168589770793915,
0.11200158298015594,
0.4172389805316925,
0.23316407203674316,
-0.03772258013486862,
0.20437732338905334,
0.23392271995544434,
0.41359177231788635,
0.1034994125366211,
0.316145360469818... |
https://github.com/huggingface/datasets/issues/5402 | Thanks, I'll follow that issue.
I was following the [cloud storage](https://huggingface.co/docs/datasets/filesystems) docs section and perhaps I'm missing some part of the flow; start with `load_dataset_builder` + `download_and_prepare`. You say I need an explicit `save_to_disk` but what object needs to be saved? t... | Missing state.json when creating a cloud dataset using a dataset_builder | ### Describe the bug
Using `load_dataset_builder` to create a builder, run `download_and_prepare` do upload it to S3. However when trying to load it, there are missing `state.json` files. Complete example:
```python
from aiobotocore.session import AioSession as Session
from datasets import load_from_disk, load_da... | 50 | Missing state.json when creating a cloud dataset using a dataset_builder
### Describe the bug
Using `load_dataset_builder` to create a builder, run `download_and_prepare` do upload it to S3. However when trying to load it, there are missing `state.json` files. Complete example:
```python
from aiobotocore.session... | [
-0.2532854676246643,
0.19776982069015503,
0.008729618042707443,
0.48059043288230896,
0.13168589770793915,
0.11200158298015594,
0.4172389805316925,
0.23316407203674316,
-0.03772258013486862,
0.20437732338905334,
0.23392271995544434,
0.41359177231788635,
0.1034994125366211,
0.316145360469818... |
https://github.com/huggingface/datasets/issues/5402 | Right now `load_dataset_builder` + `download_and_prepare` is to be used with tools like dask or spark, but `load_dataset` will support private cloud storage soon as well so you'll be able to reload the dataset with `datasets`.
Right now the only function that can load a dataset from a cloud storage is `load_from_dis... | Missing state.json when creating a cloud dataset using a dataset_builder | ### Describe the bug
Using `load_dataset_builder` to create a builder, run `download_and_prepare` do upload it to S3. However when trying to load it, there are missing `state.json` files. Complete example:
```python
from aiobotocore.session import AioSession as Session
from datasets import load_from_disk, load_da... | 61 | Missing state.json when creating a cloud dataset using a dataset_builder
### Describe the bug
Using `load_dataset_builder` to create a builder, run `download_and_prepare` do upload it to S3. However when trying to load it, there are missing `state.json` files. Complete example:
```python
from aiobotocore.session... | [
-0.2532854676246643,
0.19776982069015503,
0.008729618042707443,
0.48059043288230896,
0.13168589770793915,
0.11200158298015594,
0.4172389805316925,
0.23316407203674316,
-0.03772258013486862,
0.20437732338905334,
0.23392271995544434,
0.41359177231788635,
0.1034994125366211,
0.316145360469818... |
https://github.com/huggingface/datasets/issues/5394 | @MFatnassi, this issue and the corresponding fix only affect our Continuous Integration testing environment.
Note that `datasets` does not depend on `spacy`. | CI error: TypeError: dataclass_transform() got an unexpected keyword argument 'field_specifiers' | ### Describe the bug
While installing the dependencies, the CI raises a TypeError:
```
Traceback (most recent call last):
File "/opt/hostedtoolcache/Python/3.7.15/x64/lib/python3.7/runpy.py", line 183, in _run_module_as_main
mod_name, mod_spec, code = _get_module_details(mod_name, _Error)
File "/opt/hoste... | 22 | CI error: TypeError: dataclass_transform() got an unexpected keyword argument 'field_specifiers'
### Describe the bug
While installing the dependencies, the CI raises a TypeError:
```
Traceback (most recent call last):
File "/opt/hostedtoolcache/Python/3.7.15/x64/lib/python3.7/runpy.py", line 183, in _run_modul... | [
-0.17934031784534454,
-0.11005879938602448,
-0.061988409608602524,
0.1401691883802414,
0.31393659114837646,
-0.07446752488613129,
0.1711944341659546,
0.44393712282180786,
-0.10442748665809631,
0.07730456441640854,
0.13754433393478394,
0.41319510340690613,
-0.1148701161146164,
0.38074618577... |
https://github.com/huggingface/datasets/issues/5391 | Hey @catswithbats! Super sorry for the late reply! This is happening because there is data with label length (504) that exceeds the model's max length (448).
There are two options here:
1. Increase the model's `max_length` parameter:
```python
model.config.max_length = 512
```
2. Filter data with labels longe... | Whisper Event - RuntimeError: The size of tensor a (504) must match the size of tensor b (448) at non-singleton dimension 1 100% 1000/1000 [2:52:21<00:00, 10.34s/it] | Done in a VM with a GPU (Ubuntu) following the [Whisper Event - PYTHON](https://github.com/huggingface/community-events/tree/main/whisper-fine-tuning-event#python-script) instructions.
Attempted using [RuntimeError: he size of tensor a (504) must match the size of tensor b (448) at non-singleton dimension 1 100% 1... | 108 | Whisper Event - RuntimeError: The size of tensor a (504) must match the size of tensor b (448) at non-singleton dimension 1 100% 1000/1000 [2:52:21<00:00, 10.34s/it]
Done in a VM with a GPU (Ubuntu) following the [Whisper Event - PYTHON](https://github.com/huggingface/community-events/tree/main/whisper-fine-tuning-ev... | [
-0.18657559156417847,
-0.3833202123641968,
-0.008251868188381195,
0.36630064249038696,
0.15976983308792114,
-0.23157891631126404,
0.25094056129455566,
0.3945721387863159,
0.002418927848339081,
0.2883608937263489,
0.1047922894358635,
-0.34932398796081543,
-0.238044872879982,
0.2994163334369... |
https://github.com/huggingface/datasets/issues/5391 | @sanchit-gandhi Thank you for all your work on this topic.
I'm finding that changing the `max_length` value does not make this error go away. | Whisper Event - RuntimeError: The size of tensor a (504) must match the size of tensor b (448) at non-singleton dimension 1 100% 1000/1000 [2:52:21<00:00, 10.34s/it] | Done in a VM with a GPU (Ubuntu) following the [Whisper Event - PYTHON](https://github.com/huggingface/community-events/tree/main/whisper-fine-tuning-event#python-script) instructions.
Attempted using [RuntimeError: he size of tensor a (504) must match the size of tensor b (448) at non-singleton dimension 1 100% 1... | 24 | Whisper Event - RuntimeError: The size of tensor a (504) must match the size of tensor b (448) at non-singleton dimension 1 100% 1000/1000 [2:52:21<00:00, 10.34s/it]
Done in a VM with a GPU (Ubuntu) following the [Whisper Event - PYTHON](https://github.com/huggingface/community-events/tree/main/whisper-fine-tuning-ev... | [
-0.18657559156417847,
-0.3833202123641968,
-0.008251868188381195,
0.36630064249038696,
0.15976983308792114,
-0.23157891631126404,
0.25094056129455566,
0.3945721387863159,
0.002418927848339081,
0.2883608937263489,
0.1047922894358635,
-0.34932398796081543,
-0.238044872879982,
0.2994163334369... |
https://github.com/huggingface/datasets/issues/5390 | Hmmm, git bisect tells me that the behavior is the same since https://github.com/huggingface/datasets/commit/67e65c90e9490810b89ee140da11fdd13c356c9c (3 Oct), i.e. https://github.com/huggingface/datasets/pull/4926 | Error when pushing to the CI hub | ### Describe the bug
Note that it's a special case where the Hub URL is "https://hub-ci.huggingface.co", which does not appear if we do the same on the Hub (https://huggingface.co).
The call to `dataset.push_to_hub(` fails:
```
Pushing dataset shards to the dataset hub: 100%|██████████████████████████████████... | 17 | Error when pushing to the CI hub
### Describe the bug
Note that it's a special case where the Hub URL is "https://hub-ci.huggingface.co", which does not appear if we do the same on the Hub (https://huggingface.co).
The call to `dataset.push_to_hub(` fails:
```
Pushing dataset shards to the dataset hub: 100%... | [
-0.2565116882324219,
-0.3929585814476013,
0.04184950515627861,
0.058050595223903656,
0.010085038840770721,
-0.0018385425209999084,
0.19325679540634155,
0.2448558211326599,
0.01012004166841507,
0.03842540085315704,
-0.10119723528623581,
0.055562958121299744,
0.09907767176628113,
0.480558276... |
https://github.com/huggingface/datasets/issues/5390 | Maybe the current version of moonlanding in Hub CI is the issue.
I relaunched tests that were working two days ago: now they are failing. https://github.com/huggingface/datasets-server/commit/746414449cae4b311733f8a76e5b3b4ca73b38a9 for example
cc @huggingface/moon-landing | Error when pushing to the CI hub | ### Describe the bug
Note that it's a special case where the Hub URL is "https://hub-ci.huggingface.co", which does not appear if we do the same on the Hub (https://huggingface.co).
The call to `dataset.push_to_hub(` fails:
```
Pushing dataset shards to the dataset hub: 100%|██████████████████████████████████... | 30 | Error when pushing to the CI hub
### Describe the bug
Note that it's a special case where the Hub URL is "https://hub-ci.huggingface.co", which does not appear if we do the same on the Hub (https://huggingface.co).
The call to `dataset.push_to_hub(` fails:
```
Pushing dataset shards to the dataset hub: 100%... | [
-0.2565116882324219,
-0.3929585814476013,
0.04184950515627861,
0.058050595223903656,
0.010085038840770721,
-0.0018385425209999084,
0.19325679540634155,
0.2448558211326599,
0.01012004166841507,
0.03842540085315704,
-0.10119723528623581,
0.055562958121299744,
0.09907767176628113,
0.480558276... |
https://github.com/huggingface/datasets/issues/5390 | Hi! I don't think this has anything to do with `datasets`. Hub CI seems to be the culprit - the identical failure can be found in [this](https://github.com/huggingface/datasets/pull/5389) PR (with unrelated changes) opened today. | Error when pushing to the CI hub | ### Describe the bug
Note that it's a special case where the Hub URL is "https://hub-ci.huggingface.co", which does not appear if we do the same on the Hub (https://huggingface.co).
The call to `dataset.push_to_hub(` fails:
```
Pushing dataset shards to the dataset hub: 100%|██████████████████████████████████... | 33 | Error when pushing to the CI hub
### Describe the bug
Note that it's a special case where the Hub URL is "https://hub-ci.huggingface.co", which does not appear if we do the same on the Hub (https://huggingface.co).
The call to `dataset.push_to_hub(` fails:
```
Pushing dataset shards to the dataset hub: 100%... | [
-0.2565116882324219,
-0.3929585814476013,
0.04184950515627861,
0.058050595223903656,
0.010085038840770721,
-0.0018385425209999084,
0.19325679540634155,
0.2448558211326599,
0.01012004166841507,
0.03842540085315704,
-0.10119723528623581,
0.055562958121299744,
0.09907767176628113,
0.480558276... |
https://github.com/huggingface/datasets/issues/5388 | Hi! I can't reproduce this error locally (Mac) or in Colab. What version of `datasets` are you using? | Getting Value Error while loading a dataset.. | ### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom data configuration default-a1d9e8eaedd958cd
---... | 18 | Getting Value Error while loading a dataset..
### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom ... | [
-0.4218231439590454,
-0.3026278614997864,
0.017313838005065918,
0.4908522665500641,
0.2631383538246155,
0.0598776713013649,
0.39645811915397644,
0.042738303542137146,
0.08469156175851822,
0.2731267809867859,
-0.1654691994190216,
0.3394649624824524,
-0.17036902904510498,
0.2885279059410095,... |
https://github.com/huggingface/datasets/issues/5388 | @valmetisrinivas you get that error because you imported `datasets` (and thus `fsspec`) before installing `zstandard`.
Please, restart your Colab runtime and execute the install commands before importing `datasets`:
```python
!pip install datasets
!pip install zstandard
from datasets import load_dataset
ds ... | Getting Value Error while loading a dataset.. | ### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom data configuration default-a1d9e8eaedd958cd
---... | 49 | Getting Value Error while loading a dataset..
### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom ... | [
-0.44791293144226074,
-0.30299991369247437,
-0.01902591437101364,
0.5297800302505493,
0.29919224977493286,
0.08056466281414032,
0.3831023573875427,
0.02812393382191658,
0.12804654240608215,
0.23822930455207825,
-0.212371826171875,
0.28098541498184204,
-0.16270293295383453,
0.29270431399345... |
https://github.com/huggingface/datasets/issues/5388 | > @valmetisrinivas you get that error because you imported `datasets` (and thus `fsspec`) before installing `zstandard`.
>
> Please, restart your Colab runtime and execute the install commands before importing `datasets`:
>
> ```python
> !pip install datasets
> !pip install zstandard
>
> from datasets import... | Getting Value Error while loading a dataset.. | ### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom data configuration default-a1d9e8eaedd958cd
---... | 85 | Getting Value Error while loading a dataset..
### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom ... | [
-0.45217639207839966,
-0.3022090792655945,
-0.018817424774169922,
0.5334213972091675,
0.2990565001964569,
0.0793333500623703,
0.3811992108821869,
0.02605316787958145,
0.12390229105949402,
0.2427421659231186,
-0.2130323350429535,
0.2835162580013275,
-0.1648656278848648,
0.29461008310317993,... |
https://github.com/huggingface/datasets/issues/5387 | Hi! Our documentation builder does not support links to sections, hence the bug. This is the link it should point to https://huggingface.co/docs/datasets/v2.8.0/en/cache#improve-performance. | Missing documentation page : improve-performance | ### Describe the bug
Trying to access https://huggingface.co/docs/datasets/v2.8.0/en/package_reference/cache#improve-performance, the page is missing.
The link is in here : https://huggingface.co/docs/datasets/v2.8.0/en/package_reference/loading_methods#datasets.load_dataset.keep_in_memory
### Steps to reproduce t... | 22 | Missing documentation page : improve-performance
### Describe the bug
Trying to access https://huggingface.co/docs/datasets/v2.8.0/en/package_reference/cache#improve-performance, the page is missing.
The link is in here : https://huggingface.co/docs/datasets/v2.8.0/en/package_reference/loading_methods#datasets.lo... | [
-0.04049602523446083,
-0.17207585275173187,
-0.0869065374135971,
0.4853464365005493,
0.10513730347156525,
0.3718991279602051,
0.021011777222156525,
0.2338186502456665,
0.04772878438234329,
0.21724502742290497,
0.008832830935716629,
0.1380600780248642,
0.04583020880818367,
-0.17870812118053... |
https://github.com/huggingface/datasets/issues/5386 | Hi!
This behavior stems from the fact that we don't always embed image bytes in the underlying arrow table, which can lead to bad size estimation (we use the first 1000 table rows to [estimate](https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/arrow_dataset.py#L4627)... | `max_shard_size` in `datasets.push_to_hub()` breaks with large files | ### Describe the bug
`max_shard_size` parameter for `datasets.push_to_hub()` works unreliably with large files, generating shard files that are way past the specified limit.
In my private dataset, which contains unprocessed images of all sizes (up to `~100MB` per file), I've encountered cases where `max_shard_siz... | 101 | `max_shard_size` in `datasets.push_to_hub()` breaks with large files
### Describe the bug
`max_shard_size` parameter for `datasets.push_to_hub()` works unreliably with large files, generating shard files that are way past the specified limit.
In my private dataset, which contains unprocessed images of all sizes... | [
-0.4325348138809204,
-0.17858892679214478,
0.032033830881118774,
0.3075536787509918,
-0.041918229311704636,
-0.23482632637023926,
0.19890141487121582,
0.446437269449234,
-0.28808414936065674,
0.18014293909072876,
0.17171964049339294,
0.05644406005740166,
-0.09488017112016678,
0.00327773392... |
https://github.com/huggingface/datasets/issues/5385 | Hi! Yes, we should deprecate the `fs` param here. Would you be interested in submitting a PR? | Is `fs=` deprecated in `load_from_disk()` as well? | ### Describe the bug
The `fs=` argument was deprecated from `Dataset.save_to_disk` and `Dataset.load_from_disk` in favor of automagically figuring it out via fsspec:
https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/arrow_dataset.py#L1339-L1340
Is there a reason the... | 17 | Is `fs=` deprecated in `load_from_disk()` as well?
### Describe the bug
The `fs=` argument was deprecated from `Dataset.save_to_disk` and `Dataset.load_from_disk` in favor of automagically figuring it out via fsspec:
https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/... | [
-0.1747792661190033,
-0.4953833222389221,
-0.04820868745446205,
0.07169874012470245,
0.39074110984802246,
-0.30995795130729675,
0.3980567753314972,
-0.04317464306950569,
0.12461647391319275,
0.07487437129020691,
-0.008422214537858963,
0.32341036200523376,
-0.04272313416004181,
0.1638460755... |
https://github.com/huggingface/datasets/issues/5385 | > Hi! Yes, we should deprecate the `fs` param here. Would you be interested in submitting a PR?
Yeah I can do that sometime next week. Should the storage_options be a new arg here? I’ll look around for anywhere else where fs is an arg. | Is `fs=` deprecated in `load_from_disk()` as well? | ### Describe the bug
The `fs=` argument was deprecated from `Dataset.save_to_disk` and `Dataset.load_from_disk` in favor of automagically figuring it out via fsspec:
https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/arrow_dataset.py#L1339-L1340
Is there a reason the... | 45 | Is `fs=` deprecated in `load_from_disk()` as well?
### Describe the bug
The `fs=` argument was deprecated from `Dataset.save_to_disk` and `Dataset.load_from_disk` in favor of automagically figuring it out via fsspec:
https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/... | [
-0.09783855080604553,
-0.4176598787307739,
-0.0714980885386467,
0.08446155488491058,
0.41768521070480347,
-0.28083980083465576,
0.37226057052612305,
-0.072311170399189,
0.08835510909557343,
0.056951794773340225,
-0.01915697194635868,
0.3035809397697449,
-0.05652916431427002,
0.141014173626... |
https://github.com/huggingface/datasets/issues/5383 | Another example is that `IterableDataset.map` does not have `fn_kwargs`, among other arguments. It makes it harder to convert code from Dataset to IterableDataset. | IterableDataset missing column_names, differs from Dataset interface | ### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remove_columns=dataset.column_names, ...)
```
will not work because `.colu... | 23 | IterableDataset missing column_names, differs from Dataset interface
### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remov... | [
-0.028434552252292633,
-0.228023961186409,
-0.02068038284778595,
0.13442884385585785,
0.2349344789981842,
0.3893425464630127,
0.4180060625076294,
0.05439247936010361,
0.08721578121185303,
0.11261973530054092,
-0.0310825202614069,
0.3224223852157593,
-0.0855318084359169,
0.21674592792987823... |
https://github.com/huggingface/datasets/issues/5383 | Hi! `fn_kwargs` was added to `IterableDataset.map` in `datasets 2.5.0`, so please update your installation (`pip install -U datasets`) to use it.
Regarding `column_names`, I agree we should add this property to `IterableDataset`. In the meantime, you can use `list(dataset.features.keys())` instead. | IterableDataset missing column_names, differs from Dataset interface | ### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remove_columns=dataset.column_names, ...)
```
will not work because `.colu... | 40 | IterableDataset missing column_names, differs from Dataset interface
### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remov... | [
-0.00946713238954544,
-0.25361567735671997,
-0.01843339204788208,
0.10106556117534637,
0.19255386292934418,
0.40677228569984436,
0.38206836581230164,
0.10267141461372375,
0.10492909699678421,
0.11749016493558884,
-0.06360050290822983,
0.4139682948589325,
-0.09718717634677887,
0.24759680032... |
https://github.com/huggingface/datasets/issues/5383 | Thanks! That's great news.
On Thu, Dec 22, 2022, 07:48 Mario Šaško ***@***.***> wrote:
> Hi! fn_kwargs was added to IterableDataset.map in datasets 2.5.0, so
> please update your installation (pip install -U datasets) to use it.
>
> Regarding column_names, I agree we should add this property to
> IterableDataset. In ... | IterableDataset missing column_names, differs from Dataset interface | ### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remove_columns=dataset.column_names, ...)
```
will not work because `.colu... | 96 | IterableDataset missing column_names, differs from Dataset interface
### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remov... | [
0.061904266476631165,
-0.22509370744228363,
-0.02193634957075119,
0.08682530373334885,
0.2368462085723877,
0.4282380938529968,
0.41321247816085815,
0.14071473479270935,
0.13083313405513763,
0.12087805569171906,
-0.1222342923283577,
0.4290885329246521,
-0.08957679569721222,
0.21413022279739... |
https://github.com/huggingface/datasets/issues/5383 | I'm marking this issue as a "good first issue", as it makes sense to have `IterableDataset.column_names` in the API. Besides the case when `features` are `None` (e.g., `features` are `None` after `map`), in which we can also return `column_names` as `None`, adding this property should be straightforward, | IterableDataset missing column_names, differs from Dataset interface | ### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remove_columns=dataset.column_names, ...)
```
will not work because `.colu... | 47 | IterableDataset missing column_names, differs from Dataset interface
### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remov... | [
0.018652133643627167,
-0.199659526348114,
-0.017534803599119186,
0.07390989363193512,
0.2616927921772003,
0.3632996380329132,
0.4099634289741516,
0.06242954730987549,
0.15399524569511414,
0.12583154439926147,
-0.0031729675829410553,
0.27897581458091736,
-0.11127883195877075,
0.255274355411... |
https://github.com/huggingface/datasets/issues/5381 | Hi! This error can happen if there is a local file/folder with the same name as the requested dataset. And to avoid it, rename the local file/folder.
Soon, it will be possible to explicitly request a Hub dataset as follows:https://github.com/huggingface/datasets/issues/5228#issuecomment-1313494020 | Wrong URL for the_pile dataset | ### Describe the bug
When trying to load `the_pile` dataset from the library, I get a `FileNotFound` error.
### Steps to reproduce the bug
Steps to reproduce:
Run:
```
from datasets import load_dataset
dataset = load_dataset("the_pile")
```
I get the output:
"name": "FileNotFoundError",
"message... | 40 | Wrong URL for the_pile dataset
### Describe the bug
When trying to load `the_pile` dataset from the library, I get a `FileNotFound` error.
### Steps to reproduce the bug
Steps to reproduce:
Run:
```
from datasets import load_dataset
dataset = load_dataset("the_pile")
```
I get the output:
"name"... | [
0.040373481810092926,
0.2507588267326355,
0.01055123656988144,
0.5873170495033264,
0.24295714497566223,
0.09090293943881989,
0.26323360204696655,
0.4568336606025696,
-0.07539647817611694,
0.07974765449762344,
-0.016380351036787033,
0.2683015763759613,
0.032047089189291,
-0.3287288546562195... |
https://github.com/huggingface/datasets/issues/5380 | Hi! I agree `skip` can be inefficient to use in the current state.
To make it fast, we could use "statistics" stored in Parquet metadata and read only the chunks needed to form a dataset.
And thanks to the "datasets-server" project, which aims to store the Parquet versions of the Hub datasets (only the smaller d... | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 75 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.5122535228729248,
-0.16699348390102386,
-0.05416800454258919,
0.04517853632569313,
0.12001363188028336,
-0.09488394856452942,
-0.16149966418743134,
0.2732490301132202,
-0.26691895723342896,
0.2095625102519989,
0.1460128128528595,
0.5617438554763794,
-0.23323029279708862,
0.3225791156291... |
https://github.com/huggingface/datasets/issues/5380 | @mariosasko do the current parquet files created by the datasets-server already have the required "statistics"? If not, please open an issue on https://github.com/huggingface/datasets-server with some details to make sure we implement it. | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 32 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.4317307472229004,
-0.1258242279291153,
-0.07828357070684433,
0.09822224825620651,
0.06865829974412918,
-0.11888324469327927,
-0.054979823529720306,
0.15876507759094238,
-0.31098756194114685,
0.18370410799980164,
0.14100345969200134,
0.43883705139160156,
-0.2011394500732422,
0.4492751061... |
https://github.com/huggingface/datasets/issues/5380 | Yes, nothing has to be changed on the datasets-server side. What I mean by "statistics" is that we can use the "row_group" metadata embedded in a Parquet file (by default) to fetch the requested rows more efficiently. | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 37 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.4025791883468628,
0.03345492482185364,
-0.09691491723060608,
0.032999977469444275,
0.042815644294023514,
-0.10361085087060928,
-0.02962455525994301,
0.18939223885536194,
-0.4228830933570862,
0.17978960275650024,
0.17203104496002197,
0.5246415138244629,
-0.17698003351688385,
0.2543614208... |
https://github.com/huggingface/datasets/issues/5380 | Glad to see the feature could be of interest.
I'm sure there are many possible ways to implement this feature. I don't know enough about the datasets-server, but I guess that it is not instantaneous, in the sense that user-owned private datasets might need hours or days until they are ported to the datasets-server ... | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 82 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.37791380286216736,
-0.022255897521972656,
-0.13407525420188904,
-0.046580344438552856,
0.015885330736637115,
-0.11308460682630539,
-0.03142976760864258,
0.3005821108818054,
-0.3274039030075073,
0.2518559694290161,
0.2755398750305176,
0.37828904390335083,
-0.2762252688407898,
0.315872430... |
https://github.com/huggingface/datasets/issues/5380 | re: statistics:
- https://arrow.apache.org/docs/python/generated/pyarrow.parquet.FileMetaData.html
- https://arrow.apache.org/docs/python/generated/pyarrow.parquet.RowGroupMetaData.html
```python
>>> import pyarrow.parquet as pq
>>> import hffs
>>> fs = hffs.HfFileSystem("glue", repo_type="dataset", revision=... | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 71 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.45332133769989014,
0.08647724986076355,
-0.035936132073402405,
0.01841694861650467,
0.054327674210071564,
-0.10548359155654907,
-0.11660346388816833,
0.20756974816322327,
-0.5190558433532715,
0.06918948888778687,
0.1935848593711853,
0.6088048219680786,
-0.08815222978591919,
0.1508657634... |
https://github.com/huggingface/datasets/issues/5380 | > user-owned private datasets might need hours or days until they are ported to the datasets-server (if at all)
private datasets are not supported yet (https://github.com/huggingface/datasets-server/issues/39) | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 26 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.3892826437950134,
-0.1068219393491745,
-0.10879744589328766,
0.07360456883907318,
0.06995075941085815,
-0.1477583348751068,
0.07614585757255554,
0.2545871138572693,
-0.2190093696117401,
0.21927008032798767,
-0.02939363569021225,
0.33386266231536865,
-0.2742607295513153,
0.39802014827728... |
https://github.com/huggingface/datasets/issues/5380 | @versae `Dataset.push_to_hub` writes shards in Parquet, so this solution would also work for such datasets (immediately after the push). | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 19 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.4675790071487427,
-0.11333101242780685,
-0.07190049439668655,
0.049206942319869995,
0.09520475566387177,
-0.12068280577659607,
-0.025064125657081604,
0.21249563992023468,
-0.47335493564605713,
0.19488883018493652,
0.1271563023328781,
0.43210509419441223,
-0.20072610676288605,
0.29336795... |
https://github.com/huggingface/datasets/issues/5380 | @mariosasko that is right. However, there are still a good amount of datasets for which the shards are created manually. In our very specific case, we create medium-sized datasets (rarely over 100-200GB) of both text and audio, we prepare the shards by hand and then upload then. It would be great to have immediate acce... | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 63 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.44005298614501953,
-0.07696439325809479,
-0.13384979963302612,
-0.009636491537094116,
0.09046344459056854,
-0.10754058510065079,
-0.06090132147073746,
0.28717026114463806,
-0.2595837116241455,
0.22155646979808807,
0.09721236675977707,
0.3636692762374878,
-0.232895165681839,
0.2673861384... |
https://github.com/huggingface/datasets/issues/5380 | From looking at Arrow's source, it seems Parquet stores metadata at the end, which means one needs to iterate over a Parquet file's data before accessing its metadata. We could mimic Dask to address this "limitation" and write metadata in a `_metadata`/`_common_metadata` file in `to_parquet`/`push_to_hub`, which we cou... | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 66 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.4156387746334076,
-0.0067312270402908325,
-0.08167849481105804,
0.04512718692421913,
0.06374429166316986,
-0.17054483294487,
-0.05687352269887924,
0.2818978428840637,
-0.3282754421234131,
0.08835427463054657,
0.13442352414131165,
0.7062167525291443,
-0.24183712899684906,
0.1778403967618... |
https://github.com/huggingface/datasets/issues/5380 | So if Parquet metadata needs to be in its own file anyway, why not implement this skipping feature by storing the example counts per shard in `dataset_infos.json`? That would allow:
- Support both private and public datasets
- Immediate access to the feature upon uploading of shards
- Use any dataset, not only those... | Improve dataset `.skip()` speed in streaming mode | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | 74 | Improve dataset `.skip()` speed in streaming mode
### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the down... | [
-0.37432199716567993,
-0.05027112364768982,
-0.04929853603243828,
0.12331388145685196,
0.013577692210674286,
-0.08900665491819382,
-0.03893787041306496,
0.19122955203056335,
-0.3204062283039093,
0.15834319591522217,
0.3072509169578552,
0.5442472696304321,
-0.2791768014431,
0.40292075276374... |
https://github.com/huggingface/datasets/issues/5378 | Thanks for reporting @shaoyuta. We are investigating it.
We are transferring the issue to "the_pile" Community tab on the Hub: https://huggingface.co/datasets/the_pile/discussions/4 | The dataset "the_pile", subset "enron_emails" , load_dataset() failure | ### Describe the bug
When run
"datasets.load_dataset("the_pile","enron_emails")" failure

### Steps to reproduce the bug
Run below code in python cli:
>>> import datasets
>>> datasets.load_dataset(... | 21 | The dataset "the_pile", subset "enron_emails" , load_dataset() failure
### Describe the bug
When run
"datasets.load_dataset("the_pile","enron_emails")" failure

### Steps to reproduce the bug
Run bel... | [
-0.13004474341869354,
0.05834980309009552,
-0.029946276918053627,
0.42603036761283875,
0.27290505170822144,
0.1832219958305359,
0.5798451900482178,
0.1603626012802124,
0.13411007821559906,
0.08196955919265747,
-0.04894725978374481,
0.31444188952445984,
-0.03582896664738655,
0.1471435129642... |
https://github.com/huggingface/datasets/issues/5374 | The data files are hosted on HF at https://huggingface.co/datasets/allenai/c4/tree/main
You have 200 runs streaming the same files in parallel. So this is probably a Hub limitation. Maybe rate limiting ? cc @julien-c
Maybe you can also try to reduce the number of HTTP requests by increasing the block size of eac... | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | 81 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec
### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
... | [
-0.551461935043335,
-0.3695976436138153,
-0.000589568167924881,
0.33152133226394653,
0.2842414975166321,
-0.13825447857379913,
0.32566046714782715,
-0.1305093765258789,
0.09035421162843704,
0.31347185373306274,
-0.12639431655406952,
0.1439398229122162,
0.11891384422779083,
0.02422623336315... |
https://github.com/huggingface/datasets/issues/5374 | you don't get an HTTP error code or something in your stack trace? Kinda hard to debug with this info | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | 20 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec
### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
... | [
-0.551461935043335,
-0.3695976436138153,
-0.000589568167924881,
0.33152133226394653,
0.2842414975166321,
-0.13825447857379913,
0.32566046714782715,
-0.1305093765258789,
0.09035421162843704,
0.31347185373306274,
-0.12639431655406952,
0.1439398229122162,
0.11891384422779083,
0.02422623336315... |
https://github.com/huggingface/datasets/issues/5374 | You could try to re-run using this `datasets` branch: [raise-err-when-disconnect](https://github.com/huggingface/datasets/compare/raise-err-when-disconnect?expand=1)
It should raise the fsspec error | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | 16 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec
### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
... | [
-0.551461935043335,
-0.3695976436138153,
-0.000589568167924881,
0.33152133226394653,
0.2842414975166321,
-0.13825447857379913,
0.32566046714782715,
-0.1305093765258789,
0.09035421162843704,
0.31347185373306274,
-0.12639431655406952,
0.1439398229122162,
0.11891384422779083,
0.02422623336315... |
https://github.com/huggingface/datasets/issues/5374 | The weird thing is that I already have it saved locally & it seems to indeed be using the cached one 🧐 ; I'm also using offline mode, so I don't think it has something to do with the Hub.
```
WARNING:datasets.load:Using the latest cached version of the module from /users/muennighoff/.cache/huggingface/modules/datase... | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | 68 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec
### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
... | [
-0.551461935043335,
-0.3695976436138153,
-0.000589568167924881,
0.33152133226394653,
0.2842414975166321,
-0.13825447857379913,
0.32566046714782715,
-0.1305093765258789,
0.09035421162843704,
0.31347185373306274,
-0.12639431655406952,
0.1439398229122162,
0.11891384422779083,
0.02422623336315... |
https://github.com/huggingface/datasets/issues/5374 | No, you passed `streaming=True` so it streams the data from the Hub.
This message just shows that you use the cached version of the `c4` **module**, aka the python script that is run to generate the examples from the raw data files.
Maybe the offline mode should also disable `fsspec`/`aiohttp` HTTP calls in `datase... | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | 60 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec
### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
... | [
-0.551461935043335,
-0.3695976436138153,
-0.000589568167924881,
0.33152133226394653,
0.2842414975166321,
-0.13825447857379913,
0.32566046714782715,
-0.1305093765258789,
0.09035421162843704,
0.31347185373306274,
-0.12639431655406952,
0.1439398229122162,
0.11891384422779083,
0.02422623336315... |
https://github.com/huggingface/datasets/issues/5374 | > This message just shows that you use the cached version of the c4 module
Ah my bad you're right about the module, but it's also using the downloaded & cached c4 dataset. There's no internet during the runs so it wouldn't work otherwise | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | 44 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec
### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
... | [
-0.551461935043335,
-0.3695976436138153,
-0.000589568167924881,
0.33152133226394653,
0.2842414975166321,
-0.13825447857379913,
0.32566046714782715,
-0.1305093765258789,
0.09035421162843704,
0.31347185373306274,
-0.12639431655406952,
0.1439398229122162,
0.11891384422779083,
0.02422623336315... |
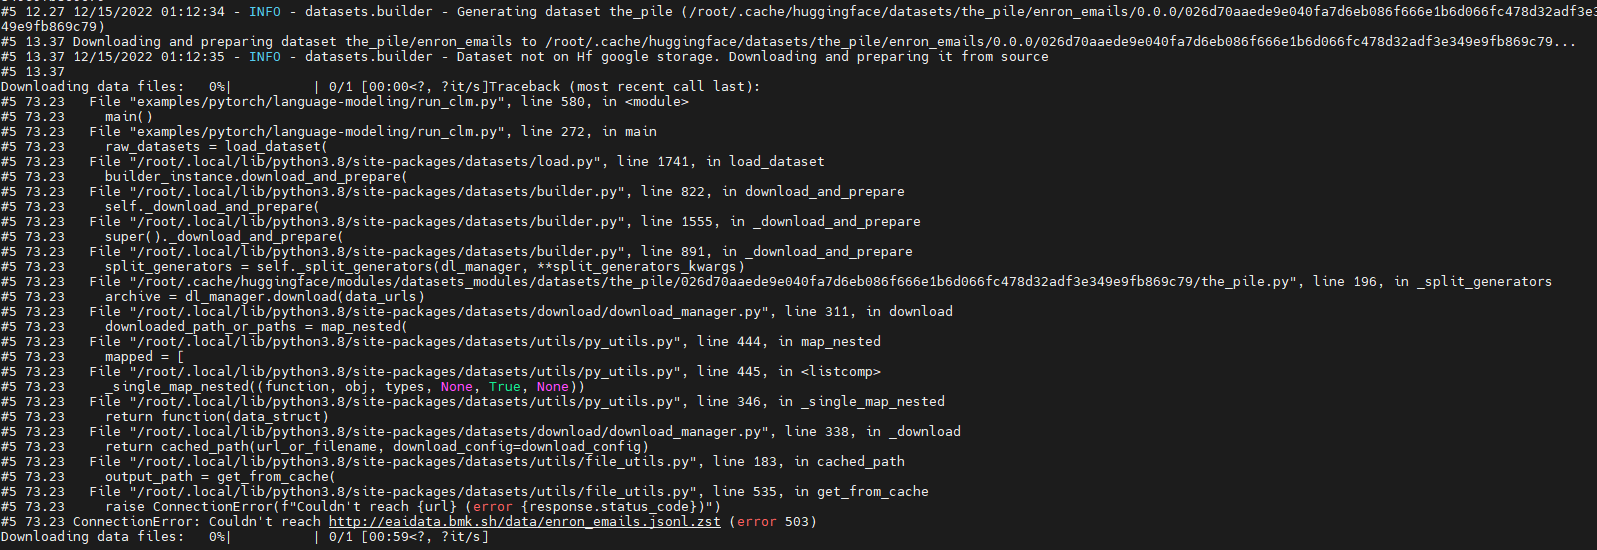
https://github.com/huggingface/datasets/issues/5362 | Thanks for reporting, @shaoyuta.
We have checked and yes, apparently there is an issue with the server hosting the data of the "enron_emails" subset of "the_pile" dataset: http://eaidata.bmk.sh/data/enron_emails.jsonl.zst
It seems to be down: The connection has timed out.
Please note that at the Hugging Face Hub... | Run 'GPT-J' failure due to download dataset fail (' ConnectionError: Couldn't reach http://eaidata.bmk.sh/data/enron_emails.jsonl.zst ' ) | ### Describe the bug
Run model "GPT-J" with dataset "the_pile" fail.
The fail out is as below:
Looks like which is due to "http://eaidata.bmk.sh/data/enron_emails.jsonl.zst" unreachable .
### Steps to ... | 103 | Run 'GPT-J' failure due to download dataset fail (' ConnectionError: Couldn't reach http://eaidata.bmk.sh/data/enron_emails.jsonl.zst ' )
### Describe the bug
Run model "GPT-J" with dataset "the_pile" fail.
The fail out is as below:
 | ### Describe the bug
Run model "GPT-J" with dataset "the_pile" fail.
The fail out is as below:

Looks like which is due to "http://eaidata.bmk.sh/data/enron_emails.jsonl.zst" unreachable .
### Steps to ... | 17 | Run 'GPT-J' failure due to download dataset fail (' ConnectionError: Couldn't reach http://eaidata.bmk.sh/data/enron_emails.jsonl.zst ' )
### Describe the bug
Run model "GPT-J" with dataset "the_pile" fail.
The fail out is as below:
:
return {"concatenated_audio": [np.concatenate([audio["array"] for audio in batch["audio"]])]}
dataset = dataset.map(
mapper_function,
batched=True,
batch_size=3,
remove_columns=list(dataset.features),
)
``` | How concatenate `Audio` elements using batch mapping | ### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# np.concatnate(audios[i: i+3]) for i in range(i, len(batc... | 26 | How concatenate `Audio` elements using batch mapping
### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# n... | [
-0.21313884854316711,
-0.16745105385780334,
-0.025562763214111328,
0.270732045173645,
-0.014795240014791489,
0.15879066288471222,
0.20670336484909058,
0.18428866565227509,
-0.2340731918811798,
0.26536625623703003,
-0.17259378731250763,
0.3468687832355499,
-0.03206638991832733,
-0.053920410... |
https://github.com/huggingface/datasets/issues/5361 | Thanks for the snippet!
One more question. I wonder why those two mappers are working so different that one taking 4 sec while other taking over 1 min :
```python
%%time
def mapper_function1(batch):
# list_audio
return {
"audio": [
{
"array": np.concatenate([audi... | How concatenate `Audio` elements using batch mapping | ### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# np.concatnate(audios[i: i+3]) for i in range(i, len(batc... | 144 | How concatenate `Audio` elements using batch mapping
### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# n... | [
-0.1701660454273224,
-0.15794961154460907,
-0.06264889240264893,
0.28099608421325684,
-0.11684790998697281,
0.038135528564453125,
0.2849518060684204,
0.12147686630487442,
-0.23791086673736572,
0.3515789210796356,
-0.20486171543598175,
0.3364012539386749,
-0.027711110189557076,
-0.165298730... |
https://github.com/huggingface/datasets/issues/5361 | In the first one you get a dataset with an Audio type, and in the second one you get a dataset with a sequence of floats type.
The Audio type encodes the data as WAV to save disk space, so it takes more time to create.
The Audio type is automatically inferred because you modify the column "audio" which was already ... | How concatenate `Audio` elements using batch mapping | ### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# np.concatnate(audios[i: i+3]) for i in range(i, len(batc... | 84 | How concatenate `Audio` elements using batch mapping
### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# n... | [
-0.28381580114364624,
-0.1815250664949417,
0.011311866343021393,
0.2613031268119812,
-0.001687716692686081,
0.1171538382768631,
0.20055517554283142,
0.2251313179731369,
-0.171248197555542,
0.31333833932876587,
-0.1593148410320282,
0.33961600065231323,
-0.015544731169939041,
-0.070890881121... |
https://github.com/huggingface/datasets/issues/5360 | If you use huggingface trainer, you will find the trainer has wrapped a `IterableDatasetShard` to avoid duplication.
See:
https://github.com/huggingface/transformers/blob/dfd818420dcbad68e05a502495cf666d338b2bfb/src/transformers/trainer.py#L835
| IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 19 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.20541121065616608,
-0.6485092043876648,
-0.03901239112019539,
0.5450435280799866,
0.1884346902370453,
-0.24366061389446259,
0.38336363434791565,
0.19024315476417542,
-0.13752207159996033,
0.3084796667098999,
-0.24906828999519348,
0.37759649753570557,
-0.07860711216926575,
0.083677046000... |
https://github.com/huggingface/datasets/issues/5360 | If you want to support it by datasets natively, maybe we also need to change the code in `transformers` ? | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 20 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.40853002667427063,
-0.4767973721027374,
-0.04256496578454971,
0.42825475335121155,
0.127531498670578,
-0.2842220664024353,
0.5116773247718811,
0.22381579875946045,
-0.15025344491004944,
0.2854844331741333,
-0.22655931115150452,
0.4095030128955841,
-0.0550556555390358,
-0.005839332938194... |
https://github.com/huggingface/datasets/issues/5360 | Maybe something like this then ?
```python
from datasets.distributed import split_dataset_by_node
ds = split_dataset_by_node(ds, rank=rank, world_size=world_size)
```
For map-style datasets the implementation is trivial (it can simply use `.shard()`).
For iterable datasets we would need to implement a new Exa... | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 66 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.42459046840667725,
-0.38009652495384216,
-0.09296968579292297,
0.35324838757514954,
-0.06343226879835129,
-0.22699537873268127,
0.4285147488117218,
0.2640458345413208,
-0.015576772391796112,
0.28691571950912476,
-0.20376041531562805,
0.537148654460907,
-0.2752929627895355,
0.10282848030... |
https://github.com/huggingface/datasets/issues/5360 | My plan is to skip examples by default to not end up with duplicates.
And if a dataset has a number of shards that is a factor of the world size, then I'd make it more optimized by distributing the shards evenly across nodes instead. | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 45 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.3472557067871094,
-0.4932485818862915,
-0.021575381979346275,
0.4353179931640625,
-0.015114927664399147,
-0.25848421454429626,
0.3807189166545868,
0.2001601904630661,
-0.12273379415273666,
0.2215447574853897,
-0.14768804609775543,
0.5018040537834167,
-0.1701529622077942,
0.0444098711013... |
https://github.com/huggingface/datasets/issues/5360 | Opened a PR here: https://github.com/huggingface/datasets/pull/5369
feel free to play with it and share your feedbacks :) | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 16 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.29532256722450256,
-0.5206151008605957,
-0.09636054188013077,
0.5269631147384644,
0.08554412424564362,
-0.24271729588508606,
0.3260630667209625,
0.22798532247543335,
-0.056025922298431396,
0.28872549533843994,
-0.23174023628234863,
0.48784685134887695,
-0.02539052441716194,
0.0267074182... |
https://github.com/huggingface/datasets/issues/5360 | @lhoestq I add shuffle after split_dataset_by_node, duplicated data still exist.
For example, we have a directory named `mock_pretraining_data`, which has three files, `part-00000`, `part-00002`,`part-00002`.
Text in `part-00000` is like this:
{"id": 0}
{"id": 1}
{"id": 2}
{"id": 3}
{"id": 4}
{"id": 5}
{"id... | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 403 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.22044341266155243,
-0.370172917842865,
0.006940584629774094,
0.5591894388198853,
-0.01064307987689972,
-0.09040850400924683,
0.3263978958129883,
0.2036275565624237,
-0.2764132618904114,
0.18778347969055176,
-0.30991262197494507,
0.6718087196350098,
-0.1850050985813141,
-0.05659192055463... |
https://github.com/huggingface/datasets/issues/5360 | Hi ! Thanks for reporting, you need to pass `seed=` to `shuffle()` or the processes won't use the same seed to shuffle the shards order before assigning each shard to a node.
The issue is that the workers are not using the same seed to shuffle the shards before splitting the shards list by node. | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 55 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.21982377767562866,
-0.5668025612831116,
-0.05250827223062515,
0.5060029625892639,
-0.01659642532467842,
-0.2757224440574646,
0.41271135210990906,
0.15478350222110748,
-0.16847580671310425,
0.3583630323410034,
-0.2531956136226654,
0.4959082007408142,
-0.06351713836193085,
-0.033704869449... |
https://github.com/huggingface/datasets/issues/5360 | I have the same issue
```
ds['train'] = load_dataset(streaming=True)
ds['train'] = split_dataset_by_node(ds['train'], rank=int(os.environ["RANK"]), world_size=int(os.environ["WORLD_SIZE"]))
vectorized_datasets = ds.map(
prepare_dataset,
remove_columns=raw_datasets_features,
).with_format("torch")
vect... | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 118 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.20593854784965515,
-0.4232087731361389,
0.02558191865682602,
0.6578266024589539,
0.1319861263036728,
-0.13606318831443787,
0.3936677873134613,
0.15741805732250214,
-0.24781741201877594,
0.1161932647228241,
-0.27916285395622253,
0.6520862579345703,
-0.05532887578010559,
0.040957599878311... |
https://github.com/huggingface/datasets/issues/5360 | There are two ways an iterable dataset can be split by node:
1. if the number of shards is a factor of number of GPUs: in that case the shards are evenly distributed per GPU
2. otherwise, each GPU iterate on the data and at the end keeps 1 sample out of n(GPUs) - skipping the others.
In case 2. it's therefore poss... | IterableDataset returns duplicated data using PyTorch DDP | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | 111 | IterableDataset returns duplicated data using PyTorch DDP
As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size... | [
-0.40176478028297424,
-0.4471839666366577,
-0.009539026767015457,
0.4609390199184418,
-0.013252207078039646,
-0.15441901981830597,
0.3621676564216614,
0.26854032278060913,
-0.14060279726982117,
0.13369499146938324,
-0.12570014595985413,
0.5460301041603088,
-0.010061917826533318,
0.09737526... |
https://github.com/huggingface/datasets/issues/5354 | Hi! Linking a comment to provide more info on the issue: https://stackoverflow.com/a/39458225. This means we should replace all (most of) the occurrences of `List` with `Sequence` in function signatures.
@tranhd95 Would you be interested in submitting a PR? | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 38 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.2320297807455063,
-0.00011309981346130371,
-0.011047016829252243,
0.12061994522809982,
0.26140034198760986,
-0.052483804523944855,
0.13928291201591492,
0.15850599110126495,
0.06648600101470947,
0.027700047940015793,
0.23363956809043884,
0.6865090727806091,
-0.2488163262605667,
0.2152842... |
https://github.com/huggingface/datasets/issues/5354 | Hi all! I tried to reproduce this issue and didn't work for me. Also in your example i noticed that the variables have different names: `list_of_filenames` and `list_of_files`, could this be related to that?
```python
#I found random data in parquet format:
!wget "https://github.com/Teradata/kylo/raw/master/samples/... | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 121 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.1178000196814537,
-0.051317840814590454,
0.010852955281734467,
0.243523970246315,
0.26680973172187805,
-0.07287730276584625,
0.05625850334763527,
0.1838153898715973,
0.016597367823123932,
0.1468179076910019,
0.25834381580352783,
0.6618994474411011,
-0.2030525952577591,
0.137481674551963... |
https://github.com/huggingface/datasets/issues/5354 | @dantema There is indeed a typo in variable names. Nevertheless, I'm sorry if I was not clear but the output is from `mypy` type checker. You can run the code snippet without issues. The problem is with the type checking. | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 40 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.1626330018043518,
-0.06226886808872223,
-0.020014267414808273,
0.20777441561222076,
0.25862550735473633,
-0.0005737841129302979,
0.12707355618476868,
0.17669031023979187,
0.006396777927875519,
0.06248645856976509,
0.2463340312242508,
0.7310905456542969,
-0.14743514358997345,
0.206906139... |
https://github.com/huggingface/datasets/issues/5354 | However, I found out that the type annotation is actually misleading. The [`from_parquet`](https://github.com/huggingface/datasets/blob/5ef1ab1cc06c2b7a574bf2df454cd9fcb071ccb2/src/datasets/arrow_dataset.py#L1039) method should also accept list of [`PathLike`](https://github.com/huggingface/datasets/blob/main/src/datas... | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 405 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.20308740437030792,
-0.1410226821899414,
0.011913619935512543,
0.17528751492500305,
0.22993989288806915,
-0.05431554466485977,
0.017583973705768585,
0.05332114174962044,
0.007895536720752716,
-0.029454275965690613,
0.18825089931488037,
0.7056475877761841,
-0.28169846534729004,
0.11585412... |
https://github.com/huggingface/datasets/issues/5354 | @avinashsai Hi, I've assigned you the issue.
@tranhd95 Yes, feel free to report this in a new issue. | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 18 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.26216453313827515,
-0.08718360215425491,
0.0008162744343280792,
0.17863903939723969,
0.30044084787368774,
-0.04939538240432739,
0.1369478702545166,
0.20783869922161102,
0.025841914117336273,
0.056282512843608856,
0.21992874145507812,
0.6769353151321411,
-0.18440720438957214,
0.193621218... |
https://github.com/huggingface/datasets/issues/5354 | @avinashsai Are you still working on this? If not I would like to give it a try. | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 17 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.2876867949962616,
-0.06751782447099686,
-0.010347865521907806,
0.1401389092206955,
0.2974570393562317,
-0.044907502830028534,
0.14442655444145203,
0.15872667729854584,
0.0058869868516922,
0.06571278721094131,
0.22005873918533325,
0.6785483956336975,
-0.20780853927135468,
0.1950530409812... |
https://github.com/huggingface/datasets/issues/5354 | Hi @tranhd95 @mariosasko ,I hope you all are doing well.
I am interested in this issue, is this still open and unresolved ?
Thanks and Regards | Consider using "Sequence" instead of "List" | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | 26 | Consider using "Sequence" instead of "List"
### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors... | [
-0.15149293839931488,
-0.15031547844409943,
0.028738878667354584,
0.2622711956501007,
0.19433021545410156,
-0.02048523724079132,
0.18442164361476898,
0.09012635797262192,
-0.011840276420116425,
-0.05534812808036804,
0.3023826479911804,
0.5749339461326599,
-0.284192830324173,
0.181688174605... |
https://github.com/huggingface/datasets/issues/5352 | Hi @J-shel, thanks for reporting.
I think the issue comes from your call to `load_dataset`. As first argument, you should pass:
- either the name of your dataset ("mrf") if this is already published on the Hub
- or the path to the loading script of your dataset ("path/to/your/local/mrf.py"). | __init__() got an unexpected keyword argument 'input_size' | ### Describe the bug
I try to define a custom configuration with a input_size attribute following the instructions by "Specifying several dataset configurations" in https://huggingface.co/docs/datasets/v1.2.1/add_dataset.html
But when I load the dataset, I got an error "__init__() got an unexpected keyword argument... | 49 | __init__() got an unexpected keyword argument 'input_size'
### Describe the bug
I try to define a custom configuration with a input_size attribute following the instructions by "Specifying several dataset configurations" in https://huggingface.co/docs/datasets/v1.2.1/add_dataset.html
But when I load the dataset, ... | [
-0.0103396475315094,
-0.6569042205810547,
0.09153121709823608,
0.46397536993026733,
0.2067398875951767,
0.08880752325057983,
0.22345000505447388,
0.004850728437304497,
-0.11013586819171906,
0.10432407259941101,
0.1245194524526596,
0.1360657513141632,
-0.14453664422035217,
0.299508512020111... |
https://github.com/huggingface/datasets/issues/5352 | Hi, following your suggestion, I changed my call to load_dataset. Below is the latest:
reader = load_dataset('data/mrf.py',"default", input_size=1024, split=split, streaming=True, keep_in_memory=None)
However, I still got the same error.
I have one question that is if I only define input_size=2048 in BUILDER_CONFIGS... | __init__() got an unexpected keyword argument 'input_size' | ### Describe the bug
I try to define a custom configuration with a input_size attribute following the instructions by "Specifying several dataset configurations" in https://huggingface.co/docs/datasets/v1.2.1/add_dataset.html
But when I load the dataset, I got an error "__init__() got an unexpected keyword argument... | 65 | __init__() got an unexpected keyword argument 'input_size'
### Describe the bug
I try to define a custom configuration with a input_size attribute following the instructions by "Specifying several dataset configurations" in https://huggingface.co/docs/datasets/v1.2.1/add_dataset.html
But when I load the dataset, ... | [
-0.0031098052859306335,
-0.6100803017616272,
0.0847414880990982,
0.4319741129875183,
0.2283126562833786,
0.08452829718589783,
0.2583859860897064,
-0.010628875344991684,
-0.14234113693237305,
0.10592222213745117,
0.11637157946825027,
0.14838987588882446,
-0.14506645500659943,
0.275924533605... |
https://github.com/huggingface/datasets/issues/5351 | Hi! `DatasetBuilder` is a parent class for concrete builders: `GeneratorBasedBuilder`, `ArrowBasedBuilder` and `BeamBasedBuilder`. When writing a builder script, these classes are the ones you should inherit from. And since all of them implement `_prepare_split`, you only have to implement the three methods mentioned a... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 44 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | Thanks so much @mariosasko for the fast response! I've been referencing [this page in the docs](https://huggingface.co/docs/datasets/v2.4.0/en/about_dataset_load) because it it pretty comprehensive in terms of what we have to do and I figured since we subclass the `BuilderConfig` the same pattern would hold, but I've a... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 63 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | cc @stevhliu who may have some ideas on how to improve this part of the docs. | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 16 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | one more question for my understanding @mariosasko. the requirement of a loading script has always seemed counterintuitive to me. if i have to provide a script with every dataset, what is the point of using `datasets` if we're doing all the work of loading it, I can just do that in my code and skip the datasets integra... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 274 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | > the requirement of a loading script has always seemed counterintuitive to me
This is a requirement only for datasets not stored in standard formats such as CSV, JSON, SQL, Parquet, ImageFolder, etc.
> if i have to provide a script with every dataset, what is the point of using datasets if we're doing all the... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 163 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | ok, that makes sense. thank you @mariosasko. I realized i'd never looked on the hub at any of the files associated with any datasets. just did that now and it appears that i'll need to have a script regardless _but_ that will just contain my custom config and builder classes, so without realizing it I was already makin... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 117 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | `download_and_prepare` downloads and prepares the arrow files. You need to call `as_dataset` on the builder to get the dataset. | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 19 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | ok, I think I was assigning the output of `builder.download_and_prepare` but it's an inplace op, so that explains the `NoneType` i was getting back. Now I'm getting:
```
ArrowInvalid Traceback (most recent call last)
<ipython-input-7-3ed50fb87c70> in <module>
----> 1 ds = dataset_buil... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 486 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | looks like my arrow files are all empty @mariosasko
i also see the `incomplete_info.lock` file a level up too. seems like the data isn't being persisted to disk when I call `download_and_prepare`. is ... | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 44 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | quick update @mariosasko. i got it working! i had to downgrade to `datasets==2.4.0`. testing other versions now and will let you know the results. | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 24 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5351 | I've tested with every version of `datasets>2.4.0` and i get the same error with all of them. | Do we need to implement `_prepare_split`? | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 17 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstr... | [
-0.39684635400772095,
0.02826392650604248,
0.03860657289624214,
0.26486557722091675,
0.1472788006067276,
0.21111729741096497,
0.5743997693061829,
0.3013264536857605,
-0.3535880446434021,
0.2715945541858673,
0.09605675935745239,
0.13665726780891418,
-0.08747732639312744,
-0.1518180668354034... |
https://github.com/huggingface/datasets/issues/5348 | note, that `datasets` already did some of that umask fixing in the past and also at the hub - the recent work on the hub about the same: https://github.com/huggingface/huggingface_hub/pull/1220
Also I noticed that each file has a .json counterpart and the latter always has the correct perms:
```
-rw------- 1 uue... | The data downloaded in the download folder of the cache does not respect `umask` | ### Describe the bug
For a project on a cluster we are several users to share the same cache for the datasets library. And we have a problem with the permissions on the data downloaded in the cache.
Indeed, it seems that the data is downloaded by giving read and write permissions only to the user launching the com... | 83 | The data downloaded in the download folder of the cache does not respect `umask`
### Describe the bug
For a project on a cluster we are several users to share the same cache for the datasets library. And we have a problem with the permissions on the data downloaded in the cache.
Indeed, it seems that the data is... | [
-0.1972026526927948,
0.027058199048042297,
-0.08662979304790497,
0.48268643021583557,
-0.04362936690449715,
0.0510198175907135,
0.13998381793498993,
-0.007853340357542038,
0.26428210735321045,
0.04169783368706703,
-0.2366980016231537,
-0.0719708800315857,
-0.10369172692298889,
-0.453565776... |
https://github.com/huggingface/datasets/issues/5345 | After some more investigation, this is due to [this line of code](https://github.com/huggingface/datasets/blob/main/src/datasets/features/audio.py#L279). The function `sf.read(file)` should be updated to `sf.read(file, dtype="float32")`
Indeed, the default value in soundfile is `float64` ([see here](https://pysoundf... | Wrong dtype for array in audio features | ### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datasets cannot be merged.
### Steps to repro... | 31 | Wrong dtype for array in audio features
### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datase... | [
-0.12291845679283142,
-0.4239886701107025,
-0.13561204075813293,
0.3905719518661499,
0.23831573128700256,
0.07607366889715195,
0.3804251551628113,
0.06847906857728958,
-0.21173880994319916,
0.051939018070697784,
-0.31208425760269165,
0.08473411947488785,
-0.04940766096115112,
0.22177012264... |
https://github.com/huggingface/datasets/issues/5345 | @qmeeus I agree, decoding of different audio formats should return the same dtypes indeed!
But note that here you are concatenating datasets with different sampling rates: 48000 for CommonVoice and 16000 for Voxpopuli. So you should cast them to the same sampling rate value before interleaving, for example:
```
cv... | Wrong dtype for array in audio features | ### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datasets cannot be merged.
### Steps to repro... | 115 | Wrong dtype for array in audio features
### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datase... | [
-0.12291845679283142,
-0.4239886701107025,
-0.13561204075813293,
0.3905719518661499,
0.23831573128700256,
0.07607366889715195,
0.3804251551628113,
0.06847906857728958,
-0.21173880994319916,
0.051939018070697784,
-0.31208425760269165,
0.08473411947488785,
-0.04940766096115112,
0.22177012264... |
https://github.com/huggingface/datasets/issues/5345 | Hi Polina,
Sorry for the late answer
It is possible that the issue was due to a bug that is now fixed. I installed an editable version of datasets from github, but I don't recall whether I had updated it at the time of the issue. My research led me to other directions so I did not follow through on the interleave dat... | Wrong dtype for array in audio features | ### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datasets cannot be merged.
### Steps to repro... | 63 | Wrong dtype for array in audio features
### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datase... | [
-0.12291845679283142,
-0.4239886701107025,
-0.13561204075813293,
0.3905719518661499,
0.23831573128700256,
0.07607366889715195,
0.3804251551628113,
0.06847906857728958,
-0.21173880994319916,
0.051939018070697784,
-0.31208425760269165,
0.08473411947488785,
-0.04940766096115112,
0.22177012264... |
https://github.com/huggingface/datasets/issues/5342 | Hi @cbarond there's already an open issue at https://github.com/dair-ai/emotion_dataset/issues/5, as the data seems to be missing now, so check that issue instead 👍🏻 | Emotion dataset cannot be downloaded | ### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 2022).
### Steps to reproduce the bug
... | 23 | Emotion dataset cannot be downloaded
### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 202... | [
-0.2650431990623474,
-0.031890541315078735,
-0.1538001447916031,
0.35737404227256775,
0.2745242714881897,
0.14052626490592957,
0.12384457141160965,
0.3136649429798126,
-0.0050668418407440186,
0.140587717294693,
-0.11704660952091217,
0.05215463414788246,
-0.1830499768257141,
-0.199113532900... |
https://github.com/huggingface/datasets/issues/5342 | Thanks @cbarond for reporting and @alvarobartt for pointing to the issue we opened in the author's repo.
Indeed, this issue was first raised in the "emotion" dataset Community tab: https://huggingface.co/datasets/emotion/discussions/3
I'm closing this issue and leave the issue above for the subsequent updates.
... | Emotion dataset cannot be downloaded | ### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 2022).
### Steps to reproduce the bug
... | 46 | Emotion dataset cannot be downloaded
### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 202... | [
-0.2444290816783905,
0.04990839958190918,
-0.15171509981155396,
0.3845749795436859,
0.31869134306907654,
0.1510685235261917,
0.09324769675731659,
0.29581594467163086,
-0.05023462325334549,
0.05524558946490288,
-0.1452038288116455,
0.07163488864898682,
-0.22129207849502563,
-0.1699876189231... |
https://github.com/huggingface/datasets/issues/5342 | > try using "SetFit/emotion" instead
I' replaced "emotion" with "SetFit/Emotion", but the code is getting stuck at
`emotions = load_dataset("SetFit/emotion")`
I pause execution using the debugger, and it takes me to filelock.py:226
`with self._thread_lock:`
Do you know a way to get past this issue? | Emotion dataset cannot be downloaded | ### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 2022).
### Steps to reproduce the bug
... | 44 | Emotion dataset cannot be downloaded
### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 202... | [
-0.2410087287425995,
0.14989586174488068,
-0.0827425941824913,
0.3248855471611023,
0.32889431715011597,
0.2756263315677643,
0.2104211151599884,
0.31520259380340576,
-0.023893088102340698,
0.04586958885192871,
0.012559004127979279,
0.15411923825740814,
-0.163013756275177,
-0.179580613970756... |
https://github.com/huggingface/datasets/issues/5338 | Hi !
> It starts using all the cores (I am not sure why because I did not pass num_proc)
The tokenizer uses Rust code that is multithreaded. And maybe the `feature_extractor` might run some things in parallel as well - but I'm not super familiar with its internals.
> then progress bar stops at every 1k steps. ... | `map()` stops every 1000 steps | ### Describe the bug
I am passing the following `prepare_dataset` function to `Dataset.map` (code is inspired from [here](https://github.com/huggingface/community-events/blob/main/whisper-fine-tuning-event/run_speech_recognition_seq2seq_streaming.py#L454))
```python3
def prepare_dataset(batch):
# load and res... | 108 | `map()` stops every 1000 steps
### Describe the bug
I am passing the following `prepare_dataset` function to `Dataset.map` (code is inspired from [here](https://github.com/huggingface/community-events/blob/main/whisper-fine-tuning-event/run_speech_recognition_seq2seq_streaming.py#L454))
```python3
def prepare_da... | [
-0.3662833869457245,
-0.08459573239088058,
-0.014782652258872986,
0.23615762591362,
0.14320316910743713,
-0.04530705511569977,
0.19075538218021393,
0.19693566858768463,
0.042741283774375916,
0.2579956352710724,
0.3843141198158264,
0.5298302173614502,
-0.015205338597297668,
0.04753725975751... |
https://github.com/huggingface/datasets/issues/5338 | Hi @lhoestq
Thanks for the explanation! it was so helpful! Let me check why `feature_extractor` is running on multiple cpus. | `map()` stops every 1000 steps | ### Describe the bug
I am passing the following `prepare_dataset` function to `Dataset.map` (code is inspired from [here](https://github.com/huggingface/community-events/blob/main/whisper-fine-tuning-event/run_speech_recognition_seq2seq_streaming.py#L454))
```python3
def prepare_dataset(batch):
# load and res... | 20 | `map()` stops every 1000 steps
### Describe the bug
I am passing the following `prepare_dataset` function to `Dataset.map` (code is inspired from [here](https://github.com/huggingface/community-events/blob/main/whisper-fine-tuning-event/run_speech_recognition_seq2seq_streaming.py#L454))
```python3
def prepare_da... | [
-0.3662833869457245,
-0.08459573239088058,
-0.014782652258872986,
0.23615762591362,
0.14320316910743713,
-0.04530705511569977,
0.19075538218021393,
0.19693566858768463,
0.042741283774375916,
0.2579956352710724,
0.3843141198158264,
0.5298302173614502,
-0.015205338597297668,
0.04753725975751... |
https://github.com/huggingface/datasets/issues/5337 | I like the idea of having `webdataset` as an optional dependency to ensure our loader generates web datasets the same way as the main project. | Support webdataset format | Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local directory, or from a dataset o... | 25 | Support webdataset format
Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local di... | [
-0.2540881633758545,
-0.2878537178039551,
-0.2043265551328659,
0.07108010351657867,
-0.13919442892074585,
0.2143101543188095,
0.15088136494159698,
0.46708646416664124,
0.4623282551765442,
-0.07798205316066742,
-0.10798372328281403,
0.05632700026035309,
-0.29503360390663147,
0.3662458062171... |
https://github.com/huggingface/datasets/issues/5337 | Webdataset is the one of the most popular dataset formats for large scale computer vision tasks. Upvote for this issue. | Support webdataset format | Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local directory, or from a dataset o... | 20 | Support webdataset format
Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local di... | [
-0.28716543316841125,
-0.3448125720024109,
-0.14642268419265747,
0.000006616115570068359,
-0.06356032192707062,
0.17611990869045258,
0.18948408961296082,
0.3859007656574249,
0.47411924600601196,
-0.062107667326927185,
-0.010728873312473297,
0.04689600691199303,
-0.24647903442382812,
0.4691... |
https://github.com/huggingface/datasets/issues/5337 | We haven't had the bandwidth to implement it so far, but if someone wants to give it a shot please don't hesitate ^^ | Support webdataset format | Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local directory, or from a dataset o... | 23 | Support webdataset format
Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local di... | [
-0.2609975039958954,
-0.3793870806694031,
-0.20094913244247437,
0.04983307421207428,
-0.0990704596042633,
0.21099914610385895,
0.11928129196166992,
0.4572092294692993,
0.4413999319076538,
-0.011851713061332703,
-0.08358485996723175,
0.038500066846609116,
-0.289950430393219,
0.4361557960510... |
https://github.com/huggingface/datasets/issues/5332 | Should `datasets` allow `ClassLabel` input parameter to be an `np.array` even though internally we need to cast it to a Python list? @lhoestq @mariosasko | Passing numpy array to ClassLabel names causes ValueError | ### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
If I define my classes as:
```
my_classes = np.array(['on... | 24 | Passing numpy array to ClassLabel names causes ValueError
### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
... | [
0.21883359551429749,
0.13178595900535583,
-0.08366695046424866,
0.4343815743923187,
0.3297925889492035,
0.023139700293540955,
0.7245234847068787,
0.2451753318309784,
0.061613693833351135,
0.22844691574573517,
-0.006206825375556946,
0.7399471402168274,
-0.19956588745117188,
-0.0428029857575... |
https://github.com/huggingface/datasets/issues/5332 | Hi! No, I don't think so. The `names` parameter is [annotated](https://github.com/huggingface/datasets/blob/582236640b9109988e5f7a16a8353696ffa09a16/src/datasets/features/features.py#L892) as `List[str]` (**NumPy arrays are not lists**), and considering that type checking is not a common practice in Python, I think we ... | Passing numpy array to ClassLabel names causes ValueError | ### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
If I define my classes as:
```
my_classes = np.array(['on... | 38 | Passing numpy array to ClassLabel names causes ValueError
### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
... | [
0.21883359551429749,
0.13178595900535583,
-0.08366695046424866,
0.4343815743923187,
0.3297925889492035,
0.023139700293540955,
0.7245234847068787,
0.2451753318309784,
0.061613693833351135,
0.22844691574573517,
-0.006206825375556946,
0.7399471402168274,
-0.19956588745117188,
-0.0428029857575... |
https://github.com/huggingface/datasets/issues/5332 | I appreciate it is the wrong type, and that type checking is not common, but I think there's a few circumstances that make it a good idea from a usability perspective.
It's quite a difficult error to debug because it comes from a utility function (so it's not immediately obvious which parameter caused it). What make... | Passing numpy array to ClassLabel names causes ValueError | ### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
If I define my classes as:
```
my_classes = np.array(['on... | 234 | Passing numpy array to ClassLabel names causes ValueError
### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
... | [
0.21883359551429749,
0.13178595900535583,
-0.08366695046424866,
0.4343815743923187,
0.3297925889492035,
0.023139700293540955,
0.7245234847068787,
0.2451753318309784,
0.061613693833351135,
0.22844691574573517,
-0.006206825375556946,
0.7399471402168274,
-0.19956588745117188,
-0.0428029857575... |
https://github.com/huggingface/datasets/issues/5332 | I agree that it's not easy to debug this issue, so perhaps we could add some basic type checking (e.g. `not isinstance(names, list)` -> error) to make debugging easier. Feel free to submit a PR.
> Additionally, passing in a set instead of the list (again, relatively easy because people may run set(classes) to genera... | Passing numpy array to ClassLabel names causes ValueError | ### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
If I define my classes as:
```
my_classes = np.array(['on... | 100 | Passing numpy array to ClassLabel names causes ValueError
### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
... | [
0.21883359551429749,
0.13178595900535583,
-0.08366695046424866,
0.4343815743923187,
0.3297925889492035,
0.023139700293540955,
0.7245234847068787,
0.2451753318309784,
0.061613693833351135,
0.22844691574573517,
-0.006206825375556946,
0.7399471402168274,
-0.19956588745117188,
-0.0428029857575... |
https://github.com/huggingface/datasets/issues/5332 | What about checking for `Sequence` instead? I think users can pass a list or a tuple as well. | Passing numpy array to ClassLabel names causes ValueError | ### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
If I define my classes as:
```
my_classes = np.array(['on... | 18 | Passing numpy array to ClassLabel names causes ValueError
### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
... | [
0.21883359551429749,
0.13178595900535583,
-0.08366695046424866,
0.4343815743923187,
0.3297925889492035,
0.023139700293540955,
0.7245234847068787,
0.2451753318309784,
0.061613693833351135,
0.22844691574573517,
-0.006206825375556946,
0.7399471402168274,
-0.19956588745117188,
-0.0428029857575... |
https://github.com/huggingface/datasets/issues/5325 | Hi! I agree it makes sense for `IterableDataset.map` to support the `batch_size=None` case. This should be super easy to fix. | map(...batch_size=None) for IterableDataset | ### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple of reasons why this might be nice.
One is th... | 20 | map(...batch_size=None) for IterableDataset
### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple o... | [
-0.472838431596756,
-0.4080769419670105,
-0.11548413336277008,
-0.02143527939915657,
-0.01474929228425026,
0.09666144847869873,
0.25117573142051697,
0.313079297542572,
0.14192207157611847,
0.20596414804458618,
0.125044047832489,
-0.0019463226199150085,
-0.46123185753822327,
-0.203920394182... |
https://github.com/huggingface/datasets/issues/5325 | @mariosasko as this is something simple maybe I can include it as part of https://github.com/huggingface/datasets/pull/5311? Let me know :+1: | map(...batch_size=None) for IterableDataset | ### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple of reasons why this might be nice.
One is th... | 19 | map(...batch_size=None) for IterableDataset
### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple o... | [
-0.5413721799850464,
-0.379557728767395,
-0.13072066009044647,
-0.02217874675989151,
0.04252048209309578,
0.1348852515220642,
0.2285553365945816,
0.3484874367713928,
0.17625409364700317,
0.207197368144989,
0.050183266401290894,
0.009742718189954758,
-0.4899643063545227,
-0.0487570948898792... |
https://github.com/huggingface/datasets/issues/5325 | Thanks again :)
> For practical usages, an alternative to this would be to convert from an iterable dataset to a map-style dataset, but it is not obvious how to do this.
This is interesting as well, if anyone wants to explore | map(...batch_size=None) for IterableDataset | ### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple of reasons why this might be nice.
One is th... | 42 | map(...batch_size=None) for IterableDataset
### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple o... | [
-0.5424900650978088,
-0.36861419677734375,
-0.1318051517009735,
-0.053702834993600845,
0.0115729421377182,
0.12986667454242706,
0.2156621813774109,
0.35392653942108154,
0.18357908725738525,
0.20941057801246643,
0.0932009220123291,
0.031993765383958817,
-0.5016154646873474,
-0.1618686616420... |
https://github.com/huggingface/datasets/issues/5324 | Ok, I believe we've cleaned up most of the old syntax we were using for the user-facing docs! There are still a couple of `:obj:`'s and `:class:` floating around in the docstrings we don't expose that I'll track down :) | Fix docstrings and types in documentation that appears on the website | While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://huggingface.co/docs/datasets/package_reference/builder_classes) of the document... | 40 | Fix docstrings and types in documentation that appears on the website
While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://hugging... | [
0.05829109251499176,
-0.10061516612768173,
-0.05663757398724556,
0.2562297284603119,
0.3562631905078888,
0.08576379716396332,
-0.06027704477310181,
0.4054103195667267,
-0.549070417881012,
-0.12703774869441986,
-0.15756094455718994,
0.10094404220581055,
-0.003952693194150925,
0.211603313684... |
https://github.com/huggingface/datasets/issues/5324 | Hi @polinaeterna @albertvillanova @stevhliu, I hope you all are doing well.
Is this issue still unresolved as I am interested in it? | Fix docstrings and types in documentation that appears on the website | While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://huggingface.co/docs/datasets/package_reference/builder_classes) of the document... | 22 | Fix docstrings and types in documentation that appears on the website
While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://hugging... | [
0.09142737835645676,
-0.21169281005859375,
-0.040311481803655624,
0.41403138637542725,
0.3623160719871521,
0.036063432693481445,
-0.1394111067056656,
0.3191322982311249,
-0.6290668249130249,
-0.12503443658351898,
-0.19987744092941284,
0.02622947469353676,
0.02427343651652336,
0.22608923912... |
https://github.com/huggingface/datasets/issues/5324 | It should be mostly fixed for the user-facing APIs, but there may be some Sphinx syntax still lurking around in the non-public APIs. Feel free to open a PR to fix those if you catch any! 🤗 | Fix docstrings and types in documentation that appears on the website | While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://huggingface.co/docs/datasets/package_reference/builder_classes) of the document... | 37 | Fix docstrings and types in documentation that appears on the website
While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://hugging... | [
0.025334879755973816,
-0.14045222103595734,
-0.05286160483956337,
0.3401479721069336,
0.3347598910331726,
0.0973585695028305,
-0.11367398500442505,
0.43796297907829285,
-0.48426204919815063,
-0.10809621214866638,
-0.17915278673171997,
0.15663759410381317,
0.1056346744298935,
0.259281218051... |
https://github.com/huggingface/datasets/issues/5324 | Thanks for your reply @stevhliu :)
Sure, I will try to find out the remaining and fix that.
| Fix docstrings and types in documentation that appears on the website | While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://huggingface.co/docs/datasets/package_reference/builder_classes) of the document... | 18 | Fix docstrings and types in documentation that appears on the website
While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://hugging... | [
0.03298291563987732,
-0.17495152354240417,
-0.06630363315343857,
0.3891785740852356,
0.37985771894454956,
0.08341337740421295,
-0.129355326294899,
0.3599199950695038,
-0.6005422472953796,
-0.08208324015140533,
-0.19791865348815918,
0.09619303047657013,
0.040438391268253326,
0.2696764469146... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.