


UltraTex: Unleashing 2K Multi-View Diffusion
for 3D Texturing


SIGGRAPH Asia 2026
Yibo Zhang1,2,
Ze Yuan3,
Nan Cao4,2,
Li Zhang5,2,
Yan-Pei Cao6,
Yuan-Chen Guo6,
Rui Ma1 †
1Jilin University
2Shanghai Innovation Institute
3The University of Hong Kong
4Tongji University
5Fudan University
6VAST
† Corresponding author
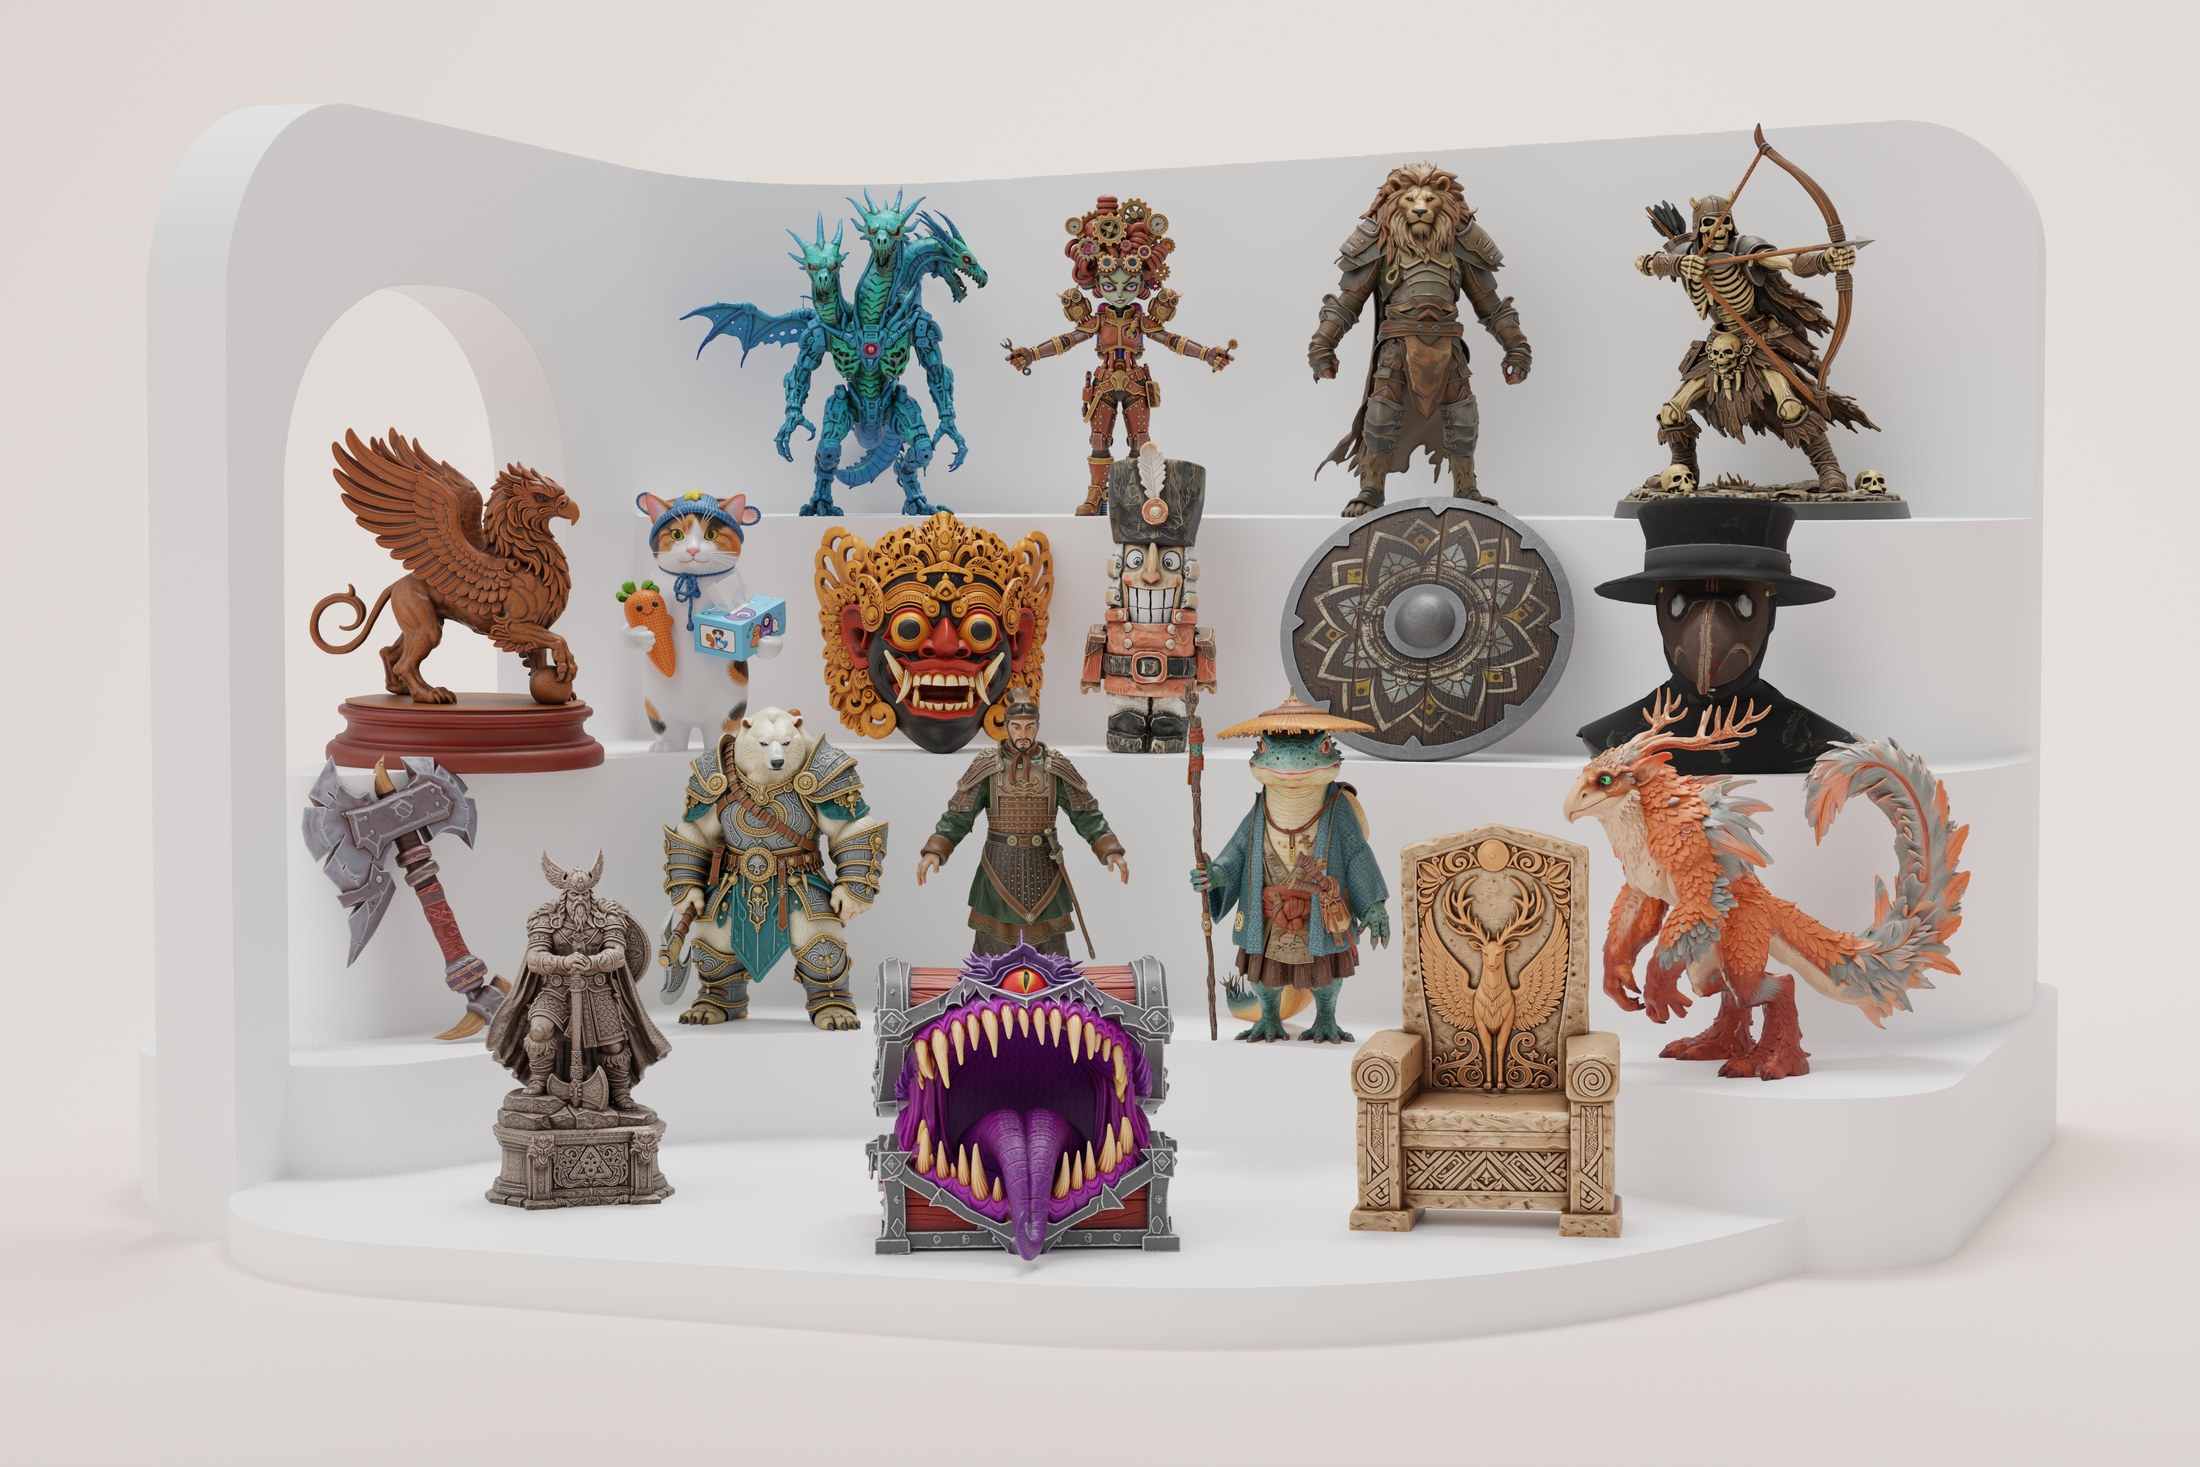
UltraTex is an efficient end-to-end framework for high-resolution multi-view diffusion-based 3D texturing at 2048×2048. Object-centric multi-view renderings contain two major sources of redundancy: background-induced sequence redundancy and sparse token interactions within the foreground. UltraTex addresses them with:
- Background Token Dropping (BTD) — discard background tokens before the DiT backbone, keeping original RoPE indices so spatial coordinates and the multi-view geometric prior survive.
- Block-Sparse Attention (BSA) — top-k sparse attention over the retained foreground sequence.
- Foreground-Aware VAE Decoding — replace the undenoised background latent with a canonical in-distribution background and lightly fine-tune the decoder so 2K reconstruction stays artifact-free.
On common samples in G-buffer TexVerse, this yields 20.6×–91.1× training speedup and 22.3×–74.6× end-to-end inference speedup over the dense baseline.
Feel free to contact me (ybzhang23@mails.jlu.edu.cn) or open an issue if you have any questions or suggestions.
News
- [2026-10-03] Training and inference code and weights released.
- [2026-09-22] Paper available on arXiv.
- [2026-09-22] Project page and G-buffer TexVerse released.
Installation
Tested with Python 3.12, CUDA 12.4 and PyTorch 2.5.1.
git clone https://github.com/yiboz2001/UltraTex.git
cd UltraTex
conda create -n ultratex python=3.12 -y
conda activate ultratex
pip install -r requirements.txt
requirements.txt pins the exact versions we tested. The sparse-attention
kernels are Triton (triton==3.1.0) and are compiled on first use.
Download the UltraTex weights into checkpoints/ (layout below):
pip install modelscope
modelscope download --model Yibo-Zhang/UltraTex --local_dir checkpoints
Repository structure
UltraTex/
├── ultratex/
│   ├── backbones/
│   │   ├── flux1/              # FLUX.1-dev backbone (BTD + BSA in math.py)
│   │   └── flux2/              # FLUX.2-Klein backbone (4B / 9B)
│   ├── sparse_attention/       # Vendored SLA, sparse branch only, Triton 3.x / H100 fixes
│   ├── data/                   # Dataset loaders
├── train_flux1.py              # Training on FLUX.1-dev
├── train_flux2.py              # Training on FLUX.2-Klein (albedo)
├── train_flux2_mr.py           # Training on FLUX.2-Klein (metallic-roughness)
├── inference_flux1.py          # Inference on FLUX.1-dev
├── inference_flux1_ai.py       # Inference on AI-generated meshes (FLUX.1)
├── inference_flux2.py          # Inference on FLUX.2-Klein
├── train_vae/                  # Foreground-Aware VAE Decoder training
│   ├── train_decoder.py        # Decoder fine-tuning, FLUX.1 AE (FG-restricted L2)
│   ├── train_decoder_flux2.py  # Decoder fine-tuning, FLUX.2 AE
│   ├── infer_decoder.py        # Decoder eval (FLUX.1)
│   └── infer_decoder_flux2.py  # Decoder eval (FLUX.2)
├── scripts/                    # Shell launch scripts
└── requirements.txt
Weights
UltraTex ships weights for two backbones. Each needs its own LoRA and its own Foreground-Aware VAE decoder — the decoders are not interchangeable, since the two backbones use different autoencoders.
Download the UltraTex weights from ModelScope and place them under checkpoints/:
checkpoints/
├── flux1/
│   ├── lora/                 # UltraTex LoRA for FLUX.1-dev
│   └── decoder.pt            # FG-aware VAE decoder for FLUX.1
├── flux2/
│   ├── lora/                 # UltraTex LoRA for FLUX.2-Klein 9B (albedo)
│   └── decoder.pt            # FG-aware VAE decoder for FLUX.2
├── flux2_mr/
│   └── lora/                 # UltraTex LoRA for FLUX.2-Klein 9B (metallic-roughness)
└── base/                     # base models, downloaded separately
    ├── FLUX.1-dev/
    │   ├── flux1-dev.safetensors
    │   └── ae.safetensors
    ├── xflux_text_encoders/  # T5 for FLUX.1 (XLabs-AI/xflux_text_encoders)
    ├── clip-vit-large-patch14/  # CLIP for FLUX.1 (openai/clip-vit-large-patch14)
    └── flux2/
        ├── flux-2-klein-base-9b.safetensors
        ├── ae.safetensors
        └── qwen3-8b/
Base models come from their original sources: FLUX.1-dev, FLUX.2, Qwen3-8B, and the XLabs T5 / CLIP encoders for FLUX.1.
A LoRA only loads into the backbone it was trained on: the 9B LoRA will not fit the 4B model (hidden size 4096 vs 3072).
Training
FLUX.1-dev backbone:
bash scripts/train_flux1_2048.sh
FLUX.2-Klein 9B backbone (albedo, or the metallic-roughness branch with TASK=mr):
bash scripts/train_flux2_9b_2048.sh
TASK=mr bash scripts/train_flux2_9b_2048.sh
Both default to the bundled demo objects (data/train_demo.json). Training
continues from the released LoRA when it is present under checkpoints/,
otherwise the LoRA is trained from scratch.
Key environment variables (all overridable, see scripts for defaults):
| Variable | Description |
|---|---|
TRAIN_JSON |
Path to training data JSON |
EVAL_JSON |
Path to evaluation data JSON |
CHECKPOINT |
UltraTex LoRA directory |
DECODER_CKPT |
Foreground-aware VAE decoder checkpoint |
LR |
Learning rate |
RESOLUTION |
Training resolution (default 2048) |
Base model locations are read from the environment so nothing is fetched from
the Hub at run time. The launch scripts set these to the checkpoints/base/
layout above; override them if your weights live elsewhere.
| Variable | Backbone | Points at |
|---|---|---|
FLUX_DEV_MODEL_PATH |
FLUX.1 | flux1-dev.safetensors |
AE_MODEL_PATH |
both | autoencoder ae.safetensors |
T5 |
FLUX.1 | XLabs T5 encoder directory |
CLIP |
FLUX.1 | CLIP encoder directory |
KLEIN_9B_BASE_MODEL_PATH |
FLUX.2 | flux-2-klein-base-9b.safetensors |
QWEN3_8B_PATH |
FLUX.2 | Qwen3-8B directory |
Inference
# FLUX.1
bash scripts/inference_flux1.sh

# FLUX.2
bash scripts/inference_flux2.sh
UltraTex predicts albedo by default. Pass --task mr to predict the
metallic-roughness map instead; that path uses train_flux2_mr.py and reads
roughness_metallic/ as the target:
bash scripts/inference_flux2.sh standard --task mr # uses checkpoints/flux2_mr/lora
The metallic-roughness branch shares the FLUX.2 VAE decoder (checkpoints/flux2/decoder.pt).
The backbone must match the checkpoint: a LoRA trained on
flux.2-klein-base-9b will not load into the 4B model (hidden size 4096 vs
3072).
Foreground-Aware VAE Decoder
Each backbone has its own decoder, trained separately so that foreground-only latents decode without background leakage. The AE encoder stays frozen and only the decoder is trained, with an L2 loss on foreground pixels.
Training (defaults to the bundled demo objects; set TRAIN_JSON / EVAL_JSON
for your own data):
bash scripts/train_vae_flux1.sh     # FLUX.1 AE -> outputs/train_vae_flux1/decoder_step*.pt
bash scripts/train_vae_flux2.sh     # FLUX.2 AE -> outputs/train_vae_flux2/decoder_step*.pt
Both read AE_MODEL_PATH (defaults to the checkpoints/base/ layout above) and
accept LR, MAX_TRAIN_STEPS, RESOLUTION, SAVE_EVERY, OUTPUT_DIR,
NUM_GPUS and MAIN_PROCESS_PORT.
Evaluation, run from the repository root:
export PYTHONPATH=$PWD
accelerate launch train_vae/infer_decoder.py --decoder_ckpt checkpoints/flux1/decoder.pt
python train_vae/infer_decoder_flux2.py --decoder_ckpt checkpoints/flux2/decoder.pt
G-buffer TexVerse
The training dataset is available at G-buffer TexVerse — 351,847 BSDF assets with multi-view G-buffer renderings at up to 4096×4096. See the dataset card for layout and download instructions.
Acknowledgements
- FLUX by Black Forest Labs
- UNO by ByteDance
- SLA (Sparse Linear Attention) by Jintao Zhang, Haoxu Wang et al. — vendored under
ultratex/sparse_attention/(Apache-2.0). We use its sparse block-attention kernels only (the linear-attention branch is removed) and patch them for Triton 3.x / H100; seeultratex/sparse_attention/PATCHES.md - Poly Haven for CC0 HDR environment maps
Citation
@inproceedings{zhang2026ultratex,
  author    = {Zhang, Yibo and Yuan, Ze and Cao, Nan and Zhang, Li and
               Cao, Yan-Pei and Guo, Yuan-Chen and Ma, Rui},
  title     = {UltraTex: Unleashing 2K Multi-View Diffusion for 3D Texturing},
  year      = {2026},
  isbn      = {9798400728426},
  publisher = {Association for Computing Machinery},
  address   = {Kuala Lumpur, Malaysia},
  url       = {https://doi.org/10.1145/3829340.3842299},
  doi       = {10.1145/3829340.3842299},
  booktitle = {Proceedings of the SIGGRAPH Asia 2026 Conference Papers},
  series    = {SA Conference Papers '26},
}
License
This code is released under the MIT License.
Krea 2 and Qwen-Image 2.1 backbones (port)
This fork adds two open-weight single-stream DiT backbones next to the FLUX
ports, selected with --backbone:
| Backbone | Weights | Latent | Tokens per 2K view | Conditioning |
|---|---|---|---|---|
krea2 |
Krea 2 Raw, 12.8B, 28 blocks, 6144 wide, GQA 48/12 | Qwen-Image / Wan 2.1 VAE, 16ch, 8x, 2x2 patch | 16,384 | Qwen3-VL-4B 12-layer tap (txtfusion), 3-axis RoPE (index, h, w), theta 1000 |
qwen21 |
Qwen-Image 2.1, 7.1B, 32 blocks, 4096 wide | Qwen-Image 2.1 RGBA VAE, 64ch, 16x, patch 1 | 16,384 | Qwen3-VL-8B last hidden state, block-causal prefix (text + references) modulated from t = 0, 3-axis RoPE (frame, h, w) |
Everything UltraTex adds (background token dropping with preserved RoPE ids,
SLA block-sparse attention, foreground-aware decoder, foreground-restricted
flow matching, UNO-style shifted timestep sampling, 2x3 TexVerse canvases,
length-aware bucketing) is shared in ultratex/mv.py and
ultratex/backbones/common.py; the backbone modules under
ultratex/backbones/{krea2,qwen21}/ load the released checkpoints with
strict=True and only change the sequence interface.
Qwen-Image 2.1 specifics: the sequence is [text, normal canvas, reference render, target canvas]; the prefix is causal and timestep-independent, so at
inference its K/V are computed once and cached across all sampling steps
(--use_prefix_cache). With --attention full it trains bidirectionally like
the FLUX ports. The RGBA VAE encodes the alpha channel directly, so the
canonical background is white + transparent and the decoder's alpha is
supervised too.
Krea 2 specifics: the sequence is [text, target canvas, normal canvas, reference render] with the references on RoPE index planes 1 and 2 (the Krea 2
edit-adapter convention); --ref_timestep_zero modulates reference tokens from
t = 0.
Setup
The scripts run inside a ComfyUI checkout that has Qwen-Image 2.1 support
(ComfyUI is imported as a library for the VAEs and text encoders; no weights
are converted). scripts/mv_env.sh holds the paths; override as needed:
export COMFY_ROOT=/path/to/ComfyUI          # with Qwen-Image 2.1 support (>= 2026-09-20)
export MV_PYTHON=$COMFY_ROOT/.venv/bin/python
export QWEN21_MODEL_PATH=.../qwen_image_2.1_bf16.safetensors
export QWEN21_VAE_PATH=.../qwen_image_2.1_vae_bf16.safetensors
export QWEN21_TEXT_ENCODER=.../qwen3vl_8b_bf16.safetensors
export KREA2_MODEL_PATH=.../krea2_raw_bf16.safetensors       # Krea 2 Raw (train on Raw)
export KREA2_VAE_PATH=.../qwen_image_vae.safetensors         # 16-channel Qwen-Image / Wan 2.1 VAE
export KREA2_TEXT_ENCODER=.../qwen3vl_4b_bf16.safetensors
Prompts are the empty string for image-guided texturing, so the text conditioning is encoded once and cached (no text encoder at train time):
BACKBONE=qwen21 bash scripts/precompute_text_mv.sh     # -> checkpoints/qwen21/text_cond.safetensors
BACKBONE=krea2  bash scripts/precompute_text_mv.sh     # -> checkpoints/krea2/text_cond.safetensors
Data
# G-buffer TexVerse is gated: request access on Hugging Face first.
hf download YiboZhang2001/G-buffer-TexVerse canonical/bsdf/00.zip --repo-type dataset --local-dir /data/texverse/zips
python tools/prepare_texverse.py --zips /data/texverse/zips/canonical/bsdf --out /data/texverse/assets \
    --train-json data/texverse_train.json --eval-json data/texverse_eval.json --eval-count 32
Train / infer
BACKBONE=qwen21 bash scripts/train_vae_mv.sh                                   # foreground-aware RGBA decoder
BACKBONE=qwen21 RESOLUTION=1024 TRAIN_JSON=data/texverse_train.json \
    EVAL_JSON=data/texverse_eval.json BUCKET_METADATA_JSON=/data/texverse/assets/foreground_ratios.json \
    DECODER_CKPT=outputs/train_vae_qwen21/decoder_step3000.safetensors bash scripts/train_mv.sh
BACKBONE=qwen21 LORA=outputs/train_qwen21_albedo_res=1024_lr=5e-5/checkpoint-20000 \
    DECODER_CKPT=outputs/train_vae_qwen21/decoder_step3000.safetensors bash scripts/inference_mv.sh
BACKBONE=krea2 selects Krea 2 everywhere. Unit tests for the sequence
layout, block-causal attention and prefix caching: python -m pytest tests/.
On the Atlas fleet, scripts/mv_leased_run.sh runs a command on a workboard
lease as a detached systemd user unit with heartbeats.