
sha256 stringlengths 64 64 | language stringclasses 28
values | size int32 1 491k | lines int32 1 23.2k | content stringlengths 1 200k |
|---|---|---|---|---|
a45d4c914db09267345cb9813aa9ade6901213b17107fb35b943424e44f6ba1d | Jupyter | 5,029 | 127 | # %% [markdown]
# In this tutorial we use a [catboost](https://tech.yandex.ru/catboost/), one of the best library for a gradient boosting on trees.
#
# You can install catboost with pip:
#
# pip install catboost
#
#
# or with conda:
#
# conda install -c conda-forge catboost
# %%
import catboost
from catboost impo... |
812f86c922b40219302bafbb3784d296b3e52c5f928d6541e7a85d4cd65a42bc | Jupyter | 5,048 | 160 | # %% [markdown]
# # Running CEBRA on the two-layer one-modality RNN trials
#
# Step 2 of the visualization pipeline:
#
# 1. **`generate_trials.m`** — simulate the chosen RNN under the desired lesion and write the synaptic-current trials to `<model_dir>/trials/*.mat`.
# 2. **This notebook** — read those tr... |
7bd6722daa78638e2bb7140701724f890feba38bb10cdbd7144961a044bf830e | Jupyter | 5,055 | 137 | # %% [markdown]
# ## Validating PRL task logs
#
# This script validates raw task logs organized acording to BIDS scheme. Script features:
# - checks proper folders and logs naming
# - looks for missing and extra files
# - looks for missing data within logs and removes duplicates
#
# ---
# **Last update**: 07.01.2020... |
fa9f48066b5984dd9940336e5fe69324305734499a9736c3f69f7cf2d0d5a7e3 | Jupyter | 5,100 | 123 | # %% [markdown]
# # Parameter Learning in Discrete Bayesian Networks
# %% [markdown]
# In this notebook, we demonstrate examples of learning the parameters (CPDs) of a Discrete Bayesian Network given the data and the model structure. pgmpy has three main algorithms for learning model parameters:
#
# 1. **Maximum Like... |
3e6f49ff208a99547f5b74cc521f0d3344c1300b34779a702fc5aa147eaf6f32 | Jupyter | 5,160 | 147 | # %%
import statsmodels.api as sm
import matplotlib.pyplot as plt
import matplotlib as mpl
import seaborn as sns
import pandas as pd
import numpy as np
import sys
import os
from pathlib import Path
from scipy.io import savemat
from scipy.stats import ttest_rel, ttest_1samp, pearsonr, f_oneway, zscore
from statsmodels.... |
aa66430e6bacdc7886307de59b089b3f17c0759b45d4eaf6d251ebfb3adbbd80 | Jupyter | 5,163 | 130 | # %% [markdown]
# # Graph measures
#
# This script is used to calculate relevant graph metrics on full connectivity matrices.
#
# ### Graph metrics
#
# Graph measures related to modularity are calculated. First, community structure is discovered using `community_louvain` algorithm for undirected, weighted networks w... |
a8d6923134fb46f33deebdb8fa25f7cafdeda8371b882e527204f42a256f0148 | Jupyter | 5,167 | 170 | # %% [markdown]
# ## Installation and Imports
# %%
import numpy as np
import matplotlib.pyplot as plt
from flax import nnx
import matplotlib.pyplot as plt
from mpl_toolkits.axes_grid1 import make_axes_locatable
# %% [markdown]
# ---
# # A. Pre-Trained Model
# %%
from nucleotide_transformer_v3.pretrained import get_... |
8d7c9afe558c3b09c787278afb6d3f20c0c2fa72565a6bed366847b0f4a1b489 | Jupyter | 5,219 | 107 | # %% [markdown]
# ### **Code to calculate and plot ant and larva positions for each assay chamber in the experiment.**
#
# ##### This script expects a directory containing the timedata_C*.csv files resulting from running 'Code_1_ETL_data_from_antrax.ipynb'.
# ##### Running this script will result in saved files 'Posit... |
d5e7dff53cc86382b92e1b899a41d81690f4d2ec60e6f0c9c64c0dc5888d01b4 | Jupyter | 5,220 | 157 | # %%
import json
import os
import sys
from dataclasses import dataclass
from datetime import datetime
import cairosvg
#import dataframe_image as dfi
import numpy as np
import pandas as pd
import skunk
from scipy.stats import spearmanr
sys.path.insert(1,'../../')
from dglgcn import compute_threshold_from_split
sys.pa... |
f28e8bff58486592a14c6ef7bbe8500f0a4a6323bcedb8a2b9eab2724bc68e2b | Jupyter | 5,231 | 100 | # %% [markdown]
# # 【使い方】
#
# ランタイム>すべてのセルを実行(**Ctrl+F9**)によりすべてのセルを実行し、セル[2]の最後に生成された**URL(Running on public URL)をクリック**して開いてください。(GUIが新しいタブで開かれる)
#
# ※このcolabの画面(タブ)は閉じないでください。
#
#
#
#
# # [How to use]
#
# Run all cells by selecting Runtime > Run all cells (**Ctrl+F9**), and **click the URL generated at the en... |
9662fc9a6521a48282b0cf9669650f278149ce23e451f306dc0a1a1606d0f11b | Jupyter | 5,233 | 158 | # %% [markdown]
# # Building a cortical surface mesh from a GM segmentation volume
#
# Produces `corticalSurface{age}mo.mat` (read by every mesh-visualisation notebook in this project) via marching cubes + Laplacian smoothing on a grey-matter segmentation volume, plus left/right hemisphere-split versions for NeuroDOT/... |
3c6ef3d1af46a93f363dfb2497d8d5e7ab046a3c6413c0eea066d14afca7062a | Jupyter | 5,243 | 143 | # %%
from tasks.scfoundation import load
import scipy.sparse as sp
import anndata as ad
import hdf5plugin
import pandas as pd
import numpy as np
import scanpy as sc
from scipy.spatial.distance import cdist
import matplotlib.pyplot as plt
# %%
def prepare_data(adata, need_normalization=True):
gene_list_df = pd.read... |
fbc4bbeb99c49066553a92e50ea0da50f92de6c99b76c96dfc9f03379f1a5a71 | Jupyter | 5,278 | 168 | # %% [markdown]
# # GPN-Star demo
#
# Use the published vertebrate GPN-Star checkpoint to inspect alignment-aware
# nucleotide probabilities, raw log-likelihood ratios, and the existing mutation-rate
# calibration example. This notebook uses only the tiny checked-in 128 bp alignment
# fixture; it never downloads a who... |
8edab1807fc56bc093aa7bd0453b92cf7a83eb23aece61ceaaf22c47c3d586ca | Jupyter | 5,285 | 126 | # %% [markdown]
# # Load packages
# %%
# Import packages
from neuromaps import transforms, nulls, datasets, plotting, images, resampling, stats, parcellate; # import neuromaps and its submodules
from neuromaps.datasets import fetch_fsaverage, fetch_fslr;
from surfplot import Plot; # this package will be used to plot t... |
295e7dc99ca30ce1dffca7e81888a46bee266c0ca1afba0ae2d3efc99a439df8 | Jupyter | 5,317 | 134 | # %%
import matplotlib.pyplot as plt
%pylab inline
import pandas as pd
from scipy.stats import pearsonr
import seaborn as sns
def pretty_ax(ax):
ax.spines['right'].set_visible(False)
ax.spines['top'].set_visible(False)
ax.tick_params(
axis='both',
which='both',
bottom=True, ... |
f46401d7ba68130d20b9ea4e2c548b3ea2fb82fdb99e5d407c97e3040479e18e | Jupyter | 5,318 | 167 | # %% [markdown]
# # Import modules
# %%
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
from figure_functions import plot_trajectory
from utils import wrapToPi
# %% [markdown]
# # Load trajectory dataset and PFN prediction dataset
# %%
stimuli = pd.read_csv('real-wvg-like... |
6d636f80d26e3200b643078ab4d391b48c97a1c72a17d52be403111f620906ea | Jupyter | 5,344 | 108 | # %%
import os
import numpy as np
dir_name = 'utility_landscape_with_noise_input_output_more_noise_levels_higher_val'
MI_arr = np.load(os.path.join(dir_name, 'MI_arr.npy'))
average_response_arr = np.load(os.path.join(dir_name, 'average_response_arr.npy'))
# noise_levels = np.load(os.path.join(dir_name, 'noise_levels.n... |
3d7a07d8ace3f38679fefad66917f67dac611cab438425165def5ac1073bf7ff | Jupyter | 5,384 | 167 | # %% [markdown]
# #### Visual stimuli
# %%
import tkinter as tk
from threading import Thread
import time
class RectangleApp:
def __init__(self, root):
self.root = root
self.root.title("Rectangle Toggle App")
# Canvas for drawing the rectangle
self.canvas = tk.Canvas(root, bg="blac... |
76df3d13e08f47becdb4552beb8695144b4772b8547a7b00d3459a6c02ad334e | Jupyter | 5,396 | 168 | # %% [markdown]
# # Import modules
# %%
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
from figure_functions import plot_trajectory
from utils import wrapToPi
# %% [markdown]
# # Load trajectory dataset and PFN prediction dataset
# %%
stimuli = pd.read_csv('C:/Users/mayc... |
55e8946e7eddc0ca8b71548e2dbf56de5e6f3e6ac9a2ce72e8b5084ccbbfb98b | Jupyter | 5,401 | 173 | # %%
%load_ext blackcellmagic
%load_ext autoreload
%autoreload 2
# %% [markdown]
# #### Imports and setup
# %%
import numpy as np
import pandas as pd
import h5py
import nibabel.freesurfer.mghformat as mgh
# %%
from spacestream.core.constants import SUBJECTS, CORE_ROI_NAMES
from spacestream.core.paths import DATA_PAT... |
43d01e5a4f728428b5804bfdf89239ecff0b74bcea1f2998447bbcaef845a8ac | Jupyter | 5,406 | 135 | # %% [markdown]
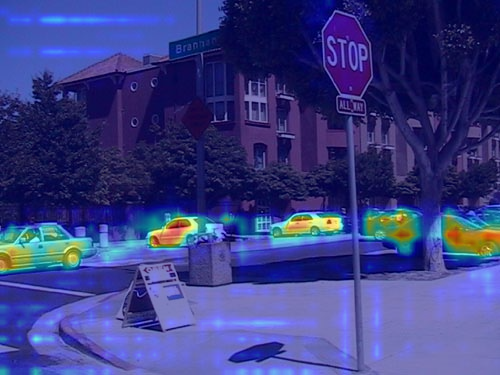
# # Tutorial: Class Activation Maps for Semantic Segmentation
# 
#
# In this tutorial we're going to see how to apply Class Activation Maps for semantic segmentaiton, using deeplabv3_resnet50 ... |
aeb7f9d5b17df940fb62e13092b7879f5f67bd4ac672000b74a17b6b07878dd1 | Jupyter | 5,414 | 158 | # %%
import json
import os
import re
import sys
from dataclasses import dataclass
from datetime import datetime
import cairosvg
#import dataframe_image as dfi
import numpy as np
import pandas as pd
import skunk
from scipy.stats import spearmanr
sys.path.insert(1, '/path/to/application/app/folder')
today_date = dateti... |
04c7f6b68154bf666b75d74119f82e2c7956804d242b3c3da1b337c55f8e0025 | Jupyter | 5,421 | 194 | # %%
%load_ext blackcellmagic
# %% [markdown]
# #### Imports and setup
# %%
import deepdish as dd
import pandas as pd
import numpy as np
from scipy.stats import ttest_1samp
# %%
from spacestream.core.constants import SUBJECTS, CORE_ROI_NAMES
from spacestream.core.paths import RESULTS_PATH
# %%
seeds = [0,1,2,3,4]
... |
3b7dd3998163d3afe3d9a84cca3671a5d09b42a61edef6b5f9dd5e5de0e550ba | Jupyter | 5,440 | 202 | # %% [markdown]
# # Spatial tissue niche discovery
# %% [markdown]
# Here we will use slideseqv2_mouse_hippocampus datasets as an example to illustrate how Garfield performs spatial tissue niche discovery for multiple batches. Data access: https://singlecell.broadinstitute.org/single_cell/study/SCP815/highly-sensitive... |
15feffa7e56ff1459eb48d05b8da7ed175ef5fcbc34a391ace8f89b0f3e3aa2c | Jupyter | 5,464 | 199 | # %%
%pylab inline
import scanpy as sc
import pandas as pd
# %% [markdown]
# ## simulated pbmc
# %%
scf_adata = sc.read_h5ad('./data/cell_type_effector_memory_CD8_positive_alpha_beta_T_cell_id10_1038_s41591_021_01329_2_seed2022/scFoundation_bbknn_design.h5ad', backed=True)
# %%
scf_adata.obs['OOR_state_str']='out of... |
ee3e2da855a683bfeef450caa9dd084c155113333224183884af08bb488fde00 | Jupyter | 5,479 | 208 | # %%
# Import modules
%matplotlib notebook
from tensorflow import keras
from tensorflow.keras.optimizers import Adam
from tensorflow.keras.utils import plot_model
from graph_model import CallBacks, DataGenerator, GraphNet
import numpy as np
import matplotlib.pyplot as plt
import pandas as pd
import os
import pickle
... |
bded41f5a4e721fb638788a087b6af8ba7299e0b3dc0bf79deff292ed6a3aec7 | Jupyter | 5,494 | 254 | # %% [markdown]
# # Plots for figure 2 in the script
# - Produces the spike timing difference distributions
# %%
from typing import Union, Optional, Callable, Iterator, List, Tuple
from pathlib import Path
import numpy as np
import matplotlib as mpl
import matplotlib.pyplot as plt
from stddc import STDDMaker, rect_P... |
51d22139e5912d15e2aec1973cdc0e6624d06540310a9770403742cc82780d57 | Jupyter | 5,500 | 124 | # %% [markdown]
# # How to define TabularCPD and LinearGaussianCPD
#
# One can implement `TabularCPD` for discrete variables inside `DiscreteBayesianNetwork`.
# and `LinearGaussianCPD` for continuous variables inside `LinearGaussianBayesianNetwork`.
#
# In this tutorial, we will demonstrate how to define each CPD.
#... |
22fd3f4014f6c00f40234755414c5d524216ae4b73c87f95d5553700dcddb9f3 | Jupyter | 5,505 | 182 | # %%
import pickle
import matplotlib.pyplot as plt
from sklearn.metrics import confusion_matrix
import seaborn as sns
import numpy as np
import scanpy as sc
# %% [markdown]
# # Plot confusion matrix
# %%
def plot_cm(cm, celltype_labels, output=None):
annot_matrix = np.where(
cm > 0.5,
np.char.add(... |
8054d0b16c89381d52081e64315074627aeffbf1e31174f8e5b70e11403c8967 | Jupyter | 5,509 | 79 | # %% [markdown]
# # Scatter Density vs. Violin Plot
#
# This gives several examples to compare the dot density vs. violin plot options for summary_plot.
# %%
import xgboost
import shap
# train xgboost model on diabetes data:
X, y = shap.datasets.diabetes()
bst = xgboost.train({"learning_rate": 0.01}, xgboost.DMatrix... |
a36e057404699c747ed09c9310b386b3669693f0ab84a39702ab51b1cc730116 | Jupyter | 5,533 | 128 | # %% [markdown]
# # 【使い方】
#
# ランタイム>すべてのセルを実行(**Ctrl+F9**)によりすべてのセルを実行し、セル[2]の最後に生成された**「ファイルを選択」ボタン**から、マスク画像をアップロードしてください。ベクター変換が行われ、最後にベクター変換後のマスク画像がzipでまとめてダウンロードされます。
#
# ※ベクター変換を行う画像の枚数に応じて所要時間が異なります。
#
# ※変換に失敗する画像が含まれることがあります。変換に失敗したら、その画像だけ再度トライしてください。
#
#
#
#
# # [How to use]
#
# Run all cells by sele... |
0904c986430d8e7c8d0f10a9f3957bf4bff34c4d1c3e509457e6d33e75392295 | Jupyter | 5,534 | 98 | # %% [markdown]
# # Null distribution of agreement between LSNs
#
# Here, agreement matrices are calculated for data driven community partitions. Agreement matrix in an n-by-n matrix calculated for the set of community partitions (this set can also contain single partition). An element of the agreement matrix $D_{ij}$... |
946ffd5bab43214ea73d2736b95db80b8bd9cdc3ff182fe702a4f97342781f7d | Jupyter | 5,547 | 227 | # %% [markdown]
# ### Figure 7
# %%
import sys
import os
os.environ["JAX_PLATFORMS"] = "cpu"
# Get the absolute path to the project root (one directory up from notebooks/)
root_path = os.path.abspath("..")
sys.path.append(root_path)
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from src i... |
849ec91dc9068d3652be64a001cd66e84810902f125aa7991701a15c7ecd8288 | Jupyter | 5,554 | 100 | # %% [markdown]
# # SegCT/MRI
#
# Automatic anatomical segmentation from CT/MRI using **TotalSegmentator**. Lite and Local use this same notebook. Compatible DICOM series are converted to NIfTI inside SegRef3D with their patient geometry preserved.
#
# 1. Select **Runtime > Change runtime type > T4 GPU** (recommended... |
6428c78d4ddb49c8d59be6211581403d34db6a9586f3d0c7967cce16357fe6ec | Jupyter | 5,555 | 178 | # %%
import matplotlib.pyplot as plt
import analyze_go_enrichment
import os
import json
from collections import defaultdict
csv_dir = "results_13_01/prototypes"
outdir = "go_analysis_13_01"
cluster_ks = [128, 256, 512, 1024, 2048, 4096, 8192, 16384]
seg_ks = [64]
Nk, C, S, R, scores = defaultdict(list), defaultdict... |
5958130e85b2c94bcc07abbe868ecd9e5ec10051ca469b7ef6add3a4c97ae057 | Jupyter | 5,592 | 184 | # %% [markdown]
# # First Panel
# This first panel includes the image of a single trajectory timeslice (for legend/labeling purposes) as well as a before and after trajectory showing the results of the data preparation for the neurel net
# %%
import matplotlib
import matplotlib.pyplot as plt
import pandas as pd
import... |
a232fc5691cec140aa76dca91f929a8c89c95e55a225e2a9af1093a003549060 | Jupyter | 5,603 | 184 | # %% [markdown]
# # First Panel
# This first panel includes the image of a single trajectory timeslice (for legend/labeling purposes) as well as a before and after trajectory showing the results of the data preparation for the neurel net
# %%
import matplotlib
import matplotlib.pyplot as plt
import pandas as pd
import... |
d3b9afc9a14d0cbce5a8f7b363f321d339344df2f854acae11a96e91c49e95cf | Jupyter | 5,606 | 192 | # %% [markdown]
# # Plots for pure symmetrization in SALNet (fig. 9)
#
# In this experiment, we investigate the convergence speed of SAL alone in the SALNet, when the forward weights are constant.
# This helps us to determine the optimal tradeoff between fast convergence and low alignment angles by choosing an appropr... |
6b799b447e722b0f73577c151d1a960280159685816b5b34ef004cb1cbbfe977 | Jupyter | 5,617 | 175 | # %%
import os
import pandas as pd
#import pingouin as pg
import numpy as np
from tqdm import tqdm
from neuroCombat import neuroCombat
from concurrent.futures import ThreadPoolExecutor
import concurrent
NUM_WORKERS = 16
# %%
import numpy as np
import matplotlib.pyplot as plt
# %%
JUDGES = ["t2w_nfs", "t2w_fs"]
TISSU... |
b3607cca36e3d4dff7a8113c7a71d276d8005eee50936e05b3e2911668296860 | Jupyter | 5,645 | 161 | # %% [markdown]
# # Using FISSA with Suite2p
#
# [suite2p](https://github.com/MouseLand/suite2p) is a blind source separation toolbox for cell detection and signal extraction.
#
# Here we illustrate how to use suite2p to detect cell locations, and then use FISSA to remove neuropil signals from the ROI signals.
#
# ... |
eb7e77d530db68fe143680bf54552a1c4b901b33a1cbd33494922d271f68061d | Jupyter | 5,657 | 203 | # %%
import sys
import os
from os.path import dirname, realpath, join
base_dir = dirname(dirname(os.getcwd()))
import itertools
import pandas as pd
from os.path import join
base_dir
sys.path.insert(0, base_dir)
from config_path import PROSTATE_DATA_PATH, PLOTS_PATH, GENE_PATH, PROSTATE_LOG_PATH, BASE_PATH
from data.da... |
69b73d2df08c410b20cf6ec6d53d7458ca44bfe98318d6b223fcbde7a1a1aaf2 | Jupyter | 5,664 | 179 | # %% [markdown]
# Import modules.
# %%
import os
import numpy as np
import pandas as pd
from cichlid_omr.config import data_dir, load_config, output_dir
from cichlid_omr.io import convert_datetime, filenames_from_folder, load_timestamped_data
from cichlid_omr.signal import interpolate_nans, order_data_by_timestamps
... |
292dbd3fe8c5eecc6b7f92286d342be66adbd12008c0813a5eaacefba13d443f | Jupyter | 5,700 | 209 | # %%
import matplotlib.pyplot as plt
import numpy as np
plt.rcParams.update({
'font.size': 14,
'font.weight': 'light'
})
# %% [markdown]
# # Beta distribution parametrizations
# This section explores relation between different parametrizations of beta distribution.
# 1. Standard paramemtrization used $a$ and... |
69a639740ff2f781a685002c2567d2623b67064c9d11e9541d7b8c0de0d8999d | Jupyter | 5,700 | 213 | # %%
# Script for logistic regression and random forest multivariate models shown in Figure S2
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sns
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler
from sklearn.metrics import ... |
668ba1d35c29df0a6da071850b15220f54c156524e901573e62e85694d1e36bc | Jupyter | 5,702 | 184 | # %% [markdown]
# # Determinant penalty ablation study
# %%
import numpy as np
import matplotlib.pyplot as plt
from oneqmc.analysis.plot import set_defaults
from oneqmc.analysis import colours
set_defaults()
# %%
t = np.arange(0, 200, 0.025)
# %%
smooth_energy = np.load(
"../../experiment_results/08_si_ablatio... |
a0c1bc196dd852a6ad0f77321447c231df86b911fb0b333d8549b70bab685aba | Jupyter | 5,717 | 122 | # %% [markdown]
# ### **Code to extract ant and larva tracking data form the .mat file outputs of AnTrax for the brood care assay.**
#
# ##### This script expects a directory structure of that found in the directory '.../Sample_data_brood_care_assay/antrax/antdata'.
# ##### Running this script will result in the timed... |
8400b96c9f260da6f3aa81dec1e7082f6f1e66575df17bc8d805535c0360b1fb | Jupyter | 5,760 | 154 | # %% [markdown]
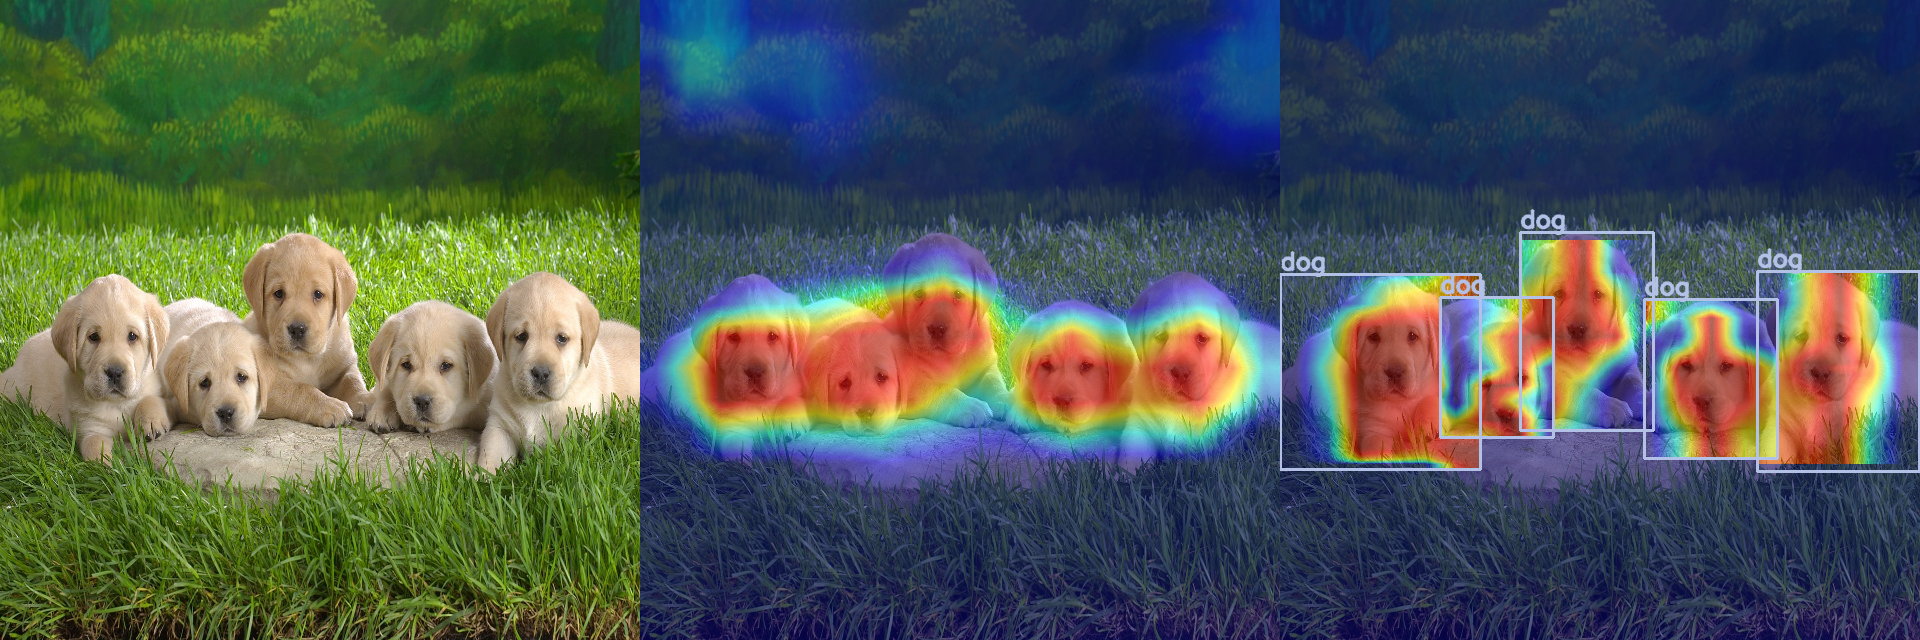
# # EigenCAM for YOLO5
#
# 
#
#
# In this tutorial we're going to see how to use EigenCAM (one of the gradient free methods) for YOLO5.
#
# This is a much simpler version of the tutorial in htt... |
596684be86ea23f284c6c7fa351a93f1de31f1c1ea43d00e628a001b947a4e6c | Jupyter | 5,764 | 197 | # %%
#Remove variables from workspace
%reset
# %%
%matplotlib inline
import os
import scipy.io
import fnmatch
from statistics import mean
import pickle
import fNIRSData
import numpy as np
import skfda
import matplotlib.pyplot as plt
from skfda.exploratory.visualization import FPCAPlot
from skfda.preprocessing.dim_red... |
97cd0862f70c1af86f2b41ce7cd3dde585eba3985ce86967279a4d1db7c82eef | Jupyter | 5,804 | 173 | # %% [markdown]
# # Inference with ChatNT
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/examples/inference_chatNT.ipynb)
# %% [markdown]
# ## Installation and imports
# %%
!pip ins... |
a05cece84a4f415cd360f9cbd8d71d030f80b191a32a7f742b049dd58ece3590 | Jupyter | 5,809 | 149 | # %% [markdown]
# # Process raw data — habituation
#
# Assemble the habituation experiment's `raw_data.json` from its recordings.
# %%
import pandas as pd
import os
import numpy as np
from cichlid_omr.config import data_dir, load_config, output_dir
from cichlid_omr.io import convert_datetime, filenames_from_folder, l... |
d93bbcff05049b4094cfd6924527c86811e09fbb1a70e9927b31a4a9f56bb798 | Jupyter | 5,816 | 181 | # %%
%matplotlib inline
# NOTE: %reset wipes every variable in the current kernel session, and normally
# prompts "Proceed (y/[n])?" interactively when run in a live notebook - kept
# here to ensure a clean run, but will hang if this notebook is ever run
# non-interactively (e.g. via jupyter nbconvert --execute).
%res... |
8287d0c37635b5f3571c9cc38d4c35ee164d24ff9d5879f45a82be279e5ef8a2 | Jupyter | 5,828 | 177 | # %% [markdown]
# ### In this notebook we guide you through an example on how to get started with AESTETIK
# 1) Data loading and preprocessing
# 2) Morphology feature extraction
# 3) Training the model
# 4) Spot representations and clustering
# %%
# Import pyvips first to lock in libvips' libjpeg/libtiff stack
# befor... |
933b1ad5d67fecdd470c0d8bb41976cb9e3798ef5754cc44bedf4900a88f0dbd | Jupyter | 5,837 | 122 | # %% [markdown]
# # Census income classification with LightGBM
#
# This notebook demonstrates how to use LightGBM to predict the probability of an individual making over $50K a year in annual income. It uses the standard UCI Adult income dataset. To download a copy of this notebook visit [github](https://github.com/sl... |
86575d00d18460617a42fbd64320833d3508c6d52a83aa8144802bdc3387cac7 | Jupyter | 5,866 | 161 | # %%
###
library(dplyr)
library(Matrix)
library(data.table)
library(Seurat)
library(ggplot2)
library(RColorBrewer)
library(Seurat)
library(ggplot2)
library (tidyverse)
library(RColorBrewer)
library(cowplot)
library(pheatmap)
library(deldir)
cols = c(brewer.pal(9, "Set1"),brewer.pal(8,"Set2")[1:8],brewer.pal(12,"Paired... |
70f5e7b112a17528fc8fbb85d1f81d768002c2d641ffeb1b1733dd23bac47ef0 | Jupyter | 5,873 | 182 | # %%
import pandas as pd
import os
import numpy as np
from collections import OrderedDict
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches
# %%
# estimate total, coding and noncoding het
template_dir = "/mnt/seagate10/genotypes/ldsc489eur10m"
coding_snps_f = "/mnt/seagate10/genotypes/ldsc489eur10m... |
a9a7f2075b3125c90a482d3baf16e26afc606cbaa2222f6f71ae62cdc6b1c633 | Jupyter | 5,876 | 231 | # %% [markdown]
# # Plotting
# %%
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt
import os
# %%
CM = 1 / 2.54
# %% [markdown]
# ## Scalability
# %%
con_sca = pd.read_table("consensus_scalability.tsv", sep="\t").astype(
{"consensus_method": "category"}
)
# %%
%matplotlib inline
fig, a... |
2cc1700394083d76e500f7bf7b372ee35c6d0af6c1e6cd8df95c30bad322545a | Jupyter | 5,889 | 171 | # %% [markdown]
# # Dynamic Bayesian Networks
# %%
# Imports
from pgmpy.models import DynamicBayesianNetwork as DBN
from pgmpy.factors.discrete import TabularCPD
# %%
# Initialize a simple DBN model modeling the Weather (W), Rain (O), Temperature (T), and Humidity (H).
dbn = DBN()
# pgmpy requires the user to defi... |
b3695cb8610cccc97801d75fab75ee928fd69d2461d40be8c73c4a1b99ce552f | Jupyter | 5,937 | 189 | # %%
import numpy as np
from rdkit import Chem
from rdkit.Chem import Descriptors
num_atom_feat = 34
def one_of_k_encoding(x, allowable_set):
if x not in allowable_set:
raise Exception("input {0} not in allowable set{1}:".format(
x, allowable_set))
return [x == s for s in allowable_set]
d... |
c384ec67a6ade513165bd418d12b6970eea6d77a756457222988d831fd59f836 | Jupyter | 5,954 | 177 | # %%
import neuroglancer
import numpy as np
# %% [markdown]
# Create a new (initially empty) viewer. This starts a webserver in a background thread, which serves a copy of the Neuroglancer client, and which also can serve local volume data and handles sending and receiving Neuroglancer state updates.
# %%
viewer = n... |
afd96f21bef1c246878e689d4155aecf005c6e44453ecf4b8bc2b75148b1040a | Jupyter | 5,963 | 139 | # %%
import os
import scanpy as sc
import numpy as np
import pandas as pd
from tasks.scfoundation import load
import anndata
import scipy.sparse as sp
# %%
def prepare_data(adata):
gene_list_df = pd.read_csv(f'{tokenizer_dir}/OS_scRNA_gene_index.19264.tsv', header=0, delimiter='\t')
gene_list = list(gene_list_... |
7f43cf71e93816bd79cf6e4f8fd03504b6fbaf3ef7fcc20ee684c2f282e2b383 | Jupyter | 6,009 | 179 | # %%
import os
os.environ["CUDA_VISIBLE_DEVICES"] = "2"
import sys
import json
import pickle
import gzip
import h5py
from glob import glob
from tqdm import tqdm
import numpy as np
import pandas as pd
from importlib import reload
from collections import defaultdict, OrderedDict
import matplotlib.pyplot as plt
import sea... |
ea62fda7732144eb3e70916647bef9454219ea24dbf845d3b69825206692793a | Jupyter | 6,009 | 153 | # %% [markdown]
# # Betaseries correlation
#
# This script uses beta-series extracted in the previous step to calculate correlation matrices. Executed steps:
# 1. Restrict atlas to ROIs that reside within brain mask for all participants. To do this script finds all ROIs with null beta-series comparing their standard d... |
a1732002113cde7d447fef1a24c09e28a1303451809ce7edc132a3d250da0dc0 | Jupyter | 6,022 | 176 | # %% [markdown]
# # Fitting a Linear Simulation with XGBoost
#
# This notebook uses shap to demonstrate how XGBoost behaves when we fit it to simulated data where the label has a linear relationship to the features.
# %%
import numpy as np
import scipy as sp
import xgboost
import shap
import sklearn
from sklearn.mode... |
6af737a8f43a9ae3dc4a2b144227ba9248f4983a3109cedbb945af5719cca75e | Jupyter | 6,041 | 183 | # %%
import numpy as np
import multiprocessing as mp
import matplotlib.pyplot as plt
from gutBrainCode.gutBrainPipeline import loadGutBrainData,fitLeftGetThresh,pullAverages, pullTimes, getTrains, getTrainsTwoTypes, fusedLoocv, pullCells, pullCellMasks,makeBrainMap,shift,corr,pullCenters,pullLocs
from gutBrainCode.gutB... |
ea6ed5118490c9322194c15deb108e49e260ad51ea607a5e5457e28f480b17f1 | Jupyter | 6,098 | 162 | # %%
import numpy as np
import matplotlib.pyplot as plt
import json
from sklearn import preprocessing
from scipy.stats import pearsonr
import sys
sys.path.append('/home/kmb/Desktop/Neuroscience/Projects/BONNA_decide_net/code')
from dn_utils.behavioral_models_REF import (get_response_mask,
... |
4707366387acbad59574ae64fa4f887382e8525854d1b597bd69af866263912f | Jupyter | 6,100 | 202 | # %%
import numpy as np
import joblib
from sklearn.metrics.pairwise import cosine_similarity
from visualizations import get_colors, show_factorization_on_image
from PIL import Image
import matplotlib.pyplot as plt
import cv2
import pydensecrf.densecrf as dcrf
from pydensecrf.utils import unary_from_softmax, create_pair... |
edb2559daabe09ff1872e026153fa5b35b98a79fb570d3a1e8ddbd95fe8ff68e | Jupyter | 6,114 | 196 | # %% [markdown]
# # Basic SHAP Interaction Value Example in XGBoost
#
# This notebook shows how the SHAP interaction values for a very simple function are computed. We start with a simple linear function, and then add an interaction term to see how it changes the SHAP values and the SHAP interaction values.
# %%
impo... |
ee80821647653cd47d66fc3a731ee6f0d293fd9d8f41c5773eabcd7fa1203afd | Jupyter | 6,162 | 152 | # %% [markdown]
# ## Second level GLM analysis
#
# This script performs group level modeling of BOLD response. Script features:
# - loads statistical maps from first level GLM analysis
# - discard data from excluded subjects
# - performs second level GLM analysis
#
# ---
# **Last update**: 24.07.2020
# %%
%matplot... |
ee438d47aa178c2438fa8f5b45fb3e8db28ce60e69e4b74619f2dc2a99abfc0c | Jupyter | 6,167 | 202 | # %%
import sys
import os
sys.path.append("engine/")
sys.path.append("funcs/")
sys.setrecursionlimit(10000)
import theano.gpuarray
theano.gpuarray.use('cuda0')
import theano
import theano.tensor as T
from theano import config
import numpy as np
import pickle
import copy
import time
from itertools import *
from matpl... |
51c1251e722a4ce5856e544515d158fb5626fb8a5adb7200c1e9233e8781ab2c | Jupyter | 6,205 | 226 | # %% [markdown]
# ## Spatial molecular niche discovery (single-modality with multiple batches)
# %% [markdown]
# Here we will use seqFISH Mouse Organogenesis datasets as an example to illustrate how Garfield performs spatial molecular niche discovery for multiple batches. Data access: https://marionilab.cruk.cam.ac.uk... |
7567205af3c4f1c4175523cccdce959405e8c9a40aa1a32e50fd9799d76637b7 | Jupyter | 6,241 | 236 | # %% [markdown]
# # Spatial niche discovery of multi-modality data
# %% [markdown]
# Here we will use spatial ATAC-RNA-seq mouse brain dataset as an example to illustrate how Garfield performs spatial multi-omics integration analysis. Data access: https://www.nature.com/articles/s41586-023-05795-1.
# %%
import os
imp... |
4eead8e34214c3b8b3364b2917533aa8a82319e99da5a197bd2c5067a7815707 | Jupyter | 6,253 | 197 | # %% [markdown]
# # Discover genes that are up/down-regulated in various perturbations in NE
# %% [markdown]
# ## 1. Import packages
# %%
# Import all the packages
# Run in pyenv4
import numpy as np
import pandas as pd
import scipy
from scipy.io import mmread, mmwrite
from scipy.sparse import load_npz, save_npz, coo... |
42d38b7d78e3960c51061415bb02cccd1e984384179ac6d4cbd879d6443a91f8 | Jupyter | 6,257 | 193 | # %% [markdown]
# # Discover genes that are up/down-regulated in various perturbations in NPB
# %% [markdown]
# ## 1. Import packages
# %%
# Import all the packages
import numpy as np
import pandas as pd
import scipy
from scipy.io import mmread, mmwrite
from scipy.sparse import load_npz, save_npz, coo_matrix, csr_ma... |
6a950a8f9bc516d085d9d26b6b04f64db03b6394c5379cc44c75c33d934c11ab | Jupyter | 6,296 | 189 | # %%
import numpy as np
from rdkit import Chem
from rdkit.Chem import Descriptors
num_atom_feat = 34
def one_of_k_encoding(x, allowable_set):
if x not in allowable_set:
raise Exception("input {0} not in allowable set{1}:".format(
x, allowable_set))
return [x == s for s in allowable_set]
d... |
1d0c2db7b5fe0d097e357aab7716734336378b7e14aefbeeebb49fcc243b4a1a | Jupyter | 6,326 | 175 | # %% [markdown]
# # Betamaps exploration
#
# This script creates handy visualisations of betamaps calculated on previous step. For each subject and task condition single plot is created. Each plot consist six subplots:
# - **top panel**: framewise displacement (FD) for entire run duration, it roughly corresponds (visu... |
b40a3a50da6ec003b127ea1977ad405c7f38ff529dc9f1df10e5ca3980d72921 | Jupyter | 6,356 | 189 | # %% [markdown]
# # Inference with pretrained Nucleotide Transformer models
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/notebooks/codon_nt/inference.ipynb)
# %% [markdown]
# ## In... |
8e56689dea35584a3b1124d16ef145d94485b5c98163384f922942d2a831e55a | Jupyter | 6,361 | 190 | # %%
import scanpy as sc
from anndata.experimental import concat_on_disk
from umap import UMAP
import numpy as np
import bionty as bt
from scdataloader.utils import get_all_ancestors
import matplotlib
import datamapplot
# %%
# run the model in parallel in a slurm job
# conda activate scprint17
srun -p gpu -q gpu --g... |
6c874c1e37372755aa02a2f1a5959d1cae41997a66fab3153bf5a685cb09af2c | Jupyter | 6,368 | 183 | # %% [markdown]
# ## Dependencies
# %%
suppressPackageStartupMessages({
library(data.table)
library(ggplot2)
library(dplyr)
library(IRdisplay)
library(purrr)
library(readxl)
library(tidyr)
library(tibble)
#install.packages("ggbeeswarm")
#install.packages("wesanderson")
#inst... |
e736ecdf12080f42358906c25266ceb732afd3b2a1c8e906fb1f85598e4242bb | Jupyter | 6,379 | 189 | # %% [markdown]
# # Inference with pretrained Agro Nucleotide Transformer model
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/notebooks/agro_nucleotide_transformer/inference.ipynb)
... |
1d39f15a5337f45d03d307a700ec50a334bf483946438221aacce5c4ea6fa587 | Jupyter | 6,389 | 142 | # %% [markdown]
# # 【使い方】
#
# ランタイム>すべてのセルを実行(**Ctrl+F9**)によりすべてのセルを実行し、セル[2]の最後に生成された**URL(Running on public URL)をクリック**して開いてください。(GUIが新しいタブで開かれる)
#
# ※このcolabの画面(タブ)は閉じないでください。
#
#
#
#
# # [How to use]
#
# Run all cells by selecting Runtime > Run all cells (**Ctrl+F9**), and **click the URL generated at the en... |
3280cbe03224a03d48afc8d081967ec2ff0e659e0a238cbbfd542e2524b54b0a | Jupyter | 6,401 | 234 | # %% [markdown]
# # Spatial molecular niche discovery
# %% [markdown]
# Here we will use seqFISH Mouse Organogenesis datasets as an example to illustrate how Garfield performs spatial molecular niche discovery for multiple batches. Data access: https://marionilab.cruk.cam.ac.uk/SpatialMouseAtlas/.
# %%
import os
impo... |
53b9eb21c1417e3e1f3e96dfbf75d43aa5f632ce290f566ec9fa0b6ddcb7767a | Jupyter | 6,428 | 247 | # %%
import scanpy as sc
from anndata.experimental import concat_on_disk
from umap import UMAP
import numpy as np
import bionty as bt
from scdataloader.utils import get_all_ancestors
# %%
ls -alh ../data/step_0_predict.h5ad
# %%
adata = sc.read_h5ad("../data/step_0_predict.h5ad")
adata
# %%
adata = sc.read_h5ad("..... |
42a856e269a7dc48a49ce861c602761e902bca0431872df7ef8de7663085dac1 | Jupyter | 6,478 | 160 | # %%
% matplotlib inline
from neurosynth.base.dataset import Dataset
from neurosynth.analysis import decode
import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib as mpl
import matplotlib.pyplot as plt
mpl.rcParams['svg.fonttype'] = 'none'
# %%
def getOrder(d, thr):
dh = []
for i in r... |
7a834aeae752a5a2afc126af1b88b54a722e2e1e86d19d73e9615c3956ab0435 | Jupyter | 6,487 | 197 | # %%
%matplotlib inline
import matplotlib.pyplot as plt
# %%
%%writefile embed.py
"""Generate a diffusion map embedding
"""
def compute_diffusion_map(L, alpha=0.5, n_components=None, diffusion_time=0,
skip_checks=False, overwrite=False):
"""Compute the diffusion maps of a symmetric simil... |
eab07a43794f23243351d60f17b857bb34a58bc1cf04d23a5f6b1b5b60a176c6 | Jupyter | 6,487 | 200 | # %% [markdown]
# # Discover genes that are up/down-regulated in various perturbations in NE
# %% [markdown]
# ## 1. Import packages
# %%
# Import all the packages
import numpy as np
import pandas as pd
import scipy
from scipy.io import mmread, mmwrite
from scipy.sparse import load_npz, save_npz, coo_matrix, csr_mat... |
076e388b37e919dbc999bd177599e01d6ca6335b69808a406c25e3db817e57e2 | Jupyter | 6,489 | 196 | # %%
import numpy as np
from dataclasses import dataclass
from datetime import datetime
import json
import os
import sys
sys.path.insert(1, '/path/to/application/app/folder')
time_now = datetime.today().ctime()
today_date = datetime.today().date()
# packages for plotting
import matplotlib.pyplot as plt
import matplotl... |
740c0e2b840f61ee3304b17a8b47cfa2826babe21eb643b303910fd5b1d9165c | Jupyter | 6,489 | 222 | # %%
%pylab inline
import scanpy as sc
import pandas as pd
# %%
def main_gene_selection(X_df, gene_list):
"""
Describe:
rebuild the input adata to select target genes encode protein
Parameters:
adata->`~anndata.AnnData` object: adata with var index_name by gene symbol
gene_list->li... |
b66dee65bb2c8c787597049f6a0296f60bbc8482faa3b392b3cd99a0892de3a3 | Jupyter | 6,496 | 198 | # %%
import numpy as np
import pandas as pd
import json
from dataclasses import dataclass
from datetime import datetime
import os
import sys
sys.path.insert(1, '/path/to/application/app/folder')
today_date = datetime.today().date()
time_now = datetime.today().ctime()
# packages for plotting
import matplotlib.pyplot as... |
e92c6c638ed1e4985e21f413bc91c6483eded6169cb49dceab6cfb27295c2828 | Jupyter | 6,516 | 222 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
import warnings
warnings.filterwarnings('ignore')
from collections import Counter
from tqdm import tqdm
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from sklearn.model_selection import train_test_split
from sklea... |
e5390f971c0bd05e90606d1ebc7f9fb292fb3c26815c975d1e6b849988a7d268 | Jupyter | 6,552 | 219 | # %% [markdown]
# ##準備
# %%
import pandas as pd
import matplotlib.pyplot as plt
from matplotlib.transforms import Bbox as BB
from google.colab import drive
from statistics import *
import numpy as np
from PIL import Image
import cv2
import os
drive.mount('/content/drive')
Repository_path = ""
# %%
#CSV形式の各ドロップレットをイ... |
4db8e67cef58a1b0d50dff2b0b65be7a7cf9fb3050e960a847b0f36bc9d0ddfb | Jupyter | 6,554 | 202 | # %%
import numpy as np
from dataclasses import dataclass
from datetime import datetime
import json
import os
import sys
sys.path.insert(1, '/path/to/application/app/folder')
time_now = datetime.today().ctime()
today_date = datetime.today().date()
# packages for plotting
import matplotlib.pyplot as plt
import matplotl... |
6c5aedc909e67984898b415819c3bc30ac54973fb9f2103d0b45df593aa7ce9c | Jupyter | 6,579 | 191 | # %% [markdown]
# # Inference with pretrained Nucleotide Transformer models
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/notebooks/nucleotide_transformer/inference.ipynb)
# %% [mar... |
38d688459a836e17de248a870d28ab9ceae2a7c17e8a21e7de732871c38d386c | Jupyter | 6,626 | 253 | # %% [markdown]
# ## Figure 6
#
# %%
import sys
import os
os.environ["JAX_PLATFORMS"] = "cpu"
# Get the absolute path to the project root (one directory up from notebooks/)
root_path = os.path.abspath("..")
sys.path.append(root_path)
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from src... |
3da19759c0026774c494787e38318c3b476289d3a842c157b5f13ae8858beda4 | Jupyter | 6,627 | 185 | # %% [markdown]
# # Fin cross-correlations
#
# Cross-correlograms between tail and pectoral-fin signals per genotype and condition.
# %%
import json
import matplotlib.pyplot as plt
import numpy as np
from scipy.signal import correlate, correlation_lags
from cichlid_omr.config import data_dir, load_config, output_dir... |
a9e5aa98e60438604c14237502bd802d264b7465d28d1e9bd66b0566d5a2101f | Jupyter | 6,627 | 182 | # %% [markdown]
# # Spot or bin resolutions
#
# Our main tutorials focus on imaging-based technologies such as Xenium or MERSCOPE data. Still, you can use Novae on NGS-based technologies such as Visium or Visium HD data. Since the resolution is highly different, we split this tutorial into two main sections: one for V... |
5b1d87ef02f421eb5723a6090c2788d7f41312663a58d676b335d9f6297e7365 | Jupyter | 6,644 | 209 | # %%
##### Fig. 1 - Phoneme and prosody identification tasks and behavioural results
#
# written by S-C. Baek
# updated date: 16.12.2024
#
# %%
# import packages
import os
import scipy.io
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
# %%
# path settings
FIGDIR = os.getcwd()
MAINDIR = os.p... |
99452049b5df40486fb27f5111e2faa03587b6b36e527a9dbc23e764a709a5d9 | Jupyter | 6,647 | 175 | # %%
import matplotlib.pyplot as plt
import pandas as pd
import numpy as np
import json
import sys
import os
import scipy
import scipy.io
from scipy import stats
path_root = os.environ.get('DECIDENET_PATH')
path_code = os.path.join(path_root, 'code')
if path_code not in sys.path:
sys.path.append(path_code)
from d... |
7f56c6e07636de020a052bb3971eefd1b582189b3c8eaa236e0a69af72447b98 | Jupyter | 6,650 | 260 | # %% [markdown]
# # Plot the phase plane diagram and SAL weight evolution (fig 2d and e)
# %%
from pathlib import Path
import numpy as np
import matplotlib as mpl
import matplotlib.pyplot as plt
from tqdm import tqdm
from tqdm.contrib.itertools import product
from neuralsampling.network import sim_poisson_neurons, r... |
820d81fc45a9a49ed7f36062e9f14e02f88cdba8bde8b71e5d8684df1fb92776 | Jupyter | 6,652 | 228 | # %% [markdown]
# # Fine-tune Pre-trained Nicheformer Model for Downstream Tasks
#
# This notebook fine-tunes a pre-trained Nicheformer model for downstream tasks and stores predictions in an AnnData object.
# %%
import os
import numpy as np
import pytorch_lightning as pl
from pytorch_lightning.callbacks import Model... |
18ed6c30e736be74fb65653e0ef6c91a9e1cd693acd46693249a49b78554be4f | Jupyter | 6,664 | 201 | # %%
import numpy as np
import pandas as pd
import json
from dataclasses import dataclass
from datetime import datetime
import os
import sys
sys.path.insert(1, '/path/to/application/app/folder')
today_date = datetime.today().date()
time_now = datetime.today().ctime()
# packages for plotting
import matplotlib.pyplot as... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.