
sha256 stringlengths 64 64 | language stringclasses 28
values | size int32 1 491k | lines int32 1 23.2k | content stringlengths 1 200k |
|---|---|---|---|---|
5c849d1c395aea3f138ccd0c777d21f965c61f14dfb0cde7e5f28fa847e06acb | Jupyter | 6,668 | 202 | # %% [markdown]
# # Load brain parcellations used to label activation peaks
#
# Here different parcellations are loaded to later serve as input for `add_clusters_label` function. Each parcellation must be processed to contain:
# - Nifti1 parcellation image with voxel intensity corresponding to region index (each image... |
d145b52a031e56093e505928b1ab65bd3e99cc9247d6286e48725f5b953e4f51 | Jupyter | 6,679 | 193 | # %%
import shutil
import time
import os
import SimpleITK as sitk
import pydicom as pydicom
from tqdm import tqdm
import subprocess
import pandas as pd
from concurrent.futures import ThreadPoolExecutor
NUM_WORKERS = 16
%matplotlib notebook
import gui
import registration_gui as rgui
# %%
DATA_DIR = r"/home/thulas... |
f41ee418a77e09f4f7b8bb348723ac57693e0a8979d5dc9711cd73ed841d90cb | Jupyter | 6,703 | 199 | # %% [markdown]
# # Playground 9: Segmentation workflows for lamin b1 (interphase)
#
# This notebook contains the workflows for lamin B1 (interphase-specific), and serves as a starting point for developing a classic segmentation workflow for your data with shell-like shapes.
#
# -------------------------------------... |
8b1453f944ff76882ad392c80547e5da9ebc7b6fdd9f8e3048e7d6b7c546c7fa | Jupyter | 6,717 | 180 | # %% [markdown]
# ## Pathing, parameters and setup
# %%
import h5py
import pandas as pd
import scipy
import numpy as np
from pathlib import Path
from tqdm import tqdm
projectRoot = Path().resolve().parent
# %% [markdown]
# ## USER SETTINGS
#
# `dataDriveRoot` is the root of the drive/mount holding the MATLAB reco... |
e1404f35ffacc5c039bf72f7e767fbd2334da9aceb4de59a13215378bd582506 | Jupyter | 6,737 | 151 | # %% [markdown]
# # Node profile dissimilarity between conditions
#
# Aim of node profile dissimilarity analysis is to find network nodes (ROIs) with highest variability of module assignemnt between task conditions. Highly variable nodes has different node profies depending on the task condtion. **Node profile** for n... |
784f35ec1a5cc409e903c00d415d8b56d4e60c896c19be790f823d15f3532e42 | Jupyter | 6,765 | 194 | # %% [markdown]
# # Expert Knowledge Integration with Causal Discovery
# %% [markdown]
# Causal Discovery (aka. Structure learning) seeks to uncover the causal relationships among random variables from observational datasets. Methods like the PC algorithm and Hill-climb Search can be used for causal discovery, however... |
dbbb260f67f2d94b37d4219ff31866162ab2b6c27be99af408394ceeda8492b5 | Jupyter | 6,766 | 147 | # %% [markdown]
# # Hybrid approach phrase preprocessing
#
# In this tutorial, we will cover the phrase preprocessing step for the hybrid-dictionary-ner approach. An alternative (and compatible) more general preprocessing can be found in the medline-preprocessing repository in [this tutorial](https://github.com/zbmed-... |
36ca08f1ba7d25328665aae64c7f072f68b318966f61134151869c5fa5aa54fa | Jupyter | 6,791 | 204 | # %% [markdown]
# #Running MMS-TTS inference in Colab
# In this notebook, we give an example on how to run text-to-speech inference using MMS TTS models.
#
# By default, we run inference on a GPU. If you want to perform CPU inference, go to "Runtiime" menu -> "Change runtime type" and set "Hardware accelerator" to "... |
b374ca0db2899d29b29c950379137000f1a5b32f4f3db34bbf9b117cc6ee5a37 | Jupyter | 6,799 | 182 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import scipy... |
647083ade19b66d0c152384a63049a8a569d2332fd159860fce6f38043251d1a | Jupyter | 6,851 | 175 | # %%
from tasks.scfoundation import load
import scipy.sparse as sp
import anndata as ad
import hdf5plugin
import pandas as pd
import numpy as np
import scanpy as sc
from scipy.spatial.distance import cdist
# %%
def prepare_data(adata, need_normalization=True):
gene_list_df = pd.read_csv(f'{tokenizer_dir}/OS_scRNA... |
65260a8bc520101de6ce8cb1b11bfbe1a54329f9bc152ff860fc382baa17e1be | Jupyter | 6,877 | 190 | # %% [markdown]
# ## Zero-shot prediction of *BRCA1* variant effects with Evo 2
#
# The human *BRCA1* gene encodes for a protein that repairs damaged DNA ([Moynahan et al., 1999](https://www.cell.com/molecular-cell/fulltext/S1097-2765%2800%2980202-6)). Certain variants of this gene have been associated with an increas... |
ad2f64ae1f37053234fd39d618c369c91d3bc0bf320264264240a6e674b6b30a | Jupyter | 6,895 | 163 | # %%
import numpy as np
import matplotlib.pyplot as plt
from scipy.integrate import solve_ivp
from TE import transfer_entropy
# %% [markdown]
# # Transfer Entropy between timeseries
#
# In this notebook we compute the transfer entropy (TE) between an auto-correlated time series Y and a derived time series X, assess... |
94e40e9bff44ff6959db5c2b9878a18af60ac280380204a718129589f59a0909 | Jupyter | 6,946 | 212 | # %% [markdown]
# # Performing SMD on all data
# %% [markdown]
# ## 1. Import packages
# %%
# Import all the packages
import numpy as np
import pandas as pd
import scanpy as sc
from scipy.io import mmread, mmwrite
from scipy.sparse import load_npz, save_npz, coo_matrix, csr_matrix, vstack
from scipy.ndimage import g... |
08837e8a407b280b25f0c62f490dc0bdf18ad6bda33c1631dc4f4d0a9623a577 | Jupyter | 6,984 | 255 | # %%
%pylab inline
import pandas as pd
import scanpy as sc
# %%
def postprocess(adata,view=True):
sc.pp.normalize_total(adata, target_sum=1e4)
sc.pp.log1p(adata)
sc.pp.highly_variable_genes(adata)
adata.raw = adata
adata = adata[:, adata.var.highly_variable]
print('after select HVG',adata.shape... |
63135be5ea9d1cdf7f3e1cfd75261872c6f0c6d9296de6b582e6173194c4ca0d | Jupyter | 7,089 | 270 | # %% [markdown]
# ### TF - motif bias matrix
#
# 1. downloading gene - motif name mapping in here: https://resources.aertslab.org/cistarget/motif_collections/v10nr_clust_public/snapshots/motifs-v10-nr.hgnc-m0.00001-o0.0.tbl
# 2. then load the motif -> gene enrichment mapping in here: https://resources.aertslab.org/cis... |
db796d460389a8f96d22245e41fecb00781173355ee7f6073bd1b19e7abae0e0 | Jupyter | 7,115 | 221 | # %%
##### Fig. 4 - Transfer of phonemic and prosodic representations along ventral and dorsal streams
#
# written by S-C. Baek
# updated date: 16.12.2024
#
# %%
# import packages
import os
import sys
import pickle
import numpy as np
import pandas as pd
from mne.stats.multi_comp import fdr_correction
import matplot... |
9a226838aaef4651c0ac33865061487e19c75784e65e8dd72fcff72656b75936 | Jupyter | 7,127 | 225 | # %% [markdown]
# ### Speed comparison of gradient boosting libraries for shap values calculations
# %% [markdown]
# Here we compare CatBoost, LightGBM and XGBoost for shap values calculations. All boosting algorithms were trained on GPU but shap evaluation was on CPU.
#
# We use the epsilon_normalized dataset from [... |
f9edb8032683c4397eac538c64fb54c6394ce9a13884b57d805e9a70458a4af2 | Jupyter | 7,132 | 239 | # %% [markdown]
# # Marginal Learning in Discrete Markov Networks
# %% [markdown]
# In this notebook, we show an example for learning the parameters (potentials) of a Factor Graph or Markov Network given the data and its corresponding marginals.
#
# In the examples, we will generate some data from given models and pe... |
e5140623c8209bab97fd1de650d629a15c61cb1d2fc6c3b27c18c03edb1b03f1 | Jupyter | 7,157 | 219 | # %%
%load_ext blackcellmagic
# %% [markdown]
# #### Imports and setup
# %%
import deepdish as dd
import pandas as pd
import numpy as np
import statsmodels.formula.api as sm
from statsmodels.stats.multitest import multipletests
# %%
from spacestream.core.constants import SUBJECTS, CORE_ROI_NAMES
from spacestream.co... |
7656fa203e5edf27ae161b71ef20a69128cdf1df41cd9b767d50f897f2e0dfe3 | Jupyter | 7,178 | 288 | # %%
### Sensitivity Analysis of the Number of Clusters
# %%
# install_github(repo="ntdyjack/fasthplus", ref = "main")
library(fasthplus)
library(SpatialExperiment)
library(here)
library("sessioninfo")
library(spatialLIBD)
library(dplyr)
library(stringr)
library(mclust)
library(pheatmap)
library(Seurat)
library(ggplot... |
a2f642622ec03d1fd1ea73b9dee6a5215a8e16544234ee2a8e3773b31b0f2378 | Jupyter | 7,229 | 175 | # %% [markdown]
# # Plotting a cortical mesh coloured by parcellation
#
# Example/utility notebook showing how to load a cortical surface mesh (produced by `makeBrainMesh.ipynb`) together with a volumetric parcellation atlas, map parcel labels onto mesh vertices, and colour the mesh using proper graph colouring (adjac... |
4fdaa4a349d25a0b1119a545079ba1bda88496832deba569ad02d7cbe540f521 | Jupyter | 7,232 | 229 | # %%
import numpy as np
import pandas as pd
import json
from dataclasses import dataclass
from datetime import datetime
import os
import sys
import exmol
sys.path.insert(1, '/path/to/application/app/folder')
today_date = datetime.today().date()
time_now = datetime.today().ctime()
# packages for plotting
import matplot... |
12ddfd4e973f0b1fcffe9e255e09f7e22e80131262dc9f206e8fb91ebd85b405 | Jupyter | 7,233 | 165 | # %% [markdown]
# # SegAnything for SegRef3D
#
# ## Before running: select a GPU runtime
#
# In Colab, select **Runtime > Change runtime type > T4 GPU > Save**. Another assigned NVIDIA GPU can also be used.
#
# 1. In SegRef3D Lite, open **SegAnything > AI Tracking Setup**.
# 2. Set each object's tracking range and a... |
f0c5b8167cd296608fa5de21c40d469900de1b4d956cad7a31110ca03d6c949c | Jupyter | 7,259 | 235 | # %%
%matplotlib inline
%reset
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import pickle
import skfda
import sys
from scipy.integrate import simpson
from skfda.preprocessing.dim_reduction import FPCA
from skfda.representation.basis import BSplineBasis
from statsmodels.stats.multitest impor... |
815e48cf6bb4fc88c6515757dc2db9aca30f6ac71e2425daaaf1a1cf95d05905 | Jupyter | 7,263 | 194 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import scipy... |
273755dfec040aa362a9cc8f1bb763e13966f630392a36b9702622bdd46f898e | Jupyter | 7,266 | 198 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import scipy... |
df0e9e0465d8ec7f482a050d53acb912744d67a496711c24a77179d20dc35531 | Jupyter | 7,278 | 255 | # %% [markdown]
# # QueryToReference mapping
# %% [markdown]
# Here we will use human pancreas datasets (scRNA-seq data) of different studies as an example to illustrate how Garfield performs QueryToreference process.
# %%
import os
os.chdir('/data2/zhouwg_data/project/Garfield')
os.getcwd()
# %%
# load packages
imp... |
251aa47f7b8c9da3d4a8301728477a349bdca4828eb0e62c4062d4cfa361424c | Jupyter | 7,285 | 245 | # %% [markdown]
# ##paper stats generator
# ryoung@unlv.edu
# %%
# Cell 1
import os
import pandas as pd
import numpy as np
from sklearn.metrics import confusion_matrix, cohen_kappa_score, mean_absolute_error
# (Optional) For fuzzy matching
# !pip install rapidfuzz
# from rapidfuzz import process
# Ensure output di... |
5b8b03cbf13f331fb3b70eee5f01920dcbe9f6a7724bf7731cc83ccdb9803bb3 | Jupyter | 7,337 | 200 | # %% [markdown]
# # Consensus partition diagrams
# %%
import json
from itertools import product
from os.path import join
import numpy as np
import pandas as pd
import plotly.graph_objects as go
from dn_utils.networks import communities_overlap
from dn_utils.path import path
from dn_utils.style import BLUE, ORANGE, PO... |
0a05faf5e64e6de53acb1d76b35c00f07e2664695b43f765762f1349c0b87e2d | Jupyter | 7,343 | 263 | # %% [markdown]
# # Pipeline Figure
# %%
import matplotlib.pyplot as plt
from matplotlib.patches import FancyBboxPatch, FancyArrowPatch
from pathlib import Path
import numpy as np
OUT = Path("saves") / "figures"
OUT.mkdir(parents=True, exist_ok=True)
fig, ax = plt.subplots(figsize=(10.5, 16.5), dpi=180)
ax.set_xlim(... |
e78db113b3f4ab89ef3c6aa75f642ceb930a973913dec6dba5272e49d62fc3d8 | Jupyter | 7,347 | 260 | # %%
import numpy as np
import pyscf
import py3Dmol
from uncertainties import ufloat
import matplotlib.pyplot as plt
# %%
from oneqmc.analysis.visual import show_mol
from oneqmc.convert_geo import load_molecules
from oneqmc.analysis.plot import set_defaults
set_defaults()
# %%
with np.load(
"../../../data_paper... |
0514e3ecc47645d7a3eb6905b1a7b03fc0d46eb838932acf052acb658a5cac1d | Jupyter | 7,370 | 203 | # %% [markdown]
# # NMF and co-segmentation.
# Works best with 1 bin, tolerance of 0.1, and starting from m/z 600 (skipping the first 300.)
# %%
from sklearn.decomposition import NMF
import matplotlib
from matplotlib import pyplot as plt
from matplotlib.lines import Line2D
import cv2
import numpy as np
from typing imp... |
7b8423878df8c0bce018fb9a87b0c31b1f9c044943c9e1984d861a937feba8dd | Jupyter | 7,371 | 140 | # %% [markdown]
# # InferRef3D v1.0 — custom model inference
#
# Apply one trusted `trainref3d-model-1.0` binary model to one SegRef3D inference request. Select **Runtime → Change runtime type → T4 GPU**, then **Runtime → Run all**. In the first code cell, approve the upload and select both ZIPs together:
#
# - **Mod... |
7a1ec92478def861d32337a50167f728a3cae1c856e79f2f87e1474fb91b1c31 | Jupyter | 7,378 | 260 | # %% [markdown]
# # Inference with Segment-Borzoi
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/notebooks/segment_nt/inference_segment_borzoi.ipynb)
# %% [markdown]
# ## Installatio... |
5330162f89f4adf0c9a2233326ebc06326ad17ec3180fb72ca4d43b1468b73a1 | Jupyter | 7,388 | 176 | # %% [markdown]
# # Running MMS-ASR inference in Colab
# %% [markdown]
# In this notebook, we will give an example on how to run simple ASR inference using MMS ASR model.
#
# Credit to epk2112 [(github)](https://github.com/epk2112/fairseq_meta_mms_Google_Colab_implementation)
# %% [markdown]
# ## Step 1: Clone fair... |
898d57a61164e0c4d254b3925281ed67c4ae71b813d7041e56b268603486854e | Jupyter | 7,392 | 260 | # %% [markdown]
# # Inference with Segment-Enformer
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/notebooks/segment_nt/inference_segment_enformer.ipynb)
# %% [markdown]
# ## Install... |
2222216b2727109dddfdc2b60b7273eefe36e47e1b37504aa8dbb80e24d18e6d | Jupyter | 7,394 | 272 | # %%
import sys
import os
from os.path import dirname, realpath, join
base_dir = dirname(dirname(dirname(os.getcwd())))
import itertools
from mutex import MutEx
import pandas as pd
from os.path import join
base_dir
# %%
sys.path.insert(0, base_dir)
from config_path import PROSTATE_DATA_PATH, PLOTS_PATH
from data.data_... |
939b6132686e3a26b95a3694560b8e935b04531642c5fa66c221d03d64f52e55 | Jupyter | 7,395 | 179 | # %% [markdown]
# # Adding H&E information
#
# In case you have an H&E slide aligned with your Spatial Transcriptomics data, you can train a new `Novae` model in multimodal mode.
#
# To handle Spatial Transcriptomics combined with H&E data, `novae` uses [`sopa`](https://prism-oncology.github.io/sopa/) and [`spatialda... |
85a0d276844d949cfb616d13f8f8dbbbbb7edbe3aee54d99a1ecb6dc15cf9cab | Jupyter | 7,407 | 254 | # %% [markdown]
# # Fig 1b: human fLoc selectivity by stream
#
# This notebook mirrors `F06_C.ipynb`, but uses **subject fLoc t-maps in fsaverage space** (`lh/rh.floc* tval_subjXX.mgz`) and fsaverage stream labels (`lh/rh.streams.mgz`).
# %%
import numpy as np
import pandas as pd
import nibabel as nib
import matplot... |
d11af1a563720045d84d429557142068864345982fe206334a2365c19aab1e7b | Jupyter | 7,443 | 137 | # %% [markdown]
# ##### **Code for determing the transition points betwen phases P1 and P2 for every ant in the experiment.**
# ##### This script requires the files 'timedata_C*.csv', PositionData_C*.csv' and 'stats_corrected.csv' resulting from Code_1, Code_2, and manual correction of 'larva_detect_frame' if required.... |
5bf1037638eebd3863fef1691aa28241d3e61e5e3645cc7d0cdef783718d0903 | Jupyter | 7,455 | 128 | # %% [markdown]
# # TrainRef3D v1.0 — one model, one target
#
# Build a MONAI 3D U-Net research baseline from a TrainRef3D Dataset ZIP. Select **Runtime → Change runtime type → T4 GPU**. Run the first code cell to approve and upload your Dataset ZIP before any installation. Then select **Runtime → Run all**; the saved... |
a23ed176a2893f9840e89011ecf14447737073e2124f2011c2791abdf1ebf318 | Jupyter | 7,455 | 211 | # %% [markdown]
# # Novae + scConcept
#
# One of Novae’s key strengths is its ability to operate across datasets with different gene panel sizes. In the original model, this is achieved by projecting the gene expression vector through a learnable gene-embedding matrix. More recently, we introduced a new variant that r... |
f68601464bb7d92b2d4072c53942a2c20271ce80d1a54e29fff1e43195aee463 | Jupyter | 7,459 | 186 | # %%
%load_ext autoreload
%autoreload 2
from ambiguous.dataset.dataset import DatasetFromNPY, DatasetTriplet, partition_dataset, partition_datasetV2
from ambiguous.models.cvae import ConvolutionalVAE
from ambiguous.models.readout import Readout
from ambiguous.train.train_MNIST_final_ccvae import reconstruct, reconstruc... |
09c3ce3c5bfbd4f8d319e6f4540c997edb7a8152eba81bf83d9f57068de765ad | Jupyter | 7,462 | 253 | # %% [markdown]
# # benchmarking on omnipath
# %%
from scprint import scPrint
from scprint.tasks import GNInfer
from bengrn import BenGRN
import scanpy as sc
from bengrn.base import train_classifier
from anndata.utils import make_index_unique
from bengrn import compute_genie3
from grnndata import utils as grnutils
... |
84525118d1c347665bda8a993e302126dfe84b39fa0922adb6520c211ca8daf1 | Jupyter | 7,466 | 202 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import scip... |
5b38b0fc03f576b1f6da53f04329817cb25c97ac5407d1d594739ec68974c231 | Jupyter | 7,475 | 221 | # %%
library(dplyr)
library(Matrix)
library(data.table)
library(Seurat)
library(ggplot2)
library(RColorBrewer)
library(cowplot)
library(future)
library(viridis)
library(SeuratObject)
library(tidyr)
plan("multicore", workers = 16)
options(future.globals.maxSize = 100 * 1024^3)
library(ComplexHeatmap)
cols = c(brewer.pal... |
100238f1aac09473f4186b0855e231db7aca7d02bb65d9c0a8ec201ac4711377 | Jupyter | 7,485 | 295 | # %% [markdown]
# ## Figure S2
# %%
import matplotlib.colors as mcolors
from mpl_toolkits.axes_grid1 import make_axes_locatable
# %%
import sys
import os
# Get the absolute path to the project root (one directory up from notebooks/)
root_path = os.path.abspath("..")
sys.path.append(root_path)
import pandas as pd
im... |
2379ae89d146a83c8204092806ef9ad46b382b7abc3bf7c3c30cee1679a21e36 | Jupyter | 7,500 | 307 | # %%
%load_ext blackcellmagic
# %% [markdown]
# #### Imports and setup
# %%
import numpy as np
import pandas as pd
import pickle
import matplotlib.pyplot as plt
import seaborn as sns
from pathlib import Path
from scipy.stats import ttest_rel
# %%
from spacestream.core.constants import SUBJECTS, CORE_ROI_NAMES, ROI_... |
1ff9a1b69f430f3ffacafa32ad01b172d370f92dcd19a823e2a612875bd80473 | Jupyter | 7,526 | 230 | # %% [markdown]
# # Running CEBRA and saving results for MATLAB plotting
#
# This notebook fits CEBRA (time-only contrastive embedding) to the synaptic-current
# trials of a trained RNN, then saves the 3-D embeddings as a `.mat` file so they
# can be loaded and plotted in MATLAB. The setup below is configured for the
... |
2521a4ebde5c8c30014f1f15a11b66b3c2f8b58a8517c9c849162bb194faa080 | Jupyter | 7,528 | 233 | # %%
import numpy as np
import joblib
from sklearn.metrics.pairwise import cosine_similarity
from visualizations import get_colors, show_factorization_on_image
img = np.load("D:\\maldi\\0.npy")
H = np.load("0_h.npy")
W = np.load("0_w.npy")
img = img[:, :, 300 : ]
orig = img.copy()
model = joblib.load("kmeans.joblib")
... |
fba3babd007b540b5bf7874cabe5571c6af061b4d301f0ec2ce5867a5bcf5e3f | Jupyter | 7,549 | 194 | # %% [markdown]
# # Tutorial: Concept Activation Maps
# ## Adapting pixel attribution methods for embedding outputs from models
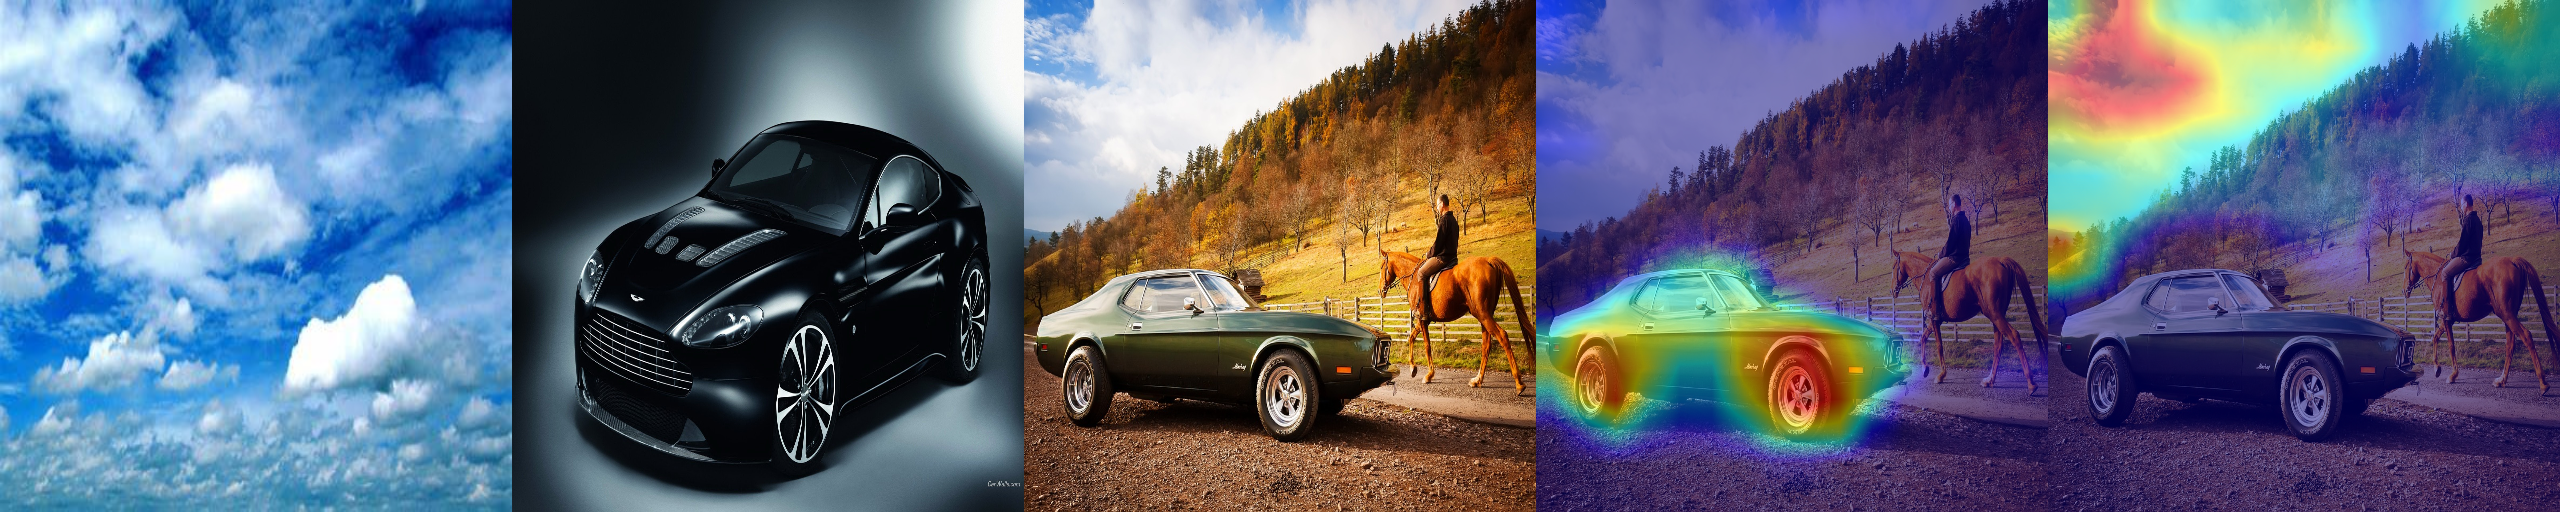
# 
#
#
# In some cases deep learning models output a feature vector, ... |
dededb3215a427022113d82f9c3793d63695fdc27709210a2d87d93545ed123c | Jupyter | 7,567 | 209 | # %%
import json
import os
import sys
from dataclasses import dataclass
from datetime import datetime
import numpy as np
import pandas as pd
from scipy.stats import spearmanr
import torch
sys.path.insert(1,'../../')
from dglgcn import compute_threshold_from_split
sys.path.insert(1, '/path/to/application/app/folder'... |
a91144a0dd21fc8b89b92126f777031d51a265b5c624e917a2fbcf57b12c05fb | Jupyter | 7,572 | 214 | # %% [markdown]
# ## Model selection
#
# In this script JAGS output for HLM sequential model containing four competing submodels is analyzed. Specifically posterior samples for model indicator variable $z_i$ are used to perform model selection. Model selection can be quantified with Bayes factors and protected exceeda... |
b15b86f4df3b1f60c78f07bf125a9447d90d8294d181b9677e27ee61dc1ffe8f | Jupyter | 7,613 | 228 | # %% [markdown]
# <a href="https://colab.research.google.com/github/InfectionMedicineProteomics/BINN/blob/main/colab/BINN_colab.ipynb" target="_parent"><img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/></a>
# %% [markdown]
# <img src="https://raw.githubusercontent.com/InfectionMe... |
f376cdb840197b3dc2cf092810b21b1c39da4d454609bf5a794ea0356d72b3e0 | Jupyter | 7,646 | 242 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
from typing import Dict
import warnings
warnings.filterwarnings('ignore')
from tqdm import tqdm
import matplotlib.pyplot as plt
import scanpy as sc
import numpy as np
import pandas as pd
import torch
from torch.utils.data import Dataset, ... |
3a1055b1f4d91616ed80eda459b2e755d338d409a72db793db95e8f569c9dbe7 | Jupyter | 7,666 | 342 | # %% [markdown]
# # Load & Parse Data
# %%
from utils.parse_data import parse_dataset
from pathlib import Path
M, H = 50, 3
data_path = Path('./data/train_pooled_stratified_share_vc')
X_train, Y_train, X_test, Y_test, device = parse_dataset(root_dir=data_path, M=M, H=H, normalize=True, stride=1, test_ratio=0.2,
... |
42eb1ee2f53f6666abaec5f9b13df78f2513d4f41a9417d76ac20a3b34bf7ebb | Jupyter | 7,717 | 206 | # %% [markdown]
# # Simulating Data From Bayesian Networks
#
# pgmpy implements the `DiscreteBayesianNetwork.simulate` method to allow users to simulate data from a fully defined Bayesian Network under various conditions. These conditions can be any combination of:
# 1. Virtual Evidence
# 2. Hard Evidence
# 3. Virtual... |
d9c545659f6c6d334fd8f5eac5c8ebf7631d8b0196ee7ba6f7edef257939c4e6 | Jupyter | 7,739 | 230 | # %% [markdown]
# ### Install libraries
# <font color='red'>**Make sure to restart the Colab runtime after installation**</font>
#
# Colab Menu -> Runtime -> Restart runtime
# %%
!pip install open_clip_torch==2.23.0 transformers==4.35.2 matplotlib
# %% [markdown]
# ## Load BiomedCLIP model
# %%
from open_clip impor... |
aa19cf959d79dd2ac4f6a93740617cdba739005665731531740e8463bdbd1a0a | Jupyter | 7,824 | 238 | # %%
##### Fig. 3 - Phonemic and prosodic representations in ventral and dorsal stream regions
#
# written by S-C. Baek
# updated date: 16.12.2024
#
# %%
# import packages
import os
import sys
import pickle
import numpy as np
from mne.stats.multi_comp import fdr_correction
import matplotlib
import matplotlib.pyplot... |
2f5853ff0c3be1bfa08d7ab7173e4652eb98c8a1452a06f53b184fd29e141e71 | Jupyter | 7,887 | 214 | # %% [markdown]
# # Embedding Novel Species
#
# This notebook will create the files you need to embed a novel species that wasn't included in the training data.
#
# To start, you will need to download the ESM2 protein embeddings and the reference proteome for the species.
#
# You can find precalculated ESM2 protein ... |
7e69454648a3223b741218cd25360cc7e253f029a10756987347cece904977e9 | Jupyter | 7,897 | 210 | # %%
import numpy as np
import matplotlib.pyplot as plt
import scipy.stats as sstats
import os
# %%
results_dir = "/mnt/c/Users/Алексей/OneDrive/projects/uio/cmma/tests/experiment_8"
outf = "qq.Intelligence_SCZ_BIP_Height_IBD_T2D.png"
save = False
fig_title = "IIBDGC CD 2017" # "HapGen p=0.003 hsq=0.7"
# ctg_intellige... |
c7e6fbe3ad8897d15a1f47cfa66e28cbfa87791a547e389c95b6d38cc8f41d1b | Jupyter | 8,043 | 232 | # %%
##### Fig. 5 - Acoustic and categorical representations for phonemes and prosody in ventral and dorsal stream regions
#
# written by S-C. Baek
# updated date: 15.12.2024
#
# %%
# import packages
import os
import sys
import pickle
import numpy as np
from mne.stats.multi_comp import fdr_correction
import matplot... |
e62677726dc1830c2ee5980b345bae062c500af225f054ef6b3ba6c356f4a118 | Jupyter | 8,098 | 235 | # %%
import numpy as np
import random
import math
from scipy.stats import norm
from scipy.integrate import quad
from scipy.optimize import minimize, basinhopping
import matplotlib.pyplot as plt
# %%
def sample_z(n, annot, p, s2, s02, r2_het_ss):
z_sample = [random.gauss(0, math.sqrt(s02)) for _ in range(n)]
fo... |
d41c4d7ac5fa704522fcded0300007d6a6909df55487e360c9999f8ef20cbbcb | Jupyter | 8,109 | 197 | # %% [markdown]
# # Betaseries extraction
#
# This script combines calculated whole brain trial beta-maps with brain parcellation and extracts trial beta-series for predefined set of brain regions. This analysis step has to be conducted separately for each parcellation. `NiftiSpheresMasker` is used for signal extracti... |
0e81a6661c07a5ad61554a71f9ba628fb88a95f400e441ce433120721e3fc687 | Jupyter | 8,142 | 285 | # %%
from os.path import join as ospj
import pandas as pd
import numpy as np
import mne
from glob import glob
import os
from tqdm import tqdm
from fractions import Fraction
from scipy.signal import resample_poly
from scipy.signal import welch, lfilter
import pickle
from config import CONFIG
from utils import *
from m... |
23558d40285cf547651f4110f54e4797fe69c370fd55980f4ba02afc46737b2e | Jupyter | 8,158 | 255 | # %% [markdown]
# ## Figure 4
# %%
import sys
import os
os.environ["JAX_PLATFORMS"] = "cpu"
# Get the absolute path to the project root (one directory up from notebooks/)
root_path = os.path.abspath("..")
sys.path.append(root_path)
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from scipy.sp... |
c6792cc1b10ed9382d743222e30a69f0f30aa4304ee5f4232c2bfd52e538ff18 | Jupyter | 8,185 | 236 | # %%
import numpy as np
import os
import pandas as pd
from collections import defaultdict
from matplotlib import rc
import matplotlib.pyplot as plt
import itertools
# %%
# /mnt/c/Users/Алексей/OneDrive/projects/uio/cmma/tests/experiment_8
# /mnt/seagate10/projects/cmm/experiments/1000genomes503eur9m/results/experiment... |
3136e627495bf7d7aa703e210737906d86456980a2fe6473432296cc4cd18135 | Jupyter | 8,202 | 196 | # %% [markdown]
# # HIPPIE tutorial: train on your own data
#
# The companion notebook (`cross_dataset_tutorial.ipynb`) uses the **pretrained** checkpoint.
# This one trains a HIPPIE model **from scratch** on a single dataset in the canonical CSV
# layout, then embeds and evaluates it. It mirrors `scripts/train.py` st... |
7d87be8b31d5c400dbef166505133a19f2cf6f6ea0cb300e075b5442915dccd0 | Jupyter | 8,314 | 174 | # %%
'''
This script analyzes difference in green and blue channel responses.
Author: Jonathan Gant
Date: 01.06.2026
'''
import numpy as np
import matplotlib.pyplot as plt
import h5py
# Set random seed for reproducibility
np.random.seed(0)
# load in the data
all_gabor_responses = h5py.File('../results/new_nat_videos... |
149d3e33b1b077453054a464122113b287866eeb9a08ba53a149277d6613c1c0 | Jupyter | 8,315 | 248 | # %% [markdown]
# # Playground 2: Segmentation workflow for spotty structures
#
# This notebook contains the workflow for fibrillarin and beta catenin, and serves as a starting point for developing a classic segmentation workflow if your data shows spotty appearance in each 2d frame.
#
# ----------------------------... |
93ca1a203ffb29253680883a059ba13c4098d26364a1d4d82b1b86fc276245bf | Jupyter | 8,315 | 250 | # %%
import pynapple as nap
import matplotlib.pyplot as plt
import numpy as np
import nemos as nmo
import scipy
from itertools import combinations
nap.nap_config.suppress_conversion_warnings = True
plt.style.use(nmo.styles.plot_style)
# %% [markdown]
# # Load data
# %%
b8 = ['3_V-097', '4_V-125', '8_V-082', '10_V-0... |
959bfa0e327762c5979bb1bb9cbcc89f73ca0f097ffe9c2e3e8b43637366c105 | Jupyter | 8,365 | 219 | # %% [markdown]
# # Playground: Segmentation workflow for centrosomes
#
# This notebook contains an optimized workflow for segmenting centrosome imaging data. It is based on the Allen Institute workflow for "dots-like" structures, including Centrin-2, Desmoplakin, and PMP34.
#
# Key steps of the workflows:
#
# * Mi... |
d441a1ba92636b1021f235c5f36bf68a7e1829ab8ee6e614a89574ec84952702 | Jupyter | 8,371 | 283 | # %%
%pylab inline
import scanpy as sc
import pandas as pd
import seaborn as sns
# %% [markdown]
# ### cd8t_b_mono_cell_embedding
# %%
hvgdf = pd.read_csv('./data/zheng68k_train_var.csv',index_col=0)
selected_gene = hvgdf.highly_variable.values
cell_geneemb = np.load('./data/cd8t_b_mono_geneemb_01B-resolution_single... |
27a3bf86d91ee6bd96233d57f129fb6490633f9b6c730d252221d496f51f6be4 | Jupyter | 8,381 | 294 | # %% [markdown]
# # RDR2 Case Study
# %% [markdown]
# ## Defining Visualisation Tools
# %%
import pandas as pd
# Residue to prototype mapping
def add_residue_to_prototype_mapping(segment_assignments, prototype_assignments):
pdb_id_segment_to_prototype = {}
for _, row in prototype_assignments.iterrows()... |
db676de5336c31dd340d0d831f1902af8fd2d7f82aee9490ca0abb4711c1e928 | Jupyter | 8,405 | 230 | # %% [markdown]
# # Playground 7: Segmentation workflow for Connexin-43
#
# This notebook contains the workflow for connexin-43, and serves as a starting point for developing a classic segmentation workflow if your data shows similar morphology as connexin-43.
#
# ----------------------------------------
#
# Cell S... |
526f2c7f5ce4c09324aee7cc2f4d064b0be6dce7320b65ef422e4dda4fbf1d9e | Jupyter | 8,418 | 288 | # %%
import diffxpy.api as de
import loompy
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import numpy_groupies as npg
import scipy.cluster.hierarchy as hc
from scipy.spatial.distance import pdist
import seaborn
import matplotlib as mpl
import gget
# suppress INFO
import logging
logger = loggi... |
f1930d5589921d3b7969ca7f816d81232972fc242bde7f533185fe6570443eab | Jupyter | 8,422 | 221 | # %% [markdown]
# # Reference Mapping Using cell embedding by pretrained scGPT model
#
# In this tutorial, we demonstrate how to use the scGPT model to embed cells and map them to referenced embeddings. Then the meta labels of the reference cells, such as cell type or disease conditions, can be propagated to the query... |
d1e7e063022053e4ab28de1f0405bdbd69d7c3a81c97c96690932b3388b1dc66 | Jupyter | 8,444 | 249 | # %%
import os
import pandas as pd
import numpy as np
import requests
import json
import logging
import time
from typing import List, Dict, Any, Optional
from enum import Enum
from dataclasses import dataclass
from sklearn.metrics import cohen_kappa_score, confusion_matrix
# Define the output directory
output_dir =... |
b0125f1d6b6b416620cf0d1f0c09f1fcb5afc4732528537d25ffacead0728737 | Jupyter | 8,472 | 207 | # %% [markdown]
# # 【使い方】
#
# ランタイム>すべてのセルを実行(**Ctrl+F9**)によりすべてのセルを実行し、セル[2]の最後に生成された**URL(Running on public URL)をクリック**して開いてください。(GUIが新しいタブで開かれる)
#
# ※このcolabの画面(タブ)は閉じないでください。
#
#
#
#
# # [How to use]
#
# Run all cells by selecting Runtime > Run all cells (**Ctrl+F9**), and **click the URL generated at the en... |
2326d744d5aabf9b1698b157a373ee66fb43281a5e8e9b0ca8b1714a58f4bfac | Jupyter | 8,495 | 264 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
from typing import Dict
import warnings
warnings.filterwarnings('ignore')
from tqdm import tqdm
import matplotlib.pyplot as plt
import scanpy as sc
import numpy as np
import pandas as pd
import torch
from torch.utils.data import Dataset, ... |
da1562f5820f01a9976589bc8b33fa626162d97094281cbef78d7f8d20c08e68 | Jupyter | 8,501 | 224 | # %%
import pandas as pd
import matplotlib.pyplot as plt
import numpy as np
from collections import namedtuple
# %%
fname = "/mnt/c/Users/Алексей/Documents/MEGAsync/cmm_paper/data/e1/e1.merged.15runs.csv"
df = pd.read_csv(fname)
#for each combination of "i_h2","i_p_c","i_p_nc","i_s2","i_repeat" take the run with the ... |
908c6f381fc2e39994536b87f5bd4ec032bab5d379fa375eb3d675706fc0fc25 | Jupyter | 8,510 | 260 | # %% [markdown]
# # Swim direction over trial
#
# Analyse and plot swim direction over the course of each trial.
# %%
import os
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from scipy.stats import ks_2samp
from cichlid_omr.config import data_dir, load_config, output_dir
# %matplotlib widge... |
2341b8e85d206030a0a1fc838f3dc9e1e4d97f9fa4b029e4954f6087db9c8dc2 | Jupyter | 8,539 | 317 | # %%
import matplotlib.gridspec
import matplotlib.colors as mcolors
import matplotlib.pyplot as plt
import matplotlib.cm as cm
import matplotlib as mpl
import seaborn as sns
from mpl_toolkits.axes_grid1 import make_axes_locatable
import numpy as np
import scipy.io
import sys
import os
path_root = os.environ.get('DEC... |
837c3df15d941b30c334ccb27c97b9a5362e16a991b2c5089f4518e4658cea12 | Jupyter | 8,567 | 248 | # %%
import matplotlib.pyplot as plt
import numpy as np
import json
import sys
sys.path.append('/home/kmb/Desktop/Neuroscience/Projects/BONNA_decide_net/code')
from dn_utils.behavioral_models_REF import *
# %% [markdown]
# ### Behavioral modelling
#
# #### Assumptions:
#
# 1. experienced utility is some function of... |
b7509867fbd9a57fc43a3b607c2eb7c190f1c715fff8ff7dd7c2abde30bb586a | Jupyter | 8,570 | 303 | # %%
import numpy as np
import pyscf
import py3Dmol
import pandas as pd
import matplotlib.pyplot as plt
# %%
from oneqmc.analysis.visual import show_mol
from oneqmc.convert_geo import load_molecules
from oneqmc.analysis.plot import set_defaults
from oneqmc.analysis import HARTREE_TO_KCAL, colours
set_defaults()
# %... |
e06f573155fbb7ac12cd482ee5831c9a8b29368863e8f56688e419e25deb486f | Jupyter | 8,618 | 317 | # %%
import scanpy as sc
from scprint import scPrint
from scprint.tasks import Embedder
from scdataloader import Preprocessor
from scdataloader.utils import load_genes, translate
import numpy as np
import pandas as pd
from sklearn.linear_model import LogisticRegression
from sklearn.ensemble import GradientBoostingC... |
d97f1f40f24a9015b9fd32b970a146fd11333c27b934748bbccbc3af26467460 | Jupyter | 8,628 | 248 | # %%
import numpy as np
from dataclasses import dataclass
from datetime import datetime
import json
import os
import sys
sys.path.insert(1, '/path/to/application/app/folder')
time_now = datetime.today().ctime()
today_date = datetime.today().date()
# packages for plotting
import matplotlib.pyplot as plt
import matplotl... |
84e05827d44b856daa08bd38485ca97d4814cf6d5889d0a4a0b44eb1e0fde2fb | Jupyter | 8,672 | 228 | # %% [markdown]
# # Annotated XML files to plain text
#
# This tutorial aims to explain how to translate from annotated XML files obtained from [Whatizit](https://github.com/zbmed-semtec/whatizit-dictionary-ner) to plain text. The translation converts the tagged concepts by the dictionary to its corresponding MeSH ID.... |
149d773ab3a3c38f8f8fcbabd66153f234a2339a4d768e16748a1f78d81a7157 | Jupyter | 8,694 | 221 | # %%
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import scipy.stats as stats
import seaborn as sns
from sklearn import preprocessing
import random
import tensorflow as tf
import keras
np.random.seed(1337)
from keras.preprocessing import sequence
from tensorflow.keras.optimizers import Adam
... |
04d7a5353ff674514c0cbc9a17ffbf309cfe48d8db56666f75715d3bdfdea368 | Jupyter | 8,698 | 247 | # %% [markdown]
# # Playground 4: Segmentation workflows for curvi-linear structures
#
# This notebook contains the workflows for Sec61 beta, Tom20 and lamin B1 (mitosis-specific), and serves as a starting point for developing a classic segmentation workflow for your data with curvilinear shapes.
#
# ---------------... |
c949b8115b617f22337f13af01b77cce47afc1e9f896e869961bc8e3de4b7334 | Jupyter | 8,748 | 240 | # %%
import torch
import os
import numpy as np
import matplotlib.pyplot as plt
from libs.networks import SirenNet
from libs.losses import NCCLoss, LNCCLoss, JacobianLossCoords
from libs.data import load_mindboggle, make_coords_tensor, fast_trilinear_interpolation, MetricMonitor, VectorCoords, BlockCoords
# %% [markd... |
c80253650ab75867499bf3da9bc9df6e652831c21781a9bcbe869ff214a101b5 | Jupyter | 8,843 | 207 | # %% [markdown]
# # Betamaps GLM
#
# Here, beta maps for individual trials are calculated for all subjects and both task conditions. For each trial separate GLM model is created with regressors:
# - `out_individual`: modelling sigle trial
# - `out_perr_pos`: modelling remaining trials with positive PE
# - `out_perr_... |
b7ba99ea0aa0182eaeea8f5aef6977e54996783ff0aa09e9948e81d494e7e5db | Jupyter | 8,882 | 199 | # %% [markdown]
# This runs DeepExplainer with the model trained on simualted genomic data from the DeepLIFT repo (https://github.com/kundajelab/deeplift/blob/master/examples/genomics/genomics_simulation.ipynb), using a dynamic reference (i.e. the reference varies depending on the input sequence; in this case, the refe... |
939d242685595740b7da1238b18ee539048f1af16a4f694f8692536f9aa04bc6 | Jupyter | 8,901 | 261 | # %% [markdown]
# # gmx_MMPBSA API analysis with seaborn
#
# This local Jupyter notebook loads a `gmx_MMPBSA` result with the Python API, extracts energy data as pandas objects, and plots the results with seaborn. It defaults to the bundled API example result, but you can point `RESULT_FILE` to any `COMPACT_MMXSA_RESU... |
d11424c2f278b69903836a5f5e53e6026a1f9a2427e68bb0b09ccb9d19a8eb6f | Jupyter | 8,919 | 208 | # %% [markdown]
# # Census income classification with XGBoost
#
# This notebook demonstrates how to use XGBoost to predict the probability of an individual making over $50K a year in annual income. It uses the standard UCI Adult income dataset. To download a copy of this notebook visit [github](https://github.com/slun... |
150b5469d6273d6597f6da25f7ea3c67d21a73602a38521c64c0d6049bcfcd3b | Jupyter | 8,944 | 302 | # %%
%load_ext blackcellmagic
# %% [markdown]
# #### Imports and setup
# %%
import os
import numpy as np
import pandas as pd
import deepdish as dd
import h5py
import pickle
import nibabel.freesurfer.mghformat as mgh
import matplotlib.pyplot as plt
import seaborn as sns
# %%
from spacestream.core.constants import SUB... |
e79da58a1a143576c2b512c531b1e93a602f61d79f180e2fd55196386aedf835 | Jupyter | 8,963 | 255 | # %% [markdown]
#
# # Functional Bayesian Networks
#
# Functional Bayesian Networks (FBNs) are Bayesian networks where each CPD is a Python function that returns a Pyro distribution. This lets you model arbitrary discrete, continuous, or mixed relationships, while keeping standard graph semantics for sampling, interv... |
6304f6149a896cebc01d681c89b4d3e722a8b566053c6dbefce2cf2b16029d22 | Jupyter | 8,975 | 240 | # %% [markdown]
# # Playground 4: Segmentation workflows for curvi-linear structures
#
# This notebook contains the workflows for Sec61 beta, Tom20 and lamin B1 (mitosis-specific), and serves as a starting point for developing a classic segmentation workflow for your data with curvilinear shapes.
#
# ---------------... |
f642aed3fc88f16d2a16219da903f323b8efcd5573ee015df2c093fc05b545c3 | Jupyter | 8,983 | 286 | # %% [markdown]
# # Zero-shot integration tutorial with scGPT
# %% [markdown]
# ## Introduction
#
# This tutorial covers the zero-shot integration with continual pre-trained scGPT. This particular workflow works for scRNA-seq datasets without fine-tuning (or any extensive training) of scGPT.
#
# Continual pre-traine... |
39a5981ba71b3a02092a3c7484109ccbd8b8068298eef256589be6446e65d469 | Jupyter | 9,019 | 306 | # %%
import sys
import os
sys.path.append("engine/")
sys.path.append("funcs/")
sys.setrecursionlimit(10000)
import theano.gpuarray
theano.gpuarray.use('cuda0')
import theano
import theano.tensor as T
from theano import config
import numpy as np
import pickle
import copy
import time
from itertools import *
from matpl... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.