
sha256 stringlengths 64 64 | language stringclasses 28
values | size int32 1 491k | lines int32 1 23.2k | content stringlengths 1 200k |
|---|---|---|---|---|
f35b5b98942f29e8403fc2fcb3664cd8701558b9130c9785fb654095f595eac7 | Jupyter | 19,920 | 617 | # %% [markdown]
# # Model Comparison
# %% [markdown]
# In this section, we will compare BELT-lite with EEGNET. In order to make the models comparable, we use a lighter version of BELT-lite here which gives us a number of parameteres in the range of EEGNET's.
# %% [markdown]
# ## Classification Performance
# %% [mark... |
5afe6df5dd6c1d30bdda0ad96c5f53bcc472289a96b57743fb93d8264fbf7f21 | Jupyter | 19,941 | 654 | # %%
import numpy as np
import matplotlib.pyplot as plt
import pandas as pd
import os
import seaborn as sns
import matplotlib.pyplot as plt
from scipy.ndimage import uniform_filter1d
from scipy.ndimage import gaussian_filter1d
import warnings
from scipy.spatial import cKDTree
warnings.filterwarnings('ignore')
# Impor... |
4906ac776d4fa6c0dbc03d14fa49272214db333f9f4f5d8714ce5f88c5d9f971 | Jupyter | 20,005 | 511 | # %% [markdown]
# # CrossSim: a hardware/software co-design tool for analog in-memory computing
#
# ### Tutorial for CrossSim v3.0
#
# www.cross-sim.sandia.gov/ <br>
# www.github.com/sandialabs/cross-sim
#
# ## Outline
#
# - Part 0: What is CrossSim?
# - Part 1: The AnalogCore interface
# - Part 2: Physical models ... |
af91be07b2719ffd6772105482df608481e7ebbb6eb02151907bb56b66f820f7 | Jupyter | 20,005 | 468 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
from typing import Dict
import warnings
warnings.filterwarnings('ignore')
import copy
from tqdm import tqdm
import random
import scanpy as sc
import numpy as np
import pandas as pd
import torch
from torch.utils.data import Dataset, DataLo... |
f5d63370f77463abfa3131964d41f84580a678d4683cda4c0416fb4e95243493 | Jupyter | 20,069 | 504 | # %% [markdown]
# ### Data Preparation
# %%
import gc
import os
import warnings
from copy import deepcopy
import anndata as ad
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import scanpy as sc
import scipy.sparse as sp
import seaborn as sns
import squidpy as sq
# import tiledb
# import tiledb... |
f0a5f2a5e64f7a64af59f89898cf7cad71d9f1327eb3bcc05407c689ac3267cb | Jupyter | 20,075 | 580 | # %%
import numpy as np
from matplotlib import pyplot as plt
import matplotlib as mpl
import scipy.signal as signal
import pandas as pd
import glob
import seaborn as sns
import scipy.ndimage as filters#changed from scipy.ndimage.filters as the namespace was deprecated 05/24/2023
import pickle
import scipy.stats as stat... |
922157f17943b6405a7e7a428a5c3dd6c37b6db58970688b4053045864ee1eb0 | Jupyter | 20,110 | 572 | # %%
import numpy as np
import pandas as pd
pd.set_option('display.max_rows', 500)
pd.set_option('display.max_columns', 500)
pd.set_option('display.width', 1000)
from sklearn.datasets import load_digits
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler
import matplo... |
eb3405926fea455683cc22108c0284b06cb24b63f99bd6c6771a8b2416dcbf1c | Jupyter | 20,160 | 500 | # %% [markdown]
# # Build Parcel Adjacency Matrices from Wang432 Volumetric Atlases
#
# This notebook builds spatial adjacency matrices for each age's Wang432 parcellation, ready for use in TFCE-based analysis. The pipeline:
#
# 1. Load the per-age registered Wang432 NIfTI (the same file the MATLAB pipeline reads as ... |
ea65a20a96b6dce17985a10ba6a146bb97dcc92345f349a1220986989a9da33f | Jupyter | 20,566 | 362 | # %% [markdown]
# # Tutorial for mapping data with Tangram
# by Tommaso Biancalani <biancalt@gene.com> and Ziqing Lu <luz21@gene.com>
#
# - The notebook introduces to mapping single cell data on spatial data using the Tangram method.
# - The notebook uses data from mouse brain cortex (different than those adopted in ... |
03bd01eb1f3be52603667d61a28675cee9e40d7136b99d51dfdae778dd640c33 | Jupyter | 20,574 | 563 | # %% [markdown]
# # Fine-tuning on Pre-trained Model for Multiomic Integration
# In this tutorial, we demonstrate how to fine-tune a pre-trained model for multiomic integration. We use the BMMC dataset as an example for RNA and protein abundance data integration from CITE-seq. The BMMC dataset consists of multiple batc... |
00ec7f0b200503754a35f8e0261bc924b663b2853e6608ba403465455140fc7b | Jupyter | 20,706 | 545 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
import warnings
warnings.filterwarnings('ignore')
import pickle
import time
import copy
from tqdm import tqdm
import numpy as np
import pandas as pd
import random
from sklearn.model_selection import StratifiedKFold
from sklearn.metrics im... |
08105eacba4d450de70bddf7d8f2e4d263bb338bc749a5353f494bf87676c49e | Jupyter | 20,869 | 587 | # %%
import numpy as np
# packages for plotting
import matplotlib.pyplot as plt
import matplotlib.font_manager as font_manager
import urllib.request
urllib.request.urlretrieve('https://github.com/google/fonts/raw/main/ofl/ibmplexmono/IBMPlexMono-Regular.ttf', 'IBMPlexMono-Regular.ttf')
fe = font_manager.FontEntry(
... |
b9e70373eefc776932ff875d37566cbfebfbdd009ba45d1403c13baeea832ec2 | Jupyter | 20,894 | 683 | # %%
import numpy as np
import pandas as pd
import scipy
from scipy.io import mmread
from scipy.sparse import load_npz, save_npz, coo_matrix, csr_matrix, vstack
from scipy.ndimage import gaussian_filter1d
from scipy.stats import binned_statistic
from scipy.cluster.hierarchy import linkage, fcluster, dendrogram
import m... |
eee80b27552b0830aaafbb52d7a7881c25bcf06394748c9a51be4ecba7035be6 | Jupyter | 21,080 | 435 | # %% [markdown]
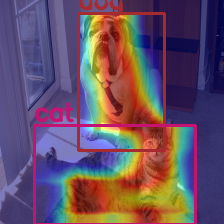
# # Tutorial: Class Activation Maps for Object Detection with Faster RCNN
#
# 
#
# In this tutorial we're going to see how to apply CAM methods for Object Detection,
# using faster-rcnn from to... |
5d6121acfbf901aace483a59a516c0efdb77fa5979a64af6c821ad85a73cbb6e | Jupyter | 21,159 | 539 | # %% [markdown]
# # Process trial data — standard OMR
#
# Segment `raw_data.json` into per-trial, per-fish records (`trial_data.json`) and split included/excluded trials.
# %%
import os
import shutil
import numpy as np
import pandas as pd
from cichlid_omr.config import data_dir, load_config, output_dir
from cichlid_... |
74bc2fca37cdd74c3923069793a2c92435aa631cae4a54c1609a7b944fb28c4b | Jupyter | 21,263 | 636 | # %% [markdown]
# # Load packages
# %%
# Import packages
from neuromaps import transforms, nulls, datasets, plotting, images, resampling, stats, parcellate; # import neuromaps and its submodules
from neuromaps.datasets import fetch_fsaverage, fetch_fslr;
from surfplot import Plot; # this package will be used to plot t... |
370a5d3e9ed8fd5b58886b36459fca56f5db96c3ac0c4baeb309fa52e42ff515 | Jupyter | 21,294 | 497 | # %% [markdown]
# # <b><font color='#FF2B00'>THIS NOTEBOOK HAS GONE OLD AND NON-FUNCTIONAL</font></b>
# Colab no longer supports the dependencies of RaSP and there is currently no solution in the pipeline. Please make a local install to use RaSP.
# %% [markdown]
# # <b><font color='#009e74'>Rapid protein stability pre... |
1825b51a82ca467878ee3639c6ff5949d5ee17ea4fb77a48c6d8b2b413fbc5a0 | Jupyter | 21,347 | 549 | # %%
import json
import os
import re
import sys
from dataclasses import dataclass
from datetime import datetime
import cairosvg
import numpy as np
import pandas as pd
import skunk
import torch
from matplotlib.offsetbox import AnnotationBbox
from scipy.stats import spearmanr, wilcoxon
sys.path.insert(1, '/path/to/app... |
46008d00d5cd59bfd7dc0f0febf4dac00fd19df86487157bd42f861888645237 | Jupyter | 21,352 | 586 | # %% [markdown]
# This notebook generates Figures 1-3 from the manuscript `Asgeir Kobro-Flatmoen, Jagir R. Hussan, Peter J. Hunter, Stig W. Omholt, "High reelin expression can explain why the entorhinal cortex is a cradle for Alzheimer’s disease", [doi: https://doi.org/10.1101/2025.06.04.655278]`. Readers should consul... |
6aac4003c3af85302ee516237a8642c29eae7fdf3f82e4e4e085dce2bb8586e1 | Jupyter | 21,406 | 520 | # %% [markdown]
# # Import and Augment David's Data
# The fly trajectory data from David's experiments lacks the necessary fields used in our estimator. In addition, the coordinate frame is the mirror-image of the coordinate frame we trained our estimator on, so this must also be taken into account. These problems, as ... |
b18019a5c2dfef5ab5c36859d33f02fca378a255aabc7d57e99739283e69b884 | Jupyter | 21,562 | 572 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
from typing import Dict
import time
import warnings
warnings.filterwarnings('ignore')
import copy
import pickle
from tqdm import tqdm
import scanpy as sc
import numpy as np
import pandas as pd
from sklearn.model_selection import Stratifie... |
ed2cbcbe0aecb77caa303013ff5573b6c3697dca9bd6d04e2eee7463528d5dd8 | Jupyter | 21,649 | 349 | # %% [markdown]
# # pRFtime: a python toolbox for spatiotemporal forward modeling of brain signals
#
# This notebook walks you through the full pipelie of the **pRFtime** framework - a biologically-inspired forward model for mapping spatio-temporal brain responses, using population receptive fields (pRFs).
#
# This... |
ee83deb8ad7f5eb732bc79085e532c51f6194830863fb0291a8f9697c6299d5d | Jupyter | 21,665 | 449 | # %% [markdown]
# ---
#
# <span style="font-size:24px"> <b> Deep learning to automate parameter extraction and model fitting of two-dimensional transistors: a jupyter notebook tutorial </b> </span>
#
# ---
#
# This notebook will walk you through the approach we use in our paper, "Deep Learning to Automate Parameter ... |
3abf0849e94d16608073388ae5a90df55d85cbba8c5585459cef5d3703443296 | Jupyter | 21,714 | 551 | # %% [markdown]
# ## 1. Importing Necessary Libraries
# This initial cell imports all the required Python libraries for the script. This includes os for file system operations, scipy for loading data from MATLAB's .mat files, matplotlib for plotting, numpy for numerical operations, and several key components from the p... |
5d35735f37f94116b62d702f937353b3b0f9626b225f16de6d29e8d731f40234 | Jupyter | 21,769 | 572 | # %%
import os
import numpy as np
import matplotlib.pyplot as plt
import pandas as pd
from skimage.transform import resize
from tqdm import tqdm
from scipy.ndimage import gaussian_filter1d
import warnings
from scipy import stats
import alphashape
import cmcrameri.cm as cmc
from scipy.ndimage import uniform_filter
fro... |
ebeca22d7bfbe615ab761b7f967201a668d9e04177eb6790e12b07bd6da15512 | Jupyter | 21,784 | 650 | # %% [markdown]
# # Random bar widths — population summaries
#
# Cross-fish population summaries built from the random-bar-width pipeline output (`cichlid_omr.random_bar_width`).
# %%
import os
import matplotlib.pyplot as plt
import numpy as np
from cichlid_omr import random_bar_width as rbw
from cichlid_omr.config... |
5d4da83d5ae920c795168f13ad05bc711f56e62b50e2409c83b616777ef77332 | Jupyter | 22,318 | 567 | # %%
'''
This script visualizes the outputs of the Gabor filters applied to the natural videos.
Author: Jonathan Gant
Date: 05.05.2025
'''
import numpy as np
import matplotlib.pyplot as plt
from tqdm import tqdm
import h5py
import os
import bottleneck as bn
# Set random seed for reproducibility
np.random.seed(0)
# %... |
b5df8acc8bbe9f96d84d2e193cdc6b945a4bb493dbde542b2617c5c06b859253 | Jupyter | 22,515 | 672 | # %%
import json
# Create histogram of plaque areas
from skimage.measure import label, regionprops
import matplotlib.pyplot as plt
import numpy as np
%matplotlib inline
from msi_visual.supervised.annotations import get_img, get_visualization, get_dataset
paths = [(r"D:\maldi\slides\slide2_notol_5_bin\0.npy", 1),
... |
f6974c0f36dbaea461ab8c765783488dc69d4440c87b9f2ceb84e654c86e2f1f | Jupyter | 22,529 | 709 | # %% [markdown]
# # Paired multi-model analysis of scRNA-seq and scProtein-seq data
# %% [markdown]
# ## 2_GSE128639 dataset
# %%
import os
os.chdir('/data2/zhouwg_data/project/Garfield')
os.getcwd()
# %%
# load packages
import os
import warnings
import Garfield as gf
import scanpy as sc
from mudata import MuData
wa... |
0e647880d1d04fadda0035170a32d580b95bb2dd3e325d7c50559f20cedc6136 | Jupyter | 22,646 | 384 | # %% [markdown]
# In this notebook, I'll demonstrate how to use the genetic algorithm (GA) tool in BPReveal.
# Before plunging into the code, I'll briefly describe what a GA is, and then we'll consider a biological problem
# where a GA could be appropriate.
# %% [markdown]
# # What is a GA?
# Let's say you have some... |
562083014e5f0a3f5b4daaea9950210f47ab6a52eb76374088ebe1dabc22fb1a | Jupyter | 22,674 | 567 | # %% [markdown]
# # BBMEP create figure notebook
# %%
import matplotlib.pyplot as plt
from matplotlib import rcParams
import numpy as np
import pandas as pd
from matplotlib.offsetbox import OffsetImage, AnnotationBbox
import matplotlib.image as mpimg
from scipy.ndimage import rotate
from matplotlib.ticker import NullL... |
e96a8566056a5c968b1a1a624122f1013fae2dd337515f70cfdbb52c70020107 | Jupyter | 22,733 | 681 | # %%
# Import modules
%matplotlib notebook
from tensorflow import keras
from graph_model import CallBacks, DataGenerator, GraphNet
import numpy as np
from scipy.interpolate import Rbf
from scipy.stats import gaussian_kde
import matplotlib.pyplot as plt
import matplotlib.gridspec as gridspec
import cartopy, shapely
... |
8a3ed82114d98a5d58ce1557cd65849538691a713d0ee3f0b6aced363ecda764 | Jupyter | 22,895 | 615 | # %% [markdown]
# ## 1. Importing Necessary Libraries
# This initial cell imports all the required Python libraries for the script. This includes os for file system operations, scipy for loading data from MATLAB's .mat files, matplotlib for plotting, numpy for numerical operations, and several key components from the p... |
1cbc518ca6a76e730973e1c9ebe2bda5f02560e7636536b9928c84a7a7b4f4f3 | Jupyter | 22,924 | 649 | # %%
%matplotlib inline
%reset
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import scikit_posthocs as sp
import seaborn as sns
import statsmodels.api as sm
import statsmodels.formula.api as smf
import statsmodels.stats.multitest as smm
from scipy import stats
from scipy.integrate import simp... |
2f6a0391118a6a000af1d993c517af76bba8f8dbfaa3496f9d0de6d0c916167e | Jupyter | 22,929 | 680 | # %% [markdown]
# # CycFluoCoreg-STAR Coregistration Pipeline
#
# This notebook performs image stack coregistration using SimpleITK.
# The workflow consists of:
#
# 1. **Affine registration (linear)** to estimate global alignment
# 2. **B-spline registration (non-linear)** to refine local alignment
#
# This tw... |
6c9da6ef4ffa8a18574ae87972c0c5b66c3a1ee761dd1db830ecc299ec41d9f2 | Jupyter | 22,996 | 818 | # %% [markdown]
# # Swim gain (speed ratio)
#
# Speed-ratio / swim-gain analysis and figures from `trial_data.json`.
# %%
import os
import dataframe_image as dfi
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import pingouin as pg
from cichlid_omr.config import data_dir, load_config, output_... |
99daf1dc7c72142a9449770e2d0bbda8779783a3bad7e3e6c32622441207bde3 | Jupyter | 23,001 | 703 | # %%
%pylab inline
import pickle
# %%
import os
os.getpid()
# %%
from gears import PertData, GEARS
# %%
pert_data = PertData('/nfs_beijing/minsheng/scbig/bioinfoDownStream/gears_singlecell/data/')
# %%
from os.path import join as pjoin
pert_data.load(data_path = pjoin('/nfs_beijing/minsheng/scbig/bioinfoDownStream/... |
24c1b6ee4bbec8dda81a08827308dc4b614d90f79bb7f15d43f3e3e51df29b06 | Jupyter | 23,110 | 673 | # %%
%pylab inline
from sklearn.metrics import *
import pandas as pd
import sklearn.preprocessing as sk
import os
import sys
# %%
import scipy.stats as ss
import scanpy as sc
import seaborn as sns
import colorbm as cbm
import scipy.stats
import sklearn
sns.set_palette(sns.color_palette(cbm.pal('npg').as_hex))
# %%
rc... |
60c92fd2ea6fa885a067cc7ff8afc8c3ebb756ef5690c94af4d5d9010b62a4d1 | Jupyter | 23,387 | 571 | # %%
# Install SOFA + dependencies
!pip install --quiet biosofa
# %% [markdown]
# The input tcga_gyn_data.h5mu needs to be download from zenodo: https://zenodo.org/records/14761127
# %%
import sofa
import torch
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from sklearn.decomposition import PC... |
6c3a91b90e181a6198b1e374aab875ec2f887623b1a5a898dbadf48437706137 | Jupyter | 23,663 | 594 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
from typing import Dict
import time
import warnings
warnings.filterwarnings('ignore')
import copy
import pickle
from tqdm import tqdm
import scanpy as sc
import numpy as np
import pandas as pd
import random
from sklearn.model_selection im... |
666c1f71a0070186375f8d7648d5d305783bc3c5ed5564c9de2e42747add1adf | Jupyter | 23,697 | 895 | # %% [markdown]
# # Plot figures 4 and 5 (SAL applied to spiking sampling networks)
#
# In this script, we plot of our spiking sampling network (SSN) experiment.
# A spiking sampling network is trained with STDP to sample from randomly selected Boltzmann distributions. To model the influence of different types of para... |
83005c496530ff061516cb6d31a227bba748128dbce13a3408d2de67cd1cd16c | Jupyter | 23,907 | 579 | # %% [markdown]
# # Allen NWB Session to CSV Converter (Using neurocurator)
#
# This notebook downloads a specific session from the Allen Institute NWB dataset using a session ID and converts it into a set of CSV files using the Neurocurator (neurocurator) processing pipeline.
#
# The notebook:
# - Downloads Allen In... |
c2345978927c33fe6b057cf9aae1d7112a27f38f00a6d32b0ee4639084673c0d | Jupyter | 23,933 | 433 | # %% [markdown]
# # *May the best explanation win*:
# # A tutorial on benchmarking and tuning model explanations
#
# Which metrics can we use to benchmark different pixel attribution techniques ?
#
# How can we measure if a model explanation is good or bad?
#
# What kind of problems do metrics for model explanatios... |
cc5273b46064733269f17001f68c3c1f6624aa1fd11a98d11778de1943eaa7e3 | Jupyter | 24,013 | 605 | # %% [markdown]
# # EEG Pain-Level Classification with XGBoost
#
# A full pipeline for classifying subjective pain levels from EEG data using Discrete Wavelet Transform (DWT) feature extraction and an XGBoost classifier.
#
# **Pipeline overview:**
# 1. [Environment Setup](#1-environment-setup)
# 2. [EEG Data Loading ... |
d673e5cffb5325480e2e048e78e8329675159d9740129c516d845b14be09aa63 | Jupyter | 24,074 | 617 | # %% [markdown]
# # EEG Pain-Level Classification with LightGBM
#
# A full pipeline for classifying subjective pain levels from EEG data using Discrete Wavelet Transform (DWT) feature extraction and a LightGBM classifier.
#
# **Pipeline overview:**
# 1. [Environment Setup](#1-environment-setup)
# 2. [EEG Data Loading... |
e547fcbcf8ce3c3f665b98878bcb303df9b65cb378afd0ccdb9efedd1efae2b3 | Jupyter | 24,086 | 817 | # %% [markdown]
# #1. 準備
# %%
import torch
import torch.nn as nn
import matplotlib.pyplot as plt
print("PyTorch:", torch.__version__)
print("CUDA :", torch.cuda.is_available())
if torch.cuda.is_available():
print("GPU name:", torch.cuda.get_device_name(0))
import os, sys, time, json, platform
import random
imp... |
5b03822c525cd3a9f89adf25a86dfc0d30c1e9481bc7cb60c0bf5e0cdc5d4407 | Jupyter | 24,092 | 456 | # %% [markdown]
# # Tutorial for spatial mapping using _Tangram_
# - by Ziqing Lu <luz21@gene.com> and Tommaso Biancalani <biancalt@gene.com>.
# - Last update: August 16th 2021
#
# ### What is _Tangram_?
# _Tangram_ is a method for mapping single-cell (or single-nucleus) gene expression data onto spatial gene expressi... |
d5a2421a1cf5adcff0825d467e358e7ebc3137a98a6fc24910effaf1608daeb6 | Jupyter | 24,116 | 647 | # %%
% matplotlib inline
import nibabel as nib
import nibabel.gifti
import nilearn
from nilearn import datasets, plotting
import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib as mpl
import matplotlib.pyplot as plt
from matplotlib.colors import ListedColormap
mpl.rcParams['svg.fonttype'] = '... |
4e0bc6e044bda8dce6c9a06788a810f4631d48ba95e2088438631e5a797518bf | Jupyter | 24,198 | 702 | # %% [markdown]
# # Ablation Experiments
# %%
import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib.pyplot as plt
import matplotlib.gridspec as gridspec
import warnings
warnings.filterwarnings('ignore')
sns.set_context("paper")
colors = sns.color_palette("muted", 10)
dpi = 600
# %%
# 评价指标函数
d... |
33ae0a76053cf9194f1a6ae2a6e0c246a7addb859ae94eaf451de9f8292c6d33 | Jupyter | 24,320 | 828 | # %% [markdown]
# # PyLossless pipeline: A step-by-step demonstration
#
# This Notebook details each pipeline step. First, the mathematical notation for the operation will be described. Second, the python code for the operation will be shown. We will go through the first step in details. Similar procedures are used in... |
83fb149be5c26d862b066b5b392857709ef87522ca8ae545f17c4ac91943b774 | Jupyter | 24,332 | 488 | # %%
import sys
sys.path.append('../')
# %%
pwd
# %%
cd ..
# %%
import torch
import json
import os
from importlib.machinery import SourceFileLoader
from matplotlib import pyplot as plt
from pado.light import *
from pado.optical_element import *
from pado.propagator import *
from utils.utils import *
from utils.D... |
4ae237e21fab05c1e447f43e16b876cacf5403f192a611b2973a6b00f5c9ebe2 | Jupyter | 24,442 | 663 | # %%
import numpy as np
import pandas as pd
pd.set_option('display.max_rows', 500)
pd.set_option('display.max_columns', 500)
pd.set_option('display.width', 1000)
from sklearn.datasets import load_digits
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler
import matplo... |
126ddf59b35a8f4c125effd5d672f8243ed66c859933c860928fab508a70d5da | Jupyter | 24,477 | 697 | # %% [markdown]
# # scPRINT use case on BPH
#
# In this use-case, also presented in Figure 5 of our
# [manuscript](https://www.biorxiv.org/content/10.1101/2024.07.29.605556v1), we
# perform an extensive analysis of a multi studies dataset of benign prostatic
# hyperplasia.
#
# Our biological question is to check if t... |
d1e070f8fe3e759037bb1560e754b13b82d74e7e4a3254438a053db599c11e84 | Jupyter | 24,749 | 715 | # %% [markdown]
# # Training phase
# %%
import TSA
import tools
PROJ_NAME = 'DualDataset'
TSA.setup_proj(PROJ_NAME, 'ab')
# %%
import keras as K
import tensorflow as tf
def create_prior_model(input_shape=(1000, 3)):
initial_model = K.models.Sequential(
[
K.layers.Input(shape=(input_s... |
89edd66905687b59b0abffe7c4b132c0cca2608dd4508de5fb94bb2bc44ab951 | Jupyter | 24,822 | 562 | # %%
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from sklearn import datasets
import skimage as ski
import os
from joblib import Parallel, delayed
import warnings
from matplotlib.colors import LinearSegmentedColormap,LogNorm
import matplotlib.ticker as ticker
from skimage import filters, expo... |
1063b6d98d77f9198b7d4bdabfa1abb0438931030b8a26cf9ef5c6ee9c014ecf | Jupyter | 24,904 | 610 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
17312ff694fb4bc3e57f5a1d738aeb20e61c675c1590d9a70ae6a708dd2a935d | Jupyter | 25,711 | 742 | # %%
import os
import numpy as np
import pandas as pd
pd.set_option('display.max_rows', 500)
pd.set_option('display.max_columns', 500)
pd.set_option('display.width', 1000)
from sklearn.datasets import load_digits
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler
from... |
b4ae96e986852934271d37dc13cfa827e6d149f66b06b45681901a952f44b8d7 | Jupyter | 25,761 | 680 | # %% [markdown]
# # Clinical Trail Research
#
# ## Clinical Trail Data Analysis - Richard Young
#
# ### ryoung@unlv.edu
# %%
# %% [markdown]
# ### Updated 2024-12-26
# %% [markdown]
# To review / Look at for ideas
#
# https://github.com/RyanWangZf/PyTrial
#
# https://stackoverflow.com/questions/78415818/how-to-... |
c8a0e5b1e0bc167c020407294ecf906fae693512165abb9901f683c4c8303cd5 | Jupyter | 26,020 | 702 | # %% [markdown]
# ## benchmarking on sushmita ROY's dataset
# %%
from scprint import scPrint
from scdataloader import Preprocessor
from scprint.tasks import GNInfer
from bengrn import BenGRN, get_sroy_gt, FILEDIR
import scanpy as sc
from bengrn.base import train_classifier
from anndata.utils import make_index_unique... |
3ea1d15a200c50b5f1c19011cad3c4c96ab5fee93caf56cef72165129b00d535 | Jupyter | 26,098 | 710 | # %%
import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib.pyplot as plt
import matplotlib.gridspec as gridspec
import warnings
warnings.filterwarnings('ignore')
dpi = 600
# %%
sns.set_context("paper")
colors1 = sns.color_palette("husl", 10)
colors2 = sns.color_palette("Paired", 10) # 用于两两分组颜... |
b61bdcbc694073735af6b2241d2f6755e49041febfc10932ae39dc6a91a3a008 | Jupyter | 26,196 | 655 | # %%
%load_ext autoreload
%autoreload 2
import sys
sys.path.append('../../utils/')
from DarioFunctions import *
pd.set_option('display.max_columns', None)
pd.set_option('display.max_rows', None)
scaler = StandardScaler()
nIter = 1
nprocess = 1
# %% [markdown]
# # Building homology graph
# %%
# Read in keys between ... |
ee3636c04cdd31dee8caca617198fb850a1db63180d392b54c43fece46727188 | Jupyter | 26,367 | 550 | # %% [markdown]
# # XAI Recipes for the HuggingFace 🤗 Image Classification Models
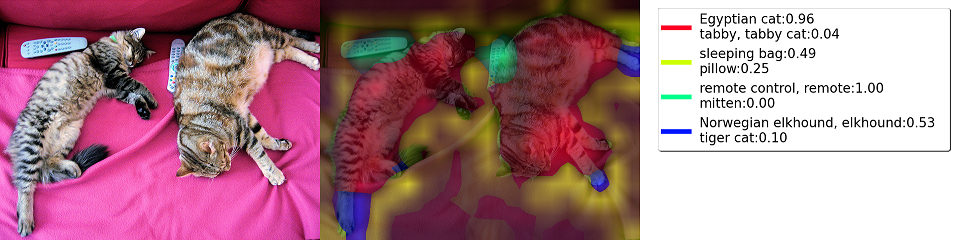
# 
# ## Goal
# In this tutorial we will go over all (or most of?) the vision classification model families in the HuggingFace collect... |
8dbcb07eb4db105048fb6fa779472a18c67cb9dada2b7011c8f546000e82ad8f | Jupyter | 26,578 | 605 | # %%
%matplotlib inline
import sys
sys.path.append("..")
import numpy as np
from simulator import AnalogCore
from simulator import CrossSimParameters
from applications.mvm_params import set_params
import scipy.linalg
import matplotlib.pyplot as plt
from PIL import Image
np.random.seed(198)
# %% [markdown]
# ## Part 2:... |
5ded6aa54b9ba1a314976bfaff9d243f48488dd99bdb65d2ab1142b8cad9afbe | Jupyter | 26,807 | 1,120 | # %%
import numpy as np
from scipy.interpolate import CubicSpline
import matplotlib as mpl
import matplotlib.font_manager as fm
import matplotlib.pyplot as plt
import matplotlib.image as mpimg
import matplotlib.gridspec as gridspec
import matplotlib.patches as patches
from matplotlib.offsetbox import OffsetImage, Ann... |
606f5ce458bdc90925d6e0af96c568c09c03b2eb5d52c2a786cc7b47bb9b7ecf | Jupyter | 27,161 | 602 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
ff549afbf8b7a736ed29b61d39612d9ae0a5ece94f98806973c8786271a924a3 | Jupyter | 27,326 | 690 | # %% [markdown]
# # Import and Augment David's Data
# The fly trajectory data from David's experiments lacks the necessary fields used in our estimator. In addition, the coordinate frame is the mirror-image of the coordinate frame we trained our estimator on, so this must also be taken into account. These problems, as ... |
79073f7bf064f5618c42da9f9994cf504d323cd9796075f97efcec6eeb3c98a9 | Jupyter | 27,470 | 556 | # %%
#################################################################
### NNUNET WSI INFERENCE WITH HALF OVERLAP
#################################################################
# nnUNet by default does half overlap if the given patch is bigger than the model's patch size.
# This means that on the borders there is no... |
554a70df694dd94c32bc8771dae77758e53fabb5e9b1c4a2aee6bc65596f23fa | Jupyter | 27,690 | 768 | # %% [markdown]
# # 🔬 Deep Learning-Enhanced Raman Microspectroscopy
#
# ---
#
# ## ✨ Welcome
#
# This notebook provides an interactive version of the Raman imaging pipeline described in [Georgiev et al., Science Advances, 2026](https://doi.org/10.1126/sciadv.aec5080).
#
# ⚡ **Purpose:** Extract chemical component... |
b7b69c0c78296b8380eedfa12cc5e8f09f4ac7f4b87151b0fd8ab2b0eae8afc0 | Jupyter | 27,721 | 773 | # %%
import numpy as np
from matplotlib import pyplot as plt
import matplotlib as mpl
import scipy.signal as signal
import pandas as pd
import glob
import seaborn as sns
import scipy.ndimage as filters#changed from scipy.ndimage.filters as the namespace was deprecated 05/24/2023
import pickle
import scipy.stats as stat... |
82b8ecab5934f341784d8e663daa7050702e3167263f969dc9554e2756eb3170 | Jupyter | 27,753 | 809 | # %% [markdown]
# # Fine-tuning on Pre-trained Model with Batch Integration
# In this tutorial, we demonstrate how to fine-tune a pre-trained model on a new dataset for the batch integration task. We use the PBMC 10K dataset as an example and fine-tune on the pre-trained whole-body model.
#
# We summarize the fine-tu... |
40b82a4954d600bf2a1db5abf62aa72697ddde11d25cff2e4d14a7b62c1b658f | Jupyter | 29,064 | 630 | # %%
import h5py
import matplotlib.pyplot as plt
import matplotlib.colors as mcolors
import numpy as np
f = h5py.File("../results/simulation_results_full_low_noise.hdf5", "r")
x_min = -50
x_max = 50
# %%
norm = mcolors.CenteredNorm()
sigma_val = 'sigma_sp_5'
environment_num = 'environment_1'
velocity_num1 = 'velocity... |
cd45a96c2c2abb1134ac5f72f32f0ab4e3ea0048fbbac17c3a239673d8f3d151 | Jupyter | 29,100 | 791 | # %%
import scanpy as sc
import numpy as np
import seaborn as sns
import pandas as pd
import matplotlib.pyplot as plt
from scipy.cluster.hierarchy import linkage, fcluster, dendrogram
from anndata import AnnData
import hvplot.pandas
# %%
adata = sc.read_h5ad('GSE155121_human_data_raw.h5ad')
# %%
adata
# %%
adata_w31... |
bdac591f8e9d92d5fb3d39427be3d95f2a1c33c8a8be2a9d46e885b0a72a8d81 | Jupyter | 29,303 | 915 | # %% [markdown]
# ##paper stats generator
# ryoung@unlv.edu
# %%
# Cell 1
import os
import pandas as pd
import numpy as np
from sklearn.metrics import confusion_matrix, cohen_kappa_score, mean_absolute_error
# (Optional) For fuzzy matching
# !pip install rapidfuzz
# from rapidfuzz import process
# Ensure output di... |
c66eb8eaf9b115716f03d9ee6da70fe4edc42fc3efba183c2f1f20e84fbbe790 | Jupyter | 29,925 | 834 | # %%
!pip install torch matplotlib torchdiffeq
import torch
import torch.nn as nn
import matplotlib.pyplot as plt
from torchdiffeq import odeint
print("PyTorch:", torch.__version__)
print("CUDA :", torch.cuda.is_available())
if torch.cuda.is_available():
print("GPU name:", torch.cuda.get_device_name(0))
impor... |
b5d39e8f48caa5f29a72b46eb38c5c23c2d612ef4c320c408123dd18c8e975aa | Jupyter | 30,259 | 928 | # %% [markdown]
# # Figure 5: Heat maps, Venn diagrams, scatterplots, lists
# %% [markdown]
# ## 1. Load packages, data, and functions
# %%
# Import all the packages
# Run in pyenv4
import numpy as np
#import math
import pandas as pd
#from scipy.io import mmread, mmwrite
#from scipy.sparse import load_npz, save_npz,... |
684a9e3a6d1943299f6a3108d8a91a0c1fabe76f3953eeeb28e7efc864db8627 | Jupyter | 30,513 | 670 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
78f40ee13cf9f314291f756355eb333e0ba510e31750d702f35c55939a5ce6a0 | Jupyter | 30,667 | 730 | # %% [markdown]
# # scPRINT use case on BPH (part 2, GN analysis)
#
# In this use-case, which some of the results are presented in Figure 5 of our [manuscript](https://www.biorxiv.org/content/10.1101/2024.07.29.605556v1), we perform an extensive analysis of gene networks generated by scPRINT in our previous [notebook]... |
c8f045980006eb8831fddeaca6fdcc9259d505a6cee34c7bc02056941e682d88 | Jupyter | 30,775 | 753 | # %%
import pandas as pd
import numpy as np
import os
import matplotlib.pyplot as plt
# %%
# estimate total, coding and noncoding het
template_dir = "/mnt/seagate10/genotypes/hapgen10k11m"
coding_snps_f = "/mnt/seagate10/MEGAsync/cmm_experiments/e1/hapgen11m.utr5.utr3.exon.snps.txt"
coding_het = 0
noncoding_het = 0
t... |
309203e12dc1532c1cac84a050195d9391d050e052455cc2a2090bd26b1f2a6d | Jupyter | 30,828 | 847 | # %%
!pip install torch matplotlib torchdiffeq
import torch
import torch.nn as nn
import matplotlib.pyplot as plt
from torchdiffeq import odeint
print("PyTorch:", torch.__version__)
print("CUDA :", torch.cuda.is_available())
if torch.cuda.is_available():
print("GPU name:", torch.cuda.get_device_name(0))
import... |
354818b57e73eb936b97b9dc0eb7548f56df4ce5e9547fcedfa6620586b49b18 | Jupyter | 31,543 | 1,136 | # %% [markdown]
# ## 垂直整合 benchmark, benchmark方法有 RunscArches, RunMultigrate, RunTotalVI 和 RunSeurat V4
# ## 数据集 RNA+ADT
# %% [markdown]
# ## Garfield method
# %% [markdown]
# 用于水平整合的数据集 3_GSE150599 4_GSE194122
# %%
import scanpy as sc
import anndata as ad
import numpy as np
import os
import time
import warnings
w... |
a25a42918b2ff0ac5e79eb7917c1f13cf3763588f456bcff9e0e77514a616de5 | Jupyter | 31,642 | 750 | # %%
import matplotlib.pyplot as plt
from math import sqrt
from collections import namedtuple
import pandas as pd
import os
import numpy as np
from scipy.stats import norm
# %%
Trait = namedtuple("Trait",["name",
"p_coding","p_noncoding","p_coding_se","p_noncoding_se",
... |
1a60c69372dc23ced022f027b1cd5b00da2c1c36adda7b16a9132c100b893347 | Jupyter | 31,681 | 967 | # %%
# import packages
import scanpy as sc
import numpy as np
import scipy
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
from scipy.sparse import load_npz, save_npz, coo_matrix, csr_matrix
from scipy.ndimage import gaussian_filter1d
import matplotlib as mpl
# %% [markdown]
# IN VITRO DAY 2... |
3cf7bcdf565ae5ca49a052f1aeeb089bf51929818eda0617ef2024789215a205 | Jupyter | 31,883 | 710 | # %%
'''
This script visualizes the outputs of the Gabor filters applied to the natural videos.
Author: Jonathan Gant
Date: 05.05.2025
'''
import numpy as np
import matplotlib.pyplot as plt
from tqdm import tqdm
import h5py
import os
import bottleneck as bn
# Set random seed for reproducibility
np.random.seed(0)
# %... |
ab34cf708da90f9bbb0ae19db24aa0fbe69cf035c69fbf8af1c0c281cd6054d1 | Jupyter | 32,011 | 709 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
8ad15b5e516469d4cb9ec120dd504b7055375acf500f96332c60e5baba302572 | Jupyter | 32,248 | 859 | # %% [markdown]
# ## Package import and define parameters
#
# Below, you will define the basic parameters for your database and subcellular structures of interest. You will also initialize the tables in your database to hold the data for your objects of interest.
#
# In general, the sections of this notebook can be r... |
7d28d1f7b49bd7189657e9a47d37ec0bf779f49087300dcdc7a364d058279c02 | Jupyter | 32,523 | 884 | # %%
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from sklearn import datasets
import skimage as ski
import os
from joblib import Parallel, delayed
import warnings
from matplotlib.colors import LinearSegmentedColormap,LogNorm
import matplotlib.ticker as ticker
from skimage import filters, expo... |
4f41658c33ad8a866a8bec2c3c2569a4d5d2d8f91fc146f6cb41a9f5348ea6e2 | Jupyter | 33,460 | 714 | # %% [markdown]
# ### paired scRNA + scATAC metrics plot
# %%
import os
import pickle
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import scanpy as sc
import matplotlib
import matplotlib.colors as colors
import matplotlib.pyplot as plt
import seaborn as sns
from matplotlib import gridspec
f... |
56c98c9e86d4f8afe59e01e21e96fe7a50270ab6c56f3436955acda12427d8f5 | Jupyter | 33,746 | 869 | # %%
import os
import numpy as np
import matplotlib.pyplot as plt
import pandas as pd
from scipy.spatial import cKDTree
from scipy.spatial.distance import cdist
from scipy.ndimage import gaussian_filter1d
from mpl_toolkits.axes_grid1 import make_axes_locatable
import time
import skimage as ski
from skimage.transform im... |
471c845813f097219465814b1c617519c7ba8bd502fc0f02680dd11030ea1586 | Jupyter | 34,197 | 941 | # %% [markdown]
# ###
# ## Phase Neural Operator (PhaseNO)
# ### PhaseNO for multi-station earthquake detection and phase picking
# ### - Predict on continuous seismic data with the pretrained model -
# ### - (March 31, 2025) Version 1.0.1: Optimized the implementation to reduce computational overhead. See README.txt ... |
e45df77bd2f58bd2b45e432e4f3b0451557bb2b9f132a298aadd2770171c0b8f | Jupyter | 34,385 | 1,080 | # %%
import os
import glob
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
def _parse_int_list(s):
s = str(s).strip().strip('"').strip("'")
if not s:
return []
return [int(x.strip()) for x in s.split(",") if x.strip() != ""]
def load_many_csvs(csv_glob_pattern: str) -> pd.... |
ac1f48b7b1de21f122e422f27e57fad70857b48043732ba6e1d13e214f4e5ec0 | Jupyter | 34,430 | 884 | # %%
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sns
import pandas as pd
import os
import sys
from mpl_toolkits.axes_grid1 import make_axes_locatable
import tifffile as tiff
import skimage as ski
import math as math
import warnings
warnings.filterwarnings("ignore")
# Set up paths
proj_dir = o... |
c4cb8a3789726f0e7cdf0b4bc0e9dc35e5191f5993328ab7a8b2f5d3b46896d1 | Jupyter | 34,454 | 1,638 | # %%
%config InlineBackend.figure_format = 'retina'
%matplotlib inline
import sys
import os
import matplotlib.pyplot as plt
from matplotlib.colors import to_rgb, hex2color
from sklearn.preprocessing import OrdinalEncoder
from scipy.cluster.hierarchy import cut_tree, dendrogram, leaves_list
import numpy as np
from nu... |
616098589838a022dcb3f7b9cc5921b3c8495b9af78b6c57952044aead7d4389 | Jupyter | 35,149 | 1,116 | # %%
import loompy
import numpy as np
import pandas as pd
import matplotlib
import matplotlib.pyplot as plt
import os
from cytograph.pipeline import load_config, PunchcardDeck
from cytograph.plotting import colorize
from cytograph.embedding import art_of_tsne
from cytograph.visualization import scatterm
from cytograph.... |
625cd7584be04c0ae2c00301debfc3b9b57d6bc2b08358dbbcd4696df0c7dd6c | Jupyter | 35,361 | 953 | # %% [markdown]
# # Clinical Data Visualization
# %%
import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib.pyplot as plt
import matplotlib.gridspec as gridspec
from scipy.stats import spearmanr
import warnings
warnings.filterwarnings('ignore')
sns.set_context("paper")
colors = sns.color_palet... |
0cef90fa5c4a09b74ca63c42e4e9c5a909a1d276afad03e588a1ef3d14955aa5 | Jupyter | 35,719 | 1,149 | # %% [markdown]
# # Additional Figures
# %% [markdown]
# #### Additional analysis
# %% [markdown]
# Preloading
# %%
import os
from biolab.bspm import BSPM
# -----------------------------
# PARAMETERS
# -----------------------------
bspm_dir = r"C:\Users\Ruben\OneDrive - University of Cambridge\PhD\BSPM_for_ECGi\Pub... |
0d98ef8b135de9906717130190fc4e27ac623bb63bad46811a488134169cee95 | Jupyter | 35,791 | 1,112 | # %% [markdown]
# # Exit / entrance distributions
#
# Spatial probability distributions of where fish exit and re-enter the arena centre.
# %%
import os
import dataframe_image as dfi
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from sklearn.neighbors import KernelDensity
from cichlid_omr.co... |
9e71f1aa2d9d34d06e69b27552f285701f026d9c3241af1dcb476e50ee309339 | Jupyter | 35,930 | 960 | # %%
import os
import glob
import matplotlib.pyplot as plt
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
import pickle
import seaborn as sn
import scipy
from numpy import linalg as LA
import random
from numpy.matlib import repmat
import copy
fro... |
7f97d8457d5c0ae271e2cebe19a4fb5a592690f6e760267422e4ed0339ab54db | Jupyter | 36,017 | 960 | # %%
import os
import glob
import matplotlib.pyplot as plt
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
import pickle
import seaborn as sn
import scipy
from numpy import linalg as LA
import random
from numpy.matlib import repmat
import copy
fro... |
66f3e80c42068d329a921a1244d1115142920459cd01b0d54b4dd2c16739d5f4 | Jupyter | 36,087 | 961 | # %%
import os
import glob
import matplotlib.pyplot as plt
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
import pickle
import seaborn as sn
import scipy
from numpy import linalg as LA
import random
from numpy.matlib import repmat
import copy
fro... |
87bb1deb7364df6e26f868e611bcd554ca7885eecaf714f5ff09b9186b604526 | Jupyter | 36,127 | 971 | # %%
import os
import glob
import matplotlib.pyplot as plt
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
import pickle
import seaborn as sn
import scipy
from numpy import linalg as LA
import random
from numpy.matlib import repmat
import copy
fro... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.