
sha256 stringlengths 64 64 | language stringclasses 28
values | size int32 1 491k | lines int32 1 23.2k | content stringlengths 1 200k |
|---|---|---|---|---|
995e8f2a40e2bf8903ffe34bfa7216239633c076282ed059cd2b579aaacc8efd | Jupyter | 12,885 | 483 | # %% [markdown]
# # Trial duration
#
# Trial-duration (stimulus time) analysis and figures.
# %%
import os
import dataframe_image as dfi
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import pingouin as pg
from cichlid_omr.config import data_dir, load_config, output_dir
# %matplotlib widget
... |
d493eb63918cab367cbb394095e399bf4ee0e121157b14857a5983672eb851a3 | Jupyter | 12,987 | 371 | # %%
# Import modules
%matplotlib notebook
import tensorflow as tf
import numpy as np
import matplotlib.pyplot as plt
from obspy import UTCDateTime, read, read_inventory, read_events
from obspy.clients.fdsn import Client
from obspy.clients.fdsn.header import FDSNNoDataException
from datetime import datetime, timedel... |
35c5c5cd380f765d12196e18f3b2d22820e7fccb5b151e51a3f7a01855d070d2 | Jupyter | 13,001 | 296 | # %% [markdown]
# # Visualization of nucleotide embeddings produced by SpliceBERT
# %%
import os
os.environ["CUDA_VISIBLE_DEVICES"] = "2" # select GPU device
os.environ["BATCH_SIZE"] = "16" # set batch size
import sys
import json
import scanpy as sc
import pickle
import gzip
import h5py
from glob import glob
from tqdm... |
3ed2469523bc08dbf84945943b6c995fde5b010c74a69097458fb399a4a0bdb7 | Jupyter | 13,042 | 371 | # %%
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt
plt.rcParams.update({'font.size': 14})
import matplotlib.font_manager as fm
import os
import urllib.request
# %%
sns.set_theme(font="Arial", font_scale=1.5)
# %%
# Set transparent background but keep horizontal grid lines
plt.rcParams['a... |
3f3ce901dedf4811fd9790a96310997be9c2f3539f39780c489acf8b90edd833 | Jupyter | 13,088 | 319 | # %% [markdown]
# ## Quality control for PPI analysis
#
# This notebook presents basic quality control analysis for PPI beta-weights. Input data consists of set of beta-weights matrices for each subject and task condition. Each beta-weight matrix is $N_{rois} \times N_{rois} \times N_{regressors}$ matrix aggregating ... |
b2e089e09d4fce10b450e45403c7295ea682f01471974ea2429de1e7df4fb5c4 | Jupyter | 13,115 | 349 | # %%
import numpy as np
from mpl_toolkits.axes_grid1.inset_locator import inset_axes
# packages for plotting
import matplotlib.pyplot as plt
import matplotlib.font_manager as font_manager
import urllib.request
urllib.request.urlretrieve('https://github.com/google/fonts/raw/main/ofl/ibmplexmono/IBMPlexMono-Regular.ttf... |
1c774f5720c4f97359c3ece7eb850d973a51434410ec5dbd9db3ff6c9dd6d0fd | Jupyter | 13,188 | 340 | # %% [markdown]
# # Basic FISSA usage
# %% [markdown]
# This notebook contains a step-by-step example of how to use the [FISSA](https://github.com/rochefort-lab/fissa) toolbox. See [basic_usage.py](https://github.com/rochefort-lab/fissa/blob/master/examples/basic_usage.py) (or [basic_usage_windows.py](https://github.c... |
82e2c3c3ed850aa4c419465da6813c52a069430bf26457d1ad6e6cc468135cb4 | Jupyter | 13,215 | 359 | # %% [markdown]
# First, ensure there's adversarial_results folder. If not, run adversarial_eval.py to generate the raw data for these plots. Then run this notebook to generate the plots.
# %%
import glob
import json
import os
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import matplotlib.fon... |
de58c17ae6f4c2d92eceb522b8d0d39f0fb96aca737275f596d79d969c668b90 | Jupyter | 13,264 | 372 | # %%
import pynapple as nap
import matplotlib.pyplot as plt
import numpy as np
import nemos as nmo
import scipy
from itertools import combinations
from matplotlib.gridspec import GridSpec
nap.nap_config.suppress_conversion_warnings = True
plt.style.use(nmo.styles.plot_style)
import warnings
warnings.filterwarnings("ig... |
9f0fea053ee0426b514c81d25bfefbdfcb0bef7b0540c03a148636e74a46e60a | Jupyter | 13,285 | 325 | # %%
import os
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from skimage.filters import gaussian
from skimage.morphology import remove_small_objects
from skimage.measure import label, regionprops
from skimage import exposure
from skimage import measure
from czifile import imread
from cellpose ... |
5165053408ea385ab39d8cdda1f2f1034012768f63b729b98c051425425fedd9 | Jupyter | 13,320 | 230 | # %% [markdown]
# # Deep Feature Factorizations for better model explainability
# 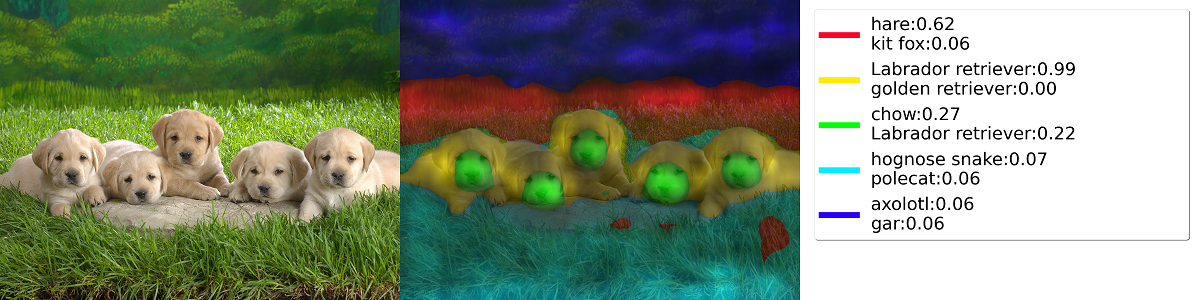
#
# In this tutorial we will see how a method called "Deep Feature Factorizations" can be used for creating insightfull visualizations about what th... |
fdebbc5084e0946d319b2defeaa74697e255cacfbe8451facf8f8f6958348a71 | Jupyter | 13,355 | 426 | # %% [markdown]
# # Simple CA1 Model - Off-Path Inhibition Experiment
#
# This notebook demonstrates a simple electrophysiology experiment:
# - Build a simple soma-dendrite model with morphology: soma → dend1 → (dend2, dend3)
# - One branch receives excitation, the other inhibition.
# - Record membrane potential from ... |
b66fe1d198aa04d3d88a73b7c997ad21fd61705a642ec7c5ad708bcadcf24ddb | Jupyter | 13,489 | 435 | # %% [markdown]
# # Simple CA1 Model - Double Excitation Experiment
#
# This notebook demonstrates a simple electrophysiology experiment:
# - Build a simple soma-dendrite model with morphology: soma → dend1 → (dend2, dend3)
# - Synaptic excitation of two dendritic branches
# - Record membrane potential from soma and d... |
28b82ab32b994ab8cd6ab6fb4863f59ac417009ac1ac07a1a955d1fbd41d5e24 | Jupyter | 13,532 | 402 | # %%
import os
import polars as pl
from src.plotting_functions import plot_transcript_class_hist
from src.utils import read_gtf, read_fasta
from Levenshtein import ratio
import seaborn as sns
import matplotlib.pyplot as plt
import orfipy_core
import matplotlib.pyplot as plt
from matplotlib_venn import venn2
# %% [mark... |
822e8a311c4dba994ffb710faab732f6f6ad460d855b6da914d10110deeff7cf | Jupyter | 13,572 | 518 | # %% [markdown]
# # RNA-FM Tutorial
# %% [markdown]
# ### Workflow of our tutorial
#
# **Preparation**
# 1. install the RNA-FM package
# 2. load the necessary libraries
#
# **Task 1. RNA family clustering**
#
# Goal: to demonstrate that RNA-FM embeddings are biologically meaningful
#
# 1. read RNA sequences for ea... |
70c36d037a44c823e5a96af2115b99140afbd073f26270b1f4d9920b0545d377 | Jupyter | 13,658 | 353 | # %% [markdown]
# # IBL Brain Wide Map → HIPPIE CSV converter
#
# Download a single IBL Brain Wide Map (BWM) insertion via the [ONE API](https://int-brain-lab.github.io/iblenv/) and convert it into the canonical HIPPIE CSV layout (`waveforms.csv`, `isi_dist.csv`, `acg.csv`, `labels.csv`, `metadata.csv`).
#
# Mirrors ... |
b642faf9816c6d4794c3c5f74cf29970b149ebcdff93b69b37dae22f856dd9be | Jupyter | 13,693 | 355 | # %% [markdown]
# # Merging "protospacer_calls_per_cell" with "filtered_matrix" hdf5 file
# %% [markdown]
# ## 1. Import packages
# %%
# Import all the packages
import h5py
from pathlib import Path
import numpy as np
import pandas as pd
from scipy.io import mmread, mmwrite
from scipy.sparse import load_npz, save_np... |
3ea7c6eba410b5d6811d573fd64c7055f437d938d665db675fa532170aa72024 | Jupyter | 13,703 | 439 | # %% [markdown]
# This notebook requires the TinyMol dataset, which is downloaded by the following cell.
# %%
!python ../../scripts/download_tinymol_dataset.py
# %%
import pandas as pd
import numpy as np
from uncertainties import ufloat_fromstr
import uncertainties.unumpy as unp
import matplotlib.pyplot as plt
from ... |
d1614ba12af23ad2c653a6b396d681e797964726ad6a38e733ccff25ccb2f77d | Jupyter | 13,719 | 315 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
86812f8a1fc2a63f9ff17c2be412e2ee9f5d5373df523fe98bf9e4491191ddb1 | Jupyter | 13,792 | 311 | # %% [markdown]
# # Visualizing MSI Images with Parametric UMAP .
#
# Binning with m/z from 900 is used to create the segmentation.
# Then we train parametric UMAP using only the non noise bins, with 1 output.
# %%
import numpy as np
import joblib
from sklearn.decomposition import non_negative_factorization
from skl... |
2beae5182874cc332cd5a1c22420eb0433e10ddd0b167dae87b329956c65785a | Jupyter | 13,805 | 500 | # %% [markdown]
# # Investigating the influence of different PSP shapes on SAL
#
# In this notebook, we investigate the influence of different PSP shapes and synaptic time constants on the symmetrization capabilities of SAL.
# We return to the standard two neuron system from the beginning and compute phase plane disgr... |
85d3c6947c9478b77778ac6830904399cf0990f529342e9edefab9b657a7cc6c | Jupyter | 13,943 | 437 | # %%
import pandas as pd
import matplotlib.pyplot as plt
from matplotlib import rcParams
import numpy as np
from uncertainties import ufloat_fromstr
from uncertainties.unumpy import nominal_values, std_devs
import matplotlib.ticker as ticker
from matplotlib.legend_handler import HandlerTuple
from matplotlib.offsetbox... |
6b0a0cd0f9307d3ee0d2d2e72dbf7dd00e1840fd5459e0d8a3c55d245f48a792 | Jupyter | 13,981 | 363 | # %% [markdown]
# # 🧬 + 🤖 **Hello Evo**: From DNA generation to protein folding
#
#
# Evo is a 7B long-context biological foundation model that generalizes across the fundamental languages of biology: DNA, RNA, and proteins. It is capable of both prediction tasks and generative design, from molecular to whole genom... |
5f4abc9cec5635b0909e348eaba6a86cc6cfff3cee05389d17ef3e93ce1ec9e0 | Jupyter | 13,986 | 442 | # %%
# ==========================
# Cell 1: Imports & Data Load
# ==========================
import os
import pandas as pd
import numpy as np
import requests
import json
import logging
import time
from typing import List, Dict, Any, Optional
from enum import Enum
from dataclasses import dataclass
from sklearn.metric... |
799c75afa457719af7943824a44809f87bcac8e6f5cf1c889c93d575bb20d5c6 | Jupyter | 14,034 | 366 | # %%
import os
import pandas as pd
import scipy.stats as sci
import statsmodels.api as sm
from statsmodels.formula.api import ols
from statsmodels.stats.multicomp import MultiComparison
from statsmodels.stats.multitest import multipletests
import warnings
import glob
import sys
curr_path = os.getcwd()
sys.path.append(f... |
03de5ebdb1f5b9b26b25d05ce3f8c97b96ca8bdc0957333eebcc063dd68f4b68 | Jupyter | 14,039 | 369 | # %% [markdown]
# # Optimal structural resolution parameter range
#
# Explore broad range of structural resolution parameter gamma to find out optimal range for further modularity analysis. Two heuristics are used: one based on module size and number of modules and another based on similarity between partitions.
#
# ... |
8a7af06f5dc81883d0d89e6bfacda77f5de9553c0be4ccdfbeb50c48efc15ffd | Jupyter | 14,043 | 293 | # %% [markdown]
# # Main usage of Novae
#
# This tutorial shows how to load a Novae model, apply it to your spatial data, and plot results. We show Noave's usage for spatial data with single-cell resolution (e.g., Xenium, MERSCOPE), but we will also soon make a tutorial for spot resolution data (e.g., Visium).
#
# Ma... |
c728858bdab6b466d8b7e5073d5d287e8a5332906e83a88654d7ba3baf88065d | Jupyter | 14,079 | 513 | # %%
import loompy
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import os
from cytograph.plotting import colorize
from urllib.request import urlretrieve
import matplotlib as mpl
# make font changeable in Illustrator
mpl.rcParams['pdf.fonttype'] = 42
# save figure with no pad
mpl.rcParams['s... |
35bba5644d7a9f6847d3950a021bd4c140e4302ea7ba7c71c352d42361c6ee96 | Jupyter | 14,119 | 419 | # %%
%matplotlib inline
%reset
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import pickle
import skfda
import sys
from scipy import linalg
from scipy.integrate import simpson
from skfda.preprocessing.dim_reduction import FPCA
from skfda.representation.basis import BSplineBasis
from statsmod... |
a502fae694c4542abea249e6f1ef481d36b09223de5b84a8d6458d41c0f4388e | Jupyter | 14,130 | 378 | # %% [markdown]
# ## Heading Estimator for Fly Trajectories
# This notebook serves as both a tutorial and a method by which one can generate realistic heading trajectories. We walk through the steps of importing data, augmenting data, making sure the coordinate frames are correct, and fine-tuning the generated headings... |
a97253fafcb2e3361492967184cd8ba6acc4f42ffdb1ae417446d5c4db711dad | Jupyter | 14,148 | 408 | # %%
!pip install fft-conv-pytorch
!pip install scikit-image
# %%
import sys
from pathlib import Path
# Find GRAPHYCS root (folder that contains graphycs/forward_model_wf.py)
start = Path.cwd()
root = None
for p in [start, *start.parents]:
if (p / "graphycs" / "forward_model_wf.py").exists():
root = p
... |
ea29669836bf139a02c83ce17bd2922e9289e97c986ec77a4b60de75f587efe6 | Jupyter | 14,207 | 438 | # %%
import numpy as np
from matplotlib import pyplot as plt
import matplotlib as mpl
import scipy.signal as signal
import pandas as pd
import glob
import seaborn as sns
import scipy.ndimage as filters#changed from scipy.ndimage.filters as the namespace was deprecated 05/24/2023
import pickle
import scipy.stats as stat... |
c9eba9894d85b3084dfebcc009a95c8e68255fdb8016e3c6d2272c8ce5c9f2a8 | Jupyter | 14,400 | 469 | # %% [markdown]
# # SDR Family Analysis
# %% [markdown]
# ## Identifying SDR Family Proteins
# %%
import json
import pandas as pd
with open("data/GeneOntology/test_interpro.json", "r") as f:
interpro = json.load(f)
rows = []
for protein_id, entry in interpro.items():
results = entry.get("results", [])... |
cfdec15be1cdab66eaf7ca1d6a1b77b6570462678da8b810dbefc460c3036694 | Jupyter | 14,403 | 355 | # %%
# =============================================================================
# Cross-level comparison: do individual-level metrics predict group-level significance?
# =============================================================================
# For each (Age × Chrom × Parcel), compute individual-level summari... |
d06b57e7d5b969370275ec14e97eb2bf79bc7da598bf457148faac263e4038d6 | Jupyter | 14,499 | 262 | # %% [markdown]
# ## **Code used to generate Figure 2E.**
# %% [markdown]
# ##### **First we load the stats csv file for Old ants as a dataframe, and calculate values needed for downstream steps.**
# %%
import pandas as pd
import numpy as np
import glob
from natsort import natsorted
#This script is used to load the ... |
af2f011781c456e26f9cb5e1db951bc93ce242a02b70423ff22c7eee54c382d4 | Jupyter | 14,501 | 377 | # %% [markdown]
# # Python Version of Tree SHAP
#
# This is a sample implementation of Tree SHAP written in Python for easy reading.
# %%
import sklearn.ensemble
import shap
import numpy as np
import numba
import time
import xgboost
# %% [markdown]
# ### Load boston dataset
# %%
X,y = shap.datasets.boston()
X.shape... |
b1603aaf4ef580a0ccd22ee9d7651ade29e679524dc4c03d68fe378f79c5f82b | Jupyter | 14,532 | 374 | # %%
import numpy as np
import matplotlib.pyplot as plt
from pathlib import Path
from google.colab import drive
from models import (simulate_rl_kernel, simulate_metarl, simulate_rbpf,
compute_measures, reversal_locked)
%matplotlib inline
plt.rcParams['figure.dpi'] = 110
plt.rcParams['font.size'] =... |
f2146b34c87bef8d8afc52f56f5e6046990554483e2c7adcb09f8d26be9c6a45 | Jupyter | 14,610 | 474 | # %%
import numpy as np
from matplotlib import pyplot as plt
import matplotlib as mpl
import scipy.signal as signal
import pandas as pd
import scipy.stats as stats
import seaborn as sns
from scipy import interpolate
import glob
import os
# %%
from ploting import *
from extented_stats_tools import *
from signal_proces... |
2c29f7cc1ddd0c3784dca66d863ef2abda231b457fb1d988b628669fb992a030 | Jupyter | 14,611 | 349 | # %%
import gseapy as gp
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sns
import matplotlib.gridspec as gridspec
import warnings
import plotly.graph_objects as go
import plotly.io as pio
from palettable.tableau import Tableau_20
warnings.filterwarnings('ignore')
sns.set_conte... |
f059f56693f3abb61f94d1f27e4e96f65b5d98b39bfcede09f1c7eaa230a9858 | Jupyter | 14,690 | 430 | # %% [markdown]
# # Prior training
#
# In this part we train prior models.
# %%
import TSA
import tools
PROJ_NAME = 'DualDataset'
TSA.setup_proj(PROJ_NAME, 'ab')
# %% [markdown]
# ## Useful functions
# %%
import keras as K
import tensorflow as tf
def create_prior_model(input_shape=(1000, 3)):
initial_model = ... |
a3b01ff8f35138631af27cadf34ee2854a60bde08cdd08fab442c321b6104bbf | Jupyter | 14,743 | 526 | # %%
import bpreveal.plotting as bprplots
import h5py
import matplotlib.pyplot as plt
import numpy as np
from bpreveal import utils
from bpreveal import colors as bprcolors
BASE_DIRECTORY="/n/projects/cm2363/bpreveal"
WORKING_DIRECTORY=BASE_DIRECTORY + "/test/acceptance/oskn-4.1.4"
GENOME_FASTA="/n/data1/genomes/index... |
f13867b4c3dabfa43841e1c9c3ec66548e09db3400a97a0ba6621e263f32feac | Jupyter | 14,887 | 398 | # %%
%matplotlib notebook
import numpy as np
import scipy.io as si
import os
import h5py
from sklearn.model_selection import KFold
from sklearn.svm import SVC
import sklearn.pipeline as skp
from sklearn.preprocessing import StandardScaler
import matplotlib.pyplot as plt
from functools import partial
from joblib import... |
cc7c3ee2243743ea3289e9d30284e5946e24f8fdd9ef3653da89faf148b41d50 | Jupyter | 14,908 | 411 | # %% [markdown]
# # Inference with sCellTransformer - PyTorch version from HuggingFace
#
# sCT was ported from `jax` to `PyTorch`, and then released through HuggingFace.
# This notebook aims to ensure that the HuggingFace model works properly, by loading it and using it on dummy sequences.
# %% [markdown]
# [![Open... |
c6092c56e9025f2143ae80878cbcca836d0746c8608eb579448376be29801ecd | Jupyter | 14,924 | 544 | # %%
import joblib
import numpy as np
import glob
from importlib import reload
from PIL import Image
import msi_visual
from msi_visual import nmf_segmentation, kmeans_segmentation
reload(nmf_segmentation)
reload(kmeans_segmentation)
paths = glob.glob("D:\maldi\slides\slide2_notol_5_bin\\*.npy")
paths = [paths[1]]
seg ... |
d51f73689703d84f1f679619c98db4c9fc3b5087a595b9bb1e9613db437ef3db | Jupyter | 15,051 | 352 | # %% [markdown]
# ## 1. Importing Necessary Libraries
# This initial cell imports all the required Python libraries for the script. This includes os for file system operations, scipy for loading data from MATLAB's .mat files, matplotlib for plotting, numpy for numerical operations, and several key components from the p... |
7b3d1046c95c1db8aaeec91f7e179262bb61f80c52015910502ddc894da0dfc7 | Jupyter | 15,087 | 460 | # %%
import json
import os
import numpy as np
import pandas as pd
from scipy.stats import spearmanr, wilcoxon
# %% [markdown]
# ### Significance Test 1: Selectiveness
#
# **"For each censoring method (feature noise, label noise, omission), does sensitive performance degrade significantly more than non-sensitive perfo... |
9a51e22e13f84d283611d7c57662c024971b1d806f029c238918bb66c99413c6 | Jupyter | 15,103 | 409 | # %%
%pylab inline
import pandas as pd
from scipy.stats import pearsonr,spearmanr
# %%
import colorbm as cbm
import seaborn as sns
sns.set_palette(sns.color_palette(cbm.pal('npg').as_hex))
# %%
import pickle
with open('/nfs/DeepCDR/DeepCDR-master/data/processed.pkl','rb') as f:
datafeature = pickle.load(f)
# %... |
4e622eb501fb1b4814cc31831a3d89c495c4228393a6ac82b9d84335adedc9eb | Jupyter | 15,252 | 538 | # %% [markdown]
# # Compare SAL, RDD and STDWI in a scatter plot
#
# As preliminary study for the “big” SymmNet experiment, we compare the three spiking symmetrization algorithms regression discontinuity design (RDD, Guerguiev et al, 2019) and spike-timing dependent weight inference (STDWI, Ahmad et al, 2020).
# A spi... |
dce1c550951321029f1fdb3aba22ca4cf74aa202e072ed3190316cfd81e3d15b | Jupyter | 15,283 | 398 | # %% [markdown]
# ## Description, Imports, and Configuration
# %%
#!/usr/bin/env python
# coding: utf-8
"""
FunBurd: Functional Burden Test for Gene Set Association Analysis
Author: Sayeh Kazem
Python Version: 3.10.2
Rationale:
FunBurd (Functional Burden Test) is a statistical method designed to estimate the associa... |
a164aa7e1678bf84b3d09c161142ed02bfad7bb0c6d683375d4d6f080b99ecfa | Jupyter | 15,291 | 387 | # %% [markdown]
# # Performing scramble PCA on SMD genes and visualizing each phenotype condition with saved components
# %% [markdown]
# ## 1. Import packages
# %%
# Import all the packages
import numpy as np
import pandas as pd
from scipy.io import mmread, mmwrite
from scipy.sparse import load_npz, save_npz, coo_m... |
25ecec11fc517cb50c2f350a7fbbcfee9663a7f31c6b8dff5e897727d8d399fc | Jupyter | 15,445 | 415 | # %%
% matplotlib inline
import nibabel as nib
import nibabel.gifti
import nilearn
from nilearn import datasets, plotting
import pandas as pd
import numpy as np
import matplotlib as mpl
import matplotlib.pyplot as plt
import pylab as plt
from matplotlib.colors import ListedColormap
mpl.rcParams['svg.fonttype'] = 'no... |
1647e25f02391a32471de05b1aa1ad8800edc90b8b2a552cb2073ed462acb86f | Jupyter | 15,601 | 557 | # %% [markdown]
# Tutorials of CPS using HBC dataset
# ===
# **Interpretations of attention scores**
# 1. read the dataset
# 2. construct the graph (construct the multi-scale features, option)
# 2. train the model
# 3. generate the arbitrary resolution spots
# 4. visualize the results
# %%
import os,sys
sys.path.appen... |
bc21d868b4e143a31d9849b6729b0cfb0740cf7e91ef59cb6fb7788a07e292d0 | Jupyter | 15,641 | 526 | # %%
import numpy as np
import pickle
from scipy.stats import hypergeom
import statsmodels.stats.multitest as smm
import sys
sys.path.append("/Users/sambe/Documents/Python_Projects/FDA/functions")
import fNIRSData
# %%
# Helper function to load data
def load_data(filename):
with open(filename, 'rb') as f:
... |
7df4ec69ef3b457dc60d74c15662a6e5c0b40420f30538b43f79f241c19a2c2b | Jupyter | 15,845 | 456 | # %%
import loompy
import numpy as np
import pandas as pd
import matplotlib
import matplotlib.pyplot as plt
import os
import numpy_groupies as npg
from scipy import sparse
import seaborn
import matplotlib as mpl
import gget
import pickle
import tomotopy as tt
from scipy.cluster import hierarchy as hc
# suppress INFO
i... |
f7b137950cdd463aa09cfdef1d236f2f95b54a7e27311f8a4bf365fa09c9eec9 | Jupyter | 15,886 | 182 | # %% [markdown]
# # EASY TRAINER LOADING
# ---
# Note that this is different from loading a predictor (for inference)
# %%
# !pip3 install -e /data/pathology/projects/pathology-lung-TIL/nnUNet_v2
# %% [markdown]
# # Libraries and utils
# %%
import os
import numpy as np
import torch
from nnunetv2.run.run_training imp... |
763964057d815a57219d72510cc2c12848bac755e76ec2ca2c94b6d206c75683 | Jupyter | 15,905 | 452 | # %% [markdown]
# # Inference with sCellTransformer - Jax version
# %% [markdown]
# [](https://colab.research.google.com/github/instadeepai/nucleotide-transformer/blob/main/notebooks/sct/inference_sCT_jax_example.ipynb)
# %% [markdown]
# ## I... |
35131da5a564c46d983b27d9f2169e58faa26315f58c5592764a4e96a08bc906 | Jupyter | 16,009 | 188 | # %% [markdown]
# # EASY TRAINER LOADING
# ---
# Note that this is different from loading a predictor (for inference)
# %%
# !pip3 install -e /data/pathology/projects/pathology-lung-TIL/nnUNet_v2
# %% [markdown]
# # Libraries and utils
# %%
import os
import numpy as np
import torch
from nnunetv2.run.run_training imp... |
7352872cddfbad69a219ff4ed2641181b1df902451ff64a3594d865396b6610e | Jupyter | 16,039 | 421 | # %% [markdown]
# # Preparation
# %% [markdown]
# ## Graz dataset
# %% [markdown]
# Download Graz Dataset (BCI COMP IV 2) `a` and `b` dataset files. Instructions to download them is given by the original paper (given in `dataset/BCI_COMP_IV_2x/desc_2x.pdf` files) and put the `GDF` files inside `dataset/BCI_COMP_IV_2x... |
09c0f41aef02e8e6c2feea1581056a7dd0c386dbb4fb88c6b05b8c2fc617ebbe | Jupyter | 16,098 | 504 | # %%
import loompy
import numpy as np
import pandas as pd
import matplotlib
import matplotlib.pyplot as plt
import os
from cytograph.pipeline import load_config, PunchcardDeck
from cytograph.plotting import colorize
from cytograph.embedding import art_of_tsne
from cytograph.visualization import scatterm
from cytograph.... |
e3f33037f0761ff18c8408ed0c79c1246e35075bf0707a20a4f649726eb86cb9 | Jupyter | 16,225 | 404 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
c49aa95c6a27880a7939405c40ad8dcb6488ce98516ae2b5de7929ca8c3aa160 | Jupyter | 16,373 | 693 | # %% [markdown]
# # Plot data for Kolen-Pollack decay rate study in SSNs
#
# In this script, we plot our study on the effect of the Kolen-Pollack weight decay rate on the training performance of spiking sampling networks (SSN). We scan through the weight decay rate in both nosie scenarios (**synpatic noise** and **pla... |
d936968ea92164f11e6407a611b8e166f3f523116f2a0b30db40935cc1bc20a2 | Jupyter | 16,460 | 484 | # %%
!pip install torch matplotlib torchdiffeq
import torch
import torch.nn as nn
import matplotlib.pyplot as plt
from torchdiffeq import odeint
print("PyTorch:", torch.__version__)
print("CUDA :", torch.cuda.is_available())
if torch.cuda.is_available():
print("GPU name:", torch.cuda.get_device_name(0))
import... |
acc8895f0534f23533f5f2736d07266bd6cdda26099fec2974d3deb6198d72a7 | Jupyter | 16,558 | 509 | # %%
##### Fig. 6 - Task modulation effect on phonemic representations in the left pSTS
#
# written by S-C. Baek
# updated date: 16.12.2024
#
# %%
# import packages
import os
import sys
import pickle
import numpy as np
from scipy import stats as stats
import mne
from mne.stats.multi_comp import fdr_correction
impo... |
2731592d9608e1cb268c06ad501451d94a10f3f7f01c58bb34f0f1b4dcc2104a | Jupyter | 16,599 | 455 | # %%
import numpy as np
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns
import scipy.stats as stats
import sys
%matplotlib qt
from pathlib import Path
from ploting import set_plot_style, set_pub_plots
code_folder = Path(R'C:\Users\jmb9770\Documents\Python\sniffs')
out_folder = code_folder/'o... |
06b392397dbac772794e61b63592b27c6ebbe4159ca20e81487e6fa95a49a209 | Jupyter | 16,656 | 435 | # %% [markdown]
# # ACQM to CSV Converter (Using Neurocurator)
#
# This notebook processes ACQM (Acquisition Manager) electrophysiology data and converts it into CSV files using the **Neurocurator** class.
#
# ## Key Features:
# - **Automatic data loading** - `Neurocurator.load_acqm()` handles everything
# - **No man... |
24684c6a699e505c7a3455de0b02bf99564aac6a171e7c389a590c4e40c29c46 | Jupyter | 16,730 | 482 | # %%
import loompy
import numpy as np
import pandas as pd
import matplotlib
import matplotlib.pyplot as plt
import os
import numpy_groupies as npg
from scipy import sparse
import seaborn
import matplotlib as mpl
import gget
import pickle
import tomotopy as tt
# suppress INFO
import logging
logger = logging.getLogger()... |
fc33eafb65b9ea47f78cbdc6371da52b743dd2e6135aff909c83be5aca978dee | Jupyter | 16,882 | 629 | # %% [markdown]
# This notebook generates Figures S1-S6 from the supplementary for the manuscript `Asgeir Kobro-Flatmoen, Jagir R. Hussan, Peter J. Hunter, Stig W. Omholt, "High reelin expression can explain why the entorhinal cortex is a cradle for Alzheimer’s disease", [doi: https://doi.org/10.1101/2025.06.04.655278... |
81ca7c44e188b9ebd0f9c41e7b847dc532e6f69b1218af6a1e4ce3c03984f1fa | Jupyter | 16,935 | 356 | # %%
import os
os.environ["CUDA_VISIBLE_DEVICES"] = "2"
import sys
from tqdm import tqdm
import pickle
import numpy as np
import matplotlib.pyplot as plt
new_rc_params = {'text.usetex': False, 'svg.fonttype': 'none' }
plt.rcParams.update(new_rc_params)
from sklearn.metrics import average_precision_score, precision_reca... |
a0fefc6e799a2d8ba65519cc69620355ec37bfb9f31774a69501c961a9a5f5ef | Jupyter | 17,133 | 425 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
a4e8c06dddcef99ea7822854ff6bb730337e25bebaf2e0d35158f2941250fc73 | Jupyter | 17,337 | 501 | # %%
import numpy as np
import pandas as pd
pd.set_option('display.max_rows', 500)
pd.set_option('display.max_columns', 500)
pd.set_option('display.width', 1000)
from sklearn.datasets import load_digits
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler
from sklearn.e... |
d56f5541326fbfb0359ff93e0a1f2005354c081958d43fa35134b4e2e08c77ea | Jupyter | 17,392 | 395 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
8e4ca8a2149d80fcc937804f08379e11cce5602a04fc11957b4a8e9473c33554 | Jupyter | 17,412 | 389 | # %%
import os
import glob
import matplotlib.pyplot as plt
from nilearn import image as nimg
from nilearn import plotting as nplot
from bids.layout import BIDSLayout
import numpy as np
import nibabel as nib
from nibabel import load
import pandas as pd
from nilearn.image import resample_to_img
import pickle
import seabo... |
9973f104e7336c12d198ec37fc433f160e134250b0c972e9a1639e7bea5efe2d | Jupyter | 17,451 | 389 | # %% [markdown]
# # Loading data
# %%
'''
This script analyzes the results of stimulated eye movements.
Author: Jonathan Gant
Date: 13.06.2025
'''
import numpy as np
import h5py
import matplotlib.pyplot as plt
import bottleneck as bn
# %%
all_gabor_responses_eye_movements = h5py.File('../results/new_nat_videos_gabo... |
609b60903c7149f34f695904c2af1c095140da1d42e2d127c2858d2e901e5563 | Jupyter | 17,520 | 296 | # %%
'''
This notebook loads and analyzes natural video data processed with Gabor filters at three different walking speeds.
Date: 04.11.2024
Author: Jonathan Gant
'''
import numpy as np
import matplotlib.pyplot as plt
import os
from utilities import logistic_func, calc_MI, calc_entropy
from tqdm import tqdm
import h5... |
60011db547123a80640cc8f13d4a3d8024904710c9700b99105d7f5536a972bb | Jupyter | 17,541 | 538 | # %%
import pandas as pd
import selfies as sf
import exmol
import time
from rdkit import Chem
from rdkit.Chem import Descriptors
from tdc.single_pred import Tox
from dglgcn import largest_mol
# packages for plotting
import matplotlib.pyplot as plt
import matplotlib.font_manager as font_manager
import urllib.request
... |
727e17ab56a69280ee4fbd70cb0d705003d7ff4fcebf392f1612ed9cec007f23 | Jupyter | 17,561 | 504 | # %%
import os
os.environ['PYTORCH_CUDA_ALLOC_CONF'] = 'expandable_segments:True'
import warnings
warnings.filterwarnings('ignore')
import pickle
import time
import copy
from tqdm import tqdm
import numpy as np
import pandas as pd
from sklearn.model_selection import StratifiedKFold
from sklearn.metrics import auc, roc_... |
12e2bab1ab9660bb3c3711451496d23e8f3f1135a7b656df746cb579eb1b087f | Jupyter | 17,580 | 390 | # %% [markdown]
# ## Processing PRL task logs
#
# This script process raw, but validated PRL task logs. Script features:
# - creates new useful variables and removes other not used ones
# - aggregates behavioral data into single, easy to work DataFrame
# - creates metadata describing aggregated behavioral data
# - pro... |
33079a31a1a41399378fdf172c89a36e991dddd7e1de00a9db8427ce11b2de93 | Jupyter | 17,630 | 528 | # %%
import numpy as np
from matplotlib import pyplot as plt
import matplotlib as mpl
import scipy.signal as signal
import pandas as pd
import glob
import seaborn as sns
import scipy.ndimage as filters#changed from scipy.ndimage.filters as the namespace was deprecated 05/24/2023
import pickle
import scipy.stats as stat... |
e3e1d1b40f1ed03892a98a1b21e7a21642571b7691e802d0f131635fdab58e02 | Jupyter | 17,690 | 460 | # %%
import sys
import os
import pandas as pd
from sklearn import preprocessing
from tqdm import tqdm
import fm
import torch
from torch import nn
from torch import optim
from torch.utils.data import DataLoader
import numpy as np
import random
def seed_torch(seed=0):
random.seed(seed)
os.environ['PYTHONHASHSEED... |
1e67c7f37a1dbaf63942dc80b2a0402f3b3d8dc689165c1afc4c78060dc4dcd2 | Jupyter | 17,717 | 351 | # %% [markdown]
# # 🧬 BINND Complete Workflow - From Data to Decisions
# This notebook demonstrates the complete workflow for DNA-DNA binding prediction using a BINND-like model. You'll be guided through:
# 1. Data preparation for your custom dataset
# 2. Model training and evaluation
# 3. Testing BINND on your own da... |
dde843b46ec7bae597c21ecd682cec7a7dc5fb5270db809c31d27768e8438e14 | Jupyter | 17,903 | 526 | # %% [markdown]
# # Individual fish trajectories & data — standard OMR
#
# Per-fish trajectory, position, and velocity figures from `raw_data.json` — example single-fish plots plus all-fish batches.
# %%
import pandas as pd
import matplotlib.pyplot as plt
import matplotlib.colors as mp_clrs
import matplotlib.cm as cm... |
88a2acda4399a67d445fddcf823fad02e3e2f1ca53b2fde1d18d5c5cfb174d89 | Jupyter | 17,974 | 440 | # %% [markdown]
# <a target="_blank" href="https://colab.research.google.com/github/tcapraz/SOFA/blob/main/docs/notebooks/sc_multiome_example.ipynb">
# <img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
# </a>
# %% [markdown]
# Before you start, make sure to set your runtime ty... |
49a5ffbf82e7b72fa5206ab2ecd5c74f1d0166d9ecad2d06c62188b08dbba073 | Jupyter | 18,055 | 407 | # %% [markdown]
# ## PPI General Linear Model
#
# Here, PPI network construction is performed by evaluating multiple linear models and extracting regressors beta weights. PPI linear model takes form:
#
# $$y=\beta_0
# +\beta_1\cdot x_{physio}
# +\beta_2\cdot x_{out\_ons}
# +\beta_3\cdot x_{out\_perr}
# +\beta_4\cdot... |
bbae6fd5aad8c09fa40d40eadd185454f08affe719bc29d5655e3fe2c645afdd | Jupyter | 18,069 | 382 | # %% [markdown]
# <a target="_blank" href="https://colab.research.google.com/github/tcapraz/SOFA/blob/main/docs/notebooks/depmap_example.ipynb">
# <img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/>
# %% [markdown]
# Before you start, make sure to set your runtime type to GPU in... |
5577686b2e487eecb91529e97ff22d2384c2065b909636fc496ea177d400e675 | Jupyter | 18,197 | 477 | # %%
from __future__ import print_function
import nibabel as nib
import sklearn
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import os
import seaborn as sns
from sklearn.externals import joblib
from sklearn.preprocessing import PolynomialFeatures, StandardScaler
from sklearn.linear_model impor... |
be1c6a8336532cf5ea38caee7c7b0ef247a484f16468ddeb6d38013566c9442e | Jupyter | 18,315 | 425 | # %%
# xgboost
!pip install xgboost
# from sklearn.metrics import confusion_matrix
import numpy as np
import anndata
import pandas as pd
import scanpy as sc
import xgboost as xgb
import os
import pickle
from sklearn.metrics import confusion_matrix, adjusted_rand_score
import matplotlib.pyplot as plt
import matplotlib.g... |
2123bedbfbbf87d6d81ac46107305737accee43136a2e0ac8446ed36c40a7732 | Jupyter | 18,421 | 446 | # %%
'''
This script attempts to replicate the results of Mineault et al. showing a decrease in the decoder error during locomotion
Author: Jonathan Gant
Date: 29.08.2024
'''
import numpy as np
import matplotlib.pyplot as plt
from utilities import calc_entropy
from tqdm import tqdm
import h5py
import os
import bottlen... |
112d47d3f4cb1f2814255744f50ee4d70896a3a92002df35b136c99e100a22c4 | Jupyter | 18,424 | 600 | # %%
% matplotlib inline
import h5py, sys, io, numpy as np
import nibabel as nib
import nibabel.gifti
import nilearn
from nilearn import datasets, plotting
import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib as mpl
import matplotlib.pyplot as plt
from matplotlib.colors import ListedColorma... |
cdf2f98b8abcc07a33405453d63f33be60f0eb5fb94ee87795c5b6ed52a3e29c | Jupyter | 18,556 | 511 | # %% [markdown]
# ## Cell 1 — Imports
# %%
%matplotlib inline
import os
os.environ["KMP_DUPLICATE_LIB_OK"] = "TRUE"
import glob
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches
from matplotlib.colors import LinearSegmentedColormap, ListedColormap
import czi... |
7d57ea7a27802467df6cd6b3ac53dd48459c02cd2d55a5e4895f414790884609 | Jupyter | 18,612 | 518 | # %% [markdown]
# # Evo 2 Mech Interp Example Notebook
# ### 25.06.05
#
# Minimal example of extracting features for an *E. coli* genome chunk and plotting to recreate parts of the main and supplementary figures
# %%
!pip install matplotlib
# %%
from typing import List, Optional, Callable
import torch
from Bio imp... |
fea3dded002ec6230965af41591c5c04f3106e68bca2642c92de34bb141f0e72 | Jupyter | 18,723 | 466 | # %%
'''
This notebook analyzes the data from the paper by Horrocks et al.
Date: 29.04.2024
Author: Jonathan Gant
'''
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
from scipy.io import loadmat
# %% [markdown]
# # Load from excel files
# %%
datadir = 'data/horrocks/'
fname = 'F1d_run.xls'
r... |
6a54e32d10406991ea954fe26fefe8f7bfa88893f19628c0aaf9f23bf2a2939f | Jupyter | 18,733 | 605 | # %%
import loompy
import numpy as np
import pandas as pd
import matplotlib
import matplotlib.pyplot as plt
import os
from cytograph.pipeline import load_config, PunchcardDeck
from cytograph.plotting import colorize
from cytograph.embedding import art_of_tsne
from cytograph.visualization import scatterm
from cytograph.... |
5a61e61c3df9cab71c2d3680bd89122bf057221b4fe5a9d569b5f881e3ff12a9 | Jupyter | 18,823 | 591 | # %% [markdown]
# # Fine-tuning Pre-trained Model for Perturbation Prediction
# %%
import json
import os
import sys
import time
import copy
from pathlib import Path
from typing import Iterable, List, Tuple, Dict, Union, Optional
import warnings
import torch
import numpy as np
import matplotlib
from torch import nn
fr... |
22af51de8189f5c032fca4a7ff1265f1b8925bfc072e192b2d1e6df6f6230beb | Jupyter | 18,960 | 472 | # %%
import json
import os
import sys
from dataclasses import dataclass
from datetime import datetime
import cairosvg
#import dataframe_image as dfi
import matplotlib.ticker as ticker
import numpy as np
import pandas as pd
import skunk
from scipy.stats import spearmanr, wilcoxon
sys.path.insert(1,'../../')
from dglgc... |
cd58660b1077ccf6dda6fa2d0da931768e369388b48dfe6e17cbdf848015e37b | Jupyter | 19,169 | 353 | # %%
'''
This notebook loads and analyzes natural video data processed with Gabor filters at three different walking speeds.
Date: 04.11.2024
Author: Jonathan Gant
'''
import numpy as np
import matplotlib.pyplot as plt
import os
from utilities import logistic_func, calc_MI, calc_entropy
from tqdm import tqdm
import h5... |
780f1085b942584c814da39f69e2b9e43c1e7884563386d6ad23e528029834c4 | Jupyter | 19,509 | 478 | # %% [markdown]
# Load relevant packages:
# %%
%matplotlib inline
%reset
import glob
import pickle
import os
import pandas as pd
import matplotlib.pyplot as plt
import numpy as np
import sys
import seaborn as sns
import textwrap
from matplotlib import cm
#from statistics import mean
from scipy.integrate import simp... |
1d59fab6de903ea95b0c8850bdf78a8e7f1a6da9e382fcac81870223665a9706 | Jupyter | 19,558 | 594 | # %% [markdown]
# # Transfer published PCNToolkit cortical-thickness models to new sites
#
# This notebook demonstrates how an external user can:
#
# 1. simulate a local healthy-reference dataset with **1,000 participants**, **three imaginary sites**, and **68 Desikan–Killiany cortical-thickness regions**;
# 2. split... |
224187dcf47e7ce724535750487e57cc8d7ac97ab554dfa18d3ddb752898d096 | Jupyter | 19,612 | 504 | # %% [markdown]
# # Attention-based GRN Inference on Fine-tuned Model
# Here we use the fine-tuned blood model on the Adamson perturbation dataset as an example of the cell-state specific GRN inference via attention weights. scGPT outputs attention weights on the individual cell level, which can be further aggregated b... |
143c3f11f8bb9683cc82779941d561f56a86c414eb5123f6054db399ee0a3d0c | Jupyter | 19,743 | 723 | # %% [markdown]
# # CosMx human liver
# %% [markdown]
# This notebook is used to tokenize the CosMx human lung dataset and generate dataset statistics for figures in nicheformer.
# %% [markdown]
# ## Imports and definitions
# %%
import scanpy as sc
import anndata as ad
import pandas as pd
import numpy as np
import ... |
338ff0874e5c7451e59513798b85f46328647c68a1f52148076d90d083f73688 | Jupyter | 19,885 | 526 | # %% [markdown]
# <a href="https://colab.research.google.com/github/Valdes-Tresanco-MS/gmx_MMPBSA/blob/colab-notebook/notebooks/gmx_MMPBSA_Colab.ipynb" target="_parent"><img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"/></a>
#
# # gmx_MMPBSA examples on Google Colab CPUs
#
# This... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.